Recent Discussions
How to Fix Copilot With Multiple Microsoft 365 Accounts
Using Microsoft 365 with more than one account can be incredibly convenient. Maybe you have a work account and a personal Microsoft account. Or perhaps you manage Microsoft 365 for multiple organizations and regularly switch between different tenants. link to the post45Views0likes0CommentsHow to Check if Your Microsoft 365 Copilot License Is Active
Microsoft 365 Copilot can be a powerful addition to your everyday workflow. It can help draft documents, summarize information, analyze content, create ideas, and make it easier to work across Microsoft 365 applications. But before you can use all the features available to you, there is one important thing to confirm: is your Microsoft 365 Copilot license actually active and assigned to your account?link to the post50Views0likes0CommentsWhat Do You Use Copilot Cowork For? Practical Ways to Get More Done
Artificial intelligence is quickly becoming part of everyday work. What once felt like futuristic technology is now helping people write emails, organize information, summarize content, brainstorm ideas, and complete tasks faster. One of the questions many professionals and teams are now asking is: What do you use Copilot Cowork for? Link to the post46Views0likes0Comments
Copilot+ laptop cannot access my local files or folders. No permission dialog to approve access.
First up - I'm not a tech expert! I have a new CoPilot+ laptop. Asked CoPilot to do a task in my folders and files that I downloaded from iCloud, but it cannot access my files or folders. Asks me to allow access through Microsoft prompt that never appears. Contacted Microsoft Support yesterday and after 2 hours and no progress, they told me to contact laptop manufacturer support. Which I did, and this resulted in a reset to factory setting of the laptop today. Problem still persists, its not hardware related. I contacted Microsoft Support again and have been directed her on the basis that this appears to be an ongoing Copilot+ issue that has already been through extensive troubleshooting, the Tech Community is currently the best channel to track updates and raise visibility with the teams investigating the problem." Any suggestions on what I need to try next? Bearing in mind, I am not an expert! Thank you in advance Gail67Views0likes1Comment
Copilot Studio + SharePoint: Markdown (.md) Files in Doc Libraries Supported as Knowledge Sources?
Hi all, We’ve been doing some deeper testing with Copilot Studio agents grounded in SharePoint knowledge sources, and I’m hoping to clarify whether what we’re seeing is a known limitation or an undocumented gap. Scenario A Copilot Studio agent uses SharePoint document libraries as a knowledge source The library contains Markdown (.md) files that are intentionally used as canonical design references The same .md files: ✅ Work well when uploaded directly to the agent ❌ Are not retrievable or citable when stored in a SharePoint library and added as a SharePoint knowledge source To help with grounding, we created modern SharePoint index pages that: Explain what the markdown collections are (Patterns, ADRs, Guardrails) Link directly to the canonical folders and files Explicitly state that the .md files are the source of truth The agent can: Discover and summarize the index pages correctly Understand that .md artifacts exist and where they live But it cannot: Read the content of the individual .md files Apply a specific pattern or ADR from those files in a design conversation Cite them as sources, even when permissions and search indexing are confirmed What We’ve Checked Permissions (agent user has access) Folder depth (kept shallow) Search results (markdown files appear in SharePoint search) SharePoint indexing status Work IQ enabled Same content works when attached directly to the agent This behavior also seems consistent with what others have reported here: Markdown works when uploaded directly Markdown retrieval degrades when hosted in SharePoint libraries Questions for the Product Team / Community Are Markdown (.md) files in SharePoint document libraries officially supported as Copilot Studio knowledge sources today? If yes, are there specific constraints (file size, rendering, parsing, indexing) that differ from Word/PDF? If no (or “not yet”), is this a known limitation on the roadmap? Is the recommended pattern to: Convert important markdown files into .aspx pages, or Use thin “index / summary” pages and keep markdown canonical until retrieval improves? We’re happy to adapt our information architecture — just trying to align with the intended platform direction rather than work against it. Thanks in advance for any guidance or clarification. This capability is extremely powerful, and clearer expectations here would help a lot of teams make the right design tradeoffs.2.9KViews14likes6CommentsWhat is the best file format for an AI agent knowledge base?
This is a best practice sharing the best format for an agent and show you why you should convert your PPT, PDF, WORD into a TXT markdown. I had an issue with my agent, time taken to answer was too long, and usually we spend a lot of time asking: What is the best prompt? Why is my agent slow? Why does retrieval sometimes work and sometimes fail? How can I improve answer quality? But I realised I was asking another question much less often: What is actually the best file format for the knowledge base? PDF? Raw text? Markdown? Pre-chunked text? Semantic sections? Context-enriched text? And more importantly: How much does the format alone affect agent performance? I tried to find a quantified benchmark answering this specific question, with the same agent, same source knowledge and same questions, but different knowledge representations. I couldn't find one that really answered what I wanted to measure. So I decided to run the experiment myself on a real case. My first exploratory tests were already surprising: depending on the representation, the agent could be significantly faster and more accurate, despite working from the exact same source information. So I decided to push the test further. My objective I want to identify, without assumptions and based on actual evaluation data, how a long document should be prepared for an LLM knowledge base so that the agent can retrieve, understand, ground and answer from it as reliably as possible. I focused on five dimensions: Answer quality Retrieval reliability Source grounding / citations Execution time Robustness across single-turn and multi-turn questions The broader question I'm trying to answer is: How should we structure knowledge so that an LLM can retrieve and use it as reliably as possible? The test case I deliberately chose a document that isn't particularly friendly for RAG: a 46-page European regulation, https://eur-lex.europa.eu/eli/reg/2011/1169/oj?locale=fr, on the provision of food information to consumers. The information is distributed across articles, definitions, exceptions, annexes, tables, numerical thresholds and cross-references. That makes it useful for testing retrieval: answering correctly often requires finding a very specific piece of information while preserving enough context to understand how it applies. I used the native PDF as the baseline and created 6 additional knowledge-base representations of the same document: Raw TXT Markdown Chunk-ready TXT RAG-oriented units Semantic TXT Contextual TXT One rule: same knowledge, same agent, same instructions, same questions. Only the knowledge representation changes. The benchmark I used two evaluation sets: 42 single-turn questions testing broad coverage of the document: direct facts, thresholds, exceptions, annexes, lists and cross-references. 5 multi-turn conversations containing 13 questions, to see what happens when a user asks a question and then follows up with things like: "And in this case?" "What are the exceptions?" "And for dietary fibre?" This gave me: 47 evaluated test cases / 55 actual questions per format Across all 7 formats: 329 evaluated conversations 385 user questions executed First results Metric Native PDF Best structured representation Overall pass rate 66.0% 85.1% - Contextual TXT Best single-turn score 69.0% 88.1% - Chunk-ready TXT Multi-turn benchmark 40% 80% - Contextual TXT Multi-turn execution time 14m24 5m54 Total benchmark time 44m31 24m49 The quality gap was already substantial: 66.0% → 85.1% That's +19.1 percentage points while keeping the underlying knowledge unchanged. I also saw a major difference in execution time. On the multi-turn test: 14m24 → 5m54 That's approximately 2.4× faster. Across the complete benchmark: 44m31 → 24m49 Around 44% less execution time. These timings represent the complete agent evaluation pipeline, so they shouldn't be interpreted as pure LLM inference latency. But the difference under identical test conditions is large enough that I want to understand it better. Findings There wasn't one format dominating every benchmark. Chunk-ready TXT scored highest on independent questions: 88.1%, while Contextual TXT performed better across multi-turn conversations and finished with the highest overall score. That may suggest that the way we optimise a document for isolated retrieval isn't exactly the same as the way we should prepare it for conversational retrieval. In the contextual version, I tried to make every section understandable when retrieved independently by keeping useful information around it: Source references Section context Retrieval cues Relevant cross-references For regulatory documents, this seems particularly important. A numerical value retrieved alone can be meaningless without knowing which rule it belongs to, under which conditions it applies, and whether another article contains an exception. Where I am now This remains an exploratory benchmark: One document One domain One agent setup One evaluation framework One run per configuration There are plenty of things I still want to test: repeated runs, retrieval-level evaluation, token consumption, larger knowledge bases, other document types, chunk sizes, overlap, contextual headers, and more. But these first results already convinced me that the preparation of the knowledge base deserves much more attention when evaluating an agent. We often spend hours refining instructions while the same information may behave very differently depending on how it reaches the retrieval layer. Next step I'll share the prompts, knowledge-base formats and evaluation methodology on GitHub so the experiment can be reproduced and challenged. I'll keep enriching the repository as I test new formats, improve the evaluation set and add new results. If people here have ideas, edge cases or formats worth testing, I'd genuinely like to include some of them in the next iteration. What would you test next?373Views2likes3Comments
Can Copilot handle repeatable account reviews, or do SMBs need agents?
Hi everyone, I’m trying to better understand how small and medium-sized businesses are using Microsoft 365 Copilot for recurring business-review workflows. A pattern I see often is account or customer review prep. For example, a team may manage dozens of customers, merchants, partners, vendors, or locations. Every month or quarter, someone needs to pull performance data, summarize what changed, create slides or a short report, recommend next actions, organize the files, and send follow-up notes. For those of you using Copilot in a small or mid-sized business: - Is Copilot enough for this kind of recurring workflow using Excel, PowerPoint, Word, Outlook, Teams, OneDrive, and SharePoint? - Where does the process still become manual or hard to repeat? - Do you need to handle many accounts/customers/locations in one run, or is one at a time enough? - How important is history tracking across months or quarters? - Would automatic OneDrive or SharePoint organization be useful so each account has a durable review history? - What would make AI-generated summaries, slides, and action plans trustworthy enough for executive or customer-facing use? I’m especially interested in the business-user perspective: account managers, customer success teams, sales/partner managers, operations teams, and small business leaders who prepare recurring reviews or performance updates. For context, we recently built a Microsoft 365 Marketplace agent focused on merchant QBR preparation, but my broader question is about the workflow pattern: what do SMB users actually want Copilot or workflow-specific agents to do when recurring review work spans data, slides, files, and follow-up? Curious how others are approaching this.14Views0likes0CommentsFor account managers running QBRs, is M365 Copilot enough or do you need workflow-specific agents?
Hi Microsoft 365 Copilot community, I’m trying to better understand how account managers and customer-facing teams are using Copilot for recurring business review workflows. Imagine you manage dozens of merchant or customer accounts. Every quarter, you need to prepare business reviews, summarize account performance, identify changes from the prior period, create executive-ready slides, recommend next actions, and send follow-up notes. For those of you doing similar work today: - Is Microsoft 365 Copilot enough for this workflow using prompts across Excel, PowerPoint, Word, Outlook, and Teams? - Where does the process still become manual or hard to repeat? - Do you need batch handling across many accounts, or is one account at a time enough? - How important is quarter-over-quarter history tracking? - Do you want outputs organized automatically in OneDrive or SharePoint so each account has a durable review history? - What would make this kind of workflow trustworthy enough for executive or customer-facing use? I’m especially interested in the business-user perspective: account managers, customer success managers, partner managers, sales operations, merchant services teams, and anyone who prepares recurring customer/account reviews. For context, we recently built a Microsoft 365 Marketplace agent called Merchant QBR AutoPilot that explores this pattern: batch QBR scorecards, PowerPoint outputs, OneDrive organization, and follow-up email drafts. But my main question is broader: what would you actually want Copilot or a workflow-specific agent to do for quarterly account reviews? Curious how others are approaching this.
Combining Project, Image, and Notebook Features for a Unified Experience
I'm currently using two different Copilot app experiences to manage my work, projects, and notebooks and each one excels in different areas while missing key capabilities found in the other. One app provides a much richer project management environment, with Tasks, true project folders, plugin connections, and the ability to embed instructions. The other offers a stronger, more fluid notebook experience, but lacks the depth and structure that the project-focused app provides. Switching back and forth between these environments creates friction, especially when I want my projects and notebooks to live together in one unified workspace. The separation makes the workflow feel fragmented. There are also inconsistencies across creative and experimental features. One Copilot app uses Create for image editing, while the other uses Imagen. One includes Team of Advisors, while the other doesn’t. Different experiments appear in different places, and the overall experience feels split rather than cohesive. I’d love to see these capabilities brought together into a single, integrated Copilot environment. I would love to have one place where projects, notebooks, agents, experiments, and creative tools coexist. Additionally, the video creation experience could benefit from deeper AI integration. Clipchamp is functional, but it doesn’t yet feel like an AI‑accelerated workflow. A more advanced, model video tool would dramatically improve speed and creativity for users who rely on Copilot for content production. Finally, many of us want broader access to Cowork and more agentic capabilities. The ability to design or customize our own agents would unlock huge value, especially for users who depend on Copilot for complex workflows. Right now, I often have to go elsewhere to build agentic tools because Copilot doesn’t allow enough personalization or agent creation within its own ecosystem. Bringing these experiences together ... unified projects, enhanced notebooks, consistent creative tools, richer video AI, and expanded Cowork access would create a far more powerful and seamless Copilot environment for everyone.
The GPT 5.5 Think Deeper Model on Copilot is not responding
I have tried all possible troubleshooting methods to correct this issue but the GPT 5.5 Think Deeper model seems to not be working and the Microsoft Support team also was not able to provide any help on this issue. Can you suggest what possible issue it could be at my end and how to fix the same and this issue is being faced by everyone on my Microsoft 365 License Everytime I ask for a response from GPT 5.5 Think Deeper model I am getting the error message " Sorry, I wasn't able to respond to that. Is there something else I can help with? " And these are for AI commands that it had been responding properly before87Views1like1CommentWhy is it so hard to get tech support?
The chat said they can't help me and then said to start a discussion incase a peer can help me. But its diagnosed as a back-end account issue: Based on the troubleshooting performed so far, the issue appears to be specific to your Microsoft account, as: Copilot is failing on multiple platforms (MacBook, iPhone, and web browser). The issue occurs in both normal and Incognito/InPrivate sessions. Your Microsoft 365 Personal subscription is active. Your Copilot credits are available. Another Microsoft account works normally on the same devices. At this point, I recommend reaching out to the Microsoft Copilot Technical Community, where account-specific Copilot issues can be reviewed by Microsoft moderators and specialists who can investigate service-side restrictions, account anomalies, or backend-related issues.28Views1like0CommentsCoPilot account issue
Bot WC said: Based on the troubleshooting performed so far, the issue appears to be specific to your Microsoft account, as: Copilot is failing on multiple platforms (MacBook, iPhone, and web browser). The issue occurs in both normal and Incognito/InPrivate sessions. Your Microsoft 365 Personal subscription is active. Your Copilot credits are available. Another Microsoft account works normally on the same devices. At this point, I recommend reaching out to the Microsoft Copilot Technical Community, where account-specific Copilot issues can be reviewed by Microsoft moderators and specialists who can investigate service-side restrictions, account anomalies, or backend-related issues. Where can a specialist sort this for me?31Views0likes0Comments
How to Integrate Copilot Studio Agent with a Website Using API?
Hello Team, I have created a Copilot Agent using Copilot Studio and published it on our public website using an iframe. Currently, the agent does not have any authentication configured because we want it to be publicly accessible. However, our website development team has raised a security concern with this approach, as embedding the Copilot Agent directly using an iframe may not be the most secure or recommended approach. We are looking for an alternative integration approach. For example: Is it possible to expose the Copilot Studio Agent through an API or another secure endpoint? Can our website development team call the agent through an API, receive the response, and build their own custom UI instead of embedding the agent using an iframe? Is there any recommended architecture or Microsoft-supported approach for securely integrating a Copilot Studio Agent with a public-facing website? If anyone has implemented a similar solution or has any recommendations, I would appreciate your suggestions.57Views0likes1CommentAny way to keep Copilot always open in the sidebar?
Looking to always have Copilot open in the sidebar when using Edge. I've found various bits of information regarding how to do this but they rely on the "sidebar" settings area which apparently has been retired from Edge. I just want Copilot in the sidebar at all times directly from startup. Thanks.131Views0likes5CommentsUnanswered Questions on GitHub Copilot Harness in Copilot Studio
We're piloting the GitHub Copilot harness in Copilot Studio (GA August 2026) and several operational and architectural details remain undocumented in the GA FAQ, Microsoft Learn, or licensing guides. Looking for official answers or PM contacts on: Architecture & Execution – When the harness breaks tasks into subtasks, does it use internal sub-agents or only skills/connected agents, what are the exact timeout/retry/max-execution-duration limits for long-running workflows, and are planning/context-retrieval/orchestration internals documented anywhere or is the orchestrator a black box? Model Selection – Can individual skills within one agent use different models or is selection strictly agent-level, how are models chosen internally when multiple skills execute, are any internal models developer-configurable, and what's the roadmap for models being added/retired/deprecated plus the lag between public release and Copilot Studio availability? Cost & Token Optimization – How exactly is the ~45% token reduction achieved, how much control do makers have over context/caching/retrieval/tool calls, what are per-model credit consumption characteristics, which models are most cost-effective for specific workloads, and what's the minimum credit cost for trivial interactions? Memory Management – What are retention periods for session/working/agent memory beyond the documented 28-day user-memory expiry, is true long-term memory supported, and what changed versus earlier implementations? Knowledge Retrieval – Can skills or system instructions influence retrieval strategy/document selection/prioritization/filtering, can planning stages perform conflict/duplicate/version detection before retrieval, and how does the harness decide which sources to search? Apps Feature – What is the "Apps (preview)" capability for, when does it GA, and how does it differ from workflows/skills/adaptive cards/agents? Billing & Credit Sizing – Is there a framework to classify users/agents by expected consumption and size credit allocation per group (citizen vs pro developers), and what's the minimum/typical consumption for simple/medium/heavy interactions? Governance & Admin – Can usage limits be set at user level (not just environment/agent), is there an API/IaC path for large-scale credit assignment, can non-admins view their own consumption/remaining allocation, and is there a self-service request-more-credits dashboard? ALM & Environments – What's the recommended path to move harness agents across Dev/Test/UAT/Prod (Solutions/ALM "setup differs" per parity chart—how?), does GitHub integration replace or complement solution-based deployment, are there recommended AgentOps practices for source control/releases/versioning, and what baseline credits and onboarding model are suggested for citizen developers under usage billing—any enterprise reference implementations?278Views2likes1Comment
How to preserve document format and structure with Copilot Agent
Hi everyone, I was building a copilot agent that should be able to accept a document and then make changes to it before returning the new version of that document, which has the same format and structure as the original. What is the best way to accomplish this in copilot studio? So far, I have tried using a power automate flow and external tools but it seems that there is no free included tool that can achieve this task. All the document writing tools seem to be paid services requiring API keys. Is there an alternate free way of achieving this task? Thank you124Views0likes1CommentHow to Avoid Tasks Copilot "You've reached our weekly Tasks limit"
I’ve been using both Chat‑Copilot (CC) and Tasks‑Copilot (TC) extensively, and I wanted to share a brief summary provided by TC, that may help others understand how each tool works, why TC sometimes stops responding, and how to avoid running into limits. ⭐ 1. Chat‑Copilot and Tasks‑Copilot serve different purposes Chat‑Copilot Real‑time conversational AI Great for brainstorming, drafting, coding, calculations, and iterative design Stateless — each message is processed independently Very stable and rarely gets stuck Tasks‑Copilot Designed for multi‑step workflows Can create and maintain documents Runs long‑lived background tasks Maintains persistent state More powerful for structured work More fragile because it depends on a task‑execution pipeline These two systems are independent. Chat can work perfectly even when TC is frozen. ⭐ 2. Why Tasks‑Copilot hits limits or becomes unresponsive TC can stop responding when: A task runs too long A multi‑step workflow fails mid‑execution The task state becomes corrupted The weekly quota system triggers The backend fails to reset on Friday Too many “pipeline‑style” requests are issued in a short time When this happens, TC may: stop responding entirely ignore all prompts remain stuck across all devices and browsers This is a backend state issue, not a browser or device problem. ⭐ 3. How to avoid triggering TC limits Here are practical ways to keep TC healthy: Use Chat‑Copilot for: brainstorming engineering design calculations drafting text generating diagrams or prompts step‑by‑step reasoning Chat handles these extremely well and never “uses up” TC capacity. Use Tasks‑Copilot only for: creating structured documents maintaining long‑form reports assembling multi‑section deliverables tasks that explicitly require persistent state Avoid these patterns in TC: “Build the entire document end‑to‑end” “Run this whole workflow” “Generate all sections at once” Rapid‑fire edits or repeated task triggers Very large or complex requests Instead, break work into small, single‑action steps. ⭐ 4. When TC gets stuck, what can users do? For consumer Microsoft 365 Personal accounts: There is no user‑accessible reset button Frontline support cannot reset TC’s task state Creating a business account does not fix the issue The only options today are: submit feedback post on the Tech Community wait for the backend to refresh This is a known limitation of the current TC preview. ⭐ 5. What would help users going forward A few improvements would make TC much more reliable: A user‑visible “Reset Task State” button Error messages instead of silent failures More predictable weekly resets Support tools that allow agents to clear stuck task containers836Views0likes2Comments


Events
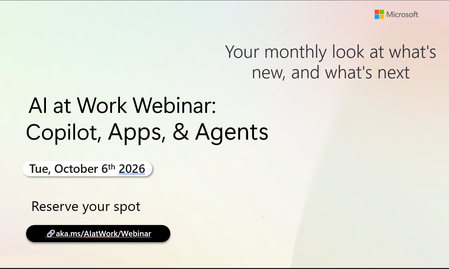
Register Here - https://aka.ms/MTC/CopilotRoadmapEventOct
AI at Work Webinar: Copilot, Apps, & Agents — Want to stay on top of everything happening across Copilot and AI-powered business applicatio...
Tuesday, Oct 06, 2026, 09:00 AM PDTOnline
0likes
16Attendees
0Comments
Recent Blogs
- OpenAI's GPT-6 Astra is rolling out in Copilot Cowork and Copilot Studio todaySep 04, 20269.2KViews1like0Comments
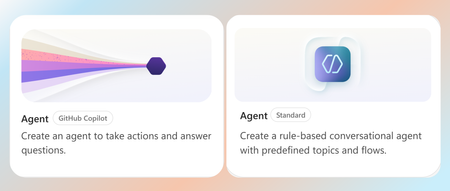
- The Standard harness and GitHub Copilot harness are two authoring and runtime options within Microsoft Copilot Studio. A harness is the operating layer between the model and the agent’s configuration...Sep 02, 20262.5KViews0likes1Comment