copilot
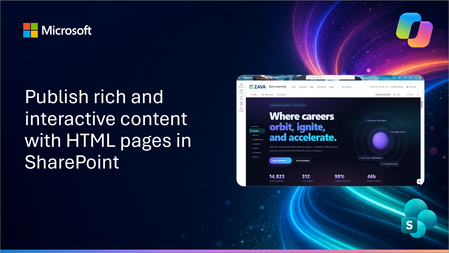
145 TopicsPublish rich and interactive content with HTML pages in SharePoint
HTML pages in SharePoint let you create rich, interactive content with Copilot or upload existing HTML, then edit, publish, and share it alongside modern pages. Copilot-created pages use your site’s branding, while familiar SharePoint permissions and security controls help manage access. Availability is rolling out gradually through the Frontier program.3KViews0likes10CommentsCopilot, Microsoft 365 & Power Platform Community call
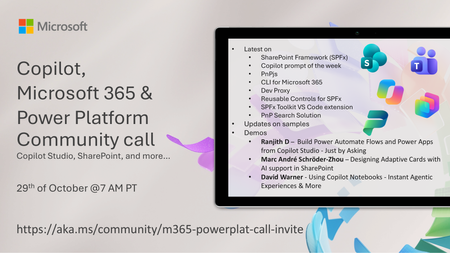
💡 Copilot, Microsoft 365 & Power Platform weekly community call focuses on different use cases and features within the Microsoft 365 and Power Platform - across Microsoft 365 Copilot, Copilot Studio, SharePoint, Power Apps and more. Demos in this call are presented by the community members. 👏 Looking to catch up on the latest news and updates, including cool community demos, this call is for you! 📅 On 29th of October we'll have following agenda: Latest on SharePoint Framework (SPFx) Latest on Copilot prompt of the week PnPjs CLI for Microsoft 365 Dev Proxy Reusable Controls for SPFx SPFx Toolkit VS Code extension PnP Search Solution Demos this time Ranjith D – Build Power Automate Flows and Power Apps from Copilot Studio - Just by Asking Marc André Schröder-Zhou – Designing Adaptive Cards with AI support in SharePoint David Warner - Using Copilot Notebooks - Instant Agentic Experiences & More 📅 Download recurrent invite from https://aka.ms/community/m365-powerplat-dev-call-invite 📞 & 📺 Join the Microsoft Teams meeting live at https://aka.ms/community/m365-powerplat-dev-call-join 💡 Building something cool for Microsoft 365 or Power Platform (Copilot, SharePoint, Power Apps, etc)? We are always looking for presenters - Volunteer for a community call demo at https://aka.ms/community/request/demo 👋 See you in the call! 📖 Resources: Previous community call recordings and demos from the Microsoft Community Learning YouTube channel at https://aka.ms/community/youtube Microsoft 365 & Power Platform samples from Microsoft and community - https://aka.ms/community/samples Microsoft 365 & Power Platform community details - https://aka.ms/community/home 🧡 Sharing is caring!102Views0likes0CommentsCopilot, Microsoft 365 & Power Platform product updates call
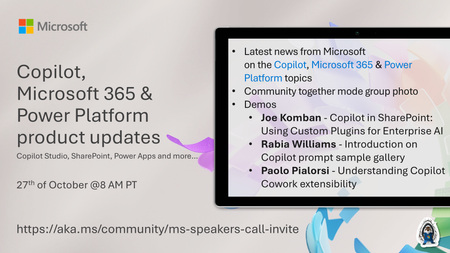
Copilot, Microsoft 365 & Power Platform product updates call concentrates on the different use cases and features within the Microsoft 365 and in Power Platform. Call includes topics like Microsoft 365 Copilot, Copilot Studio, Microsoft Teams, Power Platform, Microsoft Graph, Microsoft Viva, Microsoft Search, Microsoft Lists, SharePoint, Power Automate, Power Apps and more. 👏 Weekly Tuesday call is for all community members to see Microsoft PMs, engineering and Cloud Advocates showcasing the art of possible with Copilot, Microsoft 365 and Power Platform. 📅 On the 27th of October we'll have following agenda: News and updates from Microsoft Together mode group photo Joe Komban - Copilot in SharePoint: Using Custom Plugins for Enterprise AI Rabia Williams - Introduction on Copilot prompt sample gallery Paolo Pialorsi - Understanding Copilot Cowork extensibility 📞 & 📺 Join the Microsoft Teams meeting live at https://aka.ms/community/ms-speakers-call-join 🗓️ Download recurrent invite for this weekly call from https://aka.ms/community/ms-speakers-call-invite 👋 See you in the call! 💡 Building something cool for Microsoft 365 or Power Platform (Copilot, SharePoint, Power Apps, etc)? We are always looking for presenters - Volunteer for a community call demo at https://aka.ms/community/request/demo 📖 Resources: Previous community call recordings and demos from the Microsoft Community Learning YouTube channel at https://aka.ms/community/youtube Microsoft 365 & Power Platform samples from Microsoft and community - https://aka.ms/community/samples Microsoft 365 & Power Platform community details - https://aka.ms/community/home 🧡 Sharing is caring!121Views0likes0Comments
What replaces the Copilot in SharePoint site exclusion list after 1 November 2026
Disclosure: I work on M365 Scouts, a vendor that makes read-only audit scripts for Microsoft 365. This post is about Microsoft's own controls and doesn't need our tools. If you excluded SharePoint sites from Copilot using the preview cmdlets (KnowledgeAgentScope, KnowledgeAgentSelectedSitesList, KnowledgeAgentSelectedSitesListOperation), those settings are only honoured until 1 November 2026. The cmdlets are retired. Microsoft says general availability of Copilot in SharePoint begins rolling out on 30 September 2026. What replaces them: Site AI settings. Set by the site owner (Settings > Site AI). They hide the Copilot button on that site for visitors. Restricted Content Discovery. Set by a SharePoint admin, for example Set-SPOSite -Identity <site-url> -RestrictContentOrgWideSearch $true. It limits discovery of the site in organization-wide search and Copilot responses, and removes the AI entry points on that site. It needs a Copilot licence and SharePoint Advanced Management, and it covers SharePoint sites only, not OneDrive. On sites over 500,000 items an update can take more than a week. Neither control changes permissions. People who already have access can still open the files, and Microsoft describes Restricted Content Discovery as a temporary control to use selectively. Restricted SharePoint Search is also retiring, and new enablement has been blocked since 31 July 2026. So the real work before 1 November is knowing which sites are overshared: Anyone links, Everyone except external users, broken inheritance, ownerless sites and missing sensitivity labels. Copilot in SharePoint also needs a Microsoft 365 Copilot licence for each user. Sources: Microsoft Learn pages on Copilot in SharePoint, Restricted Content Discovery and Restricted SharePoint Search. Please check them against your tenant, because the GA page is still changing.213Views0likes1CommentUnderstanding the Notebooks in the Oversharing Template v2 (Microsoft Fabric)
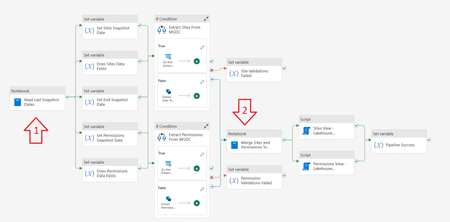
The Microsoft Graph Data Connect for SharePoint team published two notebooks used with Microsoft Fabric in the Information Oversharing v2 template. This blog explains what each code block inside these notebooks does. The goal was to help you understand what the notebooks do. Note that this document was written with help from Copilot, using simple prompts like “Analyze each section of this Jupyter notebook with PySpark and Scala code. Describe what each section does.” Notebook 1: Read Last Snapshot Dates This first notebook runs right as the pipeline starts. It checks the environment, verifies if the Sites and Permission tables exist in the Lakehouse, checks the last day data was gathered from MGDC and calculates the start and end date to use. It also cleans the staging tables and stores a few commands that are used in later steps. Section 0 – Set the Default Lakehouse for Notebook to Run %%configure { "defaultLakehouse": { "name": { "parameterName": "lakehouseName", "defaultValue": "defaultlakehousename" } } } This section uses the %%configure magic command to set a JSON configuration that defines a parameter (lakehouseName) with the default value "defaultlakehousename". This setting ensures that when the notebook is launched through a pipeline, it dynamically selects the target Lakehouse. Section 1 – Initialize Parameters import java.time.LocalDateTime import java.time.format.DateTimeFormatter import java.time.temporal.ChronoUnit import java.util.UUID import java.text.SimpleDateFormat import java.time.{LocalDate, LocalDateTime, Period} import java.time.format.DateTimeFormatter import java.time.temporal.ChronoUnit import java.util.Calendar import java.sql.Timestamp val runId = "00000000-0000-0000-0000-000000000000" val workspaceId = spark.conf.get("trident.workspace.id") val workspaceName = "LakeHouseTesting" val lakehouseId = spark.conf.get("trident.lakehouse.id") val lakehouseName = "IMAXDefault" val sitesStagingTableName = "Sites_Staging" val sitesFinalTableName = "Sites" val permissionsStagingTableName = "Permissions_Staging" val permissionsFinalTableName = "Permissions" val endTime = "2024-11-15T00:00:00Z" spark.conf.set("spark.sql.caseSensitive", true) This section imports various libraries for date/time handling and initializes key parameters for the ETL process. These include a run identifier (runId), workspace and Lakehouse information (with some values coming from Spark configuration), table names for staging and final datasets, and a fallback endTime. It also enforces case sensitivity in Spark SQL. Section 2 – Checking Required Final Tables Exist or Not val lakehouse = mssparkutils.lakehouse.get(lakehouseName) val lakehouseId = lakehouse.id val workspaceName = notebookutils.runtime.context("currentWorkspaceName") val permissionsStagingLocation = s"abfss://${workspaceName}@onelake.dfs.fabric.microsoft.com/${lakehouseName}.Lakehouse/Tables/${permissionsStagingTableName}" val sitesStagingLocation = s"abfss://${workspaceName}@onelake.dfs.fabric.microsoft.com/${lakehouseName}.Lakehouse/Tables/${sitesStagingTableName}" val sitesFinalLocation = s"abfss://${workspaceName}@onelake.dfs.fabric.microsoft.com/${lakehouseName}.Lakehouse/Tables/${sitesFinalTableName}" val permissionsFinalLocation = s"abfss://${workspaceName}@onelake.dfs.fabric.microsoft.com/${lakehouseName}.Lakehouse/Tables/${permissionsFinalTableName}" val tables = spark.catalog.listTables() val siteTableCount = tables.filter(col("name") === lit(sitesFinalTableName) and array_contains(col("namespace"), lakehouseName) ).count() val permissionsTableCount = tables.filter(col("name") === lit(permissionsFinalTableName) and array_contains(col("namespace"), lakehouseName)).count() val siteStagingTableCount = tables.filter(col("name") === lit(sitesStagingTableName) and array_contains(col("namespace"), lakehouseName) ).count() val permissionsStagingTableCount = tables.filter(col("name") === lit(permissionsStagingTableName) and array_contains(col("namespace"), lakehouseName)).count() This section retrieves the Lakehouse object and uses it to construct ABFS paths for both staging and final tables (for Sites and Permissions). It then checks for the existence of these tables by listing them in Spark’s catalog and filtering by name and namespace. Section 3 – Getting Snapshot Dates from Last Successful Extracts import org.apache.spark.sql.functions.{col, _} import org.apache.spark.sql.types._ import org.apache.spark.sql.{DataFrame, Row, SparkSession} import org.apache.spark.storage.StorageLevel val dtCurrentDateFormatt = DateTimeFormatter.ofPattern("yyyy-MM-dd HH:mm:ss.S") val dtRequiredtDateFormatt = DateTimeFormatter.ofPattern("yyyy-MM-dd'T'HH:mm:ss'Z'") var siteDataExists: Boolean = false var permissionsDataExists: Boolean = false val siteSnapshotDate = { if (siteTableCount == 1) { val dfSites = spark.sql(s"SELECT MAX(SnapshotDate) AS SnapshotDate FROM ${lakehouseName}.${sitesFinalTableName} ") val rowSites: Row = dfSites.select("SnapshotDate").head(1)(0) if (rowSites.get(0) == null) endTime else { siteDataExists = true println(s"Sites data Exists: ${siteDataExists}") LocalDateTime.parse(rowSites.get(0).toString(), dtCurrentDateFormatt) .format(dtRequiredtDateFormatt) } } else { endTime } } val permissionsSnapshotDate = { if (permissionsTableCount == 1) { val dfPermissions = spark.sql(s"SELECT MAX(SnapshotDate) AS SnapshotDate FROM ${lakehouseName}.${permissionsFinalTableName} ") val rowPermissions: Row = dfPermissions.select("SnapshotDate").head(1)(0) if (rowPermissions.get(0) == null) endTime else { permissionsDataExists = true println(s"Permissions data Exists: ${permissionsDataExists}") LocalDateTime.parse(rowPermissions.get(0).toString(), dtCurrentDateFormatt) .format(dtRequiredtDateFormatt) } } else { endTime } } This section queries the final tables to retrieve the latest SnapshotDate for both Sites and Permissions. It then reformats the date into an ISO-compliant format. If no snapshot date is found, it defaults to the predefined endTime, and two boolean flags (siteDataExists and permissionsDataExists) are toggled accordingly. Section 4 – Generate View Script for Sites val sitesView: String = s""" CREATE OR ALTER VIEW vw${sitesFinalTableName} AS SELECT *, [StorageQuotaFriendly] = (case when StorageQuota < 1048576 then concat(ceiling(StorageQuota / 1024.0), ' KB') when StorageQuota < 1073741824 then concat(ceiling(StorageQuota / 1048576.0), ' MB') when StorageQuota < 1099511627776 then concat(ceiling(StorageQuota / 1073741824.0), ' GB') when StorageQuota < 1125899906842624 then concat(ceiling(StorageQuota / 1099511627776.0), ' TB') else concat(ceiling(StorageQuota / 1125899906842624.0), ' PB') end ), [StorageUsedFriendly] = (case when StorageUsed < 1048576 then concat(ceiling(StorageUsed / 1024.0), ' KB') when StorageUsed < 1073741824 then concat(ceiling(StorageUsed / 1048576.0), ' MB') when StorageUsed < 1099511627776 then concat(ceiling(StorageUsed / 1073741824.0), ' GB') when StorageUsed < 1125899906842624 then concat(ceiling(StorageUsed / 1099511627776.0), ' TB') else concat(ceiling(StorageUsed / 1125899906842624.0), ' PB') end ) FROM ${sitesFinalTableName} """.stripMargin.replaceAll("[\n\r]"," ") println(sitesView) Here a SQL view (vwSites) is dynamically generated for the Sites final table. The view adds two computed columns (StorageQuotaFriendly and StorageUsedFriendly) that convert byte values into more digestible units such as KB, MB, GB, etc. This script will be stored and executed later. Section 5 – Generate View Script for Permissions val permissionsView: String = s""" CREATE OR ALTER VIEW vw${permissionsFinalTableName} AS SELECT *, ShareeDomain = CASE WHEN CHARINDEX('@', SharedWith_Email) > 0 AND CHARINDEX('.', SharedWith_Email) > 0 THEN SUBSTRING(SharedWith_Email,CHARINDEX('@', SharedWith_Email)+1,LEN(SharedWith_Email)) ELSE '' END, ShareeEMail = CASE WHEN CHARINDEX('@', SharedWith_Email) > 0 THEN SharedWith_Email ELSE '' END, PermissionsUniqueKey = CONCAT(SiteId,'_',RoleDefinition,'_',ScopeId,'_',COALESCE(LinkId,'00000000-0000-0000-0000-000000000000')), EEEUPermissionsCount = SUM(CASE WHEN SharedWith_Name LIKE 'Everyone except external users' THEN 1 ELSE NULL END ) OVER( PARTITION BY CONCAT(SiteId,'_',RoleDefinition,'_',ScopeId,'_',COALESCE(LinkId,'00000000-0000-0000-0000-000000000000'),SharedWith_Name) ), ExternalUserCount = SUM(CASE WHEN SharedWith_TypeV2 LIKE 'External' THEN 1 ELSE NULL END ) OVER( PARTITION BY CONCAT(SiteId,'_',RoleDefinition,'_',ScopeId,'_',COALESCE(LinkId,'00000000-0000-0000-0000-000000000000'),SharedWith_Name) ), B2BUserCount = SUM(CASE WHEN SharedWith_TypeV2 LIKE 'B2BUser' THEN 1 ELSE NULL END ) OVER( PARTITION BY CONCAT(SiteId,'_',RoleDefinition,'_',ScopeId,'_',COALESCE(LinkId,'00000000-0000-0000-0000-000000000000'),SharedWith_Name) ) FROM ${permissionsFinalTableName} """.stripMargin.replaceAll("[\n\r]"," ") println(permissionsView) This section builds a SQL view (vwPermissions) for the Permissions final table. It derives additional columns like ShareeDomain, ShareeEMail, and a composite key (PermissionsUniqueKey) while applying window functions to compute counts (e.g., for external or B2B users). This script will also be stored and executed later. Section 6 – Truncate the Staging Tables from Previous Runs if (siteStagingTableCount == 1) { spark.sql(s"DELETE FROM ${lakehouseName}.${sitesStagingTableName} ") println(s"Staging table deleted: ${lakehouseName}.${sitesStagingTableName}") } else { println(s"Staging table ${lakehouseName}.${sitesFinalTableName} not found") } if (permissionsStagingTableCount == 1) { spark.sql(s"DELETE FROM ${lakehouseName}.${permissionsStagingTableName} ") println(s"Staging table deleted: ${lakehouseName}.${permissionsStagingTableName}") } else { println(s"Staging table ${lakehouseName}.${permissionsStagingTableName} not found") } This section checks if the staging tables exist (by count) and, if found, issues a SQL DELETE command to remove existing data so that new data can be loaded. It prints messages indicating the action taken. Section 7 – Return Snapshot Dates Back to Pipeline import mssparkutils.notebook val returnData = s"""{\"LakehouseId\": \"${lakehouseId}\", \"SitesStagingTableName\": \"${sitesStagingTableName}\", \"SitesFinalTableName\": \"${sitesFinalTableName}\", \"SitesSnapshotDate\": \"${siteSnapshotDate}\", \"SitesDataExists\": ${siteDataExists}, \"SitesView\": \"${sitesView}\", \"PermissionsStagingTableName\": \"${permissionsStagingTableName}\", \"PermissionsFinalTableName\": \"${permissionsFinalTableName}\", \"PermissionsSnapshotDate\": \"${permissionsSnapshotDate}\", \"EndSnapshotDate\": \"${endTime}\", \"PermissionsDataExists\": ${permissionsDataExists}, \"PermissionsView\": \"${permissionsView}\"}""" println(returnData) mssparkutils.notebook.exit(returnData) This concluding section aggregates the key metadata—including Lakehouse information, table names, snapshot dates, existence flags, and the generated view scripts—into a JSON string. It then exits the notebook by returning that JSON to the pipeline. Notebook 2: Merge Sites and Permissions to Final Table This notebook runs after the Sites and Permissions data from MGDC has been collected successfully into the staging tables. If this is the first collection, it handles them as full datasets, storing the data directly in the final tables. If this is using MGDC for SharePoint delta datasets, it merges the new, updated or deleted objects from the staging tables into the final tables. Note: The word "Delta" here might refer to Delta Parquet (an efficient data storage format used by tables in a Microsoft Fabric Lakehouse) or to the MGDC for SharePoint Delta datasets (how MGDC can return only the objects that are new, updated or deleted between two dates). It can be a bit confusing, so be aware of the two interpretations of the word. Section 0 – Set the Default Lakehouse for Notebook to Run %%configure { "defaultLakehouse": { "name": { "parameterName": "lakehouseName", "defaultValue": "defaultlakehousename" } } } This section uses the same Lakehouse configuration as in Notebook 1. It sets the default Lakehouse through a parameter (lakehouseName) to support dynamic running of the notebook in different environments. Section 1 – Initialize Parameters import java.time.LocalDateTime import java.time.format.DateTimeFormatter import java.time.temporal.ChronoUnit import java.util.UUID import java.text.SimpleDateFormat import java.time.{LocalDate, LocalDateTime, Period} import java.time.format.DateTimeFormatter import java.time.temporal.ChronoUnit import java.util.Calendar val runId = "00000000-0000-0000-0000-000000000000" val workspaceId = spark.conf.get("trident.workspace.id") val workspaceName = "LakeHouseTesting" val lakehouseId = spark.conf.get("trident.lakehouse.id") val lakehouseName = spark.conf.get("trident.lakehouse.name") val sitesStagingTableName = "Sites_Staging" val sitesFinalTableName = "Sites" val permissionsStagingTableName = "Permissions_Staging" val permissionsFinalTableName = "Permissions" spark.conf.set("spark.sql.caseSensitive", true) This section is like Notebook 1’s Section 1 but here lakehouseName is retrieved from the configuration. It initializes variables needed for merging, such as run IDs, workspace/Lakehouse identifiers, and table names. Section 2 – Read Sites Dataset from Staging Table val lakehouse = mssparkutils.lakehouse.get(lakehouseName) val lakehouseId = lakehouse.id val workspaceName = notebookutils.runtime.context("currentWorkspaceName") println("Started reading Sites dataset") val sitesStagingLocation = s"abfss://${workspaceName}@onelake.dfs.fabric.microsoft.com/${lakehouseName}.Lakehouse/Tables/${sitesStagingTableName}" val dfSitesStaging = spark.read.format("delta").load(sitesStagingLocation) println("Completed reading Sites dataset") This section constructs the ABFS path for the Sites staging table and reads the dataset into a DataFrame using the Delta Parquet format. It includes print statements to track progress. Section 3 – Read Permissions Dataset from Staging Table println("Started reading Permissions dataset") val permissionsStagingLocation = s"abfss://${workspaceName}@onelake.dfs.fabric.microsoft.com/${lakehouseName}.Lakehouse/Tables/${permissionsStagingTableName}" val dfPermissionsStaging = spark.read.format("delta").load(permissionsStagingLocation) println("Completed reading Permissions dataset") This section performs the analogous operation for the Permissions staging table, loading the dataset into a DataFrame and providing console output for monitoring. Section 4 – Check Final Tables Exist or Not import io.delta.tables.DeltaTable val sitesFinalLocation = s"abfss://${workspaceName}@onelake.dfs.fabric.microsoft.com/${lakehouseName}.Lakehouse/Tables/${sitesFinalTableName}" val permissionsFinalLocation = s"abfss://${workspaceName}@onelake.dfs.fabric.microsoft.com/${lakehouseName}.Lakehouse/Tables/${permissionsFinalTableName}" val sitesFinalTableExists = DeltaTable.isDeltaTable(spark, sitesFinalLocation) if (!sitesFinalTableExists) { println("Final Sites table not exists. Creating final Sites table with schema only") dfSitesStaging.filter("1=2").write.format("delta").mode("overwrite").save(sitesFinalLocation) println("Final Sites table created") } else { println("Final Sites table exists already") } val permissionsFinalTableExists = DeltaTable.isDeltaTable(spark, permissionsFinalLocation) if (!permissionsFinalTableExists) { println("Final Permissions table not exists. Creating final Permissions table with schema only") dfPermissionsStaging.filter("1=2").write.format("delta").mode("overwrite").save(permissionsFinalLocation) println("Final Permissions table created") } else { println("Final Permissions table exists already") } This section checks whether the final tables for Sites and Permissions exist. If a table does not exist, it creates an empty table (schema only) from the staging DataFrame by filtering out data (filter("1=2")). Section 5 – Merge Sites Data from Staging Table to Final Table import io.delta.tables._ import org.apache.spark.sql.functions._ import org.apache.spark.sql.expressions.{Window, WindowSpec} import org.apache.spark.sql.functions.{coalesce, lit, sum, col, _} import org.apache.spark.sql.types.{StructField, _} import org.apache.spark.sql.{DataFrame, Row, SparkSession} import org.apache.spark.storage.StorageLevel val deltaTableSource = DeltaTable.forPath(spark, sitesStagingLocation) val deltaTableTarget = DeltaTable.forPath(spark, sitesFinalLocation) import spark.implicits._ val dfSource = deltaTableSource.toDF //Delete records that have Operation as Deleted println("Merging Sites dataset from current staging table") deltaTableTarget .as("target") .merge( dfSource.as("source"), "source.Id = target.Id") .whenMatched("source. Operation = 'Deleted'") .delete() .whenMatched("source.Operation != 'Deleted'") .updateAll() .whenNotMatched("source.Operation != 'Deleted'") .insertAll() .execute() println("Merging of Sites dataset completed") This section performs a Delta Lake merge (upsert) operation on the Sites data. The merge logic deletes matching records when the source’s Operation is 'Deleted', updates other matching records, and inserts new records that are not marked as 'Deleted'. Section 6 – Merge Permissions Data from Staging Table to Final Table import io.delta.tables._ import org.apache.spark.sql.functions._ import org.apache.spark.sql.expressions.{Window, WindowSpec} import org.apache.spark.sql.functions.{coalesce, lit, sum, col, _} import org.apache.spark.sql.types.{StructField, _} import org.apache.spark.sql.{DataFrame, Row, SparkSession} import org.apache.spark.storage.StorageLevel val deltaTablePermissionsSource = DeltaTable.forPath(spark, permissionsStagingLocation) val deltaTablePermissionsTarget = DeltaTable.forPath(spark, permissionsFinalLocation) import spark.implicits._ val dfPermissionsSource = deltaTablePermissionsSource.toDF //Delete records that have Operation as Deleted println("Merging Permissions dataset from current staging table") deltaTablePermissionsTarget .as("target") .merge( dfPermissionsSource.as("source"), """source.SiteId = target.SiteId and source.ScopeId = target.ScopeId and source.LinkId = target.LinkId and source.RoleDefinition = target.RoleDefinition and coalesce(source.SharedWith_Name,"") = coalesce(target.SharedWith_Name,"") and coalesce(source.SharedWith_TypeV2,"") = coalesce(target.SharedWith_TypeV2,"") and coalesce(source.SharedWith_Email,"") = coalesce(target.SharedWith_Email,"") and coalesce(source.SharedWith_AADObjectId,"") = coalesce(target.SharedWith_AADObjectId,"") """) .whenMatched("source. Operation = 'Deleted'") .delete() .whenMatched("source.Operation != 'Deleted'") .updateAll() .whenNotMatched("source.Operation != 'Deleted'") .insertAll() .execute() println("Merging of Permissions dataset completed") This section performs a merge operation on the Permissions data. The merge condition is more complex—comparing multiple columns (including handling nulls with coalesce) to identify matching records. The operation applies deletion for rows marked as 'Deleted', updates others, and inserts records where no match exists. Section 7 – Read and Display Sample TOP 10 Rows var sqlQuery = s"SELECT * FROM ${lakehouseName}.${sitesFinalTableName} order by SnapshotDate DESC LIMIT 10" val dfSitesAll = spark.sql(sqlQuery) display(dfSitesAll) sqlQuery = s"SELECT * FROM ${lakehouseName}.${permissionsFinalTableName} order by SnapshotDate DESC LIMIT 10" val dfPermissionsAll = spark.sql(sqlQuery) display(dfPermissionsAll) This final section executes SQL queries to retrieve and display the top 10 rows from both the Sites and Permissions final tables. The rows are ordered by SnapshotDate in descending order. This is typically used for sample or debugging purposes. Conclusion I hope this article helped you understand the notebooks included in the template. This might help you customize it later. These templates are intended as starting points for your work with many scenarios. Read more about MGDC for SharePoint at https://aka.ms/SharePointData.
Build AI-powered apps without creating a vector database
How do you build AI-powered applications that can reason over enterprise content while maintaining security, compliance, and governance? The latest SharePoint Embedded post explores how the https://devblogs.microsoft.com/microsoft365dev/build-ai-powered-apps-without-creating-a-vector-database?utm_source=social-M365dev can make it easier to ground AI experiences in content stored within customers' Microsoft 365 tenants. We also look at the SharePoint Embedded MCP Server (preview), an open-source developer tool that enables AI coding assistants like GitHub Copilot in Visual Studio Code or the CLI, Claude, Cursor, and Azure AI Foundry to help provision, configure, and manage SharePoint Embedded applications using natural language. Together, these capabilities help developers: Ground AI on enterprise content Avoid managing a separate vector database Respect Microsoft 365 security and compliance controls Accelerate development with AI-powered tooling https://devblogs.microsoft.com/microsoft365dev/build-ai-powered-apps-without-creating-a-vector-database?utm_source=social-M365dev to learn how to build the next generation of intelligent, enterprise-ready applications.77Views0likes0CommentsCopilot, Microsoft 365 & Power Platform Community call
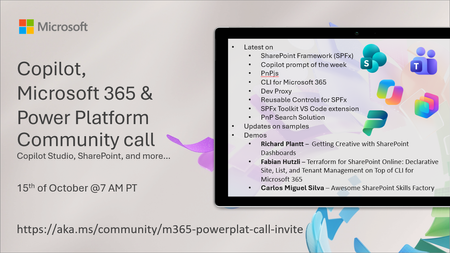
💡 Copilot, Microsoft 365 & Power Platform weekly community call focuses on different use cases and features within the Microsoft 365 and Power Platform - across Microsoft 365 Copilot, Copilot Studio, SharePoint, Power Apps and more. Demos in this call are presented by the community members. 👏 Looking to catch up on the latest news and updates, including cool community demos, this call is for you! 📅 On 15th of October we'll have following agenda: Latest on SharePoint Framework (SPFx) Latest on Copilot prompt of the week PnPjs CLI for Microsoft 365 Dev Proxy Reusable Controls for SPFx SPFx Toolkit VS Code extension PnP Search Solution Demos this time Richard Plantt – Getting Creative with SharePoint Dashboards Fabian Hutzli – Terraform for SharePoint Online: Declarative Site, List, and Tenant Management on Top of CLI for Microsoft 365 Carlos Miguel Silva – Awesome SharePoint Skills Factory 📅 Download recurrent invite from https://aka.ms/community/m365-powerplat-dev-call-invite 📞 & 📺 Join the Microsoft Teams meeting live at https://aka.ms/community/m365-powerplat-dev-call-join 💡 Building something cool for Microsoft 365 or Power Platform (Copilot, SharePoint, Power Apps, etc)? We are always looking for presenters - Volunteer for a community call demo at https://aka.ms/community/request/demo 👋 See you in the call! 📖 Resources: Previous community call recordings and demos from the Microsoft Community Learning YouTube channel at https://aka.ms/community/youtube Microsoft 365 & Power Platform samples from Microsoft and community - https://aka.ms/community/samples Microsoft 365 & Power Platform community details - https://aka.ms/community/home 🧡 Sharing is caring!297Views0likes0CommentsCopilot Extensibility community call - October 2026
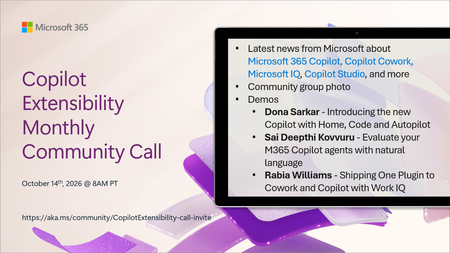
🚀 The Copilot Extensibility Monthly Community Call is a recurring virtual gathering designed to keep the global developer and maker community consistently connected, informed, and engaged with the latest advancements in Microsoft 365 Copilot, Copilot Cowork, Microsoft Scout, GitHub Copilot, Microsoft IQ, etc. and their extensibility ecosystem. 👏 Monthly Wednesday call is for all community members to see Microsoft PMs, engineering and Cloud Advocates showcasing the art of possible with the Microsoft AI technologies. 📅 On the 14th of October we'll have following agenda: News and updates from Microsoft Community group photo Dona Sarkar – Introducing the new Copilot with Home, Code and Autopilot Sai Deepthi Kovvuru - Evaluate your M365 Copilot agents with natural language Rabia Williams - Shipping One Plugin to Cowork and Copilot with Work IQ 📞 & 📺 Join the Microsoft Teams meeting live at https://aka.ms/community/CopilotExtensibility-call-join 🗓️ Download recurrent invite for this weekly call from https://aka.ms/community/CopilotExtensibility-call-invite 👋 See you in the call! 💡 Building something cool with Microsoft AI technologies (Copilot, Cowork, Copilot Studio, Microsoft IQ, etc)? We are always looking for presenters - Volunteer for a community call demo at https://aka.ms/community/request/demo 📖 Resources: Previous community call recordings and demos from the Microsoft Community Learning YouTube channel at https://aka.ms/community/youtube Labs and training material about Microsoft 365 Copilot Extensibility - https://aka.ms/copilotdevcamp Microsoft 365 & Power Platform samples from Microsoft and community - https://aka.ms/community/samples Microsoft 365 & Power Platform community details - https://aka.ms/community/home 🧡 Sharing is caring!495Views0likes0CommentsCopilot, Microsoft 365 & Power Platform product updates call
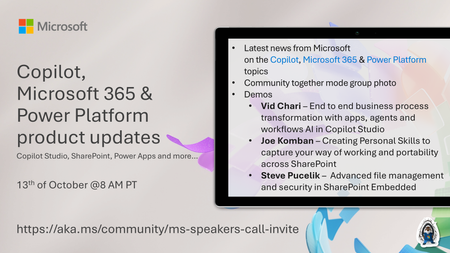
💡Copilot, Microsoft 365 & Power Platform product updates call concentrates on the different use cases and features within the Microsoft 365 and in Power Platform. Call includes topics like Microsoft 365 Copilot, Copilot Studio, Microsoft Teams, Power Platform, Microsoft Graph, Microsoft Viva, Microsoft Search, Microsoft Lists, SharePoint, Power Automate, Power Apps and more. 👏 Weekly Tuesday call is for all community members to see Microsoft PMs, engineering and Cloud Advocates showcasing the art of possible with Microsoft 365 and Power Platform. 📅 On the 13th of October we'll have following agenda: News and updates from Microsoft Together mode group photo Vid Chari – End to end business process transformation with apps, agents and workflows AI in Copilot Studio Joe Komban – Creating Personal Skills to capture your way of working and portability across SharePoint Steve Pucelik – Advanced file management and security in SharePoint Embedded 📞 & 📺 Join the Microsoft Teams meeting live at https://aka.ms/community/ms-speakers-call-join 🗓️ Download recurrent invite for this weekly call from https://aka.ms/community/ms-speakers-call-invite 👋 See you in the call! 💡 Building something cool for Microsoft 365 or Power Platform (Copilot, SharePoint, Power Apps, etc)? We are always looking for presenters - Volunteer for a community call demo at https://aka.ms/community/request/demo 📖 Resources: Previous community call recordings and demos from the Microsoft Community Learning YouTube channel at https://aka.ms/community/youtube Microsoft 365 & Power Platform samples from Microsoft and community - https://aka.ms/community/samples Microsoft 365 & Power Platform community details - https://aka.ms/community/home 🧡 Sharing is caring!223Views0likes0Comments