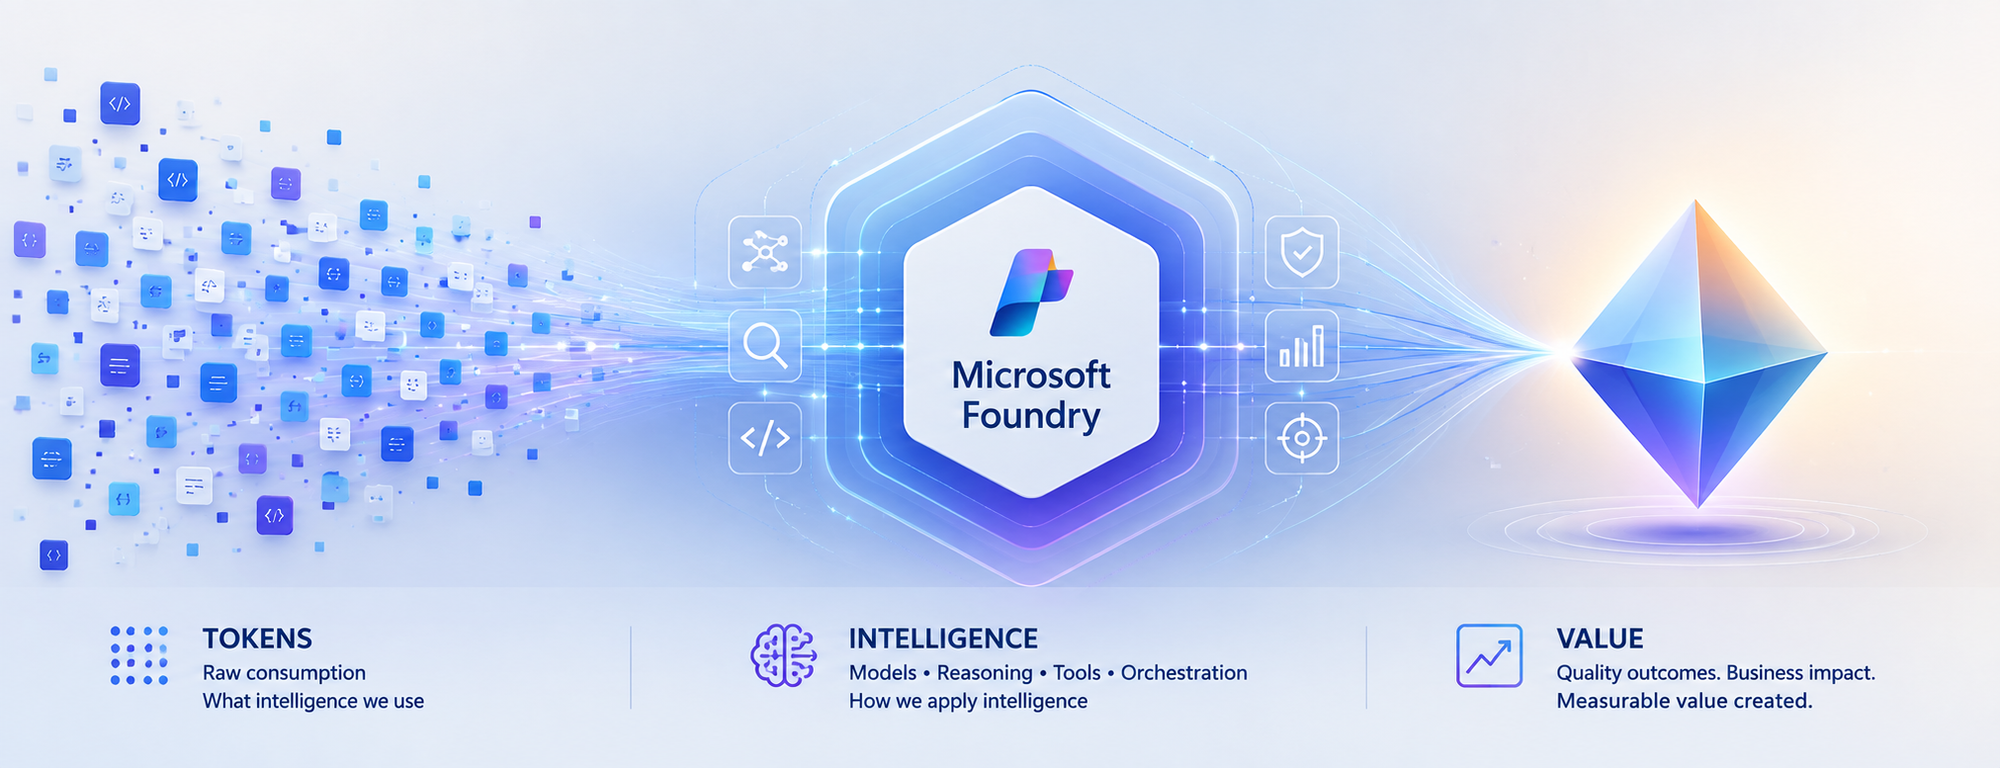
Tokens have become the new unit of AI spend, but they were never the unit of value. This article makes the case for measuring enterprise AI by Cost per Successful Outcome, and shows how Microsoft Foundry and Agent 365 make that shift practical.
Beyond Tokens: Rethinking AI Economics with Microsoft Foundry
From the cost of intelligence to the value of outcomes
Enterprise AI has an accounting problem.
Executives expect agentic AI to return roughly 171% on investment, according to one widely cited survey. Yet McKinsey finds only about 39% of organizations can attribute any earnings impact to AI at all. Both numbers can be true at once — because the gap between them is not a technology gap. It is a measurement gap.
For the first few years of generative AI, one number dominated the economics conversation: tokens. How many tokens did a model consume? What was the cost per million tokens? Could a smaller model perform the same task? Those questions mattered when enterprises were experimenting with AI. They are no longer enough as AI moves into production.
An enterprise agent doesn't simply consume tokens. It reasons, retrieves context, invokes tools, calls APIs, verifies its work, retries unsuccessful actions and sometimes escalates exceptions to humans. The model call might cost pennies. The business outcome could cost considerably more.
Which leads to an increasingly important question: What is the right economic unit for intelligence?
From AI experimentation to economic accountability
The first wave of enterprise AI was about possibility: Can AI do this? The next wave is about production, as AI becomes embedded in software engineering, customer service, finance, healthcare and supply chains.
And production changes the question: Should AI do this and at what cost?
Microsoft has moved decisively onto this ground. In August 2026, the Microsoft Foundry team launched its Economics of Agent Optimization series, arguing that "tokens have become the new unit of technology spend" and that AI should be run as a managed investment system. On the latest earnings call, Satya Nadella described Microsoft's objective as "advancing the frontier on the cost-to-outcome curve, ensuring every customer can turn tokens into business results." The discipline is going mainstream too: 98% of FinOps teams now manage AI spend, up from 31% two years ago.
Microsoft's series is largely about the numerator of that curve - making every request, agent and dollar more efficient. This article is about the denominator: what an outcome is, what it truly costs, and what it is worth.
The evolution of Microsoft Foundry reflects the same shift. At Build 2026, Microsoft expanded the conversation beyond building agents toward tracing behavior, evaluating quality, monitoring production performance, optimizing agents and connecting their operation to ROI. Think of the progression as:
Trace → Evaluate → Monitor → Optimize → ROI
This is more than a technology roadmap. It represents a shift from observing AI as technology to managing AI as an economic asset.
Tokens became the unit of spend. They were never the unit of value.
Consider two AI agents handling the same customer-service workflow. Agent A costs $0.08 per interaction. Agent B costs $0.20.
Agent A appears cheaper. But suppose Agent A successfully resolves only 55% of cases, while Agent B resolves 90%. The remainder require retries, additional reasoning or human intervention. Which agent is actually cheaper? The inexpensive interaction may produce the expensive resolution.
This illustrates a fundamental problem:
We often measure AI where it is consumed rather than where value is created.
Tokens are a unit of consumption. Businesses operate in outcomes. A customer-service leader cares about issues resolved. An engineering leader cares about high-quality software reaching production. A finance leader cares about reconciliations completed accurately. The economic denominator needs to move closer to the business.
The AI Economic Ladder
I think of this evolution as an AI Economic Ladder:
Tokens → Interactions → Tasks → Outcomes → Value
Each step moves measurement closer to what the enterprise actually cares about. At the token level: What intelligence did we consume? At the interaction level: What did each AI run cost? At the task level: What did it cost to complete the work? At the outcome level: What did a successful result cost? At the value level: Was the outcome worth creating?
An AI system can become more efficient at every technical metric while creating little economic value. Conversely, an expensive AI workflow could be extraordinarily valuable if it prevents revenue leakage, reduces operational risk or accelerates a critical business process.
The objective isn't cheaper AI. It is better economics.
Not every completed task is a successful outcome
There is another complication. If an agent completes a workflow, should we count it as a successful outcome? Not necessarily. A meaningful outcome needs three characteristics:
Completed. Quality-gated. Attributable.
It must reach its intended end state, meet an explicit standard for quality, accuracy, safety or business acceptability, and be attributable to the agent or workflow that produced it. That gives us a more meaningful measure:
Cost per Successful Outcome = Fully Loaded AI Workflow Cost / Completed, Quality-Gated, Attributable Outcomes
The denominator becomes real only when named in business language: cost per prior authorization resolved in healthcare, per pull request triaged and tested in engineering, per disputed invoice reconciled in finance operations. If you cannot name the outcome in a sentence the process owner recognizes, you are not ready to measure it.
The quality gate matters. With AI, "the system ran successfully" and "the system produced a good outcome" are not the same thing. Microsoft Foundry's tracing and evaluation capabilities become economically important for precisely this reason.
Evaluation isn't merely quality control. It helps determine what gets counted as value.
What does an AI outcome really cost?
The true economic footprint goes far beyond inference:
Model + Reasoning + Grounding + Tools + Orchestration + Infrastructure + Retries + Evaluation + Governance + Human Intervention
Human intervention is particularly easy to overlook. Every time someone must review, correct, approve or recover an AI-generated outcome, the economics change. The same applies to verification. An agent reaching an acceptable result in three steps has different economics from one requiring fifteen steps and multiple retries.
And verification is not a rounding error — it is the bulk of the bill. McKinsey's 2026 analysis of production agentic workflows found roughly 60% of an agentic task's cost is tied to refining answers — checking, repairing, re-verifying — not generating the initial response. Most of what you pay for is not intelligence. It is assurance.
This means quality and economics are connected.
The quality bar you set influences the cost you pay.
The challenge isn't simply minimizing consumption. It is finding the right balance between quality, cost, speed and risk.
Cost per outcome is only half the equation
Now imagine two agents. Both cost $5 per successful outcome. One saves an employee ten minutes of administrative work. The other prevents $500 in revenue leakage. Their cost efficiency is identical. Their economics clearly aren't.
So we need to move another step up the ladder: from Cost per Outcome to Value per Outcome.
The question isn't only how cheaply AI can complete the work. It is: How much economic value does this outcome create relative to the intelligence required to produce it?
Now the CIO, CFO, CAIO and business leader have a common conversation.
Give every outcome an Intelligence Budget
Not every problem deserves the smartest model available. Classifying an email may require relatively little intelligence. Resolving a complicated customer complaint may justify more context and reasoning. Assessing the risks in a multimillion-dollar contract may justify sophisticated reasoning, multiple validations and human review.
Every business outcome therefore has an economically rational amount of intelligence worth spending on it. Call it an Intelligence Budget.
This changes the architecture question from which model should we standardize on, to: What combination of model, reasoning, context, tools and human judgment does this outcome deserve?
This is where Microsoft Foundry's model router becomes interesting. Individual requests can be dynamically routed so simpler work doesn't consume the same model resources as complex reasoning. If the Intelligence Budget is the economic principle, intelligent routing is one way of operationalizing it.
The future enterprise AI architecture won't be about one model doing everything. It will route intelligence according to the economics, quality and risk of the outcome.
Making AI economics observable
None of this works without visibility. An AI system can be technically healthy and economically unhealthy — responsive and error-free while repeatedly choosing inefficient reasoning paths, invoking unnecessary tools or producing outputs requiring expensive human correction.
AI economics and AI observability are becoming inseparable.
Microsoft Foundry increasingly connects these disciplines. Tracing shows what an agent did. Evaluation determines whether it met required criteria. Observability helps monitor production behavior. Agent optimizer can test improvements across prompts, skills and models. Microsoft's emerging ROI capabilities take the next step by connecting operating costs with measures such as task completion, time saved and cost efficiency.
Attribution is the bridge to the finance conversation. Teams place Azure API Management in front of Foundry endpoints as an AI Gateway, stream token telemetry into Application Insights, and use Entra Agent ID to give every agent run a discrete identity that maps cost to its cost center. Microsoft Agent 365 extends the discipline tenant-wide — spending policies, budget caps and departmental chargeback across Microsoft and third-party agents.
Together, they create something enterprises have historically lacked:
A feedback loop between how intelligence is consumed and what that intelligence accomplishes.
The paradox of cheaper intelligence
There is another reason AI economics will become more important as models get cheaper. The Jevons paradox suggests that when technology makes a resource cheaper and more efficient, total consumption can actually increase. AI may experience the same effect. Cheaper intelligence enables more agents, more reasoning and more workflows that were previously uneconomic.
So we could see cost per unit of intelligence fall while total intelligence consumed rises. Cheaper AI may therefore produce larger AI bills. That isn't necessarily bad — provided value grows faster than consumption. The objective isn't minimum AI consumption. It is maximum economic value from AI consumption.
From workload economics to portfolio economics
As AI scales, economics becomes a capital-allocation question. I see three levels. Workload Economics: Is this AI system running efficiently? Outcome Economics: Is it producing quality outcomes economically? Portfolio Economics: Where should we put our next AI dollar?
That final question will become increasingly important. An enterprise with hundreds of AI initiatives shouldn't assume every one deserves continued investment. Some should scale. Some need optimization. Some should be redesigned or consolidated. And some should be stopped.
The ability to experiment cheaply created the first explosion of enterprise AI. The discipline to allocate capital intelligently will determine what scales.
Who owns AI economics?
Once an agent becomes part of how work gets done, its economics cannot remain purely an IT metric. The business understands the value of the outcome. Technology understands the architecture and optimization levers. Finance brings economic discipline and comparability. That suggests a shared model:
Business owns the outcome. Technology owns the optimization levers. Finance owns the economic discipline.
AI economics ultimately isn't just a technology-cost conversation. It is a business-performance and capital-allocation conversation.
From abundant intelligence to intelligent economics
We are entering an era where intelligence is becoming an increasingly abundant, programmable and variable-cost resource. Microsoft Foundry and the broader Microsoft AI stack are making it easier to build, evaluate, observe, optimize and govern that intelligence.
But abundant intelligence does not guarantee abundant value. Enterprises still need to decide where AI belongs, how much intelligence each problem deserves, what defines a successful outcome, when humans should remain involved and which AI investments deserve more capital.
The winners won't necessarily use the cheapest models. They won't consume the fewest tokens. And they won't be the organizations that build the most agents. They will become exceptionally good at moving up the AI Economic Ladder: from consumption, to outcomes, to value.
Because the next era of AI won't be won by organizations that buy intelligence most cheaply.
It will be won by those that convert intelligence into value most efficiently.
Where to start: the first 90 days
- Define the denominator for your top three agents — what counts as done, what quality gate applies, who signs off.
- Instrument attribution — Azure API Management as an AI Gateway, token telemetry to Application Insights, Entra Agent ID on every run.
- Wire evaluations into the cost pipeline so only quality-gated outcomes count.
- Set Intelligence Budgets — model router per request, agent optimizer against your evaluators, Agent 365 policies as circuit breakers.
- Stand up a joint monthly review — business, technology and finance on one dashboard: outcomes delivered, cost per outcome, value per outcome.
Frequently asked questions
What is Cost per Successful Outcome in enterprise AI? The fully loaded cost of an AI workload divided by outputs that were completed, quality-gated and attributable - for example, cost per prior authorization resolved or per pull request triaged. It turns token metrics into the unit economics of AI-performed work.
What is an Intelligence Budget? The economically rational amount of intelligence - model capability, reasoning, context, tools and human review — worth spending on a given outcome, based on its value and risk. Model router in Microsoft Foundry is one way to operationalize it.
Why do AI agents cost more than single model calls? One agent task can involve planning, tool calls, retries and verification - many model calls with compounding context. Research on production agentic workflows attributes roughly 60% of task cost to refining and verifying answers, not generating the first response.
Will falling model prices make AI cost management unnecessary? No. By the Jevons paradox, cheaper intelligence expands consumption, so total AI spend typically rises as unit prices fall. The discipline that matters is maximizing value per unit of intelligence.
Who should own AI economics? A shared model: the business owns the outcome and its value, technology owns the optimization levers, and finance owns the economic discipline and review cadence.
#MicrosoftFoundry #Agent365 #AzureAI #FinOps #AgenticAI #AIAgents #Azure #MicrosoftCostManagement #AIEconomics #Tokens
References
- Microsoft Azure Blog: "The Economics of Agent Optimization: From pilots to measurable returns" (August 12, 2026)
- Microsoft FY26 Q4 earnings call (Satya Nadella, July 2026)
- McKinsey — "Cost versus value: managing agentic AI system performance" (July 2026)
- FinOps Foundation — State of FinOps 2026;
- Microsoft Learn — Model router for Microsoft Foundry; Agent optimizer; Foundry Control Plane cost optimization

