troubleshooting
786 TopicsAzure SQL Data Sync After a Database Restore: Troubleshooting Leftover Sync Metadata
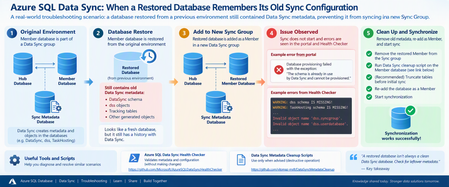
Recently, I worked on an interesting Azure SQL Data Sync issue that I thought was worth sharing with the community. The scenario looked straightforward at first: a database had been restored from another environment and was being configured as a Member database in a new Data Sync group. However, synchronization wasn't working as expected. The interesting part was not the new Sync Group itself. It was what the restored database had brought with it from its previous Data Sync configuration. The scenario The Member database was a restored copy of a database that had previously participated in another Azure SQL Data Sync group. After the restored database was configured as a Member in the new environment, synchronization wasn't working as expected. During troubleshooting, another important clue emerged. The restored database still had a history with Azure SQL Data Sync, so we needed to determine whether metadata and generated objects from its previous configuration were still present. This became one of the key areas of the investigation. Understand the Data Sync architecture first Before jumping into scripts, it's important to clearly distinguish the three database roles involved in Azure SQL Data Sync: Hub Database: The central database containing the application data being synchronized. Member Database: A database that synchronizes with the Hub. Sync Metadata Database: A separate Azure SQL Database containing Data Sync metadata and logs. Microsoft's documentation explains that Data Sync follows a hub-and-spoke topology and that the Sync Metadata Database contains Data Sync metadata and logs. This distinction became particularly important during this investigation because the initial diagnostic configuration wasn't pointing to the expected Sync Metadata Database. Troubleshooting approach Here is the troubleshooting flow we followed. Step 1: Run the Azure SQL Data Sync Health Checker One of the first tools I recommend for this type of investigation is the public Azure SQL Data Sync Health Checker: Azure SQL Data Sync Health Checker on GitHub [github.com] The tool validates whether metadata associated with the Hub and Member is in place and compares the scopes against information in the Sync Metadata Database. Importantly, the Health Checker repository states that it performs validation without changing Data Sync or user objects. The tool requires the relevant connection details for: Sync Metadata Database Hub Database Member Database The GitHub repository contains the current script and execution instructions. What we observed In our investigation, the initial Health Checker output included messages similar to: WARNING: dss schema IS MISSING! WARNING: TaskHosting schema IS MISSING! Invalid object name 'dss.syncgroup'. Invalid object name 'dss.userdatabase'. Those errors were important clues, but they needed to be interpreted together with the database roles. Microsoft's documentation states that the DataSync schema is used for system-created objects in Hub and Member databases, while the dss and TaskHosting schemas are used for system-created objects in the Sync Metadata Database. That distinction helped us recognize that we first needed to validate which database was actually being supplied to the Health Checker as the Sync Metadata Database. Lesson learned Before treating a missing dss or TaskHosting schema as corruption, first make sure you're actually connected to the Sync Metadata Database. That simple validation can save a lot of investigation time. Step 2: Check the Member database for Data Sync artifacts Once we had clarified the topology, the investigation moved to the restored Member database. Because this database had previously participated in Data Sync, we wanted to understand what Data Sync objects were still present. One of the queries used during troubleshooting was: SELECT name FROM sys.tables WHERE SCHEMA_NAME(schema_id) = 'DataSync' AND name NOT LIKE '%_tracking%'; We also inspected: SELECT * FROM DataSync.schema_info_dss; And, when checking the Member database's Data Sync scope information: SELECT * FROM DataSync.scope_info_dss; These checks helped us understand the Data Sync metadata state of the restored Member database and whether it still contained artifacts associated with its previous configuration. Why this matters Microsoft's current Data Sync best-practices documentation confirms that the DataSync schema is used for system-created objects in Hub and Member databases. So, when investigating a database restored from an environment where it previously participated in Data Sync, the DataSync schema is an important part of the investigation. Step 3: Consider the history of the restored database This was really the turning point in the investigation. Instead of treating the database simply as a "new Member", we started looking at it as: A restored database that had previously been provisioned for another Data Sync configuration. That's an important difference. When troubleshooting a restored database, ask early: Was this database previously part of another Azure SQL Data Sync group? If the answer is yes, the database's previous Data Sync state should be considered during the investigation. Step 4: Remove the Member before cleanup In our scenario, the remediation sequence was essentially: Remove the restored database from the current Sync Group. Clean up the previous Data Sync metadata from the restored Member database. Re-add the database as a Member. Trigger synchronization again. For the cleanup portion, we used the following publicly available repository: SQL Data Sync Cleanup Scripts on GitHub [github.com] The repository contains several scripts for different purposes, including: Data Sync complete cleanup.sql Data Sync cleanup hub or member.sql cleanup data sync object V2.sql The specific complete-cleanup script is available here: Data Sync complete cleanup.sql Important warning about the cleanup script Please do not treat this as a general-purpose Data Sync troubleshooting script. The script itself contains a very clear warning. It immediately cleans Data Sync-related objects associated with the database and says it should be used only for the scenarios specified in the script, including when advised by the support team during a support request. The repository also explains the different purposes of its cleanup scripts. For example, the complete-cleanup script has more restrictive usage guidance, while the Hub/Member cleanup and object cleanup scripts target different scenarios. My recommendation: use the Health Checker and read-only diagnostic queries first. Do not jump directly to metadata cleanup without understanding the database topology and existing Data Sync configuration. Step 5: Validate with one table After cleaning up the previous Data Sync artifacts, we didn't immediately assume that everything was resolved. Instead, we validated with a controlled test. A test table on the Member side was truncated, the synchronization was started again, and the table began synchronizing successfully. That provided the confirmation we needed that the previous Data Sync state of the restored Member was an important part of the issue. Root cause The troubleshooting pointed to the fact that the restored Member database had previously participated in another Data Sync configuration and retained Data Sync-related metadata/artifacts from that previous state. After cleaning up the old Data Sync state and reprovisioning the restored database as a Member, synchronization was successfully validated again. The important lesson for me wasn't simply the cleanup itself. It was recognizing that restoring a database does not necessarily mean you're starting with a clean Data Sync state. A practical troubleshooting flow For similar scenarios, I would approach the investigation in this order: Confirm the architecture Identify the: Hub Database Member Database Sync Metadata Database Run the Health Checker Use: Microsoft Azure SQL Data Sync Health Checker [github.com] Review its output before making changes. Inspect the restored Member Check whether Data Sync-related objects exist: SELECT name FROM sys.tables WHERE SCHEMA_NAME(schema_id) = 'DataSync' AND name NOT LIKE '%_tracking%'; Then, where applicable to the database's current state, inspect: SELECT * FROM DataSync.schema_info_dss; and: SELECT * FROM DataSync.scope_info_dss; Ask about the database history Was the database: restored from another environment? previously a Data Sync Member? previously associated with another Sync Group? That historical context can completely change the direction of the investigation. Consider cleanup only after understanding the environment The public cleanup scripts are available here: SQL Data Sync Cleanup Scripts [github.com] These scripts make changes to Data Sync objects and should not be the first troubleshooting step. Validate using a controlled test Once the environment has been correctly cleaned/reconfigured, validate synchronization on a controlled scope before assuming the entire configuration is healthy. My key takeaways This troubleshooting experience reinforced a few lessons for me. A restored database isn't necessarily a clean Data Sync database Restoring the application data doesn't mean you should ignore the database's previous synchronization configuration. Always distinguish Hub, Member, and Sync Metadata databases This is especially important when interpreting Health Checker output. The DataSync schema is associated with system-created objects in Hub and Member databases, while dss and TaskHosting are associated with system-created objects in the Sync Metadata Database. Use diagnostics before cleanup The Azure SQL Data Sync Health Checker is designed to validate Data Sync metadata and objects without making changes. That makes it a much better starting point than immediately removing objects. Database history matters One of my favorite questions after this investigation is now: "Was this database ever part of another Data Sync Group?" It's a simple question, but in restore or copy scenarios it can reveal an important part of the troubleshooting story. Be very careful with metadata cleanup The public cleanup repository itself provides specific guidance about when each script should be used, and the complete-cleanup script includes an explicit warning before execution. Always understand the environment and protect your data before performing destructive operations. One more important consideration: SQL Data Sync retirement There is also an important longer-term architecture consideration. Microsoft currently documents that SQL Data Sync retires on September 30, 2027. Existing Sync Groups can continue operating until the retirement date, but Microsoft recommends migrating to alternative data replication and synchronization solutions before then. So, while troubleshooting existing Data Sync environments remains necessary, organizations using the service should also begin considering their migration strategy. References and useful tools Microsoft documentation Best practices for Azure SQL Data Sync [learn.microsoft.com] Troubleshooting tools Azure SQL Data Sync Health Checker [github.com] SQL Data Sync Metadata Cleanup repository [github.com] Data Sync complete cleanup.sqlRegistry Inventory in Microsoft Intune: Verifying What’s on Your Devices
By: Madison Cooks, Product Manager | Microsoft Intune IT admins need a reliable way to confirm how Windows devices are configured, especially when troubleshooting, validating compliance, or investigating security posture. Policy assignment alone doesn’t always show what’s present on the device and getting registry visibility at scale has often required custom discovery or remediation scripts that take time to build, test, and maintain. With Microsoft Intune’s July (2607) release, device inventory will include Windows registry data, helping IT admins verify a device’s actual configuration, not just the policy assigned. With a new Device inventory property for registry keys, you define the keys you care about in the properties catalog, and Intune collects them for you. There’s no collection logic to build or keep running. This makes registry-based configuration checks easier to operationalize across managed Windows devices, so teams can spend less time maintaining scripts and more time acting on the data. Figure 1: Microsoft Intune device inventory profile creation screen showing the Properties picker with the Registry category selected for inventory data collection. What registry data you collect Registry data collection is configured through the existing properties catalog. For each entry, provide a registry key path and, when needed, a value name. For every targeted device, the device agent attempts collection and reports: Registry key path Value name Value type Value data Microsoft Intune device inventory profile configuration page showing registry key collection settings, including registry path, collection pattern options, and value name fields. The initial release supports the following collection patterns designed for common admin scenarios that use HKEY_LOCAL_MACHINE (HKLM) paths. Single value Specify a registry path and value name to collect one value from that path. For example, collect Secure Boot certificate servicing status from HKLM\SYSTEM\CurrentControlSet\Control\SecureBoot by using values such as UEFICA2023Status, UEFICA2023Error, or UEFICA2023ErrorEvent. All values under a path, non-recursive Specify a registry path to collect all values directly under that path. This pattern doesn't include subkeys. For example, collect values directly under a Windows Update configuration path to help validate expected settings. Same value across subkeys Specify a base registry key path and a value name to collect that value from each immediate subkey. For example, collect DHCP status across network interface subkeys under HKLM\SYSTEM\CurrentControlSet\Services\Tcpip\Parameters\Interfaces. Where registry inventory data appears After collection, registry inventory data will be available in Device inventory at initial release. We’ll expand access to registry data in the coming months, including support in additional reporting and exploration experiences. Microsoft Intune Device Inventory page displaying collected Windows registry data for a device, including registry key paths, values, collection status, and timestamps. This makes registry data available alongside other inventory signals, so admins can use familiar tools to investigate configuration, validate device state, and support troubleshooting without building separate collection scripts. How admins use this You can collect registry data and view it per device in Device inventory - a verified record of each endpoint’s actual configuration and a key source of settings data on each endpoint. This helps answer questions like: Is a setting actually enabled on the device? Which app, version, or configuration is installed? Did a policy apply correctly? Why is this device behaving differently from the rest? Registry data collection in Device inventory is included with Microsoft Intune Plan 1. Collection results and limits If a registry value exists but doesn’t contain data, collection succeeds and the value appears as empty. If the registry path or value name doesn’t exist on a device, that device reports Not found for the collection result. Collection continues for all other devices, so one missing value won’t block results from devices where the value exists. Registry inventory includes safeguards to keep collection focused and manageable. Each collected registry value is capped at 6 KB, and each device can collect up to 100 registry keys. If a value or device exceeds these limits, collection skips the excess data and reports the applicable result for that device. These limits help manage data volume, maintain service performance, and reduce the risk of over-collection. Registry inventory is designed for configuration visibility and troubleshooting, not for collecting sensitive or confidential data. Built-in heuristic detection helps identify and prevent ingestion of values that may contain secrets, credentials, authentication tokens, certificates, private keys, connection strings, or other data that could grant access if exposed. If a value is flagged as potentially sensitive, it isn’t collected. Collection is limited to HKEY_LOCAL_MACHINE (HKLM) paths. This keeps inventory focused on device-level configuration and avoids user-specific registry contexts. Summary Registry inventory in Microsoft Intune helps admins collect Windows registry data in a native, declarative way. Instead of maintaining custom scripts for common inventory scenarios, admins can configure registry collection in the properties catalog and query the results through familiar Intune reporting experiences. Use registry inventory for configuration visibility and troubleshooting across managed Windows devices. As you plan your collection strategy, focus on device-level HKLM data, avoid sensitive values, and remember collection limits to keep inventory targeted and manageable. If you have any feedback or questions, leave a comment below or reach out to us on X @IntuneSuppTeam.18KViews3likes16Comments
How does ERP MCP determine F&O environment?
How does the Dynamics 365 ERP MCP Server determine the target Finance & Operations environment when multiple environments (SIT, UAT, and Production) have MCP enabled? In Copilot Studio, the MCP connection only shows the authenticated user and does not expose any environment selection or environment identifier. Is the target F&O environment determined by the underlying Power Platform connection, the MCP client registration, a connection reference, or another routing mechanism? How can administrators verify which F&O environment an MCP-enabled agent is actually connected to?71Views0likes1CommentAccess Issue: Copilot Agent Kit for Makers, Users cant access through Microsoft security group
Copilot Agent Kit for Makers where users granted access through a Microsoft security group can access the application, but cannot see your organization's custom templates within the Agent Library. If i individually assign the user then they are able to see it. Few more things Both the security group and individually assigned users have the Basic User and CSK - Maker roles. The issue occurs when access is provided through the security group, while direct user assignment works. The same security group works as expected for access to the customer's Copilot Studio agents.39Views0likes0Comments
Issue with Copilot
Issue Report: Plotting Engine Fails to Generate Charts Summary The chart‑generation feature in Copilot intermittently fails to produce output. When requesting visualizations such as radar charts, bar charts, histograms, or other plotted graphics, Copilot often returns an empty result with no error message or explanation. Observed Behavior Requests for plotted charts sometimes return "" (empty output). No error message is provided, making troubleshooting impossible. The failure occurs even with simple, valid datasets and straightforward instructions. Conceptual or AI‑generated diagrams work consistently; only plotted charts fail. Expected Behavior Copilot should reliably generate charts when provided valid data and instructions, or provide a clear error message if the request cannot be completed. Impact This issue prevents users from visualizing structured datasets and reduces confidence in Copilot’s ability to produce quantitative graphics. It also forces users to retry multiple times or switch to non‑chart visualizations. Request Please investigate the stability of the chart‑generation environment, particularly around sandbox execution and rendering reliability. Adding explicit error messages when chart generation fails would also significantly improve usability.126Views0likes1CommentLessons Learned #555: The First 60 Seconds of a Production Incident: Stop, Scope, Correlate
When a critical production incident starts, the first message we often receive is something like: “The database is down.” At that moment, everything suddenly becomes urgent. Engineers open monitoring dashboards. Someone starts checking logs. Another person reviews CPU and memory. Someone else asks whether there was a deployment. Connections are tested. Metrics are queried. Teams are contacted. All of these actions may eventually be necessary. But there is a more important question to answer first: What exactly does “down” mean? After working on many production incidents, one lesson becomes increasingly clear: The first 60 seconds are not about solving the incident. They are about defining the incident. A vague problem description can send troubleshooting in many different directions. A precise problem statement dramatically reduces the investigation space. This article describes a simple approach that can be applied during the first moments of an incident: Stop. Scope. Correlate. 1. Stop: Define What “Down” Actually Means The first mistake during many incidents is assuming that everyone understands the problem in the same way. Consider the statement: “The database is unavailable.” That statement could mean many different things: Applications cannot establish new connections. Existing connections are still working, but new connections fail. Queries are timing out. A specific login cannot authenticate. One database is inaccessible. One application is failing while other applications work correctly. Performance degradation makes the service appear unavailable. The application returns HTTP 500 errors, but the database itself is healthy. Connections fail intermittently. A failover is occurring. DNS or networking issues prevent the application from reaching the database. These scenarios require completely different investigation paths. Before opening ten different tools, try to transform the original statement into something more specific. For example: Instead of: “The database is down.” Try to reach something like: “Since approximately 14:32 UTC, new application connections to Database A have intermittently failed with login errors, while existing sessions remain active.” Now we have something we can investigate. The problem statement contains: a timestamp, a specific database, a specific symptom, affected connection behavior, and an indication that the issue may be intermittent. That is already much more valuable than the original alert. 2. Scope: Determine the Blast Radius Once we understand the symptom, the next question is: Who or what is affected? This is sometimes called determining the blast radius. The scope can immediately eliminate entire categories of possible causes. Ask questions such as: Is one user affected or every user? Is one application affected or several applications? Is one database affected or all databases? Are all connection types affected? Are existing connections healthy while new connections fail? Are only specific clients or drivers affected? Imagine the following situation. Application A reports database connectivity failures. However: Application B connects successfully. SSMS connects successfully. Azure metrics show the database is available. Existing sessions continue executing queries. This changes the investigation dramatically. The problem may not be: “Azure SQL is unavailable.” It may instead be: “Application A cannot establish new connections.” That distinction is extremely important. A large percentage of troubleshooting time can be saved simply by identifying the correct scope early. 3. Build the Timeline The next critical dimension is time. During an incident, timestamps are evidence. Ask: When did the issue start? Is there an exact timestamp? How long did it last? Is the issue continuous or intermittent? Did the problem recover automatically? Did the issue occur once or multiple times? Was there another event immediately before the problem? A good incident timeline may look like this: 14:31:52 UTC – Application operating normally 14:32:08 UTC – First connection error reported 14:32:10 UTC – Database failover detected 14:32:14 UTC – Additional login failures 14:32:18 UTC – New connections begin succeeding 14:32:20 UTC – Application fully recovere Now the investigation is no longer based on assumptions. We have a five-to-ten-second window that can be correlated with platform telemetry, database events, application logs, networking information, and deployment history. Without the timeline, engineers may analyze hours of logs. With the timeline, the investigation becomes focused. 4. Correlate Before Changing Anything The next step is correlation. Once we understand the symptom, scope, and timeline, we can ask: What changed at the same time? Useful correlation sources may include: application deployments, infrastructure changes, configuration changes, database failovers, scaling operations, maintenance events, firewall changes, authentication changes, networking events, DNS changes, resource utilization, query regressions, blocking, deadlocks, connection pool behavior, driver updates, platform events. etc The key word here is correlation. It is tempting during an incident to immediately change something. For example: restart the application, restart a service, scale the database, clear the connection pool, change configuration, rebuild an index, modify a query, fail over manually. Sometimes these actions are necessary. But every change also modifies the evidence. A restart may restore the service while simultaneously removing valuable diagnostic information. Whenever possible: Collect evidence before changing the environment. 5. Use Multiple Sources of Evidence Production incidents rarely provide the complete answer in one telemetry source. A better approach is to correlate multiple sources. For a database-related incident, we may investigate: Application telemetry Application logs may reveal: connection failures, authentication errors, request latency, retry attempts, timeout exceptions, HTTP errors, dependency failures. Platform metrics Cloud metrics may help determine: service availability, CPU utilization, storage pressure, connection count, throttling, resource saturation. Database telemetry Database-level information may include: active sessions, waits, blocking, query performance, login failures, failover events, resource statistics. Query Store For performance incidents, Query Store can be extremely valuable. It may help identify: query regressions, plan changes, increased execution duration, abnormal CPU consumption, changes in execution frequency. Deployment history Always ask: What changed recently? Many incidents have a strong temporal relationship with: application deployments, schema changes, configuration modifications, infrastructure updates, new releases, security changes. The goal is not to assume that the most recent change caused the incident. The goal is to determine whether the events correlate. 6. Avoid Starting With a Tool One common troubleshooting pattern is: “Open the monitoring portal.” or: “Run this query.” or: “Check this log.” Tools are essential, but tools should follow the investigation strategy. The investigation should determine which tool we need. Not the other way around. If the problem is authentication, the investigation path may focus on: login errors, authentication configuration, identity providers, user mappings, connection strings. If the problem is performance, the investigation may focus on: Query Store, waits, blocking, execution plans, resource utilization. If the problem is connectivity, we may investigate: DNS, network paths, firewalls, drivers, retries, connection pools. A clear problem definition tells us where to look. 7. Ask the Same Questions Every Time One of the most effective improvements teams can make is standardizing the first questions asked during incidents. A simple initial checklist could be: Symptom: What exactly is failing? Scope: Who or what is affected? Timeline: When did it start? Error: What exact error message or error code is being returned? Frequency: Is the issue continuous, intermittent, or already recovered? Changes: What changed immediately before the incident? Evidence : Which telemetry sources can confirm the behavior? These questions are intentionally simple. During a high-severity incident, simplicity is valuable. 8. The First 60 Seconds Framework We can summarize the approach in four steps. 1. Define: What does the reported symptom actually mean? 2. Scope: Determine the blast radius. 3. Timeline: Identify exactly when the problem occurred. 4. Correlate Connect the symptom with telemetry, events, and recent changes. Only after these steps should we decide the deeper troubleshooting path. 9. Speed Is Important, but Direction Is More Important During critical incidents, teams naturally want to move quickly. That is the correct instinct. But speed without direction can create noise. Ten engineers investigating ten different theories at the same time may generate enormous activity without producing clarity. A well-defined incident allows teams to divide the investigation intelligently. For example: One engineer investigates application telemetry. Another checks database telemetry. Another reviews platform events. Another investigates recent deployments. Another builds the incident timeline. All of them are now investigating the same defined problem. That is very different from everyone independently trying to determine what the problem might be.
Which Accessible Source Can Reliably Return Current Date, Time, Timezone and UTC Offset?
Question for Microsoft 365 Copilot experts I am trying to implement a reliable "Current Time Validation" control inside a Microsoft 365 Copilot workflow. The requirement is to obtain a machine-readable and repeatable timestamp containing: - Current date - Current time - Time zone identifier - UTC offset For example: 2026-09-16T18:09:00+08:00 Timezone: Asia/Shanghai UTC Offset: +08:00 My goal is not a human-readable world clock page, but a source that Microsoft 365 Copilot can actually access and consume reliably during execution. Business context: The timestamp is used as a mandatory validation gate before generating operational reports. If the timestamp is wrong, downstream conclusions may become invalid because greetings, operating-hours logic, OOO/PTO analysis, and action ownership are all time-dependent. Problems encountered so far I have already tested several approaches and found multiple reliability issues: 1. Conversation context is not a reliable clock source. Copilot may retain or reuse a timestamp from the beginning of a conversation rather than reflecting the actual current time. 2. External "current time" web pages are problematic. Some sites appear to return cached/indexed content when accessed through Copilot, producing timestamps that are clearly inconsistent with real-world elapsed time. 3. Human-readable sources are insufficient. I need a source that returns structured data which can be validated programmatically. 4. Timezone information alone is not enough. The solution must provide: - current date - current time - timezone identifier - UTC offset 5. The source must be repeatable. Two consecutive queries should return updated timestamps reflecting actual elapsed time. Questions 1. Among the data sources that Microsoft 365 Copilot can realistically access today, which source can provide: - date - time - timezone - UTC offset in a machine-readable format? 2. Is there any Microsoft-native source (Microsoft Graph, Outlook, Exchange Online, mailbox settings, tenant settings, calendar services, etc.) that exposes this information directly? 3. Which source would be considered the most reliable and repeatable for workflow-validation purposes? 4. Has anyone implemented a trusted "current time authority" pattern for Microsoft 365 Copilot or Copilot Studio agents? 5. Does Microsoft 365 Copilot have access to a real-time clock source that is guaranteed to be refreshed at query time rather than returning indexed or cached timestamp information? The objective is to establish a trusted and auditable timestamp before generating business reports, task summaries, or workflow decisions. Thanks in advance.43Views0likes0Comments