troubleshooting
790 TopicsLessons Learned #560: SQL Is Slow — What Can Query Store and SSMS Copilot Uncover?
In our recently delivered session, “SQL Is Slow — What Can Query Store and SSMS Copilot Uncover?”, we demonstrated step by step how to investigate a performance problem by combining Query Store with Copilot’s capabilities in SSMS. The demonstration starts with a PHP program executing queries while we grow a table from a few hundred to millions of rows. As different execution plans appear and performance changes, we follow the evidence in Query Store to uncover what is happening and decide what to investigate next. One clue stood out. The query took about 12 milliseconds per execution in one interval and almost 2.5 seconds in another interval under the same Plan ID. Other plans appeared during the complete lab. Understanding both the differences between plans and the changes within a plan became part of the investigation. Along the way, we demonstrated how a guided conversation with Copilot can become an Agent investigation, and how the investigation itself can be captured in a reusable skill. The useful result was a method that keeps asking for evidence before accepting an explanation. The session brings the two tools together: Query Store supplies the recorded history, and Copilot helps us examine it and decide what to investigate next. The same troubleshooting story lets the audience follow Ask mode, Agent mode and the reusable skill without losing the connection to the underlying SQL evidence. A growing table and several execution plans For our sessions, we use a PHP program that generates 16 different simulations of performance and connectivity problems, allowing us to demonstrate how to investigate these scenarios through practical demos. We also have code developed in .NET and Java. In this demonstration, we add records to dbo.Notes in stages, reaching approximately 200, 32,000, 65,000, 2 million, and 4 million rows, while the PHP program executes dbo.GiveNotes with different @N values. This lets us observe how performance and execution plans evolve as the data volume grows. Several execution plans accumulated during the complete demonstration. We compared all of them, then inspected the runtime intervals within each Plan ID. The reference run revealed this change within the history of one plan: Average per execution Healthy interval Degraded interval Approximate increase CPU 7.69 ms 1,443.19 ms 188 times Duration 12.39 ms 2,473.68 ms 200 times Logical reads 68.39 12,233.10 179 times The duration increase was approximately 200 times. This comparison covers two intervals for one Plan ID, not the whole sequence of table sizes. It does not assign a particular plan or timing to each row-count stage. These are lab observations; identifiers and timings vary between runs. The reads were particularly revealing. Each execution was touching far more pages. A later plan change could not, by itself, explain degradation that had already started while the earlier plan remained in use. The next step was to investigate what had increased the work per execution. Build the timeline before choosing the explanation We first compared workload contributors using total CPU, elapsed duration, logical reads and execution count. Total consumption identified where the workload impact was concentrated; averages per execution helped distinguish expensive executions from a high volume of individually inexpensive calls. Next, we collected every plan for the selected query and compared runtime intervals chronologically. We discovered the identifiers from the database instead of supplying fixed Query IDs or Plan IDs. We asked both when another plan appeared and whether the cost had already increased before that change. A plan summary alone can hide this story. One average across a plan’s entire history blends its healthy and degraded periods. The interval history shows when the work changed and whether that happened before another plan appeared. Aggregation mattered. When combining runtime statistics, we weighted each average by its execution count. A simple average of interval averages would give a lightly used interval the same influence as a heavily used one. We also kept units explicit and separated execution types where needed. Weighted average = SUM(average value * execution count) / SUM(execution count) The increase in logical reads directed the investigation toward the amount of data processed and the access path. Waits could help explain elapsed time, but waits alone would not explain that increase in reads. dbo.GiveNotes filtered dbo.Notes on ID < @N and grouped by Name. The clustered primary key was on id2, a different column from the predicate. As rows were added, a reused plan could process more data; changing @N could also change how many rows qualified. A new Plan ID was a separate event to investigate, not an explanation to assume. Different @N values can qualify different numbers of rows, and table growth can increase the work even with an unchanged plan. We inspected distribution, statistics and access paths to test that explanation. Query Store interval averages alone do not tell us the parameter used by every execution, and parameter-sensitive behavior does not automatically prove parameter sniffing. One investigation through three Copilot experiences In Ask mode, we guided the conversation one question at a time. We first requested the Query Store overview, then asked which contributor to investigate and how its plans behaved over time. The staged prompts delayed statistics, index and parameter analysis until the runtime evidence justified those questions. Where required, we ran generated diagnostic T-SQL and brought the results back into the conversation. In Agent mode, we supplied the investigation goal and allowed Copilot to choose and execute diagnostic steps using the available SQL tools. We reviewed the proposed actions and kept the investigation read-only. The agent could use each result to decide what to inspect next. Finally, we captured the sequence in an Agent Skill. We wanted the next investigation to preserve the critical question: did the query become more expensive while the same plan was still being reused? Agent Skills provide task-specific instructions that Copilot can discover and use in Agent mode. We also demonstrated the reusable method through GitHub Copilot CLI. Database execution still requires a configured SQL tool or MCP server; without that capability, the workflow must generate diagnostics for the engineer to run. What we put into the reusable skill The SQL Performance Investigator pack captures the diagnostic sequence alongside the calculation rules and starting prompts. The agent is instructed to: Identify the main workload contributor and retain its Query ID. Collect all associated plans and their runtime history. Check whether degradation began while the same plan remained in use. Investigate relevant selectivity, statistics and index evidence. Separate confirmed observations from hypotheses and propose validation. A skill makes the method reusable; it does not guarantee the diagnosis is correct. Missing history, incorrect aggregation or a plausible but unsupported inference still need an engineer’s attention. We kept discovery read-only, with SQL permissions enforcing the access boundary. A proposed index still needs evidence of improvement In the demonstration, we evaluated an index with ID as its leading key and Name as an included column: CREATE NONCLUSTERED INDEX NOTES_IX1 ON dbo.Notes (ID) INCLUDE (Name); The key matches the range predicate, while the included column makes Name available for the aggregation. Whether this improves the workload depends on selectivity, data volume and the competing plans. Its storage and write costs also matter. We treated this as a remediation candidate. Validation requires a comparable workload, including parameter distribution and concurrency, followed by a Query Store comparison of reads, CPU, duration and variability. We did not equate an index recommendation with a demonstrated improvement. Statistics also need careful interpretation. An index histogram describes its leading key; adding Name as an INCLUDE column does not create a histogram on Name. An existing auto-created statistic should not be dropped merely because its column appears in a covering index. The lesson we took from the demonstration The complete story contained a growing table and multiple plans. Within that history, one plan became much more expensive before a later plan could explain the change. Comparing plans and examining changes within each plan gave us complementary evidence. Copilot helped us follow it, and the skill preserved the investigation sequence for another database. We enjoyed presenting this session. For DBAs, developers and support engineers, the session offers a practical way to watch a performance investigation unfold, from the PHP workload and Query Store history to the prompts and reusable skill. We look forward to continuing this demonstration and discussion with SQL user groups and the wider technical community. If you have encountered a query that became slower while the same plan remained in use, which evidence helped you explain the change? We would be interested to hear how you approached it. References and prerequisites For the SSMS Agent and Skills experience described here, Microsoft documents SSMS 22.7 or later with the AI Assistance workload and GitHub Copilot access. Query Store must be enabled with relevant history available. Specify the target server and database in the Agent prompt rather than relying on the active editor context. Check the current documentation before reproducing the session. GitHub Copilot Agent mode in SSMS Agent Skills in SSMS Monitoring performance by using Query Store Query Store runtime statistics Try the investigation with our prompts These prompts offer a practical starting point for the method demonstrated in our session. The Ask prompt is the opening prompt from our session workflow. The Agent prompts are adapted from our accompanying pack to make the target server, database and investigation window explicit. Replace the angle-bracket placeholders before submitting them. Start with Ask mode We began with a request for evidence, deliberately postponing diagnosis. Run the generated diagnostic query against the intended lab database and use its results for the next questions. I want to start a SQL performance troubleshooting investigation using Query Store. Generate a single read-only T-SQL query that I can execute in the current database to identify the main performance contributors. The query must use Query Store and return, for each query: * Query ID * Query text * Object or stored procedure name, when available * Number of execution plans * Number of executions * Total CPU time * Average CPU time per execution * Total duration * Average duration per execution * Total logical reads * Average logical reads per execution Aggregate Query Store runtime statistics correctly across runtime intervals and execution plans. Use weighted calculations based on count_executions. Do not calculate averages by simply averaging Query Store average values. Return CPU and duration values in milliseconds. Rank the results by total CPU consumption, but include all the metrics above so that we can determine later which resource is having the highest impact. Do not perform root-cause analysis yet. Do not include execution plan analysis, parameter sensitivity, statistics analysis, index analysis, or remediation recommendations. Only generate the read-only diagnostic T-SQL query that I should execute. We then asked which resource deserved investigation, which query contributed most, how all its plans performed over time, and whether the same Plan ID had become more expensive. Only after those answers did we investigate selectivity, statistics and indexes. The complete session workflow contains the staged follow-up prompts. Convert the conversation into an Agent investigation We moved the recurring calculation rules and diagnostic sequence into sql-performance-investigator. The starting prompt could then state the goal, scope and execution boundaries. The skill supplies the detailed method; the available SQL tools supply execution capability. The agent retains the discovered query and plan identifiers within the investigation. It should not ask the engineer to copy them between steps or assume the identifiers from a previous lab run. Run the method in SSMS Agent mode Make the skill available to SSMS, select Agent mode and verify the SQL tools are enabled. Specify the target explicitly because Agent mode does not inherit the active query editor context. Investigate the SQL performance problem on server <server>, database <database>, using Query Store for <UTC start> to <UTC end>. Use the sql-performance-investigator skill. Use the available sql-tools to execute read-only diagnostics and continue through the investigation, requesting approval where the host requires it. Automatically discover the dominant performance metric, target query, Query ID, all Plan IDs, runtime history, and any same-plan degradation. Retain the discovered identifiers internally. Investigate the evidence needed to explain the change, including selectivity, data distribution, statistics and existing indexes when relevant. Do not assume a plan change caused the degradation or label it parameter sniffing without evidence. Keep confirmed evidence, inference, hypotheses and missing evidence separate. Use execution-weighted averages and explicit units. If the requested history or permissions are unavailable, report the limitation. Do not create/drop indexes, update/drop statistics, force plans, clear caches, modify Query Store, or change data/schema. Finish with a supported diagnosis or remaining uncertainty, a proposed remediation if justified, and a Query Store before/after validation plan. Do not execute remediation. Use the same method in GitHub Copilot Our pack places the skill at .github/skills/sql-performance-investigator/SKILL.md and the Custom Agent at .github/agents/sql-performance-investigator.agent.md. The skill references workflow.md and query-store-rules.md for the detailed method. In GitHub Copilot CLI, select the SQL Performance Investigator custom agent and use this adapted starting prompt: Use the SQL Performance Investigator custom agent and the sql-performance-investigator skill. Investigate SQL performance on <server>, database <database>, for <UTC start> to <UTC end>, using Query Store from evidence to diagnosis. If a SQL execution tool/MCP is available, run only read-only diagnostics and continue through the investigation. Discover Query IDs and Plan IDs automatically and retain them internally. Follow the host approval requirements. If no SQL execution capability is available, generate one self-contained read-only diagnostic batch for me to run, then continue when I provide the result. Do not claim that SQL was executed. Do not apply remediation. Propose an index/statistics action only after the evidence supports it. Finish with a before/after Query Store validation plan. The reusable asset is the investigation procedure behind these prompts. Query Store supplies the evidence, Copilot helps carry out the investigation, and the engineer reviews whether the explanation and proposed change are supported by the results.Outlook clients receive error 0x8004010f when downloading the Offline Address Book
EDIT 10/01/2008: To read the updated (and more comprehensive) guidance for troubleshooting errors 0x8004010f, please go here. There are a multiple reasons for why an Outlook client can receive the 0x8004010f sync error. Unfortunately, 0x8004010f is just a generic MAPI error and will show up for a variety of problems. Here is what the error looks like under err.exe (Microsoft Exchange Server Error Code Look-up Tool): C:\WXP\system32>err 0x8004010f # for hex 0x8004010f / decimal -2147221233 ecNotFound ec.h ecAttachNotFound ec.h ecUnknownRecip ec.h ecPropNotExistent ec.h MAPI_E_NOT_FOUND mapicode.h # 5 matches found for "0x8004010f" This is what the error looks like from the sync log from within Outlook: 12:45:53 Synchronizing Mailbox <dgoldman> 12:45:53 Done 12:45:54 Microsoft Exchange offline address book 12:45:54 0x8004010f Some of the most common reasons for Outlook clients to receive the 0x8004010f error with regards to downloading the OAB are listed below. Most of these are documented and I have linked articles to each of these to help everybody out. Please note that these solutions can change a small bit depending on unknown factors in a company's environment. An administrator decommissioned the last Exchange server in a site and never pushes replicas to another Exchange server. A new OAB is created in the active directory and the information store never reads the active directory during its maintenance schedule. This will result in the OAB files never being generated and the Outlook client will fail to download anything. The information store has an invalid EntryID that points to the legacy EX:/ folders. Again there is nothing for the client to download. An outlook client logging in from one domain to another domain and attempting to log in to another users mailbox. The OAB was never generated or some OAB folders are missing from the public folder store. Multiple OAB Version folders exist of the same type. Clients are attempting to download the OAB files from a public folder store that have not received the replicated updates. The offline address book list object has a missing address list. The offline address book list object has an incorrect address list. Send/As changes in the store affect users accounts with no mailbox full rights to another mailbox. If you are seeing this error on an Exchange 2007 server and your OAB is generated by an Exchange 2007 server, please make sure of the following: 1. Make sure that you have added the replicas of OAB to the Exchange 2007 server 2. Make sure public folder replication is working. 3. Make sure the OAB is public folder enabled and you have OAB Version 2, OAB Version 3 and OAB Version 4 checked off so your legacy clients can download the OAB files from the public folder store. 4. Make sure that if you are using an Outlook 2007 client, your OAB is Web Distribution enabled and the OAB files have been replicated over to the Client Access Server. For more information on this process please see this blog: http://blogs.msdn.com/dgoldman/archive/2006/10/23/outlook-client-fails-to-download-the-oab-with-error-0x8004011b.aspx and http://blogs.msdn.com/dgoldman/archive/2006/08/25/How-Exchange-2007-OAB-Files-are-replicated-to-a-Client-Access-Server-for-download.aspx 5. If you are removing your last Exchange 2003 server from the org, please make sure that you follow our documentation on this process. - Dave Goldman82KViews1like18Comments
Microsoft 365 Copilot, data from D365 Sales through Business Applications in Work IQ (Preview).
We're looking to enable Microsoft 365 Copilot to surface and ground responses using data from Dynamics 365 Sales through the new Business Applications in Work IQ (Preview). We've followed Microsoft's guidance and completed the configuration required to enable the integration. While the feature looks to be configured correctly, we're not seeing the expected Dynamics 365 Sales data being returned within Microsoft 365 Copilot. Has anyone seen this too?4Views0likes0Comments
Issue with Copilot
Issue Report: Plotting Engine Fails to Generate Charts Summary The chart‑generation feature in Copilot intermittently fails to produce output. When requesting visualizations such as radar charts, bar charts, histograms, or other plotted graphics, Copilot often returns an empty result with no error message or explanation. Observed Behavior Requests for plotted charts sometimes return "" (empty output). No error message is provided, making troubleshooting impossible. The failure occurs even with simple, valid datasets and straightforward instructions. Conceptual or AI‑generated diagrams work consistently; only plotted charts fail. Expected Behavior Copilot should reliably generate charts when provided valid data and instructions, or provide a clear error message if the request cannot be completed. Impact This issue prevents users from visualizing structured datasets and reduces confidence in Copilot’s ability to produce quantitative graphics. It also forces users to retry multiple times or switch to non‑chart visualizations. Request Please investigate the stability of the chart‑generation environment, particularly around sandbox execution and rendering reliability. Adding explicit error messages when chart generation fails would also significantly improve usability.160Views0likes3CommentsLessons Learned #558: What an Execution Plan XML Can Tell Us in Azure SQL Database
During a performance investigation in Azure SQL Database, we requested the execution plan to understand what the query was doing. While reviewing the evidence, the customer asked a broader question: when you open the XML of an execution plan, what do you usually look for? It was a useful question. The graphical plan helps us follow the flow of data, but the XML contains details about parameters, statistics, warnings and execution that can explain why the query behaved as it did. I do not read every attribute. I start with a few checks that help connect the customer symptom to the work performed by the query. In this article, I will walk through those checks: the type of plan, parameter values, estimated versus actual rows and statistics, missing indexes and implicit conversions, and reasons for a serial plan. The XML fragments below are simplified examples that use invented values or are adapted from examples discussed in previous articles in the Lessons Learned troubleshooting series. First check whether the plan contains execution evidence Plan What we can inspect Estimated plan Optimizer choices and estimates; the query has not executed Actual plan Plan plus available counters and warnings from that execution Cached or Query Store plan Compiled plan; normally no operator actuals for the incident For the checks involving actual rows, I request an actual execution plan. In SSMS, use Include Actual Execution Plan, or capture it using SET STATISTICS XML. Choose one method. The latter executes the query and returns its plan. The account needs the permissions to run the statement and SHOWPLAN permission. SET STATISTICS IO ON; SET STATISTICS TIME ON; SET STATISTICS XML ON; -- Execute the SELECT being investigated here. SET STATISTICS XML OFF; SET STATISTICS TIME OFF; SET STATISTICS IO OFF; Save the plan as a .sqlplan file and keep the Messages output. Record when it was captured, the parameters and the reported symptom. An execution captured later may not represent the incident. Review query literals, parameter values and object names before sharing the file. Check the right statement and its parameters A procedure or batch may contain several statements. I locate the relevant StmtSimple and its QueryPlan before interpreting a warning. StatementId and operator NodeId help keep the observations attached to the correct statement and operator; NodeId is not a stable identifier across different compilations. Next, I look at ParameterList. When available, it shows both the value used when the plan was compiled and the value used during the captured execution. <ParameterList> <ColumnReference Column="@CustomerId" ParameterDataType="int" ParameterCompiledValue="(42)" ParameterRuntimeValue="(900)" /> </ParameterList> Here, the plan was compiled with CustomerId 42 and executed with CustomerId 900. If one customer has a few orders and another has thousands, I would compare their data distribution and actual plans. Different values are a reason to investigate parameter sensitivity; they do not prove that plan reuse caused the problem. A missing runtime value means this capture did not provide it. It does not mean the runtime value was the same as the compiled value. Also, eligible queries can intentionally use different plan variants through Parameter Sensitive Plan optimization. Make the comparison match the application If the query is slow in the application but fast in SSMS, I compare the SQL text, parameter types and values, database context and session options. StatementSetOptions records options associated with compilation. <StatementSetOptions ARITHABORT="true" ANSI_WARNINGS="true" ANSI_NULLS="true" QUOTED_IDENTIFIER="true" ANSI_PADDING="true" CONCAT_NULL_YIELDS_NULL="true" NUMERIC_ROUNDABORT="false" /> A difference in context can help explain why the application and SSMS use different cached plans. I capture both rather than assuming that a fast SSMS execution represents the application. The difference itself still needs to be connected to the measured performance. Compare estimated and actual rows then inspect statistics I follow the rows through the plan and look for the first useful difference between what the optimizer expected and what the operator actually processed. <RelOp NodeId="3" PhysicalOp="Index Seek" LogicalOp="Index Seek" EstimateRows="100"> <RunTimeInformation> <RunTimeCountersPerThread Thread="0" ActualRows="20000" ActualRowsRead="80000" ActualExecutions="1" /> </RunTimeInformation> <!-- Access details omitted --> </RelOp> In this single-execution example, the operator estimated 100 rows and returned 20,000: a 200-fold underestimate. It also read 80,000 rows. I would ask why the estimate was inaccurate, and why the operator read substantially more rows than it returned. These are separate questions. For repeated or parallel operators, account for executions and threads before comparing totals. Do not add the rows from every operator to calculate the query result size. The next question is often whether the statistics were out of date. OptimizerStatsUsage identifies statistics consulted during compilation, where that information is exposed. <OptimizerStatsUsage> <StatisticsInfo Schema="[PlanXmlLab]" Table="[Orders]" Statistics="[IX_Orders_CustomerId]" LastUpdate="2026-10-10T07:00:00" SamplingPercent="20" ModificationCount="15000" /> </OptimizerStatsUsage> I check the relevant statistics object, its LastUpdate, SamplingPercent and ModificationCount together. An old timestamp or a low sampling percentage alone does not prove that it caused the estimate. Updated statistics cannot explain every discrepancy; parameter values, predicates and data distribution also matter. The XML describes the statistics consulted at compilation. To check their current state, I use sys.dm_db_stats_properties, as shown next. A subsequent update does not rewrite the evidence in an already saved plan. Check when the statistics were last updated -- Run in the affected database and set the actual table name. SELECT st.name AS statistics_name, sp.last_updated, sp.rows, sp.rows_sampled, sp.modification_counter FROM sys.stats AS st OUTER APPLY sys.dm_db_stats_properties( st.object_id, st.stats_id) AS sp WHERE st.object_id = OBJECT_ID(N'PlanXmlLab.Orders'); last_updated identifies the latest statistics update; rows and rows_sampled describe the population and sample at that update. modification_counter counts modifications to the leading statistics column since the update. Metadata visibility and permissions can affect the output. Compare this information with the same statistics object in the plan. Timestamps alone do not tell us whether the update was automatic or manual. If an update is justified, validate it in a controlled comparison using the same query and representative parameters, and capture a newly compiled plan. Read the access path alongside the row counts An Index Seek can still read many rows. I inspect SeekPredicates, any residual Predicate and ActualRowsRead where available. A broad seek range followed by filtering can explain why the rows read greatly exceed the rows returned. Likewise, a Key Lookup may be inexpensive once but expensive when repeated for thousands of rows. A scan can be the right choice when a large part of the table qualifies. The operator name is a starting point; the amount of work tells us more. For the customer, the useful explanation is concrete: this operator returned many more rows than expected, these were the statistics used, and this is the next comparison that will help establish why. That is more informative than recommending a statistics update from the timestamp alone. Read missing indexes and conversion warnings as clues Missing-index messages are easy to notice. I inspect the suggestion, but I also check whether it fits the query and the existing indexes. <MissingIndexes> <MissingIndexGroup Impact="85.0"> <MissingIndex Schema="[PlanXmlLab]" Table="[Orders]"> <ColumnGroup Usage="EQUALITY"> <Column Name="[CustomerId]" ColumnId="2" /> </ColumnGroup> <ColumnGroup Usage="INCLUDE"> <Column Name="[Amount]" ColumnId="3" /> </ColumnGroup> </MissingIndex> </MissingIndexGroup> </MissingIndexes> This example suggests a key on CustomerId with Amount included for coverage. EQUALITY and INEQUALITY describe predicate columns, while INCLUDE describes covering columns. The suggestion does not settle every detail of index design. Impact is an estimated reduction in optimizer cost. A value of 85 does not promise an 85% reduction in elapsed time. The XML may contain more suggestions than the graphical plan displays. Review existing indexes and write overhead, then measure the candidate change. Check which side of the predicate is converted <Warnings> <PlanAffectingConvert ConvertIssue="Seek Plan" Expression="CONVERT_IMPLICIT(nvarchar(50),[dbo].[Customers].[Code],0)" /> </Warnings> In this separate example, I would inspect the Code column type and the application parameter declaration. A varchar column compared with an nvarchar parameter can introduce a conversion on the column side because nvarchar has higher type precedence. The warning identifies something that may affect the plan, not a measured root cause. Whether a conversion prevents an efficient seek depends on the types, collation and expression. Test an appropriate parameter declaration while preserving required character semantics, and compare results, reads and CPU. A conversion in the projection is different from one in a search predicate. Look for an explicit reason when the plan is serial Customers sometimes ask why a query does not run in parallel when the database has multiple vCores. I look for NonParallelPlanReason in QueryPlan before assuming that more resources or a higher MAXDOP will change the result. <QueryPlan DegreeOfParallelism="0" NonParallelPlanReason="TSQLUserDefinedFunctionsNotParallelizable"> <!-- Other properties omitted --> </QueryPlan> Reason What I inspect next MaxDOPSetToOne Effective MAXDOP setting or query hint TSQLUserDefinedFunctionsNotParallelizable Scalar UDF and its inlining behavior NonParallelizableIntrinsicFunction The specific intrinsic function referenced A serial plan can be appropriate. The attribute can identify a restriction, but its absence does not fully explain the optimizer decision. Scalar UDF inlining can remove a restriction without guaranteeing parallel execution. DegreeOfParallelism="1" does not demonstrate parallel work. In Azure SQL Database, check database-scoped MAXDOP and query hints. More vCores do not override every restriction or guarantee selection of a parallel plan. Lessons learned The answer to the customer was a reading process: identify the statement and capture type, inspect parameters, compare estimated and actual work, and investigate the relevant statistics and warnings. Each observation should help us ask a better question and select a useful test. For a before-and-after comparison, preserve the query, parameters, data and relevant settings. Compare returned results, logical reads, CPU and duration. A plan describes one compilation or execution; Query Store can help establish whether the behavior changed over time. A short checklist Confirm that the plan belongs to the affected statement and execution. Check parameter values and the application context. Compare estimated and actual rows, accounting for repeated work. Inspect compilation statistics and their current update metadata. Review missing indexes, implicit conversions and serial-plan reasons. Validate the explanation with a measured comparison.Azure SQL Data Sync After a Database Restore: Troubleshooting Leftover Sync Metadata
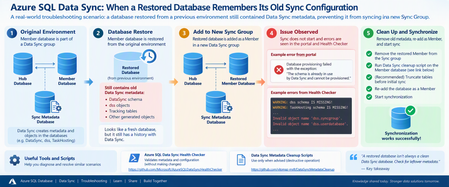
Recently, I worked on an interesting Azure SQL Data Sync issue that I thought was worth sharing with the community. The scenario looked straightforward at first: a database had been restored from another environment and was being configured as a Member database in a new Data Sync group. However, synchronization wasn't working as expected. The interesting part was not the new Sync Group itself. It was what the restored database had brought with it from its previous Data Sync configuration. The scenario The Member database was a restored copy of a database that had previously participated in another Azure SQL Data Sync group. After the restored database was configured as a Member in the new environment, synchronization wasn't working as expected. During troubleshooting, another important clue emerged. The restored database still had a history with Azure SQL Data Sync, so we needed to determine whether metadata and generated objects from its previous configuration were still present. This became one of the key areas of the investigation. Understand the Data Sync architecture first Before jumping into scripts, it's important to clearly distinguish the three database roles involved in Azure SQL Data Sync: Hub Database: The central database containing the application data being synchronized. Member Database: A database that synchronizes with the Hub. Sync Metadata Database: A separate Azure SQL Database containing Data Sync metadata and logs. Microsoft's documentation explains that Data Sync follows a hub-and-spoke topology and that the Sync Metadata Database contains Data Sync metadata and logs. This distinction became particularly important during this investigation because the initial diagnostic configuration wasn't pointing to the expected Sync Metadata Database. Troubleshooting approach Here is the troubleshooting flow we followed. Step 1: Run the Azure SQL Data Sync Health Checker One of the first tools I recommend for this type of investigation is the public Azure SQL Data Sync Health Checker: Azure SQL Data Sync Health Checker on GitHub [github.com] The tool validates whether metadata associated with the Hub and Member is in place and compares the scopes against information in the Sync Metadata Database. Importantly, the Health Checker repository states that it performs validation without changing Data Sync or user objects. The tool requires the relevant connection details for: Sync Metadata Database Hub Database Member Database The GitHub repository contains the current script and execution instructions. What we observed In our investigation, the initial Health Checker output included messages similar to: WARNING: dss schema IS MISSING! WARNING: TaskHosting schema IS MISSING! Invalid object name 'dss.syncgroup'. Invalid object name 'dss.userdatabase'. Those errors were important clues, but they needed to be interpreted together with the database roles. Microsoft's documentation states that the DataSync schema is used for system-created objects in Hub and Member databases, while the dss and TaskHosting schemas are used for system-created objects in the Sync Metadata Database. That distinction helped us recognize that we first needed to validate which database was actually being supplied to the Health Checker as the Sync Metadata Database. Lesson learned Before treating a missing dss or TaskHosting schema as corruption, first make sure you're actually connected to the Sync Metadata Database. That simple validation can save a lot of investigation time. Step 2: Check the Member database for Data Sync artifacts Once we had clarified the topology, the investigation moved to the restored Member database. Because this database had previously participated in Data Sync, we wanted to understand what Data Sync objects were still present. One of the queries used during troubleshooting was: SELECT name FROM sys.tables WHERE SCHEMA_NAME(schema_id) = 'DataSync' AND name NOT LIKE '%_tracking%'; We also inspected: SELECT * FROM DataSync.schema_info_dss; And, when checking the Member database's Data Sync scope information: SELECT * FROM DataSync.scope_info_dss; These checks helped us understand the Data Sync metadata state of the restored Member database and whether it still contained artifacts associated with its previous configuration. Why this matters Microsoft's current Data Sync best-practices documentation confirms that the DataSync schema is used for system-created objects in Hub and Member databases. So, when investigating a database restored from an environment where it previously participated in Data Sync, the DataSync schema is an important part of the investigation. Step 3: Consider the history of the restored database This was really the turning point in the investigation. Instead of treating the database simply as a "new Member", we started looking at it as: A restored database that had previously been provisioned for another Data Sync configuration. That's an important difference. When troubleshooting a restored database, ask early: Was this database previously part of another Azure SQL Data Sync group? If the answer is yes, the database's previous Data Sync state should be considered during the investigation. Step 4: Remove the Member before cleanup In our scenario, the remediation sequence was essentially: Remove the restored database from the current Sync Group. Clean up the previous Data Sync metadata from the restored Member database. Re-add the database as a Member. Trigger synchronization again. For the cleanup portion, we used the following publicly available repository: SQL Data Sync Cleanup Scripts on GitHub [github.com] The repository contains several scripts for different purposes, including: Data Sync complete cleanup.sql Data Sync cleanup hub or member.sql cleanup data sync object V2.sql The specific complete-cleanup script is available here: Data Sync complete cleanup.sql Important warning about the cleanup script Please do not treat this as a general-purpose Data Sync troubleshooting script. The script itself contains a very clear warning. It immediately cleans Data Sync-related objects associated with the database and says it should be used only for the scenarios specified in the script, including when advised by the support team during a support request. The repository also explains the different purposes of its cleanup scripts. For example, the complete-cleanup script has more restrictive usage guidance, while the Hub/Member cleanup and object cleanup scripts target different scenarios. My recommendation: use the Health Checker and read-only diagnostic queries first. Do not jump directly to metadata cleanup without understanding the database topology and existing Data Sync configuration. Step 5: Validate with one table After cleaning up the previous Data Sync artifacts, we didn't immediately assume that everything was resolved. Instead, we validated with a controlled test. A test table on the Member side was truncated, the synchronization was started again, and the table began synchronizing successfully. That provided the confirmation we needed that the previous Data Sync state of the restored Member was an important part of the issue. Root cause The troubleshooting pointed to the fact that the restored Member database had previously participated in another Data Sync configuration and retained Data Sync-related metadata/artifacts from that previous state. After cleaning up the old Data Sync state and reprovisioning the restored database as a Member, synchronization was successfully validated again. The important lesson for me wasn't simply the cleanup itself. It was recognizing that restoring a database does not necessarily mean you're starting with a clean Data Sync state. A practical troubleshooting flow For similar scenarios, I would approach the investigation in this order: Confirm the architecture Identify the: Hub Database Member Database Sync Metadata Database Run the Health Checker Use: Microsoft Azure SQL Data Sync Health Checker [github.com] Review its output before making changes. Inspect the restored Member Check whether Data Sync-related objects exist: SELECT name FROM sys.tables WHERE SCHEMA_NAME(schema_id) = 'DataSync' AND name NOT LIKE '%_tracking%'; Then, where applicable to the database's current state, inspect: SELECT * FROM DataSync.schema_info_dss; and: SELECT * FROM DataSync.scope_info_dss; Ask about the database history Was the database: restored from another environment? previously a Data Sync Member? previously associated with another Sync Group? That historical context can completely change the direction of the investigation. Consider cleanup only after understanding the environment The public cleanup scripts are available here: SQL Data Sync Cleanup Scripts [github.com] These scripts make changes to Data Sync objects and should not be the first troubleshooting step. Validate using a controlled test Once the environment has been correctly cleaned/reconfigured, validate synchronization on a controlled scope before assuming the entire configuration is healthy. My key takeaways This troubleshooting experience reinforced a few lessons for me. A restored database isn't necessarily a clean Data Sync database Restoring the application data doesn't mean you should ignore the database's previous synchronization configuration. Always distinguish Hub, Member, and Sync Metadata databases This is especially important when interpreting Health Checker output. The DataSync schema is associated with system-created objects in Hub and Member databases, while dss and TaskHosting are associated with system-created objects in the Sync Metadata Database. Use diagnostics before cleanup The Azure SQL Data Sync Health Checker is designed to validate Data Sync metadata and objects without making changes. That makes it a much better starting point than immediately removing objects. Database history matters One of my favorite questions after this investigation is now: "Was this database ever part of another Data Sync Group?" It's a simple question, but in restore or copy scenarios it can reveal an important part of the troubleshooting story. Be very careful with metadata cleanup The public cleanup repository itself provides specific guidance about when each script should be used, and the complete-cleanup script includes an explicit warning before execution. Always understand the environment and protect your data before performing destructive operations. One more important consideration: SQL Data Sync retirement There is also an important longer-term architecture consideration. Microsoft currently documents that SQL Data Sync retires on September 30, 2027. Existing Sync Groups can continue operating until the retirement date, but Microsoft recommends migrating to alternative data replication and synchronization solutions before then. So, while troubleshooting existing Data Sync environments remains necessary, organizations using the service should also begin considering their migration strategy. References and useful tools Microsoft documentation Best practices for Azure SQL Data Sync [learn.microsoft.com] Troubleshooting tools Azure SQL Data Sync Health Checker [github.com] SQL Data Sync Metadata Cleanup repository [github.com] Data Sync complete cleanup.sql116Views0likes0Comments