storage
1131 TopicsKB5122882 and Intel SATA RAID boot problem
There is a bigger issue on Supermicro motherboards when Intel SATA RAID is configured: the system fails to boot after an update. I have verified this on three different boards; X9SCL-F, X11SCW-F, X11SSL-F, after a second restart : A disk read error occurred The array is functioning correctly; I can see it when running the system from an ISO, and I have tested all possible boot repair options.363Views0likes4CommentsWindows Server 2028: A trusted foundation for an evolving enterprise
Enterprise infrastructure has evolved in response to changing and increasing business demands. Windows Server helped connect the enterprise by bringing people and resources together with Active Directory. As more business processes moved into software, it became a place to run business-critical applications. And when those applications multiplied, Hyper-V helped customers host the infrastructure they depend on more flexibly. Windows Server has evolved and grown with customers through each shift. Now customers are asking where AI should run when it needs to work with those applications and data. The cloud is part of the answer, but so is the local infrastructure they operate themselves. With Windows Server 2028, we’re strengthening the platform across the work it already does—and beginning to enable enterprise hybrid intelligence. Today, we’re introducing Windows Server 2028, in public preview now. This major release raises the security and access bar, accelerates enterprise infrastructure, and simplifies management at scale. It also begins our long term investments extending Microsoft Foundry to bring AI inference to fleets of local token factories, giving customers more choices to put the right intelligence in the right place with the right cost structure. For customers interested in early access to Windows Server 2028 features and direct engagement with Windows Server engineering, consider applying to Windows Server Technology Adoption Program (TAP) at aka.ms/WSTAP Enable enterprise hybrid intelligence AI raises an infrastructure question: where should inference run? A cloud service may be the right choice for one application. Another may need inference close to its data, near a physical operation, or within an environment the customer controls. Customers need to make that choice without building and operating a separate AI stack for every location, and want to scale their local inference servers on the same trusted platform delivering storage, compute, networking, and databases across their enterprise today. With Windows Server 2028, we’re investing across the stack needed to run inference on enterprise infrastructure. At the hardware layer, we’re introducing powerful new AI accelerators with Windows Server 2028. We’re excited to share that AMD’s Instinct MI350P card is in preview starting H1 2027 for in-market supported Windows Servers and Windows Server 2028. At the platform layer, we’re developing capabilities to deploy and configure inference environments, manage accelerated hardware, and direct model requests to the right environment. At the runtime layer, we’re working to support open-weight and custom models across technologies including Foundry Local, Windows ML, vLLM, and Llama.cpp. Running inference in an enterprise also means protecting and governing it. Windows Servers benefit from broad Windows investment in agent security and management, including Microsoft eXecution Containers for isolation, integration with Microsoft Foundry for model catalogs, and Agent 365 for agent identity and governance. Together, these capabilities are intended to help customers run AI close to their applications and data while connecting that work to a broader hybrid AI architecture. Raising the security and access bar The more an organization relies on its servers, the more important it is to keep them secure. Administrators need to protect the operating system and the virtual machines it hosts, maintain the certificates that secure connections, and prepare for threats that will change over the life of the infrastructure. Doing that well should not depend on every team starting from scratch. Windows Server 2028 is designed to give customers a stronger starting point. A hardened Server Core configuration by default and a new security baseline help reduce the work of establishing a secure baseline from day 1. Trusted Launch extends protection to virtual machines, guaranteeing boot integrity across your VM fleet, and Confidential VM support begins a journey to support integrity-protected runtimes on supported CVM hardware. We’re also investing in automatic certificate management and post-quantum cryptography, addressing both the day-to-day task of maintaining secure connections and the longer-term need to modernize them against the threats of tomorrow. Accelerate enterprise infrastructure Applications and data keep placing new demands on the systems beneath them. Customers are adopting faster storage and moving larger volumes of data, but the value of that hardware depends on whether the rest of the infrastructure can keep up. For organizations running critical workloads on Windows Server, performance improvements need to reach the applications they already operate. Windows Server 2028 adds native NVMe storage enabled by default and NVMe over TCP and RDMA transports, along with the ability to boot from ReFS. These technology ingredients combine to deliver high-performance, scalable, resilient storage solutions for Windows Server customers and help customers make better use of modern hardware to give demanding workloads more room to grow. Simplify administration and management at scale Managing a server and managing a server estate are different jobs. Across datacenters, clouds, and remote sites, teams need ways to apply policy, manage updates, and see what is running across the estate across an extraordinary diversity of Windows workloads. We hear regularly from customers who want to use proven Windows management processes and manage Clients and Servers as one fleet. We are proud to build on our recognition as a leader in Server Virtualization to help customers manage Windows Servers at scale. For teams that already manage Windows clients with Microsoft Intune, we are excited to announce Intune management for Windows Servers is now in Preview. Intune support for Windows Server brings familiar endpoint-management workflows including configuration, compliance, applications, and updates to eligible, persistent servers. Azure and Azure Arc continue to provide cloud-native management workflows for production and business-critical servers wherever they run. When a workload needs attention or a virtualization host needs troubleshooting, administrators need to get close to the machine and understand what is happening. Enterprise customers around the world run Windows Server VM fleets at scale, and need modern management tools to keep up. Windows Admin Center Virtualization Mode gives administrators the depth to work with individual servers and virtualized infrastructure as one fabric, and we are pleased to announce that WAC vMode is now in GA. These Cloud and On-Premises approaches complement one another. Customers can start with the workflows that fit their environment today, and grow into tomorrow with a consistent toolset that meets them where they are with the best of Azure and Windows management all together. Bringing Windows Server 2028 to enterprise infrastructure Bringing this vision to life takes an ecosystem spanning software, silicon, and systems integrators. We’re working closely with hardware partners to bring accelerated computing to the enterprise infrastructure customers already rely on. The strength of Windows and the strength of our ecosystem go hand in hand, and we thank our fantastic partners for their work scaling with us to support the needs of today’s enterprises. “Windows Server 2028’s advancements in security, virtualization, and modern infrastructure align naturally with AMD’s technology investments. Together, these technologies can help organizations protect data in use, modernize virtualized estates, and build efficient platforms for the next generation of mission-critical and AI-enabled workloads.” Kumaran Siva, Corporate Vice President of Business Development, AMD "Security for the AI era must be engineered across the platform—from firmware and the operating system through the full server lifecycle. Dell and Microsoft are working together so Dell PowerEdge customers can maximize the value of Windows Server 2028, including advances supporting the transition to post-quantum cryptography, with the reliability, automated protection and operational confidence they expect for their most critical workloads.” Anita Henry, Vice President of Infrastructure Solutions Group Engineering, Dell Technologies “As customers modernize distributed IT estates, they need security rooted in the server, reliability and simpler operations across edge, datacenter, and cloud. HPE ProLiant Compute, supported by Windows Server 2028’s security and hybrid-management, creates a strong foundation for resilient infrastructure that can adapt as business-critical workloads evolve.” Lauren Engebretson, Head of Compute Solutions and Enablement, Hewlett Packard Enterprise “The transition to post quantum cryptography is a major initiative for governments and enterprises. Intel’s PQC transition is well underway and, through deep co-engineering with Microsoft, we anticipate the Intel Xeon platform and Windows Server 2028 together will offer a strong PQC-capable foundation for our customers to build upon.” Srini Krishna, Distinguished Engineer, GM of Data Center Products, Intel Corporation “Customers want to bring AI closer to their data and decisions while building on the enterprise infrastructure they already rely on. Windows Server 2028, together with Lenovo Hybrid AI Advantage™ and Lenovo ThinkSystem and ThinkEdge servers, can help customers extend that foundation for trusted AI—from the edge to the data center and cloud—with greater choice, control and speed.” Scott Patti, Vice President of Infrastructure Solutions Group, Lenovo Going forward Windows Server 2028 is part of a bigger picture: intelligence across the cloud, enterprise infrastructure, and personal devices. As AI-accelerated workloads diffuse across the enterprise, different workloads have different needs. Some call for the breadth and scale of the cloud. Others need to run close to business-critical applications and data, on infrastructure customers control. Still others belong on the devices people use every day. Cost, latency, IP protection, data residency, and regulatory requirements all shape that decision. Our vision is to extend Microsoft Foundry across these environments, so teams can build with familiar tools and run each workload where it makes the most sense, from client, to cloud, to powerful Windows Server token factories running in corporate datacenters. As we move toward general availability, we’ll keep working with customers to learn where running inference on their own infrastructure makes the greatest difference—and to shape how Windows Server fits into a broader hybrid AI architecture. We’re excited about what Windows Server 2028 makes possible, and we look forward to sharing more as these capabilities develop. Explore Windows Server 2028 Security, performance, and management features are available in preview through the Windows Server Insider Program, and the Server team is looking forward to your feedback on the Windows Server Insiders Forum. Hybrid intelligence capabilities are available to a limited number of customers through an early access program, and hardware requirements apply. Thank you for the trust you’ve placed in Windows Server. Windows Server 2028 is our commitment to keep earning it: by strengthening the foundation you rely on and helping you put it to work in new ways.Matching Storage Performance to every stage of your AI Workloads on Azure
Every minute a GPU spends waiting for data is a minute you pay for and get nothing back. As accelerators get faster and clusters grow, that idle time adds up quickly: training jobs stall waiting for the next batch, checkpoints can pause thousands of GPUs at once, and inference fleets sit idle while model weights load. Keeping GPUs productive comes down to one question: can your storage deliver the right data, at the right speed, at every stage of the workload? On Azure, the answer is one architecture that combines durable core storage with workload-specific acceleration. Accelerator storage can bring data closer to compute or provide an accelerated access path within the durable storage foundation itself. In this post, we show how that works in practice, with real benchmark results, and what it means for the time your GPUs spend computing instead of waiting. One AI workload, many data paths A single AI application places very different demands on storage across its lifecycle. Data preparation must enumerate and filter enormous numbers of objects. Training requires sustained high-throughput reads, while checkpointing creates bursts of write bandwidth. Model loading drives simultaneous reads of large files across many nodes, inference and agentic workloads add latency-sensitive access and the need to persist and reuse context. Because these requirements vary so widely, the sweet spot is usually one durable data estate with a data path tuned to each stage. The storage solutions may differ, but they must work together so data, artifacts, and state remain available across the AI lifecycle. One continuous data path on Azure Azure uses Blob Storage as the durable data foundation, with multiple performance paths for workloads that require higher throughput, lower latency, file-system access, or compute-local caching. Core storage provides the foundation where data and state live across the AI lifecycle. Accelerator storage describes how performance is delivered, not only where a separate storage layer sits: it can place performance closer to compute or accelerate access to data within core storage itself. These are choices within one architecture, not a mandatory chain: each stage can use the path that best matches its throughput, latency, interface, and reuse requirements. Core storage is the durable, massively scalable system of record for the whole AI lifecycle. On Azure, that foundation is Azure Blob Storage: one home for raw and curated datasets, checkpoints and model weights, built for the scale and durability AI data demands. Azure Blob Storage has a performance profile that in several scenarios can be smoothly plugged directly in the specific AI scenario and this performance can be augmented through accelerator storage. Accelerator storage provides the workload-specific speed that improves core storage performance when needed for compute. It can take the form of a storage or caching layer closer to compute, or an accelerated access path within the core storage service itself. In either case, the goal is to deliver the throughput and latency each stage needs, from sustained training reads and checkpoint write bursts to model-loading fan-out and fast access to reusable context, so GPUs spend more time computing and less time waiting. Because core storage remains the system of record, acceleration can be matched to each job’s performance needs without turning every workload into a new data silo. Where a separate accelerator layer is used, its capacity can be sized to the job; where acceleration is delivered within core storage, higher performance can be applied to the data that needs it. Applications can retain familiar file system interfaces or existing object storage APIs, while data, artifacts and state remain part of one durable data estate. Acceleration in action: performance where the workload needs it Turbo tier: accelerating Azure Blob Storage Turbo tier brings SSD-backed performance to your Azure Blob data while the remainder can stay on lower-cost HDD-backed tiers in the same storage account. It brings SSD-backed performance to performance-demanding data while retaining HDD-backed economics for the rest, within one standard Azure Storage account. Applications continue using the same account, namespace, Blob APIs, SDKs and tooling. Turbo is an access tier, not a cache or a separately managed high-performance storage account: customers can accelerate the subset of data that requires it rather than move an entire dataset into a separate SSD storage architecture. Customers define a Turbo capacity target for the high-performance working set. Smart placement moves eligible objects between Turbo and HDD-backed tiers as access patterns change, while explicit tiering remains available when applications need deterministic control. The objective is to apply higher throughput, higher transaction rates and lower latency where they create workload value, without requiring every object to carry the cost of SSD-backed storage. In a synthetic 4 KiB random-read test against the same dataset, Turbo tier delivered 16.8× the transaction rate, reaching 10.1 million transactions per second compared with 601,000 on Standard Blob with HDD-backed tiers. Turbo tier used 256 Standard D96s v6 worker VMs, while Standard Blob used 72 to stay within HDD-backed storage account limits. In a separate read-bandwidth benchmark, Turbo tier sustained more than 20 Tbps, relevant for checkpoint recovery, model loading and inference scale-out. Read more in our blog post Blob Storage Turbo Tier: High performance with object storage scale and economics For AI training and fine-tuning, this can help feed performance-sensitive training data and support checkpoint writes. For inference, it can provide faster access to models and application data as services start and scale; analytics and HPC pipelines can similarly accelerate repeated processing of the performance-demanding portion of a larger data lake. Preview eligibility is limited to LRS accounts in selected regions, subject to regional capacity. Azure Managed Lustre: feeding training and protecting checkpoints Azure Managed Lustre is another example of what the accelerator layer can deliver when AI workloads need performance close to compute. Its integration with Azure Blob Storage connects the high-performance file system used by the job with the durable core storage layer where datasets, checkpoints and model artifacts can remain available across the AI lifecycle. MLPerf Storage v3.0 results, released by MLCommons on September 1, 2026, provides an independent and comparable view of that accelerator performance. Azure Managed Lustre was the first hyperscale cloud storage service submitted at the scale of more than 600 GB/s (4.8 Tbps). The results illustrate two critical accelerator storage patterns. For training, Azure Managed Lustre sustained the data path needed to keep simulated accelerator utilization above 90% for five consecutive hours, while read bandwidth scaled from 17.4 GiB/s at 3 simulated NVIDIA B200 accelerators to 379.1 GiB/s at 70. For checkpointing, the largest configuration, representing a 1,250B-parameter model, wrote at 642.2 GiB/s and recovered at 489.6 GiB/s, the second-highest peak checkpoint write among all submissions. Overall, Azure performed comparably to purpose-built on-premises AI storage in both categories. Figure 1. MLPerf Storage v3.0 results on Azure. Left: training read bandwidth from 3 to 70 simulated B200 accelerators versus ideal linear scaling. Right: checkpoint write and recovery read throughput by model scale. Explore the Azure Managed Lustre MLPerf Storage v3.0 results for benchmark methodology, tested configurations, and detailed training and checkpointing results. DACS: bringing reusable data closer to GPU compute DACS extends the accelerator pattern to AI workloads on Azure Kubernetes Service. Now in public preview, it is a distributed read-through cache that uses local NVMe disks across nodes to keep frequently read data from Azure Blob Storage close to GPU compute. For repeated reads after the working set is warm, this can reduce Blob fetches and increase the bandwidth available for model loading and repeated training-data access. This means reducing warm-model loading times and repeated Blob reads as inference workloads scale, restart or recover, and can accelerate training that repeatedly accesses the same dataset portions. In Standard LRS sequential-read testing with BlobFuse2 across ten workers, colocated DACS reached 47,760.75 MiB/s of warm bandwidth at 16 I/O threads per worker, 84.0% above BlobFuse2 alone and 10.9% above dedicated DACS. Teams can use DACS through Azure Container Storage with Run:ai Model Streamer, BlobFuse2 or the native Python client, while Azure Blob Storage remains the durable source of truth and the fallback when data is not cached. Figure 2. Standard LRS sequential-read bandwidth by I/O thread count for BlobFuse2 alone and dedicated or colocated DACS, with cold and warm cache results. Choosing the right acceleration for your bottleneck To optimize your GPU data path, you can choose the best solution for each workload stage: Azure Blob Storage can be accelerated using Turbo tier when an application needs higher-performance object access without changing its Blob account, namespace, or APIs. Azure Managed Lustre can be used when training and checkpointing require a high-throughput parallel file system close to compute, and your applications need POSIX file system semantics. DACS on AKS can be used when repeated reads of Blob data can benefit from distributed node-local caching. Today, DACS supports Run:ai Model Streamer, BlobFuse2 or the native Python client. In all the cases, Azure Blob Storage remains the durable data foundation that can be still accessed directly by all the portion of the workflows that do not require specific acceleration. The architectural goal is the same: place performance where the workload needs it, so compute spends less time waiting for data without creating new systems of record. See it at SC26 These topics will be covered in our session at SC26. At the Microsoft booth, we’ll walk through the same data path end to end: preparing data, feeding training, protecting checkpoints, loading models and reusing context for inference. You’ll see where each storage layer helps keep GPUs busy and how the layers connect into one architecture. Join Wolfgang De Salvador, Sachin Sheth and Brian Lepore for Storage Innovation for AI on Wednesday 18 November, 2:00–2:20 pm CT, at booth #3411. Session: Storage Innovation for AI Speakers: Wolfgang De Salvador, Sachin Sheth and Brian Lepore Where: Microsoft booth theater, booth #3411, McCormick Place, Chicago When: Wednesday 18 November, 2:00–2:20 pm CT
Announcing Windows Server vNext Preview Build 29706
Hello Windows Server Insiders! Today we are pleased to release a new build of the next Windows Server Long-Term Servicing Channel (LTSC) Preview that contains both the Desktop Experience and Server Core installation options for Datacenter and Standard editions and Azure Edition (for VM evaluation only). The branding for this preview has been updated to Windows Server 2028 -- when reporting issues please continue to refer to Windows Server vNext preview. Build 29531 established a new Server preview baseline build. Please perform a clean install of Build 29531 (or later) using the installation media linked below. Please note: Upgrades from Windows Server vNext preview builds older than 29531 are not supported. We encourage all Windows Server vNext preview users to perform a clean install using 29531 or later to successfully upgrade to future Windows Server vNext preview builds. While upgrades from earlier Windows Server previews (Build 26525 and older) are not technically blocked by setup.exe, a number of known issues have been identified related to upgrades necessitating the establishment of a new baseline build for our Server vNext Preview Program. The new baseline build (29531) will not be Flighted due to upgrade issues. Flighting support resumed with preview build 29550 or later. What's New [NEW] With this build, we are excited to announce branding for our vNext release. Windows Server 2028 [NEW] Please join us at IGNITE 2026 this week (either in person or online) to learn about some of the exciting new features coming in Windows Server 2028. Feedback Hub app is available for Server Desktop users! The app should automatically update with the latest version, but if it does not, simply Check for updates in the app’s settings tab. Known Issues A race condition in the TLS hybrid key exchange implementation may cause the LSASS service to crash when hybrid groups are negotiated by a TLS server. To avoid this issue until the fix is released, please disable hybrid groups (X25519_MLKEM768, SecP256r1_MLKEM768, SecP384r1_MLKEM1024) using TLS cmdlets or Group Policy, as outlined here. Server Core Upgrades and AppCompat FOD: Enabling AppCompat FOD after reinstall may fail due to legacy 3rd-party license compatibility issues on Server Core devices. Server Core users may be unable to install the latest AppCompat FOD after upgrading to build 29574. This appears to be limited to Server Core installations with 3rd-party application licenses that fail compatibility checks after upgrade. This will be addressed in a future build. Upgrading from older builds of Windows Server vNext previews (26525 or older) are not supported. Please perform a clean install of build 29531 or later. Users may experience failures when attempting to upgrade from earlier previews (build 26525 and older). VMs may fail to upgrade or start after upgrade from older preview builds impacting live migration and failover cluster scenarios. Download Windows Server Insider Preview (microsoft.com) Flighting: The label for this flight may incorrectly reference Windows 11. However, when selected, the package installed is the Windows Server vNext update. Please ignore the label and proceed with installing your flight. This issue will be addressed in a future release. Available Downloads Downloads to certain countries may not be available. See Microsoft suspends new sales in Russia - Microsoft On the Issues. Windows Server Long-Term Servicing Channel Preview in ISO format in 18 languages, and in VHDX format in English only. Windows Server Datacenter Azure Edition Preview in ISO and VHDX format, English only. Microsoft Server Languages and Optional Features Preview Keys: Keys are valid for preview builds only Server Standard: MFY9F-XBN2F-TYFMP-CCV49-RMYVH Datacenter: 2KNJJ-33Y9H-2GXGX-KMQWH-G6H67 Azure Edition does not accept a key. Symbols: Available on the public symbol server – see Using the Microsoft Symbol Server. Expiration: This Windows Server Preview will expire October 15, 2027. How to Download Registered Insiders may navigate directly to the Windows Server Insider Preview download page. If you have not yet registered as an Insider, see GETTING STARTED WITH SERVER on the Windows Insiders for Business portal. We value your feedback! The most important part of the release cycle is to hear what's working and what needs to be improved, so your feedback is extremely valued. Please use the new Feedback Hub app for Windows Server if you are running a Desktop version of Server. If you are using a Core edition, or if you are unable to use the Feedback Hub app, you can use your registered Windows 10 or Windows 11 Insider device and use the Feedback Hub application. In the app, choose the Windows Server category and then the appropriate subcategory for your feedback. In the title of the Feedback, please indicate the build number you are providing feedback on as shown below to ensure that your issue is attributed to the right version: [Server #####] Title of my feedback See Give Feedback on Windows Server via Feedback Hub for specifics. The Windows Server Insiders space on the Microsoft Tech Communities supports preview builds of the next version of Windows Server. Use the forum to collaborate, share and learn from experts. For versions that have been released to general availability in market, try the Windows Server for IT Pro forum or contact Support for Business. Diagnostic and Usage Information Microsoft collects this information over the internet to help keep Windows secure and up to date, troubleshoot problems, and make product improvements. Microsoft server operating systems can be configured to turn diagnostic data off, send Required diagnostic data, or send Optional diagnostic data. During previews, Microsoft asks that you change the default setting to Optional to provide the best automatic feedback and help us improve the final product. Administrators can change the level of information collection through Settings. For details, see http://aka.ms/winserverdata. Also see the Microsoft Privacy Statement. Terms of Use This is pre-release software - it is provided for use "as-is" and is not supported in production environments. Users are responsible for installing any updates that may be made available from Windows Update. All pre-release software made available to you via the Windows Server Insider program is governed by the Insider Terms of Use.523Views2likes0Comments
Urgent: Thousands of OneDrive Files Disappeared Without Any Recycle Bin or Restore Activity Records
Hello Microsoft Community, I am experiencing a serious data loss issue with my university-provided OneDrive account and would appreciate assistance from Microsoft support staff or anyone who has encountered a similar problem. On 12 November 2026, OneDrive unexpectedly began deleting a large number of files without any manual deletion on my part. The deletion process continued for an extended period, and the missing files disappeared from both the cloud and my synchronised devices. On 15 November, I received an official Microsoft email stating that a large number of files had recently been deleted and could be recovered from the Recycle Bin within 93 days. However, I discovered something very unusual: 1. **Most of the files that disappeared earlier on 12 November are completely absent from both the first-stage and second-stage Recycle Bins.** 2. **These missing files also have no deletion records in the OneDrive Restore activity history.** 3. Only the final, relatively small batch of files deleted later that same day appears in both the Recycle Bin and the OneDrive Restore activity history. 4. I previously attempted to use the "Restore your OneDrive" feature. Although the restoration process reported 100% completion, the majority of my missing files were not recovered. 5. I also attempted local data recovery using third-party recovery software, but it did not locate the missing files. My main concern is that the earlier mass disappearance of files seems to have left no visible deletion records, while the later deletions were recorded normally. Could someone from Microsoft please clarify: - Under what circumstances can OneDrive files disappear without appearing in either Recycle Bin or the OneDrive Restore activity history? - Could this be caused by a synchronisation malfunction, an account lifecycle or retention policy change, or a backend deletion operation? - Is it possible for Microsoft to investigate the underlying SharePoint/OneDrive audit logs to determine what happened? - If the files cannot be recovered through the normal recovery tools, is there a way to request a server-side backup recovery? - How can an individual user escalate this issue to Microsoft's technical support team for investigation, particularly when using a university-managed account? These files contain important academic and research materials accumulated over several years, and their loss would have serious consequences. I would be extremely grateful for any assistance or guidance on how to recover the data. Thank you.31Views0likes1CommentChange to OneDrive mounting Shared Libraries on MacOS
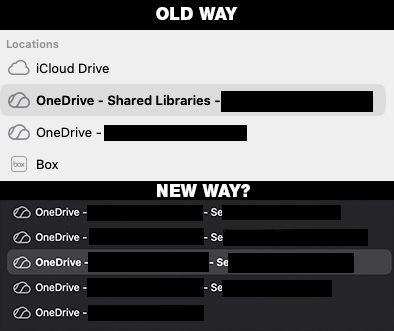
OneDrive usually mounts shared libraries on MacOS under a Shared Library directory and any items you choose to sync go to this location. Overnight it seems OneDrive keeps updating these mounts to separate directories. Is this an expected change? I am unable to find any release notes online about this but some users are still mounted the old way and some will mount the old way but after a few minutes onedrive will update the mounts to this new way. This changes the file paths to things and is breaking a lot of workflows. the major difference is that the old way had 4 things mounted in shared libraries and now all 4 of them are separate mounts446Views1like3CommentsUnlock multi-region HPC capabilities with Azure CycleCloud
As HPC workloads grow, organizations need the flexibility to access more compute capacity without adding complexity to how they manage data. Expanding across regions can unlock new resources, but moving data between environments often introduces additional operational overhead. The Azure CycleCloud Multi-region plugin for Azure Managed Lustre (AMLFS) helps address this challenge by bringing compute, storage and automated data staging together in a coordinated workflow. Azure CycleCloud Multi-region plugin for Azure Managed Lustre (AMLFS) makes regional data staging part of the familiar Slurm job lifecycle. Azure CycleCloud manages compute provisioning and autoscaling, while the integrated extension uses Slurm Burst Buffer hooks to automate declared input staging and output return to the home region. Once configured, the workflow reduces manual data handling and keeps archive and import operations outside the job's compute allocation, helping teams focus allocated cores on simulation rather than bulk transfers. This architecture keeps ongoing simulation I/O close to the nodes, helping limit runtime and core hours spent waiting on remote I/O. Teams gain these execution options while retaining familiar Slurm submissions and application file paths. Stage inputs in the selected spoke region, run the simulation against local storage, and return results to the home region. Azure CycleCloud and its integrated Slurm workflow connect these steps, giving teams broader execution options while preserving familiar job submissions and application file paths. Regional routing and scaling policies remain managed through the Slurm scheduler configuration. More Regional Capacity, One Connected HPC Workflow Expanding HPC workloads across regions gives organizations greater flexibility to access compute resources where they’re available. By keeping data close to the workloads that need it, teams can reduce unnecessary data movement and simplify how simulations are managed across regions. The result is a more flexible approach to scaling HPC environments without having to manage each region as a separate workflow. Azure CycleCloud Multi-region plugin for AMLFS brings these pieces into one coordinated workflow. The home region hosts the Slurm scheduler node and the Azure Managed Lustre file system holding inputs and receiving results. Each spoke region pairs compute with its own Azure Managed Lustre file system for local simulation I/O. Azure CycleCloud manages compute provisioning and autoscaling, while configured Slurm partition mappings associate jobs with their execution region. At a high level, the solution automates how data moves between the home region and the regions where compute jobs run. Input data is staged before execution, jobs access it through regional Azure Managed Lustre file systems, and outputs are returned to the home region when processing is complete. This reduces the need for teams to coordinate each data transfer manually. Slurm Burst Buffer hooks on the home scheduler automate declared input staging through a shared Azure Blob Storage container, archiving from the home Azure Managed Lustre file system and importing into the selected spoke file system through hierarchical storage management (HSM). The job remains pending until stage in completes. Import establishes the namespace and metadata; file contents are restored on first access. Managed identity authorizes storage operations, and the Azure Managed Lustre and Blob Storage integration transfers the data. After execution, the same workflow returns declared outputs to the home file system. Archive and import operations run outside the job's compute allocation. In an autoscaled pool starting from powered down nodes, Azure CycleCloud starts the required compute after stage in and scheduling. Once execution and normal node completion activities finish, outputs remain on the spoke Azure Managed Lustre file system while released compute can serve other jobs or scale down under configured policies. Jobs running in the home region use the home file system directly. For HPC teams, this means more options for where workloads run, while maintaining a consistent way to submit jobs and manage data. Automated staging helps reduce manual data handling, allowing teams to focus more on running simulations and less on coordinating transfers between regions. Performance and cost can also be assessed across different regional configurations to help inform workload placement decisions. Users add #BB_LUA stage_in and stage_out directives to their Slurm scripts, retaining uniform application and data paths through the Azure Managed Lustre file system in the selected region. Administrators configure regional mappings at the cluster level. See the job usage guide for the complete example. Getting Started with the Multi-region plugin for AMLFS Follow the project's quick start and architecture guide to configure networking, an Azure Managed Lustre file system in the home region and each spoke region, compatible clients, and managed identity permissions for the scheduler node in the home region. Enable the project extension through the Azure CycleCloud cluster-init configuration to integrate staging with the Slurm job lifecycle. Start with a representative simulation and follow its complete journey: input staging from the home Azure Managed Lustre file system, data restoration on the spoke Azure Managed Lustre file system, spoke execution, compute release, and output return to the home region. Configure workload paths, permissions, regional placement, and scaling policies to match your operational requirements, then measure the workflow against your performance and cost goals. Put more of Azure's regional HPC possibilities to work. Azure CycleCloud Multi-region plugin for AMLFS brings compute management, Azure Managed Lustre file systems in the home and spoke regions, and automated data staging together, helping teams expand execution options, simplify operations, and keep simulations at the center of the workflow. Conclusion Scaling HPC is about more than adding compute capacity. It’s about ensuring the right data is available wherever workloads need to run. By combining regional compute flexibility with automated data staging, the Azure CycleCloud Multi-region plugin for AMLFS offers HPC teams a more coordinated way to expand their environments while retaining familiar tools and workflows. See it at SC26 See the “Multi-region HPC with AMLFS on Azure CycleCloud” demo at the Microsoft booth (#3411), Exhibit Hall, McCormick Place, Chicago, 16-19 November. Learn More Azure CycleCloud Multi-region plugin for AMLFS project Multi-region plugin for AMLFS quick start and deployment guide Azure Managed Lustre and Blob Storage integration Azure Managed Lustre import options and limits Azure CycleCloud Slurm scaling configuration Slurm Burst Buffer Guide
OneDrive Shows 6.5 GB Used Despite Empty Storage | Storage Management Issues
Hello, My Microsoft account appears to have a problem with OneDrive storage management. OneDrive continuously shows 6.5 GB used out of 5 GB (130%), even though: My Files is empty The Recycle Bin is empty Personal Vault is empty Searches do not find any large files In addition, the "Manage Storage" page fails to load and displays an "Unknown Rendering Error". The issue persists after: Signing out and back in Using Incognito/Private mode Testing on different pages and services There are also related Outlook issues: Outlook on the web reports that there is not enough storage available I can no longer send emails The Outlook desktop app fails when trying to add or configure the account At this point, neither OneDrive nor Outlook shows what is actually using the reported 6.5 GB of storage. Has anyone experienced this issue before, or does anyone know how I can get the storage usage or account data checked when the storage management page itself is broken? Thank you for any help.65Views0likes1CommentOneDrive won't allow installation on fixed D: drive
Since 24 Sep 2026, OneDrive refuses to use my internal D:\ drive, even though the OneDrive build and Windows haven't changed. This applies to my Personal OneDrive and institutional OneDrive accounts. Build 26.168.0830.0006 (per-machine install, installed 20 Sep 2026) synced both of my accounts to D:\ normally from 20 to 23 Sep. At the 24 Sep morning boot, OneDrive could not find either folder. Setup now rejects D:\ with "Your OneDrive folder can't be created in the location you selected," and Learn More links to the article on external drives. The rejection persists with my existing folders (after renaming them) and with a brand-new empty folder (D:\ODTest). E:\, an identical Crucial T500 4TB NVMe in the motherboard's native M.2 slot, is accepted. The only difference is that D:\ is attached through an M.2-to-PCIe adapter card in an internal PCIe 4.0 slot (in place since Nov 2025). Windows reports D:\ as Fixed and NTFS (Get-Volume, DriveInfo, Win32_DiskDrive), and it does not appear in Safely Remove Hardware. Dropbox on the same drive is unaffected. With the build unchanged and Windows Update paused, this looks like a server-side change in how OneDrive classifies drives. Please restore support for internal NVMe drives attached through PCIe adapter cards.Solved917Views5likes4Comments
Robocopy missing option
Hi, I am using robocopy to keep my primary drives and my backup drives in sync. I used to use the GUI version, but that seems unstable on win10, so I've switched to the command line option. It this is not the right Forum, please guide me to the right one. When I sync files, I don't care about anything else, but the file size of my files. I am really missing a robocopy which allows me to do so. My problem (like so many others I have seen reporting the same problem), is that robocopy seems to react on timestamps that are not visible using the "Normal" tools. Copying large files, means that the change timestamp on the dest files will be later than the source files, meaning that robocopy, alone for that reason, will copy the same file next time. I have tried almost all combinations on the options without achieving the perfect result: Purge files to a destination drive, just classifying files based on the file size, and absolutely nothing else. Any suggestions?655Views1like1Comment