learning
587 TopicsBuild an AI-Powered Space Invaders Game
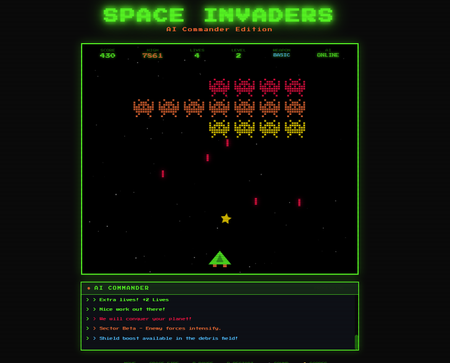
Build an AI-Powered Space Invaders Game: Integrating LLMs into HTML5 Games with Microsoft Foundry Local Introduction What if your game could talk back to you? Imagine playing Space Invaders while an AI commander taunts you during battle, delivers personalized mission briefings, and provides real-time feedback based on your performance. This isn't science fiction it's something you can build today using HTML, JavaScript, and a locally-running AI model. In this tutorial, we'll explore how to create an HTML5 game with integrated Large Language Model (LLM) features using Microsoft Foundry Local. You'll learn how to combine classic game development with modern AI capabilities, all running entirely on your own machine—no cloud services, no API costs, no internet connection required during gameplay. We'll be working with the Space Invaders - AI Commander Edition project, which demonstrates exactly how to architect games that leverage local AI. Whether you're a student learning game development, exploring AI integration patterns, or building your portfolio, this guide provides practical, hands-on experience with technologies that are reshaping how we build interactive applications. What You'll Learn By the end of this tutorial, you'll understand how to combine traditional web development with local AI inference. These skills transfer directly to building chatbots, interactive tutorials, AI-enhanced productivity tools, and any application where you want intelligent, context-aware responses. Set up Microsoft Foundry Local for running AI models on your machine Understand the architecture of games that integrate LLM features Use GitHub Copilot CLI to accelerate your development workflow Implement AI-powered game features like dynamic commentary and adaptive feedback Extend the project with your own creative AI features Why Local AI for Games? Before diving into the code, let's understand why running AI locally matters for game development. Traditional cloud-based AI services have limitations that make them impractical for real-time gaming experiences. Latency is the first challenge. Cloud API calls typically take 500ms to several seconds, an eternity in a game running at 60 frames per second. Local inference can respond in tens of milliseconds, enabling AI responses that feel instantaneous and natural. When an enemy ship appears, your AI commander can taunt you immediately, not three seconds later. Cost is another consideration. Cloud AI services charge per token, which adds up quickly when generating dynamic content during gameplay. Local models have zero per-use cost, once installed, they run entirely on your hardware. This frees you to experiment without worrying about API bills. Privacy and offline capability complete the picture. Local AI keeps all data on your machine, perfect for games that might handle player information. And since nothing requires internet connectivity, your game works anywhere, on planes, in areas with poor connectivity, or simply when you want to play without network access. Understanding Microsoft Foundry Local Microsoft Foundry Local is a runtime that enables you to run small language models (SLMs) directly on your computer. It's designed for developers who want to integrate AI capabilities into applications without requiring cloud infrastructure. Think of it as having a miniature AI assistant living on your laptop. Foundry Local handles the complex work of loading AI models, managing memory, and processing inference requests through a simple API. You send text prompts, and it returns AI-generated responses, all happening locally on your CPU or GPU. The models are optimized to run efficiently on consumer hardware, so you don't need a supercomputer. For our Space Invaders game, Foundry Local powers the "AI Commander" feature. During gameplay, the game sends context about what's happening, your score, accuracy, current level, enemies remaining and receives back contextual commentary, taunts, and encouragement. The result feels like playing alongside an AI companion who actually understands the game. Setting Up Your Development Environment Let's get your machine ready for AI-powered game development. We'll install Foundry Local, clone the project, and verify everything works. The entire setup takes about 10-15 minutes. Step 1: Install Microsoft Foundry Local Foundry Local installation varies by operating system. Open your terminal and run the appropriate command: # Windows (using winget) winget install Microsoft.FoundryLocal # macOS (using Homebrew) brew install microsoft/foundrylocal/foundrylocal These commands download and install the Foundry Local runtime along with a default small language model. The installation includes everything needed to run AI inference locally. Verify the installation by running: foundry --version If you see a version number, Foundry Local is ready. If you encounter errors, ensure you have administrator/sudo privileges and that your package manager is up to date. Step 2: Install Node.js (If Not Already Installed) Our game's AI features require a small Node.js server to communicate between the browser and Foundry Local. Check if Node.js is installed: node --version If you see a version number (v16 or higher recommended), you're set. Otherwise, install Node.js: # Windows winget install OpenJS.NodeJS.LTS # macOS brew install node # Linux sudo apt install nodejs npm Node.js provides the JavaScript runtime that powers our proxy server, bridging browser code with the local AI model. Step 3: Clone the Project Get the Space Invaders project onto your machine: git clone https://github.com/leestott/Spaceinvaders-FoundryLocal.git cd Spaceinvaders-FoundryLocal This downloads all game files, including the HTML interface, game logic, AI integration module, and server code. Step 4: Install Dependencies and Start the Server Install the Node.js packages and launch the AI-enabled server: npm install npm start The first command downloads required packages (primarily for the proxy server). The second starts the server, which listens for AI requests from the game. You should see output indicating the server is running on port 3001. Step 5: Play the Game Open your browser and navigate to: http://localhost:3001 You should see Space Invaders with "AI: ONLINE" displayed in the game HUD, indicating that AI features are active. Use arrow keys or A/D to move, SPACE to fire, and P to pause. The AI Commander will start providing commentary as you play! Understanding the Project Architecture Now that the game is running, let's explore how the different pieces fit together. Understanding this architecture will help you modify the game and apply these patterns to your own projects. The project follows a clean separation of concerns, with each file handling a specific responsibility: Spaceinvaders-FoundryLocal/ ├── index.html # Main game page and UI structure ├── styles.css # Retro arcade visual styling ├── game.js # Core game logic and rendering ├── llm.js # AI integration module ├── sound.js # Web Audio API sound effects ├── server.js # Node.js proxy for Foundry Local └── package.json # Project configuration index.html: Defines the game canvas and UI elements. It's the entry point that loads all other modules. game.js: Contains the game loop, physics, collision detection, scoring, and rendering logic. This is the heart of the game. llm.js: Handles all communication with the AI backend. It formats game state into prompts and processes AI responses. server.js: A lightweight Express server that proxies requests between the browser and Foundry Local. sound.js: Synthesizes retro sound effects using the Web Audio API—no audio files needed! How the AI Integration Works The magic of the AI Commander happens through a simple but powerful pattern. Let's trace the flow from gameplay event to AI response. When something interesting happens in the game, you clear a wave, achieve a combo, or lose a life, the game logic in game.js triggers an AI request. This request includes context about the current game state: your score, accuracy percentage, current level, lives remaining, and what just happened. The llm.js module formats this context into a prompt. For example, when you clear a wave with 85% accuracy, it might construct: You are an AI Commander in a Space Invaders game. The player just cleared wave 3 with 85% accuracy. Score: 12,500. Lives: 3. Provide a brief, enthusiastic comment (1-2 sentences). This prompt travels to server.js , which forwards it to Foundry Local. The AI model processes the prompt and generates a response like: "Impressive accuracy, pilot! Wave 3 didn't stand a chance. Keep that trigger finger sharp!" The response flows back through the server to the browser, where llm.js passes it to the game. The game displays the message in the HUD, creating the illusion of playing alongside an AI companion. This entire round trip typically completes in 50-200 milliseconds, fast enough to feel responsive without interrupting gameplay. Using GitHub Copilot CLI to Explore and Modify the Code GitHub Copilot CLI accelerates your development workflow by letting you ask questions and generate code directly in your terminal. Let's use it to understand and extend the Space Invaders project. Installing Copilot CLI If you haven't installed Copilot CLI yet, here's the quick setup: # Install GitHub CLI winget install GitHub.cli # Windows brew install gh # macOS # Authenticate with GitHub gh auth login # Add Copilot extension gh extension install github/gh-copilot # Verify installation gh copilot --help With Copilot CLI ready, you can interact with AI directly from your terminal while working on the project. Exploring Code with Copilot CLI Use Copilot to understand unfamiliar code. Navigate to the project directory and try: gh copilot explain "How does llm.js communicate with the server?" Copilot analyzes the code and explains the communication pattern, helping you understand the architecture without reading every line manually. You can also ask about specific functions: gh copilot explain "What does the generateEnemyTaunt function do?" This accelerates onboarding to unfamiliar codebases, a valuable skill when working with open source projects or joining teams. Generating New Features Want to add a new AI feature? Ask Copilot to help generate the code: gh copilot suggest "Create a function that asks the AI to generate a mission briefing at the start of each level, including the level number and a random mission objective" Copilot generates starter code that you can customize and integrate. This combination of AI-powered development tools and AI-integrated gameplay demonstrates how LLMs are transforming both how we build games and how games behave. Customizing the AI Commander The default AI Commander provides generic gaming commentary, but you can customize its personality and responses. Open llm.js to find the prompt templates that control AI behavior. Changing the AI's Personality The system prompt defines who the AI "is." Find the base prompt and modify it: // Original const systemPrompt = "You are an AI Commander in a Space Invaders game."; // Customized - Drill Sergeant personality const systemPrompt = `You are Sergeant Blaster, a gruff but encouraging drill sergeant commanding space cadets. Use military terminology, call the player "cadet," and be tough but fair.`; // Customized - Supportive Coach personality const systemPrompt = `You are Coach Nova, a supportive and enthusiastic gaming coach. Use encouraging language, celebrate small victories, and provide gentle guidance when players struggle.`; These personality changes dramatically alter the game's feel without changing any gameplay code. It's a powerful example of how AI can add variety to games with minimal development effort. Adding New Commentary Triggers Currently the AI responds to wave completions and game events. You can add new triggers in game.js : // Add AI commentary when player achieves a kill streak if (killStreak >= 5 && !streakCommentPending) { requestAIComment('killStreak', { count: killStreak }); streakCommentPending = true; } // Add AI reaction when player narrowly avoids death if (nearMissOccurred) { requestAIComment('nearMiss', { livesRemaining: lives }); } Each new trigger point adds another opportunity for the AI to engage with the player, making the experience more dynamic and personalized. Understanding the Game Features Beyond AI integration, the Space Invaders project demonstrates solid game development patterns worth studying. Let's explore the key features. Power-Up System The game includes eight different power-ups, each with unique effects: SPREAD (Orange): Fires three projectiles in a spread pattern LASER (Red): Powerful beam with high damage RAPID (Yellow): Dramatically increased fire rate MISSILE (Purple): Homing projectiles that track enemies SHIELD (Blue): Grants an extra life EXTRA LIFE (Green): Grants two extra lives BOMB (Red): Destroys all enemies on screen BONUS (Gold): Random score bonus between 250-750 points Power-ups demonstrate state management, tracking which power-up is active, applying its effects to player actions, and handling timeouts. Study the power-up code in game.js to understand how temporary state modifications work. Leaderboard System The game persists high scores using the browser's localStorage API: // Saving scores localStorage.setItem('spaceInvadersScores', JSON.stringify(scores)); // Loading scores const savedScores = localStorage.getItem('spaceInvadersScores'); const scores = savedScores ? JSON.parse(savedScores) : []; This pattern works for any data you want to persist between sessions—game progress, user preferences, or accumulated statistics. It's a simple but powerful technique for web games. Sound Synthesis Rather than loading audio files, the game synthesizes retro sound effects using the Web Audio API in sound.js . This approach has several benefits: no external assets to load, smaller project size, and complete control over sound parameters. Examine how oscillators and gain nodes combine to create laser sounds, explosions, and victory fanfares. This knowledge transfers directly to any web project requiring audio feedback. Extending the Project: Ideas for Students Ready to make the project your own? Here are ideas ranging from beginner-friendly to challenging, each teaching valuable skills. Beginner: Customize Visual Theme Modify styles.css to create a new visual theme. Try changing the color scheme from green to blue, or create a "sunset" theme with orange and purple gradients. This builds CSS skills while making the game feel fresh. Intermediate: Add New Enemy Types Create a new enemy class in game.js with different movement patterns. Perhaps enemies that move in sine waves, or boss enemies that take multiple hits. This teaches object-oriented programming and game physics. Intermediate: Expand AI Interactions Add new AI features like: Pre-game mission briefings that set up the story Dynamic difficulty hints when players struggle Post-game performance analysis and improvement suggestions AI-generated names for enemy waves Advanced: Multiplayer Commentary Modify the game for two-player support and have the AI provide play-by-play commentary comparing both players' performance. This combines game networking concepts with advanced AI prompting. Advanced: Voice Integration Use the Web Speech API to speak the AI Commander's responses aloud. This creates a more immersive experience and demonstrates browser speech synthesis capabilities. Troubleshooting Common Issues If something isn't working, here are solutions to common problems. "AI: OFFLINE" Displayed in Game This means the game can't connect to the AI server. Check that: The server is running ( npm start shows no errors) You're accessing the game via http://localhost:3001 , not directly opening the HTML file Foundry Local is installed correctly ( foundry --version works) Server Won't Start If npm start fails: Ensure you ran npm install first Check that port 3001 isn't already in use by another application Verify Node.js is installed ( node --version ) AI Responses Are Slow Local AI performance depends on your hardware. If responses feel sluggish: Close other resource-intensive applications Ensure your laptop is plugged in (battery mode may throttle CPU) Consider that first requests may be slower as the model loads Key Takeaways Local AI enables real-time game features: Microsoft Foundry Local provides fast, free, private AI inference perfect for gaming applications Clean architecture matters: Separating game logic, AI integration, and server code makes projects maintainable and extensible AI personality is prompt-driven: Changing a few lines of prompt text completely transforms how the AI interacts with players Copilot CLI accelerates learning: Use it to explore unfamiliar code and generate new features quickly The patterns transfer everywhere: Skills from this project apply to chatbots, assistants, educational tools, and any AI-integrated application Conclusion and Next Steps You've now seen how to integrate AI capabilities into a browser-based game using Microsoft Foundry Local. The Space Invaders project demonstrates that modern AI features don't require cloud services or complex infrastructure, they can run entirely on your laptop, responding in milliseconds. More importantly, you've learned patterns that extend far beyond gaming. The architecture of sending context to an AI, receiving generated responses, and integrating them into user experiences applies to countless applications: customer support bots, educational tutors, creative writing tools, and accessibility features. Your next step is experimentation. Clone the repository, modify the AI's personality, add new commentary triggers, or build an entirely new game using these patterns. The combination of GitHub Copilot CLI for development assistance and Foundry Local for runtime AI gives you powerful tools to bring intelligent applications to life. Start playing, start coding, and discover what you can create when your games can think. Resources Space Invaders - AI Commander Edition Repository - Full source code and documentation Play Space Invaders Online - Try the basic version without AI features Microsoft Foundry Local Documentation - Official installation and API guide GitHub Copilot CLI Documentation - Installation and usage guide GitHub Education - Free developer tools for students Web Audio API Documentation - Learn about browser sound synthesis Canvas API Documentation - Master HTML5 game rendering963Views0likes3Comments
Unable to access https://cdx.transform.microsoft.com
Hello I have an organization that is a valid TSP. They want to access and use https://cdx.transform.microsoft.com/ but they are presented with the error message: Not Authorized Oops! It looks like you do not have permissions to access this page. We looked but we couldn't find your login [email address] associated to a Microsoft partner organization. How do they fix this? Who provides access? Regards Chintan PatelSolved
HOW TO RETRIEVE MY MCP ID
Good day, I passed my Microsoft E-Learning exam long time ago and I've lost all document that my MCP Id number is suppose to be on. Kindly help me. I need my document. Also the company email that I've used before is no longer available. Is there a way I can get my certificate again? Thanks in advanceSolvedMCT New and Renewing MCTs - Update July 26
Updated July 26, 2025 As we step into FY26 on July 1st, 2025, I want to share some important updates regarding the MCT Program—especially for those planning to renew. New Fees Coming October 2025, no exact date and the cost will be shared at a later date. Starting July 1st, 2025, we will introduce: A renewal fee (ecommerce tool will be available in October 2025 for everyone to renew) A new MCT enrollment fee (ecommerce tool will be available in October 2025 for new MCTs) Our systems are currently being updated to support this change, with the new tool expected to launch in October 2025. More to come on costs. Pricing will be region supported. Session Requirement for Renewal Effective January 1st, 2026, MCTs will be required to complete six (6) sessions or six (6) days of training per calendar year to qualify for renewal. For clarity on what qualifies as a session, please refer to the attached PDF: Mandatory Use of MTM We will be enforcing stricter requirements for using Metrics That Matter (MTM) to log sessions with your Training Services Partner (TSP). Please coordinate with your TSPs to ensure MTM is being used correctly. What to Expect Next More details on program costs will be shared closer to the tool’s release. All MCTs that were MCTs before manual enrollment have been extended through January 1st, 2026, with full benefits. You’ll see this extension reflected in your profile in your MCT Trainer History NOT active certification. All current MCTs will be able to renew when the tool is available in October 2025 and the requirement to renew will be to have an active certification and have taught one class since your last renewal and pay the renewal fee (costs to come later). We will be checking that you have taught the one class using MTM. New MCTs will need ISC certificate, one role-based active certification and pay the MCT new enrollment fee. New MCT Enrollment Process | Microsoft Learn 🙏 Thank you for your continued support and patience as we enhance our systems. Here’s to a successful and impactful FY26!Solved
Question about Microsoft IT specialist certification, in relation to Coursera.
Please, bear with me, as it took me 3 hours just to get navigated here for help. I am taking IT courses with Coursera. I am not an IT professional...I am trying to change my career and my life. I was taking Googles IT Support Specialist course, but after 4 days of classes, I came across a major roadblock: Outdated information on their QwikLabs setup. The course was at least a year behind, the Demo on how to use Qwiklabs was seriously outdated, and Google has changed Qwiklabs into a "Pay to Create" gimmick that really doesn't work for anyone that is a Student, imo. $25+ to create a project, per project, and then 3 cents an hour while its running, can build up really fast. It was also changes and charges that Coursera was unaware of. So, how does this relate? I want to switch over to Microsoft IT Support courses and certification, but i want to make sure that its up to date, and that i won't run into another "out of the course" pay wall structure, because i really don't have that kind of money to throw around like that. It may not seem like a major deal to alot of people, but I am maintaining two households, on two continents, off one paycheck, and Im a kitchen employee...so Im sure alot of people can relate to how this is suddenly an issue. Can anyone verify how up-to-date that course is, from Microsoft, on Coursera? Im trying to change my life, and its already upsetting finding i wasted a weeks worth of effort.Train a simple Recommendation Engine using the new Azure AI Studio
The AI Studio Odyssey: Embark on a journey to the heart of personalization with our latest guide, “Train a Simple Recommendation Engine using the new Azure AI Studio.” Unlock the secrets of the all-new Azure AI Studio intuitive tools to craft a recommendation system that feels like magic, yet is grounded in data and user preferences. Ready to enchant your audience? Grab some popcorn and read on!6.8KViews0likes2CommentsSet Up Plaud Note Pro with Microsoft Foundry
Prerequisites Riffado, up and running: follow the setup guide in the official Riffado repository to get it going with Docker Compose. A Microsoft Foundry (formerly Azure AI Foundry) resource, with the models you want deployed; in my case, whisper for transcription and o3-mini for summaries. A Plaud device, or any audio recordings you can import into Riffado. Once Riffado is up, head to the Settings page > Providers > Add Provider, and select Custom. This is where the Azure details will go. Why "OpenAI-compatible" isn’t one thing on Microsoft Foundry Azure AI Foundry exposes two different API surfaces on the same resource, and which one serves your model depends on the model: Surface Path shape Serves OpenAI-compatible? v1 route /openai/v1/… gpt-4o-transcribe, gpt-4o-mini-transcribe, chat models, embeddings Yes: Bearer auth, model in the body, no api-version needed Classic route /openai/deployments/{name}/… Whisper (and other legacy audio) No: deployment name lives in the URL, and ?api-version= is mandatory A generic OpenAI client (Riffado's included) can only speak the first dialect. It has nowhere to put a deployment name in the path and no way to append a query parameter. That single fact drives everything below. Part 1 - Transcription Whisper and the DeploymentNotFound mystery Symptom My very first transcription attempt in Riffado failed with 404 Resource not found. Off to a flying start. Configured provider: base URL https://<resource>.services.ai.azure.com, model whisper. Dead end #1: the missing path The first bug was mine: the base URL had no path. Riffado's OpenAI client appends /audio/transcriptions to whatever you give it, so requests were hitting https://<resource>…/audio/transcriptions, a path that doesn't exist on the resource at all. Fixing the base URL to end in /openai/v1 got us to a more interesting error: POST /openai/v1/audio/transcriptions · model=whisper {"error":{"code":"DeploymentNotFound","message":"The API deployment for this resource does not exist. If you created the deployment within the last 5 minutes, please wait a moment and try again."}} Dead end #2: catalog ≠ deployment Worth checking before anything else: selecting a model in the Foundry catalog is not deploying it. GET /openai/v1/models lists everything you could deploy; only Deployments → Deploy model creates an endpoint that answers. If you get DeploymentNotFound, first confirm a deployment actually exists (the listing below requires only the API key): enumerate real deployments (classic control-plane, key auth) curl -s -H "api-key: $KEY" \ "https://<resource>.openai.azure.com/openai/deployments?api-version=2023-03-15-preview" # → {"data":[{"id":"whisper","model":"whisper","status":"succeeded",…}]} The actual cause Here is the part that nearly drove me mad: the deployment existed and was succeeded, yet the v1 route still said DeploymentNotFound. Because Whisper deployments are not served on the v1 route at all. They only answer on the classic path. Verified side by side with the same tiny WAV file: Request Result POST /openai/v1/audio/transcriptions · model=whisper · Bearer 404 DeploymentNotFound POST /openai/deployments/whisper/audio/transcriptions?api-version=2024-06-01 · Bearer 200 {"text":"you"} Same classic path, without ?api-version= 404 Resource not found Three constraints, then: Whisper needs the classic path; the classic path needs api-version; Riffado can send neither. One piece of good news hiding in the table: the classic route accepts Authorization: Bearer, not just Azure's api-key header, so the shim doesn't have to touch auth at all. The fix: a Caddy shim Drop a stock caddy:2-alpine container into the Compose network. Riffado points at it as if it were OpenAI; the shim rewrites the path, injects api-version, and proxies to Azure. The Bearer header passes through untouched. azure-shim.Caddyfile { admin off auto_https off } :80 { @transcribe path /v1/audio/transcriptions /audio/transcriptions handle @transcribe { rewrite * /openai/deployments/whisper/audio/transcriptions?api-version=2024-06-01 reverse_proxy https://<resource>.services.ai.azure.com { header_up Host <resource>.services.ai.azure.com } } handle { respond "azure-shim ok" 200 } } docker-compose.yml (added service) azure-shim: image: caddy:2-alpine restart: unless-stopped volumes: - ./azure-shim.Caddyfile:/etc/caddy/Caddyfile:ro Riffado's provider settings become: Field Value Base URL http://azure-shim/v1 Model whisper (must equal the deployment name) API key the Azure resource key (forwarded as Bearer) Verified From inside the Riffado container: POST http://azure-shim/v1/audio/transcriptions → 200 {"text":"…"}. Transcription works end-to-end in the UI. Part 2 · Summaries & titles o3-mini and the empty answer Symptom The summary button showed "An unexpected error occurred." The container logs were more honest: riffado-app logs Error generating title: TypeError: undefined is not an object (evaluating 'C.choices[0]') Riffado calls chat/completions and reads choices[0] without checking whether the response was an error. So anything the API refuses becomes "an unexpected error." What was it refusing? Cause 1: reasoning models reject the classic knobs o3-mini belongs to Azure/OpenAI's o-series reasoning models, which hard-reject parameters every classic chat client sends. Riffado sends temperature: 0.7 and max_tokens: 50 for titles (0.5 / 2000 for summaries), and o3-mini answers: POST /openai/v1/chat/completions · model=o3-mini HTTP 400 {"error":{"message":"Unsupported parameter: 'max_tokens' is not supported with this model. Use 'max_completion_tokens' instead.", …}} # and with max_tokens fixed: HTTP 400 {"error":{"message":"Unsupported parameter: 'temperature' is not supported with this model.", …}} Cause 2: reasoning tokens starve the output Stripping the bad params gets you to 200, and then comes a subtler failure, my personal favourite of this whole saga. Reasoning models spend completion tokens on internal "thinking" before emitting a single visible character. Riffado's 50-token title budget is consumed entirely by reasoning, and the reply comes back syntactically valid and empty: max_completion_tokens reasoning_effort finish_reason content 50 not set length "" (all 50 spent reasoning) 2000 not set stop "Q3 Budget Planning Strategy Meeting" 2000 low stop same, less reasoning overhead The fix: a Node shim that rewrites the request body Caddy can rewrite paths but not JSON bodies, so this shim is ~60 lines of dependency-free Node on node:20-alpine. Per request it: converts max_tokens → max_completion_tokens, strips temperature / top_p / penalties, floors the token budget at 4000, sets reasoning_effort: "low", maps /v1/* → /openai/v1/*, and forwards to the Azure resource. o3-shim.js const http = require('http'); const https = require('https'); const UPSTREAM_HOST = '<resource>.services.ai.azure.com'; // Params o-series reasoning models reject on chat/completions. const STRIP = ['temperature','top_p','presence_penalty', 'frequency_penalty','logprobs','top_logprobs']; const server = http.createServer((req, res) => { const chunks = []; req.on('data', c => chunks.push(c)); req.on('end', () => { let body = Buffer.concat(chunks); // Riffado's base_url is http://o3-shim/v1 → map to Azure's /openai/v1 let path = req.url; if (path.startsWith('/v1/')) path = '/openai' + path; const ct = (req.headers['content-type'] || '').toLowerCase(); if (ct.includes('application/json') && body.length) { try { const j = JSON.parse(body.toString('utf8')); if (j && typeof j === 'object' && !Array.isArray(j)) { if ('max_tokens' in j) { if (!('max_completion_tokens' in j)) j.max_completion_tokens = j.max_tokens; delete j.max_tokens; } // Reasoning spends tokens before any visible output; small // budgets (Riffado sends 50 for titles) return empty strings. if (Array.isArray(j.messages)) { j.max_completion_tokens = Math.max(Number(j.max_completion_tokens) || 0, 4000); if (!('reasoning_effort' in j)) j.reasoning_effort = 'low'; } for (const k of STRIP) delete j[k]; body = Buffer.from(JSON.stringify(j)); } } catch (_) { /* not JSON - forward untouched */ } } const headers = { ...req.headers, host: UPSTREAM_HOST, 'content-length': Buffer.byteLength(body) }; const up = https.request( { host: UPSTREAM_HOST, port: 443, method: req.method, path, headers }, upRes => { res.writeHead(upRes.statusCode, upRes.headers); upRes.pipe(res); } ); up.on('error', e => { res.writeHead(502, {'content-type':'application/json'}); res.end(JSON.stringify({error:{message:'o3-shim upstream error: '+e.message}})); }); up.end(body); }); }); server.listen(80, () => console.log('o3-shim listening on :80')); docker-compose.yml (added service) o3-shim: image: node:20-alpine restart: unless-stopped working_dir: /app command: ["node", "/app/o3-shim.js"] volumes: - ./o3-shim.js:/app/o3-shim.js:ro Add a second provider in Riffado (base URL http://o3-shim/v1, model o3-mini, the resource's API key) and set it as the default enhancement provider (summaries/titles), keeping the Whisper one as default for transcription. Riffado's exact title request (temperature: 0.7, max_tokens: 50) through the shim → 200, finish_reason: stop, real title text. A full meeting-transcript summary returns structured key points and action items. The final shape Reading it left to right: Riffado never talks to Azure directly. Transcription requests pass through azure-shim, a stock Caddy container that rewrites each request onto Whisper's classic deployment path and injects the mandatory api-version parameter. Summary and title requests pass through o3-shim, a tiny Node server that rewrites the request body into the shape o3-mini accepts and floors the token budget so the model's internal reasoning cannot starve the actual answer. As far as Riffado is concerned, it is simply talking to two ordinary OpenAI providers. Both shims live on the Compose network only; nothing is exposed publicly. Riffado is unmodified. Verification checklist Each layer, testable in isolation. Run these before blaming the app: smoke tests # 1. Key + resource alive? (v1 models listing, Bearer auth) curl -s -H "Authorization: Bearer $KEY" \ https://<resource>.services.ai.azure.com/openai/v1/models | head -c 200 # 2. Whisper answers on the classic path? curl -s -H "Authorization: Bearer $KEY" -F file=@test.wav \ "https://<resource>.services.ai.azure.com/openai/deployments/whisper/audio/transcriptions?api-version=2024-06-01" # 3. Shim translates correctly? (from inside the compose network) docker exec riffado-app node -e "fetch('http://azure-shim/') .then(r=>r.text()).then(console.log)" # 4. o3-mini via shim, sending the params Riffado sends? # (temperature + max_tokens:50; the shim must absorb both) If you'd rather not run shims Both shims exist because of the specific models chosen. Pick models that live natively on the v1 route and Riffado connects directly, with base URL https://<resource>.services.ai.azure.com/openai/v1 and zero extra containers: Transcription: deploy gpt-4o-mini-transcribe (or gpt-4o-transcribe) instead of Whisper. Summaries: deploy a non-reasoning chat model such as gpt-4o-mini, which happily accepts temperature and max_tokens. The shim approach earns its keep when you're standardized on specific models (Whisper's transcription quality, o3-mini's reasoning), or when you want a control point to add logging, retries, or budget caps later. For reference, this is what the finished setup looks like on Riffado's side. Each shim is registered as a plain Custom provider. Here is the whisper provider pointing at azure-shim, with Use for transcription ticked: And once both are saved, they sit side by side in the providers list, whisper tagged for transcription and o3-mini tagged for enhancement: A quick look at the Foundry portal In the Microsoft Foundry portal, head over to Models > AI Services and you will find a pleasant surprise: fifteen AI service models already deployed and ready to use, covering the Azure Speech family (including Voice Live and Speech to Text), Azure Translator, Azure Language, and Content Understanding: You can of course deploy another model for this, but the pre-deployed ones are a handy cost-saving option. Click on the Azure Speech – Voice Live radio button and you will be shown the Base URL and API Key, which you can then paste into the provider settings on Riffado's Settings page. A quick note on cost: these services are not free. They are billed pay-as-you-go based on usage. Azure Speech transcription is charged per audio hour, and Voice Live pricing is tiered by the model you choose. The free tier does include a monthly allowance, though. Check the Azure Speech pricing page before committing. And if you would rather deploy a dedicated transcription model such as whisper, Foundry gives you the flexibility to do just that. Open the model page in the catalogue, click Deploy, and go with Default settings unless you need custom quotas or guardrails: Let's test the setup On your Plaud device, just tap to start recording. The little LED bars light up to show it is listening: Or skip the device entirely and upload an audio file straight into Riffado using the Upload Audio button. Either way, the recording lands on the Recordings page; hit Transcribe and let the spinner do its thing: As you can see below, whisper, the transcription model we deployed earlier, even managed to transcribe a recording in Malay without a hitch. My 3:32 test clip came back as 186 words of clean Malay, with the language correctly detected and tagged: I have also set o3-mini as the enhancement provider, and it enhanced the transcription with a proper summary, key points, and title as well! The Meeting Notes-style summary came straight out of o3-mini through the shim, with zero manual prompting. Wrapping up What started as a TikTok-fuelled impulse buy nearly killed off by subscription pricing ended up as a fully self-hosted pipeline: Plaud for recording, Riffado as the interface, and Microsoft Foundry serving whisper and o3-mini behind two tiny shims. The total extra infrastructure came to two containers and roughly sixty lines of code, and not a single monthly subscription in sight. If you try this setup and run into a failure mode I have not covered here, do share it in the comments. Half the fun is in the debugging.369Views0likes0Comments
The new MD-102 and the missing labs
Hi. This complete rewrite of MD-102 has been long underway and very much wanted. The new courseware arrived on time, but much to our disappointment, we discovered that labs will first arrive in the next 30-60 days. Clients will not be happy with a 5 days course without labs. If this is the new norm, then it will render the Courseware Title Plan useless, if we only get part of the course on the dates mentioned.Join us on June 3rd for the MSLE AI Bootcamps - Copilot Chat Agents for Academics Special Session!
Hi TSP Community, We’re excited to invite you to a special session on June 3rd introducing the upcoming Microsoft Learn for Educators (MSLE) AI Copilot Chat Agents for Academics Bootcamp. This session will provide an early look at a new, scalable skilling experience designed specifically for higher education faculty and administrators—and how you can leverage it in your field engagements. What we’ll cover: Overview of the Copilot Agents for Academics Bootcamp and delivery model How faculty will be enabled to use, integrate, and build Copilot agents for teaching, learning, and operations A walkthrough of the curriculum progression (Agent Foundations → Integration & Autonomy) Examples of hands-on labs, live demos, and role-based scenarios The TSP opportunity: how this standardized, repeatable offering supports AI skilling conversations and drives customer value 📅 Date: June 3rd, 2026 at 7:00 AM PST | 7:30 PM IST 📣 Join Here: https://aka.ms/MSLEAgentsTSPSpecialSession Make sure to download the calendar invite attached! We hope you’ll join to learn how this offering can accelerate your engagements and expand AI skilling across your academic customers.