learning
790 TopicsBuild an AI-Powered Space Invaders Game
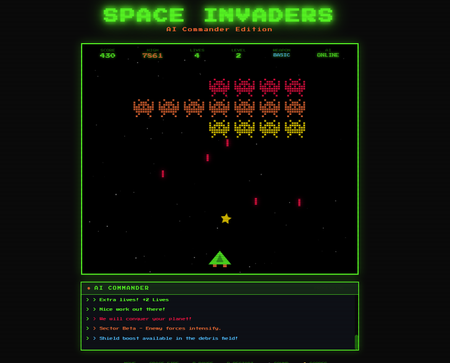
Build an AI-Powered Space Invaders Game: Integrating LLMs into HTML5 Games with Microsoft Foundry Local Introduction What if your game could talk back to you? Imagine playing Space Invaders while an AI commander taunts you during battle, delivers personalized mission briefings, and provides real-time feedback based on your performance. This isn't science fiction it's something you can build today using HTML, JavaScript, and a locally-running AI model. In this tutorial, we'll explore how to create an HTML5 game with integrated Large Language Model (LLM) features using Microsoft Foundry Local. You'll learn how to combine classic game development with modern AI capabilities, all running entirely on your own machine—no cloud services, no API costs, no internet connection required during gameplay. We'll be working with the Space Invaders - AI Commander Edition project, which demonstrates exactly how to architect games that leverage local AI. Whether you're a student learning game development, exploring AI integration patterns, or building your portfolio, this guide provides practical, hands-on experience with technologies that are reshaping how we build interactive applications. What You'll Learn By the end of this tutorial, you'll understand how to combine traditional web development with local AI inference. These skills transfer directly to building chatbots, interactive tutorials, AI-enhanced productivity tools, and any application where you want intelligent, context-aware responses. Set up Microsoft Foundry Local for running AI models on your machine Understand the architecture of games that integrate LLM features Use GitHub Copilot CLI to accelerate your development workflow Implement AI-powered game features like dynamic commentary and adaptive feedback Extend the project with your own creative AI features Why Local AI for Games? Before diving into the code, let's understand why running AI locally matters for game development. Traditional cloud-based AI services have limitations that make them impractical for real-time gaming experiences. Latency is the first challenge. Cloud API calls typically take 500ms to several seconds, an eternity in a game running at 60 frames per second. Local inference can respond in tens of milliseconds, enabling AI responses that feel instantaneous and natural. When an enemy ship appears, your AI commander can taunt you immediately, not three seconds later. Cost is another consideration. Cloud AI services charge per token, which adds up quickly when generating dynamic content during gameplay. Local models have zero per-use cost, once installed, they run entirely on your hardware. This frees you to experiment without worrying about API bills. Privacy and offline capability complete the picture. Local AI keeps all data on your machine, perfect for games that might handle player information. And since nothing requires internet connectivity, your game works anywhere, on planes, in areas with poor connectivity, or simply when you want to play without network access. Understanding Microsoft Foundry Local Microsoft Foundry Local is a runtime that enables you to run small language models (SLMs) directly on your computer. It's designed for developers who want to integrate AI capabilities into applications without requiring cloud infrastructure. Think of it as having a miniature AI assistant living on your laptop. Foundry Local handles the complex work of loading AI models, managing memory, and processing inference requests through a simple API. You send text prompts, and it returns AI-generated responses, all happening locally on your CPU or GPU. The models are optimized to run efficiently on consumer hardware, so you don't need a supercomputer. For our Space Invaders game, Foundry Local powers the "AI Commander" feature. During gameplay, the game sends context about what's happening, your score, accuracy, current level, enemies remaining and receives back contextual commentary, taunts, and encouragement. The result feels like playing alongside an AI companion who actually understands the game. Setting Up Your Development Environment Let's get your machine ready for AI-powered game development. We'll install Foundry Local, clone the project, and verify everything works. The entire setup takes about 10-15 minutes. Step 1: Install Microsoft Foundry Local Foundry Local installation varies by operating system. Open your terminal and run the appropriate command: # Windows (using winget) winget install Microsoft.FoundryLocal # macOS (using Homebrew) brew install microsoft/foundrylocal/foundrylocal These commands download and install the Foundry Local runtime along with a default small language model. The installation includes everything needed to run AI inference locally. Verify the installation by running: foundry --version If you see a version number, Foundry Local is ready. If you encounter errors, ensure you have administrator/sudo privileges and that your package manager is up to date. Step 2: Install Node.js (If Not Already Installed) Our game's AI features require a small Node.js server to communicate between the browser and Foundry Local. Check if Node.js is installed: node --version If you see a version number (v16 or higher recommended), you're set. Otherwise, install Node.js: # Windows winget install OpenJS.NodeJS.LTS # macOS brew install node # Linux sudo apt install nodejs npm Node.js provides the JavaScript runtime that powers our proxy server, bridging browser code with the local AI model. Step 3: Clone the Project Get the Space Invaders project onto your machine: git clone https://github.com/leestott/Spaceinvaders-FoundryLocal.git cd Spaceinvaders-FoundryLocal This downloads all game files, including the HTML interface, game logic, AI integration module, and server code. Step 4: Install Dependencies and Start the Server Install the Node.js packages and launch the AI-enabled server: npm install npm start The first command downloads required packages (primarily for the proxy server). The second starts the server, which listens for AI requests from the game. You should see output indicating the server is running on port 3001. Step 5: Play the Game Open your browser and navigate to: http://localhost:3001 You should see Space Invaders with "AI: ONLINE" displayed in the game HUD, indicating that AI features are active. Use arrow keys or A/D to move, SPACE to fire, and P to pause. The AI Commander will start providing commentary as you play! Understanding the Project Architecture Now that the game is running, let's explore how the different pieces fit together. Understanding this architecture will help you modify the game and apply these patterns to your own projects. The project follows a clean separation of concerns, with each file handling a specific responsibility: Spaceinvaders-FoundryLocal/ ├── index.html # Main game page and UI structure ├── styles.css # Retro arcade visual styling ├── game.js # Core game logic and rendering ├── llm.js # AI integration module ├── sound.js # Web Audio API sound effects ├── server.js # Node.js proxy for Foundry Local └── package.json # Project configuration index.html: Defines the game canvas and UI elements. It's the entry point that loads all other modules. game.js: Contains the game loop, physics, collision detection, scoring, and rendering logic. This is the heart of the game. llm.js: Handles all communication with the AI backend. It formats game state into prompts and processes AI responses. server.js: A lightweight Express server that proxies requests between the browser and Foundry Local. sound.js: Synthesizes retro sound effects using the Web Audio API—no audio files needed! How the AI Integration Works The magic of the AI Commander happens through a simple but powerful pattern. Let's trace the flow from gameplay event to AI response. When something interesting happens in the game, you clear a wave, achieve a combo, or lose a life, the game logic in game.js triggers an AI request. This request includes context about the current game state: your score, accuracy percentage, current level, lives remaining, and what just happened. The llm.js module formats this context into a prompt. For example, when you clear a wave with 85% accuracy, it might construct: You are an AI Commander in a Space Invaders game. The player just cleared wave 3 with 85% accuracy. Score: 12,500. Lives: 3. Provide a brief, enthusiastic comment (1-2 sentences). This prompt travels to server.js , which forwards it to Foundry Local. The AI model processes the prompt and generates a response like: "Impressive accuracy, pilot! Wave 3 didn't stand a chance. Keep that trigger finger sharp!" The response flows back through the server to the browser, where llm.js passes it to the game. The game displays the message in the HUD, creating the illusion of playing alongside an AI companion. This entire round trip typically completes in 50-200 milliseconds, fast enough to feel responsive without interrupting gameplay. Using GitHub Copilot CLI to Explore and Modify the Code GitHub Copilot CLI accelerates your development workflow by letting you ask questions and generate code directly in your terminal. Let's use it to understand and extend the Space Invaders project. Installing Copilot CLI If you haven't installed Copilot CLI yet, here's the quick setup: # Install GitHub CLI winget install GitHub.cli # Windows brew install gh # macOS # Authenticate with GitHub gh auth login # Add Copilot extension gh extension install github/gh-copilot # Verify installation gh copilot --help With Copilot CLI ready, you can interact with AI directly from your terminal while working on the project. Exploring Code with Copilot CLI Use Copilot to understand unfamiliar code. Navigate to the project directory and try: gh copilot explain "How does llm.js communicate with the server?" Copilot analyzes the code and explains the communication pattern, helping you understand the architecture without reading every line manually. You can also ask about specific functions: gh copilot explain "What does the generateEnemyTaunt function do?" This accelerates onboarding to unfamiliar codebases, a valuable skill when working with open source projects or joining teams. Generating New Features Want to add a new AI feature? Ask Copilot to help generate the code: gh copilot suggest "Create a function that asks the AI to generate a mission briefing at the start of each level, including the level number and a random mission objective" Copilot generates starter code that you can customize and integrate. This combination of AI-powered development tools and AI-integrated gameplay demonstrates how LLMs are transforming both how we build games and how games behave. Customizing the AI Commander The default AI Commander provides generic gaming commentary, but you can customize its personality and responses. Open llm.js to find the prompt templates that control AI behavior. Changing the AI's Personality The system prompt defines who the AI "is." Find the base prompt and modify it: // Original const systemPrompt = "You are an AI Commander in a Space Invaders game."; // Customized - Drill Sergeant personality const systemPrompt = `You are Sergeant Blaster, a gruff but encouraging drill sergeant commanding space cadets. Use military terminology, call the player "cadet," and be tough but fair.`; // Customized - Supportive Coach personality const systemPrompt = `You are Coach Nova, a supportive and enthusiastic gaming coach. Use encouraging language, celebrate small victories, and provide gentle guidance when players struggle.`; These personality changes dramatically alter the game's feel without changing any gameplay code. It's a powerful example of how AI can add variety to games with minimal development effort. Adding New Commentary Triggers Currently the AI responds to wave completions and game events. You can add new triggers in game.js : // Add AI commentary when player achieves a kill streak if (killStreak >= 5 && !streakCommentPending) { requestAIComment('killStreak', { count: killStreak }); streakCommentPending = true; } // Add AI reaction when player narrowly avoids death if (nearMissOccurred) { requestAIComment('nearMiss', { livesRemaining: lives }); } Each new trigger point adds another opportunity for the AI to engage with the player, making the experience more dynamic and personalized. Understanding the Game Features Beyond AI integration, the Space Invaders project demonstrates solid game development patterns worth studying. Let's explore the key features. Power-Up System The game includes eight different power-ups, each with unique effects: SPREAD (Orange): Fires three projectiles in a spread pattern LASER (Red): Powerful beam with high damage RAPID (Yellow): Dramatically increased fire rate MISSILE (Purple): Homing projectiles that track enemies SHIELD (Blue): Grants an extra life EXTRA LIFE (Green): Grants two extra lives BOMB (Red): Destroys all enemies on screen BONUS (Gold): Random score bonus between 250-750 points Power-ups demonstrate state management, tracking which power-up is active, applying its effects to player actions, and handling timeouts. Study the power-up code in game.js to understand how temporary state modifications work. Leaderboard System The game persists high scores using the browser's localStorage API: // Saving scores localStorage.setItem('spaceInvadersScores', JSON.stringify(scores)); // Loading scores const savedScores = localStorage.getItem('spaceInvadersScores'); const scores = savedScores ? JSON.parse(savedScores) : []; This pattern works for any data you want to persist between sessions—game progress, user preferences, or accumulated statistics. It's a simple but powerful technique for web games. Sound Synthesis Rather than loading audio files, the game synthesizes retro sound effects using the Web Audio API in sound.js . This approach has several benefits: no external assets to load, smaller project size, and complete control over sound parameters. Examine how oscillators and gain nodes combine to create laser sounds, explosions, and victory fanfares. This knowledge transfers directly to any web project requiring audio feedback. Extending the Project: Ideas for Students Ready to make the project your own? Here are ideas ranging from beginner-friendly to challenging, each teaching valuable skills. Beginner: Customize Visual Theme Modify styles.css to create a new visual theme. Try changing the color scheme from green to blue, or create a "sunset" theme with orange and purple gradients. This builds CSS skills while making the game feel fresh. Intermediate: Add New Enemy Types Create a new enemy class in game.js with different movement patterns. Perhaps enemies that move in sine waves, or boss enemies that take multiple hits. This teaches object-oriented programming and game physics. Intermediate: Expand AI Interactions Add new AI features like: Pre-game mission briefings that set up the story Dynamic difficulty hints when players struggle Post-game performance analysis and improvement suggestions AI-generated names for enemy waves Advanced: Multiplayer Commentary Modify the game for two-player support and have the AI provide play-by-play commentary comparing both players' performance. This combines game networking concepts with advanced AI prompting. Advanced: Voice Integration Use the Web Speech API to speak the AI Commander's responses aloud. This creates a more immersive experience and demonstrates browser speech synthesis capabilities. Troubleshooting Common Issues If something isn't working, here are solutions to common problems. "AI: OFFLINE" Displayed in Game This means the game can't connect to the AI server. Check that: The server is running ( npm start shows no errors) You're accessing the game via http://localhost:3001 , not directly opening the HTML file Foundry Local is installed correctly ( foundry --version works) Server Won't Start If npm start fails: Ensure you ran npm install first Check that port 3001 isn't already in use by another application Verify Node.js is installed ( node --version ) AI Responses Are Slow Local AI performance depends on your hardware. If responses feel sluggish: Close other resource-intensive applications Ensure your laptop is plugged in (battery mode may throttle CPU) Consider that first requests may be slower as the model loads Key Takeaways Local AI enables real-time game features: Microsoft Foundry Local provides fast, free, private AI inference perfect for gaming applications Clean architecture matters: Separating game logic, AI integration, and server code makes projects maintainable and extensible AI personality is prompt-driven: Changing a few lines of prompt text completely transforms how the AI interacts with players Copilot CLI accelerates learning: Use it to explore unfamiliar code and generate new features quickly The patterns transfer everywhere: Skills from this project apply to chatbots, assistants, educational tools, and any AI-integrated application Conclusion and Next Steps You've now seen how to integrate AI capabilities into a browser-based game using Microsoft Foundry Local. The Space Invaders project demonstrates that modern AI features don't require cloud services or complex infrastructure, they can run entirely on your laptop, responding in milliseconds. More importantly, you've learned patterns that extend far beyond gaming. The architecture of sending context to an AI, receiving generated responses, and integrating them into user experiences applies to countless applications: customer support bots, educational tutors, creative writing tools, and accessibility features. Your next step is experimentation. Clone the repository, modify the AI's personality, add new commentary triggers, or build an entirely new game using these patterns. The combination of GitHub Copilot CLI for development assistance and Foundry Local for runtime AI gives you powerful tools to bring intelligent applications to life. Start playing, start coding, and discover what you can create when your games can think. Resources Space Invaders - AI Commander Edition Repository - Full source code and documentation Play Space Invaders Online - Try the basic version without AI features Microsoft Foundry Local Documentation - Official installation and API guide GitHub Copilot CLI Documentation - Installation and usage guide GitHub Education - Free developer tools for students Web Audio API Documentation - Learn about browser sound synthesis Canvas API Documentation - Master HTML5 game rendering871Views0likes3Comments
Unable to access https://cdx.transform.microsoft.com
Hello I have an organization that is a valid TSP. They want to access and use https://cdx.transform.microsoft.com/ but they are presented with the error message: Not Authorized Oops! It looks like you do not have permissions to access this page. We looked but we couldn't find your login [email address] associated to a Microsoft partner organization. How do they fix this? Who provides access? Regards Chintan PatelSolved
HOW TO RETRIEVE MY MCP ID
Good day, I passed my Microsoft E-Learning exam long time ago and I've lost all document that my MCP Id number is suppose to be on. Kindly help me. I need my document. Also the company email that I've used before is no longer available. Is there a way I can get my certificate again? Thanks in advanceSolvedMCT New and Renewing MCTs - Update July 26
Updated July 26, 2025 As we step into FY26 on July 1st, 2025, I want to share some important updates regarding the MCT Program—especially for those planning to renew. New Fees Coming October 2025, no exact date and the cost will be shared at a later date. Starting July 1st, 2025, we will introduce: A renewal fee (ecommerce tool will be available in October 2025 for everyone to renew) A new MCT enrollment fee (ecommerce tool will be available in October 2025 for new MCTs) Our systems are currently being updated to support this change, with the new tool expected to launch in October 2025. More to come on costs. Pricing will be region supported. Session Requirement for Renewal Effective January 1st, 2026, MCTs will be required to complete six (6) sessions or six (6) days of training per calendar year to qualify for renewal. For clarity on what qualifies as a session, please refer to the attached PDF: Mandatory Use of MTM We will be enforcing stricter requirements for using Metrics That Matter (MTM) to log sessions with your Training Services Partner (TSP). Please coordinate with your TSPs to ensure MTM is being used correctly. What to Expect Next More details on program costs will be shared closer to the tool’s release. All MCTs that were MCTs before manual enrollment have been extended through January 1st, 2026, with full benefits. You’ll see this extension reflected in your profile in your MCT Trainer History NOT active certification. All current MCTs will be able to renew when the tool is available in October 2025 and the requirement to renew will be to have an active certification and have taught one class since your last renewal and pay the renewal fee (costs to come later). We will be checking that you have taught the one class using MTM. New MCTs will need ISC certificate, one role-based active certification and pay the MCT new enrollment fee. New MCT Enrollment Process | Microsoft Learn 🙏 Thank you for your continued support and patience as we enhance our systems. Here’s to a successful and impactful FY26!Solved
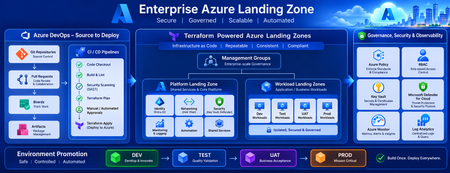
Building a Fully Automated Azure Landing Zone Deployment Using Azure DevOps and Terraform
Discover how to build a fully automated Azure Landing Zone using Azure DevOps and Terraform. This article walks through real-world Git workflows, CI/CD automation, environment promotion strategies, and governance integration to create secure, scalable, and enterprise-ready Azure environments.1.1KViews1like0CommentsDistributing Agents to Microsoft Teams and Microsoft 365 Copilot Part 4/5
This is the fourth post in our series on the Microsoft agent platform. We cover the Distribute in M365 pillar — publishing your agents to Microsoft Teams and Microsoft 365 Copilot so they reach users where they already work. All examples reference the FibreOps repository, demonstrated at Microsoft Build BRK241. The Distribution Story Building a great agent is only half the challenge. The other half is getting it into the hands of users without asking them to learn a new tool, visit a new URL, or change their workflow. Microsoft 365 Copilot and Microsoft Teams are where enterprise users already spend their day, making them the natural distribution surface for agents. With the GA release, publishing an agent to Teams and M365 Copilot is a single command. No separate app registration portal, no manual manifest assembly, no multi-step approval workflow for development and testing. Publishing to Microsoft 365 Copilot (GA) FibreOps ships as a declarative agent + action plugin ready for sideload. A single CLI command produces the complete package: python -m fibreops.demo publish-m365 --out dist/m365 # Output: # ✓ wrote dist/m365/declarativeAgent.json # ✓ wrote dist/m365/fibreops-action.json # ✓ wrote dist/m365/manifest.json # ✓ wrote dist/m365/color.png (192x192) # ✓ wrote dist/m365/outline.png ( 32x32) # ✓ wrote dist/m365/fibreops-copilot.zip What Gets Generated File Purpose declarativeAgent.json Defines the agent's persona, capabilities, and conversation starters for M365 Copilot fibreops-action.json Action plugin that proxies tool calls to the deployed FastAPI backend via OpenAPI manifest.json Teams app manifest with publisher metadata, permissions, and capabilities color.png / outline.png App icons for Teams and M365 surfaces fibreops-copilot.zip Ready-to-upload package for Teams Admin Center Configuration Set the base URL to your deployed FastAPI app before publishing — the action plugin uses this to resolve the OpenAPI runtime: # Set the public HTTPS hostname of the deployed FastAPI app $env:M365_ACTION_BASE_URL = "https://fibreops-demo.azurewebsites.net" # Optional: customise publisher metadata $env:M365_PUBLISHER_NAME = "Contoso Network Operations" $env:M365_PUBLISHER_WEBSITE = "https://contoso.com/noc" # Generate the package python -m fibreops.demo publish-m365 --out dist/m365 Environment Variable Purpose M365_ACTION_BASE_URL Public HTTPS root for the FastAPI /openapi.json (e.g., Container Apps FQDN) M365_APP_ID Override the generated Teams app GUID (default: deterministic per repo) M365_PUBLISHER_NAME Publisher name shown in M365 Admin Center M365_PUBLISHER_WEBSITE Publisher website link Uploading the Package Upload the generated fibreops-copilot.zip through either path: Teams Admin Center → Manage apps → Upload new app M365 Admin Center → Integrated apps → Upload custom apps Once uploaded, the declarative agent: Inherits the publisher metadata you configured Advertises conversation starters from the FibreOps deck (e.g., "What is the current outage status?", "Dispatch an engineer to FN-LDN-001") Proxies tool calls to the deployed FastAPI app via the action plugin Appears in Microsoft 365 Copilot as a specialised agent users can invoke How Declarative Agents Work A declarative agent in Microsoft 365 Copilot is defined by metadata rather than code running in the M365 surface. The intelligence lives in your backend — Copilot handles the conversational UX, tool orchestration schema, and user authentication. The flow: User invokes the agent in Microsoft 365 Copilot or Teams Copilot renders conversation starters and accepts natural language input When the agent needs to act, Copilot calls the action plugin (your OpenAPI endpoint) Your FastAPI backend processes the request using the full agent pipeline Results return to the user in the Copilot/Teams UX This architecture means your agent logic stays in one place — the backend. The M365 surface is purely a distribution and interaction layer. Action Plugins and OpenAPI The action plugin ( fibreops-action.json ) references your FastAPI app's /openapi.json endpoint. FibreOps exposes a JSON API that the action plugin can call: /api/runs — List and query agent runs /api/optimiser — Get optimizer scores and suggestions /sdk/chat — Natural language interaction with the agent system /healthz — Liveness probe Because FastAPI auto-generates OpenAPI schemas from your typed Python endpoints, the action plugin gets accurate parameter descriptions, response schemas, and error codes without any manual specification work. Publishing as Autopilots (Public Preview) Autopilots take distribution one step further — agents that operate autonomously without requiring a user to initiate each interaction. An Autopilot can: React to events (e.g., a critical telemetry signal) without human initiation Take actions within defined guardrails Notify users only when human intervention is needed Operate continuously across Microsoft 365 surfaces For FibreOps, an Autopilot would monitor the Event Hub stream continuously and only surface to the NOC team when an incident exceeds automated resolution capability — a fully autonomous operations agent. Teams Adaptive Cards FibreOps posts rich Adaptive Card notifications to Microsoft Teams throughout the agent pipeline. This is separate from the declarative agent — it is a push notification channel for real-time operational awareness. # The NetOps agent posts an outage notice via Incoming Webhook def post_outage_notice(incident_id, node_id, severity, summary, engineer=None): card = { "type": "AdaptiveCard", "body": [ {"type": "TextBlock", "text": f"🚨 Outage: {node_id}", "weight": "Bolder", "size": "Large"}, {"type": "FactSet", "facts": [ {"title": "Severity", "value": severity.upper()}, {"title": "Incident", "value": incident_id}, {"title": "Summary", "value": summary}, ]}, ], "actions": [ {"type": "Action.OpenUrl", "title": "View in NOC Console", "url": f"{base_url}/runs/{incident_id}"} ] } # POST to Teams webhook or append to outbox for offline mode ... If TEAMS_WEBHOOK_URL is not configured, cards are appended to state/teams_outbox.jsonl for review in the NOC console's Teams panel. End-to-End: From Code to Copilot Here is the complete flow from development to distribution: Build — Develop agents with Microsoft Agent Framework, test locally with python -m fibreops.demo --backend local Publish agents — python -m fibreops.demo publish creates hosted Prompt Agents in Foundry Deploy infrastructure — azd up provisions App Service, ACR, Event Hub, Key Vault, and Application Insights Deploy hosted agent — azd env set FIBREOPS_DEPLOY_HOSTED true && azd up Generate M365 package — python -m fibreops.demo publish-m365 --out dist/m365 Upload to Teams — Upload fibreops-copilot.zip via Teams Admin Center Users interact — The agent is now available in Microsoft 365 Copilot and Teams Security Considerations Managed Identity — The deployed app uses system-assigned managed identity for all Azure service access. No secrets in code. Least privilege — Each role grant is scoped to the minimum required (Event Hubs Data Owner, Key Vault Secrets User, AcrPull, Azure AI Developer). Authentication — The M365 Copilot surface handles user authentication; your backend receives authenticated requests. Guardrails — Autopilots operate within defined boundaries; human-in-the-loop escalation is built into the Routine and agent decision logic. Key Takeaways Publishing to Teams and M365 Copilot is GA — a single command generates the complete package. Declarative agents separate distribution (M365) from intelligence (your backend). Action plugins leverage your existing FastAPI OpenAPI schema — no manual specification needed. Autopilots (Public Preview) enable fully autonomous operation within guardrails. Adaptive Cards provide real-time push notifications alongside the conversational agent surface. The same backend serves the NOC console, the Copilot SDK, and the M365 declarative agent. Next Steps Explore the FibreOps repository — try python -m fibreops.demo publish-m365 Microsoft 365 Copilot extensibility documentation Next in this series: Voice Live and Observability for Production Agent SystemsBuilding Autonomous Agents with Microsoft Agent Framework and GitHub Copilot SDK Part 2/5
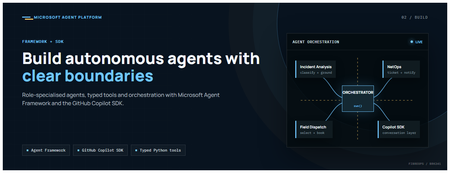
This is the second post in our series on the Microsoft agent platform. Here we dive deep into building autonomous agents, the development experience, the Microsoft Agent Framework, tool design patterns, and how the GitHub Copilot SDK brings conversational AI to your agent system. All examples reference the FibreOps repository, an autonomous fibre outage response system demonstrated at Microsoft Build BRK241. The Microsoft Agent Framework The Microsoft Agent Framework (now GA) provides a unified programming model for building agents. It supports multiple backends through a single .run() contract: Hosted — FoundryAgent connected to a Prompt Agent published to Microsoft Foundry Agent Service. Foundry — Agent + FoundryChatClient with the definition resolved locally (ideal for prompt iteration). Local — Deterministic LocalAgent for offline development and testing. This design means your orchestration code never changes regardless of where the agent runs. The factory pattern in FibreOps selects the backend at startup: # src/fibreops/agents/factory.py — simplified from agent_framework_foundry import FoundryAgent from agent_framework import Agent, FoundryChatClient def build_agent(role: str, backend: str, config: Config): if backend == "hosted": return FoundryAgent(agent_id=config.foundry_agents[role]) elif backend == "foundry": return Agent( instructions=get_instructions(role), chat_client=FoundryChatClient(endpoint=config.endpoint), tools=get_tools(role), ) else: return LocalAgent(role=role) Set FIBREOPS_AGENT_BACKEND to override the backend, or leave it as auto for intelligent detection. Designing Role-Specialised Agents FibreOps demonstrates a key pattern: role specialisation. Rather than one monolithic agent, the system uses three focused agents, each with a clear responsibility boundary: Agent Role Tools Available IncidentAnalysisAgent Classify severity, find root cause, retrieve SOP Knowledge (SOPs + topology), Web IQ, Work IQ NetOpsCoordinatorAgent File D365 incident, post Teams notice Ticketing, Teams, Memory FieldDispatchAgent Select engineer, book resource, update team Dispatch, Teams, Voice Why Role Specialisation? Focused system prompts — Each agent has a tightly scoped instruction set, reducing hallucination and improving reliability. Independent evaluation — You can score each agent separately against role-specific criteria. Parallel development — Teams can iterate on agents independently. Selective upgrade — Swap one agent's model or implementation without touching others. Tool Design: Typed Python Functions Tools in the Microsoft Agent Framework are typed Python functions that the runtime supplies to the hosted agent definition. FibreOps demonstrates several tool categories: Knowledge Tools # src/fibreops/tools/knowledge.py — simplified def sop_lookup(node_id: str, signal_type: str) -> dict: """Retrieve the Standard Operating Procedure for a given signal type. Args: node_id: The fibre node identifier (e.g., FN-LDN-001) signal_type: The type of signal (loss_of_light, high_ber, signal_degradation) Returns: SOP with steps, escalation path, and estimated resolution time. """ # Load from local markdown SOPs or Foundry IQ ... def web_iq_search(query: str, *, limit: int = 5) -> list[dict]: """Search public web for context relevant to the incident. Grounding against roadworks, weather, power outages, splice guidance. Falls back to deterministic fixtures when endpoint is unset. """ ... def work_iq_search(query: str, *, limit: int = 5) -> list[dict]: """Search enterprise knowledge for context relevant to the incident. Site surveys, SLA tiers, competency matrix, MTTR trends. """ ... Integration Tools # src/fibreops/tools/teams.py — simplified def post_outage_notice( incident_id: str, node_id: str, severity: str, summary: str, engineer: str | None = None, ) -> dict: """Post an Adaptive Card outage notice to the configured Teams channel. If TEAMS_WEBHOOK_URL is not set, appends to state/teams_outbox.jsonl for offline review. """ card = build_adaptive_card(incident_id, node_id, severity, summary, engineer) if config.teams_webhook_url: requests.post(config.teams_webhook_url, json=card) else: append_to_outbox(card) return {"status": "posted", "incident_id": incident_id} Design Principles for Agent Tools Typed parameters with docstrings — The runtime uses type hints and docstrings to generate the tool schema for the LLM. Graceful degradation — Every tool works offline by falling back to local fixtures or file-based state. Idempotent where possible — Tools that create resources return existing records if called with the same parameters. Observable — Every tool invocation emits an OpenTelemetry span for tracing and debugging. The Orchestrator Pattern The orchestrator drives signals through the agent pipeline. It is deliberately simple — a linear flow with error handling: # src/fibreops/orchestrator.py — simplified async def handle_signal(signal: TelemetrySignal) -> RunResult: """Process a telemetry signal through the agent pipeline.""" # Stage 1: Incident Analysis analysis = await incident_agent.run( f"Analyse this signal: {signal.model_dump_json()}" ) # Stage 2: NetOps Coordination coordination = await netops_agent.run( f"Coordinate response for: {analysis.summary}" ) # Stage 3: Field Dispatch dispatch = await dispatch_agent.run( f"Dispatch engineer for incident: {coordination.incident_id}" ) return RunResult( signal=signal, analysis=analysis, coordination=coordination, dispatch=dispatch, ) The orchestrator honours the same contract regardless of backend — hosted , foundry , or local — because all backends implement await agent.run(prompt) . GitHub Copilot SDK Integration (GA) The GitHub Copilot SDK enables conversational interaction with your agent system. FibreOps implements FibreOpsCopilotClient with the same interface as github/copilot-sdk : # src/fibreops/sdk/__init__.py — simplified from fibreops.sdk.client import FibreOpsCopilotClient client = FibreOpsCopilotClient() session = client.create_session() # Query agent status response = session.send_and_wait("status") print(response.text) # Human-readable summary print(response.data) # Structured JSON # Inject a telemetry signal via conversation response = session.send_and_wait(json.dumps({ "signal_id": "sig-demo", "node_id": "FN-LDN-001", "signal_type": "loss_of_light", "severity": "critical" })) The adapter routes prompts by shape: JSON signal-shaped dicts — Forwarded to the orchestrator for processing. Free-form text — Answered by a deterministic responder ( help , status , nodes , engineers , optimiser , dispatch ). Drive it from the terminal: python -m fibreops.demo chat "help" python -m fibreops.demo chat "status" python -m fibreops.demo chat '{"signal_id":"sig-demo","node_id":"FN-LDN-001","signal_type":"loss_of_light","severity":"critical"}' Or hit the embedded HTTP endpoint when the NOC console is running: Invoke-RestMethod -Method Post http://127.0.0.1:8800/sdk/chat -Body '{"prompt":"status"}' -ContentType application/json Development Workflow with Foundry Toolkit for VS Code The Foundry Toolkit for VS Code provides an integrated development experience: Author prompts — Edit system instructions with live preview and token counting. Test locally — Run against the foundry backend with FoundryChatClient pointing at your development model. Iterate fast — The foundry backend resolves definitions locally, so prompt changes take effect immediately without republishing. Publish when ready — python -m fibreops.demo publish creates hosted Prompt Agents in Foundry. Multi-Model Support The Microsoft Agent Framework supports multiple models. FibreOps defaults to gpt-4.1-mini (the model available in most demo Foundry accounts), but any chat-completions deployment works: # .env AZURE_AI_MODEL_DEPLOYMENT=gpt-4.1-mini # or gpt-4o-mini, gpt-4o, gpt-4.1 The framework also supports Claude Code connectors and Magentic-One for multi-agent collaboration scenarios. Testing Strategy FibreOps demonstrates a layered testing approach: Unit tests — Test tools in isolation with mocked dependencies. Local backend tests — Run the full pipeline with LocalAgent for deterministic assertions. Integration tests — Run against real Foundry agents with pytest -q . Rubric evaluation — The optimizer scores every run against defined criteria. # Run the test suite .\.venv\Scripts\python.exe -m pytest -q Key Takeaways The Microsoft Agent Framework provides a unified .run() contract across hosted, foundry, and local backends. Role specialisation keeps agents focused, testable, and independently evolvable. Tools are typed Python functions with docstrings — the runtime generates schemas automatically. The GitHub Copilot SDK (GA) enables conversational interaction with any agent system. Graceful degradation means the entire system works offline for development. The factory pattern lets you switch backends without changing orchestration code. Next Steps Clone the FibreOps repository and run python -m fibreops.demo --signals 3 Microsoft Agent Framework documentation Next in this series: Running Hosted Agents in Microsoft Foundry Agent Service
Vector search finds candidates. Reranking decides what your RAG app reads
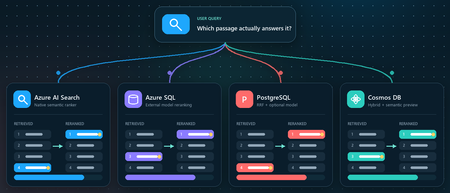
You ask a retrieval-augmented generation (RAG) application a question. Vector search returns ten passages that are clearly related to the topic. The passage that actually contains the answer, however, is ranked seventh, while the language model receives only the first five. Retrieval did not completely fail. It found the evidence, but ordered it below less useful context. Reranking addresses that gap between a passage that is semantically similar and a passage that is relevant to the user's specific question. This article demonstrates that pattern in four Azure services using the Stanford Question Answering Dataset (SQuAD). The goal is not to declare a winning service or publish a quality benchmark. It is to show where retrieval, rank fusion, and model-based reranking run in each architecture, and to illustrate how the position of a known source passage can change. What this demonstration establishes The examples show rank movement for three selected questions. They do not establish that one reranker or service is universally more accurate. A production decision requires a larger, representative query set and aggregate relevance, latency, and cost measurements. Get the full Python implementation: pauldj54/azure-vector-reranking-squad Retrieval and reranking are different stages A production search pipeline commonly uses two stages: Retrieve for recall. Fast retrieval narrows a large corpus to a bounded candidate set. It can use vector search, keyword search, or both. Rerank for precision. A more expensive model evaluates only those candidates against the original query and produces the final order. Reciprocal Rank Fusion (RRF) belongs between those two ideas. RRF is a model-free rank aggregation method that merges independent result lists, usually vector and keyword results. For a document d, a typical score is: RRF(d) = ∑ r ∈ R 1 k + rank r (d) Here, R is the set of ranked lists and k is commonly 60. RRF works with positions rather than raw scores, so it can combine signals such as cosine distance and BM25 without pretending their score scales are comparable. This gives a clearer three-part vocabulary: Stage Purpose Typical mechanism Retrieve Find broad candidate set Vector search, BM25, filters Fuse Combine independent rankings RRF Rerank Reassess query-document relevance Semantic ranker or cross-encoder RRF often improves hybrid retrieval when exact names, dates, identifiers, or terms matter. A learned reranker can then read the query and each candidate together, capturing interactions that separately generated embeddings can miss. The learned stage costs more, so it should operate on tens of candidates rather than the whole corpus. The following image describes the general process: Why use SQuAD for this demonstration? SQuAD 1.1 contains crowd-written questions over more than 500 Wikipedia articles. Its packaged splits contain 87,599 training rows and 10,570 validation rows. Each row includes a question, a context passage, and one or more answer spans inside that passage. That source-context mapping gives this demonstration a useful label: the context associated with a question is treated as its gold passage. We can then inspect whether each search stage moves that passage up or down. This is convenient, but it is not a perfect passage-ranking benchmark. SQuAD was designed for extractive question answering, and another passage in the corpus might also answer a question. The gold context is therefore a reproducible reference, not proof that every other passage is irrelevant. The results shown here use the 2,067 unique contexts in the SQuAD validation split and 1,536-dimensional embeddings. The repository default should be set to the same corpus size before treating the screenshots or rank transitions as directly reproducible. Three illustrative questions Question Expected answer Gold context According to game stats, which Super Bowl 50 quarterback had his worst year since his first NFL season? Peyton Manning 12, Super Bowl 50 What else did Tesla do for work at this time? Various electrical repair jobs 165, Nikola Tesla Who acts as laborer, paymaster, and design team for a renovation project? The property owner 1306, Construction Each notebook selects a seeded demonstration question when it runs. The three saved examples were collected across separate runs; the current notebooks do not execute all three questions in one pass. A benchmark harness should iterate over a fixed question list and save all stage results in one structured output. Capability boundaries at a glance Service Retrieval and Fusion Learned Reranking Boundary to Keep in Mind Azure AI Search Native keyword and vector retrieval with native RRF Built-in semantic ranker Semantic ranking only reorders the retrieved top 50 Azure SQL Database Exact vector retrieval in the current notebook External Cohere model invoked through native REST procedure SQL issues the HTTPS request; Foundry performs inference PostgreSQL Flexible Server pgvector plus hand-written SQL RRF over full-text search Optional external Cohere call from Python Retrieval primitives are native; this RRF query and Cohere path are application code Azure Cosmos DB for NoSQL Native vector search and native hybrid RRF SDK-integrated Semantic Reranker, currently preview Reranking is a separate inference call over at most 50 supplied documents Azure AI Search: native hybrid retrieval and semantic ranking How it works: Azure AI Search provides the most integrated pipeline in this demonstration. A hybrid query runs keyword and vector retrieval, combines the lists with RRF, and passes up to the top 50 results to the built-in semantic ranker. The semantic ranker assigns @search.rerankerScore values from 0 to 4 and can return extractive captions and answers. The semantic configuration identifies the fields that carry the meaning of each document: semantic_search = SemanticSearch( configurations=[ SemanticConfiguration( name=SEMANTIC_CONFIG, prioritized_fields=SemanticPrioritizedFields( title_field=SemanticField(field_name="title"), content_fields=[SemanticField(field_name="content")], ), ) ] ) This tells the semantic ranker which text fields to evaluate. The query then enables semantic ranking after hybrid retrieval: results = search_client.search( search_text=question, vector_queries=[vector_query], query_type="semantic", semantic_configuration_name=SEMANTIC_CONFIG, top=10, ) The important constraint is candidate recall. Semantic ranking does not search the corpus again. If the correct passage is absent from the hybrid top 50, the semantic stage cannot recover it. See 01_azure_ai_search_reranking.ipynb for the complete setup and query path. Test results for Azure AI Search These examples show that semantic reranking improves relevance selectively, not universally. It strongly helps the construction query, moving the correct passage from rank 4 to rank 1, but slightly degrades the Super Bowl and Tesla queries by one position. This reinforces that semantic ranking should be evaluated across a representative query set using aggregate metrics such as MRR or NDCG, rather than judged from a single result. Azure SQL Database: vector retrieval plus external Cohere reranking How it works. The Azure SQL notebook retrieves 20 candidates with exact cosine distance and sends their text to Cohere Rerank v4.0 Fast through sys.sp_invoke_external_rest_endpoint. The vector column and query vector must have the same dimensions. This repository uses 1,536-dimensional embeddings: SELECT TOP (@ candidate_count) context_id, title, content, 1 - VECTOR_DISTANCE( 'cosine', CAST(@ query_vector AS VECTOR(1536)), embedding ) AS similarity FROM dbo.documents ORDER BY similarity DESC; For reranking, we selected Cohere Rerank v4.0 Fast (Cohere-rerank-v4.0-fast), a fast version of Cohere’s fourth-generation relevance-ranking model. The model is deployed in Microsoft Foundry, where its Azure Direct inference endpoint is available in the deployment details within the Foundry portal. Azure SQL can call REST APIs directly using sp_invoke_external_rest_endpoint. Because Azure SQL allowlists Azure AI’s *.cognitiveservices.azure.com domain, we translate the equivalent Foundry endpoint from *.services.ai.azure.com while preserving the Cohere reranking route. from urllib.parse import urlsplit, urlunsplit def sql_compatible_endpoint(endpoint: str) -> str: """Convert an Azure Direct endpoint to Azure SQL's allowed hostname.""" parts = urlsplit(endpoint) if parts.hostname.endswith(".services.ai.azure.com"): resource = parts.hostname.removesuffix(".services.ai.azure.com") hostname = f"{resource}.cognitiveservices.azure.com" elif parts.hostname.endswith(".cognitiveservices.azure.com"): hostname = parts.hostname else: raise ValueError("Expected an Azure AI Services endpoint.") return urlunsplit( (parts.scheme, hostname, parts.path, parts.query, "") ) Then I defined a re-rank with cohere function, starting by loading the endpoint and setting the authentication: def rerank_with_cohere( cursor, question: str, candidates: list[dict], top_n: int = 10, ) -> list[dict]: """ Rerank candidate documents by calling Cohere through Azure SQL. Each candidate must contain a 'content' field. """ if not candidates: return [] sql_endpoint = sql_compatible_endpoint( os.environ["COHERE_RERANK_ENDPOINT"] ) model = os.environ["COHERE_RERANK_MODEL"] access_token = credential.get_token( "https://cognitiveservices.azure.com/.default" ).token headers = json.dumps({"Authorization": f"Bearer {access_token}"}) payload = json.dumps( { "model": model, "query": question, "documents": [row["content"] for row in candidates], "top_n": min(k, len(candidates)), }, ensure_ascii=False, ) cursor.execute( """ DECLARE @url NVARCHAR(4000) = CAST(? AS NVARCHAR(4000)); DECLARE @headers NVARCHAR(4000) = CAST(? AS NVARCHAR(4000)); DECLARE Payload NVARCHAR(MAX) = CAST(? AS NVARCHAR(MAX)); DECLARE Response NVARCHAR(MAX); DECLARE @status INT; EXEC @status = sys.sp_invoke_external_rest_endpoint @url = @url, @method = 'POST', @headers = @headers, Payload = Payload, @timeout = 60, @retry_count = 2, Response = Response OUTPUT; SELECT @status, Response; """, sql_endpoint, headers, payload, ) status, response_text = cursor.fetchone() if status != 0: raise RuntimeError(f"Reranker endpoint returned HTTP status {status}.") response = json.loads(response_text)["result"] You can see the complete implementation in the 02_azure_sql_reranking.ipynb notebook. Test results for Azure SQL Db Across the three sample questions, Cohere reranking consistently moved the correct SQuAD passage closer to the top: from rank 5 to 1 for the Super Bowl question, 3 to 2 for the Tesla question, and 8 to 1 for the construction question. These examples show how vector search provides a strong candidate set, while reranking applies deeper query-document relevance scoring to improve the final ordering. The results are illustrative rather than a complete quality benchmark, so broader evaluation across many queries is still recommended. Azure Database for PostgreSQL flexible server: pgvector, SQL RRF, and an optional model How it works: PostgreSQL makes the pipeline components explicit. The notebook uses pgvector for vector similarity, PostgreSQL full-text search for keyword retrieval, and SQL to implement RRF. Vector retrieval uses cosine distance: SELECT context_id, title, content, 1 - (embedding <= > % (query_vector) s:: vector) AS similarity FROM squad_docs ORDER BY embedding <= > % (query_vector) s:: vector LIMIT % (candidate_count) s; The hybrid query independently ranks vector and keyword hits, then combines positions rather than raw scores: SELECT d.context_id, COALESCE(1.0 / (60 + v.rank), 0) + COALESCE(1.0 / (60 + k.rank), 0) AS rrf_score FROM squad_docs AS d LEFT JOIN vector_hits AS v USING (context_id) LEFT JOIN keyword_hits AS k USING (context_id) WHERE v.context_id IS NOT NULL OR k.context_id IS NOT NULL ORDER BY rrf_score DESC; This is not a built-in PostgreSQL RRF operator. It is transparent, hand-written SQL over native retrieval primitives, which makes weighting and debugging flexible but leaves implementation and tuning with the application team. The notebook's optional learned stage sends the vector candidates from Python to a Foundry deployment of Cohere Rerank v4.0 Fast. This path was chosen because the tested Flexible Server azure_ai extension version expected the older serverless reranking endpoint contract. Microsoft documentation still describes azure_ai.rank() as a preview function whose default model is Cohere Rerank v3.5, even though that model retired on May 14, 2026. Treat this as a version-specific compatibility issue and verify current extension behavior before selecting an architecture. Azure HorizonDB is a different product path. Its AI Model Management feature can provision Cohere Rerank v4.0 Fast as default-reranker, but that management feature is currently a limited preview. It should not be described as a generally available Flexible Server capability. See 03_azure_postgres_reranking.ipynb for the full SQL and optional external model path. Test results for Azure SQL for PostgreSQL Flexible Server The tests show that PostgreSQL vector search provides a useful candidate set, SQL RRF can substantially improve results when keyword evidence is strong, and the Cohere semantic reranker is the most consistent overall: it moved the correct passage to rank 1 in two tests and from rank 3 to rank 2 in the Tesla test. RRF produced the biggest gain for the construction question, moving the correct passage from outside the vector top five to rank 1, but did not improve every query. The scores across stages are not directly comparable because cosine similarity, RRF score, and Cohere relevance use different scales. Azure Cosmos DB for NoSQL: hybrid search with built-in RRF How it works: Azure Cosmos DB for NoSQL supports native hybrid ranking with VectorDistance, FullTextScore, and RRF inside ORDER BY RANK: SELECT TOP K C.context_id, c.title, c.text FROM c ORDER BY RANK RRF( VectorDistance(c.vector, @query_vector), FullTextScore(c.text, @term1, @term2, @term3) ) The notebook extracts distinct terms from the question before building the full-text part of the query. That token selection is application logic and can materially affect the hybrid ranking, so production evaluation should test analyzers, languages, term extraction, and optional RRF weights. Cosmos DB Semantic Reranker is an SDK-integrated preview feature. The application first runs a query, serializes the resulting documents, and submits those documents with the user's context string: result = container.semantic_rerank( context=question, documents=documents, options={ "return_documents": False, "top_k": min(k, len(documents)), "sort": True, "document_type": "json", "target_paths": "title,text", }, ) The service accepts at most 50 documents per rerank call and returns relevance scores from 0 to 1, plus inference latency and token usage. It uses the Microsoft semantic ranking model also used by Azure AI Search. The reranking call requires Microsoft Entra authentication, the appropriate Semantic Reranker role, and an account-linked inference endpoint. The 04_azure_cosmosdb_reranking.ipynb in the shared repo contains and end-to-end implementation. Test results for Azure Cosmos Db The results show that vector search provides a strong baseline, while hybrid RRF and semantic reranking improve different queries in different ways. Hybrid RRF helps when exact keywords matter, moving the construction answer into the top results, while the semantic reranker delivers the strongest overall ordering, promoting the correct construction passage from hybrid rank 3 to rank 1 and improving the Super Bowl answer from rank 5 to rank 2. However, it does not always place the gold passage first, as seen in the Tesla example, confirming that reranking improves relevance but is query-dependent and should be evaluated across a larger test set. What the examples do and do not show The four services expose different ownership boundaries: • Azure AI Search owns hybrid fusion and learned semantic ranking inside the search service. • Azure SQL owns vector retrieval and outbound REST invocation in this example, while Foundry owns model inference. • PostgreSQL supplies vector and full-text primitives; the application owns the RRF SQL and optional Cohere call. • Cosmos DB provides native hybrid RRF and integrates a separate preview inference call through its SDK. Across three selected questions, the known source passage often moved substantially. That supports the practical value of testing a second-stage ranker. It does not prove that semantic reranking always improves top-1 accuracy, that RRF is universally beneficial, or that scores from different stages can be compared directly. Cosine similarity, RRF score, Azure AI Search reranker score, Cohere relevance, and Cosmos DB semantic relevance all have different definitions and scales. Compare rank positions and task-level metrics, not raw values across systems. Turn the demonstration into an evaluation For a production RAG system, convert the notebook pattern into a repeatable evaluation harness: Build a representative labeled query set from real user tasks. Freeze corpus, chunking, embedding model, dimensions, and candidate counts for each run. Record ranks after retrieval, fusion, and learned reranking. Measure Recall@k or Hit@k to verify that retrieval finds relevant evidence. Measure Mean Reciprocal Rank (MRR) when the position of the first relevant result matters. Use NDCG when judgments include multiple passages or graded relevance. Record latency percentiles, inference usage, request cost, and failure rates. Evaluate the generated answer separately for correctness, citation support, and refusal behavior. Also test the operational cases that a three-question demonstration cannot cover: empty keyword results, missing gold passages, long documents, multilingual text, filters, partial outages, token expiration, throttling, model retirement, and low-confidence scores. Practical guidance Retrieve broadly enough that the correct evidence can reach the learned stage. Use RRF when vector and keyword retrieval provide complementary signals. Rerank a bounded candidate set, commonly 20 to 50 passages, and measure the latency cost. Keep citations and source identifiers through every rank transformation. Version the corpus, embedding model, dimensions, query set, and reranker deployment. Do not hard-code assumptions about model endpoints or lifecycle dates. Verify current service documentation and the deployed extension or SDK version. Add thresholds or fallback behavior only after calibrating scores on your own data. Judge the full RAG chain. Better passage order is valuable only when it improves grounded answers for users. Vector search is built to find plausible candidates quickly. Rank fusion can reconcile retrieval signals, and a learned reranker can decide which candidates best address the question. The right architecture depends on where your data lives, which service boundaries you want to operate, and what your evaluation says about quality, latency, and cost. Resources Companion repository Azure AI Search semantic ranker Azure SQL VECTOR_DISTANCE Azure SQL sp_invoke_external_rest_endpoint Azure Database for PostgreSQL AI functions Microsoft Foundry model retirement schedule Azure Cosmos DB hybrid search Azure Cosmos DB Semantic Reranker SQuAD dataset card Dataset attribution Rajpurkar, P., Zhang, J., Lopyrev, K., and Liang, P. (2016). SQuAD: 100,000+ Questions for Machine Comprehension of Text. EMNLP 2016. SQuAD 1.1 is distributed under CC BY-SA 4.0.
Question about Microsoft IT specialist certification, in relation to Coursera.
Please, bear with me, as it took me 3 hours just to get navigated here for help. I am taking IT courses with Coursera. I am not an IT professional...I am trying to change my career and my life. I was taking Googles IT Support Specialist course, but after 4 days of classes, I came across a major roadblock: Outdated information on their QwikLabs setup. The course was at least a year behind, the Demo on how to use Qwiklabs was seriously outdated, and Google has changed Qwiklabs into a "Pay to Create" gimmick that really doesn't work for anyone that is a Student, imo. $25+ to create a project, per project, and then 3 cents an hour while its running, can build up really fast. It was also changes and charges that Coursera was unaware of. So, how does this relate? I want to switch over to Microsoft IT Support courses and certification, but i want to make sure that its up to date, and that i won't run into another "out of the course" pay wall structure, because i really don't have that kind of money to throw around like that. It may not seem like a major deal to alot of people, but I am maintaining two households, on two continents, off one paycheck, and Im a kitchen employee...so Im sure alot of people can relate to how this is suddenly an issue. Can anyone verify how up-to-date that course is, from Microsoft, on Coursera? Im trying to change my life, and its already upsetting finding i wasted a weeks worth of effort.Train a simple Recommendation Engine using the new Azure AI Studio
The AI Studio Odyssey: Embark on a journey to the heart of personalization with our latest guide, “Train a Simple Recommendation Engine using the new Azure AI Studio.” Unlock the secrets of the all-new Azure AI Studio intuitive tools to craft a recommendation system that feels like magic, yet is grounded in data and user preferences. Ready to enchant your audience? Grab some popcorn and read on!6.8KViews0likes2Comments