azure sql database
558 TopicsLessons Learned #559: Understanding query timeouts in Azure SQL Database
In a recent support case, an application using Hibernate and the Microsoft JDBC Driver for SQL Server reported "The query has timed out". The application team had timestamps for the failures, but the SQL evidence reviewed did not show matching query cancellations. This raised a question that developers and DBAs frequently ask: If the exception contains SQLServerException, does that mean the database engine generated the timeout? The important distinction is where the timeout is reported and enforced, versus what caused the operation to exceed that limit. A command timeout is controlled by the client. Its underlying cause can still be a slow query, blocking, a communication delay, or another issue along the client and database path. In this article, we will explain that distinction, what to capture when it happens, and when increasing the command timeout can be appropriate. The examples use invented values and generic statements; no customer identifiers or application SQL are included. First identify which timeout occurred An application request can wait at several different stages. Before changing a setting, identify the stage that failed. Stage What to check Acquiring a connection from the pool Pool capacity, connection lifetime, and the pool acquisition timeout Establishing a database connection Connection or login timeout, endpoint, authentication, and handshake evidence Executing a SQL command Effective JDBC query timeout or SqlClient CommandTimeout, query execution, and blocking Communicating with the server Driver socket settings and evidence of interrupted or delayed communication Processing the application request ORM processing and the application's request or transaction deadline Changing a connection timeout does not increase the query timeout. Similarly, an HTTP request deadline is not the same setting as a database command timeout. A failure while obtaining a pooled connection should not automatically be investigated as a query that timed out in SQL. The Microsoft JDBC timeout documentation distinguishes these settings. JDBC queryTimeout and cancelQueryTimeout use seconds; socketTimeout uses milliseconds. Understand what the exception tells us The useful part of the exception chain in this case was: org.hibernate.QueryTimeoutException Caused by: java.sql.SQLTimeoutException: The query has timed out. Caused by: com.microsoft.sqlserver.jdbc.SQLServerException: The query has timed out. ... TDSCommand.checkForInterrupt(...) The stack places the observed exception in the client/JDBC execution and response handling path, propagated through Hibernate. SQLServerException is a driver exception class. Its presence alone does not establish that SQL Server generated a corresponding engine error. This is a client reported query timeout. That describes the observed error, not the root cause. If blocking prevents a command from completing before the client's limit, the client raises the timeout, while the delay is explained by database activity. Developers and DBAs need to investigate the same attempt together. What queryTimeout actually controls The Microsoft JDBC Driver uses queryTimeout to limit its wait for a server response after sending an execute command. When that timeout expires, the documented behavior is to cancel the command. cancelQueryTimeout controls the subsequent wait for acknowledgment of cancellation before the driver closes the connection. These settings do not define an exact stopwatch for the entire business request. Pool acquisition, connection establishment, cancellation handling, retries, and application processing can have different deadlines. The caller's total elapsed time can therefore differ from the configured query timeout. For JDBC, setQueryTimeout sets the timeout on a statement in seconds. In .NET, the corresponding setting is SqlCommand.CommandTimeout. Its documented semantics include network reads during command execution or result processing; it is not a limit on all user code that processes those results. The default is also provider dependent. SqlClient documents a 30 second default. Do not assume the same default for JDBC or for statements created by an ORM. Check the effective value used by the failing operation. This client command timeout is not an Azure SQL Database engine configuration setting. The same distinction applies when the application connects to Azure SQL Managed Instance or SQL Server on an Azure VM. How a command timeout becomes an Attention The application configures the driver's deadline; it does not send a "CommandTimeout" SQL error to the engine. The diagram shows the cancellation path for a request already sent through the Microsoft JDBC Driver. If the command completes within the limit, no timeout driven Attention is needed. Figure 1. The application owns the deadline. The driver enforces it and requests cancellation; the engine handles the SQL request. The values are illustrative, not recommended settings. For an already submitted request, Attention is a TDS cancellation message. SQL Server marks the request for cancellation and honors it at yield points, as described in the Attention and error 3617 guidance. The timer expiring and the engine stopping are not necessarily simultaneous. The driver consumes the remaining response until it receives the cancellation acknowledgment. The TDS cancellation state describes this response cleanup. A query timeout normally leaves the connection open after that exchange; it does not immediately cut off all communication. If no acknowledgment arrives and a configured cancelQueryTimeout expires, the Microsoft JDBC Driver closes the connection. A socket timeout or transport failure can also close it. Closing the socket alone does not establish the SQL operation's outcome. Other providers can have different cancellation and connection handling details. What we could conclude from the case We reviewed the reported failure windows, the available SQL activity, and the query identified by the application team. Some client initiated aborts were recorded, but we could not correlate them with the reported failures. The resource metrics reviewed did not establish resource pressure as the cause either. The supported conclusion was that the client reported a query timeout, while the SQL evidence reviewed did not identify a matching cancellation or establish the root cause. Further correlation was required. The reported statement was a SELECT. The transaction and write examples later in this article explain additional design considerations; they are not findings of failed writes or abandoned transactions in this case. Statistics maintenance had also been performed, but that action did not establish why the client timed out. A fast maximum or average in the available query statistics does not prove that the failed attempt was fast. Confirm the query, parameter types, destination database and replica, execution context, and time window. Successful executions and retries may appear alongside the attempt that failed. Developers should capture each failed attempt The message alone is not enough. Record the failure as an individual attempt that a DBA can correlate with database evidence. Evidence to record Why it matters UTC start and error timestamps and elapsed time Establish the failure window and observed duration Request correlation identifier and attempt number Separate the original call from retries Full exception chain and available SQLState or error code Identify the provider and phase reporting the failure Driver and ORM versions and effective timeout with its unit Establish which settings actually applied Parameterized SQL template and parameter types Identify the statement without publishing customer data Protected destination and connection identifiers Correlate with the correct database, replica, and session Measure pool acquisition, execution, result reading, and subsequent application processing separately. A request duration alone cannot tell us where the time was spent. If the ordinary logs are insufficient, collect a targeted JDBC driver trace during the same window. Keep credentials and personal data out of diagnostic examples. Retain the necessary correlation details in controlled diagnostic records and anonymize them before sharing publicly. DBAs should correlate cancellations with execution evidence On the database side, use Extended Events to capture sqlserver.attention together with relevant batch or RPC start and completion events. Correlate the timestamps and session or connection information with the application's failed attempt. The query timeout troubleshooting guidance describes this approach. An Attention indicates a client cancellation signal, but it does not identify why the client canceled. A user pressing Cancel can also produce it. Compare the associated execution duration with the application's effective timeout and logs; do not interpret the Attention event's own duration as the query's total runtime. Query Store adds historical context. In sys.query_store_runtime_stats, execution_type = 3 means client initiated aborted execution. It is not an exclusive count of query timeouts. Query Store statistics are aggregated. Select intervals overlapping the incident window, aggregate rows for the same plan, execution type, and interval, and examine both aborted and regular executions. Filtering only on last_execution_time can miss relevant activity within an interval. A query hash identifies a query family, not an individual request. For additional examples, see Lesson Learned 1 on capturing a TSQL command timeout, Lesson Learned 202 on reproducing and finding a command timeout, and Lesson Learned 525 on tracking timeouts beyond Query Store with Extended Events. For Azure SQL Database, use database scoped Extended Events. Check capture coverage, filters, retention, and possible event loss before interpreting missing events. Do not expect every command timeout to appear in the SQL error log. Also check transaction cleanup. Canceling a statement does not guarantee that the entire explicit transaction has been rolled back. The application's error handling must account for the resulting transaction state, as explained in the Azure SQL blocking guidance. When increasing the command timeout makes sense In Lesson Learned 253 and Lesson Learned 372, I shared examples that increase the execution timeout across retry attempts, including a PowerShell example. That technique changes how long the client is prepared to wait. It does not make the SQL statement execute faster. A bounded increase may be appropriate when the workload legitimately needs more time, or as a temporary mitigation while investigating. It can also help a controlled diagnostic execution complete so its behavior can be examined. If the operation normally completes quickly but suddenly exceeds the limit, investigate blocking, plan changes, resource waits, and communication before treating a larger timeout as the permanent solution. Verify the change against representative load and the application's response time requirements. The following examples show where the setting belongs. They assume an already open connection and run a generic statement with an intentional delay. Use them only in a test environment. For Java with the Microsoft JDBC Driver: try (java.sql.Statement statement = connection.createStatement()) { statement.setQueryTimeout(20); // seconds statement.execute("WAITFOR DELAY '00:00:12'; SELECT 1;"); } For .NET with Microsoft.Data.SqlClient: using var command = connection.CreateCommand(); command.CommandTimeout = 20; // seconds command.CommandText = "WAITFOR DELAY '00:00:12'; SELECT 1;"; using var reader = command.ExecuteReader(); With a 5 second command timeout, the deliberate 12 second delay should produce a timeout. With 20 seconds, the operation should have time to complete under normal test conditions. The delay has not become shorter; only the client's permitted wait has changed. This demonstrates the mechanism, not a fix for the original case. For each test, record the UTC start and end, effective timeout, elapsed time, exception, and attempt identifier. Capture Attention and the related execution events at the same time. Compare the two runs: the application setting changed, while the SQL statement and database configuration remained the same. Use the captured events to verify the expected behavior rather than assuming exact timestamps or a fixed event count. When an ORM creates the statement, apply the equivalent setting through the supported ORM configuration and verify its effective value and unit. Setting setQueryTimeout(0) or CommandTimeout = 0 removes that statement's timeout limit; it should not be a routine response to unexplained failures. If retries are used, record the timeout on every attempt, limit the attempts, allow a delay between them, and keep the total within the request's overall deadline. Transactions determine what must succeed or fail together A single UPDATE, INSERT, or DELETE already executes within a transaction in autocommit mode. Use an explicit transaction when several statements form one business operation and must be committed or rolled back together. The transaction documentation describes these transaction modes. For example, an application might UPDATE inventory, INSERT an order, and DELETE its reservation. If the first two statements finish and the third is canceled, the outcome depends on how the unit of work was managed. Transaction design What the application must account for Each statement in autocommit Earlier statements may already be committed. Canceling the later statement does not undo those earlier commits. One explicit transaction for all three statements Earlier changes remain part of that transaction until it is committed or rolled back. An Attention alone does not guarantee rollback of the whole transaction. COMMIT sent but its confirmation not received The client may not know whether the transaction committed. Verify the outcome before retrying the business operation. One transaction preserves the intended unit of work; it does not replace timeout and error handling. An open transaction left after cancellation can retain locks and delay other sessions. A poorly handled timeout can therefore contribute to further timeouts. Keep the transaction as short as the business rules allow. Do not include user interaction or unrelated external calls while holding it open. A command timeout also does not automatically limit the transaction's total duration: if the application sends several commands separately, each command has its own limit. Track the total operation deadline as well. A rollback inside TSQL CATCH may never run for Attention This is an important detail for developers: T-SQL TRY CATCH does not catch Attentions, including client interrupt requests. Placing ROLLBACK only in a stored procedure's CATCH block is therefore insufficient protection against a client cancellation. The application or ORM that owns the transaction must handle the failed call and resolve that transaction. Attempt rollback using its transaction API when the connection remains usable; log cleanup failures separately and do not continue using an unresolved transaction. A rollback attempt is not proof of a completed rollback. Follow the provider's cleanup rules before returning the connection to normal pool use. SET XACT_ABORT ON controls transaction abortion for applicable runtime errors. Microsoft's Attention and transaction guidance also describes it as a way to control rollback when a cancellation occurs. Set it deliberately for the SQL session or batch and validate the behavior with the actual driver, ORM, and transaction ownership model. It does not change CommandTimeout, and it cannot undo a transaction that already committed. In a disposable test environment, repeat the cancellation experiment inside a transaction after a small data modification. Compare XACT_ABORT OFF and ON. After cancellation acknowledgment, inspect transaction state on the same usable connection and ensure cleanup. If cancellation closes the connection, record that outcome instead of claiming to have queried its former session. This test is separate from the original SELECT investigation. A timeout does not establish whether a write committed If a connection fails after COMMIT was processed but before its acknowledgment reaches the application, the client can receive an error even though the changes were committed. Retrying an INSERT or increment blindly can then duplicate a business operation. Microsoft's connection resiliency documentation describes this commit failure and idempotency issue. Use a stable operation identifier that is reused across retries. Record it atomically with the business changes and enforce uniqueness in the database, so a repeated attempt can identify the prior operation rather than apply it again. If the original transaction is still in progress, resolve or wait for its outcome; an absent record in a single check is not always conclusive. The transaction provides atomicity for the changes. An operation identifier and deliberate retry handling help the application manage an uncertain result. Together, they make the timeout response part of the business operation's design.Lessons Learned #558: What an Execution Plan XML Can Tell Us in Azure SQL Database
During a performance investigation in Azure SQL Database, we requested the execution plan to understand what the query was doing. While reviewing the evidence, the customer asked a broader question: when you open the XML of an execution plan, what do you usually look for? It was a useful question. The graphical plan helps us follow the flow of data, but the XML contains details about parameters, statistics, warnings and execution that can explain why the query behaved as it did. I do not read every attribute. I start with a few checks that help connect the customer symptom to the work performed by the query. In this article, I will walk through those checks: the type of plan, parameter values, estimated versus actual rows and statistics, missing indexes and implicit conversions, and reasons for a serial plan. The XML fragments below are simplified examples that use invented values or are adapted from examples discussed in previous articles in the Lessons Learned troubleshooting series. First check whether the plan contains execution evidence Plan What we can inspect Estimated plan Optimizer choices and estimates; the query has not executed Actual plan Plan plus available counters and warnings from that execution Cached or Query Store plan Compiled plan; normally no operator actuals for the incident For the checks involving actual rows, I request an actual execution plan. In SSMS, use Include Actual Execution Plan, or capture it using SET STATISTICS XML. Choose one method. The latter executes the query and returns its plan. The account needs the permissions to run the statement and SHOWPLAN permission. SET STATISTICS IO ON; SET STATISTICS TIME ON; SET STATISTICS XML ON; -- Execute the SELECT being investigated here. SET STATISTICS XML OFF; SET STATISTICS TIME OFF; SET STATISTICS IO OFF; Save the plan as a .sqlplan file and keep the Messages output. Record when it was captured, the parameters and the reported symptom. An execution captured later may not represent the incident. Review query literals, parameter values and object names before sharing the file. Check the right statement and its parameters A procedure or batch may contain several statements. I locate the relevant StmtSimple and its QueryPlan before interpreting a warning. StatementId and operator NodeId help keep the observations attached to the correct statement and operator; NodeId is not a stable identifier across different compilations. Next, I look at ParameterList. When available, it shows both the value used when the plan was compiled and the value used during the captured execution. <ParameterList> <ColumnReference Column="@CustomerId" ParameterDataType="int" ParameterCompiledValue="(42)" ParameterRuntimeValue="(900)" /> </ParameterList> Here, the plan was compiled with CustomerId 42 and executed with CustomerId 900. If one customer has a few orders and another has thousands, I would compare their data distribution and actual plans. Different values are a reason to investigate parameter sensitivity; they do not prove that plan reuse caused the problem. A missing runtime value means this capture did not provide it. It does not mean the runtime value was the same as the compiled value. Also, eligible queries can intentionally use different plan variants through Parameter Sensitive Plan optimization. Make the comparison match the application If the query is slow in the application but fast in SSMS, I compare the SQL text, parameter types and values, database context and session options. StatementSetOptions records options associated with compilation. <StatementSetOptions ARITHABORT="true" ANSI_WARNINGS="true" ANSI_NULLS="true" QUOTED_IDENTIFIER="true" ANSI_PADDING="true" CONCAT_NULL_YIELDS_NULL="true" NUMERIC_ROUNDABORT="false" /> A difference in context can help explain why the application and SSMS use different cached plans. I capture both rather than assuming that a fast SSMS execution represents the application. The difference itself still needs to be connected to the measured performance. Compare estimated and actual rows then inspect statistics I follow the rows through the plan and look for the first useful difference between what the optimizer expected and what the operator actually processed. <RelOp NodeId="3" PhysicalOp="Index Seek" LogicalOp="Index Seek" EstimateRows="100"> <RunTimeInformation> <RunTimeCountersPerThread Thread="0" ActualRows="20000" ActualRowsRead="80000" ActualExecutions="1" /> </RunTimeInformation> <!-- Access details omitted --> </RelOp> In this single-execution example, the operator estimated 100 rows and returned 20,000: a 200-fold underestimate. It also read 80,000 rows. I would ask why the estimate was inaccurate, and why the operator read substantially more rows than it returned. These are separate questions. For repeated or parallel operators, account for executions and threads before comparing totals. Do not add the rows from every operator to calculate the query result size. The next question is often whether the statistics were out of date. OptimizerStatsUsage identifies statistics consulted during compilation, where that information is exposed. <OptimizerStatsUsage> <StatisticsInfo Schema="[PlanXmlLab]" Table="[Orders]" Statistics="[IX_Orders_CustomerId]" LastUpdate="2026-10-10T07:00:00" SamplingPercent="20" ModificationCount="15000" /> </OptimizerStatsUsage> I check the relevant statistics object, its LastUpdate, SamplingPercent and ModificationCount together. An old timestamp or a low sampling percentage alone does not prove that it caused the estimate. Updated statistics cannot explain every discrepancy; parameter values, predicates and data distribution also matter. The XML describes the statistics consulted at compilation. To check their current state, I use sys.dm_db_stats_properties, as shown next. A subsequent update does not rewrite the evidence in an already saved plan. Check when the statistics were last updated -- Run in the affected database and set the actual table name. SELECT st.name AS statistics_name, sp.last_updated, sp.rows, sp.rows_sampled, sp.modification_counter FROM sys.stats AS st OUTER APPLY sys.dm_db_stats_properties( st.object_id, st.stats_id) AS sp WHERE st.object_id = OBJECT_ID(N'PlanXmlLab.Orders'); last_updated identifies the latest statistics update; rows and rows_sampled describe the population and sample at that update. modification_counter counts modifications to the leading statistics column since the update. Metadata visibility and permissions can affect the output. Compare this information with the same statistics object in the plan. Timestamps alone do not tell us whether the update was automatic or manual. If an update is justified, validate it in a controlled comparison using the same query and representative parameters, and capture a newly compiled plan. Read the access path alongside the row counts An Index Seek can still read many rows. I inspect SeekPredicates, any residual Predicate and ActualRowsRead where available. A broad seek range followed by filtering can explain why the rows read greatly exceed the rows returned. Likewise, a Key Lookup may be inexpensive once but expensive when repeated for thousands of rows. A scan can be the right choice when a large part of the table qualifies. The operator name is a starting point; the amount of work tells us more. For the customer, the useful explanation is concrete: this operator returned many more rows than expected, these were the statistics used, and this is the next comparison that will help establish why. That is more informative than recommending a statistics update from the timestamp alone. Read missing indexes and conversion warnings as clues Missing-index messages are easy to notice. I inspect the suggestion, but I also check whether it fits the query and the existing indexes. <MissingIndexes> <MissingIndexGroup Impact="85.0"> <MissingIndex Schema="[PlanXmlLab]" Table="[Orders]"> <ColumnGroup Usage="EQUALITY"> <Column Name="[CustomerId]" ColumnId="2" /> </ColumnGroup> <ColumnGroup Usage="INCLUDE"> <Column Name="[Amount]" ColumnId="3" /> </ColumnGroup> </MissingIndex> </MissingIndexGroup> </MissingIndexes> This example suggests a key on CustomerId with Amount included for coverage. EQUALITY and INEQUALITY describe predicate columns, while INCLUDE describes covering columns. The suggestion does not settle every detail of index design. Impact is an estimated reduction in optimizer cost. A value of 85 does not promise an 85% reduction in elapsed time. The XML may contain more suggestions than the graphical plan displays. Review existing indexes and write overhead, then measure the candidate change. Check which side of the predicate is converted <Warnings> <PlanAffectingConvert ConvertIssue="Seek Plan" Expression="CONVERT_IMPLICIT(nvarchar(50),[dbo].[Customers].[Code],0)" /> </Warnings> In this separate example, I would inspect the Code column type and the application parameter declaration. A varchar column compared with an nvarchar parameter can introduce a conversion on the column side because nvarchar has higher type precedence. The warning identifies something that may affect the plan, not a measured root cause. Whether a conversion prevents an efficient seek depends on the types, collation and expression. Test an appropriate parameter declaration while preserving required character semantics, and compare results, reads and CPU. A conversion in the projection is different from one in a search predicate. Look for an explicit reason when the plan is serial Customers sometimes ask why a query does not run in parallel when the database has multiple vCores. I look for NonParallelPlanReason in QueryPlan before assuming that more resources or a higher MAXDOP will change the result. <QueryPlan DegreeOfParallelism="0" NonParallelPlanReason="TSQLUserDefinedFunctionsNotParallelizable"> <!-- Other properties omitted --> </QueryPlan> Reason What I inspect next MaxDOPSetToOne Effective MAXDOP setting or query hint TSQLUserDefinedFunctionsNotParallelizable Scalar UDF and its inlining behavior NonParallelizableIntrinsicFunction The specific intrinsic function referenced A serial plan can be appropriate. The attribute can identify a restriction, but its absence does not fully explain the optimizer decision. Scalar UDF inlining can remove a restriction without guaranteeing parallel execution. DegreeOfParallelism="1" does not demonstrate parallel work. In Azure SQL Database, check database-scoped MAXDOP and query hints. More vCores do not override every restriction or guarantee selection of a parallel plan. Lessons learned The answer to the customer was a reading process: identify the statement and capture type, inspect parameters, compare estimated and actual work, and investigate the relevant statistics and warnings. Each observation should help us ask a better question and select a useful test. For a before-and-after comparison, preserve the query, parameters, data and relevant settings. Compare returned results, logical reads, CPU and duration. A plan describes one compilation or execution; Query Store can help establish whether the behavior changed over time. A short checklist Confirm that the plan belongs to the affected statement and execution. Check parameter values and the application context. Compare estimated and actual rows, accounting for repeated work. Inspect compilation statistics and their current update metadata. Review missing indexes, implicit conversions and serial-plan reasons. Validate the explanation with a measured comparison.Lessons Learned #557: Investigating an unexpected query slowdown
While working on a support case, our customer told us that the application was performing very poorly. We identified the affected query and found two execution plans in Query Store. When we compared them, we saw a clear difference: one plan used the CustomerId index, while the other scanned the table's clustered index. That led us to investigate why the query was no longer using that index. The following example reproduces this scenario with 100,000 fictional orders in an existing test database in Azure SQL Database. Follow the execution history In the example, query_id 231 has two captured plans, 243 and 251. Comparing their XML revealed the following differences: Access operator property With the CustomerId index Without the CustomerId index PhysicalOp Index Seek Clustered Index Scan Object / Index IX_TmpOrdersExample_MS_CustomerId Clustered primary key Filter placement SeekPredicates on CustomerId Predicate evaluated during the scan EstimatedRowsRead 10 100,000 EstimateRows after the filter 10 11.6601 ParameterCompiledValue 42 42 The scan references PK__TmpOrder__C3905BCF2BEADCD8. It still uses an index, but it no longer uses the nonclustered CustomerId index. The most useful difference for our investigation was EstimatedRowsRead: 10 for the seek and 100,000 for the scan, with the same compiled parameter value of 42. The XML also identifies each plan through QueryPlanHash: 0xA9A905E8788F2826 for the seek and 0xD122865CD758CA3C for the scan. Investigate why the index was no longer used The plan comparison showed a change from an Index Seek to a Clustered Index Scan, but it did not explain why that change occurred. I therefore reviewed the Query Store metadata for both plans to check. DECLARE @QueryId bigint = 231; SELECT * FROM sys.query_store_plan WHERE query_id = @QueryId ORDER BY plan_id; The results were: Plan 243 had is_forced_plan = 1, force_failure_count = 1 and last_force_failure_reason_desc = NO_INDEX. Plan 251 was not marked as forced. This is where we discovered that the earlier plan had been configured as forced and that an attempt to apply it had failed. NO_INDEX identifies an unavailable index dependency. The forcing flag records configuration, while the failure fields record unsuccessful attempts. The counter increments on recompilation failures and resets when forcing changes from off to on. This gives us a specific explanation. The expected plan references an index that was removed. The engine could not apply that plan and could optimize the query normally instead. The query can therefore continue returning the correct result while its execution strategy changes. Check the actual index definition and the deployment changes, then inspect the alternative plan. The NO_INDEX result explains the forcing failure; demonstrating that the alternative caused the reported slowdown still requires the runtime comparison. This is one possible cause of a regression, not an explanation for every slow query. Review forcing failures during maintenance This case also gave us a useful maintenance check. Instead of looking only for NO_INDEX, we can review the other forcing failures recorded by sys.query_store_plan. The following query groups affected plans by their last reported reason. Run it in the database being reviewed. DECLARE @SinceUtc datetimeoffset = DATEADD(day, -7, SYSUTCDATETIME()); SELECT last_force_failure_reason_desc AS LastFailureReason, COUNT_BIG(*) AS PlansWithFailures, COUNT(DISTINCT query_id) AS AffectedQueries, SUM(CASE WHEN is_forced_plan = 1 THEN CONVERT(bigint, 1) ELSE 0 END) AS CurrentlyForcedPlans, SUM(force_failure_count) AS CumulativeFailureCount FROM sys.query_store_plan WHERE force_failure_count > 0 AND (@SinceUtc IS NULL OR last_execution_time >= @SinceUtc) GROUP BY last_force_failure_reason_desc ORDER BY PlansWithFailures DESC; Use @SinceUtc to focus on plans with execution activity since a date, or set it to NULL to review all retained plans with failures. The date filters activity, not the time of the forcing failure. The counters are cumulative and may include older failures or failures with a different earlier reason. Identify queries that reference an index before removing it Before removing an index, we can ask a related question: which captured query plans read from it, and how often have those plans executed recently? The following query searches the retained plan XML for the index and returns one row per matching plan. Change the schema, table, index and UTC dates. This example looks for the CustomerId index used in my labs. DECLARE @SchemaName sysname = N'dbo'; DECLARE @TableName sysname = N'TmpOrdersExample_MS'; DECLARE @IndexName sysname = N'IX_TmpOrdersExample_MS_CustomerId'; DECLARE @SinceUtc datetimeoffset = DATEADD(day, -7, SYSUTCDATETIME()); DECLARE @UntilUtc datetimeoffset = SYSUTCDATETIME(); DECLARE @XmlDatabase nvarchar(258) = QUOTENAME(DB_NAME()); DECLARE @XmlSchema nvarchar(258) = QUOTENAME(@SchemaName); DECLARE @XmlTable nvarchar(258) = QUOTENAME(@TableName); DECLARE @XmlIndex nvarchar(258) = QUOTENAME(@IndexName); ;WITH XMLNAMESPACES (DEFAULT 'http://schemas.microsoft.com/sqlserver/2004/07/showplan'), Plans AS ( SELECT query_id, plan_id, is_forced_plan, TRY_CONVERT(xml, query_plan) AS PlanXml FROM sys.query_store_plan ) SELECT p.query_id, p.plan_id, p.is_forced_plan, COALESCE(r.Executions, 0) AS CapturedExecutions, r.FirstIntervalStartUtc, r.LastIntervalEndUtc FROM Plans AS p OUTER APPLY ( SELECT SUM(rs.count_executions) AS Executions, MIN(i.start_time) AS FirstIntervalStartUtc, MAX(i.end_time) AS LastIntervalEndUtc FROM sys.query_store_runtime_stats AS rs JOIN sys.query_store_runtime_stats_interval AS i ON i.runtime_stats_interval_id = rs.runtime_stats_interval_id WHERE rs.plan_id = p.plan_id AND rs.execution_type = 0 AND i.start_time >= @SinceUtc AND i.end_time <= @UntilUtc ) AS r WHERE p.PlanXml.exist(' //RelOp/IndexScan/Object[ @Database = sql:variable("@XmlDatabase") and Schema = sql:variable("@XmlSchema") and @Table = sql:variable("@XmlTable") and @Index = sql:variable("@XmlIndex") ]') = 1 ORDER BY CapturedExecutions DESC, p.query_id, p.plan_id; Read the output in three steps: query_id and plan_id identify the captured plans to inspect. The same query can appear with several plans. CapturedExecutions counts successful executions of those plans in intervals fully inside the requested window. is_forced_plan = 1 highlights a current forcing dependency, even when the plan has no executions in that window. These are plan execution counts, not exact counts of index operator executions: an operator in a conditional branch may not run every time. A missing result does not prove that an index is unused. Check Query Store capture and retention, infrequent jobs, read replicas, index hints and constraints before deciding to remove it. Compare with index usage counters We can also check the current index usage counters. This query provides a second view of the same index: SELECT i.name AS IndexName, u.user_seeks, u.user_scans, u.user_lookups, u.user_updates, u.last_user_seek, u.last_user_scan, u.last_user_lookup, u.last_user_update FROM sys.indexes AS i LEFT JOIN sys.dm_db_index_usage_stats AS u ON u.database_id = DB_ID() AND u.object_id = i.object_id AND u.index_id = i.index_id WHERE i.object_id = OBJECT_ID(N'dbo.TmpOrdersExample_MS') AND i.name = N'IX_TmpOrdersExample_MS_CustomerId'; These counters describe index operations, not distinct queries, and they have their own reset history. They are not limited to the Query Store date window. For a maintenance review, save two snapshots and compare them only after checking for resets or index changes. Use Query Store to identify the queries and these counters to understand the recorded read and write activity. Neither source alone proves that removing an index is safe. Lessons learned A forced plan is a configuration that still has dependencies. In this example, NO_INDEX explains why the intended index could not be used. Query Store shows the latest forcing status and counters, while an event capture provides dated evidence. Before removing an index, inspect recent captured plans and current forcing dependencies, then assess whether the observation period represents the workload that matters. Public references sys.query_store_plan sp_query_store_force_plan Query Store monitoring best practices Extended Events in Azure SQL Create an event session with a ring buffer target sys.query_store_runtime_stats sys.query_store_runtime_stats_interval sys.dm_db_index_usage_stats sys.query_store_query sys.query_context_settings109Views0likes0CommentsAzure SQL Data Sync After a Database Restore: Troubleshooting Leftover Sync Metadata
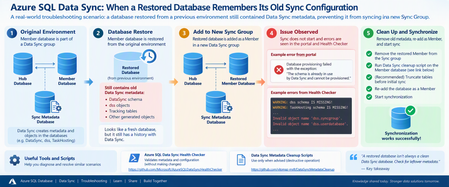
Recently, I worked on an interesting Azure SQL Data Sync issue that I thought was worth sharing with the community. The scenario looked straightforward at first: a database had been restored from another environment and was being configured as a Member database in a new Data Sync group. However, synchronization wasn't working as expected. The interesting part was not the new Sync Group itself. It was what the restored database had brought with it from its previous Data Sync configuration. The scenario The Member database was a restored copy of a database that had previously participated in another Azure SQL Data Sync group. After the restored database was configured as a Member in the new environment, synchronization wasn't working as expected. During troubleshooting, another important clue emerged. The restored database still had a history with Azure SQL Data Sync, so we needed to determine whether metadata and generated objects from its previous configuration were still present. This became one of the key areas of the investigation. Understand the Data Sync architecture first Before jumping into scripts, it's important to clearly distinguish the three database roles involved in Azure SQL Data Sync: Hub Database: The central database containing the application data being synchronized. Member Database: A database that synchronizes with the Hub. Sync Metadata Database: A separate Azure SQL Database containing Data Sync metadata and logs. Microsoft's documentation explains that Data Sync follows a hub-and-spoke topology and that the Sync Metadata Database contains Data Sync metadata and logs. This distinction became particularly important during this investigation because the initial diagnostic configuration wasn't pointing to the expected Sync Metadata Database. Troubleshooting approach Here is the troubleshooting flow we followed. Step 1: Run the Azure SQL Data Sync Health Checker One of the first tools I recommend for this type of investigation is the public Azure SQL Data Sync Health Checker: Azure SQL Data Sync Health Checker on GitHub [github.com] The tool validates whether metadata associated with the Hub and Member is in place and compares the scopes against information in the Sync Metadata Database. Importantly, the Health Checker repository states that it performs validation without changing Data Sync or user objects. The tool requires the relevant connection details for: Sync Metadata Database Hub Database Member Database The GitHub repository contains the current script and execution instructions. What we observed In our investigation, the initial Health Checker output included messages similar to: WARNING: dss schema IS MISSING! WARNING: TaskHosting schema IS MISSING! Invalid object name 'dss.syncgroup'. Invalid object name 'dss.userdatabase'. Those errors were important clues, but they needed to be interpreted together with the database roles. Microsoft's documentation states that the DataSync schema is used for system-created objects in Hub and Member databases, while the dss and TaskHosting schemas are used for system-created objects in the Sync Metadata Database. That distinction helped us recognize that we first needed to validate which database was actually being supplied to the Health Checker as the Sync Metadata Database. Lesson learned Before treating a missing dss or TaskHosting schema as corruption, first make sure you're actually connected to the Sync Metadata Database. That simple validation can save a lot of investigation time. Step 2: Check the Member database for Data Sync artifacts Once we had clarified the topology, the investigation moved to the restored Member database. Because this database had previously participated in Data Sync, we wanted to understand what Data Sync objects were still present. One of the queries used during troubleshooting was: SELECT name FROM sys.tables WHERE SCHEMA_NAME(schema_id) = 'DataSync' AND name NOT LIKE '%_tracking%'; We also inspected: SELECT * FROM DataSync.schema_info_dss; And, when checking the Member database's Data Sync scope information: SELECT * FROM DataSync.scope_info_dss; These checks helped us understand the Data Sync metadata state of the restored Member database and whether it still contained artifacts associated with its previous configuration. Why this matters Microsoft's current Data Sync best-practices documentation confirms that the DataSync schema is used for system-created objects in Hub and Member databases. So, when investigating a database restored from an environment where it previously participated in Data Sync, the DataSync schema is an important part of the investigation. Step 3: Consider the history of the restored database This was really the turning point in the investigation. Instead of treating the database simply as a "new Member", we started looking at it as: A restored database that had previously been provisioned for another Data Sync configuration. That's an important difference. When troubleshooting a restored database, ask early: Was this database previously part of another Azure SQL Data Sync group? If the answer is yes, the database's previous Data Sync state should be considered during the investigation. Step 4: Remove the Member before cleanup In our scenario, the remediation sequence was essentially: Remove the restored database from the current Sync Group. Clean up the previous Data Sync metadata from the restored Member database. Re-add the database as a Member. Trigger synchronization again. For the cleanup portion, we used the following publicly available repository: SQL Data Sync Cleanup Scripts on GitHub [github.com] The repository contains several scripts for different purposes, including: Data Sync complete cleanup.sql Data Sync cleanup hub or member.sql cleanup data sync object V2.sql The specific complete-cleanup script is available here: Data Sync complete cleanup.sql Important warning about the cleanup script Please do not treat this as a general-purpose Data Sync troubleshooting script. The script itself contains a very clear warning. It immediately cleans Data Sync-related objects associated with the database and says it should be used only for the scenarios specified in the script, including when advised by the support team during a support request. The repository also explains the different purposes of its cleanup scripts. For example, the complete-cleanup script has more restrictive usage guidance, while the Hub/Member cleanup and object cleanup scripts target different scenarios. My recommendation: use the Health Checker and read-only diagnostic queries first. Do not jump directly to metadata cleanup without understanding the database topology and existing Data Sync configuration. Step 5: Validate with one table After cleaning up the previous Data Sync artifacts, we didn't immediately assume that everything was resolved. Instead, we validated with a controlled test. A test table on the Member side was truncated, the synchronization was started again, and the table began synchronizing successfully. That provided the confirmation we needed that the previous Data Sync state of the restored Member was an important part of the issue. Root cause The troubleshooting pointed to the fact that the restored Member database had previously participated in another Data Sync configuration and retained Data Sync-related metadata/artifacts from that previous state. After cleaning up the old Data Sync state and reprovisioning the restored database as a Member, synchronization was successfully validated again. The important lesson for me wasn't simply the cleanup itself. It was recognizing that restoring a database does not necessarily mean you're starting with a clean Data Sync state. A practical troubleshooting flow For similar scenarios, I would approach the investigation in this order: Confirm the architecture Identify the: Hub Database Member Database Sync Metadata Database Run the Health Checker Use: Microsoft Azure SQL Data Sync Health Checker [github.com] Review its output before making changes. Inspect the restored Member Check whether Data Sync-related objects exist: SELECT name FROM sys.tables WHERE SCHEMA_NAME(schema_id) = 'DataSync' AND name NOT LIKE '%_tracking%'; Then, where applicable to the database's current state, inspect: SELECT * FROM DataSync.schema_info_dss; and: SELECT * FROM DataSync.scope_info_dss; Ask about the database history Was the database: restored from another environment? previously a Data Sync Member? previously associated with another Sync Group? That historical context can completely change the direction of the investigation. Consider cleanup only after understanding the environment The public cleanup scripts are available here: SQL Data Sync Cleanup Scripts [github.com] These scripts make changes to Data Sync objects and should not be the first troubleshooting step. Validate using a controlled test Once the environment has been correctly cleaned/reconfigured, validate synchronization on a controlled scope before assuming the entire configuration is healthy. My key takeaways This troubleshooting experience reinforced a few lessons for me. A restored database isn't necessarily a clean Data Sync database Restoring the application data doesn't mean you should ignore the database's previous synchronization configuration. Always distinguish Hub, Member, and Sync Metadata databases This is especially important when interpreting Health Checker output. The DataSync schema is associated with system-created objects in Hub and Member databases, while dss and TaskHosting are associated with system-created objects in the Sync Metadata Database. Use diagnostics before cleanup The Azure SQL Data Sync Health Checker is designed to validate Data Sync metadata and objects without making changes. That makes it a much better starting point than immediately removing objects. Database history matters One of my favorite questions after this investigation is now: "Was this database ever part of another Data Sync Group?" It's a simple question, but in restore or copy scenarios it can reveal an important part of the troubleshooting story. Be very careful with metadata cleanup The public cleanup repository itself provides specific guidance about when each script should be used, and the complete-cleanup script includes an explicit warning before execution. Always understand the environment and protect your data before performing destructive operations. One more important consideration: SQL Data Sync retirement There is also an important longer-term architecture consideration. Microsoft currently documents that SQL Data Sync retires on September 30, 2027. Existing Sync Groups can continue operating until the retirement date, but Microsoft recommends migrating to alternative data replication and synchronization solutions before then. So, while troubleshooting existing Data Sync environments remains necessary, organizations using the service should also begin considering their migration strategy. References and useful tools Microsoft documentation Best practices for Azure SQL Data Sync [learn.microsoft.com] Troubleshooting tools Azure SQL Data Sync Health Checker [github.com] SQL Data Sync Metadata Cleanup repository [github.com] Data Sync complete cleanup.sqlLessons Learned #556: Finding the SQL Statement Behind a Query Hash in Azure SQL Database
Recently, I worked on a performance investigation in which several queries were identified by their query hashes. The hashes helped us discuss the workload, but the customer still needed to answer a practical question: which SQL statements were behind them? A value such as 0x0123456789ABCDEF does not tell an application developer which statement to review. Fortunately, if Query Store captured the query and still retains it, the customer can use that hash to find the SQL text and the query ID in their own database. In this article, I will show that lookup and explain what to do with the result. The hash used below is a placeholder; replace it with a hash from your investigation. A hash is a lookup key rather than the SQL text A query hash is an eight-byte value derived from the shape of a query. It cannot be decoded back into the original statement. We need a source that stores the relationship between the hash and the text. Query Store provides that relationship through two catalog views. sys.query_store_query contains the query hash and query ID. Its query_text_id links to sys.query_store_query_text, where we can retrieve the SQL text. That gives us a small, read-only query to answer the customer’s question. Find the statement in the correct database Connect directly to the Azure SQL Database that executed the workload, rather than master or another database on the same logical server. Use an account with the permissions required to read Query Store information. Then run the following query, replacing the example hash: DECLARE @QueryHash binary(8) = 0x0123456789ABCDEF; SELECT CONVERT(varchar(18), q.query_hash, 1) AS query_hash, q.query_id, q.context_settings_id, qt.query_sql_text FROM sys.query_store_query AS q JOIN sys.query_store_query_text AS qt ON qt.query_text_id = q.query_text_id WHERE q.query_hash = @QueryHash ORDER BY q.query_id; Use the hexadecimal value with its 0x prefix, as shown, without quotation marks. The returned hash is formatted in the same hexadecimal notation so you can compare it with the original value. This lookup does not need a date filter: it searches the query records that Query Store currently retains. Reviewing performance during a particular incident is the next step, after identifying the matching queries. One hash can return more than one query ID Suppose the lookup returns query IDs 125 and 206. Those are illustrative IDs, but they show an important point: we should inspect both rows rather than select the first one automatically. Each query ID can also have more than one execution plan. This simple lookup intentionally returns query records without joining the plan table, so multiple plans do not repeat the SQL text in the results. Use the query ID to continue in SSMS Once the text is identified, the hash has done its job. In SQL Server Management Studio, expand the database, open Query Store, and select Tracked Queries. Enter a returned query ID and choose the period you want to investigate. From there, review the available execution plans and compare CPU, duration, reads, and execution frequency. Repeat the review for other matching query IDs where necessary. Finding the statement does not prove that it caused a particular resource spike. That conclusion still requires performance statistics and an appropriate time correlation. The useful outcome here is that the customer now knows which SQL statement to review. What if the lookup returns no rows An empty result does not prove that the query never ran. First confirm the database and the hash. Then check whether Query Store captured the query and whether its history remains available. Capture policy, cleanup, or Query Store being disabled during execution can explain a missing record. Enabling Query Store now cannot recreate a statement that was never captured. If the workload runs again, capture it and repeat the lookup after verifying that Query Store is collecting the relevant activity. References sys.query_store_query and the query hash. sys.query_store_query_text and SQL text. Monitor performance using Query Store.111Views0likes0CommentsAzure SQL Database is retiring Always Encrypted with Intel SGX enclaves
On October 31, 2027, Azure SQL Database will retire Intel Software Guard Extensions (SGX) enclave functionality for Always Encrypted. Workloads that still depend on Intel SGX enclaves after that date will no longer work as configured. The path forward is Virtualization-Based Security (VBS) enclaves, a hardware-independent option that does not require attestation. To retain secure-enclave capabilities, move databases from DC-series compute to a supported standard-series, non-DC tier and update affected applications for VBS enclave mode. What is changing? Intel SGX enclaves are tied to DC-series compute. After October 31, 2027, databases on these tiers must move to supported compute to retain enclave-enabled capabilities. Applications configured for Intel SGX enclaves may also need driver and connection-string updates. For workloads that do not require isolation from the host operating system, VBS enclaves offer a straightforward migration within Azure SQL Database. If your threat model requires Intel SGX-equivalent host isolation, evaluate SQL Server on Azure Confidential VMs instead. Choose the right migration path Use the migration guide to identify databases and elastic pools on DC-series compute, choose the target architecture that matches your threat model, update application connectivity and attestation settings, and validate the workload before production cutover. Move to VBS enclaves in Azure SQL Database Choose VBS enclaves when you need to protect sensitive data from unauthorized users or malicious insiders but do not require isolation from the host operating system. VBS enclaves run on supported non-DC compute tiers and eliminate attestation requirements. Consider SQL Server on Azure Confidential VMs If your threat model requires stronger isolation from the host operating system, assess SQL Server on Azure Confidential VMs. Compare architecture, operations, compatibility, and cost with the Azure SQL Database option. Start planning early Start now. Discovery, compute-tier changes, application updates, security review, and production validation all take time. Complete the migration before October 31, 2027, to keep enclave-enabled workloads running without interruption. Help and support Have questions? Ask community experts in Microsoft Q&A. If you have an Azure support plan and need technical help, create a support request. Review service retirements that may affect your resources in the Azure Retirement Workbook. For more ways to find impacted resources, see the retirement guidance. Retirement information may take up to two weeks to appear.166Views1like1Comment
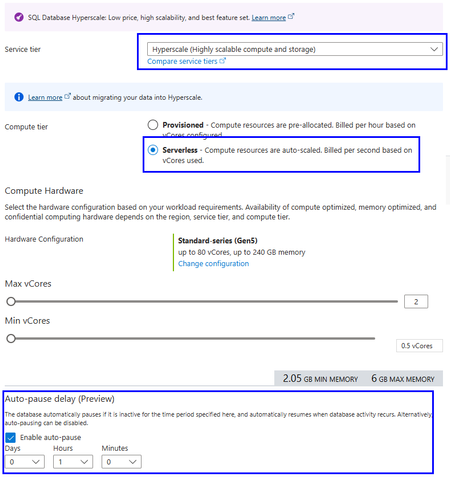
Public Preview: Auto-pause and auto-resume for Azure SQL Database Hyperscale Serverless
Auto-pause and auto-resume are now available in public preview for Azure SQL Database Hyperscale Serverless. You can now combine Hyperscale's independent scaling of compute and storage with the ability to automatically pause inactive databases, helping reduce compute costs for workloads with extended or predictable idle periods.327Views0likes0CommentsDatabase Hub in Fabric: Now in Public Preview -Turn Database Signals into Guided Action
As applications grow, so does the database estate behind them. What starts with a handful of databases can become hundreds or thousands of resources spread across services, subscriptions, and environments. For the teams responsible for keeping them healthy, the challenge is no longer just collecting signals. It is knowing what needs attention, why it matters, and what to do next. Now in public preview, Database Hub in Microsoft Fabric brings inventory, health, performance, security, and optimization insights into one connected experience. It helps administrators and developers see the bigger picture, identify affected resources, and move from estate-wide visibility to focused investigation, without losing the context that brought them there. The preview brings together supported resources across Azure SQL Database, SQL Server enabled by Azure Arc, Azure Database for PostgreSQL, Azure Cosmos DB, and SQL database in Fabric. Available capabilities and signals vary by service and preview configuration. Database Hub Overview brings together estate-wide findings and cross-engine performance trends to help you prioritize what needs attention. Start with what needs your attention When you manage a large database estate, another dashboard is only useful if it helps you decide where to spend your time. The Overview page provides that starting point, bringing together findings across security, performance, and optimization. It distinguishes Issues, which require timely attention, from Suggestions, which highlight opportunities to improve your estate over time. You might begin with a security configuration that needs review or a performance signal that warrants investigation. Selecting a finding opens Estate with the relevant filters already applied, so you can see the affected resources rather than search for them again. The result is a more direct path from “something needs attention” to “these are the resources I should investigate.” Overview highlights issues across Security, Performance, and Optimization, with affected-resource counts and direct links to investigate further. Bring your estate into one view, and make it relevant to you The Estate experience brings supported resources into a unified inventory, scoped to your existing permissions. Search and filters help you narrow that inventory to the service, subscription, or resource group you manage. This is especially useful when your responsibilities span database engines. You can begin with a broader view, then focus on Azure SQL databases, Arc-enabled SQL Server resources, or Azure Database for PostgreSQL flexible servers without rebuilding the resource list in separate portals. Each resource brings its associated Issues and Suggestions into context. Open a finding to review the affected resource, supporting information, and recommended next step. The inventory also respects the resource model of each service. For example, the PostgreSQL view represents flexible server instances, rather than every database hosted within them. A unified view does not mean moving your databases. Your Azure resources remain in their existing subscriptions, and on-premises SQL Server instances remain on-premises, connected through Azure Arc. Database Hub brings operational context together; it does not require relocating or mirroring your application data into Fabric. Estate brings resource inventory, Issues, and Suggestions into one view, with quick actions to continue investigation in the Azure portal, VS Code, or SSMS. Understand security posture and performance in context Database Hub helps you identify configurations worth reviewing and resources that need a closer look. For security, supported signals can include Microsoft Entra authentication, customer-managed keys, and auditing coverage, depending on the database service. These findings provide a starting point for investigation, not a blanket judgment that every flagged resource is insecure or noncompliant. For example, a suggestion to review customer-managed keys should be evaluated against your organization’s requirements. A resource using service-managed keys is still encrypted at rest. For performance, built-in dashboards bring supported utilization and activity signals into view, including CPU, memory, storage, I/O, and connections. Review trends across your estate, then narrow the scope and time range to investigate individual resources. Metric availability varies by engine and monitoring configuration; missing data should not be interpreted as good health. For supported SQL monitoring scenarios, you can also create a custom monitoring dashboard from a template and tailor its charts and layout to the resources your team follows regularly. Together, these experiences help answer two practical questions: Where is pressure building, and where is there an opportunity to improve? Performance summaries highlight recent capacity signals and trends across Microsoft SQL, PostgreSQL, and Cosmos DB. The Security dashboard summarizes Microsoft Entra authentication, audit logging, and customer-managed key coverage, helping you identify configurations that warrant review across your estate. The Performance monitoring dashboard combines memory-pressure trends, resource-level details, and interpretation guidance to help focus your investigation. Move from a finding to an informed next step Estate-wide visibility is the beginning of an investigation, not a replacement for database expertise. When a finding needs deeper analysis, Database Hub helps you review the evidence and continue in the appropriate native experience, such as the Azure portal or SQL Server Management Studio (SSMS). Engine-specific diagnostics and configuration changes remain in the tools designed for that work. Consider a performance issue that occurred before an administrator could inspect it. In supported agent-assisted scenarios, captured incident evidence can help establish what happened, when it happened, and which queries or sessions were involved. That context gives the administrator a more informed starting point for investigation. The operator remains in control: review the evidence, evaluate the recommendation, and apply authorized changes through the appropriate service tools. The preview investigation workflow does not automatically remediate issues, and existing permissions and approval requirements continue to apply. Bring database expertise into agent-assisted workflows We are also making database operational intelligence available through agent skills: reusable capabilities that agents can call to support observability, monitoring, diagnostics, optimization, and other database operations. Database Hub provides estate context; skills provide a way to bring database expertise into an agent-assisted investigation. This creates a foundation for helping teams move from identifying an affected resource to understanding its signals and evaluating the next step. We’re building toward making this expertise available in the AI companions and development tools teams already use, with recommendations grounded in evidence, the specific database, and your organization’s operational controls. If we take a step back, our broader vision brings together a free, extensible Database Hub experience, agentic observability, and OneLake integration, all within Microsoft Fabric. It’s a foundation for connecting database operations with analytics and AI and helping teams turn signals into informed action. Get started with Database Hub Start with the Database Hub documentation to review preview availability, supported services, and setup requirements. Ask your Fabric administrator to enable the preview where required, confirm that you have the appropriate resource permissions, and complete any service-specific monitoring prerequisites. Then open Microsoft Fabric, select Databases in the left navigation, and begin with Overview. Choose a finding, explore the affected resources in Estate, and follow the evidence into your next investigation. For more details on supported services and getting set up, the Database Hub documentation is also available on Microsoft Learn. Learn more What is Database Hub in Fabric? Enable performance monitoring for Microsoft SQL Performance Monitoring for Azure SQL in Database Hub657Views5likes1CommentMigrate to Azure SQL Database, including Hyperscale, straight from Azure Arc (public preview)
The challenge Most organisations do not run in one place. Estates stretch across on-premises datacentres, hybrid deployments and the cloud, and every migration decision must balance application dependencies, operational requirements and a modernization roadmap that is already in motion. Mixed environments and legacy dependencies make that harder, and needing a different tool for assessment, migration, monitoring and management harder still. The result is more operational effort, inconsistency between teams, and modernization that moves slower than anyone wants. Azure Arc already solves the first half of that problem. It discovers and assesses SQL Server estates at scale, so you know which databases are ready to move. The second half has been the gap: once a database is identified as migration-ready, the path to Azure SQL Database runs outside Arc. You leave the experience you were working in, learn Azure Database Migration Service, configure a Self-hosted Integration Runtime, and juggle several tools to get one database across. That fragmentation costs time, and it is one of the reasons why assessments do not turn into migrations. What's new Azure Arc Database Migration now adds Azure SQL Database; including Hyperscale as a supported migration target, in public preview. You can migrate Arc enabled SQL Server databases to Azure SQL Database through a single, guided experience in the Azure portal. Behind that experience, the workflow integrates Azure Database Migration Service and streamlines Self-hosted Integration Runtime setup directly into the migration journey. You assess, configure, migrate, monitor and complete the migration without leaving Arc. This is a logical migration performed by DMS through the Self-hosted Integration Runtime, so there is no separate staging step for you to plan or maintain but it requires a planned downtime. Why Hyperscale For many teams, the database that most requires modernizing is also the largest one they run. Hyperscale is the Azure SQL Database service tier built for exactly that case: a fully managed platform designed to scale storage and compute independently as a workload grows, so a large SQL Server database can move to a managed service without being re-architected first. Making Hyperscale reachable from Arc matters because it removes a decision point from the middle of the journey. The databases Arc flags as migration-ready are often the ones whose size is used to rule out a managed destination; and now the assessment and the target sit in the same place. One portal, one operational model The principle has not changed: one portal for discovery, assessment and migration. The entire migration lifecycle is managed from a single tool in the Azure portal; assess readiness, select a target, configure settings, choose databases and tables to migrate, monitor progress and validate the results. Migrating to Azure SQL Database follows the same operational model already available for existing migration scenarios in Arc. The same migration dashboard, the same monitoring experience and the same guided workflow apply regardless of destination. That reduces the learning curve, keeps operational processes consistent, and lets your team choose the most appropriate Azure SQL platform for each database without changing migration methodology. How it works The flow starts where you already are, in the Database migration pane of your Arc-enabled SQL Server instance. Assess in Arc. Readiness assessments are generated automatically every weekend, and you can run one manually in a few minutes if you would rather not wait. SQL Server migration in Azure Arc is available by default for Arc-enabled SQL Server instances starting with SQL Server 2014 (12.x). Choose your target. Select Azure SQL Database, including the Hyperscale service tier, for the databases the assessment identified as ready. Set up DMS and SHIR, guided. The portal walks you through creating the Azure Database Migration Service resource and registering a Self-hosted Integration Runtime, inside the same workflow rather than as separate homework. Migrate. DMS performs a logical migration of your schema and data to the Azure SQL Database target through the integration runtime. Monitor and Completion. Track progress on the migration dashboard you already use, validate the results when the migration is completed. Microsoft Copilot is built into the Database migration pane to help you along the way. Why SHIR, and what it means for you The Self-hosted Integration Runtime secures bridge that it acts as the connectivity layer that enables Azure Database Migration Service to securely connect to the source SQL Server and the target Azure SQL Database for data movement. Azure DMS is a fully managed service for migrations to Azure data platforms and can be driven from the Azure portal, PowerShell or the Azure CLI — the runtime is simply how it gets to your source. In practice, setup is guided and one-time. You register the runtime once during the migration workflow, and subsequent migrations from the same environment reuse it. Nothing about how you operate your Arc-enabled instances changes. Learn more details in the technical documentation. Get started Trying the preview takes three things: an Arc-enabled SQL Server instance, a recent readiness assessment, and a target Azure SQL Database. In the Azure portal, open your Arc-enabled SQL Server instance, go to the Database migration pane, review the assessment results, and choose Azure SQL Database as your target. The portal takes it from there. Learn more: SQL Server migration in Azure Arc What is Azure Database Migration Service Create a Self-hosted Integration Runtime Step-by-step guidance for the new target We want your feedback For product feedback, feature requests, or migration pain points you'd like the team to track and act on, please share them through aka.ms/sqlfeedback under the Migration & Modernization category.350Views0likes0CommentsMI link support for multiple databases in an Always On availability group for SQL Server (Preview)
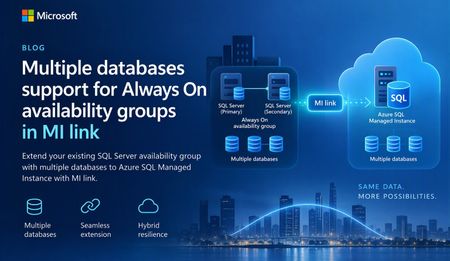
A simpler way to extend availability groups to Azure We are pleased to announce the preview of multi-database mode for Managed Instance link. The new mode lets you replicate multiple databases from an existing Always On availability group through a single link between SQL Server and Azure SQL Managed Instance. Managed Instance link uses distributed availability group technology to provide near-real-time replication between SQL Server and Azure SQL Managed Instance. It supports hybrid architectures, online migration, disaster recovery, and read-only workload offload. The link can be configured and managed through SQL Server Management Studio (SSMS), PowerShell, Azure CLI, and Azure APIs. Previously, each link supported one database. Customers with multi-database availability groups therefore had to split databases into separate availability groups and create a link for each database. Multi-database mode removes that limitation for supported SQL Server versions and editions, while the existing single-database mode remains available for earlier versions and other supported configurations. What you can do with multi-database link mode Migrate multiple databases to Azure SQL Managed Instance with minimal cutover downtime. Offload read-only workloads, including reporting and analytics, to the secondary replica. Use Azure SQL Managed Instance as a disaster recovery target for supported SQL Server versions. Start replication in either direction when the SQL Server version and Azure SQL Managed Instance update policy support that direction. Reverse primary and secondary roles through a planned failover. Build hybrid and multicloud topologies that place database groups where they are most useful. One link for an existing multi-database availability group If you already use an Always On availability group, multi-database link mode lets you extend the complete database group to Azure SQL Managed Instance without creating a separate availability group for every database. All databases in the link move together as one managed group. Databases on the primary are read-write, while their copies on the secondary are read-only. Use of your existing Always On AG listener endpoint is supported with multi-database mode MI link, allowing the link to remain operational after a local AG failover. Image 1: A multi-database Always On availability group replicated to Azure SQL Managed Instance through one Managed Instance link. The diagram illustrates the availability group relationship rather than a specific Azure SQL Managed Instance service-tier replica count. Managed Instance link is supported across all Azure SQL Managed Instance service tiers. Run multiple links in different directions A single SQL Server instance can participate in multiple links. Each link can carry a different availability group, and supported links can replicate in different directions at the same time. In the following example, AG1 (containing DB1, DB2, and DB3) replicates from SQL Server to Azure SQL Managed Instance through MI link 1. AG2 (containing DB4, DB5, and DB6) replicates from Azure SQL Managed Instance to SQL Server through MI link 2. Both links can operate at the same time between the two instances. Image 2: Two multi-database availability groups using separate links with opposite replication directions. Important: Database names must be unique in this configuration. A database cannot be renamed on the secondary while it is participating in replication to resolve a naming conflict. Replicate one availability group to multiple managed instances Multi-database mode also supports fan-out topologies. You can replicate multiple availability groups to one managed instance, or replicate the same availability group to different managed instances. For example, separate links can target managed instances in different Azure regions. Image 3: One multi-database availability group replicated through separate links to two Azure SQL managed instances. Preview requirements Requirement Details SQL Server SQL Server 2022 with CU27 or SQL Server 2025 with CU9 and above. Edition Enterprise or Developer edition. Standard edition supports basic availability groups with one database and is not supported for multi-database mode. Azure SQL Managed Instance Use a compatible update policy (2022 or 2025) matching your SQL Server version. SSMS SSMS 22.10.2 or later for the multi-database link capability. Automation Az module 16.3.0 or later and Az.Sql 7.1.0 or later, or the corresponding Azure APIs. Get started To evaluate multi-database mode during preview: Confirm that the SQL Server version, edition, servicing level, and Azure SQL Managed Instance update policy meet the preview requirements. Upgrade to SSMS 22.10.2 or later, or use a supported automation interface. Enable multi-database mode before creating a multi-database link. Create the link from the existing Always On availability group and validate synchronization for every database. Review the Azure documentation for multi-database Managed Instance link configuration, limitations, monitoring, failover, and cleanup guidance. Share your feedback We would love to hear about your experience with multi-database mode. Please share questions, feedback, and feature suggestions through the Managed Instance link feedback form.334Views0likes0Comments