api
607 Topics
Struggling with running DQ Scans (Long queuing and Retry Count Error Issues)
Hi everyone, I have been exploring Microsoft Purview Data Quality quite extensively. At this point, I have configured more than 4,000 data quality rules across more than 10 Microsoft Fabric capacities, each with a minimum capacity of F16. Fabric is the source for all assets registered in Purview. I have identified several issues with the product, but the two that are currently impacting me the most are the following: DQ scans failing with a generic error“Max Retry Count Reached. Ending Workflow. Current Task HandleError”The challenge is that the error message does not identify which rule is causing the failure. As a result, I have to troubleshoot manually by disabling groups of rules, rerunning the scans, and repeating the process until I find the problematic rule. This trial-and-error approach is very time-consuming, especially at this scale. This seems to be caused by issues in some of the DQ rules, even though all rules are marked as “Good to go” in Purview. When running Data Quality scans, I often receive the following error: DQ scans remain queued for a long timeI am not sure why this happens or what resource, orchestration, or scheduling constraint is causing the delay. Whenever I run these DQ scans, they remain in a Queued state for at least 10 minutes, even when there is nothing running on the Fabric capacities. Has anyone experienced similar behavior with Purview Data Quality at this scale? Specifically, I would appreciate any guidance on: How to identify which DQ rule is causing a scan failure Why scans remain queued even when Fabric capacity appears to be idle Whether there are known limitations or best practices for running thousands of DQ rules in Purview Thank you.383Views0likes2Comments
Guidance Needed: Syncing Appointments Between New Outlook and Web App via Outlook Add-in
Hello Community, I need guidance on syncing appointments between New Outlook and our Web Application. We have an Outlook Add-in where users log in using only their Web Application credentials. When an appointment is created from the add-in, we need it to: Create the appointment in the Web Application (via SOAP API). Create the same appointment in the user's Outlook calendar. Keep updates synchronized in both systems. We previously achieved this using EWS in Classic Outlook, but EWS is not supported in New Outlook. We are now exploring Microsoft Graph API. My understanding is that Graph API requires each Outlook user to be authenticated and authorized before calendar operations can be performed. We have thousands of users across different organizations, and we do not want to require every user to complete a separate Microsoft authentication flow or implement SSO. Is my understanding correct about Microsoft Graph API functioning? If so, what is the recommended approach to create and synchronize Outlook calendar Appointment/Event from a New Outlook web Add-in while minimizing outlook user authentication requirements in Microsoft Graph API? Note: We don't want to suggest every organization (and users in it) to implement SSO now (not sure if this is needed or forced or recommended.), to be able to use the application in Outlook and sync data. So, I am looking for any previous experiences on who this is handled or what can we do differently. Any suggestions or implementation experiences would be greatly appreciated. Thank you in advance for your help. Thanks & Regards, SM31Views0likes0CommentsMicrosoft Agent 365 and Azure API Management integration for MCP governance
As agents gain access to enterprise tools, organizations need consistent ways to govern what those agents can access and enforce those decisions at runtime Today, we're announcing a new integration between Microsoft Agent 365 and Azure API Management now in public preview. The integration connects centralized governance in Agent 365 with runtime enforcement for MCP servers and tools through Azure API Management for V2 and AI Gateway tiers. With this integration, AI administrators can discover and govern gateway managed MCP servers and tools from Agent 365 and application platform teams use Azure API Management, to enforce those access decisions at runtime. Microsoft Defender and Microsoft Purview add additional layers of protection by evaluating tool requests and results for threats and sensitive information risks. Centralized governance, enforced at the gateway Agent 365 and Azure API Management play complementary roles. Agent 365 defines governance intent, maintains inventory, and manages access decisions. Azure API Management enforces those decisions inline for traffic to MCP servers and tools. Together, they connect the enterprise governance experience with the infrastructure platform teams already use to manage access to business systems. Administrators can make supported access decisions from Agent 365, while enforcement happens at the gateway in the customer's Azure environment. For agents already using a configured gateway endpoint, that connection remains in place. Customers can extend governance to their existing gateway-managed tools without rearchitecting those agents or moving tools out of their Azure subscriptions. Discover tools and control what agents can do The integration brings together four key capabilities: Discover existing gateways and MCP servers. After a one-time tenant-level consent, Agent 365 discovers supported Azure API Management resources and the MCP servers they expose, removing manual registration. Maintain a centralized inventory. Administrators can find gateway-managed MCP servers in Agent 365 and inspect available metadata, bringing these assets into a shared governance experience. Control access at the right level. Block or unblock an entire MCP server. With the Azure API Management AI Gateway tier (preview) they can apply more granular controls by blocking individual tools without disabling the server. Use runtime signals for oversight. Tool activity observability on AI Gateway tier supports monitoring, auditing, and incident investigation, connecting access decisions with what happens at runtime. Add protection before tools run and before results return Controlling which tools agents can access is one part of the governance model. Organizations also need protection for information flowing through those tools . The Agent 365 tool threat protection policy (supported in the AI Gateway tier) uses Microsoft Defender and Microsoft Purview capabilities to evaluate tool requests and results for risks such as malicious content, prompt injection, and exposure of sensitive information. Platform teams can configure evaluation before tool invocation, after invocation, or at both stages. With blocking configured, pre-invocation evaluation can prevent a disallowed call from executing. Post-invocation evaluation can withhold unsafe results before they reach the agent. Build on open standards and existing investments This integration connects centralized governance with enforcement where agents access tools, while building on the infrastructure organizations already operate. MCP provides a common interface for tool access. Azure API Management provides the gateway boundary for applying policy, security, and observability. Agent 365 brings those gateway-managed assets into a centralized governance experience, with Microsoft security capabilities adding protection along the tool-call path. The goal is not to make every agent use the same runtime. It is to help organizations apply governance to tools reached through supported gateway endpoints, bringing AI administrators, platform teams, and security teams closer together, while preserving the existing architecture. Get started API Management v2 tiers support centralized MCP inventory and server-level blocking and unblocking through Agent 365.The AI Gateway tier adds more granular capabilities including individual-tool blocking, tool activity observability, and tool threat protection . Start with the Agent 365 integration guide, explore tool threat protection with Defender and Purview, and configure your gateway in the AI Gateway portal.1.6KViews0likes4Comments
Update network rules for the API Management service tag
To improve Azure API Management resiliency and scalability, we’re expanding our infrastructure and adding control-plane IP addresses. These addresses are included in the ApiManagement service tag. If you use VNet internal or VNET external with the classic (v1) tiers, check your network security groups (NSGs), user-defined routes (UDRs), and firewalls. Replace hard-coded API Management IP addresses with the service tag wherever supported. Make this change by November 30, 2026, to avoid disruption to management access. If network rules block connectivity to the management endpoint after that date, you may be unable to manage your API Management configuration—such as APIs, operations, and policies—from the Azure portal or CLI. This change affects management-plane traffic only. Runtime traffic, including API calls to your services, is not impacted. Find the ApiManagement tag in Microsoft’s Azure service tags overview or the latest Azure IP Ranges and Service Tags JSON download. If your firewall doesn’t support service tags, use the published list and keep your IP rules synchronized with its latest version. Don’t rely on a fixed, point-in-time IP list. During the transition, the service tag includes both existing and new addresses. For reference: Use API Management in an internal virtual network
Migrate Data Ingestion from Data Collector to Log Ingestion - Part 2
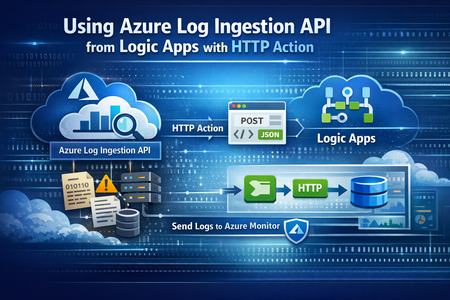
In Part1, we discussed how to use HTTP action to migrate from the deprecated Data Collector API to Log Ingestion API. However, since the deprecated Data Collector API was allowing message payload up to 30MB, some migration scenarios encountered issues; since the new Log Ingestion API has only 1MB payload limit. This applies to both HTTP action, and the preview (Log Ingestion connector) Azure Monitor service limits - Azure Monitor | Microsoft Learn When sending payload larger than 1MB, the HTTP action would fail with the error: In order to overcome this, we can chunk the array payload, before calling the Ingestion API. We need to chunk the array payload, so each produced chunk is around 800KB To do this, you can divide the size of your full payload, by the number of records it has, and this would give an average record size. Then divide 800,000 bytes with the average record size, and this will give you the chunk size. For example, if your payload size is 1,200,259 bytes, and the number of records is 2500, then the average record size is: 1,200,259 / 2,500 =~ 480 bytes To find the chunk size, we divide 800,000 bytes by 480 bytes 800,000 / 480 =~ 1666 records. So if we send around 1600 records, this should be less than 1MB. To chunk your array payload, we can use the chunk expression inside a compose action. You can use the expression below for chunking inside the compose action: After the compose action, add for-each action, and use the output of the compose action as an input: Inside the for-each, use the normal HTTP to send the logs, and in the body, choose the for-each current item292Views1like0Comments
Central pki
Has anyone implemented a centralised PKI where the Root CA is stored in Azure Key Vault and workloads can automatically obtain the Root CA when they are deployed, as well as receive updated versions when the Root CA needs to be rotated or renewed? I’m looking to implement a centralised PKI for an Azure hub-and-spoke architecture, where workloads across the spokes can automatically obtain and trust the Root CA. The workloads could include VMs, AKS, containers, App Services and Azure Functions. I’m aware that Azure Machine Configuration can be used to deploy certificates to VMs, but this is specific to VMs. What is the recommended approach for distributing the Root CA to the other Azure workload types using a consistent and automated mechanism? Ideally, I’d like the solution to be fully automated, so that new workloads receive the current Root CA during deployment and existing workloads automatically receive updated versions whenever the Root CA is rotated or renewed. I will be deploying the root ca in a key vault via terraform a project for the root ca only to update whenever is needed and then each resources to be able to get the latest root ca. Has anyone implemented something similar, or could you provide guidance on the recommended architecture and distribution mechanism?266Views0likes1Comment
Microsoft SSO SAML Assertion Claims
While getting the assertions back from SAML Assertion Claims, I have configured the user.country & assigned some value in the field. But while getting the claim we are reading the some different value like "IN" ? can I know does the user.country claim supports or not during the claim?452Views0likes4CommentsHow to setup customer to obtain AADB2C token for an API exposed through APIM
I am setting up Azure APIM instance behind a Azure Application gateway. Developer portal will be exposed so external customers will be able to subscribe to products containing the APIs and obtain the subscription key that way. There will be approvals required for subscription. I want to setup OIDC on top of the subscription key validation. For that I believe I have to setup a Validate JWT policy on the API in APIM, using this guide below and use scopes/roles:- https://learn.microsoft.com/en-us/azure/api-management/validate-jwt-policy And seems like I will have to setup client credentials flow for customers to be able to obtain token from AADB2C, using the below KB:- https://learn.microsoft.com/en-us/azure/active-directory-b2c/client-credentials-grant-flow?pivots=b2c-custom-policy Q1 - Firstly, is that the correct way of setting it up? Secondly, with client credentials flow seems like customers will have to use the POST request (or PowerShell) like the one below to obtain the token:- https://<tenant-name>.b2clogin.com/<tenant-name>.onmicrosoft.com/<policy>/oauth2/v2.0/token But this will mean that I will have to document my B2C token endpoint in Developer portal documentation to advise customers on how to obtain token. I have 2 questions related to that:- Q2 - Is advising/advertising B2C token endpoint good practice from security point of view? Q3 - With client credentials flow, setting up the calling app APP Registration in B2C and providing related APP secret will become a manual process. This will remove the benefit of having Product/API subscriptions process automated through APIM and bring in the complexity of securely communicating the secret to customers. Is there a better way of doing this?425Views0likes2CommentsAI Gateway tier of Azure API Management — August 2026 updates
The August 2026 update for the AI Gateway tier (preview) of Azure API Management introduces new capabilities for observing AI workloads and governing model spend. Release highlights Richer OpenTelemetry observability: AI Gateway can now emit logs, distributed traces, token metrics, and estimated cost metrics through the OpenTelemetry Protocol. The built-in monitoring experience helps teams investigate model and MCP tool activity, policy execution, latency, errors, token consumption, and individual traces. Model cost monitoring and budget enforcement: Teams can review estimated model spend by API key and model, then use cost limit policies to set calendar-based budgets and block requests when configured limits are reached. The release also streamlines Microsoft Foundry model imports, refines provider onboarding, improves portal reliability and error guidance, expands Anthropic Messages compatibility, and adds an in-product What's new experience. For configuration guidance, important upgrade information, and the complete list of changes, read the full August 2026 release notes in the AI Gateway portal. Try the latest capabilities in the AI Gateway portal.953Views0likes0CommentsAnnouncing the resiliency agent in Azure Copilot, now in public preview
The distance between knowing and doing Most teams already know that zonal resiliency matters. What slows them down is everything in between: assessing posture across subscriptions and regions, deciding which gaps should be prioritized, writing the templates, and confirming the change actually rolled out. That is four separate workstreams, in four separate places, usually picked up long after the application is shipped. The resiliency agent closes that distance. We’re excited to announce that it is now available in public preview as part of the agents in Azure Copilot. The agent brings resiliency assessment, prioritized recommendations, and deployment-ready code into a single conversation, so resiliency becomes something your team does continuously rather than something you audit once a year. Learn more about Azure Copilot agents here. What the resiliency agent does The Resiliency agent is the conversational, action-oriented layer of Azure Infrastructure Resiliency Manager. The platform gives you a goal-driven view of your resiliency posture, and the agent lets you act on that posture in plain language. It brings together the signals you would otherwise chase manually across availability zones, Azure Backup, Azure Site Recovery, service level indicators, and Azure health models, then turns them into workload-aware guidance you can execute. Starting with zonal resiliency, it is designed to complement the resiliency capabilities you already rely on rather than replace them. The agent is built on the same foundational belief as Azure Infrastructure Resiliency Manager: application resiliency is a continuous journey, not a one-time task. That journey runs in three phases: Start Resilient Get Resilient Stay Resilient. This public preview addresses the activities associated with first two phases, frontloading the capabilities customers asked for most: direct remediation, Infrastructure as Code integration, and cost visibility. Stay Resilient comes next. What you can do in public preview Generate deployment-ready Bicep and Terraform with zone-redundant settings already enabled, before your first deployment Find the service groups and resources that are not zone resilient across your subscriptions and regions Prioritize remediation with cost-aware indicators that flag whether a fix needs extra spend, downtime, or redeployment Generate ready-to-deploy scripts to configure zone resiliency for supported resource types Create and update service groups so your applications are modeled correctly from the start Start resilient: build it in from the first line of code The most durable resiliency is the kind you never have to retrofit. Starting resilient means treating zone resiliency as an architectural requirement on day one, and the Resiliency Agent makes that the path of least resistance. Describe the application you are building, and the agent helps you generate deployment-ready Infrastructure as Code with the recommended resiliency configurations already enabled at creation time. Ask for a Bicep or Terraform template for a new workload and the agent returns one with zone-redundant settings pre-built for your databases, VMs, and load balancers, aligned to the goals you set. For example, try prompts like: “Generate a Bicep template for a zonally resilient VM setup.” “Create Terraform templates for a resilient architecture with VMs, AKS, and Storage.” The payoff: new services reach production already meeting your high availability standards, and the expensive redesign never has to happen. Get resilient: close the gaps in what you already run Applications change. The configuration that was right at first deployment is often not the one a business-critical workload needs two years later. This is where the resiliency agent turns posture insight into prioritized, executable action. Ask the agent to assess your environment, and it surfaces the resources and service groups that are not zone resilient, that are exposed to a datacenter outage, or that have key alerts waiting on attention. Every recommendation carries cost-aware decision support, qualitative indicators that flag whether a fix requires additional spend, downtime, or redeployment, so your team can sequence remediation against business value instead of guesswork. When you are ready to act, the agent generates ready-to-deploy scripts to configure zone resiliency for supported resource types, or targeted IaC snippets to close one specific gap. Try prompts like: “Assign resiliency goals for my application.” “Give me the posture of my service group: Contoso Payments.” “Enable zonal resiliency for my PostgreSQL server.” “Generate scripts to create a zonally resilient storage account.” This is a human-in-the-loop model by design. The agent brings the analysis, the recommendations, and the code. You keep full control over execution. Remediation gets faster without giving up governance. Stay resilient: what comes next Resiliency is not only about withstanding a zone outage. It is about protecting your data and knowing you can recover when something does go wrong. Recovery orchestration plans and zone drills are available today in Azure Infrastructure Resiliency Manager, and we are bringing both into the agent experience next. That closes the loop: assess, remediate, and validate recovery readiness in the same conversation. Get started with the public preview Open Azure Copilot and select the Resiliency Agent from the dropdown or the side panel. Three actions will get you value in the first session. Model your application. The agent works from your application, not a flat list of resources, so make sure it is represented as a service group that reflects your latest resource discovery. You can create service groups natively through the agent. Try: “Create a service group for my application.” Find your gaps. Ask which of your service groups and resources are not zone resilient. Most teams uncover exposure that was previously invisible. See Set resiliency goals and track compliance. Design it in. Ask for a Bicep template with zone-redundant defaults for a workload you plan to deploy and see how much retrofit effort disappears. See Generate resilient Bicep templates. What to expect in the preview Ready-to-deploy zone resiliency scripts are supported for Azure services that have zonal resiliency support in Infrastructure Resiliency Manager. See the support matrix for current coverage. Some advanced configurations, including multi-user authorization and Azure Site Recovery, may require manual steps, and the agent provides guidance to help you complete them. Where we are going This public preview is a starting line, not a finish. We are building toward end-to-end, agent-led journeys across Start, Get, and Stay Resilient, with cross-agent orchestration that reaches into migration, deployment, and observability, and multi-surface delivery so resiliency validation shows up in your IDEs, APIs, and CI/CD pipelines, not only in Azure Copilot. Service coverage will keep expanding, and the guidance will keep getting richer. The goal is simple and ambitious: make resilient-by-design the path of least resistance for every application on Azure. Preview is where that gets shaped, so tell us what is working and what you need next at azureresiliency@microsoft.com. Start here: open Azure Copilot, select the resiliency agent, and ask which of your applications are not zone resilient yet. Resources Announcing Azure Infrastructure Resiliency Manager public preview Agents in Azure Copilot public preview Resiliency capabilities in Agents (preview) in Azure Copilot, Azure Infrastructure Resiliency Manager overview Get started with service groups Microsoft Learn Questions or feedback: azureresiliency@microsoft.com