Recent Blogs
By Mark Gitau and Azin Heidarshenas
In the MLPerf Inference v6.1 round, Azure demonstrated strong Deepseek-R1 performance on GB300 NVL72 and GB200 NVL72 platforms. Azure submitted GB200 results at ...
Sep 16, 2026345Views
1like
0Comments
In large scale AI clusters storage is responsible for delivering training data fast enough to keep accelerators busy and completing checkpoint saves and recoveries quickly enough to avoid costly stal...
Sep 02, 2026386Views
1like
0Comments
3 MIN READ
Overview
Microsoft HPC Pack is a Windows‑based high‑performance computing (HPC) scheduler that enables customers to deploy, manage, and operate HPC workloads in on‑premises and hybrid environments....
Aug 25, 20261.1KViews
0likes
1Comment
Introduction
Traditional High-Performance Computing (HPC) is central to most scientific computing and engineering applications. These systems are based on well tested, repeatable, and scalable comp...
Jul 21, 2026442Views
0likes
0Comments
Introduction
High-performance computing is the engine behind the most demanding engineering breakthroughs. In electronic design automation, HPC enables massive simulation farms, verification regres...
Jul 21, 2026656Views
0likes
0Comments
By Shantanu Patankar, and Azin Heidarshenas
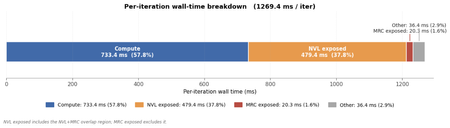
As part of Azure's MLPerf Training v6.0 submission, we scaled Llama 3.1 405B (NVFP4) pretraining to 8,192 GB200 GPUs across 128 racks on Azure's Fairwa...
Jun 24, 2026492Views
2likes
0Comments

This blog presents a validation study of Siemens NX 2506 running in a multi-user Azure Virtual Desktop (AVD) environment powered by NVIDIA RTX PRO 6000 GPUs. It demonstrates how a single GPU-backed A...
Jun 17, 2026463Views
0likes
0Comments
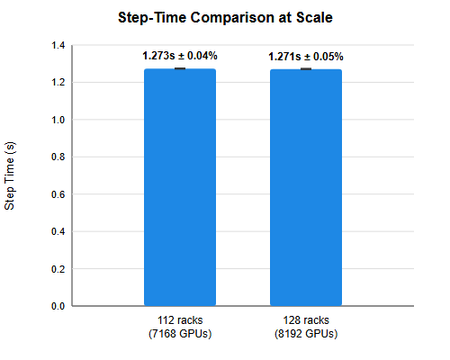
Azure achieved the most performant MLPerf Training v6.0 result to date for Llama 3.1 405B, with a time-to-train of just over seven minutes according to MLCommons. This loadbearing benchmark measures ...
Jun 16, 20266.5KViews
6likes
0Comments
Co-Author:
Ansys/Synopsys
Roman Walsh
Madeleine Driver
Jun 11, 2026217Views
0likes
0Comments

10 MIN READ
The Paradigm Shift in Model Training
The conventional wisdom in deep learning has been simple: bigger models require bigger infrastructure. Training a 100-billion parameter language model tradition...
May 28, 2026445Views
1like
0Comments
Tags
- hpc260 Topics
- ai infrastructure117 Topics
- virtual machines80 Topics
- benchmarking63 Topics
- storage23 Topics
- updates21 Topics
- events19 Topics
- ramp up with me13 Topics
- msignite2 Topics
- Microsoft Ignite 20231 Topic