hpc
264 TopicsMatching Storage Performance to every stage of your AI Workloads on Azure
Every minute a GPU spends waiting for data is a minute you pay for and get nothing back. As accelerators get faster and clusters grow, that idle time adds up quickly: training jobs stall waiting for the next batch, checkpoints can pause thousands of GPUs at once, and inference fleets sit idle while model weights load. Keeping GPUs productive comes down to one question: can your storage deliver the right data, at the right speed, at every stage of the workload? On Azure, the answer is one architecture that combines durable core storage with workload-specific acceleration. Accelerator storage can bring data closer to compute or provide an accelerated access path within the durable storage foundation itself. In this post, we show how that works in practice, with real benchmark results, and what it means for the time your GPUs spend computing instead of waiting. One AI workload, many data paths A single AI application places very different demands on storage across its lifecycle. Data preparation must enumerate and filter enormous numbers of objects. Training requires sustained high-throughput reads, while checkpointing creates bursts of write bandwidth. Model loading drives simultaneous reads of large files across many nodes, inference and agentic workloads add latency-sensitive access and the need to persist and reuse context. Because these requirements vary so widely, the sweet spot is usually one durable data estate with a data path tuned to each stage. The storage solutions may differ, but they must work together so data, artifacts, and state remain available across the AI lifecycle. One continuous data path on Azure Azure uses Blob Storage as the durable data foundation, with multiple performance paths for workloads that require higher throughput, lower latency, file-system access, or compute-local caching. Core storage provides the foundation where data and state live across the AI lifecycle. Accelerator storage describes how performance is delivered, not only where a separate storage layer sits: it can place performance closer to compute or accelerate access to data within core storage itself. These are choices within one architecture, not a mandatory chain: each stage can use the path that best matches its throughput, latency, interface, and reuse requirements. Core storage is the durable, massively scalable system of record for the whole AI lifecycle. On Azure, that foundation is Azure Blob Storage: one home for raw and curated datasets, checkpoints and model weights, built for the scale and durability AI data demands. Azure Blob Storage has a performance profile that in several scenarios can be smoothly plugged directly in the specific AI scenario and this performance can be augmented through accelerator storage. Accelerator storage provides the workload-specific speed that improves core storage performance when needed for compute. It can take the form of a storage or caching layer closer to compute, or an accelerated access path within the core storage service itself. In either case, the goal is to deliver the throughput and latency each stage needs, from sustained training reads and checkpoint write bursts to model-loading fan-out and fast access to reusable context, so GPUs spend more time computing and less time waiting. Because core storage remains the system of record, acceleration can be matched to each job’s performance needs without turning every workload into a new data silo. Where a separate accelerator layer is used, its capacity can be sized to the job; where acceleration is delivered within core storage, higher performance can be applied to the data that needs it. Applications can retain familiar file system interfaces or existing object storage APIs, while data, artifacts and state remain part of one durable data estate. Acceleration in action: performance where the workload needs it Turbo tier: accelerating Azure Blob Storage Turbo tier brings SSD-backed performance to your Azure Blob data while the remainder can stay on lower-cost HDD-backed tiers in the same storage account. It brings SSD-backed performance to performance-demanding data while retaining HDD-backed economics for the rest, within one standard Azure Storage account. Applications continue using the same account, namespace, Blob APIs, SDKs and tooling. Turbo is an access tier, not a cache or a separately managed high-performance storage account: customers can accelerate the subset of data that requires it rather than move an entire dataset into a separate SSD storage architecture. Customers define a Turbo capacity target for the high-performance working set. Smart placement moves eligible objects between Turbo and HDD-backed tiers as access patterns change, while explicit tiering remains available when applications need deterministic control. The objective is to apply higher throughput, higher transaction rates and lower latency where they create workload value, without requiring every object to carry the cost of SSD-backed storage. In a synthetic 4 KiB random-read test against the same dataset, Turbo tier delivered 16.8× the transaction rate, reaching 10.1 million transactions per second compared with 601,000 on Standard Blob with HDD-backed tiers. Turbo tier used 256 Standard D96s v6 worker VMs, while Standard Blob used 72 to stay within HDD-backed storage account limits. In a separate read-bandwidth benchmark, Turbo tier sustained more than 20 Tbps, relevant for checkpoint recovery, model loading and inference scale-out. Read more in our blog post Blob Storage Turbo Tier: High performance with object storage scale and economics For AI training and fine-tuning, this can help feed performance-sensitive training data and support checkpoint writes. For inference, it can provide faster access to models and application data as services start and scale; analytics and HPC pipelines can similarly accelerate repeated processing of the performance-demanding portion of a larger data lake. Preview eligibility is limited to LRS accounts in selected regions, subject to regional capacity. Azure Managed Lustre: feeding training and protecting checkpoints Azure Managed Lustre is another example of what the accelerator layer can deliver when AI workloads need performance close to compute. Its integration with Azure Blob Storage connects the high-performance file system used by the job with the durable core storage layer where datasets, checkpoints and model artifacts can remain available across the AI lifecycle. MLPerf Storage v3.0 results, released by MLCommons on September 1, 2026, provides an independent and comparable view of that accelerator performance. Azure Managed Lustre was the first hyperscale cloud storage service submitted at the scale of more than 600 GB/s (4.8 Tbps). The results illustrate two critical accelerator storage patterns. For training, Azure Managed Lustre sustained the data path needed to keep simulated accelerator utilization above 90% for five consecutive hours, while read bandwidth scaled from 17.4 GiB/s at 3 simulated NVIDIA B200 accelerators to 379.1 GiB/s at 70. For checkpointing, the largest configuration, representing a 1,250B-parameter model, wrote at 642.2 GiB/s and recovered at 489.6 GiB/s, the second-highest peak checkpoint write among all submissions. Overall, Azure performed comparably to purpose-built on-premises AI storage in both categories. Figure 1. MLPerf Storage v3.0 results on Azure. Left: training read bandwidth from 3 to 70 simulated B200 accelerators versus ideal linear scaling. Right: checkpoint write and recovery read throughput by model scale. Explore the Azure Managed Lustre MLPerf Storage v3.0 results for benchmark methodology, tested configurations, and detailed training and checkpointing results. DACS: bringing reusable data closer to GPU compute DACS extends the accelerator pattern to AI workloads on Azure Kubernetes Service. Now in public preview, it is a distributed read-through cache that uses local NVMe disks across nodes to keep frequently read data from Azure Blob Storage close to GPU compute. For repeated reads after the working set is warm, this can reduce Blob fetches and increase the bandwidth available for model loading and repeated training-data access. This means reducing warm-model loading times and repeated Blob reads as inference workloads scale, restart or recover, and can accelerate training that repeatedly accesses the same dataset portions. In Standard LRS sequential-read testing with BlobFuse2 across ten workers, colocated DACS reached 47,760.75 MiB/s of warm bandwidth at 16 I/O threads per worker, 84.0% above BlobFuse2 alone and 10.9% above dedicated DACS. Teams can use DACS through Azure Container Storage with Run:ai Model Streamer, BlobFuse2 or the native Python client, while Azure Blob Storage remains the durable source of truth and the fallback when data is not cached. Figure 2. Standard LRS sequential-read bandwidth by I/O thread count for BlobFuse2 alone and dedicated or colocated DACS, with cold and warm cache results. Choosing the right acceleration for your bottleneck To optimize your GPU data path, you can choose the best solution for each workload stage: Azure Blob Storage can be accelerated using Turbo tier when an application needs higher-performance object access without changing its Blob account, namespace, or APIs. Azure Managed Lustre can be used when training and checkpointing require a high-throughput parallel file system close to compute, and your applications need POSIX file system semantics. DACS on AKS can be used when repeated reads of Blob data can benefit from distributed node-local caching. Today, DACS supports Run:ai Model Streamer, BlobFuse2 or the native Python client. In all the cases, Azure Blob Storage remains the durable data foundation that can be still accessed directly by all the portion of the workflows that do not require specific acceleration. The architectural goal is the same: place performance where the workload needs it, so compute spends less time waiting for data without creating new systems of record. See it at SC26 These topics will be covered in our session at SC26. At the Microsoft booth, we’ll walk through the same data path end to end: preparing data, feeding training, protecting checkpoints, loading models and reusing context for inference. You’ll see where each storage layer helps keep GPUs busy and how the layers connect into one architecture. Join Wolfgang De Salvador, Sachin Sheth and Brian Lepore for Storage Innovation for AI on Wednesday 18 November, 2:00–2:20 pm CT, at booth #3411. Session: Storage Innovation for AI Speakers: Wolfgang De Salvador, Sachin Sheth and Brian Lepore Where: Microsoft booth theater, booth #3411, McCormick Place, Chicago When: Wednesday 18 November, 2:00–2:20 pm CT
Accelerating AI Data Processing, HPC, and Agentic Workloads with Azure HDv2 Virtual Machines
Advancing model intelligence starts with training, and training starts with data. Before GPU supercomputers can train a model, enormous fleets of CPUs must collect, clean, filter, and format that data. If CPUs fall behind, expensive GPU capacity becomes underutilized and delays the delivery of smarter models to market. As demand grows for models yielding ever more intelligence per task, the need for leadership AI data processing capabilities becomes paramount. To address that need, Microsoft is excited to announce today the Preview of Azure HDv2 virtual machines (VMs), the fastest and most energy efficient platform ever for AI data processing. HDv2 VMs are built with 6 th Gen AMD EPYC™ processors, codenamed “Venice.” Customers can sign up to request access to the Preview at https://aka.ms/HDv2Preview. “When we prepare large datasets for AI research, more CPU cores let us split the work across more jobs, provided each job has enough memory. That same balance matters when many coding agents build software and run tests at once. We’ve worked with Microsoft on Azure HDv2, and we’re excited to explore what it can bring to our research as these workloads grow.” -Rafael Dietrich, Head of CPU & Storage Capacity Planning, OpenAI “As AI scales, data preparation, processing, and orchestration all place enormous demands on CPU compute. With Azure HDv2, AMD and Microsoft co-designed a platform around 6th Gen AMD EPYC processors with Azure’s expertise in cloud infrastructure at scale. Our work together will help customers accelerate turning massive data sets into frontier intelligence.” -Dan McNamara, Senior Vice President and General Manager of Compute and Enterprise AI, AMD Enabling Faster Time to Intelligence HDv2 has been co-designed with leading AI model developers for the highest levels of data processing performance and efficiency. To support highly parallelized applications like Apache Spark, HDv2 features more than 500 physical AMD “Zen 6” CPU cores from the newly introduced EPYC 9006-series of processors. To store vast datasets in memory across a fleet of compute VMs, HDv2 also features 3.8 terabytes of DDR5-8800 memory. To cache these datasets close to compute, HDv2 features 30 TB of PCIe Gen 5 NVMe storage. And to quickly ingress raw data and egress a refined dataset primed for training, HDv2 features 400 Gb Azure Boost Networking. Together, this design enables HDv2 to deliver the highest levels of performance and energy efficiency ever for data processing, even compared against the latest in-market alternatives. Figure 1: HDv2 VM specifications, with Apache Spark performance, and performance/watt measurements. Preliminary measurements only and subject to change. Leadership in Compute-bound HPC, and Agentic + RL Task Throughput Data preparation for AI training is only one of HDv2’s strengths, as it also brings very large performance advantages to other popular HPC and agentic workloads Azure customers rely on for research, development, and mission-critical services. First, HDv2 delivers large gains for compute-bound HPC applications thanks to its 500 cores capable of single-cycle AVX-512 instruction throughput, which yield more than 2x the peak FP64 performance of any other Cloud dual-socket server. Coupled with 3.8 TB of RAM per VM and 8 GB of RAM per core profile, HDv2 can run the large majority of HPC models from research and industry within a single VM at exceptionally high performance. HPC workloads such as implicit finite element analysis, acoustics, molecular dynamics, and electromagnetics, financial risk simulation, and high-fidelity post-processing will all see significant speedups compared against the latest in-market alternatives. Below, find a performance comparison across the newly released SPEC CPU 2026 Floating Point benchmark suite evaluating 12 distinct workload domains representing the broader HPC market spanning industrial technical computing, to scientific simulation, and beyond. Figure 2: HDv2 performance on SPEC CPU 2026 FP Rate, with comparative diverse conventional HPC workload domains. Preliminary measurements only and subject to change. In addition, HDv2’s more than 500 physical cores make it Azure’s most powerful platform to date for agentic AI and reinforcement learning (RL), where CPUs set the pace for the GPUs they support. Every time an agent runs code or calls a tool, it does so in an isolated sandbox on a CPU, and RL runs hundreds or thousands of these sandboxes at once. When cores run short, the GPUs directing the agents sit idle. A single HDv2 VM can run about twice as many sandboxes in parallel as the next-best in-market alternative with up to 1.7x more agentic task throughput, keeping accelerators productive and agentic workflows responsive to end users. The chart below shows HDv2’s throughput advantage on SPEC CPU 2026 Integer Rate, a proxy for agentic and RL task throughput. Figure 3: HDv2 performance on SPEC CPU 2026 Integer Rate, with comparative agentic AI and reinforcement learning task-throughput measurements. Preliminary measurements only and subject to change. Broadly Accessible by Design HDv2’s advantages for a wide variety of customer workloads means it is important Microsoft make it as accessible as possible. As such, HDv2 will be made available at GA through a broad set of Microsoft services such as Azure Kubernetes Service, Azure Databricks, and Azure CycleCloud, as well as leading partner platforms such as those from Rescale, Synopsys (ANSYS), and others. Figure 4: Microsoft services and partner platforms for broad access to Azure HDv2 VMs. Availability may vary. “Azure HDv2 VMs will empower Rescale’s HPC customers with new levels of performance. HDv2’s 500+ cores and nearly 4 TB of memory expand the performance frontier for CAE workflows, from larger implicit FEA models and dense-matrix electromagnetics, to coupled fluid-structure simulations. By putting more compute and memory in a single node, these VMs allow many workloads currently spread across multiple nodes to run on a single node, reducing communication overhead and simplifying execution” -Adam McKenzie, Chief Technology Officer, Rescale Sign up for the HDv2 preview Preview registration is now open for Azure HDv2 VMs. Customers interested in faster AI data preparation, compute-intensive HPC performance, and dense agentic sandbox capacity can sign up today to request access and evaluate HDv2 with their workloads. Sign up for preview access to Azure HDv2 VMs
From Silicon to Service: Bringing AMD Helios™ to Azure
Article contributed by: Yash Bhamare and Anna Daly Azure’s ND MI455X v7 brings a rack-scale approach to AI inference, powered by AMD Helios. Each liquid-cooled compute rack combines 72 MI455X GPUs, 18 AMD EPYC “Venice” CPUs, and 31 TB of HBM4 memory, with a two-tier Ethernet backend connecting racks into larger clusters. Designed for reasoning, long-context inference, search, and multi-agent services, the platform brings compute, memory, and networking together to support demanding AI workloads. In the Azure context, “silicon to service” describes the engineering around that hardware foundation and deploying the hardware at scale. Start with the user’s needs Consider a user who asks a trained AI model a question and receives a response. For that user, the response is the result that matters. Microsoft provides the infrastructure behind that experience as a cluster product, including GPU capacity and a commitment to its availability and reliability. Users need confidence that their GPUs will be available when needed, that the next job will run reliably, that updates will leave the system usable, and that faults will leave enough evidence for diagnosis. Reliability lets model teams and engineers focus on their models rather than rediscovering machine state. It requires infrastructure that can be deployed, observed, updated, and recovered predictably. Datacenter requirements At Microsoft, we deliver AI supercomputing clusters as a product. With AMD, we design from the rack up to meet customer workload requirements. We account for power, cooling, and physical fit so each rack can be deployed, operated, and maintained in the datacenter throughout its lifetime. A Microsoft-owned, two-tier back-end network connects racks for high-bandwidth communication. Our job is to bring compute, networking, software, and physical infrastructure together into a system customers can use reliably. Hardware availability shapes how we get there, and a standalone rack lets us advance software enablement and rack-local testing, but validating the cluster requires connected racks and the back-end network operating together under load. That is why we include power delivery, cooling, cabling, and software versions in the test configuration rather than treating them as separate concerns. The same principle applies after maintenance. We confirm that a replacement component responds and works within the connected system. Establish a repeatable software foundation System firmware, the operating-system kernel and device drivers must work together to initialize and manage hardware. Testing each layer alone cannot establish how the stack behaves. A versioned baseline recipe of all firmware components, the operating-system image, GPU and network drivers, and diagnostic tools are tested together. This supports reproducible installation in cloud-scale datacenters and helps distinguish hardware faults from configuration or integration issues. Secure boot and driver signing also belong in that baseline and repeatability must preserve Microsoft’s trust requirements. When expected behavior changes, the baseline provides a traceable starting point for investigation. Bring cloud management into the lab early Our work starts when the first systems power on in the lab, and since early hardware is limited and still evolving, we focus on iterating quickly by testing whatever we can, fixing what we find, and testing again. The first milestone is a stable foundation, where each system reliably boots the target operating system, discovers and initializes its devices, and reports their health. Getting there often exposes subtle interactions between firmware, drivers, and the operating system that we need to resolve before more advanced testing can begin. Once the system is stable, we turn to performance, starting with microbenchmarks for GPU compute, memory bandwidth, and GPU-to-GPU and network transfers, and using tools such as TransferBench and RCCL tests to characterize how accelerators communicate. These simple tests are especially valuable during bring-up because an unexpected result can point to a firmware defect, a driver issue, or a configuration problem. From there, we step up to distributed training and inference workloads to see how compute, memory, and networking behave together under sustained load and where the software stack needs tuning. Alongside this work, we validate how device inventory and configuration integrate with Azure for health reporting, updates, and recovery, so the tests, tooling, and management workflows we refine in the lab are ready to scale in the datacenter. Burn-In – Make readiness an engineering outcome Burn-in is where we take the same kinds of tests we ran in the lab and automate them at scale in the datacenter. Before a cluster reaches customers, we lock in an approved hardware and software configuration and use SuperBench to orchestrate sustained workloads across the whole system. Running these workloads for extended periods across thousands of GPUs surfaces intermittent hardware failures, thermal problems, and performance anomalies that shorter lab runs can miss. The communication tests from the lab also expand to cover the full network, both within racks (scale-up) and across racks (scale-out), where RCCL collectives such as AllReduce and AllGather expose bandwidth bottlenecks, topology misconfigurations, and failures that only appear at scale. After any faulty components are repaired or replaced and retested, the cluster enters production with data showing it can sustain demanding distributed AI workloads at expected performance and run reliably as one system. Exercise recovery as normal operation Once GPU racks enter production and begin running customer workloads, hardware failures are inevitable over time. These failures may manifest as workload performance degradation, unexpected errors, or device failures that must be traced to specific hardware components across one or more systems. To maintain cluster capacity, healthy spare nodes replace affected systems, while faulty nodes are moved to dedicated quarantine racks for further investigation. There, we run extensive diagnostics to isolate the underlying issues and repair or replace faulty components. Repair alone, however, is not sufficient to return a system to production. While still in quarantine, the repaired node undergoes another round of validation, running representative workloads against established performance and reliability baselines. This ensures that the original issue has been resolved and that the system performs as expected under realistic operating conditions. Once the node passes these checks, it becomes a healthy spare, ready to replace the next system requiring maintenance. This creates a continuous cycle of detection, isolation, repair, validation, and reuse, allowing Azure to maintain reliable GPU capacity as hardware ages and individual components fail. We apply the same rigor to system updates, looking across the GPU, firmware, operating system, and network layers to verify that the system remains healthy and workloads can continue or recover predictably after a change. Come and See it at SC26 This is what we mean by Microsoft delivering AI Supercomputing Clusters. Yash Bhamare and Anna Daly will share more in their session at the Microsoft booth (#3411) at SC26, on Wednesday 18 November at 10:00am CT.Retirement of Microsoft HPC Pack
Overview Microsoft HPC Pack is a Windows‑based high‑performance computing (HPC) scheduler that enables customers to deploy, manage, and operate HPC workloads in on‑premises and hybrid environments. Since its original release, HPC Pack has supported a range of Windows‑centric HPC scenarios, including job scheduling, workload orchestration, and integration with Windows Server–based technologies. Microsoft is announcing the planned retirement of HPC Pack. For customers looking to run HPC workloads going forward, Microsoft’s supported platform for managed HPC and parallel workloads is Azure Batch. Customers may also adopt any other Azure service as appropriate for their workload. These platforms provide modern, cloud‑native capabilities for scheduling, scaling, and operating HPC workloads on Azure. Important Dates Retirement announcement: August 27, 2026 End of Support / retirement date: August 27, 2027 After August 27, 2027, HPC Pack will no longer receive feature updates, bug fixes, or standard product support. No new versions or enhancements will be released. Existing HPC Pack deployments will not be forcibly disabled; however, they will be considered unsupported. Microsoft will not extend HPC Pack 2019 support beyond August 27, 2027, or offer paid post-retirement support. Support During the Retirement Period HPC Pack is now entering a one-year retirement period that ends at End of Support on August 27, 2027. Microsoft will provide limited, retirement-only support during this period. The scope of this support is defined below so customers know what to expect. What Microsoft will provide during the retirement period: Security response, including investigation of applicable security vulnerabilities (CVEs) and any security updates deemed necessary by Microsoft Guidance based on existing Microsoft documentation, published best practices, and previously validated HPC Pack configurations Assistance with support incidents involving supported HPC Pack components and documented product functionality What is NOT included during the retirement period: Non-security bug fixes Performance, reliability, scalability, or optimization improvements New features or feature enhancements Customer-specific hotfixes, custom code changes, or design modifications Validation or certification of new operating systems, hardware platforms, drivers, firmware, third-party software, or dependencies Validation of new deployment architectures, configurations, or integration scenarios Changes to existing product behavior or design Creation of new documentation, guidance, or troubleshooting content Troubleshooting that requires new product investigation beyond existing product knowledge, documentation, or previously validated scenarios New customer onboarding, solution design, or pre-sales assistance Migration planning, migration execution, or migration consulting services Support for configurations, integrations, or deployment scenarios that are outside published documentation, established best practices, or previously validated HPC Pack environments After End of Support (August 27, 2027): HPC Pack will receive no further updates, fixes, or technical support, and deployments will be considered unsupported. What Customers Should Do Customers currently using HPC Pack should begin planning migration to a supported alternative as soon as possible. For most scenarios, the following services are recommended: Azure Batch – for managed scheduling and execution of parallel and HPC workloads Or any other Azure service as appropriate for your workload Resources HPC Pack documentation: Microsoft HPC Pack 2019 Public issue tracker: Azure/hpcpack GitHub repository Next Steps Customers who anticipate needing additional planning assistance or migration guidance should engage early with their Microsoft account team or Cloud Solution Architect (CSA) to help ensure a smooth transition and avoid potential disruption.Upgrade Azure CycleCloud Slurm Node OS Images Without Recreating the VM Scale Set
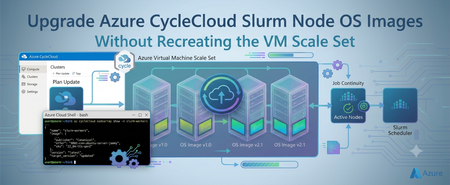
Overview Operating-system image updates in an Azure CycleCloud Slurm cluster are not the same as installing ordinary packages inside a running node. A CycleCloud Slurm node is typically an instance in an Azure Virtual Machine Scale Set (VMSS), and the VMSS model defines the image from which its OS disk is created. This distinction is especially important when the VMSS uses Manual upgrade mode. Changing an image setting does not automatically upgrade running instances. Likewise, reimaging a node without first changing the VMSS model can rebuild that node from the same old image. This article describes a controlled, node-by-node method for moving an existing CycleCloud-managed Slurm partition from one Ubuntu HPC image version to another without deleting and recreating the entire VMSS. NOTE: The same procedure can be used for other schedulers. The appropriate scheduler specific commands need to used for node servicing. The validated example changes the image reference from: microsoft-dsvm:ubuntu-hpc:2404:24.04.2026052601 to: microsoft-dsvm:ubuntu-hpc:2404:24.04.2026092501 These versions are examples from the validated procedure. Always select and validate an image appropriate for your region, VM size, kernel, drivers, scheduler integration, and application stack. Problem statement A CycleCloud Slurm cluster may have long-running compute or GPU nodes that require a newer OS image for reasons such as: Security and compliance updates Kernel fixes Updated device drivers Platform fixes Updated HPC libraries Standardization on a newer image baseline Application or container-runtime compatibility Supportability requirements The most straightforward lifecycle operation is often to update the image in CycleCloud, scale the partition down, allow CycleCloud to remove the old VMSS, and then scale the partition back up. CycleCloud then creates a new VMSS using the updated image. Although that method provides a clean deployment, it may be undesirable in a busy HPC environment because: The complete partition may need a maintenance window. All nodes in the partition may become unavailable together. Deleting the scale set deliberately releases the partition’s current VM allocations. Capacity must be acquired again when the partition is restarted. Azure capacity is dynamic and cannot always be guaranteed at the time of reacquisition. Validation happens after a larger infrastructure change instead of on a single canary node. A deployment problem can affect the entire partition rather than one selected instance. Large distributed workloads may take significant time to drain from the full partition. Administrators may therefore need a method that updates the OS image of selected idle nodes while the remaining nodes continue serving workloads. The challenge is that three separate states must be understood and managed: CycleCloud cluster configuration The image definition CycleCloud will use when it creates or recreates infrastructure. VMSS model The image reference currently defined on the existing scale set. VMSS instance state Whether a particular VMSS instance has applied the latest VMSS model. If these three states are not handled in the correct order, a reimage can complete successfully while leaving the node on the old image. Why reimage alone does not solve the problem A reimage replaces the node’s OS disk using the image and configuration associated with its current infrastructure model. Reimage does not, by itself, select a newer OS image. This creates a common failure pattern: The desired image is changed in the CycleCloud cluster configuration. The existing VMSS continues to reference the old image. A CycleCloud, Slurm, or VMSS reimage action is initiated. The OS disk is rebuilt. The node returns using the old image because the VMSS model still references that image. For a VMSS configured with Manual upgrade mode, the required order is: Drain the selected Slurm node. Change the image reference in the existing VMSS model. Confirm the new image in the VMSS model. Confirm that existing instances report LatestModelApplied=False. Apply the latest model to one selected instance using az vmss update-instances. Wait for the node to return. Confirm that the selected instance reports LatestModelApplied=True. Verify the new image from inside the VM. Validate the OS, scheduler, drivers, network fabric, container runtime, and workload. Resume the node. Repeat for the remaining instances. Update the CycleCloud node-array image configuration to prevent configuration drift. Advantages of this approach No full VMSS recreation The existing VMSS object is updated in place. The process does not intentionally delete the complete scale set and create a replacement. Node-level maintenance Only the selected VMSS instance is disrupted. Other nodes can remain available, provided that the workload and cluster architecture support node-by-node maintenance. Canary validation One idle node can be upgraded first. The new image can be tested against the actual scheduler, drivers, network, containers, and applications before expanding the change. Smaller failure domain If the first upgraded node fails validation, it can remain drained while the remaining nodes continue using the previous image. Reduced capacity exposure The procedure avoids deliberately scaling the entire partition to zero and releasing all current allocations at once. This can reduce exposure to capacity reacquisition risk. However, it should not be treated as a guarantee that host placement or capacity will never change during platform servicing. Controlled scheduling Nodes can be upgraded as they become idle. Slurm drain and resume operations create a clear boundary between: Workload evacuation Infrastructure servicing Technical validation Return to production Measurable rollout progress The latestModelApplied property provides an explicit signal showing which VMSS instances have received the updated model. Easier rollback control If the canary node fails, the rollout can stop before all nodes are changed. This is generally easier to manage than recovering an entire recreated partition. Important limitations This is a rolling infrastructure procedure, not a zero-downtime operation. The selected node becomes unavailable while its OS disk is serviced. Jobs running on that node must complete, migrate, be requeued, or be stopped. Multi-node MPI and distributed training jobs may make node-by-node maintenance impractical. A partition-wide maintenance window may be safer when jobs span most or all nodes. Data or configuration stored only on the OS disk may be lost during servicing. Node bootstrap should be reproducible and important state should be stored externally. Containers do not isolate applications from every host change. The host kernel, GPU driver, RDMA stack, device plugins, mounts, and scheduler integration remain important to containerized workloads. A direct VMSS update does not permanently update the CycleCloud cluster definition. CycleCloud must be updated after successful validation to prevent configuration drift. Prerequisites Before starting, confirm the following: The target node belongs to the expected CycleCloud-managed VMSS. The VMSS uses Manual upgrade mode. The target image has been selected and validated for the environment. The target image is available for the required region and VM size. You have Azure permissions to read and update the VMSS and its instances. (Contributor or Virtual Machine contributor role for the subscription) Azure CLI is installed and authenticated in the correct tenant and context. jq is available on the Linux node for metadata formatting. You have Slurm administrative permission to drain and resume nodes. Required application and configuration state is not stored only on the OS disk. A maintenance window has been approved. A rollback plan has been documented. The first target is an idle or noncritical canary node. Define placeholders instead of embedding environment-specific values: RESOURCE_GROUP="<RESOURCE-GROUP>" VMSS_NAME="<VMSS-NAME>" INSTANCE_ID="<INSTANCE-ID>" SLURM_NODE="<SLURM-NODE-NAME>" TARGET_IMAGE_VERSION="24.04.2026092501" PREVIOUS_IMAGE_VERSION="24.04.2026052601" Detailed upgrade procedure Step 1: Capture the current image from inside the HPC compute node Run the following on the target VM. curl -s -H Metadata:true --noproxy "" "http://169.254.169.254/metadata/instance/compute?api-version=2021-10-01" | jq '{publisher, offer, sku, version, osType}' Output: { "publisher": "microsoft-dsvm", "offer": "ubuntu-hpc", "sku": "2404", "version": "24.04.2026052601", "osType": "Linux" } Also record the current OS release and kernel: cat /etc/os-release uname -r Keep these results in the change record. They provide the baseline needed to prove that the image changed after the operation. vinil@”$SLURM_NODE”:~$ cat /etc/os-release PRETTY_NAME="Ubuntu 24.04.4 LTS" NAME="Ubuntu" VERSION_ID="24.04" VERSION="24.04.4 LTS (Noble Numbat)" VERSION_CODENAME=noble ID=ubuntu ID_LIKE=debian HOME_URL="https://www.ubuntu.com/" SUPPORT_URL="https://help.ubuntu.com/" BUG_REPORT_URL="https://bugs.launchpad.net/ubuntu/" PRIVACY_POLICY_URL="https://www.ubuntu.com/legal/terms-and-policies/privacy-policy" UBUNTU_CODENAME=noble LOGO=ubuntu-logo vinil@”$SLURM_NODE”:~$ uname -r 6.8.0-1054-azure Step 2: Confirm the VMSS upgrade mode and current image Run the following from Azure Cloud Shell: az vmss show --resource-group "$RESOURCE_GROUP" --name "$VMSS_NAME" --query "{UpgradeMode:upgradePolicy.mode,Image:virtualMachineProfile.storageProfile.imageReference}" --output json Sanitized output: { "Image": { "offer": "ubuntu-hpc", "publisher": "microsoft-dsvm", "sku": "2404", "version": "24.04.2026052601" }, "UpgradeMode": "Manual" } The important value is: "UpgradeMode": "Manual" With Manual upgrade mode, changing the VMSS model does not automatically update existing instances. Do not continue until the current image and upgrade mode match the change plan. Step 3: Map Slurm nodes to VMSS instance IDs List all instances in the scale set: az vmss list-instances --resource-group "$RESOURCE_GROUP" --name "$VMSS_NAME" --query "[].{InstanceId:instanceId,ComputerName:osProfile.computerName,ProvisioningState:provisioningState}" --output table Output: InstanceId ComputerName ProvisioningState ------------ -------------- ------------------- 0 <NODE-000> Succeeded 1 <NODE-001> Succeeded Confirm the mapping carefully. A VMSS instance ID is not necessarily the same as a Slurm node name. For the first validation: INSTANCE_ID="0" SLURM_NODE="slurm-hpc-1" Only one instance should be selected for the canary upgrade. Step 4: Drain the selected Slurm node Prevent Slurm from scheduling new jobs on the node: SLURM_NODE="slurm-hpc-1" scontrol update NodeName="$SLURM_NODE" State=DRAIN Reason="VMSS OS image upgrade" Confirm the state: sinfo -N -n "$SLURM_NODE" Output: NODELIST NODES PARTITION STATE slurm-hpc-1 1 hpc* drain Check whether jobs are still assigned to the node: root@slurm01-scheduler:~# squeue -w "$SLURM_NODE" JOBID PARTITION NAME USER ST TIME NODES NODELIST(REASON) root@slurm01-scheduler:~# Proceed only when: The node is DRAINING while existing work completes, or DRAINED when no work remains. squeue -w returns no active jobs for the node. Dependencies involving distributed jobs have been considered. The node does not hold application state required by active workloads. Do not continue while the node is still running a workload. Step 5: Update the OS image in the VMSS model Update only the image version in the existing scale-set model: az vmss update --resource-group "$RESOURCE_GROUP" --name "$VMSS_NAME" --set virtualMachineProfile.storageProfile.imageReference.version="$TARGET_IMAGE_VERSION" The command may return a large JSON object. The important sections should contain: { "upgradePolicy": { "mode": "Manual" }, "virtualMachineProfile": { "storageProfile": { "imageReference": { "offer": "ubuntu-hpc", "publisher": "microsoft-dsvm", "sku": "2404", "version": "24.04.2026092501" } } } } At this point: The VMSS model references the target image. Existing VMSS instances have not yet been upgraded. No node should be assumed to be using the target image yet. This separation is one of the most important concepts in the procedure. Step 6: Verify the target image in the VMSS model Query only the image reference: az vmss show --resource-group "$RESOURCE_GROUP" --name "$VMSS_NAME" --query "virtualMachineProfile.storageProfile.imageReference" --output json Output: { "offer": "ubuntu-hpc", "publisher": "microsoft-dsvm", "sku": "2404", "version": "24.04.2026092501" } Do not continue until the VMSS model shows the intended target image. Step 7: Confirm that existing instances have not applied the new model Run: az vmss list-instances --resource-group "$RESOURCE_GROUP" --name "$VMSS_NAME" --expand instanceView --query "[].{InstanceId:instanceId,ComputerName:osProfile.computerName,LatestModelApplied:latestModelApplied,ProvisioningState:provisioningState}" --output table Output: InstanceId ComputerName LatestModelApplied ProvisioningState ------------ -------------- -------------------- ----------------- 0 <NODE-000> False Succeeded 1 <NODE-001> False Succeeded The important value is: LatestModelApplied=False This confirms that: The VMSS model contains the new image. The existing VMSS instances are still using their previous model. The model change has not automatically upgraded the nodes. Step 8: Apply the latest model to the canary instance Apply the updated VMSS model to only the selected instance: az vmss update-instances --resource-group "$RESOURCE_GROUP" --name "$VMSS_NAME" --instance-ids "$INSTANCE_ID" This operation is disruptive to the selected node. Its OS disk is serviced and connectivity is temporarily unavailable. Do not start another node upgrade until this instance has: Returned to a successful provisioning state. Booted correctly. Completed CycleCloud initialization. Reconnected to Slurm. Passed the complete validation checklist. Step 9: Confirm that the canary applied the latest model Run the instance-view query again: az vmss list-instances --resource-group "$RESOURCE_GROUP" --name "$VMSS_NAME" --expand instanceView --query "[].{InstanceId:instanceId,ComputerName:osProfile.computerName,LatestModelApplied:latestModelApplied,ProvisioningState:provisioningState}" --output table Expected result after upgrading instance 0: InstanceId ComputerName LatestModelApplied ProvisioningState ------------ -------------- -------------------- ----------------- 0 <NODE-000> True Succeeded 1 <NODE-001> False Succeeded This is the desired canary state: Instance 0 has applied the latest model. Instance 1 remains on the previous model. The VMSS continues to exist. The rollout can pause for detailed validation. Do not rely only on ProvisioningState=Succeeded. Confirm both the model status and the in-guest OS image. Step 10: Verify the image from inside the upgraded node After the VM becomes accessible, query its metadata again: curl -s -H Metadata:true --noproxy "" "http://169.254.169.254/metadata/instance/compute?api-version=2021-10-01" | jq '{publisher, offer, sku, version, osType}' Output { "publisher": "microsoft-dsvm", "offer": "ubuntu-hpc", "sku": "2404", "version": "24.04.2026092501", "osType": "Linux" } This confirms that the image changed from: microsoft-dsvm:ubuntu-hpc:2404:24.04.2026052601 to: microsoft-dsvm:ubuntu-hpc:2404:24.04.2026092501 Step 11: Verify the operating-system release Run: # cat /etc/os-release PRETTY_NAME="Ubuntu 24.04.5 LTS" NAME="Ubuntu" VERSION_ID="24.04" VERSION="24.04.5 LTS (Noble Numbat)" VERSION_CODENAME=noble ID=ubuntu ID_LIKE=debian HOME_URL="https://www.ubuntu.com/" SUPPORT_URL="https://help.ubuntu.com/" BUG_REPORT_URL="https://bugs.launchpad.net/ubuntu/" PRIVACY_POLICY_URL="https://www.ubuntu.com/legal/terms-and-policies/privacy-policy" UBUNTU_CODENAME=noble LOGO=ubuntu-logo Verify the running kernel: # uname -r 6.8.0-1067-azure The result should match the kernel expected for the approved target image and its driver stack. The actual kernel output should be recorded internally rather than copied into a public article if it contains environment-specific information. Step 12: Validate operating-system health # Check for failed services: systemctl --failed --no-pager # Check the overall system state: systemctl is-system-running # Review boot errors: journalctl -b -p err --no-pager # If cloud-init is used: cloud-init status --long Validation criteria should include: The node booted successfully. No unexpected failed services remain. Cloud-init or equivalent bootstrap completed. CycleCloud initialization completed. Required filesystems and application paths are available. DNS resolution works. Time synchronization is healthy. Identity and authentication components work. Monitoring and security agents are operational. No unexpected kernel or device initialization errors are present. Step 13: Validate CycleCloud and Slurm integration Confirm that Slurm can see the node: scontrol show node "$SLURM_NODE" Review the node’s: State Features Partitions CPU count Memory Generic resources Reason field Registration status The OS image upgrade may change bootstrap timing or host configuration. Confirm that CycleCloud applied the expected node configuration and that Slurm did not register the node with unexpected hardware or resource values. Step 14: Validate HPC and accelerator dependencies An OS image update can change the kernel, device drivers, user-space libraries, and bootstrap behavior. Validate every host-level dependency used by the partition. GPU validation For GPU nodes: nvidia-smi Confirm: All expected GPUs are visible. The driver initializes successfully. No unexpected device or driver errors are reported. The driver is compatible with the application and container stack. InfiniBand and RDMA validation For InfiniBand or RDMA nodes: ibv_devices ibstat Confirm: Expected devices are present. Ports are active. Link state is correct. The expected transport stack is available. Container validation For containerized environments, validate: Container runtime startup GPU device exposure RDMA device exposure Host-library injection Required mounts User namespace behavior Scheduler integration Application-specific plugins A container does not remove dependency on the host kernel, GPU driver, network device stack, or scheduler configuration. Workload validation Run representative tests such as: A single-node CPU job A GPU visibility and compute test An RDMA connectivity test An MPI or UCX smoke test A container launch test A small version of a production workload Do not treat a successful VM boot as sufficient proof that the node is production-ready. Step 15: Resume the validated node After all checks pass: scontrol update NodeName="$SLURM_NODE" State=RESUME Verify the state: sinfo -N -n "$SLURM_NODE" Confirm that: Slurm returns the node to the expected state. No unexpected drain reason remains. A small test job runs successfully. The node behaves as expected under scheduling. Step 16: Upgrade the next instance After the canary node has passed validation, select the next idle instance: INSTANCE_ID="1" SLURM_NODE="<NODE-001>" Drain it: scontrol update NodeName="$SLURM_NODE" State=DRAIN Reason="VMSS OS image upgrade" Confirm there are no jobs: sinfo -N -n "$SLURM_NODE" squeue -w "$SLURM_NODE" Apply the already-updated VMSS model: az vmss update-instances --resource-group "$RESOURCE_GROUP" --name "$VMSS_NAME" --instance-ids "$INSTANCE_ID" After the operation completes, repeat all control-plane, operating-system, scheduler, driver, network, container, and workload validation. When both example instances have been upgraded, the expected state is: InstanceId ComputerName LatestModelApplied ProvisioningState ------------ -------------- -------------------- ----------------- 0 <NODE-000> True Succeeded 1 <NODE-001> True Succeeded Repeat the drain, update, validate, and resume cycle until every intended instance reports LatestModelApplied=True and passes workload validation. Update-instances versus reimage These operations address different layers of the upgrade. Operation What it changes Key point az vmss update VMSS model Existing instances remain unchanged in Manual mode. az vmss update-instances Selected VMSS instances Applies the latest VMSS model to the selected instances. az vmss reimage Selected instance OS disks Rebuilds the OS disk but should not be treated as a substitute for applying the latest model in this workflow. CycleCloud or Slurm reimage action Requests node reimage through the cluster workflow Does not itself change an old VMSS image reference to a new one. Scale down and scale up after changing CycleCloud Recreates infrastructure from the CycleCloud definition Provides a clean deployment but may require partition-wide downtime and capacity reacquisition. The most important rule is: A reimage can reproduce the old OS if the infrastructure model still references the old image. The validated sequence is therefore: Update VMSS model verify model confirm LatestModelApplied=False run update-instances confirm LatestModelApplied=True verify the image from inside the node Prevent configuration drift in CycleCloud Directly modifying the existing VMSS is not the final configuration-management step. CycleCloud remains the owner of the cluster definition. If CycleCloud later removes and recreates the VMSS, the replacement scale set will use the image configured in the CycleCloud node array. If the CycleCloud definition still points to the previous image, newly created nodes may return to that version even though the current VMSS was upgraded manually. After the canary and rollout succeed: Update the OS image in the corresponding CycleCloud node-array configuration. Use the same publisher, offer, SKU, and version validated in the VMSS. Review or export the cluster configuration to confirm the new value is persistent. Test a controlled scale-out or node replacement if the maintenance plan permits. Record the CycleCloud configuration change with the VMSS change. The desired end state is: CycleCloud node-array image = VMSS model image = Image reported by every upgraded VMSS instance Updating only the current VMSS should not be treated as a permanent CycleCloud configuration change. Rollback strategy A rollback plan should be prepared before the first node is changed. If the canary fails validation: Keep the node drained. Stop the rollout to all remaining nodes. Capture boot, extension, driver, scheduler, and application logs. Change the VMSS model back to the previous image. Apply the previous model to the affected instance. Revalidate the restored node. Resume it only after the previous service level has been restored. Example rollback: az vmss update --resource-group "$RESOURCE_GROUP" --name "$VMSS_NAME" --set virtualMachineProfile.storageProfile.imageReference.version="$PREVIOUS_IMAGE_VERSION" Apply the restored model: az vmss update-instances --resource-group "$RESOURCE_GROUP" --name "$VMSS_NAME" --instance-ids "$INSTANCE_ID" Verify the model: az vmss show --resource-group "$RESOURCE_GROUP" --name "$VMSS_NAME" --query "virtualMachineProfile.storageProfile.imageReference" --output json Verify the instance status: az vmss list-instances --resource-group "$RESOURCE_GROUP" --name "$VMSS_NAME" --expand instanceView --query [].{InstanceId:instanceId,LatestModelApplied:latestModelApplied,ProvisioningState:provisioningState}" --output table Because a VMSS has one current model, coordinate rollback carefully if some nodes are already on the new image. Restore the intended VMSS model after the affected node has been recovered, and do not continue the rollout until the incompatibility is understood. Conclusion Updating the OS image of CycleCloud Slurm nodes without recreating the entire VMSS is possible when the scale set uses Manual upgrade mode. However, it requires a deliberate separation between: The CycleCloud cluster definition The VMSS model The model applied to each VMSS instance The core workflow is: Drain one node Update the VMSS image reference Verify the new VMSS model Confirm LatestModelApplied=False Apply the latest model to one instance Confirm LatestModelApplied=True Verify the image inside the VM Validate the complete HPC workload path Resume the node Repeat for the remaining nodes Align the CycleCloud configuration This approach provides a controlled canary rollout, limits disruption to selected nodes, avoids deliberate recreation of the full scale set, and makes validation and rollback easier to manage. Its success depends on disciplined scheduler operations, complete host-level validation, careful treatment of distributed workloads, and final synchronization of the CycleCloud cluster configuration.
Choosing the Right Azure Virtual Machine for Ansys CFX
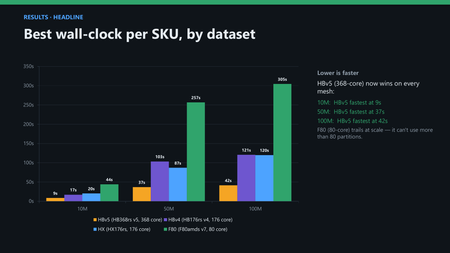
If you are moving Ansys CFX turbomachinery simulation software to the cloud, the first question is not whether Azure can run your computational fluid dynamics (CFD) workloads, but it is which Virtual Machine (VM) delivers the best balance of performance and cost. Azure offers multiple AMD EPYC-based HPC VMs, each optimized differently for compute, memory bandwidth, and price. As a result, the largest VM or the lowest hourly-cost option is not necessarily the most economical choice once the cost of completing a simulation is considered. Ultimately, two metrics matter most: the time to complete a simulation and the cost to run the simulation. To evaluate both, we benchmarked a CFX airfoil case at 10M, 50M, and 100M mesh nodes across Azure HBv5, HBv4, HX, and Fams_v7 VMs. We then validated the optimal HBv5 tuning approach using the TUDA transonic compressor benchmark from TU Darmstadt, a widely recognized open benchmark for turbomachinery CFD. This allowed us to assess whether the observed performance benefits extend beyond a single airfoil test case to a fundamentally different CFD workload. Key findings include: The latest generation HBv5 VM is 2-3x faster than a 176-core node on real meshes, and on any 50M mesh nodes and up it is highly cost effective. On small meshes the economics flip: a 176-core HBv4 delivers the lowest cost per solve. Despite its low hourly cost, Fams_v7 is the most expensive per simulation on large meshes. The TUDA compressor study confirms that the performance benefits seen in the airfoil benchmarks also apply to larger turbomachinery workloads, while smaller models require more careful MPI rank tuning to achieve optimal results. The practical answer to "which VM should I choose?" depends on mesh size and how you run. This guide gives you the crossover points to make that decision with confidence. Benchmark overview The benchmark used an external-aerodynamics airfoil model at 10M, 50M, and 100M mesh nodes. All simulations were performed in single precision using the CPU-based CFX solver. The study evaluated 168 VM, mesh, and rank-count configurations across four Azure VM families and included 254 solver runs, retaining the best result for each configuration. Performance was measured using CFD Solver wall-clock time rather than total workflow runtime. This distinction matters because preprocessing, partitioning, storage, and workflow orchestration overheads vary by environment. Solver wall-clock time isolates the computational workload and provides the clearest view of how each VM family executes and scales CFX. There is also a practical CFX-specific reason to focus on the solver timer. CFX output can report timing for both partitioning and solving, and partitioning is often less sensitive to core count. If users measure the partitioner, scaling may appear artificially flat. The 50M and 100M cases required large partitioning due to 64-bit indexing, while the 10M case used 32-bit indexing. VM Azure family CPU Cores Notes HBv5 HBv5-series EPYC 9V64H Zen 4 cores with HBM 368 High-bandwidth memory for bandwidth-bound HPC HBv4 HBv4-series EPYC 9V33X “Genoa-X” with 3D V-Cache 176 DDR5 with large L3 cache HX HX-series EPYC 9V33X, same as HBv4 176 Larger memory footprint for big models Fams_v7 Fasv7-series, F80ams_v7 EPYC 9005-series "Turin” 80 Compute-optimized general VM Table 1. AMD EPYC-based Azure VM families evaluated in the CFX benchmark. Note: HBv4 and HX share the identical 9V33X CPU, so on compute they are near interchangeable. The primary difference is memory capacity, not speed. Performance comparison The performance story is best seen in the chart below. HBv5 delivered the shortest solver runtime across all three mesh sizes, and its advantage widened as the workload grew. On the 100M-cell model, HBv5 completed the solve in roughly one-third of the time required by HBv4 or HX. Figure 1. Best solver wall-clock time by VM family and mesh size. Lower is faster. Three observations stand out: HBv5 wins every mesh, and its lead widens with size: it is about 2x faster than a 176-core node at 10M, and about 2.9x faster at 100M. HBv4 and HX produced similar solver performance, consistent with their shared AMD EPYC 9V33X processor generation. Fams_v7 showed strong low-rank performance, but it caps at 80 cores and ends up about 7x slower than HBv5 on the 100M mesh. Why cost-per-simulation matters Raw speed and sticker price both mislead in the cloud, because you rent the whole VM by the hour regardless of how many cores a job uses. The metric that governs your bill is cost per completed simulation. Cost per run = solver wall-clock seconds / 3600 x VM hourly rate (Linux, South Central US.) This ties speed and price together, and it is the metric a cloud-adoption business case should be built on. VM $/hr PAYG $/hr 3-yr reserved HBv5 23.76 11.88 HX 10.37 5.18 HBv4 8.64 4.32 Fams_v7 8.47 3.30 Table 2. Azure retail list prices used in the benchmark calculations: Linux, South Central US. VM Airfoil 10M Airfoil 50M Airfoil 100M HBv5 $0.057 $0.242 $0.274 HBv4 $0.041 $0.248 $0.289 HX $0.058 $0.251 $0.345 Fams_v7 $0.104 $0.604 $0.717 Table 3. Cost per solve using PAYG pricing and best solver wall-clock time. Figure 2. Cost to solve the 100M-cell benchmark once. The cost analysis reveals an important shift as model sizes increase. For the smallest 10M mesh case, HBv4 delivers the lowest cost per simulation, despite HBv5 achieving the fastest runtime. However, as workloads grow to 50M and 100M mesh nodes, HBv5 emerges as both the fastest and most cost-effective platform, with its performance advantage more than offsetting the higher hourly VM rate. In contrast, Fams_v7 illustrates the danger of evaluating cloud resources based solely on hourly pricing. While it offers one of the lowest hourly costs, its longer runtimes make it the most expensive option on a per-simulation basis for larger CFD workloads. For organizations running CFX regularly, Reserved Instances can further improve the economics, reducing infrastructure costs by roughly 50% while preserving the same performance characteristics. How CFX scales on Azure HBv5 HBv5 keeps winning as meshes grow because it provides scaling headroom. On the 100M mesh, HBv5 goes from 550 seconds at 16 ranks to 42 seconds at 368 ranks, a 13.2x speed-up, and still gains from higher rank counts at the top of its range. Figure 3. HBv5 scaling for the 100M-cell CFX airfoil benchmark. Fams_v7 can be attractive at very low rank counts, but its scaling is constrained by its 80-core configuration. HBv4 and HX scale to 176 cores before approaching a plateau. HBv5 continues extracting value up to 368 ranks, which is why its advantage grows as models become larger. Transonic compressor validation on HBv5 The TUDA transonic compressor benchmark is selected because it tests the same HBv5 tuning approach on a different physics, i.e., a turbomachinery workload, not just the original airfoil case. The result is consistent: spreading ranks one-per-CCD-first across the 48 CCDs, combined with MPI pinning, helps heavier cases to continue scaling as more of the node is used. Figure 4. TUDA transonic compressor scaling on HBv5 with CCD-spread + MPI pinning. Lower solver wall-clock time is better. This case is a 43M mesh node model and improves from 218 seconds at 48 ranks to 57 seconds at 368 ranks, a 3.8x speed-up, showing that large turbomachinery models have more parallel work available per rank and can keep scaling further up the CCD ladder. Figure 5. Radial Compressor 20M scaling on HBv5 using CCD-spread MPI rank placement. The Radial Compressor 20M benchmark shows the other side of the sizing rule. Solver wall-clock time decreases from 1,173 seconds at 48 ranks to 331 seconds at 368 ranks, a 3.5× reduction in turnaround time, but most of the benefit is captured before the full-node configuration. Above roughly 150–250 ranks the scaling efficiency tapers, because the case is smaller per rank and communication/startup overheads become more visible. This makes the radial-compressor case a useful example: HBv5 still delivers the fastest turnaround, but smaller turbomachinery models should not automatically use every core if cost-per-solve is the goal. Choosing the right Azure VM for your CFX workload The practical rule is to match the VM to the workload rather than to the price tag. For production meshes of roughly 50M mesh nodes and above, HBv5 is the preferred starting point because it offers the strongest combination of turnaround time and cost per completed simulation. For smaller or high-volume short runs around 10M mesh nodes, HBv4 can provide a better cost-per-solve profile. HX should be selected over HBv4 when the additional memory footprint is required, not because compute performance is expected to differ materially. Fams_v7 can be useful for development, sanity checks, or occasional small runs, but it should not be the default production-throughput VM for larger CFX workloads. Users should also validate MPI choice, use large partitioning when required, measure solver time rather than partitioning time, and avoid over-provisioning ranks on small meshes Rule of thumb: The bigger the mesh, the more HBv5 wins on both speed and cost. The smaller the mesh, the more a 176-core HBv4 wins on cost. The crossover in this data sits below the 50M mesh. Practical tuning notes for CFX on Azure VMs Validate MPI choice. MPI performance varied across the Azure VM families tested, with HBv5, HBv4, and Fams_v7 favoring one configuration and HX another. Validate MPI options for your workload and VM configuration. Partition big meshes with -part-large. The 50M and 100M meshes need 64-bit integer indexing, while the 10M mesh runs 32-bit. Measure the solver wall-clock, not the partitioner. CFX output can report total wall-clock time twice: first for partitioning, then for the solver. If scaling looks flat as ranks increase, you may be timing the partitioner. Do not over-provision ranks on small meshes. Tiny cases can hit communication overhead before they use every core. Key takeaways for Azure cloud adoption HBv5 is the preferred platform for production-scale CFX workloads, delivering both the fastest runtimes and the lowest cost per solve on larger meshes. HBv4 remains attractive for smaller workloads where minimizing cost per simulation is more important than minimizing runtime. Cloud sizing decisions should be based on cost per simulation rather than hourly VM pricing. Taken together, Azure gives CFX users a practical cloud-sizing framework: select the VM based on mesh size, solver scalability, and cost per completed simulation. Learn More: Learn more about Ansys CFX capabilities Request a Microsoft Azure Free TrialBuild a Simple GPU-Enabled Kubernetes Cluster on Azure N-Series VMs
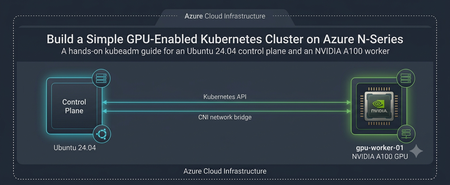
Audience: Platform engineers, ML engineers, and developers who need a small, understandable GPU development cluster without the abstraction of a managed Kubernetes service. Reference topology: Role Azure VM size Operating system Purpose Control plane Standard_D8s_v6 Ubuntu 24.04 LTS API server, scheduler, controllers, etcd GPU worker Standard_NC24ads_A100_v4 Ubuntu 24.04 LTS CUDA-enabled development workloads Software baseline: Kubernetes v1.33, containerd, Flannel CNI, NVIDIA Container Toolkit, and NVIDIA Kubernetes device plugin v0.17.0. Why Build This Cluster? A two-node kubeadm cluster is useful when you want direct access to Kubernetes internals while developing or debugging GPU applications. It keeps the control plane on a general-purpose VM and reserves the expensive N-series capacity for workloads that explicitly request a GPU. Development Use Case: Shared GPU Sandbox Imagine a small ML team validating a PyTorch service before moving it to a production platform. Developers build containers locally or in CI, deploy them to this cluster, request nvidia.com/gpu: 1, inspect CUDA behavior, tune resource requests, and test Kubernetes manifests. The same environment can exercise Jobs, model-serving Deployments, ConfigMaps, Secrets, storage mounts, and observability agents. This design is appropriate for experimentation, integration testing, workshops, and short-lived development. It is not a production blueprint: the control plane is not highly available, etcd has no redundancy, Flannel is intentionally simple, and operational safeguards are minimal. Architecture and Traffic Flow Control plane: runs the Kubernetes API server, scheduler, controller manager, and etcd. GPU worker: runs containerd, kubelet, the NVIDIA container runtime, and GPU workloads. Pod network: Flannel allocates pod addresses from 10.244.0.0/16. GPU discovery: the NVIDIA device plugin advertises nvidia.com/gpu to Kubernetes. Before You Begin Create both VMs in the same Azure virtual network and subnet. Use private IP connectivity between nodes. Confirm that the selected region has quota and capacity for Standard_NC24ads_A100_v4. GPU VM availability and quota are subscription- and region-dependent. Use trusted administrative source ranges for SSH. Ensure the nodes can communicate on the Kubernetes control-plane, kubelet, and Flannel ports required by your network policy. Avoid exposing the Kubernetes API server broadly to the internet. Disk requirement: Use 128GB disk as OS disk in Standard_NC24ads_A100_v4 as 32GB will be the default and it may not be sufficient to run the test job mentioned below. 1. Prepare Both Nodes Run the following commands on both the control-plane VM and the GPU worker. Use a non-root account with sudo access. Set Host Names and Name Resolution Assign a unique host name on each VM: Control plane sudo hostnamectl set-hostname controlplane GPU worker sudo hostnamectl set-hostname gpunode Add both private IP addresses to /etc/hosts on each node, replacing the placeholders: <CONTROL_PLANE_PRIVATE_IP> controlplane <GPU_WORKER_PRIVATE_IP> gpunode Disable Swap Kubelet expects swap to be disabled unless it is explicitly configured to tolerate it. sudo swapoff -a sudo sed -i '/ swap / s/^/#/' /etc/fstab swapon --show The final command should return no active swap devices. Load Required Kernel Modules cat <<EOF | sudo tee /etc/modules-load.d/k8s.conf overlay br_netfilter EOF sudo modprobe overlay sudo modprobe br_netfilter Configure Kubernetes Networking Parameters cat <<EOF | sudo tee /etc/sysctl.d/k8s.conf net.bridge.bridge-nf-call-iptables = 1 net.bridge.bridge-nf-call-ip6tables = 1 net.ipv4.ip_forward = 1 EOF sudo sysctl --system Install and Configure containerd sudo apt-get update sudo apt-get install -y containerd sudo mkdir -p /etc/containerd sudo containerd config default | sudo tee /etc/containerd/config.toml > /dev/null sudo sed -i 's/SystemdCgroup = false/SystemdCgroup = true/g' /etc/containerd/config.toml sudo systemctl restart containerd sudo systemctl enable containerd sudo systemctl status containerd --no-pager The SystemdCgroup = true setting aligns containerd with kubelet and systemd cgroup management. Install Kubernetes v1.33 Packages The repository minor version and the packages installed on every node must match. The commands below configure the v1.33 repository used by this guide. sudo apt-get update sudo apt-get install -y apt-transport-https ca-certificates curl gpg conntrack socat sudo mkdir -p /etc/apt/keyrings curl -fsSL https://pkgs.k8s.io/core:/stable:/v1.33/deb/Release.key | sudo gpg --dearmor -o /etc/apt/keyrings/kubernetes-apt-keyring.gpg echo 'deb [signed-by=/etc/apt/keyrings/kubernetes-apt-keyring.gpg] https://pkgs.k8s.io/core:/stable:/v1.33/deb/ /' | sudo tee /etc/apt/sources.list.d/kubernetes.list sudo apt-get update sudo apt-get install -y kubelet kubeadm kubectl sudo apt-mark hold kubelet kubeadm kubectl kubeadm version kubectl version --client If you choose another supported Kubernetes minor release, replace v1.33 consistently on every node and follow that release’s upgrade and version-skew guidance. 2. Initialize the Control Plane Run this section only on controlplane. Initialize Kubernetes Update the CIDR value as per your requirement sudo kubeadm init --pod-network-cidr=10.xxx.0.0/16 Save the kubeadm join command printed at the end. It contains a time-limited bootstrap token and the control-plane CA hash. Configure kubectl for the Administrator mkdir -p "$HOME/.kube" sudo cp -i /etc/kubernetes/admin.conf "$HOME/.kube/config" sudo chown "$(id -u):$(id -g)" "$HOME/.kube/config" kubectl get nodes The control-plane node may remain NotReady until the CNI is installed. Install Flannel kubectl apply -f https://github.com/flannel-io/flannel/releases/latest/download/kube-flannel.yml kubectl get pods -n kube-flannel -w Because Flannel’s default manifest uses 10.244.0.0/16, it matches the pod CIDR supplied to kubeadm. Generate a New Join Command if Needed kubeadm token create --print-join-command Treat the join command as a secret while it is valid. Run it only on the intended worker. 3. Configure the GPU Worker Complete the shared preparation steps first, then perform the following work on gpunode. Validate the NVIDIA Driver The Azure GPU VM must have a compatible NVIDIA driver. Confirm that the host can see the accelerator: nvidia-smi Do not continue until this command reports the GPU and driver successfully. Driver installation varies by Azure image and extension strategy, so standardize it before automating the node build. Install NVIDIA Container Toolkit curl -fsSL https://nvidia.github.io/libnvidia-container/gpgkey | sudo gpg --dearmor -o /etc/apt/keyrings/nvidia-container-toolkit-keyring.gpg curl -s -L https://nvidia.github.io/libnvidia-container/stable/deb/nvidia-container-toolkit.list | sed 's#deb https://#deb [signed-by=/etc/apt/keyrings/nvidia-container-toolkit-keyring.gpg] https://#g' | sudo tee /etc/apt/sources.list.d/nvidia-container-toolkit.list sudo apt-get update sudo apt-get install -y nvidia-container-toolkit sudo nvidia-ctk runtime configure --runtime=containerd --nvidia-set-as-default sudo systemctl restart containerd sudo systemctl status containerd --no-pager Join the Worker to the Cluster Run the exact command generated by the control plane. It will resemble: sudo kubeadm join <CONTROL_PLANE_PRIVATE_IP>:6443 --token <TOKEN> --discovery-token-ca-cert-hash sha256:<HASH> Back on the control plane, watch the node registration: kubectl get nodes -o wide -w azureuser@controlplane:~$ kubectl get nodes NAME STATUS ROLES AGE VERSION controlplane Ready control-plane 84s v1.33.13 azureuser@controlplane:~$ kubectl get nodes NAME STATUS ROLES AGE VERSION controlplane Ready control-plane 111s v1.33.13 gpunode NotReady <none> 8s v1.33.13 azureuser@controlplane:~$ kubectl get nodes NAME STATUS ROLES AGE VERSION controlplane Ready control-plane 112s v1.33.13 gpunode Ready <none> 9s v1.33.13 4. Advertise the GPU to Kubernetes Run these commands on the control plane. Install the NVIDIA Device Plugin Pinning the manifest version makes the cluster reproducible. curl -fsSL -o nvidia-device-plugin.yml https://raw.githubusercontent.com/NVIDIA/k8s-device-plugin/v0.17.0/deployments/static/nvidia-device-plugin.yml kubectl apply -f nvidia-device-plugin.yml kubectl get daemonset -n kube-system nvidia-device-plugin-daemonset kubectl get pods -n kube-system -l name=nvidia-device-plugin-ds -o wide Verify GPU Capacity kubectl describe node gpunode | grep -A 10 -E 'Capacity:|Allocatable:' kubectl get node gpunode -o jsonpath='{.status.allocatable.nvidia\.com/gpu}{"\n"}' The expected allocatable value depends on the VM’s visible GPU count and partitioning configuration. Kubernetes schedules GPUs as integer extended resources. azureuser@controlplane:~$ kubectl describe node gpunode | grep -A 10 -E 'Capacity:|Allocatable:' Capacity: cpu: 24 ephemeral-storage: 128917488Ki hugepages-1Gi: 0 hugepages-2Mi: 0 memory: 226765912Ki nvidia.com/gpu: 1 pods: 110 Allocatable: cpu: 24 ephemeral-storage: 118810356745 hugepages-1Gi: 0 hugepages-2Mi: 0 memory: 226663512Ki nvidia.com/gpu: 1 pods: 110 System Info: Machine ID: ac82b1424d30473a86a3f22bb2c4ffa1 System UUID: 67d695c2-b663-4514-9952-9e6e29671e4e azureuser@controlplane:~$ kubectl get node gpunode -o jsonpath='{.status.allocatable.nvidia\.com/gpu}{"\n"}' 1 5. Run an End-to-End PyTorch GPU Test Create gpu-test-job.yaml on the control plane with the following content: apiVersion: batch/v1 kind: Job metadata: name: pytorch-gpu-test namespace: default spec: backoffLimit: 2 template: spec: restartPolicy: Never containers: - name: pytorch-trainer image: pytorch/pytorch:2.1.0-cuda12.1-cudnn8-runtime command: ["python3", "-c"] args: - | import time import torch import torch.nn as nn import torch.optim as optim print("=== CUDA validation ===") if not torch.cuda.is_available(): raise SystemExit("CUDA was not detected by PyTorch") device = torch.device("cuda:0") print(f"Device: {torch.cuda.get_device_name(0)}") print(f"Capability: {torch.cuda.get_device_capability(0)}") model = nn.Sequential( nn.Linear(1000, 2048), nn.ReLU(), nn.Linear(2048, 1000) ).to(device) optimizer = optim.SGD(model.parameters(), lr=0.01) criterion = nn.MSELoss() inputs = torch.randn(128, 1000, device=device) targets = torch.randn(128, 1000, device=device) started = time.time() for epoch in range(1, 101): optimizer.zero_grad() loss = criterion(model(inputs), targets) loss.backward() optimizer.step() if epoch % 20 == 0: vram = torch.cuda.memory_allocated(0) / 1e6 print(f"Epoch {epoch}/100 | Loss {loss.item():.4f} | VRAM {vram:.2f} MB") print(f"Completed in {time.time() - started:.4f}s") resources: limits: nvidia.com/gpu: "1" requests: nvidia.com/gpu: "1" Submit and observe the Job: kubectl apply -f gpu-test-job.yaml kubectl get pods -l job-name=pytorch-gpu-test -o wide kubectl logs -l job-name=pytorch-gpu-test --follow kubectl get job pytorch-gpu-test A successful run prints the NVIDIA device name, CUDA capability, training progress, and completion time. azureuser@controlplane:~$ kubectl get pods -l job-name=pytorch-gpu-test -o wide NAME READY STATUS RESTARTS AGE IP NODE NOMINATED NODE READINESS GATES pytorch-gpu-test-j5wh8 1/1 Running 0 109s XXXX gpunode <none> <none> azureuser@controlplane:~$ kubectl logs -l job-name=pytorch-gpu-test --follow === CUDA validation === Device: NVIDIA A100 80GB PCIe Capability: (8, 0) Epoch 20/100 | Loss 1.0461 | VRAM 51.37 MB Epoch 40/100 | Loss 1.0415 | VRAM 51.37 MB Epoch 60/100 | Loss 1.0371 | VRAM 51.37 MB Epoch 80/100 | Loss 1.0328 | VRAM 51.37 MB Epoch 100/100 | Loss 1.0287 | VRAM 51.37 MB Completed in 0.1250s Conclusion This compact cluster provides a transparent path from an Azure GPU VM to a Kubernetes-scheduled CUDA workload. It is small enough to understand, reset, and rebuild, yet realistic enough to validate container images, resource requests, device discovery, Jobs, and model-serving patterns before adopting a production-grade architecture.Running OpenFOAM simulations on Azure Batch
OpenFOAM (Open Field Operation and Manipulation) is an open-source computational fluid dynamics (CFD) software package. It provides a comprehensive set of tools for simulating and analyzing complex fluid flow and heat transfer phenomena. It is widely used in academia and industry for a range of applications, such as aerodynamics, hydrodynamics, chemical engineering, environmental simulations, and more. Azure offers services like Azure Batch and Azure CycleCloud that can help individuals or organizations run OpenFOAM simulations effectively and efficiently. In both scenarios, these services allow users to create and manage clusters of VMs, enabling parallel processing and scaling of OpenFOAM simulations. While CycleCloud provides a similar experience to on-premises thanks to its support to common schedulers like OpenPBS or SLURM; Azure Batch provides a cloud native resource scheduler that simplifies the configuration, maintenance and support of your required infrastructure. This article covers a step-by-step guide on a minimal Azure Batch setup to run OpenFOAM simulations. Further analysis should be performed to identify the right sizing both in terms of compute and storage. A previous article on How to identify the recommended VM for your HPC workloads could be helpful.