powershell
2279 Topics
Start-SPOSiteReview issue in PowerShell: RecipientRole unknown parameter
Has anyone else tried using the PowerShell command Start-SPOSiteReview? Per Microsoft Learn documentation, using the -RecipientRole parameter sends a request to Site Owners, Site collection administrators or both. https://learn.microsoft.com/en-us/powershell/module/microsoft.online.sharepoint.powershell/start-spositereview?view=sharepoint-ps However, three of us have tried the script and we have all tried it in both PS 7 and PS 5.1, but we are all getting the same error: Start-SPOSiteReview : A parameter cannot be found that matches parameter name 'RecipientRole'. However, both the Microsoft Learn documentation and our Microsoft support technician is telling us that RecipientRole is a known parameter that we should be able to use. Has anyone else run into this and know the issue / solution?42Views0likes1Comment
Updated OnedriveMapper (to map Onedrive/Sharepoint to driveletters or network locations)
If you're using the free OnedriveMapper Powershell script, a new version was just released :) http://www.lieben.nu/liebensraum/2018/03/onedrivemapper-v3-14-released/ It uses WebDAV, so it won't even approach the stability of the actual Onedrive Client, but where you can't use the Onedrive client itself, this script can help out :)3.8KViews3likes1CommentConverting Scripts from Search-UnifiedAuditLog
Investigating the work necessary to convert PowerShell scripts based on the Search-UnifiedAuditLog cmdlet to use the AuditLogQuery Graph API shows that it’s not easy. Running audit jobs is a multi-stage process rather than running a simple cmdlet. Parameter values are now passed in a request body or different named parameters, and the properties output in the AuditData payload use a different format. This is definitely not a drop-in exercise, so it’s time to get ready by finding scripts that need to be converted. https://office365itpros.com/2026/10/27/auditlogquery-conversion/65Views0likes0CommentsWhy the Microsoft Graph PowerShell SDK has Two Cmdlets to Add Group Members
It’s a consequence of how the Microsoft Graph PowerShell SDK is built that two cmdlets are available to add members to Entra ID groups (the same is true for group owners). The reason why the New-MgGroupMember and New-MgGroupMemberByRef cmdlets exist is down to how the Graph SDK build process constructs cmdlets from Graph metadata. The Graph exposes two ways to add new group members, so the SDK follows suit. https://office365itpros.com/2026/10/20/group-member-sdk-cmdlets/57Views0likes0CommentsWhat Really Happens When You Scale Azure SQL Database? How to Monitor Long-Running Scale Operations
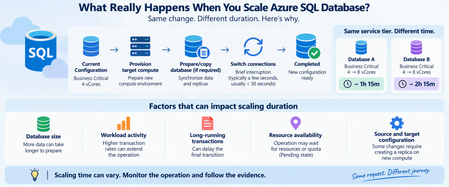
One of the advantages of Azure SQL Database is the ability to scale compute resources without managing the underlying infrastructure. Changing from 4 vCores to 8 vCores can be only a few clicks or a single command. But there is a question I frequently see when troubleshooting scaling operations: "Why is my Azure SQL Database scaling operation taking so long?" An even more interesting question appears when two databases undergo what looks like the same change: Database A Business Critical → Business Critical Scaling duration: ~1 hour 15 minutes Database B Business Critical → Business Critical Scaling duration: ~2 hours 15 minutes Same service tier. Similar scaling request. Very different completion time. At first glance, that might look unusual. However, a scale operation isn't simply Azure changing a configuration value from one number of vCores to another. Depending on the source and target configuration, Azure SQL Database can need to provision target compute, prepare or copy database data, transition connections to the target compute, and clean up the original environment. Microsoft specifically notes that creating a database replica on the new compute instance for some scaling combinations can strongly influence the overall latency. Let's look at what happens and, more importantly, how to monitor it. Scaling Is More Than Changing vCores When you submit a scaling request such as: Business Critical 4 vCores ↓ Business Critical 8 vCores it's tempting to imagine something like: CPU allocation: 4 → 8 Done. That isn't necessarily what happens. At a high level, Microsoft documents a scaling workflow involving two important stages: Create a new compute instance with the requested service tier and compute size Switch routing from the original compute instance to the new one For some combinations of service-tier and compute-size changes, Azure SQL Database must also create a replica on the new compute instance, involving data copying. A simplified view is: Scaling request ↓ Prepare target compute ↓ Prepare/copy database if required ↓ Bring target environment ready ↓ Switch connections ↓ Scaling complete The important takeaway is: A scale operation can involve moving database execution to a new compute environment, not simply increasing CPU on the existing environment. Why Can Two Similar Databases Take Different Amounts of Time? This is where troubleshooting becomes interesting. Imagine two databases: Database A 4 vCores → 8 vCores Completed in 75 minutes Database B 4 vCores → 8 vCores Completed in 135 minutes The natural question is: "If the source and destination configurations are the same, shouldn't the duration also be the same?" Not necessarily. The requested configuration tells us where the database needs to end up. It does not mean the work required to reach that state is identical. Several factors can affect the operation. 1. Database Size and Data Movement One of the most important factors can be the amount of data that must be prepared on the target compute. Microsoft's scaling documentation explicitly states that for some source/target combinations, a replica must be created on the new compute instance. That involves copying data and can significantly affect the overall scaling latency. Conceptually: Small database Provision ████ Data preparation ██████ Switch █ versus: Large database Provision ████ Data preparation ████████████████████████ Switch █ Database size alone doesn't provide a precise prediction of completion time, but it can influence the amount of work required during applicable scaling paths. 2. Workload Activity Matters A database also doesn't necessarily stop processing application traffic while Azure prepares the target environment. Microsoft states that during target compute creation, the database remains online and connections continue to the original compute instance. That creates an interesting challenge: Target environment preparing + Application still generating workload A highly active transactional database and a relatively idle database can therefore present different operational conditions during scaling. The practical lesson is: Two databases with the same service objective aren't necessarily in the same workload state when scaling begins. When investigating a slow scale operation, look at the activity around the scaling window, including: transaction volume; write activity; long-running transactions; workload peaks; batch operations; maintenance activity. 3. Long-Running Transactions Can Affect Switchover Toward the end of scaling, connections need to transition to the target compute instance. Microsoft documents that existing connections to the original compute are dropped and new connections are established to the target compute. The switch generally results in a short interruption, often only a few seconds and generally less than 30 seconds. However, there's an important exception. Microsoft notes that: If long-running transactions are active when connections are dropped, the switch can take longer because aborted transactions need to recover. Conceptually: Normal transition Target ready ↓ Switch ↓ Reconnect ↓ Done With a long-running transaction: Target ready ↓ Connection transition ↓ Transaction interruption ↓ Recovery work ↓ Reconnect ↓ Done This is one reason application workload should be considered when evaluating scaling duration. 4. Resource Availability Can Matter Another clue comes from Azure SQL's operation-status metadata. The sys.dm_operation_status DMV exposes several states for database operations, including: PENDING IN_PROGRESS COMPLETED FAILED CANCEL_IN_PROGRESS CANCELLED Importantly, Microsoft defines PENDING as an operation waiting for resource or quota availability. That means some of the elapsed time around an operation may occur before active processing progresses as expected. This is why comparing scale operations purely by database size or vCore count can be misleading. How Can I Monitor a Scaling Operation? Rather than repeatedly refreshing the Azure portal, there are several useful methods for inspecting progress. Method 1: Azure PowerShell with Get-AzSqlDatabaseActivity Azure PowerShell provides: Get-AzSqlDatabaseActivity Microsoft documents this cmdlet specifically for retrieving the status of operations against Azure SQL databases. For example: Get-AzSqlDatabaseActivity ` -ResourceGroupName "MyResourceGroup" ` -ServerName "myserver" ` -DatabaseName "mydatabase" This can help identify database operations associated with the selected database. For clearer output: Get-AzSqlDatabaseActivity ` -ResourceGroupName "MyResourceGroup" ` -ServerName "myserver" ` -DatabaseName "mydatabase" | Select-Object ` Operation, OperationId, DatabaseName, State, PercentComplete, StartTime, ErrorCode, ErrorMessage The specific fields returned can vary with module/API behavior, so always interpret them in the context of the operation being monitored. The important point is that you're no longer asking only: "Is scaling still happening?" You can inspect the operation itself. Method 2: Check Current and Requested Service Objectives Another useful PowerShell command is: Get-AzSqlDatabase Microsoft documents this cmdlet for retrieving Azure SQL Database properties. Its output includes service-objective information such as CurrentServiceObjectiveName and RequestedServiceObjectiveName. For example: Get-AzSqlDatabase ` -ResourceGroupName "MyResourceGroup" ` -ServerName "myserver" ` -DatabaseName "mydatabase" | Select-Object ` DatabaseName, Status, Edition, CurrentServiceObjectiveName, RequestedServiceObjectiveName During a change, comparing these fields can help establish the current and requested configuration. Think of it as: CurrentServiceObjectiveName ↓ Where am I now? RequestedServiceObjectiveName ↓ Where am I trying to go? Once the operation completes successfully, the current configuration should reflect the requested target. Method 3: Use sys.dm_operation_status For SQL-side monitoring, sys.dm_operation_status provides information about database operations such as CREATE and ALTER. For example: SELECT major_resource_id, operation, state_desc, percent_complete, start_time, last_modify_time, error_code, error_desc FROM sys.dm_operation_status ORDER BY start_time DESC; Useful columns include: operation state_desc percent_complete start_time last_modify_time error_code error_desc Microsoft defines the operation states as including PENDING, IN_PROGRESS, COMPLETED, and FAILED. Be Careful With PercentComplete This is an important detail. It is tempting to interpret: PercentComplete = 50 as: "Half of the work is finished, so half of the remaining time is left." That isn't necessarily correct. For sys.dm_operation_status, Microsoft documents percent_complete for most operations as: 0 = Operation not started 50 = Operation in progress 100 = Operation complete Restore operations are an important exception, where values between 1 and 99 can indicate more granular progress. So for a normal ALTER/scale operation: 50% should generally be interpreted as: The operation is in progress rather than: Exactly half the work remains. This distinction is very useful when communicating with application teams during long-running operations. A Practical Monitoring Script For PowerShell users, I like combining the configuration and operation views. First check the database: $db = Get-AzSqlDatabase ` -ResourceGroupName "MyResourceGroup" ` -ServerName "myserver" ` -DatabaseName "mydatabase" $db | Select-Object ` DatabaseName, Status, Edition, CurrentServiceObjectiveName, RequestedServiceObjectiveName Then check database operations: Get-AzSqlDatabaseActivity ` -ResourceGroupName "MyResourceGroup" ` -ServerName "myserver" ` -DatabaseName "mydatabase" This gives you two complementary perspectives: DATABASE STATE + OPERATION STATE ↓ Better understanding of scaling progress What About Application Availability During Scaling? One of the biggest concerns is: "Does the database remain available while scaling?" For Azure SQL Database, Microsoft states that the database remains online while the new compute environment is being prepared. Connections continue to the original compute during that stage. The important availability event occurs during the transition. At switchover: Existing connections ↓ Dropped ↓ Routing switches ↓ New connections ↓ Target compute Microsoft says the switch generally causes an interruption of less than 30 seconds and often only a few seconds. Applications should therefore implement appropriate transient-error handling and retry logic. Microsoft explicitly recommends retry logic for applications and components using the database while the service tier is being changed. Don't Immediately Cancel a "Slow" Scaling Operation A scale operation taking longer than expected does not automatically mean: Scaling is stuck. It could still be legitimately working through: Resource availability ↓ Target compute preparation ↓ Data/replica preparation ↓ Synchronization / workload handling ↓ Switchover Before assuming failure, gather evidence. Check: Operation state Current service objective Requested service objective Start time Last modification time Error details Workload activity Long-running transactions Then determine whether the operation is: Pending Actively progressing Completed or: Failed Troubleshooting Two Databases With Different Scaling Durations Suppose you're investigating: Database A Scale duration: 1h15 Database B Scale duration: 2h15 Here is the approach I recommend. 1. Verify that the changes truly match Compare: Source service tier Target service tier Source vCores Target vCores Compute tier Storage configuration Do not assume both operations were identical simply because both ended at, for example, Business Critical 8 vCores. 2. Compare database characteristics Look at: Database size Workload level Write activity Transaction volume Long-running transactions 3. Compare operation timing Retrieve: Start time State Last modification time Completion time sys.dm_operation_status exposes this operation metadata for Azure SQL database operations. 4. Determine whether either operation spent time pending Remember: PENDING can mean the operation is waiting for resource or quota availability. That represents a very different explanation from: "The database took longer to copy." 5. Check workload around the transition Look for: Large transactions Bulk writes ETL operations Maintenance High transaction rates Long-running transactions particularly around the switchover period. Scaling Duration Is Not an SLA Stopwatch This leads to perhaps the most important takeaway. If: Database A took 75 minutes you should not assume: Database B must take approximately 75 minutes. Even apparently similar scale operations can encounter different database and platform conditions. A better operational expectation is: Treat each scaling operation as an asynchronous platform operation whose duration depends on the work required to safely reach the requested configuration. Monitor the operation rather than predicting its completion from a previous database. Recommended Checklist Before scaling a production Azure SQL Database: Before Review workload activity. Identify long-running transactions or batch processes. Confirm the requested service objective. Ensure application retry logic is implemented. Record the UTC start time. Understand dependent application connection behavior. During Monitor: Get-AzSqlDatabaseActivity Get-AzSqlDatabase sys.dm_operation_status and watch: State CurrentServiceObjectiveName RequestedServiceObjectiveName StartTime LastModifyTime Error information After Confirm: Current service objective = requested target Database status = Online Application connectivity = Healthy Workload performance = Expected Also validate that applications successfully reconnected after the transition. Final Thoughts When Azure SQL Database scaling takes longer than expected, it's easy to think: "Something must be wrong." And when two similar databases take very different amounts of time, it's equally tempting to expect the durations to match. But a scale operation can involve substantially more than changing a vCore number. At a high level: Request scaling ↓ Provision target compute ↓ Prepare/copy database when required ↓ Transition connections ↓ Complete Microsoft's documentation confirms that data copying for applicable scale paths can strongly influence latency, that the switchover can take longer in the presence of long-running transactions, and that a pending operation might be waiting for resource or quota availability. So when someone asks: "Why is Azure SQL scaling taking so long?" my recommendation is not to start by guessing how many minutes it should take. Instead ask: "What state is the operation currently in, and what evidence do we have about its progress?" With Get-AzSqlDatabaseActivity, Get-AzSqlDatabase, and sys.dm_operation_status, you can turn an opaque waiting period into a much more structured investigation. References Scale single database resources in Azure SQL Database Scale resources in Azure SQL Database sys.dm_operation_status Get-AzSqlDatabaseActivity Get-AzSqlDatabase301Views0likes0CommentsAutomating Microsoft 365 with PowerShell Update 29
After some major developments in the world of Microsoft 365 PowerShell, we’ve updated the Automating Microsoft 365 with PowerShell eBook to version 29.2. Refreshed EPUB and PDF files are available for current subscribers to download from Gumroad.com. This release will eventually form part of the Microsoft 365 for IT Pros November 2026 update. The nice thing about electronic publishing is that we can put information in our readers’ hands as soon as we’ve had time to analyze changes. https://office365itpros.com/2026/10/16/automating-microsoft-365-29/80Views0likes0CommentsMGDC for SharePoint FAQ: How to List SharePoint Webs or Subsites?
1. Introduction SharePoint uses a known object hierarchy to store your files, including, in order: Site Collection (site, SPSite) Web (site, subsite, SPWeb) List (SPList, Document Library, SPDocumentLibrary) Folder (SPFolder) List Item (documents, files, SPListItem, SPFile) If you are not familiar with all those, you can read more about them at What is in the Permissions dataset? 2.What we have in MGDC for SharePoint The SharePoint Sites dataset in Microsoft Graph Data Connect offers a list of all sites (site collections) in your tenant. The SharePoint Files will give you details about each file (document). However, there are no MGDC datasets that will give you one object per SharePoint Web (subsite) or SharePoint List (library). There is a workaround, though. If you pay attention to the schema for the SharePoint Sites and SharePoint Files datasets in MGDC, you will find that Sites includes a few interesting details about the Root Web (the main web in the site collection) and the total number of webs (subsites) in each site. Also, the Files dataset includes details about the web (subsite) and the list (library) where the file lives. You could group on these columns to expose more information about webs and lists. 3. One Web These days, if you create a modern SharePoint site, you will get one web (called the Root Web) and no obvious mechanism to create subsites or additional webs. For any sites created in the last few years, you likely have no additional webs outside the Root Web. Your SharePoint might have existed for many years and your company could have sites using old templates with multiple subsites. If you’re trying to find out if that’s the case for your tenant, the information is available in MGDC, if you are willing to dig a little deeper. 4. Finding Old Subsites The main task here is to create a custom query to join the Sites and Files datasets. You would then group that in a particular way to enumerate each subsites (Webs). You might also tag the Webs that are a Root Web, so that you can identify subsites that are not at the top of the Site hierarchy. If you pulled the Sites and Files datasets into a SQL Server or a Lakehouse in Microsoft Fabric, this is what that query could look like: SELECT Webs.SiteId, Sites.RootWeb.Title AS SiteTitle, Sites.Url AS SiteUrl, Sites.WebCount, Webs.WebId, CASE WHEN Root.RootWeb.Id IS NOT NULL THEN 1 ELSE 0 END AS IsRootWeb, Webs.FileCount, Webs.TotalSize, Webs.TotalSizeWithVersions FROM ( SELECT SiteId, WebId, COUNT(*) AS FileCount, SUM(SizeInBytes) AS TotalSize, SUM(SizeInBytesWithVersions) AS TotalSizeWithVersions FROM Files GROUP BY SiteId, WebId ) AS Webs LEFT JOIN Sites AS Sites ON Webs.SiteId = Sites.Id LEFT JOIN Sites AS Root ON Webs.SiteId = Root.Id AND Webs.WebId = Root.RootWeb.Id 4. Empty Webs, Web properties This technique will get you a nice list of Webs, but there are a few problems. First, if a specific web has no files, we won’t see that web in the Files dataset and therefore the query will fail to list that particular web. You would still see that Web counted in the WebCount property of the Sites dataset, but there would be no listing of that web in the query proposed above, since it has no files. Another problem is that there is no way to find in MGDC the details properties of the Web, like the Title. You get some of those for the Root Web in the Sites dataset, but not for the other Webs. For that, you would have to query the Web object using another source like the Graph API or PowerShell. 5. Conclusion I hope this article helped you find details about enumerating SharePoint Webs using the Microsoft Graph Data Connect. For recent deployments of SharePoint Online, you should have only one web per site and the Sites dataset (with Root Web details) should give you plenty of details. However, this might come in handy if you want to manage some of the old subsites of a slightly older SharePoint deployment. Finally, if you’re looking for a challenge, I would suggest adapting the SQL code above to enumerate all the document libraries using the Files dataset. It can be done following a similar pattern…Azure Key Vault Control Plane API Update: Required Upgrade for Azure CLI and Azure PowerShell Users
Deadline: February 27, 2027 All Azure Key Vault control plane (management) API versions released before 2026-02-01 will stop working on February 27, 2027. This does NOT affect the data plane (getting/setting secrets, keys, and certificates) — only vault and access-control management operations are impacted. TL;DR — What you need to do Upgrade Azure CLI to 2.90.0 or later (run az upgrade). Upgrade Az PowerShell's Az.KeyVault module to 6.6.1 or later, or upgrade the Az package to 16.3.0 or later. Do this before February 27, 2027 to avoid any interruption to vault management operations. No data plane changes are required — reading/writing secrets, keys, and certificates is unaffected. For details, see Prepare for Key Vault API version 2026-02-01 and later. What is changing Current releases of Azure CLI 2.90.0 or later and Az PowerShell 16.3.0 or later (including Az.KeyVault 6.6.1 or later) already use Key Vault control plane API version 2026-02-01. Upgrade to these versions before February 27, 2027; after that date, earlier control plane API versions will no longer be served. Who is affected You are affected if you use either of the following: Azure CLI scripts or automation that call az keyvault management commands (create, update, network-rule, access-policy, etc.). Az PowerShell scripts that use the Az.KeyVault module's management cmdlets (New-AzKeyVault, Set-AzKeyVault, Update-AzKeyVault, etc.). Minimum versions to upgrade to Tool / SDK Minimum version How to upgrade Azure CLI 2.90.0 or later az upgrade Az PowerShell (Az.KeyVault module) Az.KeyVault 6.6.1 or later; or Az 16.3.0 or later Update-Module Az -Force Impact if you take no action What breaks on and after February 27, 2027 if you have not upgraded Key Vault management operations (create/update/delete vault, change network rules, change access policies or RBAC settings, etc.) issued with a pre-2026-02-01 API version will fail. You’ll get the following error message: “Due to an RBAC security default, Key Vault's Resource Manager API versions older than 2026-02-01 will retire on 2027-04-01.” Your vaults are NOT deleted and existing secrets/keys/certificates remain fully accessible via the data plane — only management (control plane) operations are blocked. There is no way to opt out or request an extension once the retirement takes effect on February 27, 2027. How to check your installed versions Check your Azure CLI version Run the following command: az version Check the azure-cli value. If the installed version is earlier than 2.90.0, upgrade Azure CLI before February 27, 2027 by running az upgrade. Check your Az PowerShell version Run the following commands: Get-InstalledModule Az, Az.KeyVault | Select-Object Name, Version If Az.KeyVault is earlier than 6.6.1, or the installed Az package is earlier than 16.3.0, upgrade before February 27, 2027. To upgrade the complete Az package, run: Update-Module Az -Force Alternatively, to update only the Az.KeyVault module to the latest version, run: Update-Module Az.KeyVault -Force Timeline Date Milestone March 2026 Control plane API version 2026-02-01 generally available across public Azure regions, Azure Government, and Azure operated by 21Vianet. Today → February 27, 2027 Preparation window. Upgrade to Azure CLI 2.90.0 or later, Az.KeyVault 6.6.1 or later, or Az 16.3.0 or later before February 27, 2027. February 27, 2027 All control plane API versions released before 2026-02-01 are retired and stop being served. Questions? For any questions about Azure CLI or Azure PowerShell, please submit feedback through GitHub: Azure CLI GitHub issues Azure PowerShell GitHub issues662Views0likes0Comments