generative orchestration
21 Topics
Agent Credit Limits and Alerts - Copilot Studio
Hi everyone, We're evaluating the use of Agent Credit Limits and alert notifications in the Power Platform Admin Center as a way to control unexpected Copilot Credit consumption. Recently, we had an agent consume 668k Copilot Credits in just 3 days, which raised concerns about how quickly usage can grow before administrators become aware of it. My questions are: How frequently is Copilot Credit consumption evaluated against an agent's credit limit? Are alert notifications generated in near real-time, or are they dependent on the same reporting pipeline used by the consumption reports? If an agent reaches its configured credit limit, is it automatically turned off or blocked from further consumption? Given that consumption reports often appear to refresh hours later (or even the next day), can alerts also be delayed? If there is a reporting delay, is there a risk that an agent could significantly exceed the intended limit before administrators receive a notification? What is the recommended approach for preventing large unexpected consumption spikes in production? Has anyone successfully implemented a governance model that provides more immediate protection against runaway usage, or are the current credit limits and alerts primarily intended for retrospective monitoring? Thanks in advance for any guidance.363Views0likes4Comments
Understand the Copilot Studio app-building harness
The first important distinction is that building an app is different from building a conversational agent. An app provides an interactive user interface. An agent reasons about a request and may use tools to accomplish a task. A workflow executes defined business logic. You can combine all three in a business solution. Component Responsibility Example Copilot Studio Apps User interface and application experience An employee service dashboard GitHub Copilot harness AI-powered building and orchestration runtime Planning multi-step tasks and generating app components Agent Reasoning and task execution Investigating a service request Workflow Repeatable business process Routing an approved request Data layer Stores and retrieves business information Requests, users, approvals, and status Connectors and APIs Integrates enterprise systems SharePoint, Microsoft Graph, or ServiceNow The GitHub Copilot harness in Copilot Studio is not the same thing as using the GitHub Copilot service. It is a Copilot Studio runtime for advanced reasoning and orchestration. Microsoft's documentation states that the normal Copilot Studio security, privacy, compliance, and data residency commitments continue to apply. 2. Before building: define the application properly One of the biggest mistakes is asking the builder to create an app with a vague prompt. For example: Weak prompt "Build an employee management app." This leaves too many decisions to the AI. It might generate an attractive interface but miss important business requirements. Instead, define these eight elements before generating the application. Element What to specify Business problem What problem does the application solve? Target users Who will use it? User journeys What tasks must users complete? Data model What entities, fields, and relationships are needed? UI requirements What screens, components, filters, and interactions are required? Business rules What validations and conditions must be enforced? Integrations What APIs, data sources, and systems are involved? Security Who can view, create, edit, approve, or delete records? Also define the acceptance criteria before generation. For example: Users can search requests by ID, owner, status, and date. Selecting a request opens its detailed view. Users can update permitted fields. Invalid status transitions are rejected. Loading, empty, and error states are handled. Changes are persisted to the intended data source. My recommendation: Write the requirements first, then build the app. Don't use repeated prompts to discover the business requirements while simultaneously generating the UI. 3. Step-by-step guide to building an app Step 1: Open the app-building experience Open copilot studio Step 2: Start with a complete application specification Let's use an example: an Enterprise AI Operations Dashboard. The app will help employees and administrators monitor AI automation requests, investigate failures, track processing time, and manage remediation. Start with a structured prompt. Master app-generation prompt You can adapt this prompt for your first build. Build a professional enterprise application called Enterprise AI Operations Dashboard. BUSINESS OBJECTIVE Create a centralized interface for monitoring AI automation requests, execution outcomes, failures, processing time, and remediation activities. TARGET USERS Operations analysts who monitor executions. Administrators who investigate failures. Managers who review operational performance. APPLICATION STRUCTURE Create the following pages: Overview Dashboard Total executions Successful executions Failed executions Success rate Average processing time Execution trend over time Recent failures Status distribution Execution Explorer Search by execution ID Filter by status, application, owner, and date Sort by execution time and duration Paginated or appropriately limited results Select an execution to open its details Execution Details Execution ID Application name Initiated by Start time and end time Duration Status Error summary Diagnostic information, when available Remediation history Remediation Center Display unresolved failures Allow authorized users to assign an owner Add investigation notes Update remediation status Record timestamps for changes Settings Configurable filters and display preferences Clear explanation of administrative permissions No destructive administrative actions without confirmation DATA MODEL Create a logical data model containing: Execution: ExecutionId ApplicationName InitiatedBy StartTime EndTime DurationSeconds Status ErrorSummary Environment RemediationStatus Remediation: RemediationId ExecutionId AssignedTo Notes Status CreatedAt UpdatedAt Define a relationship between Execution and Remediation. If a persistent data source is not configured, use clearly identified sample data. Do not present sample data as live production data. UI AND DESIGN Use a clean, modern enterprise dashboard with: Clear visual hierarchy Readable typography Consistent spacing Responsive layouts Accessible contrast Reusable UI components Summary cards Appropriate charts Searchable and filterable tables Clear loading, empty, success, and error states FUNCTIONAL REQUIREMENTS Search and filters must work. Dashboard metrics must be calculated from the underlying dataset. Selecting a row must display the corresponding execution details. Form inputs must be validated. Status changes must update the intended data source. Display clear error messages when operations fail. Prevent duplicate submissions where appropriate. Confirm potentially destructive actions. Preserve filters when navigating between related screens where feasible. SECURITY Respect the signed-in user's permissions. Do not expose secrets, access tokens, or sensitive diagnostic information. Do not rely on hiding a UI button as the only authorization control. Enforce authorization at the data source or API. Do not create external integrations without explicitly identifying their requirements. IMPLEMENTATION PROCESS First, summarize the proposed architecture, data entities, pages, and assumptions. Ask clarifying questions if a critical requirement is ambiguous. Then generate the first functional version of the application. After generation, test the primary user journeys and identify incomplete functionality. Clearly distinguish implemented features, simulated features, and integrations that still require configuration. This is a starting specification, not a guarantee that every requested capability will be generated correctly. Inspect the resulting application and verify its actual behavior. Step 3: Review the generated application Once the app preview appears, don't immediately ask for more features. First, inspect the application against the specification. Check: Does the navigation work? Are the pages connected logically? Do the tables display consistent data? Do the filters actually change the results? Are dashboard metrics calculated correctly? Does selecting a record open the correct details? Do forms validate required fields? Does saving actually persist the changes? Are the displayed integrations real or simulated? This distinction is essential: a functional-looking interface is not proof of a working backend. Microsoft's app-building experience provides an interactive preview and lets you refine the app through conversation. It also exposes the underlying code for inspection. 4. Technical prompting techniques for better apps This is where you can significantly improve the quality of generated applications. Technique 1: Build in controlled iterations Avoid asking the builder to implement every feature, integration, chart, and workflow in one enormous request. Use a sequence of targeted changes. Iteration 1: Application foundation "Review the generated application and identify missing requirements. Fix the navigation structure, page layout, data model, and core interactions before adding new features." Iteration 2: Data integrity "Review the application data model. Ensure each execution has a unique identifier, remediation records reference valid executions, and dashboard metrics are calculated from the underlying records. Identify any assumptions that require confirmation." Iteration 3: UI quality "Improve the visual hierarchy, spacing, typography, responsive behavior, table readability, and empty states. Preserve existing functionality and data relationships." Iteration 4: Functional behavior "Test search, filtering, sorting, record selection, form validation, and save operations. Fix broken interactions. Do not replace functional data operations with hardcoded sample results." Iteration 5: Error handling "Add appropriate handling for failed API requests, unavailable data, validation errors, empty results, and repeated submissions. Provide useful user-facing messages without exposing secrets or internal stack traces." Iteration 6: Final verification "Compare the application against the original requirements. List each requirement as implemented, partially implemented, or not implemented. Identify any feature that uses mock data or still needs external configuration." This approach makes failures easier to isolate and reduces the risk of breaking working functionality during a large rewrite. Technique 2: Specify behavior, not just appearance A prompt such as: "Add a modern search bar." defines appearance, not behavior. A better instruction is: "Add a search field above the execution table. Search across ExecutionId and ApplicationName. Apply the search when the user submits or after a short debounce. Combine the search with existing status and date filters. Show an empty state when no records match. Provide a clear-search action and preserve the selected sort order." The second instruction describes expected behavior, interaction, and edge cases. Technique 3: Define invariants An invariant is a condition that must remain true throughout the application. Examples: Every remediation record must reference an existing execution. Execution IDs must be unique. Failed executions must not be marked successful merely because a remediation note was added. A user cannot approve their own request if the business policy prohibits it. Dashboard metrics must use the same filtering rules as the displayed data. Failed writes must not display a false success notification. Add important invariants to the application specification and ask the builder to preserve them during modifications. Technique 4: Request minimal changes When fixing a specific problem, avoid asking the builder to regenerate the entire application. Instead, use an instruction such as: "Fix the execution table's date filter. Preserve the existing navigation, data model, styling, and other filters. Change only the logic needed to make the date filter work. Verify that it works independently and in combination with the status filter." This helps reduce unintended changes and makes troubleshooting easier. Technique 5: Ask for evidence of completion Don't accept a statement that a feature is complete without testing it. Ask: "Identify the implementation for this requirement, test the relevant user journey in the preview, and report any remaining limitation. If the functionality depends on an unconfigured API or connector, identify that dependency explicitly." Where the preview does not allow a test to be performed, request a clear statement of what remains unverified. 5. Underlying code: what to inspect Copilot Studio's app authoring experience includes a way to switch between the interactive preview and the underlying code. Use that capability to inspect the implementation rather than treating the generated UI as a black box. A. Component structure Look for whether the application separates responsibilities into logical components, such as: Navigation Dashboard cards Charts Data tables Search and filter controls Detail views Forms Notifications Loading and error states A large application that puts everything into one component can become difficult to maintain. Prompt: "Review the application structure and identify opportunities to separate repeated UI patterns into reusable components. Refactor only where the current authoring environment supports it, and preserve the existing behavior." B. State management Check how the app manages: Selected records Active filters Search terms Form values Loading states API errors Unsaved changes For example, changing the status filter should not unexpectedly clear the search term or cause the selected record to display stale data. Prompt: "Review state management for the search, filter, table, and detail views. Prevent stale selections, inconsistent filters, and UI updates that occur before a save operation succeeds." C. Data access Identify whether each data source is: Hardcoded sample data Local application state A configured connector A REST API A persistent business data source For production applications, ensure the data access layer has clear responsibilities and that failures are handled consistently. Prompt: "Identify every data source used by the application. Classify each as sample data, local state, or a live integration. Do not imply that data is persisted if it exists only in memory." D. Security Inspect the implementation for: Sensitive values embedded in client-side code Authorization implemented only through UI visibility Excessive data exposure Missing validation Unrestricted destructive operations Unclear handling of user identity Never place API secrets or privileged credentials in browser-accessible code. For sensitive operations, authorization must be enforced by the relevant backend or data source, not just by the interface. Important: Access to the app and access to its underlying data are separate concerns. Microsoft's documentation explains that apps use the signed-in user's identity when connecting to organizational data, and sharing an app does not automatically grant access to data the recipient otherwise cannot access. 6. Connecting the app to enterprise systems For a Microsoft enterprise scenario, you might need to connect the app to SharePoint, Dataverse, Microsoft Graph, Power Automate, or an internal API. The appropriate integration depends on the operation and the capabilities supported by the app-building environment. Requirement Possible integration Technical consideration Store business records Dataverse Define tables, relationships, permissions, and validation Read or update SharePoint items SharePoint connector or API Respect site and item permissions Retrieve Microsoft 365 information Microsoft Graph Configure authentication, consent, and least-privilege permissions Execute deterministic business logic Power Automate or an appropriate workflow Handle failures, retries, and duplicate requests Integrate a custom enterprise system REST API or supported connector Define authentication, schemas, and error contracts Use agent reasoning Copilot Studio agent Restrict tools and define clear instructions These are architecture options, not a claim that every integration is automatically configured by the app builder. Recommended architecture For an enterprise application, consider the following logical design: User ↓ Copilot Studio app and UI ↓ Approved application actions ↓ Connector, workflow, or API ↓ Business data source Where reasoning is required, the app can also invoke an appropriately configured agent. Keep responsibilities separate: UI: Collect input and display results. Business logic: Enforce validation and business rules. Agent: Handle tasks that benefit from reasoning. Workflow: Execute predictable, repeatable steps. Data source: Persist records and enforce applicable access controls. For example, an AI-generated remediation recommendation can be presented in the UI, but changing a production system should require an authorized action and the appropriate validation. 7. App testing: use a structured checklist Before publishing, test the main user journeys, not just the visual design. Test category Example test Functional Can the user create, view, and update a record? Validation Does the app reject a missing required field? Data integrity Does a remediation reference the correct execution? Filtering Do search and status filters work together? Error handling What happens when the API returns an error? Persistence Does the update remain after refreshing or reopening the app? Authorization Can an unauthorized user perform a restricted action? Accessibility Are controls labelled and keyboard-accessible? Responsive design Does the layout remain usable at narrower widths? Performance Does the interface remain responsive with realistic data volumes? Security Are secrets excluded from client-side code? Data integrity under failure Does a failed write avoid displaying a false success message? For each critical requirement, define an expected result and test it. For an application that modifies business data, also test repeated submissions, concurrent updates, and partial failures where applicable. 8. Optimize Copilot Credits and iteration time App creation, previewing, testing, and refinement can consume Copilot Credits. Microsoft documents usage-based billing for the app-building experience. These practices can help reduce unnecessary iterations. Write a complete specification first. Resolve critical questions about users, data, and business behavior before generation. Generate a minimum viable application. Start with the core pages and one complete user journey. Fix related problems together. Instead of making five separate requests for spacing, typography, card alignment, and table readability, group those visual changes into one clearly scoped request. Avoid unnecessary full rewrites. Ask for a targeted fix and explicitly preserve unrelated functionality. Separate requirements from optional enhancements. Finish the core user journey before adding animations, elaborate charts, and secondary features. Reuse a master specification. Keep the requirements, data model, and acceptance criteria in a reusable document so you don't need to reconstruct them for every iteration. Verify before requesting another change. Test the current result first. Otherwise, you may spend credits fixing an issue that no longer exists or introduce a new issue while fixing an old one. These are practical optimization strategies, not a guarantee of a particular percentage reduction in credit consumption. 9. Publishing and sharing the application Once the app has passed its tests: Review the final UI and application behavior. Confirm that sample data is clearly distinguished from live data. Verify configured connections and permissions. Test the intended user experience. Use the available publish action to publish the app. Share it with the intended users or groups. Verify access with an appropriately authorized test account. Document known limitations and outstanding integrations. The preview status matters. Microsoft explicitly notes that Apps in Copilot Studio is a preview feature, which may have restricted functionality and is not intended for production use. Therefore, don't assume that a successful preview or publishing action alone makes the application suitable for production. Confirm the current feature terms, organizational approval, and production-readiness requirements before deploying it for business-critical use. My final recommendation For your work with Copilot Studio, Power Platform, Cowork, MCP integrations, and enterprise automation, I would develop a reusable App Builder Playbook with five parts: A requirements template. A master app-generation prompt. A reusable set of UI and data-model refinement prompts. A testing and security checklist. A credit-optimization and publishing checklist. That gives you a repeatable engineering process instead of relying on trial-and-error prompting for every new app. The most important principle is this: use natural language to accelerate implementation, but use engineering discipline to verify the result.87Views1like0CommentsAre bigger agents better? How to design agents that scale
There is a moment every maker hits. An agent works, so you add another tool. Then another knowledge source. Then instructions for an exception that appeared last week or an entirely new use case you want your agent to be able to tackle. Each addition is useful on its own, and the agent can now do more. But "can do more" and "reliably does the right thing" are different properties. As an agent’s scope increases, the model has more choices to distinguish, more context to process, and more possible execution paths to manage. That doesn’t mean large agents are bad. It means that as capability grows, the challenge increasingly becomes a design problem. The key to scaling an agent isn't giving it more. It's being deliberate about what it sees, what it decides, and what it delegates. What changes as an agent grows The agent scaling challenge Consider a supplier-onboarding agent. The first version collects supplier details, checks that the request is complete, and starts an approval. Over time, makers add tools for ERP records, tax validation, sanctions screening, bank verification, contract storage, service tickets, email, and reporting. They add knowledge for regional policies and instructions for exceptions. Eventually, a request such as "Onboard our newest supplier" might present the agent with several supplier-search tools, multiple ways to create or update a record, and overlapping policy sources. The agent still has all the required capabilities, but choosing the right path is harder. The agent scaling challenge tends to show up in four places: Selection: Similar tool names and descriptions make the correct action harder to identify. Context: Tool definitions, instructions, knowledge, conversation history, and tool outputs all compete for a finite context window. Execution: More possible paths create more opportunities for unnecessary calls, retries, and inconsistent outcomes. Operations: A larger capability surface is harder to evaluate, secure, govern, and maintain. A recent post from Microsoft Research discusses one part of this problem: Tools that work well independently can reduce end-to-end performance when they compete in a large or overlapping set. Often, the problem isn’t one bad tool. It is the ambiguity between several reasonable ones. Figure 1: As a supplier-onboarding agent grows, overlapping tools, instructions, and knowledge compete for attention before the agent begins the task. More context comes with a cost There is also a direct cost associated with an expanding toolset. A tool consumes tokens even when it is never called because its name, description, and parameter schema are included in the context presented to the model. When it is called, its output becomes part of the agent's ongoing context. More context can mean more spend, as well as less reliable selection. The goal isn’t a smaller agent. It is a system where each decision sees only the context, authority, and capabilities it needs. Success is measured by business outcomes, reliability, cost, and control. What our harness can handle for you Good agent architecture doesn't mean solving every scaling challenge yourself. The GitHub Copilot harness in Copilot Studio is built to manage some of the complexity as an agent grows. Model improvements that don’t require agent redesign New models are made available through the GitHub Copilot harness as they release. As more advanced frontier models become available, teams can evaluate them against their scenarios and adopt improvements without redesigning the overall solution architecture. Model choice can also be an important factor in agent cost optimization, helping makers balance the number of tokens used against the capability needed to achieve a goal. Manage complexity natively with tool search The GitHub Copilot harness includes runtime capabilities designed for reasoning-heavy, multistep work. One example is tool search. When the available tool set becomes large, tool search can hold external tool definitions back and load the relevant ones on demand instead of placing every full schema in the model's context. For the supplier-onboarding request, this can narrow a large catalog to the tools associated with finding a supplier, validating its details, and starting onboarding. The model works with a smaller, better-matched set of choices while unrelated tool definitions remain out of the way. The harness can also plan across tools, skills, workflows, MCP servers, files, and connected agents, and adjust its path as work progresses. This all makes large, reasoning-heavy automations more practical. But runtime capabilities only solve part of the scaling challenge. How you divide responsibilities across tools, workflows, skills, and connected agents still matters. How to design agents that scale in Copilot Studio A scalable design starts by deciding which part of the system should own each responsibility. For instance: Use a tool for a bounded action or lookup with a clear input and output. Use a workflow when a sequence, approval, or business rule should execute consistently. Use a skill for specialized instructions that are only needed for a particular task. Use a connected agent when a domain has distinct context, ownership, or requirements. Use the main agent to coordinate outcomes, gather information, make judgments, and handle exceptions. These are not interchangeable building blocks. Each introduces different tradeoffs in context, flexibility, latency, cost, security, and maintenance. The goal is to use the simplest component that gives each responsibility a clear owner. 1. Make choices distinct Start with the choices already available to the agent. Give tools, knowledge sources, and connected agents specific names and descriptions that explain both what they do and when they should be used. Merge or remove duplicate capabilities. Avoid several general-purpose tools that all appear to answer the same intent. In the supplier example, "Search suppliers in ERP by legal name or tax ID" is easier to select correctly than a generic tool named "Search." If two tools search the same supplier records, expose one clear route rather than asking the model to choose between implementations. Tool search itself relies on names, descriptions, and parameter metadata to find relevant tools, so good metadata improves both discovery and final selection. 2. Load specialist guidance only when it is needed Some instructions are only relevant when an agent performs a particular task. Keeping all of them in the main agent instructions means they occupy context on every turn, even when they do not apply. Skills let makers package specialized instructions separately so the agent can load them when the task requires them. For example, regional supplier due-diligence guidance can be packaged as a skill and loaded for suppliers in that region, rather than remaining in the main instructions for every supplier request. The principle is the same as tool search: keep relevant context close and leave unrelated context out of the current decision. 3. Split on real boundaries When one agent contains several distinct domains, consider separating them. To clarify: Don't split an agent simply because it has grown large. Split where there is a meaningful boundary in context, ownership, security, or requirements. In the GitHub Copilot harness, connected agents let a primary agent delegate a bounded task to another Copilot Studio agent with its own instructions, knowledge, tools, and orchestration context. The supplier-onboarding agent could remain the front door while delegating: Compliance assessment to a compliance agent owned by the risk team. Supplier record creation to a finance operations agent with access to the ERP. Contract preparation to a legal operations agent with its own templates and policies. The primary agent now chooses between a few clearly described business capabilities instead of dozens of lower-level tools. Each specialist can be evaluated, secured, deployed, and improved independently. Copilot Studio also supports open agent architectures. Depending on the runtime and scenario, solutions can compose Copilot Studio agents or connect supported external agents through the Agent2Agent protocol. In the supplier scenario, a specialist due-diligence agent hosted outside Copilot Studio could sit behind the same clear boundary, rather than being rebuilt as a collection of tools. 4. Put fixed sequences in workflows Use the agent where the next step requires judgment. Use a workflow where the sequence, approval, or control must remain consistent. This helps preserve adaptability without making every part of the process probabilistic. For example, supplier onboarding might always require the same core sequence: validate required fields, check for an existing supplier, run mandated compliance checks, create the record, and route it for approval. A workflow can own that sequence. The agent can still decide when to start it, gather missing information, and handle exceptions. This reduces the number of low-level decisions the model must make and gives makers one place to enforce approvals, retries, and audit requirements. The supplier-onboarding agent, redesigned So let’s go back to the original agent in our example. It had one long instruction set, several knowledge sources, and dozens of tools. The redesigned system doesn’t eliminate that agent. It gives it a clearer job: coordinating the overall outcome while other components take on more specialized responsibilities. That gives us a system: The main supplier-onboarding agent understands the request, collects any needed details, delegates as needed, handles exceptions, and responds. Tool search limits the external tools loaded for the current request. Clear metadata separates supplier lookup, compliance, finance operations, and contract tasks. A workflow owns the fixed onboarding and approval sequence. Skills provide regional guidance only when the supplier's location requires it. Connected agents own compliance, ERP, and legal domains where those boundaries justify separate agents. The result is the same overall capability, but as a composed system with clearer responsibilities and less for any one decision to reason over. Evaluate for the outcome Each approach discussed above has limits. A stronger model cannot compensate for unclear instructions or overlapping tools. Tool search reduces what the model sees, but it does not create boundaries that have not been designed. Workflows and skills reduce what the main agent must reason over, but they add components to maintain. And connected agents can provide clearer ownership and security boundaries, but each handoff adds token use, another failure point, and more to govern. Designing agents that scale means managing all four components of the agent scaling challenge together: making selection easier with distinct choices and clear boundaries, controlling context with tool search and skills, making execution more predictable with workflows and deliberate delegation, and strengthening operations through components that can be evaluated, secured, governed, and improved independently. Agent scale is not a tool-count contest. Models, requirements, and available tools will keep changing, but these principles give you a more durable way to evolve an agent without letting added capability become added confusion. The goal is not the biggest agent; it is a composed system that reliably does the right work, at the right cost, with clear ownership.950Views0likes0CommentsBest practice for Copilot Studio agents and SharePoint libraries with unique permissions?
We recently ran into an issue where a Copilot Studio agent was unable to retrieve content from SharePoint libraries that have unique permissions and nested folder structures. Users with elevated permissions were able to retrieve results, while users with read-only/visitor access could not, even though they had access to the underlying documents. We've observed similar behavior across multiple agents and suspect the library's unique permission structure is impacting indexing or content retrieval. For organizations that use SharePoint libraries with extensive unique permissions, nested folders, and restricted access models: What is the recommended approach when using these libraries as knowledge sources for Copilot Studio agents? Are there known limitations or best practices regarding unique permissions and nested folders? Is it better to simplify permissions, create dedicated access groups, flatten the folder structure, or maintain separate agent-specific content locations? How are others balancing security requirements with reliable agent retrieval? We'd appreciate any guidance, best practices, or lessons learned from similar implementations.349Views0likes2CommentsChild agents and local agents in Copilot Studio
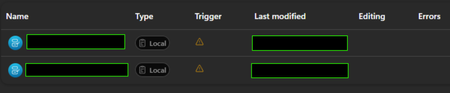
I'm AI administrator, and I have a colleague who've build an agent in Copilot Studio that uses to child agents. However on his screen they have the relationship "Local" and he can't access them or do anything. When I look at his agent, the sub agents have relationship "Child" and everything works fine. The image down below is what he sees - and the trigger also gets that orange triangle. Have anybody experienced the same? We tried to give another colleague editor permission to the agent, and that colleague experiences the same. They are both sitting at an office in another country than me.480Views0likes3Comments
White paper: Choosing between the GitHub Copilot and Standard harnesses in Copilot Studio
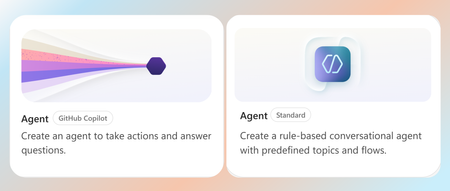
The Standard harness and GitHub Copilot harness are two authoring and runtime options within Microsoft Copilot Studio. A harness is the operating layer between the model and the agent’s configuration. It determines how the model receives context, uses instructions and tools, interprets results, and moves through a task toward completion. Put simply, the model provides the reasoning capability, while the harness equips and directs it. Both harnesses are built for task-based, multi-step agents that create real business value, but they are suited to different scenarios. The Standard harness supports consistent, reliable execution of bounded business processes, while the GitHub Copilot harness extends these capabilities to longer-running, coordination-heavy, and reasoning-intensive work at a larger scale. This paper explains the key differences, tradeoffs, and scenarios to help you choose which harness is right for your business process. Read the full paper by clicking the PDF attachment below.8.4KViews0likes2CommentsUnanswered Questions on GitHub Copilot Harness in Copilot Studio
We're piloting the GitHub Copilot harness in Copilot Studio (GA August 2026) and several operational and architectural details remain undocumented in the GA FAQ, Microsoft Learn, or licensing guides. Looking for official answers or PM contacts on: Architecture & Execution – When the harness breaks tasks into subtasks, does it use internal sub-agents or only skills/connected agents, what are the exact timeout/retry/max-execution-duration limits for long-running workflows, and are planning/context-retrieval/orchestration internals documented anywhere or is the orchestrator a black box? Model Selection – Can individual skills within one agent use different models or is selection strictly agent-level, how are models chosen internally when multiple skills execute, are any internal models developer-configurable, and what's the roadmap for models being added/retired/deprecated plus the lag between public release and Copilot Studio availability? Cost & Token Optimization – How exactly is the ~45% token reduction achieved, how much control do makers have over context/caching/retrieval/tool calls, what are per-model credit consumption characteristics, which models are most cost-effective for specific workloads, and what's the minimum credit cost for trivial interactions? Memory Management – What are retention periods for session/working/agent memory beyond the documented 28-day user-memory expiry, is true long-term memory supported, and what changed versus earlier implementations? Knowledge Retrieval – Can skills or system instructions influence retrieval strategy/document selection/prioritization/filtering, can planning stages perform conflict/duplicate/version detection before retrieval, and how does the harness decide which sources to search? Apps Feature – What is the "Apps (preview)" capability for, when does it GA, and how does it differ from workflows/skills/adaptive cards/agents? Billing & Credit Sizing – Is there a framework to classify users/agents by expected consumption and size credit allocation per group (citizen vs pro developers), and what's the minimum/typical consumption for simple/medium/heavy interactions? Governance & Admin – Can usage limits be set at user level (not just environment/agent), is there an API/IaC path for large-scale credit assignment, can non-admins view their own consumption/remaining allocation, and is there a self-service request-more-credits dashboard? ALM & Environments – What's the recommended path to move harness agents across Dev/Test/UAT/Prod (Solutions/ALM "setup differs" per parity chart—how?), does GitHub integration replace or complement solution-based deployment, are there recommended AgentOps practices for source control/releases/versioning, and what baseline credits and onboarding model are suggested for citizen developers under usage billing—any enterprise reference implementations?665Views2likes1CommentUpdate: Root Cause Identified
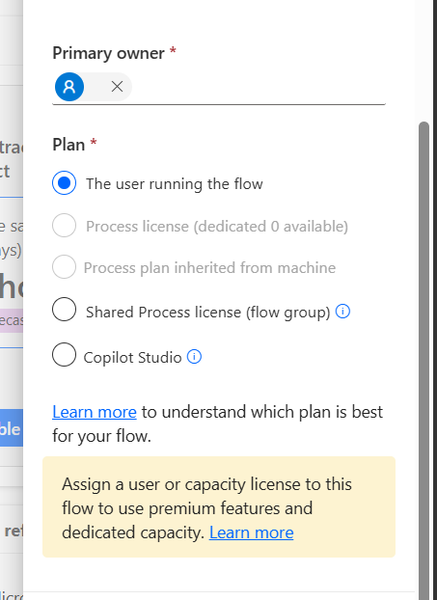
Hi everyone, I would like to share the root cause and solution in case someone else encounters the same issue. The Problem I created several agent flows directly in Power Automate using: https://make.powerautomate.com The flows were configured correctly: The flow starts with When an agent calls the flow The flow ends with Respond to the agent The flow and agent are in the same environment The flow is included in a solution The flow is published and fully functional The flows could be added to an agent and executed successfully. However, unlike flows created directly from Copilot Studio, they did not appear in the Global Tools directory. What I Investigated I verified: Trigger configuration Respond to the agent action Environment consistency Solution membership Publish all customizations Asynchronous response settings Synchronization delays between Power Automate and Copilot Studio None of these were the root cause. Root Cause The issue was related to the workflow Plan. I discovered that: Flows created directly in Power Automate were assigned: Plan = The user running the flow Flows created directly in Copilot Studio were assigned: Plan = Copilot Studio Although the Power Automate flow was fully functional and could be used by the agent, it was not visible in the Global Tools directory. Solution After changing the workflow Plan to: Plan = Copilot Studio the flow immediately appeared in the Global Tools directory. Configuration Location The setting can be found in the workflow properties under: Primary owner → Plan Important Note Based on my testing, changing the Plan to Copilot Studio appears to be a one-way operation and may not be reversible. It may be a good idea to export or save the flow before making the change. Acknowledgements Special thanks to sohnash for reproducing the scenario and providing troubleshooting suggestions, and to Patty_Velasquez for sharing similar observations that helped confirm the behavior. Hopefully this helps others who encounter the same issue. Best regards, Adhonaï KOUKA206Views1like0Comments