evaluation
56 Topics
Gulf Air's Continuous Improvement Journey with Microsoft Foundry
On November 9, Gulf Air reached a milestone: two AI agents in its Falcon Eye application—a voice agent and a chat agent—went live for users. The milestone did not come from finding one perfect prompt. Gulf Air had spent weeks building a demanding pool of evaluation questions, studying traces, finding gaps, changing instructions and code, and testing again. Ahmed reported that the team generated approximately 10,000 candidate questions across different business perspectives, then ran selected questions in smaller batches to exercise real aviation and management logic. Ahmed AbdulJalil Ebrahim described the impact plainly: " What evaluation, insights, and optimize did for us was really amazing. We were able to fix business logic the agent had not understood." For us, the important part of this story is not that one tool produced one answer. It is that Gulf Air assembled a repeatable improvement practice around the hard questions its business would actually ask. The application had to do more than retrieve an answer Falcon Eye is an important Gulf Air application used for operational analysis and management decision support. Ahmed described a five-agent vision spanning UI summaries, smart search, dynamic reporting, real-time voice, and a reasoning chat experience. These agents connect to operational data through APIs and a Postgres MCP. They can analyze information, perform calculations, and help users create reports or dashboards. That makes them useful, but it also raises the quality bar. A simple factual test cannot establish whether an agent: selected the right operational field for the user's question; followed an aviation-specific rule; generated an appropriate query; performed a calculation correctly; preserved the user's data permissions; or remained reliable when the same intent appeared in a different form. For senior leaders asking operational or financial questions, a fluent answer is not enough. The reasoning path and the business result both matter. Gulf Air built an evaluation pool around the hardest business questions Ahmed described this generated question pool as covering multiple business perspectives. He emphasized that these were not only straightforward questions such as total departures or delays. They were intended to test the business logic that had been difficult to express through a system prompt alone. The team selected questions from that pool and generally ran them in batches of 100. The evaluation results separated successful answers, failures, no-answers, and errors. Gulf Air then examined the resulting traces and insights, brought the evidence into VS Code with its engineering context, implemented changes, and evaluated again. The loop looked like this: Run difficult evaluation questions -> inspect failures, no-answers, and errors -> review generated insights and supporting traces -> bring the evidence into the coding workflow -> change instructions, tools, or application logic -> test candidate improvements -> add independent human review -> run evaluation again Human review was a deliberate part of the process. Other team members approached the agent differently and documented issues that the original test design had missed. Their findings became new inputs to the next improvement cycle. Immediately before our November 9 conversation, Ahmed had completed another 400-question run and applied additional fixes. This was not a one-time benchmark. It was an operating rhythm. Evidence became useful when it entered the engineering workflow The workflow did not stop at an evaluation score or a list of traces. Gulf Air used the evidence to decide what to change. Insights from traces helped group recurring behaviors and connect them with representative executions. VS Code supplied the surrounding engineering context: code, APIs, MCP access, reports, and prior findings. The team could then investigate whether an issue came from instructions, tool behavior, application logic, or the test itself. This distinction matters. An insight can identify a pattern and point to a likely direction, but it is not automatically a validated fix. Gulf Air still reviewed the evidence, implemented the change in the appropriate system, and ran the agent again. That developer-led pattern is also central to the latest Microsoft Foundry experience: Scheduled and on-demand analysis can process new traces incrementally after the initial lookback. Linked and highlighted traces let developers inspect the evidence behind an insight. Custom categories and additional instructions help focus future analysis on business-specific concerns. A proposed change can be copied into a coding workflow when the issue belongs in code or application configuration. For eligible instruction or tool-description issues, developers can use fix insights and create an agent optimizer run. The handoff is important, but so is its boundary: a proposed fix is a starting point for validation, not an automatic production change. From a selected insight to an evaluated candidate From the Insights tab, a developer can choose Select insights, select the relevant insights, and choose Fix insights to create an optimization run. Foundry uses the selected evidence to prepare supported replay scenarios, proposes candidate changes, and compares them with the current agent version as the baseline. The goal is not to accept whichever candidate has the highest single score. Developers can inspect: which selected issues improved; the candidate's actual instruction or tool-description changes; per-scenario and overall evaluation results; quality comparisons with the baseline; token usage and estimated cost; latency; and whether independent conversations were available to check for broader regressions. Sometimes the responsible result is still the baseline. A candidate might fix one failure while regressing elsewhere, the evaluator might find the result inconclusive, or the available evidence might be too narrow. The developer reviews those trade-offs and explicitly decides whether to promote a candidate. Nothing in this workflow automatically changes the active agent. Human review, promotion, testing, and production activation remain separate decisions. Gulf Air assembled this handoff manually. The new select-insights-to-fix experience is designed to shorten part of that journey by carrying verified insight evidence into a controlled optimization run. Confidence was the business outcome The value of this work was not a single score or a one-time test. Each evaluation cycle produced reusable evidence - failure cases, traces, human-reviewed findings, and proposed changes that the team could carry into the next iteration. Validation became part of the engineering workflow rather than a final checkpoint before launch. The business outcome was confidence. Ahmed described the workflow as giving Gulf Air a level of confidence in its agents that the team had not achieved before. He also reported that Gulf Air management was impressed by the voice and chat-agent demonstration on launch day. From Gulf Air: what changed for our team “The agent refinement experience changed the way we approach agent AI development at Gulf Air. Instead of relying on individual tests or continually adjusting prompts, we can systematically challenge our agents with thousands of real business questions, understand where they struggle, and use evaluation, traces and insights to identify the underlying issues. This approach helps us refine how agents understand complex aviation business logic and gives our teams greater confidence in the agents we move into production. More importantly, it establishes a continuous development cycle where real-world usage and evaluation drive the next improvement.” Five lessons for teams moving agents into production Gulf Air's experience suggests five practical lessons. 1. Build the evaluation set around business difficulty Start with the questions your business struggles to encode, not only the questions your agent already answers well. Include ambiguity, calculations, tool use, permissions, and domain rules. 2. Use insights to find patterns beyond predefined evaluations Evaluations test the requirements a team already knows how to define. Insights can look across production traces for recurring behavior the team did not anticipate, bring related executions together, and show representative evidence. Custom categories and additional instructions can focus that analysis on business-specific concerns. Developers still review the cited traces and compare the finding with business expectations before deciding that an issue is real. 3. Turn recurring guidance into a reusable skill When a verified issue reflects guidance the agent should apply across many future interactions, repeatedly tuning prompts might not be enough. A versioned skill can capture that learning in a form the team can review, evaluate, and deliberately adopt. Not every issue belongs in a skill. Code defects, tool-description problems, data-quality issues, and platform failures still need to go to the workflow that owns the responsible layer. 4. Compare trade-offs, not only quality scores A candidate can improve one behavior while using more tokens, adding latency, or regressing on normal conversations. Compare candidates with the baseline and inspect the underlying evaluation cases. 5. Keep production changes explicit Continuous analysis can discover new patterns, and optimization can test candidates. Neither should remove the developer's responsibility to review evidence, approve changes, and test the promoted version before sending production traffic to it. The next chapter: keep learning after launch Production is not the end of the evaluation set. It is where new evidence begins. Real users ask questions in ways a development team did not anticipate. Data changes, tools evolve, and a response that works for one scenario can fail at the edge of another. The opportunity is to turn those new production behaviors into the next round of learning without losing the controls that made the launch possible. For Gulf Air and other enterprises building complex agents, that means establishing a repeatable rhythm: Observe new behavior in production traces. Verify the pattern against representative evidence and business expectations. Turn confirmed failures into evaluation coverage. Test candidate changes against the current baseline. Compare quality, latency, and cost rather than optimizing one measure in isolation. Promote a change only after human review, then watch the new version under real traffic. This is the larger promise of continuous improvement in Microsoft Foundry. Insights from production traces can help teams discover what deserves attention. Evaluation makes expected behavior testable. Agent optimizer can compare possible improvements. Developers remain responsible for deciding what is correct, what is safe, and what should reach production. The next milestone is not an agent that changes itself without oversight. It is a controlled learning system in which production evidence, business context, evaluation, and human decisions reinforce one another. For Gulf Air, the first milestone is already real: difficult questions became evidence, evidence became engineering work, and that work helped two agents reach production with greater confidence.74Views0likes0Comments
Copilot Studio agent: OpenAIModelTokenLimit, ContentFiltered, duplicate replies and raw JSON in chat
Hi everyone, While testing an agent in Copilot Studio, I’m running into the following errors and would appreciate any guidance. OpenAIModelTokenLimit: “The request is resulting in too much data to handle” The agent returns this error instead of an answer, even for short, single questions. Repeated messages A single question produces two answers in the same turn: a structured answer, then a rephrased version of the same content. The activity map shows the same step running twice in that turn. Follow-up questions from the agent also sometimes appear twice. ContentFiltered: “The content was filtered due to Responsible AI restrictions” Raw JSON shown alongside the rendered answer Intermediate “thinking” messages Intermediate, thinking-style messages occasionally appear in the chat before the final answer. Questions What typically causes OpenAIModelTokenLimit when the question itself is short? What’s the recommended way to prevent duplicate answers in the same turn? How can I stop raw JSON from being displayed to the user? Is there a way to suppress the intermediate messages? These responses come from the parent agent, which is connected to a child agent. Only the child agent has the knowledge sources needed to answer questions, and the parent agent’s instructions route all questions to it.25Views0likes0CommentsFinOps in Microsoft Foundry: see your token spend, hit your quality bar for less, and set limits
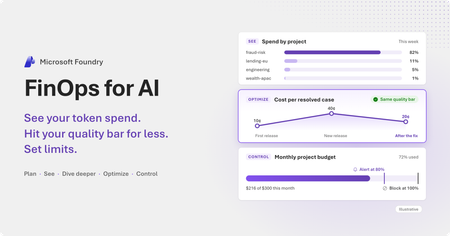
An end-to-end walkthrough of FinOps for AI in Microsoft Foundry: plan what an agent should cost, see where the spend goes, find out why it changed, hit your quality bar for less, and set limits.656Views0likes0Comments
Copilot Studio agent behaves differently in Teams and the test pane
Hello, We have built a topic-based agent in Microsoft Copilot Studio that uses SharePoint as a knowledge source and is published to Microsoft Teams. We are seeing the following behavior: The agent sometimes stops responding in Teams. To make it respond again, we need to use commands such as: /debug clearstate /debug clearhistory /debug conversationid 3. One of our topics contains a Question node asking whether the user’s query was resolved. 4. The question and its options appear correctly in the Copilot Studio evaluation/test pane. 5. However, the same question never appears when the agent is used in Teams. Has anyone experienced similar behavior? Any troubleshooting guidance would be helpful.249Views0likes2CommentsImprove production agents with closed-loop evaluations in Microsoft Foundry
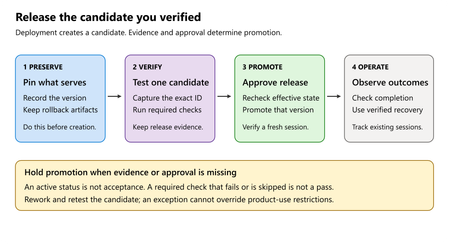
A production agent can lose accuracy or cost too much without a single code change. As live traffic grows, new user requests expose gaps in the agent instructions. At the same time, newer models can offer better quality or lower operating cost. Yet editing prompts by hand or swapping models in place risks breaking workflows that already work. The diagram uses v1 and v2 for the active baseline and candidate; Microsoft Foundry assigns the actual version numbers. Prerequisites and integration responsibilities Before implementing this workflow, verify these platform resources and application components: Microsoft Foundry resources: Deploy a hosted agent with the Agent Optimizer SDK. Connect Application Insights, deploy approved models, and grant Microsoft Entra ID permissions. Application team responsibilities: Supply the sandboxed tool test harness, reviewed outcome labels ( ground_truth ), the CI/CD release policy script, and session canary routing ( version_indicator ). How the scheduled loop runs end to end A scheduled GitHub Actions workflow or an Azure Monitor alert starts each cycle across Microsoft Foundry and GitHub Actions. On each run, the workflow reads recent continuous evaluation scores, Application Insights error metrics, and newly approved model deployments. When triage confirms an agent quality drop or a scheduled model evaluation, the workflow samples recent traces into a dataset for human label review. Next, Agent Optimizer searches across instructions, skills, tool descriptions, and models on your training and validation datasets. Your release automation applies the selected candidate and opens a pull request for engineer review. It then gates promotion on a held-out regression suite and updates .agent_configs/baseline/ after promotion. 1. Monitor live traffic with continuous evaluation Safe promotion starts with measuring the active production configuration, which serves as the baseline for every comparison against a proposed candidate. On live traffic, Microsoft Foundry continuous evaluation scores execution traces to track how quality, tool use, latency, and cost change over time: Tool output versus reply ( groundedness ). Checks whether the reply has support in the supplied context, flagging unsupported completion claims. Instructions versus actions ( task_adherence ). Checks whether the agent followed its system prompt rules during the conversation. Query versus tool calls ( tool_call_accuracy and intent_resolution ). Verifies that the agent selected the right tool and arguments for the user's request. Safety and trace rules ( indirect_attack and span checks). Flags injected instructions while span checks detect tool errors and repeated write calls. Triage alerts and set the optimization objective When a quality alert fires, check Application Insights traces and Azure Monitor metrics first. Separate an agent configuration issue from other operational changes before running an optimizer job: Backend or tool outages. Rising tool timeouts or API errors call for infrastructure recovery before you tune the agent. Traffic-mix shifts. A surge in a new request type may require new tools, policy rules, or test coverage before optimization. Evaluator or rubric updates. A changed grader prompt or threshold shifts scores even when agent behavior is unchanged. Confirm that a configuration change can address the issue, or start a run from a scheduled review or new model deployment. Define the objective up front: Optimization objective Primary target Mandatory requirements Improve quality Achieve a target score gain on failing task categories and meet the required quality floor Preserve scores in existing categories, pass all critical safety and business checks, and stay within cost and latency limits Reduce operating cost Lower token and model cost across the agent workload Meet the quality floor, stay within the allowed variation margin, pass all critical checks, and stay within latency limits 2. Turn production traces into isolated, executable datasets Once monitoring identifies what to improve, the next step is building the evaluation datasets for Agent Optimizer and CI/CD. Microsoft Foundry trace dataset generation ( project_client.datasets.begin_create_generation_job ) samples production traces from Application Insights into a versioned dataset registered in your project. When you set max_samples , Microsoft Foundry uses MinHash sampling to filter out repetitive messages and select diverse conversations. Pinning agent_version samples behavior from one known release while redacting private content ( redact_private_content=True ) by default. In a tool-using workflow such as an order refund agent, flagged traces often expose three failure patterns: Unsafe retries after a tool timeout. The agent calls a write tool such as submit_refund , and the call times out with outcome_unknown . The agent repeats the write request before it checks the first request's status. The backend must also prevent duplicate transactions. Premature completion claims on asynchronous work. The agent skips get_refund_status and reports a refund as completed while backend processing remains pending . Prompt injection inside untrusted tool data. The agent obeys injected text inside a customer return note ( untrusted_return_note ) and reports an unverified status. Figure 1. The agent checks the refund status after a timed-out submission. The tool sequence shows how it handles an unknown outcome. Bridge the gap from recorded traces to safe test execution A generated trace dataset captures the conversation history from production. Turning those recorded interactions into safe, repeatable evaluation cases requires verified expected outcomes and a sandboxed test backend. Keep all evaluation runs isolated from live payment APIs and customer databases: Review expected outcomes ( ground_truth ). Inspect each sampled trace and add the reviewed business outcome ( status , order_id , refund_id , and reason ) to ground_truth . Preserve the original captured response as the historical record. Isolate tool execution in a test harness. Bind each evaluation case to controlled tool doubles and a resettable test database or ledger snapshot. Every evaluation run executes fresh tool calls against this sandbox. Keep optimizer data separate from the release regression suite. Split reviewed cases into training and validation datasets ( 2a ) for Agent Optimizer, and reserve a held-out regression suite ( 2b ) for CI/CD release gating. Keep all requests from the same incident in one data split. Figure 2. This example dataset uses synthetic interactions to illustrate the production trace workflow. Reviewers verify expected outcomes and pair each case with isolated test state. 3. Configure eval.yaml and evaluators against fixed requirements With the datasets registered in Microsoft Foundry, define how each run is scored. Use eval.yaml to bind your baseline agent configuration, the training and validation datasets, evaluators, and approved model search space: name: Refund agent configuration search agent: name: refund-release-loop kind: hosted model: gpt-5.4-mini config: .agent_configs/baseline/metadata.yaml dataset: name: refund-loop-training version: "1" validation_dataset: name: refund-loop-validation version: "1" evaluators: - builtin.task_adherence - name: refund-state version: "3" options: eval_model: gpt-5.4-mini optimization_model: gpt-5.4 max_candidates: 4 optimization_config: model_search_space: - gpt-5.4-mini - gpt-5.4 Keep the held-out regression suite ( refund-loop-release ) in a separate CI/CD evaluation configuration so Agent Optimizer cannot access or overfit those cases during search. Keep release criteria independent of candidate instructions Prompt evaluators such as builtin.task_adherence help spot instruction drift, while Agent Optimizer rewrites instructions.md and SKILL.md to improve performance. Grade every candidate against fixed business requirements kept outside the editable agent configuration: Evaluator type What it checks on each fresh sandboxed run How it protects the release gate Semantic and rubric evaluators Grades the reply against fixed task-level criteria , mapped grounding context, and ground truth Allows better phrasing or model changes while enforcing business rules and grounded claims Custom code evaluator Inspects the tool call sequence, structured JSON output, and resulting sandbox ledger state Blocks duplicate write calls, skipped status checks, and mismatched transaction states To use builtin.groundedness on tool-supported claims, pass serialized tool outputs as grounding context and map that field in your evaluator inputs. Before testing, set your quality floor, target gain or cost savings, and allowed regression margin. Semantic evaluation permits harmless wording changes. The regression margin defines the largest acceptable quality loss. Assess sampling uncertainty separately. Microsoft Foundry custom code evaluators inspect the candidate's tool events and sandbox state snapshot directly. The following illustrative check blocks duplicate refund submissions and status claims that disagree with the verification tool or ledger: # Illustrative custom code evaluator logic submissions = [e for e in events if e["tool"] == "submit_refund"] if len(submissions) > 1: failures.append("repeated_submission") verifications = [e["result"] for e in events if e["tool"] == "get_refund_status"] claimed = output.get("status") if claimed in {"completed", "pending", "failed"}: if not verifications or verifications[-1].get("status") != claimed: failures.append("unverified_claim") if not ledger or ledger[-1].get("status") != claimed: failures.append("claim_state_mismatch") Because custom code evaluators run in an isolated environment without network access, the evaluation harness attaches the resulting sandbox state snapshot to each evaluation item. 4. Run Agent Optimizer on your evaluation dataset Once eval.yaml is ready, run Agent Optimizer from your agent project root: azd ai agent optimize The command detects eval.yaml automatically. Agent Optimizer is in preview; see the optimization quickstart for supported flags and regions. During the job, it scores .agent_configs/baseline/ , proposes up to max_candidates revisions from training tasks, and ranks candidates on validation_dataset : Optimization target Baseline input What Agent Optimizer changes Instruction tuning instructions.md Rewrites the system prompt with explicit constraints, step ordering, and output format rules Skill improvement skills/<name>/SKILL.md Refines domain skill descriptions, bodies, and activation criteria while keeping their purpose intact Tool optimization tools.json Clarifies function and parameter descriptions without changing the executable tool schema Model selection model_search_space in eval.yaml Tests candidate model deployments from the approved list in your Foundry project Load the selected instructions, skills, model, and tool descriptions at runtime with load_config() . Keep application logic, authorization, and tool contracts outside the optimization scope. For an illustrative submit_refund timeout, a candidate can update the refund skill and tool descriptions to check get_refund_status first. The configuration diff shows the intended changes, while evaluation provides evidence that the agent follows your business rules. Figure 3. The comparison ranks four candidates on validation runs. The selected candidate refines the skill and tool descriptions. 5. Gate the candidate in GitHub Actions CI/CD After you select a candidate in Agent Optimizer, apply its configuration to .agent_configs/ and open a pull request for review: azd ai agent optimize apply --candidate <candidate-id> In GitHub Actions, the workflow signs in to Azure with Microsoft Entra ID. It then runs a four-step release gate while live traffic stays on v1 : Deploy the candidate version ( v2 ). Run azd deploy --no-prompt to register the candidate container without changing the endpoint selector ( v1 ). Evaluate both pinned versions on the held-out suite ( 2b ). Run cloud evaluations on refund-loop-release for v1 and v2 (or azd ai agent eval run per version). Retrieve complete grades and resource metrics. Collect all evaluator scores, latency metrics, and model token counts from both completed runs. Enforce the release policy. Compare v2 against v1 using the objective from Step 1, and exit non-zero when the policy fails: Release check result Outcome on the held-out regression suite CI/CD gate action Quality objective pass Candidate clears the quality floor, meets the required quality gain after accounting for sampling uncertainty, passes all critical checks, and stays within resource limits Pass the release gate and permit canary verification Cost objective pass Candidate reduces measured model spend (using model token pricing), clears the quality floor, stays within the allowed regression margin, and passes all critical checks Pass the release gate and permit canary verification Insufficient gain or savings Candidate misses the target quality gain or measured cost reduction Keep the baseline active Regression or critical failure Candidate drops below the quality floor or triggers repeated_submission , unverified_claim , or claim_state_mismatch Fail the workflow and block release Separate evaluation job health from agent task performance. Every test case must return a complete evaluation record and all required evaluator scores; missing records or failed evaluator jobs always block release. Score recorded agent execution errors (such as a malformed response) as task failures. This lets a candidate repair a broken baseline case, such as an illustrative outcome_unknown timeout retry. Fixing one failure mode alone does not satisfy every release requirement. In Figure 4, the gate blocks promotion when the run shows category regressions, excess token usage, or incomplete baseline evidence. Figure 4. GitHub Actions deploys the candidate version, blocks release when the held-out regression suite fails, and skips endpoint promotion. 6. Run a canary release, promote, and prepare the next cycle Passing the held-out regression suite provides evidence that the candidate meets the requirements covered by those tests. Verify live traffic in four steps before full promotion: Smoke-test the deployed version. Send synthetic sessions with version_indicator set to v2 to verify container startup, credentials, and tool connections. Route canary sessions against a live control. Microsoft Foundry hosted endpoints send 100 percent of default traffic to v1 . Set your minimum sample count, observation window, and thresholds before starting. Route a slice of new sessions ( 5% , then 25% ) to v2 via version_indicator alongside matching v1 control traffic. Wait for settled outcomes. Hold the canary stage until v1 and v2 collect enough continuous evaluation scores, Azure Monitor metrics, and settled refund outcomes. Promote, hold, or roll back: Canary and post-deployment evidence Release action Candidate meets quality, latency, and settled outcome thresholds against live v1 control traffic during the canary window Promote v2 by switching the Microsoft Foundry endpoint version selector to v2 for all new default sessions Sample size is still below the minimum count or asynchronous transactions are still settling Hold the current canary percentage and continue collecting evidence Candidate quality falls below the required floor, exceeds the allowed regression margin against control, or triggers critical tool errors or Azure Monitor alerts Roll back routing for new sessions to v1 , stop or drain active v2 sessions, and reconcile affected records Plan for both session routing and backend state during a rollback. During a canary, clearing version_indicator sends new sessions to the default version ( v1 ). After promotion, rolling back requires switching the Microsoft Foundry endpoint selector back to v1 . Existing v2 sessions continue on v2 until you stop them explicitly (for example, with project_client.agents.stop_session ) or let them drain. For transactions already submitted during the canary window, use backend idempotency keys and compensating reversals to keep customer records consistent. Reset the baseline and refresh held-out cases for the next loop After promoting v2 to 100 percent of default traffic, your release automation records its configuration in .agent_configs/baseline/ as the new comparison baseline. Keep v1 available until all in-flight v1 sessions finish. To keep the held-out regression suite representative of current traffic, periodically add fresh reviewed production traces to both your training datasets and your release suite. This reduces the risk of repeated candidate selection gradually overfitting a single fixed test set. Next steps: Implement continuous evaluation and CI/CD gating Use these paths to set up the workflow in Microsoft Foundry: Enable continuous evaluation and trace datasets. Configure production monitoring on your deployed agent and convert production conversations into trace datasets. Create your evaluation suite and custom evaluators. Prepare eval.yaml and datasets for Agent Optimizer, add custom evaluators, and run cloud evaluations. Optimize and automate CI/CD releases. Follow the Agent Optimizer overview, the optimization quickstart, and the hosted agent CI/CD guide to gate deployments in GitHub Actions.578Views0likes0CommentsArchitecting Multi-Agent Systems in Copilot Studio: Orchestration, Delegation, and Handoffs
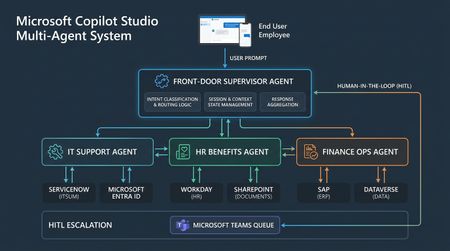
Executive Summary As enterprise conversational AI matures, organizations quickly run into the "Monolithic Agent Dilemma": a single bot tasked with answering IT questions, navigating HR benefits, generating financial forecasts, and resetting passwords quickly becomes unmanageable. Maintenance turns brittle, topic trigger collisions skyrocket, and system prompts balloon beyond effective context windows. The industry solution is Multi-Agent Architecture—decoupling monolithic agents into specialized, bounded worker agents governed by an intelligent supervisor agent. In this article, we break down how to architect, build, and deploy an enterprise-grade multi-agent ecosystem using Microsoft Copilot Studio, complete with orchestration patterns, state-passing best practices, and graceful human-in-the-loop (HITL) escalations. 1. The Architectural Shift: Monolith vs. Multi-Agent In traditional chatbot design, all logic resides in a single container. In a multi-agent system, agents mimic a real-world enterprise organizational chart with a Front-Door Supervisor Agent, specialized Worker Agents (IT, HR, Finance), and human escalation queues. Why Multi-Agent Wins for Enterprise: Separation of Concerns: HR teams maintain HR topics and knowledge; IT teams maintain infrastructure playbooks without cross-team deployment collisions. Isolated Context Windows: Worker agents only receive instructions and data relevant to their domain, reducing hallucination risks. Granular Security and DLP: IT agents can access privileged admin connectors, while HR agents operate under zero-trust privacy boundaries. Independent Versioning and ALM: Teams deploy updates to their specific agent solution without redeploying the entire company bot. 2. Core Architectural Roles: The Supervisor & Worker Agents The Supervisor Agent (The Front-Door Concierge) Acts as the primary endpoint interacting with end users across Microsoft Teams, web portals, or M365 Copilot. Greeting and persona consistency. Ambiguity clarification and intent routing. Shared state and session tracking. Handoff management and post-execution response synthesis. Worker Agents (Domain Specialists) Focused task-solvers that execute deterministic workflows or specialized generative actions: Identity and Access Agent: Handles Entra ID group requests, MFA resets, and licensing checks. Travel and Expense Agent: Inspects corporate travel policy, checks receipts, and posts expense reports. Knowledge Agent: Connects to specific Graph connectors and Azure AI Search indexes with targeted grounding. 3. Communication & Delegation Patterns Pattern 1: Direct Sub-Agent Invocation (Agent-as-a-Tool) How it Works: The supervisor agent registers worker agents as callable tools or custom actions via OpenAPI or Power Automate. Best Used For: Fast, single-turn tasks where worker agents return structured data to the supervisor. Pattern 2: Bot-to-Bot Protocol / Skills How it Works: The supervisor connects to worker agents registered as Bot Framework Skills using Direct Line or App Registrations. Best Used For: Long-running multi-turn dialogs where the worker temporarily takes over the conversation canvas. Pattern 3: Event-Driven Orchestration via Dataverse How it Works: Tasks are logged to an audit table in Dataverse; background agents pick up requests asynchronously and notify the user via Adaptive Cards. Best Used For: Asynchronous workflows requiring multi-approver sign-off or external job completion. 4. State & Context Passing: Avoiding the "Amnesia Problem" The biggest challenge in multi-agent handoffs is loss of context. If a user reports a specific VPN error code, transferring them to the IT Agent with a blank state causes the bot to ask the user to repeat themselves. Solution: Context Packet Schema When transferring between the Supervisor and Worker Agent, serialize and pass a structured JSON Context Payload: json { "sessionId": "conv-98421-m365", "initiator": { "userId": "user_aad_guid_12345", "upn": "email address removed for privacy reasons", "department": "Engineering", "locale": "en-US" }, "intent": { "domain": "IT_Support", "subCategory": "VPN_Diagnostics", "confidence": 0.94 }, "extractedEntities": { "errorCode": "800", "clientOs": "Windows 11 Enterprise", "initialQuery": "My VPN is failing with error 800, can you help me fix it?" } } Implementing in Copilot Studio: In the Supervisor Agent, capture global variables (such as Global.UserContext and Global.ExtractedProblem). When calling the Worker Action or Skill, map these global variables into the worker's Input Arguments. In the Worker Agent, configure the topic to check incoming arguments: if errorCode is already populated, skip intake questions and begin diagnostics immediately. 5. Designing Graceful Fallbacks & Human-in-the-Loop (HITL) Multi-agent systems require a fault-tolerant escalation pipeline when automated resolution confidence falls below threshold. Best Practices for Human Escalation: Warm Handoffs Only: Never dump a cold transfer. Always attach the transcript, attempted diagnostic steps, and error codes. Microsoft Teams Shared Channels: For internal support, dispatch escalation Adaptive Cards into a private Support Teams channel where engineers can claim the ticket with one click. Omnichannel for Customer Service: Utilize Copilot Studio's native integration with Dynamics 365 Omnichannel to pass live chats with full routing rules. 6. Security, DLP, and Governance Guardrails Data Loss Prevention (DLP) Isolation: Assign worker agents to dedicated Power Platform environments based on their data classification tier. General environments handle read-only FAQ and public knowledge; high-privilege environments handle Active Directory changes and ERP transactions. Prompt Injection Resilience: The Supervisor agent must sanitize freeform inputs before passing them into sub-agent prompts. Audit Trails: Log every agent-to-agent delegation event in Dataverse with execution timestamps, latency, and token consumption metrics. 7. Implementation Checklist Audit Your Current Bot: Identify topics with high trigger overlap and cluster them by business domain. Define the Supervisor Contract: Standardize a JSON schema for user identity, intent, and parameter passing. Build Your First Worker Agent: Start with a high-volume, bounded domain like IT Service Desk or Password Management. Implement Tool Calling: Register the worker agent as a callable action inside your front-door supervisor. Test Edge Cases: Validate that multi-turn dialogs maintain context and unknown intents gracefully route back to human triage. Join the Discussion Have you implemented multi-agent architectures in your tenant? How are you handling state transfer and DLP across specialized bots? Share your thoughts and architectural questions in the comments below!252Views0likes0CommentsInformation Extraction with Low-Inference-Cost Models: 85% F1 Gain via Foundry Interactive Training
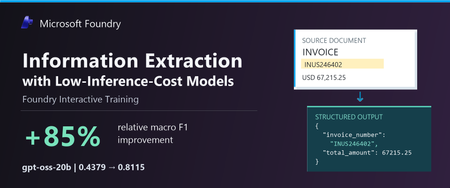
Authors: Shih-Yao Lin, Apurva Saksena The task: turn documents into structured data Many business workflows need to turn documents into structured data. The model must find the right values, capture the requested records, and return output the next system can use. Long documents and repeated tables make this harder. We tested gpt-oss-20b and gpt-oss-120b to explore lower-cost alternatives to frontier models. In our baseline tests, both fell short on field coverage. gpt-oss-20b also declined the task or returned unparseable output. We wanted to see whether task-specific fine-tuning could improve these results. In Figure 1, we show an invoice that we held out from training. We can quickly spot the invoice number, customer, due date, and balance, but our application must map those values to the correct schema fields, preserve all 37 line items, and return complete, valid JSON. A wrong or missing value can trigger downstream errors or manual review, while invalid JSON can break the workflow altogether. We used schema-guided extraction. We gave the model document text and a JSON Schema defining the required fields, then asked it to return one JSON object. Our grader compared normalized field-path/value pairs with the expected answer, counting repeated occurrences. We measure precision as the share of extracted pairs that match the expected answer, and recall as the share of expected pairs we recover correctly. We use F1 to combine the two into one score, using their harmonic mean. F1 ranges from 0 to 1, with higher scores indicating better extraction. A wrong value hurts precision and can also hurt recall if the expected value remains unmatched. A missing value hurts recall. What changed after fine-tuning We evaluated the base and fine-tuned versions of gpt-oss-20b and gpt-oss-120b on the same 20 documents. Both improved their extraction F1. gpt-oss-20b rose from 0.4379 to 0.8115, and gpt-oss-120b rose from 0.6816 to 0.8573. gpt-oss-20b made the larger gain, with an 85.3% relative improvement after 100 GRPO steps. Fine-tuned gpt-oss-120b finished with the higher F1. Fine-tuning helped both models, but the size of the improvement differed. We also evaluated GPT-5.5, GPT-5.6-sol, and GPT-6-sol as reference models. They scored 0.9760, 0.9766, and 0.9764, respectively—still higher than our fine-tuned models. gpt-oss-20b reached 83.1% of GPT-5.6-sol’s reference F1. This is a substantial improvement for gpt-oss-20b and a promising starting point for further task-specific tuning. Our base and tuned scores are averaged across repeated evaluations, while the reference models used a different single-pass protocol. These reference scores provide useful context for the progress we made, with the evaluation differences noted above. These improvements make lower inference-cost base models worth a closer look. Table 1 compares published Azure inference prices. The pricing comparison is intended to provide inference-cost context only and should not be interpreted as a complete total-cost-of-ownership analysis, which would also include training, hosting, retries, and operational costs. Table 1. Extraction macro F1 and published Azure inference prices (USD per 1M tokens); GPT-5.5, GPT-5.6-sol, and GPT-6-sol are included as frontier-model references Model Macro F1 Azure input / 1M Azure output / 1M gpt-oss-20b 0.8115 $0.07 $0.30 gpt-oss-120b 0.8573 $0.15 $0.60 GPT-5.6-sol 0.9766 $4.00 $20.00 GPT-5.5 0.9760 $5.00 $30.00 GPT-6-sol 0.9764 $2.00 $10.00 Notes: Prices checked October 9, 2026, in USD; input rates are uncached. gpt-oss-20b prices are published fine-tuned inference rates for Regional deployments. gpt-oss-120b prices are base-model rates; its fine-tuned rates remain unconfirmed. Frontier prices use Global Standard pricing, with the short-context tier for GPT-5.6-sol and GPT-6-sol. These rates do not represent measured deployment costs for our experimental checkpoints. Token rates exclude training and hosting costs. F1 scores come from fine-tuned checkpoints for the two gpt-oss models and reference runs for the frontier models. All use the same 20 documents, but tuned scores average repeated evaluations while frontier references use a different single-pass protocol. We observed more parseable output and higher coverage We looked through gpt-oss-20b’s responses and found examples where it declined the task or said it could not finish. We tracked this with a “refusal-wording rate”: the share of responses where our grader detected an apology or cannot-complete language. This measures wording, not whether the model made a safety refusal. We tracked JSON parseability and field coverage separately, although these problems can overlap. After fine-tuning, the refusal-wording rate (Refusals) fell from 25% to zero; JSON parseability (Valid JSON) rose from 63.8% to 98.8%, and coverage rose from 47.1% to 94.9%. Valid JSON means our grader could read the response as an object or array. Coverage compares the number of predicted field/value pairs with the expected count, capped at 100%. Wrong or extra pairs can raise coverage, so we read it alongside F1 rather than treat it as a measure of correctness. Extraction quality and output behavior before and after fine-tuning on the same 20 documents. Bars show means across repeated evaluations. “Valid JSON” measures JSON parseability, not schema compliance or value correctness. “Refusal rate” measures detected refusal wording, not safety refusals. Higher is better except for refusal rate. Figure 4 shows how these measures changed during training. We repeated the full training run with a second seed. It reached 0.8101 F1, close to the headline run’s 0.8115. We ran four temperature-0 evaluations for each seed. Across all eight post-training evaluations, our grader detected no refusal wording. What we learned from the model comparison We saw different starting points and different gains between the two models. gpt-oss-20b had clearer output problems before training: it sometimes declined the task, returned unparseable JSON, or missed required information. After fine-tuning, we saw improvements in extraction F1, JSON parseability, and field coverage, along with less refusal wording. gpt-oss-120b started with fewer format problems. We detected no refusal wording, and 96.3% of its baseline responses were parseable JSON. But parseable output did not mean complete or correct extraction. After fine-tuning, its field coverage rose from 74.1% to 94.1%, and its F1 rose from 0.6816 to 0.8573. gpt-oss-20b made the larger F1 gain, while fine-tuned gpt-oss-120b finished with the higher F1. For us, the lesson is to measure the problem first. Try simpler, lower-cost changes, such as prompting, before committing to training. Then consider fine-tuning when your grader can reward the improvements your application needs. How we trained with Foundry Interactive Training We used the Foundry Interactive Training API [1] with 17 training documents, expected structured answers, and a Python grader. We followed the cookbook to connect our grader to Foundry’s managed generation and training operations. We ran 100 group relative policy optimization, or GRPO, steps and saved checkpoints for evaluation. For each document, we had gpt-oss-20b generates eight candidate answers. Our grader awarded partial credit for correct values and penalized invalid JSON. GRPO used the candidates’ relative scores to reinforce better answers. We used the expected answers only for grading. We did not include them in the inputs we gave the model during reinforcement training. The model had to produce its own answers, and the grader supplied the feedback. 5. Customers define the application outcome and quality bar; Foundry Interactive Training runs the post-training loop in Microsoft Foundry. How customers can use Foundry Interactive Training To try this approach, bring four ingredients: a supported base model, examples from your workload, expected outcomes, or another way to check the answers, and a Python grader. Your grader should measure what matters to the application—not just whether an answer looks convincing. To prepare your extraction data and establish a baseline, start with the ExtractBench text-evaluation sample. It includes data preparation, an extraction grader, and evaluation of F1, refusal wording, JSON parseability, and field coverage. The sample covers preparation and evaluation only; follow the onboarding cookbook below for training. Get connected. Request access to the Microsoft Foundry Interactive Training public preview [2] and connect the onboarding cookbook [3][4] to an assigned Foundry project. Separate your data. Build training, validation, and final test sets. Use validation data to choose checkpoints. Keep the final test set for an independent check, with new sources and document structures where possible. Build your grader. Implement a grader that rewards the desired outcome. For our extraction task, we checked normalized field-path/value pairs and penalized unparseable JSON. Run a bounded experiment. Set a training budget, inspect the training signal, and compare saved checkpoints on the validation set. Once you choose a checkpoint, evaluate it on the untouched final test set. Evaluate and prepare for deployment. Use session sampling to test your LoRA adapter on held-out prompts and compare it with the baseline. Save checkpoints so you can continue experimenting. Before using the model in an application, confirm the supported deployment path, model compatibility, and serving costs. Takeaway With Foundry Interactive Training, we improved extraction F1 for both gpt-oss-20b and gpt-oss-120b. We brought our task examples and a Python grader, and Foundry managed the generation and training loop. gpt-oss-20b made the larger gain, while fine-tuned gpt-oss-120b reached the higher F1. We did not match the frontier references, but our results show why task-specific fine-tuning is worth exploring before switching to a higher-priced model. The final choice should depend on independently tested quality and the full cost of deployment. Reference [1] https://github.com/microsoft-foundry/fine-tuning [2] What is interactive training (preview) in Microsoft Foundry? - Microsoft Foundry | Microsoft Learn [3] Interactive Training - Public Preview Intake Form [4] https://github.com/microsoft-foundry/fine-tuning/tree/main/interactive_training How to Cite If you find this work useful, please consider citing this article: MISC{lin2026informationextraction, title = {Information Extraction with Low-Inference-Cost Models: 85\% {F1} Gain via {Foundry Interactive Training}}, author = {Lin, Shih-Yao and Saksena, Apurva}, year = {2026}, howpublished = {Microsoft Azure AI Foundry Blog}, url = {https://techcommunity.microsoft.com/blog/azure-ai-foundry-blog/information-extraction-with-low-inference-cost-models-85-f1-gain-via-foundry-int/4563661} }642Views0likes0Comments
All Copilot Studio Workflow Tools Suddenly Returning HTTP 403 Before Execution
Hello Copilot Studio Community, I am experiencing an authorization issue with multiple workflows connected to an agent built using the Copilot Studio new experience and new Workflows experience. These workflows worked successfully for multiple users yesterday. Today, all workflow tools connected to the agent began returning an immediate HTTP 403 authorization error. I did not intentionally change the agent, workflows, environment, or workflow permissions before the issue started. Error message: You don’t have permission to use this tool. You’re signed in, but access to this resource is blocked. Error details: Authorization - 403 Example error information: Status: Failed Error message: Flow returned HTTP 403 Error code: Http403 Inner error code: NotSpecified Tool duration: Approximately 93 milliseconds Configuration: - Copilot Studio new agent experience - Copilot Studio new Workflows experience - Agent and workflows are in the same Power Platform environment - Workflows use the "When an agent calls the workflow" trigger - Each workflow includes a "Respond to the agent" action - Workflows are saved and published - Agent is saved and published Observed behavior: The problem affects several independent workflows, including: - New-request submission - Current-user identity resolution - Approval decisions - Requester justification - Executive decisions - Fulfillment updates For every affected workflow: - The agent fills the workflow inputs correctly. - The tool call fails almost immediately. - No corresponding run appears in the workflow Activity history. - The workflow trigger is never reached. - No workflow actions execute. Because no workflow run is created, the rejection appears to occur before workflow execution, possibly within the Copilot Studio agent-to-workflow authorization or invocation layer. Troubleshooting already completed: - Confirmed that all workflows are published. - Confirmed that the agent is published. - Tested in a completely new conversation. - Removed an affected workflow tool from the agent. - Saved the agent. - Added the same published workflow back to the agent. - Reconfigured and verified the tool inputs. - Republished the agent. - Confirmed that no workflow Activity run is created. - Confirmed that the issue affects multiple workflows rather than one specific workflow. Removing and re-adding the workflow did not resolve the problem. Questions for the community: 1. Is anyone else currently experiencing HTTP 403 errors when Copilot Studio agents invoke workflows? 2. Is this a known issue or regression in the new Workflows experience? 3. Is there an environment-level or tenant-level permission that controls agent-to-workflow invocation? 4. Could a tenant policy, Conditional Access change, service principal, connection reference, or workflow-sharing configuration cause all workflow tools to fail simultaneously? 5. Where can an administrator find detailed authorization logs when the workflow never creates a run? 6. Has anyone found a workaround for this issue? Any guidance or confirmation from others experiencing the same behavior would be appreciated. I can provide screenshots, complete error details, timestamps, and additional configuration information if needed. Thank you.876Views3likes4Comments