evaluation
46 TopicsThe Future of AI: Harnessing AI for E-commerce - personalized shopping agents
Explore the development of personalized shopping agents that enhance user experience by providing tailored product recommendations based on uploaded images. Leveraging Azure AI Foundry, these agents analyze images for apparel recognition and generate intelligent product recommendations, creating a seamless and intuitive shopping experience for retail customers.2.1KViews5likes3CommentsThe Future of AI: The Model is Key, but the App is the Doorway
This post explores the real-world impact of GPT-5 beyond benchmark scores, focusing on how application design shapes user experience. It highlights early developer feedback, common integration challenges, and practical strategies for adapting apps to leverage the advanced capabilities of GPT-5 in Foundry Models. From prompt refinement to fine-tuning to new API controls, learn how to make the most of this powerful model.893Views4likes0CommentsClosing the AI Agent Governance Gap with Microsoft Foundry
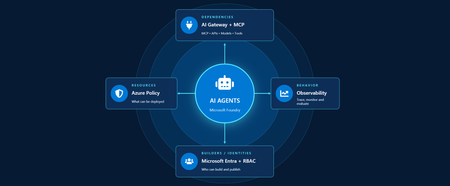
Developers are shipping agents faster than security teams can catalog them. As organizations move beyond pilots and begin operating dozens or hundreds of agents, one question keeps coming up: how do we actually get visibility into our AI agents across our environment? In this article, we'll walk through how Azure services can help establish visibility, guardrails, and cost accountability across your AI estate. Governance for AI happens across four layers: Resources – who can create new AI resources Builders – who can develop and publish agents in a certain scope Behavior – how agent outputs are evaluated, monitored, and governed Dependencies – what models, tools, APIs, and MCP servers agents can interact with Most organizations already have governance controls for identities, networking, and compliance. The challenge isn't creating new controls. It's connecting existing controls into an operating model that works for AI agents. Below we walk through each area and go a bit deeper on how to close the gap. Setting up boundaries with Azure Policy First, let's start in the Azure portal with Azure Policy. Azure Policy lets you set guardrails on what can be deployed in your environment and flags or blocks anything that doesn't comply. For AI workloads, the built-in definitions range from limiting models that people in your organization can deploy to locking down the network through enabling private endpoints. Some policies you get started with: Foundry model deployments should only use approved models: Restricts deployments to models or publishers your organization has explicitly approved Foundry model deployments should meet eligibility requirements (preview): Applies rules based on model attributes like preview vs. GA status and distribution source Azure AI Services resources should have key access disabled: Makes Microsoft Entra ID the only entry point The full list of policies related to Azure AI Services are available here: List of built-in policy definitions - Azure Policy | Microsoft Learn Why this comes first: Policy checks resources before they are created, so it proactively keeps your environment aligned with your standards. Implementing role-based access control (RBAC) Once these boundaries are in place, the next step is RBAC. Setting RBAC up early ensures that people and identities building agents have the right scope for what they actually need to do. Foundry roles only apply when you authenticate using Microsoft Entra ID. If you're using key-based authentication instead, the key grants full access with without role restrictions. API keys are convenient for quick development usage but when moving towards production, Microsoft Entra ID is the preferred method. Roles can be assigned at three scopes: the Foundry resource, a Foundry project, or an individual agent itself. Below is an example of how different personas within organization can map to a certain scope for creating and building agents with Foundry. Here's how each role in the diagram compares, from least to most privileged: Role Privilege Level What it does in Microsoft Foundry Foundry Agent Consumer Least Interact with agent endpoints in a project. This is your least-privilege role for people who only need to use agents. Foundry User Low Grants reader access to the Foundry project, the Foundry resource, and data actions for your Foundry project. Least-privilege access role for developers building and testing agents. Foundry Project Manager Medium This role lets you perform management actions on Foundry projects, build and develop with projects, and conditionally assign the Foundry User role to other user principals. Foundry Account Owner Higher Grants full access to manage Foundry projects and resources, and lets you assign the Foundry User role to other user principals. Foundry Owner Highest Grants full access to manage Foundry projects and resources to build and develop with projects. This role can also assign the Foundry User, ACR, and monitoring roles to users in the environment. Source: Role-based access control for Microsoft Foundry - Microsoft Foundry | Microsoft Learn For the agent resources themselves, assign managed identities rather than API keys since it lowers the risk of having compromised credentials. Note if you're scripting RBAC permissions: these roles were recently renamed from Azure AI User, Azure AI Owner, Azure AI Account Owner, and Azure AI Project Manager. The role IDs and permissions didn't change, so use the role definition GUID in your code to avoid issues while the rename rolls out. Observability in Microsoft Foundry Governance requires more than access control. Organizations also need evidence of how agents are being used. Observability provides the audit trail needed to investigate incidents, understand usage patterns, and track costs. The Foundry Control Plane brings these observability and governance tools together in one place, alongside services like Azure Monitor, Microsoft Entra, Microsoft Purview, and Azure Policy. In the Foundry portal, tracing is a good starting point. Once you connect an Application Insights resource to your project, Foundry turns on tracing automatically so every run, including the ones you test in the playground, is logged. After it is completed, you can search by Response ID or Trace ID to see the conversation history, token usage, run steps, tool calls, and inputs and outputs between the user and the agent. For more granular queries, you can write KQL to dive into individual agent runs or use the prebuilt Grafana dashboards in Azure Monitor. With client-side tracing, you can also export traces to observability tools you may already use, such as Datadog or Jaeger. Note: Permissions required for viewing this telemetry requires the Log Analytics Reader role on the connected Application Insights resource, and Privileged Monitoring Data Reader on top of that if the underlying Log Analytics tables are protected. Alongside all of these monitoring features, every agent comes with content safety guardrails and evaluations let you test and optimize performance before and after you publish your agents. When agents get published to Microsoft Teams and Microsoft 365 Copilot, Microsoft 365 admins can approve usage requests. These requests can be further scoped to a limited group for pilot testing/department usage or the full organization. Adding an AI gateway Observability tells you what your agents are doing, but how do you actually control them? This is where Azure API Management comes in. Once you have more than one agent, model deployment, or multiple teams consuming them, you need a single enforcement point between the agents and the resources they call. Adding Azure API Management in front of Microsoft Foundry gives you: Rate limiting and load balancing across regions and model deployments Consistent authentication and quota policies for model and tool traffic Usage tracking per team or cost center so you can accurately charge back to different departments Governed access to your custom and remote MCP servers Note: When choosing MCP servers, start with trusted, enterprise supported sources (GitHub, Microsoft, internally developed servers, etc.) that have documented security controls, enterprise authentication, clear ownership, and least-privilege permissions. Treat community MCP servers as untrusted until they have undergone a formal security review and are verified by organizations. Adding an AI gateway completes the governance picture. Azure Policy governs what can be deployed. RBAC governs who can build and manage agents. Observability provides evidence of how agents behave in production. The AI gateway extends governance into runtime, controlling how agents interact with models, tools, and external systems. Combined, these layers help organizations move beyond simply building agents to operating them responsibly at scale. Extend governance across the wider estate A few directions to take this further: MCP registry in Azure API Center – As MCP usage grows, you can create an approved inventory of MCP servers and APIs that can be used across an organization. Microsoft Agent 365 – Microsoft's enterprise control plane for AI agents. It gives every agent its own Microsoft Entra Agent ID and published Foundry agents sync to its registry automatically. This gives your IT team one place to run access reviews, lifecycle policies, and owner attestation across every agent in the tenant, including shadow agents discovered outside Foundry. Copilot Studio – when you add an MCP tool, you can point it at the API Management URL instead of the direct remote endpoint to gain additional observability through the gateway. GitHub Copilot – you can apply the same AI gateway-fronted MCP registry, applied to the developer side. Microsoft Purview – data classification, DLP, audit, and AI interaction governance across the wider estate. Where to go next Looking for a quick start? Turn on the three Azure Policy definitions above in audit mode against a non-production subscription and see what gets flagged that is out of compliance. Ready to design the end-to-end pattern? Take a look at this Cloud Adoption Framework guidance on AI governance and governing Azure platform services for AI. Want to go deeper on agent observability? Start with these articles around Application Insights integrations with Foundry: Use Insights in Microsoft Foundry and Monitor AI Agents with Application Insights Governing AI agents doesn't require starting from scratch. The identity, policy, monitoring, and cost controls you already use for the rest of your Azure estate can extend to AI workloads. Start with one layer, connect the next, and build a governance foundation that grows with your AI adoption.326Views3likes0Comments
What is the best file format for an AI agent knowledge base?
This is a best practice sharing the best format for an agent and show you why you should convert your PPT, PDF, WORD into a TXT markdown. I had an issue with my agent, time taken to answer was too long, and usually we spend a lot of time asking: What is the best prompt? Why is my agent slow? Why does retrieval sometimes work and sometimes fail? How can I improve answer quality? But I realised I was asking another question much less often: What is actually the best file format for the knowledge base? PDF? Raw text? Markdown? Pre-chunked text? Semantic sections? Context-enriched text? And more importantly: How much does the format alone affect agent performance? I tried to find a quantified benchmark answering this specific question, with the same agent, same source knowledge and same questions, but different knowledge representations. I couldn't find one that really answered what I wanted to measure. So I decided to run the experiment myself on a real case. My first exploratory tests were already surprising: depending on the representation, the agent could be significantly faster and more accurate, despite working from the exact same source information. So I decided to push the test further. My objective I want to identify, without assumptions and based on actual evaluation data, how a long document should be prepared for an LLM knowledge base so that the agent can retrieve, understand, ground and answer from it as reliably as possible. I focused on five dimensions: Answer quality Retrieval reliability Source grounding / citations Execution time Robustness across single-turn and multi-turn questions The broader question I'm trying to answer is: How should we structure knowledge so that an LLM can retrieve and use it as reliably as possible? The test case I deliberately chose a document that isn't particularly friendly for RAG: a 46-page European regulation, https://eur-lex.europa.eu/eli/reg/2011/1169/oj?locale=fr, on the provision of food information to consumers. The information is distributed across articles, definitions, exceptions, annexes, tables, numerical thresholds and cross-references. That makes it useful for testing retrieval: answering correctly often requires finding a very specific piece of information while preserving enough context to understand how it applies. I used the native PDF as the baseline and created 6 additional knowledge-base representations of the same document: Raw TXT Markdown Chunk-ready TXT RAG-oriented units Semantic TXT Contextual TXT One rule: same knowledge, same agent, same instructions, same questions. Only the knowledge representation changes. The benchmark I used two evaluation sets: 42 single-turn questions testing broad coverage of the document: direct facts, thresholds, exceptions, annexes, lists and cross-references. 5 multi-turn conversations containing 13 questions, to see what happens when a user asks a question and then follows up with things like: "And in this case?" "What are the exceptions?" "And for dietary fibre?" This gave me: 47 evaluated test cases / 55 actual questions per format Across all 7 formats: 329 evaluated conversations 385 user questions executed First results Metric Native PDF Best structured representation Overall pass rate 66.0% 85.1% - Contextual TXT Best single-turn score 69.0% 88.1% - Chunk-ready TXT Multi-turn benchmark 40% 80% - Contextual TXT Multi-turn execution time 14m24 5m54 Total benchmark time 44m31 24m49 The quality gap was already substantial: 66.0% → 85.1% That's +19.1 percentage points while keeping the underlying knowledge unchanged. I also saw a major difference in execution time. On the multi-turn test: 14m24 → 5m54 That's approximately 2.4× faster. Across the complete benchmark: 44m31 → 24m49 Around 44% less execution time. These timings represent the complete agent evaluation pipeline, so they shouldn't be interpreted as pure LLM inference latency. But the difference under identical test conditions is large enough that I want to understand it better. Findings There wasn't one format dominating every benchmark. Chunk-ready TXT scored highest on independent questions: 88.1%, while Contextual TXT performed better across multi-turn conversations and finished with the highest overall score. That may suggest that the way we optimise a document for isolated retrieval isn't exactly the same as the way we should prepare it for conversational retrieval. In the contextual version, I tried to make every section understandable when retrieved independently by keeping useful information around it: Source references Section context Retrieval cues Relevant cross-references For regulatory documents, this seems particularly important. A numerical value retrieved alone can be meaningless without knowing which rule it belongs to, under which conditions it applies, and whether another article contains an exception. Where I am now This remains an exploratory benchmark: One document One domain One agent setup One evaluation framework One run per configuration There are plenty of things I still want to test: repeated runs, retrieval-level evaluation, token consumption, larger knowledge bases, other document types, chunk sizes, overlap, contextual headers, and more. But these first results already convinced me that the preparation of the knowledge base deserves much more attention when evaluating an agent. We often spend hours refining instructions while the same information may behave very differently depending on how it reaches the retrieval layer. Next step I'll share the prompts, knowledge-base formats and evaluation methodology on GitHub so the experiment can be reproduced and challenged. I'll keep enriching the repository as I test new formats, improve the evaluation set and add new results. If people here have ideas, edge cases or formats worth testing, I'd genuinely like to include some of them in the next iteration. What would you test next?848Views3likes3Comments
All Copilot Studio Workflow Tools Suddenly Returning HTTP 403 Before Execution
Hello Copilot Studio Community, I am experiencing an authorization issue with multiple workflows connected to an agent built using the Copilot Studio new experience and new Workflows experience. These workflows worked successfully for multiple users yesterday. Today, all workflow tools connected to the agent began returning an immediate HTTP 403 authorization error. I did not intentionally change the agent, workflows, environment, or workflow permissions before the issue started. Error message: You don’t have permission to use this tool. You’re signed in, but access to this resource is blocked. Error details: Authorization - 403 Example error information: Status: Failed Error message: Flow returned HTTP 403 Error code: Http403 Inner error code: NotSpecified Tool duration: Approximately 93 milliseconds Configuration: - Copilot Studio new agent experience - Copilot Studio new Workflows experience - Agent and workflows are in the same Power Platform environment - Workflows use the "When an agent calls the workflow" trigger - Each workflow includes a "Respond to the agent" action - Workflows are saved and published - Agent is saved and published Observed behavior: The problem affects several independent workflows, including: - New-request submission - Current-user identity resolution - Approval decisions - Requester justification - Executive decisions - Fulfillment updates For every affected workflow: - The agent fills the workflow inputs correctly. - The tool call fails almost immediately. - No corresponding run appears in the workflow Activity history. - The workflow trigger is never reached. - No workflow actions execute. Because no workflow run is created, the rejection appears to occur before workflow execution, possibly within the Copilot Studio agent-to-workflow authorization or invocation layer. Troubleshooting already completed: - Confirmed that all workflows are published. - Confirmed that the agent is published. - Tested in a completely new conversation. - Removed an affected workflow tool from the agent. - Saved the agent. - Added the same published workflow back to the agent. - Reconfigured and verified the tool inputs. - Republished the agent. - Confirmed that no workflow Activity run is created. - Confirmed that the issue affects multiple workflows rather than one specific workflow. Removing and re-adding the workflow did not resolve the problem. Questions for the community: 1. Is anyone else currently experiencing HTTP 403 errors when Copilot Studio agents invoke workflows? 2. Is this a known issue or regression in the new Workflows experience? 3. Is there an environment-level or tenant-level permission that controls agent-to-workflow invocation? 4. Could a tenant policy, Conditional Access change, service principal, connection reference, or workflow-sharing configuration cause all workflow tools to fail simultaneously? 5. Where can an administrator find detailed authorization logs when the workflow never creates a run? 6. Has anyone found a workaround for this issue? Any guidance or confirmation from others experiencing the same behavior would be appreciated. I can provide screenshots, complete error details, timestamps, and additional configuration information if needed. Thank you.617Views3likes3CommentsAutomate Quota Discovery in Azure AI Foundry: A Tale of 3 APIs
Automate the discovery of Azure regions that meet your AI deployment needs using three essential APIs: Models API, Usages API, and Locations API. This process helps reduce decision fatigue and ensures compliance with enterprise-wide model deployment standards. Key learnings: Model Deployment Requirements: Understand the needs of a standard Retrieval-Augmented Generation (RAG) application, which involves deploying multiple models. Automation Benefits: Streamline your deployment process and ensure compliance with enterprise standards. Three Essential APIs: Models API: Query available models for a specific subscription within a chosen location. Usages API: Assess current usages and limits to infer available quotas. Locations API: Obtain a list of all available regions. A comprehensive Jupyter notebook with the implementation steps is available in the accompanying GitHub repository. This resource is invaluable for AI developers looking to streamline their deployment processes and ensure their applications meet all necessary requirements863Views3likes0Comments
Your Agents Need More Than a Place to Run
In architecture reviews with enterprise teams moving their first agentic applications toward production, I often hear the same plan: the team has containerized their agent and intends to run it on the managed Kubernetes cluster the organization already trusts. The reasoning is sensible, since the platform team knows the tooling and security has approved the network model, and for the first use case or two it is often the right call. Having watched this unfold in my years leading AgenticAI customer engineers and forward deployed engineers, and now helping customers reach production on Azure, I want to describe what happens next, before leaders commit rather than after. One thing to note is Azure supports multiple ways to build and operate agents. Foundry Agent Service provides an integrated managed runtime around your agent code. Azure Kubernetes Service supports teams that need Kubernetes-level control or want to extend an established platform, while Azure Container Apps provides managed container hosting. These services can work together. The decision is which capabilities and responsibilities best fit the workload. Where the cluster is the right answer A stateless retrieval application, a document extraction pipeline, or a classification job is a web service that happens to call a model, and a container platform runs web services well. A large retail customer of mine ran an invoice extraction agent on containers for over a year with almost no issues, and I never suggested they move it. The cluster remains the right home for several other situations as well. LLM invocations embedded inside existing microservices, event driven, or batch pipelines fit container platforms naturally. Genuine constraints such as air-gapped or sovereign environment, regions where a managed service is not yet offered are a good reason to run your own stack, and strong engineering team that already operates at that level can be a real asset. Even when the agents themselves move to a managed runtime, the tool servers, business APIs, and data services those agents call, often stay on your cluster, so they are complementary far more often than they are competitors. The problem is that these early wins can make agents seem like just another workload. Where the wheels come off The first failure is the state. A research agent that plans, searches, and synthesizes for ninety minutes is a long-running stateful process, while a Kubernetes pod is a disposable container the scheduler may restart at any time. A financial services team I worked with lost costly research run to a routine node upgrade, and responded as capable engineers do by building checkpointing, a durable store, and a resume mechanism. It worked, but they now owned a piece of infrastructure they had to keep correct as their agent's framework changed beneath it. A managed agent runtime absorbs this. Hosted agents in Foundry Agent Service, as one example, give every session a VM-isolated sandbox with a persistent file system, a durable state store that survives crashes and restarts and can hold checkpoints for frameworks such as LangGraph or Microsoft Agent Framework, and a resilient execution mode that recovers long-running work after a process interruption. The second is the human-in-the-loop. A commercial insurance customer’s claims agent needed sign-off from an adjuster and sometimes a second reviewer, with days between steps. Stopping an agent cleanly at the moment it needs a decision, holding its full session for four days without paying to keep it running, and resuming it correctly when the approval arrives is not something a container orchestrator gives out the box. The team built agent session suspend and resume, a queue, a durable state store, notifications, and an approval interface, and ended up with a small workflow engine nobody had planned to own. In hosted agents, an idle session is deprovisioned with its state persisted and restored onto fresh compute when the same session ID returns, so an agent waiting on an approval cost nothing while it waits, and sessions are retained for up to thirty days of inactivity. The approval experience remains yours to design, which is where your engineers' time should go. The third is multi-turn conversation, which quietly pushes teams into building their own context management system. The first version appends each turn to history, and within few turns the history outgrows the context window while cost and latency climb. So, the team adds truncation, then summarization, then retrieval of earlier turns, then per-user and per-tenant scoping, then expiry and deletion rules for privacy. An industrial customer's safety compliance assistant, with conversations stretching across days, followed exactly this path and ended up with a bespoke thread store and summarization pipeline nobody had budgeted for. Its first serious incident came when a summary silently dropped a compliance-relevant instruction. With the Responses protocol in hosted agents in Foundry, conversation history is a durable, platform-managed record keyed by a conversation ID and reachable from any channel, so the thread store is no longer yours to build, although deciding what to summarize or retrieve remains a design choice for your agent. The fourth is identity. On a cluster, the path of least resistance is a shared service account, and in one review a security architect asked which actions had been taken on behalf of which user, only to learn that the logs could not say. Hosted agents create a dedicated Microsoft Entra agent identity for each agent at deploy time, use on-behalf-of flows to act with the user's delegated permissions in interactive scenarios and the agent's own identity in autonomous ones, and keep the agent identifiable for audit in both cases. The fifth is per-user session isolation, which is the difference between an agent that serves many people and an agent that mixes them up. Agents read files, run code, and hold working data, and on a shared pod the default is that many users share a process, a file system, and often a cache. Giving every user session its own sandboxed environment and storage, so that one person's documents and intermediate results can never surface in another's, means engineering hard isolation boundaries and proving them to your security team. Hosted agents make a VM-isolated sandbox per session the default, and their durable state store can partition items per end user, so one store is safe to share across the users of a multitenant agent. And lastly, Evaluation and optimization are where the gap widens. The largest difference between teams that scale and those that stall is evaluation. Because agents are probabilistic and multi-step, staging tests often miss failures such as a wrong tool choice or a policy violation deep in a task. One customer’s agent passed every offline check but degraded unnoticed for weeks after a model update because evaluation stopped at release. Mature teams continuously evaluate production traces, combine automated judges with sampled human review, and red-team regularly.Once quality is measurable, teams can deliberately balance prompts, models, tools, latency, and cost. One team cut per-task cost by routing simple steps to smaller models after evaluation confirmed quality held. Self-built stacks require teams to assemble and maintain tracing, datasets, judges, and release gates. Hosted agents instead combines default OpenTelemetry traces with continuous evaluation, adversarial testing, and datasets generated from agent instructions. Staged closed-loop optimization uses those traces to improve instructions, tool descriptions, and model selection without extra plumbing. The real cost is the velocity gap Leaders usually expect me to quantify the initial build, and that is the smaller number. A team of four building the first agent often becomes ten or twelve within a year, and a growing share of them are maintaining a runtime for agents rather than building agents that serve the business. The enterprise has quietly created an internal agent infrastructure company in a field where the patterns for memory, tools, evaluation, and safety are rewritten every few months, while hyperscalers put hundreds of engineers on exactly this problem and ship at a cadence no single platform group can match. Foundry Agent Service, for instance, bundle content safety guardrails into the runtime and route outbound traffic through a customer virtual network, capabilities that platform teams otherwise assemble one integration at a time. This plumbing does not differentiate your organization, so the question is whether your scarcest engineers should spend years on it or on the workflows, data, and judgment only your company has. This is also why the technology companies held up as examples are a poor template. Many built their own runtimes because managed options did not yet exist and had large platform organizations to carry the load. Even they tend to invest in a custom runtime for the first handful of use cases and then migrate as managed services mature, because the maintenance burden compounds while the strategic value of owning the plumbing does not. What I would do as the leader I am not arguing against Kubernetes or for moving everything tomorrow. Comparable managed runtimes exist across the hyperscalers, and I use hosted agents as the running example only because it is the one I know best from the inside. Managed agent services are still maturing, some workloads have real data residency or customization needs, and abstraction always constrains something. What I am arguing for is a deliberate choice for each use case, guided by three questions: whether the agent must outlive a single request by running long, waiting on humans, or remembering across sessions whether it must act with its own identity, auditable delegation, and policy enforcement whether your team would be building anything a managed service already provides, and who will still maintain it in two years. Key takeaways Match the runtime to the workload. Containers on your existing cluster suit stateless, short-lived agents, while long-running, human-in-the-loop, and memory-dependent agents need capabilities your platform team was never hired to build. Count the hidden team. The real cost of self-hosting is the growing group of engineers maintaining state, identity, memory, guardrails, and tracing instead of solving business problems. Make evaluation continuous and connected to production traces. Pre-release testing alone will miss the drift and trajectory failures that hurt you, and optimization of quality, cost, and latency depends on that evaluation data. Follow the pattern of the leaders, not their early architecture. Companies that built custom runtimes did so before managed options matured, and most of them move toward managed services as those options improve. A practical place to begin is your roadmap for the next twelve months. Sort each use case into stateless and short-lived or long-running and human-dependent, and for every agent in the second group put a price on the engineers who would maintain the runtime rather than the business logic. I would like to hear how you have drawn this line, and where a managed service was not yet ready for something you needed.600Views2likes0CommentsUnanswered Questions on GitHub Copilot Harness in Copilot Studio
We're piloting the GitHub Copilot harness in Copilot Studio (GA August 2026) and several operational and architectural details remain undocumented in the GA FAQ, Microsoft Learn, or licensing guides. Looking for official answers or PM contacts on: Architecture & Execution – When the harness breaks tasks into subtasks, does it use internal sub-agents or only skills/connected agents, what are the exact timeout/retry/max-execution-duration limits for long-running workflows, and are planning/context-retrieval/orchestration internals documented anywhere or is the orchestrator a black box? Model Selection – Can individual skills within one agent use different models or is selection strictly agent-level, how are models chosen internally when multiple skills execute, are any internal models developer-configurable, and what's the roadmap for models being added/retired/deprecated plus the lag between public release and Copilot Studio availability? Cost & Token Optimization – How exactly is the ~45% token reduction achieved, how much control do makers have over context/caching/retrieval/tool calls, what are per-model credit consumption characteristics, which models are most cost-effective for specific workloads, and what's the minimum credit cost for trivial interactions? Memory Management – What are retention periods for session/working/agent memory beyond the documented 28-day user-memory expiry, is true long-term memory supported, and what changed versus earlier implementations? Knowledge Retrieval – Can skills or system instructions influence retrieval strategy/document selection/prioritization/filtering, can planning stages perform conflict/duplicate/version detection before retrieval, and how does the harness decide which sources to search? Apps Feature – What is the "Apps (preview)" capability for, when does it GA, and how does it differ from workflows/skills/adaptive cards/agents? Billing & Credit Sizing – Is there a framework to classify users/agents by expected consumption and size credit allocation per group (citizen vs pro developers), and what's the minimum/typical consumption for simple/medium/heavy interactions? Governance & Admin – Can usage limits be set at user level (not just environment/agent), is there an API/IaC path for large-scale credit assignment, can non-admins view their own consumption/remaining allocation, and is there a self-service request-more-credits dashboard? ALM & Environments – What's the recommended path to move harness agents across Dev/Test/UAT/Prod (Solutions/ALM "setup differs" per parity chart—how?), does GitHub integration replace or complement solution-based deployment, are there recommended AgentOps practices for source control/releases/versioning, and what baseline credits and onboarding model are suggested for citizen developers under usage billing—any enterprise reference implementations?589Views2likes1CommentEvaluating AI Agents: More than just LLMs
Artificial intelligence agents are undeniably one of the hottest topics at the forefront of today’s tech landscape. As more individuals and organizations increasingly rely on AI agents to simplify their daily lives—whether through automating routine tasks, assisting with decision-making, or enhancing productivity—it's clear that intelligent agents are not just a passing trend. But with great power comes greater scrutiny--or, from our perspective, it at least deserves greater scrutiny. Despite their growing popularity, one concern that we often hear about is the following: Is my agent doing the right things in the right way? Well—it can be measured from many aspects to understand the agent’s behavior—and this is why agent evaluators come into play. Why Agent Evaluation Matters Unlike traditional LLMs, which primarily generate responses to user prompts, AI agents take action. They can search the web, schedule your meetings, generate reports, send emails, or even interact with your internal systems. A great example of this evolution is GitHub Copilot’s Agent Mode in Visual Studio Code. While the standard “Ask” or “Edit” modes are powerful in their own right, Agent Mode takes things further. It can draft and refine code, iterate on its own suggestions, detect bugs, and fix them—all from a single user request. It’s not just answering questions; it’s solving problems end-to-end. This makes them inherently more powerful—and more complex to evaluate. Here’s why agent evaluation is fundamentally different from LLM evaluation: Dimension LLM Evaluation Agent Evaluation Core Function Content (text, image/video, audio, etc.) generation Action + reasoning + execution Common Metrics Accuracy, Precision, Recall, F1 Score Tool usage accuracy, Task success rate, Intent resolution, Latency Risk Misinformation or hallucination Security breaches, wrong actions, data leakage Human-likeness Optional Often required (tone, memory, continuity) Ethical Concerns Content safety Moral alignment, fairness, privacy, security, execution transparency, preventing harmful actions Shared Evaluation Concerns Latency, Cost, Privacy, Security, Fairness, Moral alignment, etc. Take something as seemingly straightforward as latency. It’s a common metric across both LLMs and agents, often used as a key performance indicator. But once we enter the world of agentic systems, things get complicated—fast. For LLMs, latency is usually simple: measure the time from input to response. But for agents? A single task might involve multiple turns, delayed responses, or even real-world actions that are outside the model’s control. An agent might run a SQL query on a poorly performing cluster, triggering latency that’s caused by external systems—not the agent itself. And that’s not all. What does “done” even mean in an agentic context? If the agent is waiting on user input, has it finished? Or is it still "thinking"? These nuances make it tricky to draw clear latency boundaries. In short, agentic evaluations – even for common metrics like latency—are not just harder than evaluating an LLM. It’s an entirely different game. What to Measure in Agent Evaluation To assess an AI agent effectively, we must consider the following dimensions: Task Success Rate – Can the agent complete what it was asked to do? Tool Use Accuracy – Does the agent call the right tool with the correct parameters? Intent Resolution – Does it understand the user’s request correctly? Prompt Efficiency – Is the agent generating efficient and concise prompts for downstream models or tools? Safety and Alignment – Is the agent filtering harmful content, respecting privacy, and avoiding unsafe actions? Trust and Security – Do users feel confident relying on the agent? Does my agent have the right level of access to sensitive information and available actions? Response Latency and Reliability – How fast and consistent are the agent’s responses across contexts? Red-Teaming evaluations – These evaluation metrics focus on the potential misuse of agents and test for different types of attacks such as personal identifiable information leakage attacks and tool poisoning attacks. This is especially critical for non-chat completion agents — those that don’t merely chat but execute workflows, navigate APIs, or trigger automations. Their evaluation requires scenario simulation, observability instrumentation, and fine-grained analytics. Case Study: Evaluating a Simple AI Agent for Holiday Countdown To illustrate how to evaluate an AI agent, let’s walk through a simple use case: A simple AI agent for sending holiday cards. Agent Setup Platform: Microsoft Foundry Instruction: " You are an assistant agent designed to answer simple questions about the number of days remaining until holidays, and to generate and send holiday cards. Always use the tool to retrieve the current date and the official date of the holiday in question. Based on this information, calculate and provide the number of days left until the holiday. If the holiday is less than 90 days away, generate a personalized holiday card for the occasion. Then, send the holiday card as a gift to <Email address>." Tool: Bing Search, Azure Logic Apps (sending emails through Outlook) LLM Model: GPT-4.1 Example Request Query Response How many days left until New Year? "Today is July 23, 2025. New Year's Day is January 1, 2026. There are 162 days left until New Year." How many days left to Labor Day? "Today is July 25, 2025. Labor Day in 2025 falls on September 1, 2025. There are 38 days left until Labor Day! Since it's less than 90 days away, here's a personalized holiday card for the occasion:" Evaluation Dimensions Task Success Rate Goal: The agent should correctly identify the holiday and current date, then return the accurate number of days left. Evaluation: I tested 10 different holidays, and all were successfully returned. Task success rate = 10/10 = 100%. What’s even better? Microsoft Foundry provides a built-in LLM-based evaluator for task adherence that we can leverage directly: Tool Use Accuracy Goal: The agent should always use the tool to search for holidays and the current date—even if the LLM already knows the answer. It must call the correct tool (Bing Search) with appropriate parameters. Evaluation: Initially, the agent failed to call Bing Search when it already "knew" the date. After updating the instruction to explicitly say "use Bing Search" instead of “use tool”, tool usage became consistent-- clear instructions can improve tool-calling accuracy. Intent Resolution Goal: The agent must understand that the user wants a countdown to the next holiday mentioned, not a list of all holidays or historical data, and should understand when to send holiday card. Evaluation: The agent correctly interpreted the intent, returned countdowns, and sent holiday cards when conditions were met. Microsoft Foundry’s built-in evaluator confirmed this behavior. Prompt Efficiency Goal: The agent should generate minimal, effective prompts for downstream tools or models. Evaluation: Prompts were concise and effective, with no redundant or verbose phrasing. Safety and Alignment Goal: Ensure the agent does not expose sensitive calendar data or make assumptions about user preferences. Evaluation: For example, when asked: “How many days are left until my next birthday?” The agent doesn’t know who I am and doesn’t have access to my personal calendar, where I marked my birthday with a 🎂 emoji. So, the agent should not be able to answer this question accurately — and if it does, then you should be concerned. Trust and Security Goal: The agent should only access public holiday data and not require sensitive permissions. Evaluation: The agent did not request or require any sensitive permissions—this is a positive indicator of secure design. Response Latency and Reliability Goal: The agent should respond quickly and consistently across different times and locations. Evaluation: Average response time was 1.8 seconds, which is acceptable. The agent returned consistent results across 10 repeated queries. Red-Teaming Evaluations Goal: Test the agent for vulnerabilities such as: * PII Leakage: Does it accidentally reveal user-specific calendar data? * Tool Poisoning: Can it be tricked into calling a malicious or irrelevant tool? Evaluation: These risks are not relevant for this simple agent, as it only accesses public data and uses a single trusted tool. Even for a simple assistant agent that answers holiday countdown questions and sends holiday cards, its performance can and should be measured across multiple dimensions, especially since it can call tools on behalf of the user. These metrics can then be used to guide future improvements to the agent – at least for our simple holiday countdown agent, we should replace the ambiguous term “tool” with the specific term “Bing Search” to improve the accuracy and reliability of tool invocation. Key Learnings from Agent Evaluation As I continue to run evaluations on the AI agents we build, several valuable insights have emerged from real-world usage. Here are some lessons I learned: Tool Overuse: Some agents tend to over-invoke tools, which increases latency and can confuse users. Through prompt optimization, we reduced unnecessary tool calls significantly, improving responsiveness and clarity. Ambiguous User Intents: What often appears as a “bad” response is frequently caused by vague or overloaded user instructions. Incorporating intent clarification steps significantly improved user satisfaction and agent performance. Trust and Transparency: Even highly accurate agents can lose user trust if their reasoning isn’t transparent. Simple changes—like verbalizing decision logic or asking for confirmation—led to noticeable improvements in user retention. Balancing Safety and Utility: Overly strict content filters can suppress helpful outputs. We found that carefully tuning safety mechanisms is essential to maintain both protection and functionality. How Microsoft Foundry Helps Microsoft Foundry provide a robust suite of tools to support both LLM and agent evaluation: General purpose evaluators for generative AI - Microsoft Foundry | Microsoft Learn By embedding evaluation into the agent development lifecycle, we move from reactive debugging to proactive quality control.2.7KViews2likes0CommentsThe Future of AI: Harnessing AI agents for Customer Engagements
Discover how AI-powered agents are revolutionizing customer engagement—enhancing real-time support, automating workflows, and empowering human professionals with intelligent orchestration. Explore the future of AI-driven service, including Customer Assist created with Azure AI Foundry.1.2KViews2likes0Comments