container networking
23 TopicsUse cases of Advanced Network Observability for your Azure Kubernetes Service clusters
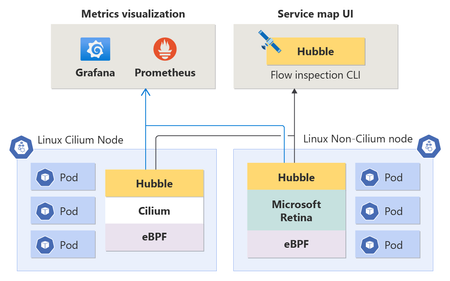
The blog explores the use cases of Advanced Network Observability for Azure Kubernetes Service (AKS) clusters. It introduces the Advanced Network Observability feature, which brings Hubble's control plane to both Cilium and Non-Cilium Linux data planes. This feature provides deep insights into containerized workloads, enabling precise detection and root-cause analysis of network-related issues in Kubernetes clusters. The document also includes customer scenarios that demonstrate the benefits of Advanced Network Observability, such as DNS metrics, network policy drops at the pod level, and traffic imbalance for pods within a workload4.3KViews4likes2Comments
Multi-NIC Support on AKS powered by DRANET – Now in Public Preview
Kubernetes was designed around a simple networking model, every pod gets one network interface, and every pod on a node shares the same flat network. For most stateless microservices, this works well as it keeps the model simple and the platform portable. But a large class of workloads don't fit that shape. Some need network separation, with management, control, and data traffic on separate and isolated networks rather than multiplexed over one interface. Other workloads need predictable performance, a dedicated path for high-throughput or latency-sensitive traffic. Until now, meeting these requirements on Kubernetes meant adding and manually integrating multiple components, or keeping the workload on VMs. Today we're announcing the public preview of multi-NIC support for pods on AKS, powered by the AKS managed DRANET driver. You can now provision worker nodes with multiple network interfaces connected to different subnets, and attach a dedicated interface directly to a pod using standard upstream Kubernetes APIs, with no Multus, no custom CNI extensions, and no manual interface wiring. Two ways to use multi-NIC on AKS Use case 1: A dedicated NIC attached directly to a pod “As a networking engineer, I want to attach a dedicated network interface directly to a Kubernetes pod so the workload can connect to different networks and route traffic natively, without relying on host-level DPDK/VPP forwarding, custom routing rules, or gateway-based NAT.” “I also want the secondary interface on my pod to send and receive traffic on a specific, known public IP address, so that downstream partners can allow-list my traffic by IP and no NAT hop adds latency to time-sensitive streams." This is the pattern where the workload itself expects to see multiple interfaces. The pod asks for a network device the same way it would ask for any other resource, and the interface shows up inside the container alongside the standard CNI interface. No host-level forwarding layer, no NAT gateway in the middle. What you get The DRANET driver is deployed automatically. Once a node pool is configured with secondary interfaces, AKS installs and manages the driver for you; there is no add-on to install and no CRDs to author by hand. Declarative, scheduler-aware requests. Interfaces are advertised to Kubernetes as allocatable devices, so a pod that asks for one is placed on a node that can actually provide it, using standard Dynamic Resource Allocation (DRA) objects rather than vendor-specific annotations. A predictable interface lifecycle. The driver handles attach, release, and recovery as pods are rescheduled or restarted. A public IP address can be assigned directly to a secondary interface, configured at node pool creation time using IP tags. The pod's secondary interface talks to the outside world without going through the load balancer or any address translation layer. Both IPv4 and IPv6 addresses are supported on the secondary interface. What to plan around Interfaces are dedicated, not shared. When a NIC is attached to a pod, it moves into that pod's network namespace and is no longer available to the node or to any other pod. Sharing a secondary NIC across pods isn't supported in this release. Because of that, pod density on a multi-NIC node pool is bounded by the number of interfaces on the node. All interfaces must be attached to the same virtual network as the primary NIC. On a bring-your-own VNet cluster, different subnets within that VNet are supported, but different VNets are not, in this preview. On an AKS-managed VNet, secondary interfaces are currently limited to the same subnet as the primary NIC , since creating a new subnet on a managed VNet isn't supported yet. Each pod's secondary interface gets its own dedicated public IP, so plan node pool sizing around how many pods need a tagged public IP of their own. Public IP assignment is configured at node pool creation time through IP tags, so decide your IP range and tagging strategy before you provision the node pool. Kubernetes network policy is enforced on the primary interface only. Plan isolation for secondary interfaces at the subnet and NSG layer. Use Case 2: Multi-NIC nodes with your own NIC management “As a platform/networking engineer, I want to provision Kubernetes worker nodes with multiple network interfaces connected to different networks and use my own VPP, DPDK, or any custom routing logic to steer traffic at the node level, without attaching additional interfaces to pods.” This is the pattern for teams who already own their dataplane. The node is multi-homed, each interface lands on its own subnet, and your own software decides which traffic goes where. Pods keep a single CNI-assigned interface and stay unaware of the underlying topology. What you get Depending on the selected SKU size, you can configure nodes with multiple network interfaces. Full control, and full ownership of the additional nics. AKS provisions the interfaces and keeps them attached to the node. How traffic is steered across them is entirely yours to design, configure, operate, and support. That includes your routing rules, your userspace dataplane, and any troubleshooting of the forwarding path itself. The same-VNet constraint applies here too, secondary interfaces can span subnets, but not virtual networks. This applies to bring-your-own VNet clusters. On an AKS-managed VNet, secondary interfaces are restricted to the primary NIC's subnet for now. Both patterns start from the same node pool configuration. The difference is whether you stop there and manage the interfaces yourself, or let the DRANET hand them to your pods. How it works Multi-NIC on AKS starts with a single configuration step: you add secondary network interfaces to a node pool. AKS provisions the NICs on every VM in the pool and installs the DRANET driver alongside them. From there, what happens to those NICs depends on your workload. Reference a resource claim in your pod spec, and DRANET moves an interface into the pod Or Leave them on the node and steer traffic yourself with VPP, DPDK, or custom routing. Step 1: Provision the node pools with secondary NICs Secondary interfaces are declared when you create the node pool. The agent pool's network profile carries a secondaryNetworkInterfaces array, and each entry points at a subnet in the same virtual network as the primary NIC: "networkProfile": { "secondaryNetworkInterfaces": [ { "type": "Standard", "vnetSubnetId": "<VNET_SUBNET_ID>" } { "type": "Standard", "vnetSubnetId": "<VNET_SUBNET_ID>" } ] } AKS extends VMSS provisioning to attach those NICs to every VM in the pool. Add more entries for more interfaces, up to what the VM SKU allows. The array length is validated against the SKU at creation time, so a pool with mixed sizes has to be planned around the smallest one. The node is now multi-homed and the interfaces are visible on the host. If you are building for use case 2, this is where you stop. AKS provisions and keeps the interfaces attached to the node, and how traffic is steered across them, the routing rules, the userspace dataplane, the troubleshooting of the forwarding path, is yours to design, operate, and support. Step 2: Using AKS managed DRANET driver to hand an interface to the pod Once a node pool has secondary interfaces configured, and the cluster is using AKS-managed CNI (Azure CNI or Azure CNI Powered by Cilium), AKS automatically installs the DRANET driver as a DaemonSet, packaged and delivered through an AKS-managed Helm chart. There is nothing to deploy yourself and no CRDs to author by hand. If you're running a BYO CNI cluster, AKS still provisions the secondary NICs, but you're responsible for deploying DRANET (or your own driver of choice) yourself. The driver does three things: Discovers the additional interfaces present on each node. Advertises them to Kubernetes as allocatable DRA devices, published in a ResourceSlice. Manages the lifecycle: exclusive per-pod allocation, attachment, release, and recovery as pods move or restart. Inspect the DRANET deamonset, pods, and deviceclass using the following commands: kubectl get deviceclasses kubectl get daemonset -A kubectl get pods -A -o wide Now you can create a “ResourceClaimTemplate” that defines how each pod requests a device. apiVersion: resource.k8s.io/v1 kind: ResourceClaimTemplate metadata: name: nic-dev-template spec: spec: devices: requests: - name: nic exactly: deviceClassName: standard-secondary-nic allocationMode: ExactCount count: 1 Configure the pod references the template, and the scheduler places it on a node that has a matching NIC available: apiVersion: v1 kind: Pod metadata: name: multi-nic-test spec: containers: - name: multi-nic image: nicolaka/netshoot resources: claims: - name: nic resourceClaims: - name: nic resourceClaimTemplateName: nic-dev-template A pod referencing a claim comes up with its usual CNI-assigned eth0 plus the allocated secondary interface, and you can confirm both from inside the container. When DRANET attaches a secondary NIC to a pod, that interface moves into the pod's network namespace and is no longer available on the node or to any other pod. It returns to the node's pool of available devices when the pod terminates. That gives you a clean isolation boundary and deterministic performance, with the trade-off that pod density on a multi-NIC pool is bounded by interface count, not just CPU and memory. For the full walkthrough including feature flag registration, more examples visit https://aka.ms/aks/multi-nic. Try it now Multi-NIC support for pods on AKS is available now in public preview. Start with the documentation for the full walkthrough: provisioning a node pool with secondary interfaces, defining a resource claim, and validating that both interfaces appear inside the pod. Documentation: https://aka.ms/aks/multi-nic Upstream project: DRANET on GitHub Preview is when your input can actually shape the feature. If you hit a limitation or have a use case we haven’t covered, comment below and share your feedback. 532Views3likes0Comments
Announcing public preview: Cilium mTLS encryption for Azure Kubernetes Service
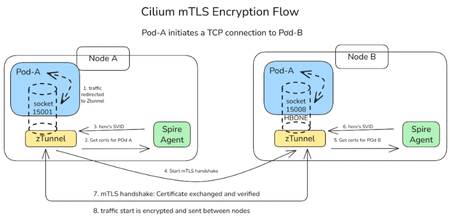
We are thrilled to announce the public preview of Cilium mTLS encryption in Azure Kubernetes Service (AKS), delivered as part of Advanced Container Networking Services and powered by the Azure CNI dataplane built on Cilium. This capability is the result of a close engineering collaboration between Microsoft and Isovalent (now part of Cisco). It brings transparent, workload‑level mutual TLS (mTLS) to AKS without sidecars, without application changes, and without introducing a separate service mesh stack. This public preview represents a major step forward in delivering secure, high‑performance, and operationally simple networking for AKS customers. In this post, we’ll walk through how Cilium mTLS works, when to use it, and how to get started. Why Cilium mTLS encryption matters Traditionally, teams looking to in-transit traffic encryption in Kubernetes have had two primary options: Node-level encryption (for example, WireGuard or virtual network encryption), which secures traffic in transit but lacks workload identity and authentication. Service meshes, which provide strong identity and mTLS guarantees but introduce operational complexity. This trade‑off has become increasingly problematic, as many teams want workload‑level encryption and authentication, but without the cost, overhead, and architectural impact of deploying and operating a full-service mesh. Cilium mTLS closes this gap directly in the dataplane. It delivers transparent, inline mTLS encryption and authentication for pod‑to‑pod TCP traffic, enforced below the application layer. And implemented natively in the Azure CNI dataplane built on Cilium, so customers gain workload‑level security without introducing a separate service mesh, resulting in a simpler architecture with lower operational overhead. To see how this works under the hood, the next section breaks down the Cilium mTLS architecture and follows a pod‑to‑pod TCP flow from interception to authentication and encryption. Architecture and design: How Cilium mTLS works Cilium mTLS achieves workload‑level authentication and encryption by combining three key components, each responsible for a specific part of the authentication and encryption lifecycle. Cilium agent: Transparent traffic interception and wiring Cilium agent which already exists on any cluster running with Azure CNI powered by cilium, is responsible for making mTLS invisible to applications. When a namespace is labelled with “io.cilium/mtls-enabled=true”, The Cilium agent enrolls all pods in that namespace. It enters each pod's network namespace and installs iptables rules that redirect outbound traffic to ztunnel on port 15001. It is also responsible for passing workload metadata (such as pod IP and namespace context) to ztunnel. Ztunnel: Node‑level mTLS enforcement Ztunnel is an open source, lightweight, node‑level Layer 4 proxy that was originally created by Istio. Ztunnel runs as a DaemonSet, on the source node it looks up the destination workload via XDS (streamed from the Cilium agent) and establishes mutually authenticated TLS 1.3 sessions between source and destination nodes. Connections are held inline until authentication is complete, ensuring that traffic is never sent in plaintext. The destination ztunnel decrypts the traffic and delivers it into the target pod, bypassing the interception rules via an in-pod mark. The application sees a normal plaintext connection — it is completely unaware encryption happened. SPIRE: Workload identity and trust SPIRE (SPIFFE Runtime Environment) provides the identity foundation for Cilium mTLS. SPIRE acts as the cluster Certificate Authority, issuing short‑lived X.509 certificates (SVIDs) that are automatically rotated and validated. This is a key design principle of Cilium mTLS - trust is based on workload identity, not network topology. Each workload receives a cryptographic identity derived from: Kubernetes namespace Kubernetes ServiceAccount These identities are issued and rotated automatically by SPIRE and validated on both sides of every connection. As a result: Identity remains stable across pod restarts and rescheduling Authentication is decoupled from IP addresses Trust decisions align naturally with Kubernetes RBAC and namespace boundaries This enables a zero‑trust networking model that fits cleanly into existing AKS security practices. End‑to‑End workflow example To see how these components work together, consider a simple pod‑to‑pod connection: A pod initiates a TCP connection to another pod. Traffic intercepted inside the pod network namespace and redirected to the local ztunnel instance. ztunnel retrieves the workload identity using certificates issued by SPIRE. ztunnel establishes a mutually authenticated TLS session with the destination node’s ztunnel. Traffic is encrypted and sent between pods. The destination ztunnel decrypts the traffic and delivers it to the target pod. Every packet from an enrolled pod is encrypted. There is no plaintext window, and no dropped first packets. The connection is held inline by ztunnel until the mTLS tunnel is established, then traffic flows bidirectionally through an HBONE (HTTP/2 CONNECT) tunnel. Workload enrolment and scope Cilium mTLS in AKS is opt‑in and scoped at the namespace level. Platform teams enable mTLS by applying a single label to a namespace. From that point on: All pods in that namespace participate in mTLS Authentication and encryption are mandatory between enrolled workloads Non-enrolled namespaces continue to operate unchanged Encryption is applied only when both pods are enrolled. Traffic between enrolled and non‑enrolled workloads continues in plaintext without causing connectivity issues or hard failures. This model enables gradual rollout, staged migrations, and low-risk adoption across environments. Getting started in AKS Cilium mTLS encryption is available in public preview for AKS clusters that use: Azure CNI powered by Cilium Advanced Container Networking Services You can enable mTLS: When creating a new cluster, or On an existing cluster by updating the Advanced Container Networking Services configuration Once enabled, enrolling workloads is as simple as labelling a namespace. 👉 Learn more Concepts: How Cilium mTLS works, architecture, and trust boundaries How-to guide: Step-by-step instructions to enable and verify mTLS in AKS Looking ahead This public preview represents an important step forward in simplifying network security for AKS and reflects a deep collaboration between Microsoft and Isovalent to bring open, standards‑based innovation into production‑ready cloud platforms. We’re continuing to work closely with the community to improve the feature and move it toward general availability. If you’re looking for workload‑level encryption without the overhead of a traditional service mesh, we invite you to try Cilium mTLS in AKS and share your experience.1.8KViews3likes0Comments
Introducing Container Network Logs with Advanced Container Networking Services for AKS
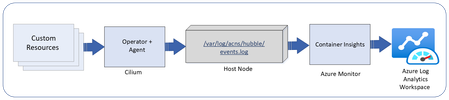
Overview of container network logs Container network logs offer a comprehensive way to monitor network traffic in AKS clusters. Two modes of support, stored-logs and on-demand logs, provides debugging flexibility with cost optimization. The on-demand mode provides a snapshot of logs with queries and visualization with Hubble CLI UI for specific scenarios and does not use log storage to persist the logs. The stored-logs mode when enabled continuously collects and persists logs based on user-defined filters. Logs can be stored either in Azure Log Analytics (managed) or locally (unmanaged). Managed storage: Logs are forwarded to Azure Log Analytics for secure, scalable, and compliant storage. This enables advanced analytics, anomaly detection, and historical trend analysis. Both basic and analytics table plans are supported for storage. Unmanaged storage: Logs are stored locally on the host nodes under /var/log/acns/hubble. These logs are rotated automatically at 50 MB to manage storage efficiently. These logs can be exported to external logging systems or collectors for further analysis. Use cases Connectivity monitoring: Identify and visualize how Kubernetes workloads communicate within the cluster and with external endpoints, helping to resolve application connectivity issues efficiently. Troubleshooting network errors: Gain deep granular visibility into dropped packets, misconfigurations, or errors with details on where and why errors are occurring (TCP/UDP, DNS, HTTP) for faster root cause analysis. Security policy enforcement: Detect and analyze suspicious traffic patterns to strengthen cluster security and ensure regulatory compliance. How it works Container network logs use eBPF technology with Cilium to capture network flows from AKS nodes. Log collection is disabled by default. Users can enable log collection by defining custom resources (CRs) to specify the types of traffic to monitor, such as namespaces, pods, services, or protocols. The Cilium agent collects and processes this traffic, storing logs in JSON format. These logs can either be retained locally or integrated with Azure Monitoring for long-term storage and advanced analytics and visualization with Azure managed Grafana. Fig1: Container network logs overview If using managed storage, users will enable Azure monitor log collection using Azure CLI or ARM templates. Here’s a quick example of enabling container network logs on Azure monitor using the CLI: az aks enable-addons -a monitoring --enable-high-log-scale-mode -g $RESOURCE_GROUP -n $CLUSTER_NAME az aks update --enable-acns \ --enable-retina-flow-logs \ -g $RESOURCE_GROUP \ -n $CLUSTER_NAME Key benefits Faster issue resolution: Detailed logs enable quick identification of connectivity and performance issues. Operational efficiency: Advanced filtering reduces data management overhead. Enhanced application reliability: Proactive monitoring ensures smoother operations. Cost optimization: Customized logging scopes minimize storage and data ingestion costs. Streamlined compliance: Comprehensive logs support audits and security requirements. Observing logs in Azure managed Grafana dashboards Users can visualize container network logs in Azure managed Grafana dashboards, which simplify monitoring and analysis: Flow logs dashboard: View internal communication between Kubernetes workloads. This dashboard highlights metrics such as total requests, dropped packets, and error rates. Error logs dashboard: Easily zoom in only on the logs which show errors for faster log parsing. Service dependency graph: Visualize relationships between services, detect bottlenecks, and optimize network flows. These dashboards provide filtering options to isolate specific logs, such as DNS errors or traffic patterns, enabling efficient root cause analysis. Summary statistics and top-level metrics further enhance understanding of cluster health and activity. Fig 2: Azure managed Grafana dashboard for container network logs Conclusion Container network logs for AKS offer a powerful and cost optimized way to monitor and analyze network activity, enhance troubleshooting, security, and ensure compliance. To get started, enable Advanced Container Networking Services in your AKS cluster and configure custom resources for logging. Visualize your logs in Grafana dashboards and Azure Log Analytics to unlock actionable insights. Learn more here.1.6KViews3likes0CommentsSecuring Microservices with Cilium and Istio
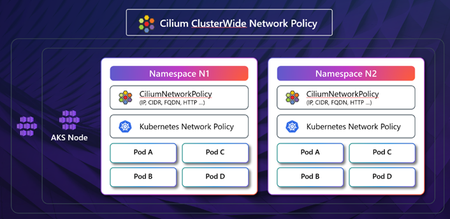
The adoption of Kubernetes and containerized applications is booming, leading to new challenges in visibility and security. As the landscape of cloud-native applications is rapidly evolving so are the number of sophisticated attacks targeting containerized workloads. Traditional tools often fall short in tracking the usage and traffic flows within these applications. The immutable nature of container images and the short lifespan of containers further necessitate addressing vulnerabilities early in the delivery pipeline. Comprehensive Security Controls in Kubernetes Microsoft Azure offers a range of security controls to ensure comprehensive protection across various layers of the Kubernetes environment. These controls include but are not limited to: Cluster Security: Features such as private clusters, managed cluster identity, and API server authorized ranges enhance security at the cluster level. Node and Pod Security: Hardened bootstrapping, confidential nodes, and pod sandboxing are implemented to secure the nodes and pods within a cluster. Network Security: Advanced Container Networking Services and Cilium Network policies offer granular control over network traffic. Authentication and Authorization: Azure Policy in-cluster enforcement, Entra authentication, and Istio mTLS and authorization policies provide robust identity and access management. Image Scanning: Microsoft Defender for Cloud provides both image and runtime scanning to identify vulnerabilities and threats. Let’s highlight how you can secure micro services while scaling your applications running on Azure Kubernetes Service (AKS) using service mesh for robust traffic management, and network policies for security. Micro segmentation with Network Policies Micro segmentation is crucial for enhancing security within Kubernetes clusters, allowing for the isolation of workloads and controlled traffic between microservices. Azure CNI by Cilium leverages eBPF to provide high-performance networking, security, and observability features. It dynamically inserts eBPF bytecode into the Linux kernel, offering efficient and flexible control over network traffic. Cilium Network Policies enable network isolation within and across Kubernetes clusters. Cilium also provides an identity-based security model, offering Layer 7 (L7) traffic control, and integrates deep observability for L4 to L7 metrics in Kubernetes clusters. A significant advantage of using Azure CNI based on Cilium is its seamless integration with existing AKS environments, requiring minimal modifications to your infrastructure. Note that Cilium Clusterwide Network Policy (CCNP) is not supported at the time of writing this blog post. FQDN Filtering with Advanced Container Networking Services (ACNS) Traditional IP-based policies can be cumbersome to maintain. ACNS allows for DNS-based policies, providing a more granular and user-friendly approach to managing network traffic. This is supported only with Azure CNI powered by Cilium and includes a security agent DNS proxy for FQDN resolution even during upgrades. It’s worth noting that with Cilium’s L7 enforcement, you can control traffic based on HTTP methods, paths, and headers, making it ideal for APIs, microservices, and services that use protocols like HTTP, gRPC, or Kafka. At the time of writing this blog, this capability is not supported via ACNS. More on this in a future blog! AKS Istio Add-On: Mutual TLS (mTLS) and Authorization Policy Istio enhances the security of microservices through its built-in features, including mutual TLS (mTLS) and authorization policies. The Istiod control plane, acting as a certificate authority, issues X.509 certificates to the Envoy sidecar proxies via the Secret Discovery Service (SDS). Integration with Azure Key Vault allows for secure management of root and intermediate certificates. The PeerAuthentication Custom Resource in Istio controls the traffic accepted by workloads. By default, it is set to PERMISSIVE to facilitate migration but can be set to STRICT to enforce mTLS across the mesh. Istio also supports granular authorization policies, allowing for control over IP blocks, namespaces, service accounts, request paths, methods, and headers. The Istio add-on also supports integration with Azure Key Vault (AKV) and the AKV Secrets Store CSI Driver Add-On for plug-in CA certificates, where the root CA lives on a secure machine offline, and the intermediate certs for the Istiod control plane are synced to the cluster by the CSI Driver Add-On. Additionally, certificates for the Istio ingress gateway for TLS termination or SNI passthrough can also be stored in AKV. Defense-In-Depth with Cilium, ACNS and Istio Combining the capabilities of Cilium's eBPF technologies through ACNS and AKS managed Istio addon, AKS provides a defense-in-depth strategy for securing Kubernetes clusters. Azure CNI's Cilium Network Policies and ACNS FQDN filtering enforce Pod-to-Pod and Pod-to-egress policies at Layer 3 and 4, while Istio enforces STRICT mTLS and Layer 7 authorization policies. This multi-layered approach ensures comprehensive security coverage across all layers of the stack. Now, let’s highlight the key steps in achieving this: Step 1: Create an AKS Cluster with Azure CNI (by Cilium), ACNS and Istio Addon enabled. az aks create \ --resource-group $RESOURCE_GROUP \ --name $CLUSTER_NAME \ --location $LOCATION \ --kubernetes-version 1.30.0 \ --node-count 3 \ --node-vm-size standard_d16_v3 \ --enable-managed-identity \ --network-plugin azure \ --network-dataplane cilium \ --network-plugin-mode overlay \ --pod-cidr 192.168.0.0/16 \ --enable-asm \ --enable-acns \ --generate-ssh-keys Step 2: Create Cilium FQDN policy that allows egress traffic to google.com while blocking traffic to httpbin.org. Sample Policy (fqdn-filtering-policy.yaml): apiVersion: cilium.io/v2 kind: CiliumNetworkPolicy metadata: name: sleep-network-policy namespace: foo spec: endpointSelector: matchLabels: app: sleep egress: - toFQDNs: - matchPattern: "*.google.com" - toEndpoints: - matchLabels: "k8s:io.kubernetes.pod.namespace": foo "k8s:app": helloworld - toEndpoints: - matchLabels: "k8s:io.kubernetes.pod.namespace": kube-system "k8s:k8s-app": kube-dns toPorts: - ports: - port: "53" protocol: ANY Apply policy: kubectl apply -f fqdn-filtering-policy.yaml Step 3: Create an Istio deny-by-default AuthorizationPolicy. This denies all requests across the mesh unless specifically authorized with an “ALLOW” policy. Sample Policy (istio-deny-all-authz.yaml): apiVersion: security.istio.io/v1 kind: AuthorizationPolicy metadata: name: allow-nothing namespace: aks-istio-system spec: {} Apply policy: kubectl apply -f istio-deny-all-authz.yaml Step 4: Deploy an Istio L7 AuthorizationPolicy to explicitly allow traffic to the “sample” pod in namespace foo for http “GET” requests. Sample Policy (istio-L7-allow-policy.yaml): apiVersion: security.istio.io/v1 kind: AuthorizationPolicy metadata: name: allow-get-requests namespace: foo spec: selector: matchLabels: app: sample action: ALLOW rules: - to: - operation: methods: [“GET”] Apply policy: kubectl apply -f istio-L7-allow-policy.yaml Step 5: Deploy an Istio strict mTLS PeerAuthentication Resource to enforce that all workloads in the mesh only accept Istio mTLS traffic. Sample PeerAuthentication (istio-peerauth.yaml): apiVersion: security.istio.io/v1 kind: PeerAuthentication metadata: name: strict-mtls namespace: aks-istio-system spec: mtls: mode: STRICT Apply policy: kubectl apply -f istio-peerauth.yaml These examples demonstrate how you can manage traffic to specific FQDNs and enforce L7 authorization rules in your AKS cluster. Conclusion Traditional IP and perimeter security models are insufficient for the dynamic nature of cloud-native environments. More sophisticated security mechanisms, such as identity-based policies and DNS names, are required. Azure CNI, powered by Cilium and ACNS, provides robust FQDN filtering and Layer 3/4 Network Policy enforcement. The Istio add-on offers mTLS for identity-based encryption and Layer7 authorization policies. A defense-in-depth model, incorporating both Azure CNI and service mesh mechanisms, is recommended for maximizing security posture. So, give these a try and let us know (Azure Kubernetes Service Roadmap (Public)) how we can evolve our roadmap to help you build the best with Azure. Credit(s): Niranjan Shankar, Sr. Software Engineer, Microsoft2.6KViews3likes0Comments
Azure CNI Powered by Cilium for Azure Kubernetes Service (AKS)
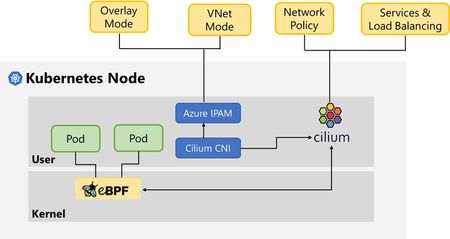
Azure CNI powered by Cilium integrates the scalable and flexible Azure IPAM control plane with the robust dataplane offered by Cilium OSS to create a modern container networking stack that meets the demands of cloud native workloads.17KViews3likes1Comment
Azure CNI Overlay for Application Gateway for Containers and Application Gateway Ingress Controller
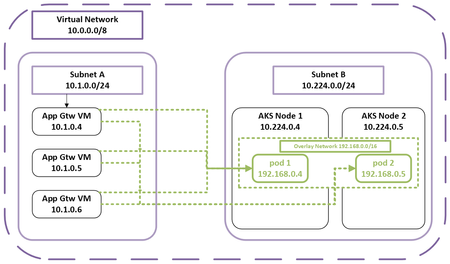
What are Azure CNI Overlay and Application Gateway? Azure CNI Overlay leverages logical network spaces for pod IP assignment management (IPAM). This provides enhanced IP scalability with reduced management responsibilities. Application Gateway for Containers is the latest and most recommended container L7 load-balancing solution. It introduces a new scalable control plane and data plane to address the performance demands and modern workloads being deployed to AKS clusters on Azure. Azure network control plane configures routing between Application Gateway and overlay pods. Why is the feature needed? As businesses increasingly use containerized solutions, managing container networks at scale has become a priority. Within container network management, IP address exhaustion, scalability and application load balancing performance are highly requested and discussed in many forums. Azure CNI Overlay is the default container networking IPAM mode on AKS. In the overlay design, AKS nodes use IPs from Azure virtual network (VNet) IP address range and pods are addressed from an overlay IP address range. The overlay pods can communicate with each other directly via a different routing domain. Overlay IP addresses can be reused across multiple clusters in the same VNet, provisioning a solution for IP exhaustion and increasing IP scale to over 1M. Azure CNI Overlay supporting Application Gateway for Containers provides customers with a more performant, reliable, and scalable container networking solution. Meanwhile, Azure CNI Overlay supporting AGIC provides customers with full feature parity if they choose to upgrade AKS clusters from kubenet to Azure CNI Overlay. Key Benefits High scale with Azure CNI Overlay combined with a high-performance ingress solution Azure CNI Overlay provides direct pod to pod routing with high IP scale using direct azure native routing with no encapsulation overhead. IPs can be reused across clusters in the same VNET allowing customers to conserve IP addresses. Application Gateway for Containers is the latest and most recommended container L7 load-balancing solution. Installing Application Gateway for Containers on AKS clusters with Azure CNI Overlay provides customers with the best solution combination of IP scalability and ingress solution on Azure. Feature parity between kubenet and Azure CNI Overlay With the retirement announcement of kubenet, we expect to see customers upgrade their AKS container networking solution from kubenet to Azure CNI Overlay soon. This feature allows customers to maintain business continuity during the transitioning process. Learn More Read more about Azure CNI Overlay and Application Gateway for Containers. Learn more on how to upgrade AKS clusters’ IPAM to Azure CNI Overlay. Learn more about Azure Kubernetes Service and Application Gateway.834Views2likes0CommentsProvide a Flat Network Scaling Solution to AKS - Azure CNI Pod Subnet - Static Block Allocation
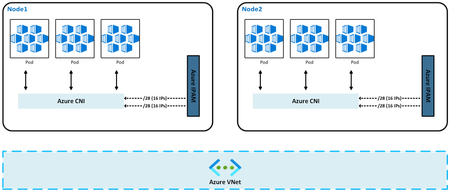
We are excited to announce the general availability of Azure CNI Pod Subnet - Static Block Allocation – a networking solution that transforms how you scale Azure Kubernetes Service (AKS) clusters! This long-awaited feature is now here, providing enterprise-grade flat networking for clusters in unprecedented capacity. What is Azure CNI Pod Subnet - Static Block Allocation? Azure CNI Pod Subnet - Static Block Allocation revolutionizes AKS networking by expanding cluster capacity from 65K to 1M pods – a game-changing 15x increase that eliminates traditional scaling barriers. Instead of assigning a batch of random individual IP addresses to each node, this innovative approach assigns dedicated Azure subnet CIDR ranges directly to nodes. Every pod scheduled on a node receives its IP address from that node's pre-allocated CIDR block, raising IP limit and simplifying massive deployments. The result is you gain unmatched flexibility with separate node and pod subnets, granular control over NAT and NSG policies, isolated workloads at the pod level, and VNet-native pod networking that maintains peak performance. It also seamlessly works with Azure CNI Powered by Cilium to provide advanced networking capabilities and comprehensive network policy enforcement. Why is Azure CNI Pod Subnet - Static Block Allocation needed? Kubernetes network solutions are challenging to plan due to rapidly evolving business needs. AKS users often face difficulties balancing simplicity, security, and scalability, while environmental changes further increase management costs. Many AKS users need a flat network architecture, pods with direct inbound connectivity, and Azure-native solution integrations, but traditional flat networks couldn't scale beyond 65K pods. Until the launch of static block, customers either choose overlay networks to achieve massive scale or sacrifice the benefits of flat networking. Azure CNI Pod Subnet - Static Block Allocation enables VNet-routed IP addresses that can scale to over 1M pods, providing the simplicity and low latency of a flat network. Each node receives pre-allocated CIDR blocks, and all pods on that node obtain IP addresses from these ranges. This approach delivers massive scale, previously only available with overlay networks (up to 1M pods) while maintaining all the benefits of a flat network architecture. It also works seamlessly alongside Azure CNI Pod Subnet - Dynamic IP Allocation, simply deploy it on new node pools with dedicated subnets. AKS users can scale up AKS network solutions with minimal effort while maintaining enterprise-grade reliability and security. Key Benefits That Matter to You Massive Scale Increase: Break through the 65K pod limitation and scale up to 1M pods per cluster. This isn't just a number—it's about giving you the freedom to build and scale without hitting unexpected networking limits. High Performance: AKS users’ pods get routed on the VNet which is a benefit for ingress/egress, eliminating unnecessary network hops and reducing latency for VNet-native pod networking. Efficient IP Management: AKS users now can allocate CIDR blocks to nodes. This approach raises the IP scalability limit for large-scale deployments. Unmatched Flexibility: Work seamlessly with existing clusters with Azure CNI Pod Subnet - Dynamic IP Allocation Share pod subnets across multiple node pools or even different clusters. Scale your node and pod networks independently Granular Control and Security: Since pods get their own dedicated subnet, AKS users can: Apply different network security policies to pods vs. nodes. Configure customized NAT and NSG policies. Implement isolated workloads at the pod level. Learn more about Azure CNI Pod Subnet - Static Block Allocation Read more in Azure CNI Pod Subnet - Static Block Allocation and try it out in your environment today. Learn more about the solution limitations. Learn more about Azure Kubernetes Service.916Views2likes0Comments
Introducing Layer 7 Network Policies with Advanced Container Networking Services for AKS Clusters!
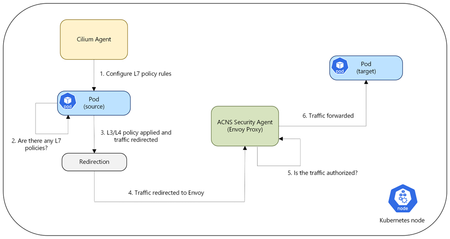
We have been on an exciting journey to enhance the network observability and security capabilities of Azure Kubernetes Service (AKS) clusters through our Azure Container Networking Services offering. Our initial step, the launch of Fully Qualified Domain Name (FQDN) filtering, marked a foundational step in enabling policy-driven egress control. By allowing traffic management at the domain level, we set the stage for more advanced and fine-grained security capabilities that align with modern, distributed workloads. This was just the beginning, a glimpse into our commitment to enabling AKS users with robust and granular security controls. Today, we are thrilled to announce the public preview of Layer 7 (L7) Network Policies for AKS and Azure CNI powered by Cilium users with Advanced Container Networking Services enabled. This update brings a whole new dimension of security to your containerized environments, offering much more granular control over your application layer traffic. Overview of L7 Policy Unlike traditional Layer 3 and Layer 4 policies that operate at the network and transport layers, L7 policies operate at the application layer. This enables more precise and effective traffic management based on application-specific attributes. L7 policies enable you to define security rules based on application-layer protocols such as HTTP(S), gRPC, and Kafka. For example, you can create policies that allow traffic based on HTTP(S) methods (GET, POST, etc.), headers, paths, and other protocol-specific attributes. This level of control helps in implementing fine-grained access control, restricting traffic based on the actual content of the communication, and gaining deeper insights into your network traffic at the application layer. Use cases of L7 policy API Security: For applications exposing APIs, L7 policies provide fine-grained control over API access. You can define policies that only allow specific HTTP(S) methods (e.g., GET for read-only operations, POST for creating resources) on particular API paths. This helps in enforcing API security best practices and prevent unnecessary access. Zero-Trust Implementation: L7 policies are a key component in implementing a Zero-Trust security model within your AKS environment. By default-denying all traffic and then explicitly allowing only necessary communication based on application-layer context, you can significantly reduce the attack surface and improve overall security posture. Microservice Segmentation and Isolation: In microservice architecture, it's essential to isolate services to limit the blast radius of potential security breaches. L7 policies allow you to define precise rules for inter-service communication. For example, you can ensure that a billing service can only be accessed by an order processing service via specific API endpoints and HTTP(S) methods, preventing unauthorized access from other services. How Does It Work? When a pod sends out network traffic, it is first checked against your defined rules using a small, efficient program called an extended Berkley Packet Filter (eBPF) probe. This probe marks the traffic if L7 policies are enabled for that pod, it is then redirected to a local Envoy Proxy. The Envoy proxy here is part of the ACNS Security Agent, separate from the Cilium agent. The Envoy Proxy, part of the ACNS Security Agent, then acts as a gatekeeper, deciding whether the traffic is allowed to proceed based on your policy criteria. If the traffic is permitted, it flows to its destination. If not, the application receives an error message saying access denied. Example: Restricting HTTP POST Requests Let's say you have a web application running on your AKS cluster, and you want to ensure that a specific backend service (backend-app) only accepts GET requests on the /data path from your frontend application (frontend-app). With L7 Network Policies, you can define a policy like this: apiVersion: cilium.io/v2 kind: CiliumNetworkPolicy metadata: name: allow-get-products spec: endpointSelector: matchLabels: app: backend-app # Replace with your backend app name ingress: - fromEndpoints: - matchLabels: app: frontend-app # Replace with your frontend app name toPorts: - ports: - port: "80” protocol: TCP rules: http: - method: "GET" path: "/data" How Can You Observe L7 Traffic? Advanced Container Networking Services with L7 policies also provides observability into L7 traffic, including HTTP(S), gRPC, and Kafka, through Hubble. Hubble is enabled by default with Advanced Container Networking Services. To facilitate easy analysis, Advanced Container Networking Services with L7 policy offers pre-configured Azure Managed Grafana dashboards, located in the Dashboards > Azure Managed Prometheus folder. These dashboards, such as "Kubernetes/Networking/L7 (Namespace)" and "Kubernetes/Networking/L7 (Workload)", provide granular visibility into L7 flow data at the cluster, namespace, and workload levels. The screenshot below shows a Grafana dashboard visualizing incoming HTTP traffic for the http-server-866b29bc75 workload in AKS over the last 5 minutes. It displays request rates, policy verdicts (forwarded/dropped), method/status breakdown, and dropped flow rates for real-time monitoring and troubleshooting. This is just an example; similar detailed metrics and visualizations, including heatmaps, are also available for gRPC and Kafka traffic on our pre-created dashboards. For real-time log analysis, you can also leverage the Hubble CLI and UI options offered as part of the Advanced Container Networking Services observability solution, allowing you to inspect individual L7 flows and troubleshoot any policy enforcement. Call to Action We encourage you to try out the public preview of L7 Network Policies on your AKS clusters and level up your network security controls for containerized workloads. We value your feedback as we continue to develop and improve this feature. Please refer to the Layer 7 Policy Overview for more information and visit How to Apply L7 Policy for an example scenario.1.4KViews2likes0Comments