azure horizondb
19 Topics
Rethinking Memory Management for Azure HorizonDB on Disaggregated Storage
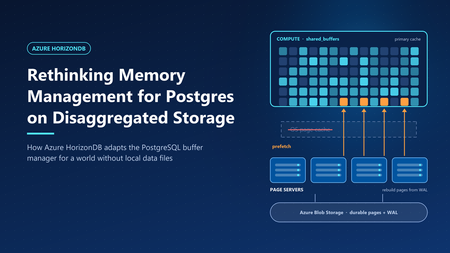
In Smarter Storage for Azure HorizonDB, we described how HorizonDB moves durability, replication, checkpointing, and recovery out of PostgreSQL and into a purpose-built storage layer. The compute node writes only the write-ahead log (WAL). Data pages are rebuilt and stored by remote page servers. That design raises an obvious question: if PostgreSQL no longer reads and writes its own data files, what happens to its memory management? PostgreSQL's buffer manager was built around a specific partner: the operating system's page cache. Many of its defaults and heuristics only make sense because the kernel is quietly doing a lot of work underneath. HorizonDB removes that partner. This post explains which assumptions broke, and the changes we made to the PostgreSQL engine, so memory works well on disaggregated storage. What PostgreSQL assumes about the kernel PostgreSQL stores each table and index as ordinary files and accesses them with buffered I/O. Every page therefore can live in two places in memory: in PostgreSQL's own buffer pool (shared_buffers) and in the operating system's page cache. This "double buffering" is a deliberate part of the design, and it shapes several behaviors. A modest buffer pool. The PostgreSQL documentation suggests starting shared_buffers at about 25% of system memory. Much of the rest is expected to act as kernel file cache. A page evicted from shared_buffers is often still in the kernel cache, so reading it back costs a memory copy rather than a disk read. Prefetching is a hint to the kernel. When PostgreSQL knows it will need a page soon—during a bitmap heap scan, for example—it calls posix_fadvise with POSIX_FADV_WILLNEED. The kernel starts reading the page into its cache. A later read finds it there. PostgreSQL itself never allocates a buffer for the prefetched page. Sequential scans rely on kernel readahead. For sequential access, the kernel detects the pattern and reads ahead automatically, so PostgreSQL can issue fewer explicit hints. Ring buffers protect the cache. Large sequential scans, VACUUM, and bulk writes such as COPY use a small private ring of buffers—from a few hundred kilobytes to a few megabytes—instead of the whole buffer pool. A scan of a table much larger than memory therefore cannot push the working set out of shared_buffers. This is safe because a page that cycles through the ring is usually still in the kernel cache if it is needed again. Writes are cheap and deferred. When a dirty buffer is evicted, PostgreSQL writes it to the kernel cache, which flushes it to disk later. The background writer cleans buffers ahead of eviction so that queries rarely wait for a write. Checkpoints write all dirty pages and call fsync to make them durable. Each of these behaviors assumes that a miss in shared_buffers is usually cheap, and that writing a page means writing it to a local file. What changes in HorizonDB Figure 1. Compute memory layout: Community PostgreSQL vs. Azure HorizonDB. In HorizonDB, permanent tables and indexes do not exist as local files on the compute node. There is no kernel page cache holding database pages. A miss in shared_buffers must be served by the remote storage layer: Tier Where it lives Typical role Shared buffers Compute memory Working set; all pages are read and modified here SSD cache Compute local disk Extends shared buffers; holds cached copies of pages Page servers Remote storage fleet Page cache of the current version of every page Azure Blob Storage Remote, zone-redundant Durable backing store for pages and WAL A page that falls out of memory no longer drops into a free kernel cache. It may require a network round trip to a page server, which is much more expensive than a memory read. Writes change too. Because page servers rebuild pages from WAL, "writing" a dirty page on the compute node does not mean copying it anywhere. PostgreSQL only has to make sure the WAL describing the change is durable - a rule it already enforces before any page write. Taken together, this inverts the trade-offs behind PostgreSQL's defaults. Memory is no longer one of two caches. It is the primary cache. Design principle: shared buffers are the primary cache We organized the engine changes around one principle. shared_buffers is the primary cache, eliminating the memory overhead of double buffering and improving memory efficiency. Every page that is about to be needed should arrive in memory before the query asks for it. The following sections describe the engine changes that implement it. 1. Size shared buffers for the machine Without a kernel cache to share memory with, leaving 75% of RAM to the operating system would waste most of it. HorizonDB sizes shared_buffers automatically at 60–70% of the compute node's memory, depending on the size of the instance. The remaining memory is left for connections, query execution memory such as sorts and hashes, and the operating system. 2. Retire ring buffers Ring buffers exist so that a large scan can use a few megabytes of memory and rely on the kernel cache for anything it needs again. In HorizonDB, there is no such safety net. Recycling a small ring means that every page the scan touches is read, used once, and discarded—and a second scan of the same table must fetch everything again from storage. Ring buffers also exist to limit write traffic: a bulk operation that dirties pages in a small ring must write them out quickly. HorizonDB doesn't need to write dirty data pages back to disk at all, so that motivation disappears as well. HorizonDB therefore disables buffer ring strategies. Sequential scans, VACUUM, and bulk loads use the shared buffer pool like any other query. This is a trade-off, not a free win. A very large scan can now displace pages from shared_buffers that other queries were using. Two factors limit the cost. First, clock-sweep replacement tracks how often each buffer is used, so frequently accessed pages outlive pages a scan touched only once—and buffer replacement is an area we continue to improve. Second, pages that leave shared_buffers are not simply lost: HorizonDB can keep them close by in the local SSD cache. How it decides and what goes there is a story for a separate post. 3. Prefetch directly into shared buffers On a local disk, a prefetch miss costs a disk seek. On disaggregated storage, it costs a network round trip. Hiding that latency matters even more, so HorizonDB makes prefetching explicit, aggressive, and memory aware. Prefetch requests go to the page servers. When PostgreSQL issues a prefetch, HorizonDB sends a read request for the page to the page server that owns it, and does not wait for the answer. Each backend keeps a set of outstanding requests by default, so dozens of page reads overlap instead of running one after another. Sequential scans prefetch explicitly. PostgreSQL's read stream mechanism, which drives sequential scans and other block-range reads, normally avoids prefetching sequential blocks because it expects kernel readahead to cover them. HorizonDB turns that assumption off, so sequential reads are prefetched like any other access pattern. Responses land in their final buffer. In stock PostgreSQL, a prefetch only warms the kernel cache, so the later read still has to copy the page into shared_buffers. In HorizonDB, the page server's response goes straight into a shared buffer. When the query asks for the page, it is already in memory, with no extra copy and no second request to storage. These are only some of the prefetch optimizations we have built into the engine. Others use custom prefetch implementations and logic that tunes how far ahead each query reads. All of them share one goal: hiding storage latency so queries spend less time waiting on I/O and more time doing useful work. What this means for you As a fully managed service, our goal is to delight customers with a best-in-class PostgreSQL experience. You shouldn't have to think about kernel caches, buffer rings, or prefetch windows—that is our job. HorizonDB retains full PostgreSQL compatibility, so applications keep the familiar Postgres programming interface while the engine is tuned to deliver predictable performance on the storage underneath626Views5likes1CommentAI-assisted Oracle-to-PostgreSQL schema conversion in Visual Studio Code
By AI Omar Rajawat, Pranay Lohia, Gautam Juneja, Vikas Nimmagadda, Anil Dogra, Aditya Duvuri We’re seeing significant interest in migrating database workloads from Oracle to Azure Database for PostgreSQL. Historically, schema conversion has been one of the most technically challenging and expensive steps in that journey, demanding specialist knowledge of both engines and stretching migration timelines before a single row of data moves. Recent advances in AI-assisted schema conversion are changing that, turning what used to be a long, manual effort into a faster, more accessible, and lower-cost proposition. This post looks at what that shift means in practice for teams moving to Azure Database for PostgreSQL flexible server. Oracle schema conversion is where the complexity of translating schema and code objects to PostgreSQL becomes visible. Packages, procedures, triggers, custom types, and dependencies built up over years must be mapped to PostgreSQL-compatible definitions while preserving the relationships that make the schema work. Generally available since May 2026, the feature is built into the PostgreSQL extension for Visual Studio Code, published by Microsoft. It helps teams convert Oracle schema and code objects — tables, views, constraints, packages, procedures, functions, and triggers — into PostgreSQL-compatible definitions for Azure Database for PostgreSQL flexible server, with no separate conversion utility to install and no disconnected workflow to manage. It brings schema discovery, conversion, compile validation, and review into one project-based experience. Teams can connect to Oracle, select schemas, and configure a Microsoft Foundry connection in the same project. The extension then translates Oracle-specific constructs, compiles and syntax-checks converted DDL into scratch schemas on Azure Database for PostgreSQL flexible server and surfaces unresolved items as review tasks that teams can work through with GitHub Copilot agent mode. Why schema conversion deserves a better workflow Traditional conversion tools can produce a useful first pass, but the long tail of the process is rarely solved by generating replacement DDL alone. Teams still need clear answers to practical questions: What converted successfully? What needs attention? Which Oracle constructs require a PostgreSQL design decision? Which items should be reviewed first? We designed the schema conversion experience around those questions. The goal is not to hide complexity behind a single score. It is to help teams make steady progress while keeping the work visible and reviewable. What the schema conversion experience provides The experience guides teams through a schema conversion project rather than a collection of separate scripts. It discovers the selected Oracle schemas and converts both the relational model and the code that runs on it: tables, indexes, sequences, primary key, unique, check and foreign key constraints, views and materialized views, synonyms, and Oracle object types — along with the PL/SQL that is usually the hardest part of the migration. Packages and package bodies, package-level state, standalone procedures and functions, and triggers are translated into PostgreSQL functions, procedures, and trigger functions. Oracle-specific constructs are mapped to PostgreSQL equivalents rather than dropped or stubbed out. REF CURSOR and SYS_REFCURSOR become PostgreSQL refcursor; CLOB and BLOB columns become text and bytea ; and NUMBER and VARCHAR2 are mapped by precision and length to their closest PostgreSQL types. Oracle date functions such as ADD_MONTHS, LAST_DAY, MONTHS_BETWEEN, and TRUNC are resolved through the orafce extension, which the project detects and flags for you before deployment. Every converted definition is compiled against scratch schemas on Azure Database for PostgreSQL flexible server, so the deployment script you end up with is an organized, dependency-ordered set of PostgreSQL SQL artifacts that has already been proven to build. Objects that still require human judgment are surfaced as review tasks. Teams can inspect the source and converted definitions side by side, work through the remaining items, and use GitHub Copilot agent mode for guided assistance — keeping automation and human review in the same workflow. How it works: the system architecture Under the hood, the conversion engine follows one principle — the language model is a single, bounded stage; it never has the first or the last word. Deterministic steps decide what the model sees and what it is allowed to produce. Deterministic in. Rule-based extraction reads the Oracle DDL and metadata, then a dependency-graph decomposition splits the estate into bounded, dependency-ordered chunks — so every object is converted in the context that keeps it correct. Bounded conversion. A tiered model strategy through the Microsoft Foundry connection translates each chunk with structured, contract-wrapped input and output. Even very large PL/SQL packages are split and converted member by member, so nothing is trusted as a monolith. Deterministic out. Converted objects pass through review, then compile-and-verify against scratch schemas on Azure Database for PostgreSQL flexible server, and finally dependency-ordered deploy assembly. Unresolved items become review tasks, and every object carries a per-object audit trail. A continuous-improvement loop closes the system: the engineering team maintains a versioned regression suite of supported conversion patterns, and an executable benchmark tracks regressions as the pipeline evolves. Proven in production The approach has been exercised on real enterprise estate. Across representative production runs totaling more than 60,000 schema objects; conversion reached roughly 98% overall — with several schemas converting at a full 100%. The hardest tail, PL/SQL package members, now compiles at 96% across more than 20,000 members thanks to targeted coverage and a resilient compile stage. Conversion outcome and review status are separate measures. Objects that convert and compile cleanly are safe to deploy as they are; the rest are deliberately routed into a prioritized review queue rather than silently accepted. In a representative single-schema run, no object ended in a hard conversion failure, and a cleanly generated object can still involve a PostgreSQL design decision. That is the workflow operating as intended: automation absorbs the volume, and review tasks to keep the remaining judgment calls visible, ordered, and auditable. Measured, not asserted: the SchemaBench eval Quality is verified by running it. SchemaBench, the evaluation framework, deploys each converted schema to a live PostgreSQL database and probes real behavior — whether constraints still fire and whether objects still resolve — rather than comparing DDL text. It scores seven weighted dimensions: semantic fidelity, structure, constraints, completeness, performance, target idioms, and maintainability, behind hard gates. On the e-commerce benchmark, the strongest model scored 96.1 overall with 100% semantic fidelity and a ~98% behavioral-probe pass rate. Every failure a migration hits becomes a permanent regression test the next run has to pass. Learn more: Oracle to Azure Database for PostgreSQL schema conversion overview508Views5likes0CommentsWhy PostgreSQL Still Inspires Builders
The PostgreSQL project turned 30 years old in July. As it enters middle-age, developers and builders rely on it more today than ever. In the crowded and competitive SQL database market, what is driving this popularity? PostgreSQL is a great fully featured database, but it’s not clearly better than the alternatives (SQL Server, MySQL, Oracle) on performance benchmarks or in feature-by-feature comparisons. Its popularity stems from other factors: the community’s focus on reliability and stability, and its open governance and lenient licensing. Together these qualities of PostgreSQL have spawned an ecosystem of extensions and forks built around its stable core. A stable open core My claim that PostgreSQL is more reliable than other databases is based on my experience and not on any hard data. I don’t know of any rigorous study on the count and severity of regressions in new releases of different database engines. Companies love to show off their TPC-C benchmark performance numbers, but we don’t have such an easily measurable metric for reliability. I’ve written code for a few different database engines in my engineering career (SQL Server, MemSQL/Singlestore in the MySQL ecosystem, and Azure HorizonDB in the PostgreSQL ecosystem). Of those, PostgreSQL is on the more conservative, careful and rigorous end of the engineering spectrum. The PostgreSQL committers may move a little more slowly when adding new features, but they move with great care. PostgreSQL’s open and independent governance model prevents a single company from dominating its evolution. That said, large companies such as Microsoft and Amazon employ teams of engineers whose job is writing open-source PostgreSQL engine code (not working on proprietary closed source forks for their respective companies). Application developers have learned to expect a steady stream of new features year after year as a result. PostgreSQL can run on a laptop, your own server running a variety of different operating systems, or on any of a dozen different PostgreSQL cloud services (see Table 1 below). It’s the database that gives builders the most choice and least single vendor lock-in. Built to extend and fork The PostgreSQL source code is also an important building block in many PostgreSQL derived databases and services. Folks building applications in the PostgreSQL ecosystem have a broad choice of vendors and systems. PostgreSQL’s permissive license makes it the most forked open-source database engine. There are forks that specialize in data warehousing, distributed SQL and cloud native OLTP. Its code base is a building block generating billions in revenues across the global economy for various companies. The table below shows some of the PostgreSQL compatible databases or services in production today. They include more specialized forks built to handle use cases that community Postgres is not as good at (i.e., data warehousing) as well as services that run mostly unmodified Postgres as a cloud service. The databases in bold are available on Azure. Category Product/Service Name Compatibility Cloud Native OLTP Azure HorizonDB, AWS Aurora PostgreSQL, Google AlloyDB, Neon, PolarDB PostgreSQL forks designed to run on top of specialized WAL and page storage services enabling lower latency writes, faster failovers, storage auto grow/shrink, efficient read scale out etc. Managed OLTP Services Azure Database for PostgreSQL AWS RDS PostgreSQL, Google CloudSQL PostgreSQL, Supabase, Crunchy Data Run mostly unmodified PostgreSQL as a service attached to off-the-shelf cloud storage (managed disks) and virtual machines Distributed SQL extensions or forks CitusDB (Azure PostgreSQL Elastic Clusters), YugabyteDB, Aurora DSQL, Aurora Limitless Shard data across a cluster of machines with a PostgreSQL compatible distributed query layer on top enabling read and write scale out. Distributed SQL with Postgres compatibility Google Spanner, CockroachDB These are not Postgres forks, but are sharded databases that aim for PostgreSQL query and wire compatibility Data warehousing extensions or forks Greenplum, ParAccel (powers AWS Redshift), Aster Data, TimescaleDB Postgres forks that add parallel query processing and column stores for data warehousing Document database forks or extensions Azure DocumentDB, FerretDB MongoDB compatibility layer on top of Postgres storage Table 1 – Postgres based databases or services; Not an exhaustive list. For more see PostgreSQL derived databases - PostgreSQL wiki No other open-source database has as many successful product offerings based on its source code or its query and wire protocols. MySQL would be a distant second place as far as number of derived databases or services. The databases listed above aren’t all fully compatible with community PostgreSQL, but many are highly compatible. Postgres on Azure At Azure, we’ve built three services around PostgreSQL shown in bold in Table 1 Azure Database for PostgreSQL runs Postgres on Azure virtual machines and Azure managed disks managing backups, high availability, and geo-replica’s as needed. It offers the Citus extension (via the Elastic Clusters configuration) to shard data across a cluster of Postgres worker machines to scale out writes and reads as needed. Azure HorizonDB extends the core PostgreSQL engine with a custom storage layer that has specialized WAL and page services improving performance, reliability and scalability. It frees up Postgres to run queries and transactions by pushing the work to make data durable and highly available into the storage layer (replication, checkpointing, WAL archival, etc.). Azure DocumentDB gives customers the option to build apps against a MongoDB compatible service on top of PostgreSQL’s solid foundation. So, thank you to the PostgreSQL developers (and community) for the hard work they’ve put in over three decades. The family of Postgres derivative or compatible databases wouldn’t exist with their foundational work. Choosing Postgres gives builders the confidence they’re building on a mature, reliable and flexible foundation. Who knows where a new fork or extension may take Postgres in the future. About PostgreSQL Perspectives PostgreSQL Perspectives is a monthly blog series featuring insights from Microsoft engineers, contributors, and builders working with PostgreSQL. Explore more articles on the Microsoft for PostgreSQL blog.533Views4likes0CommentsPostgreSQL on Azure: Two services, one future-proofed ecosystem
At Microsoft Build 2026, the Azure Databases team announced the public preview of Azure HorizonDB, a new powerhouse for PostgreSQL in the cloud. It’s a fully managed, PostgreSQL-compatible cloud database service that delivers sub-millisecond latency, rapid read scale-out, and seamless integration with Microsoft Foundry to empower teams to build secure, compliant and high-performing applications with confidence. At the same event, we also announced several enhancements to the existing managed PostgreSQL offering, Azure Database for PostgreSQL flexible server, boosting performance, analytics and security, and expanding tooling for migration scenarios. Where there was one, now there’s two Now our customers have two strong options to choose from. Azure Database for PostgreSQL remains a reliable, cost-effective, fully open-source compatible workhorse for most users’ everyday needs. Azure HorizonDB is the new PostgreSQL-compatible service with an elastic scale-out architecture built on a highly optimized shared storage system that unlocks 3x faster OLTP performance and other cloud-native advantages for the most demanding workloads. With this new service, you might be wondering which service is the best fit. Let’s take a closer look at these options and explore where they align and differ and what you might want to consider when making your choice. Azure Database for PostgreSQL: Enterprise ready, managed open source Microsoft is one of the largest contributors to the open-source Postgres project and has also invested heavily in PostgreSQL managed services on Azure. Microsoft engineers have authored or co-authored hundreds of code commits and provided extensive reviews, and, to date, have made more than 345 commits and changed more than 64K lines of code for PostgreSQL 19. In the cloud, Azure Database for PostgreSQL is built on the open-source ecosystem, sharing the same extensions and experience that developers and DBAs know and love. Patching, backups, scaling, and monitoring are all simple, one-click operations. If you have an app that already uses a PostgreSQL database, in another cloud or on-premises, migrating to Azure for the added benefits is an easy lift and shift. Inside Azure Database for PostgreSQL Azure Database for PostgreSQL is a mature, feature-rich service already battle-tested by thousands of applications and being used by Fortune 500s across sectors. Enterprise-grade performance: Compute tiers can scale up to 192 vCores with features like read replicas and elastic clusters, which is based on the open-source Citus extension and unique to this class of service, make it easy to right-size workloads and optimize performance by offloading read-heavy traffic or sharding data across nodes. Reliability and security: Backed by Azure’s robust infrastructure, Azure Database for PostgreSQL comes equipped with high availability and zone-redundant options, point-in time restore and security features, including data encryption, network isolation, and Entra ID for enterprise identity. Frictionless migrations: Migrating existing PostgreSQL workloads to Azure Database for PostgreSQL is very straightforward thanks to built-in migration tooling. We’ve even launched AI-assisted tooling for Oracle to PostgreSQL migrations in VS Code, which leverages GitHub Copilot AI to handle app and schema conversions and pre-migration validations. From incorporating cutting-edge hardware, horizontal scaling and Microsoft Fabric and Microsoft Foundry integrations, to supporting 90+ open-source extensions and counting, we continue to optimize the service to meet the needs of our customers building on open-source Postgres. Azure HorizonDB: Next-gen engine to build what’s next Azure HorizonDB was designed and purpose-built to meet the needs of modern AI-native applications and large-scale enterprise migrations. Shireesh Thota, Azure Databases CVP, describes it as the database of choice for workloads that need “a lot of storage, want really fast latencies and significantly higher IOPS.” The service offers faster throughput than open-source PostgreSQL and rapid compute scale-out to support the performance and availability needs of your most demanding applications. Inside Azure HorizonDB Azure HorizonDB is where performance meets possibility, empowering teams to build intelligent apps to scale, modernize, and innovate without compromise. Cloud-tuned performance: The cloud-native architecture of Azure HorizonDB fully decouples compute and storage, enabling users to scale database resources independently. The service can support deployments up to 3,072 vCores and 128 TB of shared storage for a single workload, and provides a single endpoint for read replicas with transparent load balancing to deliver massive read throughput seamlessly to the application. Reliability and security: Azure HorizonDB comes standard with features to support production-level, mission-critical enterprise workloads. Built-in multi-availability zone (AZ) replication reduces failover time to less than 5 seconds, and native integration with Microsoft Entra ID and private endpoint networking ensures Azure HorizonDB meets the Azure-standard enterprise-grade security from day one. Tailored for AI and next-gen apps: Azure HorizonDB provides an extensive set of AI features for building modern applications. In comparison to similar PostgreSQL services in the cloud, IDC described Azure HorizonDB as having "fewer moving parts and a straighter path to AI features.” Azure HorizonDB ships with Microsoft’s latest version of DiskANN vector indexing, which includes advanced filtering that delivers up to 3x faster vector search than traditional pgvector indexes. It also comes with built-in AI Model Management for native integration to Microsoft Foundry models, AI Functions to invoke models from SQL, and AI Pipelines to provide durable orchestration of data modification. Developer productivity: Along with building the best Postgres service, Microsoft is committed to delivering the best Postgres developer tools to the entire community. The Microsoft PostgreSQL extension for Visual Studio (VS) Code makes the coding environment Postgres-aware to help optimize queries, schemas and query performance using AI. Azure HorizonDB is the next-generation of PostgreSQL on Azure for mission-critical, high-throughput, and data-intensive workloads. For everything else, Azure Database for PostgreSQL remains a strong choice. Making your selection Adopting technology should always be driven by a real need. Having two choices is great, but it raises the logical question: “which one is right for me and when?” Choose Azure Database for PostgreSQL when: You’re migrating existing Postgres databases as-is. You can migrate seamlessly to Azure Database for PostgreSQL with minimal tweaks or reconfigurations. You require full open-source compatibility, including rapid adoption of new community versions. Azure Database for PostgreSQL now ships major versions on the same day as the community release. You want to start now and decide later. Azure Database for PostgreSQL is generally available in 60+ regions today. Later, if your project requires greater scale, you can upgrade to Azure HorizonDB, and the migration process will be quick and easy. Choose Azure HorizonDB when: You’re migrating tier-1 workloads to the cloud that already have critical scale, performance, and availability requirements. Up to 128 TB of storage and 3,072 vCores for a single workload makes Azure HorizonDB the ideal destination for these workloads. You anticipate requirements that go beyond Azure Database for PostgreSQL’s capabilities. Azure HorizonDB expands on the capabilities of Azure Database for PostgreSQL, so you’ll be future proofed for scale and reliability. You are focused on building next-gen intelligent apps. Azure HorizonDB is optimized for building new AI applications, enabling developers to ship faster with fewer moving parts. Both services are built on the core Postgres engine, and upgrading to Azure HorizonDB is easy. If your scenario changes, your toolkit can change too. Azure offers the managed service to support you either way. Choose the cloud with the deepest Postgres expertise The PostgreSQL ecosystem on Azure is richer than ever. With both Azure Database for PostgreSQL and Azure HorizonDB, Azure covers the spectrum from steady, everyday workloads to cutting-edge, innovative ones. Whether you’re in a two-person startup or a Fortune 500 enterprise, PostgreSQL on Azure can meet your business’ needs. Now is the perfect time to make a move to Postgres on Azure: Learn more about Azure Database for PostgreSQL Learn more about Azure HorizonDBUltimate Guide to POSETTE: An Event for Postgres, 2026 edition
POSETTE: An Event for Postgres 2026 is back for its 5th year: free, virtual, and unapologetically all about Postgres. No travel budget required and no jet lag involved. Just your laptop, a decent internet connection, and curiosity. This year the POSETTE 2026 schedule has 4 livestreams (16-18 June) with 44 talks at ~25 minutes each—covering everything from query performance and partitioning to Postgres 19 features, extensions, and use cases. Which is awesome but also a bit of work to figure out which talks are for you. Hence this ultimate guide post. Every talk will land on YouTube afterward (un-gated, of course) so if you miss anything you care about, you can watch it later. But if you can catch a livestream in June, do it. That’s when the “virtual hallway track” happens on Discord—where you can ask the POSETTE speakers questions and compare notes with other attendees. Meeting other attendees who have the same weird Postgres problems you do can be reassuring somehow. And yes, there will be swag. This guide is your cheat sheet: I’ve categorized and tagged all 44 talks so you don’t have to read 44 abstracts back-to-back. In this post you'll get: “By the numbers” summary Map of the 44 talks 2 Keynote sessions 23 Postgres core talks 11 Postgres ecosystem talks 8 Azure Database talks Why participate on the virtual hallway track on Discord A big thank you to our amazing speakers Join us for POSETTE 2026 & mark your calendars Official POSETTE 2026 Trailer “By the numbers” summary for POSETTE 2026 Here’s a quick snapshot of what you need to know about POSETTE this year: 3 days 16-18 June 2026 4 livestreams In Americas & EMEA time zones but of course you can watch from anywhere 44 talks All free, all virtual 2 invited keynotes Driving Postgres forward at Microsoft (Livestream 1), and Postgres 19 Hackers Panel: What’s In, What’s Out, & What’s Next (Livestream 2) 25 minutes Average length per talk ~1100 minutes Total minutes in POSETTE 2026 talks 50 speakers POSETTE 2026 speakers include PostgreSQL hackers and contributors, users, application developers, PG community members, Azure engineers, & Azure customers 6 keynote speakers Affan Dar & Charles Feddersen (Livestream 1); and Álvaro Herrera, Heikki Linnakangas, Melanie Plageman, & Thomas Munro (Livestream 2) 19 countries Speakers reside in 19 different countries 23 companies Speakers hail from 23 different companies 17.6% CFP acceptance rate 42 talks selected from 238 submisssions 75% general Postgres talks 33 talks are not cloud-specific at all, they’re about the Postgres technology & ecosystem 25% Azure-related talks 11 of 44 talks feature Azure Database for PostgreSQL or Azure HorizonDB 1 organizing company Organized by the Postgres team at Microsoft, in partnership with AMD 17 languages Published talk videos will have captions available in 17 languages, including English, Czech, Dutch, French, German, Hindi, Italian, Japanese, Korean, Polish, Portuguese, Russian, Spanish, Turkish, Ukrainian, and Chinese Simplified & Chinese Traditional Map of the 44 talks To help you quickly navigate all 44 talks, here’s a map of the high-level categories and detailed topics. : A map of the POSETTE 2026 talks—high-level categories and detailed tags to help you find what you care about 2 Keynote sessions Affan Dar and Charles Feddersen lead the PostgreSQL engineering and product teams at Microsoft, In this keynote, they’ll walk through how Microsoft is contributing to Postgres, both upstream in the open source project and in the cloud database service they build on top of it. Driving Postgres forward at Microsoft, by Affan Dar & Charles Feddersen (Azure Database for PostgreSQL, Azure HorizonDB, VS Code, Dev tools, community, Postgres hacking, open source, PosetteConf, livestream-1) Want to understand how Postgres features get decided? This keynote panel with 4 PostgreSQL committers & hackers will peel back the curtain. You’ll hear what made it into Postgres 19, what didn’t (and why), and get a sneak peek into a few of the things in the oven for Postgres 20. Postgres 19 Hackers Panel: What’s In, What’s Out, & What’s Next, by Álvaro Herrera, Heikki Linnakangas, Melanie Plageman, & Thomas Munro (Postgres 19, Postgres hacking, panel, open source, collaboration, multithreading, livestream-2) 23 Postgres core talks Data Modeling JSON in PostgreSQL - evil data type or just needs to be tamed?, by Boriss Mejias (JSON, performance, data modeling, livestream-1) PostgreSQL Design Patterns, by Chris Ellis (data modeling, SQL, PG use cases, livestream-1) Graph Data Exploring property graphs with SQL/PGQ in PostgreSQL, by Ashutosh Bapat (SQL/PGQ, graph data, data modeling, Postgres 19, livestream-4) LISTEN/NOTIFY LISTEN Carefully: How NOTIFY Can Trip Up Your Database, by Jimmy Angelakos (LISTEN/NOTIFY, PG use cases, triggers, livestream-4) Performance Maintaining Large Tables in PostgreSQL, by Sarat Balijepalli (WAL, performance, scaling Postgres, vacuum, autovacuum, statistics, partitioning, monitoring, livestream-3) My Postgres partitioning cookbook, by Derk van Veen (partitioning, PG use cases, data modeling, performance, livestream-4) PostgreSQL 17 vs 18: Side‑by‑Side Performance Wins in Real‑World Queries, by Divya Bhargov (performance, PG use cases, livestream-3) Vacuuming Enhancements in PostgreSQL 18: Faster, Smarter, More Predictable, by Shashikant Shakya (vacuum, async IO, monitoring, performance, livestream-4) PG Internals Linux and PostgreSQL in the Multiverse of Connections, by Josef Machytka (Linux, PG internals, connection pooling, livestream-2) pg_stats: How Postgres Internal Stats Work, by Richard Yen (statistics, pg_stats, PG internals, query planner, livestream-2) Postgres isn’t slow, your storage is, by Sai Srirampur (storage, IO, performance, livestream-3) PostgreSQL queues done right with PgQ, by Alexander Kukushkin (queues, PG internals, extensions, livestream-2) random_page_cost in Postgres - why the default is 4.0 and should you lower it?, by Tomas Vondra (PG internals, IO, performance, livestream-1) The Wonderful World of WAL, by Bruce Momjian (WAL, PG internals, replication, livestream-3) What's new with constraints in Postgres 18, by Gülçin Yıldırım Jelínek (constraints, data modeling, livestream-2) Postgres Hacking Fuzzing PostgreSQL, by Adam Wolk (PG internals, testing, Dev tools, libpq, security, livestream-1) Journey of developing a performance optimization feature in PostgreSQL, by Rahila Syed (Postgres hacking, PG internals, performance, WAL, replication, livestream-4) The Hitchhiker’s Guide to PostgreSQL Hacking: Don’t Panic, Just Start Small, by Xuneng Zhou (Postgres hacking, PG internals, community, livestream-2) Replication Past, Present, and Future: Logical Decoding and Replication in PostgreSQL, by Hari Kiran (replication, logical decoding, PG internals, livestream-4) Where Does My INSERT Go? A Logical Replication Story, by Hamid Akhtar (replication, PG internals, WAL, livestream-4) Security From Dev to Prod: Securing Postgres the Right Way, by Sakshi Nasha (security, roles, PG use cases, extensions, monitoring, livestream-4) From trust to Tokens: A Short History of PostgreSQL Authentication, by Murat Tuncer (authentication, security, livestream-2) PostgreSQL vs. SQL Server: Security Model Differences, by Taiob Ali (security, authentication, SQL Server, roles, livestream-1) 11 Postgres ecosystem talks Analytics pg_lake: Postgres as a lakehouse, by Marco Slot (pg_lake, extensions, OLAP, data warehouse, Iceberg, DuckDB, analytics, livestream-2) Apache AGE Querying & Visualizing Graphs in Postgres with Apache AGE, by Christian Miles (Apache AGE, graph data, data visualization, SQL/PGQ, Azure HorizonDB, livestream-1) Autotuning Building safety tooling for risk-free AI tuning of Postgres: Fast cars need fast brakes, by Mohsin Ejaz (autotuning, AI, performance, monitoring, livestream-2) Change Data Capture Building Event-Driven Systems with PostgreSQL Logical Replication and Drasi, by Diaa Radwan (Drasi, replication, WAL, CDC, livestream-3) Citus Move Less, Move Faster: Speeding Up Citus Cluster Scaling, by Muhammad Usama (Citus, extensions, performance, scaling Postgres, livestream-4) Dev Tools An MCP for your Postgres DB, by Pamela Fox (MCP, AI, Python, Dev tools, livestream-1) pgcov: Bringing Real Test Coverage to PostgreSQL Code, by Pavlo Golub (testing, Postgres hacking, Dev tools, extensions, CI/CD, livestream-3) PostgreSQL Tooling Across AI Editors and Agents, by Matt McFarland (Dev tools, VS Code, Cursor, AI, data visualization, Apache AGE, graph data, Azure, MCP, Copilot, livestream-1) Django PostgreSQL Generated Columns by Example, by Paolo Melchiorre (app dev, Django, generated columns, livestream-2) Kubernetes Quorum-Based Consistency for Cluster Changes with CloudNativePG Operator, by Jeremy Schneider & Leonardo Cecchi (CloudNativePG, Kubernetes, PG use cases, livestream-3) Performance Modelling Postgres Performance Degradation on Burstable Cloud Instances, by Chun Lin Goh (performance, burstable, compute, QA, livestream-4) 8 Azure Database for PostgreSQL & Azure HorizonDB talks AI-related talks From Queries to Agents: The Next Era of Data Retrieval on PostgreSQL, by Abe Omorogbe (AI, MCP, Azure Database for PostgreSQL, graph data, Apache AGE, Azure HorizonDB, livestream-3) Production RAG at Scale with Azure Database for PostgreSQL, by Julia Schröder Langhaeuser & Paula Santamaría (Azure Database for PostgreSQL, AI, RAG, PG use cases, livestream-3) AMD Choose the Right Azure Infrastructure to Improve Postgres Performance by Over 60%, by Andrew Ruffin (AMD, performance, Azure, compute, Azure Database for PostgreSQL, livestream-1) Azure HorizonDB Why we built Azure HorizonDB for PostgreSQL, by Dingding Lu (Azure HorizonDB, scaling Postgres, livestream-3) Flexible Server pg_duckdb in Action: Accelerating Analytics on Azure Database for PostgreSQL, by Nitin Jadhav (DuckDB, Azure Database for PostgreSQL, extensions, OLAP, analytics, performance, livestream-4) The Rise of PostgreSQL as the Everything Database, by Varun Dhawan (Postgres history, extensions, graph data, Apache AGE, Azure Database for PostgreSQL, DuckDB, Citus, livestream-3) What I’ve Learned Teaching Postgres to 200+ field engineers at Microsoft, by Paula Berenguel (training, Azure, Postgres skilling, livestream-1) Oracle to Postgres Migrating VLDBs from Oracle to Azure Database for PostgreSQL, by Adithya Kumaranchath (migration, Azure Database for PostgreSQL, Oracle to Postgres, livestream-2) Why participate in the virtual hallway track on Discord If you’ve checked out the schedule and plan to watch some of the talks, you might still be wondering: why join live—and why bother with the virtual hallway track on Discord? Here’s how a few of last year’s attendees described the experience: “Very impressed by all the speakers and content I am absolutely shattered as there was so much great content in all the talks over the past 3 days but I have probably learnt more in these sessions than I could have in months of reading up.” “Want to let y’all know how much I got from this onine conference, the speakers were excellent, well-prepared and well-presented. The hosts were informative, engaging, & amusing. The discord hallway channel made me feel connected. I learned a lot and found some new inspiration. I’ll be back next year!” “I have no idea how I’m going to summarise all the interesting stuff for coworkers.” The common thread: the live, shared experience—being able to ask questions, compare notes, and learn alongside other people in real time. How to join the virtual hallway track Head to the #posetteconf channel on Discord (on the Microsoft Open Source Discord) That’s where speakers and attendees hang out during the livestreams—it’s where you can ask questions, share reactions, and just say hi Big thank you to our amazing speakers Every great event starts with great talks—and great talks start with great speakers. Want to learn more about the people behind these talks? Visit the POSETTE 2026 Speaker page Click a speaker’s bio to see their written interview (if available) If a speaker has been a guest on the Talking Postgres podcast in the past, then you’ll find a link to their episode there, too Join us for POSETTE 2026! Mark your calendars I hope you join us for POSETTE 2026. Consider yourself officially invited. As part of the talk selection team, I’m definitely biased—but I truly believe these speakers and talks are worth your time. I’ll be hosting Livestream 1 and you’ll find me in the #posetteconf Discord chat. I hope to see you there. And please: tell your Postgres friends, so they don’t miss out! 🗓️ Add the livestreams to your calendar Livestream 1: Tue 16 June, 8am–2pm PDT (UTC-7) [ register for updates ] and/or [ add to calendar ] Livestream 2: Wed 17 June, 8am–2pm CEST (UTC+2) [ register for updates ] and/or [ add to calendar ] Livestream 3: Wed 17 June, 8am–2pm PDT (UTC-7) [ register for updates ] and/or [ add to calendar ] Livestream 4: Thu 18 June, 8am–2pm CEST (UTC+2) [ register for updates ] and/or [ add to calendar ] Watch last year’s POSETTE 2025 talks in advance: And if you want to get ready, you can watch talks from the POSETTE 2025 playlist on YouTube anytime, anywhere. Lots of solid, useful, and evergreen Postgres talks in there. “Official Trailer” for POSETTE 2026 is on YouTube To help more developers, community members, and Postgres users discover POSETTE 2026, our team created this short video trailer. Take a peek and share it with friends as an invitation of sorts. We’re trying to make sure that people don’t miss their opportunity to be part of the livestreams and ask questions on the discord during the conference (as well as watch the talks on YouTube after the event is over.) Watch and share the trailer: Official Trailer for POSETTE: An Event for Postgres 2026 Acknowledgements & Gratitude I’ve already thanked the 50 amazing speakers above. In addition, thanks go to Silvano Coriani, Cornelia Biacsics, Aaron Wislang, and My Nguyen for reviewing parts of this post before publication. I also want to thank the team at AMD for their partnership and support of POSETTE this year! And of course, big thank you to the POSETTE 2026 organizing team and POSETTE talk selection team—without you, there would be no POSETTE! Figure 3: Visual invitation to join the virtual hallway track for POSETTE 2026 on the Microsoft Open Source Discord, so you can chat with the speakers & others in the Postgres community1.4KViews3likes0CommentsNovember 2025 Recap: PostgreSQL on Azure
Hello Azure Community, November was an exciting month for PostgreSQL on Azure, packed with announcements at Microsoft Ignite 2025. In this recap, we’ll walk you through the highlights from features recaps to deep-dive sessions so you can catch up on everything you might have missed. If you couldn’t join us live, here are some of the key sessions now available on demand: Modern data modern apps: Innovation with Microsoft Databases AI-assisted migration: The path to powerful performance on PostgreSQL Azure HorizonDB: Deep Dive into a New Enterprise-Scale PostgreSQL The blueprint for intelligent AI agents backed by PostgreSQL Nasdaq Boardvantage: AI-driven governance on PostgreSQL and Microsoft Foundry We also introduced major updates, including Azure HorizonDB preview with AI capabilities and new features for Azure Database for PostgreSQL that make migrations faster, deployments smarter, and performance more predictable. The blog is organized into the following sections: Azure HorizonDB (Preview) Azure Database for PostgreSQL feature announcements Azure HorizonDB: AI features & developer tools Photo Gallery from Ignite Azure HorizonDB (Preview) If it’s not obvious, the introduction of Azure HorizonDB is a big deal. This brand-new, fully managed PostgreSQL service is built for mission-critical workloads and modern AI applications, bringing cloud-native scale, ultra-low latency, and deep Azure integration in one powerful offering. Here are some of the features that we offer with Azure HorizonDB: Scale-out compute architecture supporting up to 3,072 vCores across primary and replica nodes. Auto-scaling shared storage that handles databases up to 128 TB, while achieving sub-millisecond multi-zone commit latencies. Breakthrough throughput up to 3× higher than open-source PostgreSQL for transactional workloads, powered by our storage innovations. Learn more about Azure HorizonDB in our detailed blog. Azure Database for PostgreSQL feature announcements We introduced a wave of new capabilities focusing on performance, analytics, security and AI-assisted migration for Azure Database for PostgreSQL. Among the key general availability announcements were PostgreSQL 18, Fabric mirroring, Elastic clusters, and support for Parquet in the azure_storage extension. We also unveiled several exciting preview features, including Intel and AMD v6-series SKUs, the pg_duckdb extension, and enhanced tooling for Oracle-to-PostgreSQL migrations. All these updates are captured in our blog post explore the full list and learn more. Azure HorizonDB: AI features & developer tools Azure HorizonDB isn’t just built for enterprise-scale workloads it’s also designed to power next-generation AI applications. At Ignite, we introduced advanced AI capabilities including DiskANN with Advanced Filtering, built-in AI model management, and Microsoft Foundry integration. DiskANN Advanced Filtering reduces query latency by up to 3×, depending on filter complexity. AI Model Management enables developers to set up semantic operators directly within the PostgreSQL environment, simplifying AI workflows. Microsoft Foundry Integration adds a PostgreSQL connector, allowing Foundry agents to interact with HorizonDB securely using natural language instead of SQL. General Availability of PostgreSQL extension for VS Code We announced the general availability of the PostgreSQL extension for VS Code, making development faster and more intuitive. The PostgreSQL extension for VS code has now over 300K downloads from the Visual Studio Marketplace! This extension makes it easier for developers to seamlessly interact with any PostgreSQL databases. To learn more about these AI features in Azure HorizonDB, check out our blog post. Photo Gallery from Microsoft Ignite Ignite 2025 brought a lot of great sessions, announcements, and hands-on demos. Here’s a quick photo recap of some key moments from technical deep dives to product launches to hearing real world impact from our amazing customer speakers. POSETTE CFP Now Open We are excited to announce that the Call for Proposals (CFP) for POSETTE: An Event for Postgres 2026 is now open! We’re inviting speakers, practitioners, educators, and community contributors to share their knowledge through talks and demos. If you’re passionate about PostgreSQL, open-source innovation, or building resilient data systems, we’d love to see your submission. CFP Link: https://posetteconf.com/2026/cfp/814Views3likes0Comments
Postgres Skills: Give Your AI Agent PostgreSQL Expertise
Modern application development increasingly relies on AI agents to generate code, configure services, and accelerate delivery. But generic agents often stop at plausible SQL or broad recommendations. They do not reliably inspect the live database, account for PostgreSQL versions and extensions, distinguish self-hosted from managed environments, apply production guardrails, or verify that a change actually works. That gap matters when database decisions affect security, performance, availability, and customer experience. A syntactically correct query can still create an isolation issue, use an incompatible feature, recommend an unsupported managed-service command, or leave an application with a design that does not scale. The solution: PostgreSQL Skills PostgreSQL Skills closes this gap by giving agents the PostgreSQL expertise, live context, execution tools, and validation workflow needed to turn a generic answer into a safe, production-ready outcome that solves the application’s business problem. Its 32 expert sub-skills support PostgreSQL running locally, self-hosted, or on any cloud; Azure Database for PostgreSQL and HorizonDB. The plugin includes postgres-mcp for live database access and Azure CLI integration for managed-service operations. One install works across GitHub Copilot CLI, VS Code, Claude Code, and Codex CLI. Domain What you can do PostgreSQL Anywhere Build vector search, partition tables, implement row-level security, index JSONB data, and analyze query regressions on local, self-hosted, or cloud deployments Azure Database for PostgreSQL & HorizonDB Provision and scale servers, configure HA/DR and PITR, use Entra ID authentication, plan major-version upgrades, and get HorizonDB (Preview) guidance You do not need to choose a sub-skill or tell the agent which rules apply. The plugin checks your environment and routes each request to the guidance that fits your deployment. Live database context and PostgreSQL expertise, together The included postgres-mcp server gives your agent structured access to the database you are using. It can inspect schemas, roles, extensions, and server capabilities, run queries, and apply changes you approve. This grounds the work in live database state instead of assumptions. The sub-skills guide how the agent uses that access. They define what to check, which rules apply to your deployment, when to ask for confirmation, and how to validate the outcome. Together, postgres-mcp and the sub-skills help the agent move from a generic answer to a change that fits your database and has been verified. Try it yourself Choose a host and follow the setup path for your operating system. Install your host Add the marketplace and install PostgreSQL Skills GitHub Copilot CLI copilot plugin marketplace add microsoft/postgres-skills copilot plugin install postgres-skills@postgres-skills copilot plugin list # confirm postgres-skills is active Claude Code /plugin marketplace add microsoft/postgres-skills /plugin install postgres-skills@postgres-skills /plugin # confirm the plugin appears as installed Codex CLI codex plugin marketplace add microsoft/postgres-skills codex plugin add postgres-skills codex plugin list # confirm postgres-skills is active See it work: three developer scenarios PostgreSQL anywhere: enforce tenant isolation Prompt: "Add row-level security so each tenant can only access its own data." A generic agent with SQL access can write a CREATE POLICY statement. But it may not inspect table ownership, BYPASSRLS roles, existing policies, or how your application establishes tenant context. The policy can look correct while still leaving an isolation gap. With PostgreSQL Skills, the agent inspects the live schema and role model, identifies the tenant key, accounts for owner bypass behavior, and proposes the policy against your actual tables. It asks before enabling RLS, then tests allowed and denied access with representative roles. You get a verified security boundary, not just policy syntax. PostgreSQL application development: build hybrid search Prompt: "Add semantic and keyword search to my product catalog." A generic agent can generate a pgvector query and a full-text search query. It still leaves you to reconcile two result sets, choose compatible indexes, and adapt the example to your schema and PostgreSQL version. With PostgreSQL Skills, the agent inspects your catalog schema and extension availability, designs the embedding and text-search columns, creates the appropriate indexes, and combines both signals with reciprocal rank fusion. It runs the search against your data and verifies the result before calling the implementation complete. Azure PostgreSQL: connect an application without passwords or public access Prompt: "Connect my application to Azure Database for PostgreSQL without passwords or public internet access." A generic agent with Azure CLI access may provide the right ingredients: Entra authentication, a managed identity, and a private endpoint. It may not check which server is targeted, whether private networking is already configured, how the application identity maps to PostgreSQL, or whether disabling an existing authentication path will break deployed applications. With PostgreSQL Skills, the agent confirms the Azure connection and discovers the server, subscription, resource group, networking mode, and current authentication configuration. It identifies the application identity, proposes a private and passwordless connection plan, and explains every Azure and PostgreSQL object that will change. It asks before modifying identity, authentication, or network access, validates token-based connectivity, and leaves existing access in place until you confirm it can be removed. Guardrails for safe execution Acting on a database is only useful if it is safe on any host. One rule is universal: Every destructive or non-reversible action is confirmed with you first. This applies without exception on self-hosted and Azure deployments. If you're connected to Azure, three more rules kick in automatically: Azure guidance uses `azure_pg_admin`, never `SUPERUSER`. It never assumes access that the managed service does not grant. No `ALTER SYSTEM` and no OS-level access on Flexible Server. Azure changes go through az ... parameter set, matching how the service actually works. Connection-aware gating. Azure-only guidance loads only after the live connection confirms isAzure: true. It never guesses your environment or applies Azure rules to a database that is not one. Get started Repo: github.com/microsoft/postgres-skills. Visit the PostgreSQL Skills repository for installation commands, usage examples, and contribution guidance. Explore the open-source collection of PostgreSQL skills for AI coding agents, including installation commands, usage examples, and contribution guidance. Contribute: Follow CONTRIBUTING.md to add a reference file, register its triggers in the routing table, run the validation checks, and submit a pull request. Feedback: open an issue on the repo with what you tried and what broke The takeaway: generic agents can produce plausible database code, but solving real application problems requires PostgreSQL expertise, live environment context, production guardrails, and validation. PostgreSQL Skills brings those capabilities together so your agent can move beyond suggesting an answer to delivering a safe, deployment-aware, and verified outcome.851Views2likes0CommentsSmarter Storage for Azure HorizonDB
A key benefit of Azure HorizonDB comes from its smart storage layer, which works seamlessly with Postgres and takes over durability and high availability work typically done by Postgres itself. This frees Postgres to operate as a stateless compute engine focused on running queries and transactions leaving more CPU, disk, and network bandwidth available for your application’s business logic. For example, HorizonDB’s storage layer handles work such as replicating WAL to read replicas and archiving WAL to blob storage for point-in-time restore. PostgreSQL also no longer needs full-page writes or background dirty-page flushing, that work is handled by the storage layer. The rest of this post explains the storage architecture that enables this division of responsibility. HorizonDB Storage Overview HorizonDB’s storage design is similar to that of Socrates. The write‑ahead log (WAL) is the sole mechanism used to persist writes to storage (Orange in Figure 1). PostgreSQL compute nodes never write data pages to storage directly in HorizonDB (blue in Figure 1). Instead, pages and other on‑disk structures are treated as derived state and are reconstructed by the storage layer from WAL records. Each Postgres instance in a cluster shares the same copy of the data pages in storage (blue “Page Reads” arrow in Figure 1). A Postgres read replica doesn’t need to maintain its own copy of WAL and data pages as in a typical Postgres setup with a hot standby or readable secondary. Figure 1 - HorizonDB WAL and Page Storage HorizonDB uses separate storage services for WAL and data pages. This separation allows each to be specialized for the very different patterns of reads and writes for WAL versus pages. The WAL server is optimized for low latency writes to the tail of the log stream and reads often at or near the tail. The page server is optimized for elastic storage of potentially many terabytes of pages and it must support random reads and writes of pages. This specialization improves query performance as we have demonstrated in the past. Moving Work into Storage Figure 2) shows the work Postgres does in a typical configuration with high availability, backups and WAL archiving configured. The Postgres primary is doing the work to send WAL to the secondary, and archive WAL to blob storage. The primary and secondary nodes both maintain their own complete copies of the data. Figure 2 - Postgres without Smart Storage Figure 3) shows where the equivalent work is done by HorizonDB storage. The primary and secondaries share one copy of the data in storage in this design. Figure 3 – HorizonDB storage offloading work from Postgres Some example work HorizonDB storage is now doing in Figure 3. The work usually done by the Postgres walsender and archiver processes to send WAL to standbys\secondaries or to WAL archive (blob storage) is now done by HorizonDB’s WAL servers in Figure 3) instead of by Postgres as in Figure 2). In HorizonDB, Postgres secondaries don’t ever communicate directly the with primary. When Postgres starts up, it no longer needs to redo WAL to bring stale page content up to date speeding up startup times. HorizonDB’s page servers in Figure 3) take care of page recovery for Postgres and can send it any pages it needs on demand. The Postgres checkpointer and background writer no longer need to write dirty pages to disk. The page server handles this work. Both Postgres primary and any secondaries can retrieve the page versions they need from the page servers. HorizonDB page servers protect against torn pages making Postgres Full page writes unnecessary reducing the amount of WAL generated and improving write throughput. On read replicas, HorizonDB only requires redo of WAL onto pages that the read replica has stored in memory already saving the work to persist the WAL and redo it. HorizonDB read replicas don’t maintain their own private copy of the data, so redo is only used as a mechanism to keep their in-memory copy in sync with the primary. Tables 1) and 2) below summarize the Postgres processes whose work moved into HorizonDBs storage layer. Task Resource Savings Postgres Process Moved WAL sending to Postgres replicas Disk IO, Network IO walsender WAL archiving to blob storage Disk IO, Network IO archiver WAL filtering CPU, Network IO Shared Storage Specific (*) Dirty Page Writing Disk IO background writer Checkpointing Disk IO checkpointer PostgreSQL WAL recovery Disk IO, CPU startup recovering PostgreSQL read replica redo Disk IO, CPU startup recovering PostgreSQL read replica shared storage (read replicas share storage with primary Disk IO Background writer, checkpointer Backups Disk IO pg_dump, pg_basebackup, pg_backup_start, pg_backup_stop Full page writes Disk IO Backends doing WAL writing Hot standby feedback Vacuum accuracy walreceiver Task HorizonDB Storage Component Responsible WAL sending to Postgres replicas WAL Service WAL archiving to blob storage WAL Service WAL filtering WAL Filtering Service Dirty Page Writing Page Server Checkpointing Page Server PostgreSQL WAL recovery Page Server PostgreSQL read replica redo Page Server PostgreSQL read replica shared storage Page Server Backups WAL Service and Page Server Full page writes Page Server Hot standby feedback WAL Filtering Service (*) Table 1) and 2) refer to HorizonDB’s WAL filtering service. We haven’t talked about this service yet. It’s responsible for sharding the WAL stream across many page servers. To store 10s of TBs of data the page servers shard that data out across many machines. The WAL filtering service takes as input the full WAL stream and shards it into the parts that apply to each page server shard, sending only the WAL that applies to a given shard to that shard (reducing network amplification). Some other shared storage OLTP databases do this WAL filtering on the compute VM, within or alongside Postgres, incurring non-trivial CPU use and higher tail latencies on WAL writes. In summary, by moving durability, recovery, and replication into a purpose-built storage layer, HorizonDB simplifies Postgres while freeing up compute resources for query execution. The result is higher throughput, faster recovery, and lower cost, without compromising the familiar Postgres programming interface.803Views2likes0CommentsAI-Powered Retrieval in PostgreSQL with Azure HorizonDB
Developers need flexible, efficient item searches by description. Using a Wikipedia movie dataset, I started with full-text search, then created embeddings for descriptions, and performed semantic searches. Queries combined text or similarity searches with filters. Common questions arose: How to update embeddings as data changes? How to avoid reprocessing all data? How to make AI calls more efficient? I prefer to keep business logic in the app and data manipulation in SQL, but triggers and stored procedures complicate this. This post explores keeping retrieval workflows inside the database, using data, indexes, filters, and rules already in place. Instead of external workers, I want SQL abstractions to handle operations like generating and maintaining embeddings as part of the data model. I begin with relational data, using BM25 text search, generating embeddings with AI Model Management (AIMM) and AI Functions, storing them with pgvector, indexing them with DiskANN, and integrating AI into PostgreSQL. Then I define an AI pipeline to maintain consistency without extra procedural code. The goal is to keep AI processing close to data with declarative SQL. I used a Kaggle movies dataset with 30,000 entries over 11 years, importing a subset for simplicity. Each file has title, description, director, country, year, and ID. HorizonDB and AI extensions I've run this on HorizonDB preview, where I enabled pg_textsearch, pg_vector, DiskANN, and azure_ai extensions: postgres=> select name, current_setting(name) from pg_settings where name in ('server_version', 'azure.extensions') ; name | current_setting ------------------+----------------------------------------------- azure.extensions | pg_diskann,vector,pg_textsearch,azure_ai server_version | 17.9 (Azure HorizonDB (81895d42565)(release)) (2 rows) I downloaded and unzipped the dataset files in the current directory: \! curl -L -o movies-dataset-2016-2026.zip https://www.kaggle.com/api/v1/datasets/download/lakshyaupadhyaya/wikipedia-movies-dataset-2016-2026 \! unzip -o movies-dataset-2016-2026.zip \! rm movies-dataset-2016-2026.zip I created a table where I can load this data and add embeddings later: postgres=> drop table if exists wikipedia_movies ; DROP TABLE postgres=> create table wikipedia_movies ( year int, id bigint, title text, description text, directed_by text, written_by text, produced_by text, starring text, cinematography text, edited_by text, release_date text, country text, language text, primary key (year, id) ); CREATE TABLE postgres=> create index on wikipedia_movies (country) ; CREATE INDEX I loaded data from 2026 using a one-liner that prepends the year from the filename. postgres=> \copy wikipedia_movies from program 'awk ''FNR>1{print substr(FILENAME,1,4)","$0}'' {2026..2026}.csv' with (format csv) COPY 852 Some rows have a NULL description. I updated them with the title so every row has something meaningful to embed or search, and make sure the description cannot be null: postgres=> update wikipedia_movies set description = format('Title: %s', title) where description is null ; UPDATE 22 postgres=> alter table wikipedia_movies alter column description set not null ; ALTER TABLE So far, there's nothing AI-specific here. It's simply PostgreSQL functioning as it always does: storing structured data, enforcing keys, and allowing me to load, clean, and query using SQL. Try full-text search first Before generating embeddings for similarity search, I started with lexical search. Azure Database for PostgreSQL supports pg_textsearch , which provides BM25-based full-text search and scoring. postgres=> create extension if not exists pg_textsearch; CREATE EXTENSION postgres=> create index wikipedia_movies_description_idx on wikipedia_movies using bm25 (description) with (text_config = 'english') ; NOTICE: BM25 index build started for relation wikipedia_movies_description_idx NOTICE: Using text search configuration: english NOTICE: Using index options: k1=1.20, b=0.75 NOTICE: BM25 index build completed: 852 documents, avg_length=35.95 CREATE INDEX Then I can search the descriptions: postgres=> select description <@> 'Spanish tragicomedy autofiction from 2026' as score, title, description from wikipedia_movies where country = 'Spain' and year = '2026' order by score limit 2 ; score | title | description --------------------+------------------+------------------------------------------------------------------------------------------------------------------------------------------------------------------------------------------------------------------------------------------------------------------------------------------------------------------ -17.06686845421791 | Bitter Christmas | Bitter Christmas (Spanish: Amarga Navidad) is a 2026 Spanish tragicomedy film written and directed by Pedro Almodóvar. It stars Bárbara Lennie and Leonardo Sbaraglia alongside Aitana Sánchez-Gijón, Victoria Luengo, Patrick Criado, Milena Smit, and Quim Gutiérrez. It incorporates elements of autofiction. -5.273793399333954 | Aida, the Movie | Aida, the Movie (Spanish: Aída y vuelta) is a 2026 Spanish comedy film directed by Paco León serving as a meta-sequel to the sitcom Aída. (2 rows) Time: 31.024 ms This is the appropriate initial step. When the query includes terms found in the text, BM25 provides search and scoring capabilities. It is transparent, efficient, and easy to combine with relational filters. Nevertheless, lexical search has its limitations. It works best when the query vocabulary matches the data. But what if the user searches by concept rather than exact words? Or if the query is in French while the descriptions are in English? In such situations, embeddings help capture the semantic meaning of the description rather than its words. They do not replace BM25 but serve as an additional signal for retrieval. AI Model Management AI Model Management (AIMM) includes pre-provisioned models, so manual registration is not required, and I've just enabled the managed model: Once successfully enabled, I can see three registered models, which are used by default by the AI functions: postgres=> select alias, model_name, status from model_registry.model_list_all(); alias | model_name | status -------------------+-------------------------+------------ default-chat | gpt-5.4 | registered default-embedding | text-embedding-3-small | registered default-reranker | Cohere-rerank-v4.0-fast | registered (3 rows) postgres=> Without AIMM, you would need to bring your own model, or deploy an OpenAI model in Azure AI Foundry, and register it: postgres=> create extension if not exists azure_ai ; CREATE EXTENSION postgres=> select model_registry.model_add('default-embedding',...) ; model_add ------------------------------------------------------------------------ Model 'default-embedding' (text-embedding-3-small) added successfully. (1 row) Time: 40.762 ms Generate embeddings manually I created a vector column and generated embeddings directly from the movie descriptions. postgres=> create extension if not exists azure_ai ; CREATE EXTENSION postgres=> create extension if not exists vector; CREATE EXTENSION postgres=> alter table wikipedia_movies add column embedding vector(1536), alter column embedding set storage external -- (it's the default) ; ALTER TABLE postgres=> update wikipedia_movies set embedding = azure_openai.create_embeddings( input => description, dimensions => 1536 )::vector(1536) ; INFO: Using user-assigned managed identity authentication method. UPDATE 852 Time: 200905.958 ms (03:20.906) This approach invokes the embedding service separately for each row. These calls are visible if you set client_min_messages to 'log' . Making external service calls asynchronously for each row is not optimal. Performance could be improved by batching the requests into a more complex query: postgres=> with numbered as ( select year, id, description, (row_number() over() - 1) / 100 as batch_num from wikipedia_movies ), batched AS ( select array_agg(year) as years, array_agg(id) as ids, array_agg(description) as texts, batch_num from numbered group by batch_num ), embedded AS ( select unnest(years) as year, unnest(ids) as id, azure_openai.create_embeddings( input => texts, dimensions => 1536 ) as emb from batched ) update wikipedia_movies t set embedding = e.emb::vector(1536) from embedded e where t.year = e.year and t.id = e.id ; UPDATE 852 Time: 10892.871 ms (00:10.893) This is precisely where an abstraction is needed to simplify and optimize embedding generation. I will add that later. After setting the vectors in the table, I can proceed to add a DiskANN index. postgres=> CREATE EXTENSION IF NOT EXISTS pg_diskann ; CREATE EXTENSION postgres=> CREATE INDEX wikipedia_movies_embedding_idx ON wikipedia_movies USING diskann (embedding vector_cosine_ops) ; CREATE INDEX Time: 5369.375 ms (00:05.369) This allows me to perform a semantic query in French on English descriptions while continuing to filter using standard SQL: postgres=> select azure_openai.create_embeddings( input => 'une comédie amère sur le thème de l''auto-fiction' )::vector(1536) <=> embedding as score, title, description from wikipedia_movies where country = 'Spain' and year = '2026' order by score limit 2 ; score | title | description -------------------+------------------+-------------------------------------------------------------------------------------------------------------------------------------------------------------------------------------------------------------------------------------------------------------------------------------------------------------------- 0.692949073279717 | Bitter Christmas | Bitter Christmas (Spanish: Amarga Navidad) is a 2026 Spanish tragicomedy film written and directed by Pedro Almodóvar. It stars Bárbara Lennie and Leonardo Sbaraglia alongside Aitana Sánchez-Gijón, Victoria Luengo, Patrick Criado, Milena Smit, and Quim Gutiérrez. It incorporates elements of autofiction. 0.757078099513101 | Cool Books | Cool Books (Spanish: Casi todo bien)[1] is a 2026 Spanish comedy-drama film directed by Andrés Salmoyraghi and Rafael López Saubidet and written by López Saubidet and Ricardo Uhagón Vivas. It stars Marcel Borràs and Silma López alongside Lorenzo Ferro, Julián Villagrán, Secun de la Rosa, and Adelfa Calvo. (2 rows) Time: 269.598 ms The query goes beyond simple token matching: it searches based on the description's meaning across different languages, while PostgreSQL continues to enforce relational filters on the year and country. The execution plan shows a filtered scan through the DiskANN index: QUERY PLAN ----------------------------------------------------------------------------------- Limit (actual time=1.622..1.642 rows=2 loops=1) -> Custom Scan (DiskANNFilteredScan) (actual time=1.620..1.639 rows=2 loops=1) Strategy: Filter(BitmapHeapScan) -> Vector Rows Retrieved: 2 count TIDs Collected: 31 count Planning Time: 250.003 ms Execution Time: 1.789 ms (7 rows) Time: 283.231 ms This approach is efficient: the "country" predicate leverages the b-tree index for pre-filtering, narrowing the search to 31 rows identified by their TID—tuple identifiers stored in the b-tree leaf nodes. The Approximate Nearest Neighbors search then considers only this pre-filtered list when navigating the vector index, finding the best candidates, and subsequently retrieving the top two. Although I could have used pgvector's HNSW index instead of DiskANN, it lacks pre-filtering capabilities. I now face a maintenance issue: the embeddings remain correct only until the next insert or update of the description. In SQL, I expect indexes to be maintained synchronously by the database rather than by the application, but embedding generation is a step in between. Embedding becomes a pipeline For a one-time load, manually running the UPDATE is sufficient. However, for regular applications, this approach isn't practical. I don't want to remember to run an embedding update whenever new movies arrive, nor do I want an extra worker polling the table, additional queues, retry loops, or extra status tables that can cause data to get out of sync. Instead, I prefer the embedding workflow to be directly linked to the data, with AI pipelines in the AI Functions. A pipeline consists of a source, steps, a trigger, and a sink. In this case, the source is the movie table, the step is embedding generation, the trigger is an on_change event, and the sink is the same table with the embeddings stored as a column within each row’s description. postgres=> SELECT ai.create_pipeline( name => 'movie_embeddings', source => ai.table_source('wikipedia_movies'), steps => ARRAY[ ai.embed( model => 'default-embedding', input => 'description', dimensions => 1536 ) ], trigger => 'on_change', sink => ai.table_sink( 'wikipedia_movies', on_conflict => ARRAY['year', 'id'], on_conflict_action => 'DO UPDATE SET embedding = EXCLUDED.embedding' ) ); NOTICE: trigger "_ai_pipeline_movie_embeddings_trigger" for relation "public.wikipedia_movies" does not exist, skipping create_pipeline -------------------------------------------------- Pipeline 'movie_embeddings' created successfully (1 row) The AI pipeline is configured to insert embeddings into a sink table, with an on-conflict clause that updates the existing row rather than inserts a new one when the key already exists. When the sink table is the source table, this always leads to an insert conflict because the row already exists when the pipeline runs, making it an update. The pipeline creates an internal batch from the source, generates embeddings, and writes them back with ON CONFLICT DO UPDATE. The trigger verifies whether the pipeline is already running in the same transaction to prevent an infinite recursion when it writes back to the same table. I can validate my pipeline by updating all embeddings for each description using the AI model and requesting a backfill: postgres=> select ai.backfill('movie_embeddings') ; NOTICE: table "_ai_batch_d03946bdb634_chunks" does not exist, skipping backfill ----------------------------------------------------------- Pipeline 'movie_embeddings' completed: 852 rows processed (1 row) Time: 10653.393 ms (00:10.65) This was as quick as my batching query because the default batch size is 100. Under the hood: triggers and batches I like to understand what is executed behind the abstraction. The call to ai.create_pipeline() has created an internal trigger on my table: postgres=> \d wikipedia_movies Table "public.wikipedia_movies" Column | Type | Collation | Nullable | Default ------------------+--------------+-----------+----------+--------- year | integer | | not null | id | bigint | | not null | title | text | | | description | text | | | directed_by | text | | | written_by | text | | | produced_by | text | | | starring | text | | | cinematography | text | | | edited_by | text | | | release_date | text | | | country | text | | | language | text | | | embedding | vector(1536) | | | Indexes: "wikipedia_movies_pkey" PRIMARY KEY, btree (year, id) "wikipedia_movies_country_idx" btree (country) "wikipedia_movies_description_idx" bm25 (description) WITH (text_config=english) "wikipedia_movies_embedding_idx" diskann (embedding vector_cosine_ops) Triggers: _ai_pipeline_movie_embeddings_trigger AFTER INSERT OR UPDATE ON wikipedia_movies FOR EACH STATEMENT EXECUTE FUNCTION ai._pipeline_trigger_movie_embeddings() postgres=> \sf ai._pipeline_trigger_movie_embeddings CREATE OR REPLACE FUNCTION ai._pipeline_trigger_movie_embeddings() RETURNS trigger LANGUAGE plpgsql AS $function$ DECLARE running BOOLEAN; BEGIN SELECT EXISTS(SELECT 1 FROM ai.pipeline_runs WHERE pipeline_name = 'movie_embeddings' AND status = 'running') INTO running; IF NOT running THEN PERFORM ai.run('movie_embeddings'); END IF; RETURN NULL; END; $function$ This trigger function is called after each INSERT or UPDATE statement, not after individual rows, and runs the pipeline if it's not already active. The FOR EACH STATEMENT option ensures it triggers once per DML statement rather than per row, enabling batching. By default, it behaves like my previous ai.backfill() , updating all embeddings regardless of description changes. Interestingly, it calls ai.run() instead of ai.backfill() , which can operate incrementally if a tracking column exists in the source table. Only process what changed: incremental pipelines Without an incremental_column specified in the pipeline, it replicates the source table as its batch table and re-embeds all data each time. Generating embeddings again for the unchanged description is inefficient. To prevent this, I should add a timestamp column to indicate each row's last modification time and configure the pipeline to use it as a watermark: postgres=> -- add the tracking column alter table wikipedia_movies add column updated_at timestamptz not null default clock_timestamp() ; postgres=> -- function to set the update_at to now() create or replace function update_timestamp() returns trigger as $$ begin new.updated_at = clock_timestamp(); return new; end; $$ language plpgsql ; postgres=> -- trigger to call the function on insert or update create trigger wikipedia_movies_updated before insert or update on wikipedia_movies for each row execute function update_timestamp() ; Lots of PostgreSQL examples use now() to set the update time, but now() returns the time when the transaction began, not the time when the update occurred, so using it for an incremental approach could miss the changes if a concurrent session ran the pipeline between those two in Read Committed isolation. I use clock_timestamp() which gets the time after the verification that no concurrent pipeline is running. Now I can re-create the pipeline with the incremental column defined: postgres=> select ai.drop_pipeline( 'movie_embeddings' ); drop_pipeline ------------------------------------- Pipeline 'movie_embeddings' dropped (1 row) postgres=> select ai.create_pipeline( name => 'movie_embeddings', source => ai.table_source( 'wikipedia_movies', incremental_column => 'updated_at' ), steps => ARRAY[ ai.embed( model => 'default-embedding', input => 'description', dimensions => 1536 ) ], trigger => 'on_change', sink => ai.table_sink( 'wikipedia_movies', on_conflict => ARRAY['year', 'id'], on_conflict_action => 'DO UPDATE SET embedding = EXCLUDED.embedding' ) ); NOTICE: trigger "_ai_pipeline_movie_embeddings_trigger" for relation "public.wikipedia_movies" does not exist, skipping create_pipeline -------------------------------------------------- Pipeline 'movie_embeddings' created successfully (1 row) When using incremental_column => 'updated_at' , the batch records the last execution time as a checkpoint, so the next run only processes rows with an updated_at value higher than that checkpoint. The next run will then process all rows again: postgres=> select ai.run('movie_embeddings'); NOTICE: table "_ai_batch_ef762cbb918f_chunks" does not exist, skipping run ----------------------------------------------------------- Pipeline 'movie_embeddings' completed: 852 rows processed (1 row) Time: 12231.656 ms (00:12.232) However, a new execution will process only incrementally: postgres=> select ai.run('movie_embeddings'); run ----------------------------------------------------- Pipeline 'movie_embeddings': no new rows to process (1 row) postgres=> update wikipedia_movies set description = description || ' (film Français)' where country = 'France' ; NOTICE: table "_ai_batch_9769bddf6224_chunks" does not exist, skipping UPDATE 7 Time: 477.686 ms postgres=> select ai.run('movie_embeddings'); run ----------------------------------------------------- Pipeline 'movie_embeddings': no new rows to process (1 row) Time: 33.692 ms The 7 updated rows have been handled by the trigger, which set the checkpoint timestamp, ensuring that the next run has no further processing to perform. I loaded only 2026 movies to save AI model tokens. I insert more movies from previous years and specific countries: \copy wikipedia_movies from program 'awk ''FNR>1{print substr(FILENAME,1,4)","$0",,"}'' {2016..2025}.csv' with (format csv) where description is not null and country like '%France%' COPY 1730 Time: 24935.910 ms (00:24.936) The insert has automatically generated 1730 embeddings from the model. The new rows are immediately accessible and can be retrieved using a new query. postgres=> select azure_openai.create_embeddings( input => 'a movie based on a novel from A. Camus' )::vector(1536) <=> embedding as score, year, title, country from wikipedia_movies order by score limit 2 ; score | year | title | country --------------------+------+------------------+----------------- 0.4765376989279472 | 2025 | The Stranger | France, Belgium 0.5485678715584099 | 2024 | An Ordinary Case | France (2 rows) Time: 448.648 ms The result includes the newly inserted movies from previous years. The index remains strongly consistent when the “embedding” column is modified, and the AI pipeline ensures this consistency also applies to changes in the “description” column. It behaves exactly like indexes in SQL: transparent to the application, consistent in the database. More AI functions Generating the embeddings is not the only feature of AI functions. Previously I've updated the description for the movies that didn't have one, simply putting the title in it. However, I can use generate() to get a real description: postgres=> \x Expanded display is on. postgres=> select azure_ai.generate(format( 'Write a short description for the movie %s, directed by %s', title, directed_by )), title from wikipedia_movies where description like 'Title: %' limit 3 ; -[ RECORD 1 ]--------------------------------------------------------------------------------------------------------------------------------------------------------------------------------------------------------------------------------------------------------------------------------------------------------------------------------------------------------------------------- generate | Billie Eilish – Hit Me Hard and Soft: The Tour (Live in 3D) is a concert film directed by James Cameron and Billie Eilish, capturing the energy and emotion of Eilish’s live tour in immersive 3D. Blending striking visuals with powerful performances, the film brings audiences into the heart of the show and offers a vivid celebration of her music and stage presence. title | Billie Eilish – Hit Me Hard and Soft: The Tour (Live in 3D) -[ RECORD 2 ]--------------------------------------------------------------------------------------------------------------------------------------------------------------------------------------------------------------------------------------------------------------------------------------------------------------------------------------------------------------------------- generate | Border 2 is an upcoming Indian war drama directed by Anurag Singh. Serving as a sequel to the iconic film Border, it is expected to bring a powerful story of patriotism, courage, and sacrifice, set against the backdrop of military conflict. title | Border 2 -[ RECORD 3 ]--------------------------------------------------------------------------------------------------------------------------------------------------------------------------------------------------------------------------------------------------------------------------------------------------------------------------------------------------------------------------- generate | *February* (2022) is a drama film directed by Kamen Kalev. The story follows a quiet man through different stages of his life, using minimal dialogue and striking imagery to reflect on solitude, routine, and the passage of time. title | (February 2022) The generate() function doesn't simply repeat the title. Using the title and director as context, it generates a richer description that can be stored in the table, indexed with BM25, embedded for semantic search. Instead of generating text from structured column, with the generate() function, I can do the opposite: create new columns from the description with the extract() function: postgres=> select azure_ai.extract( description, array['genre'] ), title from wikipedia_movies limit 3 ; -[ RECORD 1 ]-------------------------------------- extract | {"genre": "coming-of-age romantic drama"} title | 18th Rose -[ RECORD 2 ]-------------------------------------- extract | {"genre": "drama"} title | Animol -[ RECORD 3 ]-------------------------------------- extract | {"genre": "documentary film"} title | The Best Summer Like embeddings, extracted attributes or additional columns could be maintained automatically through an AI Pipeline when descriptions change. Another function, azure_ai.rank() , can use the re-ranker model on the set of candidates (AIMM installed the Cohere Rerank model). Hybrid search in one query Once the table has both a BM25 index and embeddings, there is no need to choose between lexical and semantic retrieval. For many real applications, the best answer is to get candidates from both approaches and combine them to retrieve the best overall score. A classic way to combine them is Reciprocal Rank Fusion: postgres=> with semantic as ( select year, id, rank() over ( order by embedding <=> azure_openai.create_embeddings( input => 'space opera produced or directed by luc besson', dimensions => 1536 )::vector(1536) ) as r from wikipedia_movies where year between 2016 and 2026 ), lexical as ( select year, id, rank() over ( order by description <@> 'space opera produced or directed by luc besson' ) as r from wikipedia_movies where year between 2016 and 2026 ) select m.year, m.title from wikipedia_movies m join semantic s using (year, id) -- Join both result sets (full join to keep all) full join lexical l using (year, id) -- Reciprocal Rank Fusion (RRF): order by coalesce(1.0 / (60 + s.r), 0) + coalesce(1.0 / (60 + l.r), 0) desc limit 5 ; NOTICE: pg_diskann: Filter selectivity too high (1.0000), skipping filtered vector scan year | title ------+--------------------------------------------- 2017 | Valerian and the City of a Thousand Planets 2025 | Dracula 2016 | Ballerina 2024 | Meanwhile on Earth 2016 | The Warriors Gate (5 rows) Time: 410.727 ms The data and filters remain relational, with both BM25 and vector search options available. Ranking is handled through SQL, embeddings are synchronized through a pipeline, and reranking can be delegated to an AI model when additional precision is required. The notable aspect isn't just PostgreSQL's ability to invoke AI models, but that the entire retrieval workflow, from indexing and filtering to ranking and reranking, remains close to the data and can be expressed declaratively in SQL. Conclusion This example started with a simple retrieval problem: searching movie descriptions, combining lexical and semantic relevance, and keeping embeddings synchronized as data changes. Along the way, it used AI Functions, BM25 full-text search, vector embeddings, DiskANN indexes, and AI Pipelines, all from within PostgreSQL. Those capabilities are part of a broader set of multi-model features in HorizonDB, including built-in AI models and functions, graph queries with Apache AGE, and durable workflow execution. What interested me here was not any individual feature, but how they fit together around the data. Search, embeddings, indexing, and synchronization can be expressed in SQL and managed alongside the application data they depend on. AI applications still need models, prompts, and business logic in the application layer. But retrieval remains a critical foundation. By combining relational data, keyword search, vector search, and automated embedding pipelines within a single PostgreSQL database, HorizonDB reduces the infrastructure required to keep that foundation accurate, consistent, and up to date. If you'd like to try these capabilities yourself, visit the PostgreSQL Hub for sample applications, learning paths, and solution accelerators. The PostgreSQL Developer Forum is also the best place to share feedback, ask questions, and participate in the community.653Views2likes0Comments