autonomous agents
16 Topics
What is the best file format for an AI agent knowledge base?
This is a best practice sharing the best format for an agent and show you why you should convert your PPT, PDF, WORD into a TXT markdown. I had an issue with my agent, time taken to answer was too long, and usually we spend a lot of time asking: What is the best prompt? Why is my agent slow? Why does retrieval sometimes work and sometimes fail? How can I improve answer quality? But I realised I was asking another question much less often: What is actually the best file format for the knowledge base? PDF? Raw text? Markdown? Pre-chunked text? Semantic sections? Context-enriched text? And more importantly: How much does the format alone affect agent performance? I tried to find a quantified benchmark answering this specific question, with the same agent, same source knowledge and same questions, but different knowledge representations. I couldn't find one that really answered what I wanted to measure. So I decided to run the experiment myself on a real case. My first exploratory tests were already surprising: depending on the representation, the agent could be significantly faster and more accurate, despite working from the exact same source information. So I decided to push the test further. My objective I want to identify, without assumptions and based on actual evaluation data, how a long document should be prepared for an LLM knowledge base so that the agent can retrieve, understand, ground and answer from it as reliably as possible. I focused on five dimensions: Answer quality Retrieval reliability Source grounding / citations Execution time Robustness across single-turn and multi-turn questions The broader question I'm trying to answer is: How should we structure knowledge so that an LLM can retrieve and use it as reliably as possible? The test case I deliberately chose a document that isn't particularly friendly for RAG: a 46-page European regulation, https://eur-lex.europa.eu/eli/reg/2011/1169/oj?locale=fr, on the provision of food information to consumers. The information is distributed across articles, definitions, exceptions, annexes, tables, numerical thresholds and cross-references. That makes it useful for testing retrieval: answering correctly often requires finding a very specific piece of information while preserving enough context to understand how it applies. I used the native PDF as the baseline and created 6 additional knowledge-base representations of the same document: Raw TXT Markdown Chunk-ready TXT RAG-oriented units Semantic TXT Contextual TXT One rule: same knowledge, same agent, same instructions, same questions. Only the knowledge representation changes. The benchmark I used two evaluation sets: 42 single-turn questions testing broad coverage of the document: direct facts, thresholds, exceptions, annexes, lists and cross-references. 5 multi-turn conversations containing 13 questions, to see what happens when a user asks a question and then follows up with things like: "And in this case?" "What are the exceptions?" "And for dietary fibre?" This gave me: 47 evaluated test cases / 55 actual questions per format Across all 7 formats: 329 evaluated conversations 385 user questions executed First results Metric Native PDF Best structured representation Overall pass rate 66.0% 85.1% - Contextual TXT Best single-turn score 69.0% 88.1% - Chunk-ready TXT Multi-turn benchmark 40% 80% - Contextual TXT Multi-turn execution time 14m24 5m54 Total benchmark time 44m31 24m49 The quality gap was already substantial: 66.0% → 85.1% That's +19.1 percentage points while keeping the underlying knowledge unchanged. I also saw a major difference in execution time. On the multi-turn test: 14m24 → 5m54 That's approximately 2.4× faster. Across the complete benchmark: 44m31 → 24m49 Around 44% less execution time. These timings represent the complete agent evaluation pipeline, so they shouldn't be interpreted as pure LLM inference latency. But the difference under identical test conditions is large enough that I want to understand it better. Findings There wasn't one format dominating every benchmark. Chunk-ready TXT scored highest on independent questions: 88.1%, while Contextual TXT performed better across multi-turn conversations and finished with the highest overall score. That may suggest that the way we optimise a document for isolated retrieval isn't exactly the same as the way we should prepare it for conversational retrieval. In the contextual version, I tried to make every section understandable when retrieved independently by keeping useful information around it: Source references Section context Retrieval cues Relevant cross-references For regulatory documents, this seems particularly important. A numerical value retrieved alone can be meaningless without knowing which rule it belongs to, under which conditions it applies, and whether another article contains an exception. Where I am now This remains an exploratory benchmark: One document One domain One agent setup One evaluation framework One run per configuration There are plenty of things I still want to test: repeated runs, retrieval-level evaluation, token consumption, larger knowledge bases, other document types, chunk sizes, overlap, contextual headers, and more. But these first results already convinced me that the preparation of the knowledge base deserves much more attention when evaluating an agent. We often spend hours refining instructions while the same information may behave very differently depending on how it reaches the retrieval layer. Next step I'll share the prompts, knowledge-base formats and evaluation methodology on GitHub so the experiment can be reproduced and challenged. I'll keep enriching the repository as I test new formats, improve the evaluation set and add new results. If people here have ideas, edge cases or formats worth testing, I'd genuinely like to include some of them in the next iteration. What would you test next?1KViews3likes3CommentsUpdate: Root Cause Identified
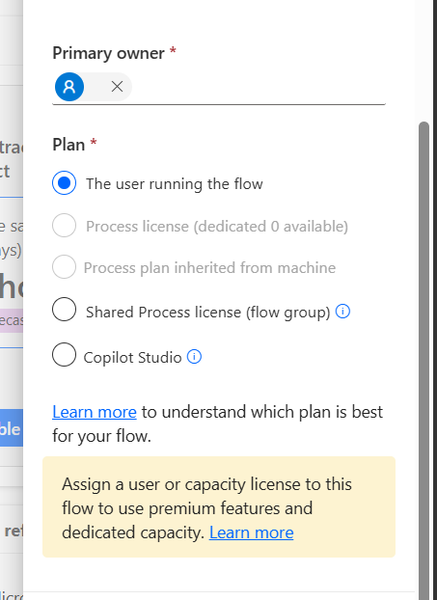
Hi everyone, I would like to share the root cause and solution in case someone else encounters the same issue. The Problem I created several agent flows directly in Power Automate using: https://make.powerautomate.com The flows were configured correctly: The flow starts with When an agent calls the flow The flow ends with Respond to the agent The flow and agent are in the same environment The flow is included in a solution The flow is published and fully functional The flows could be added to an agent and executed successfully. However, unlike flows created directly from Copilot Studio, they did not appear in the Global Tools directory. What I Investigated I verified: Trigger configuration Respond to the agent action Environment consistency Solution membership Publish all customizations Asynchronous response settings Synchronization delays between Power Automate and Copilot Studio None of these were the root cause. Root Cause The issue was related to the workflow Plan. I discovered that: Flows created directly in Power Automate were assigned: Plan = The user running the flow Flows created directly in Copilot Studio were assigned: Plan = Copilot Studio Although the Power Automate flow was fully functional and could be used by the agent, it was not visible in the Global Tools directory. Solution After changing the workflow Plan to: Plan = Copilot Studio the flow immediately appeared in the Global Tools directory. Configuration Location The setting can be found in the workflow properties under: Primary owner → Plan Important Note Based on my testing, changing the Plan to Copilot Studio appears to be a one-way operation and may not be reversible. It may be a good idea to export or save the flow before making the change. Acknowledgements Special thanks to sohnash for reproducing the scenario and providing troubleshooting suggestions, and to Patty_Velasquez for sharing similar observations that helped confirm the behavior. Hopefully this helps others who encounter the same issue. Best regards, Adhonaï KOUKA204Views1like0Comments