autonomous agents
16 TopicsBuild a Local Microsoft Sentinel Triage Agent in VS Code (Copilot + MCP)
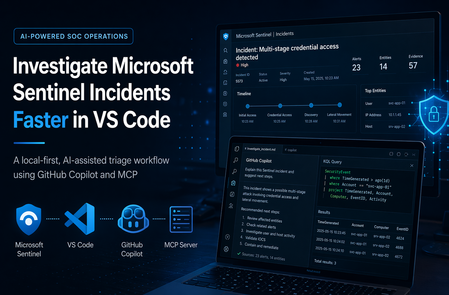
Modern SOC work is not limited by data—it’s limited by the friction of collecting it. This post shows a local-first workflow that lets you investigate Microsoft Sentinel incidents from inside VS Code using GitHub Copilot Chat for reasoning and a small, deterministic MCP toolset for evidence retrieval and (optionally) approval-gated writeback. What you’ll take away: How to structure a Copilot + MCP triage loop that stays grounded in Azure evidence A reliability pattern: fall back to KQL when Sentinel subresource APIs are flaky A safety pattern: draft-first, explicit-approval writeback for incident comments Why This Exists Sentinel triage is powerful but fragmented: you jump between the portal, KQL, entity pivots, and case notes just to answer “what happened?” The goal here is to collapse that into a single, repeatable loop inside the editor. Resolve the incident and pull the underlying alerts/entities Pivot into AzureActivity (and other logs) to identify the actor and outcome Use threat intelligence (TI) for context—not as the decision Generate an evidence-backed narrative and draft comment; write back only on explicit approval Design Principles Evidence first: every claim must be traceable to Sentinel APIs or Log Analytics results Small tool surface: fewer tools, clearer prompting, easier hardening Reliability by design: if one API path fails, pivot to KQL and continue Safety boundary: investigation and writeback are separate, and writeback is approval-gated Architecture & Data Flow A local TypeScript MCP server exposes a handful of triage tools to Copilot Chat in VS Code. Reads come from Sentinel + Log Analytics; writes (incident comments) are optional and require explicit approval. Copilot Chat (VS Code) decides the next step and summarizes outputs MCP server executes allowed tools: incident lookup, alert/entity retrieval, KQL queries, optional comment writeback Evidence sources: Sentinel Incident APIs + Log Analytics tables (SecurityIncident, SecurityAlert, AzureActivity, TI tables) Safety gate: writeback happens only after explicit approval; otherwise you get a draft Tool Surface MCP is useful here because it separates reasoning from execution: Copilot can decide what to do, but only the MCP server can do it—and only through tools you explicitly define and can audit. list_incidents / get_incident (ground the case) get_incident_alerts / get_incident_entities (fast path) run_incident_kql (reliable fallback + pivots) add_incident_comment (draft-first; writes only with approval) The Investigation Loop (3 Steps) Prompt used sentinel-triage-local Investigate Sentinel incident 1478 end to end in workspace Subscription ID/Resource Group/Workspace Name. Resolve the incident ID first, collect underlying alerts and entities, enrich with AzureActivity and TI, determine whether the activity is malicious or benign, and return: 1. Investigation summary 2. Key evidence 3. Entity analysis 4. TI enrichment result 5. Risk assessment 6. Recommended disposition 7. Final incident comment draft Rules: - Use tool output only, no guessing. - If alert/entity subresource APIs fail, pivot to KQL and continue. - Do not submit the comment unless I explicitly say: APPROVE COMMENT. 1) Ground the incident Resolve the human-friendly incident number to the Sentinel incident resource ID, then capture the metadata you need to drive every later pivot. Incident numbers are convenient for analysts, but the actual investigation flow depends on the underlying incident resource ID. Resolving that first gives the workflow a concrete anchor for: Title Severity Owner Status Alert count Analytic rule IDs Incident URL This gives you the stable identifiers (and the URL) needed to retrieve alerts, entities, and supporting logs. 2) Collect alerts and entities (fast path) Pull the alerts behind the incident and the entities they reference. When the incident subresource APIs behave, this is the fastest way to assemble the working set. In the ideal path, the agent can call the incident alert and entity subresources directly. That gives fast access to: Alert IDs Alert names Timestamps Severities Entities Provider metadata 3) Stay reliable: pivot to KQL when APIs fail In real environments, the incident subresource APIs for alerts/entities are not always dependable. When they fail, the workflow switches to Log Analytics and reconstructs the same evidence via KQL—so the investigation continues. SecurityIncident to recover the incident record and alert IDs SecurityAlert to retrieve alert details and entities AzureActivity to determine who or what performed the operation ThreatIntelligenceIndicator and ThreatIntelIndicators for enrichment The High-Signal Pivot: AzureActivity In the incidents I tested, AzureActivity was the fastest way to classify “suspicious deployment” alerts: it tells you who did the action, what operation ran, and whether it succeeded. The evidence showed: The caller was a single Microsoft Entra ID object ID Claims_d.idtyp = "app" Authorization_d.evidence.principalType = "ServicePrincipal" The activity was tied to a policy assignment The operation was MICROSOFT.RESOURCES/DEPLOYMENTS/WRITE The result was BadRequest with InvalidTemplate That pattern typically points to automation (service principal + policy-driven deployment) failing due to a bad template—not an interactive attacker. Threat Intelligence: Use It as Context Enrich observables against TI, but treat it as corroboration: a hit is not proof, and a miss is not a clean bill of health. In my test runs, TI mainly helped refine confidence after AzureActivity and alert evidence established the likely story. Output: An Evidence-Backed Narrative (and a Draft Comment) Once the tools return results, Copilot’s job is synthesis: turn structured evidence into a short narrative an analyst can paste into the case. What happened, who/what triggered it, and whether it succeeded Key supporting evidence (alerts, entities, AzureActivity pivots, TI context) A recommended disposition and a draft incident comment Incident comment written back automatically (after approval) (screenshot): Safety + Reliability: Approval-Gated Writeback The agent can draft a comment automatically, but it cannot change incident state unless the analyst explicitly approves. That boundary is what makes the workflow usable in real operations. After approval, the tool submits the drafted comment directly to the Sentinel incident so the portal reflects the same evidence-backed narrative. Default: return the draft comment only On approval: acquire an ARM token via Azure CLI and submit via curl.exe (hardened with validation + retries) Why This Is Worth Building Less context switching: investigation happens where you already work More consistency: the same loop runs every time, with deterministic tools Better classification: AzureActivity pivots reduce false “user did X” assumptions Safer automation: drafts are automatic; writes are explicit and auditable Conclusion AI is most useful in a SOC when it is constrained: deterministic tools fetch the evidence, the model synthesizes it, and humans keep control of state changes. A local Copilot + MCP workflow hits that sweet spot—faster triage for the SOC analysts.
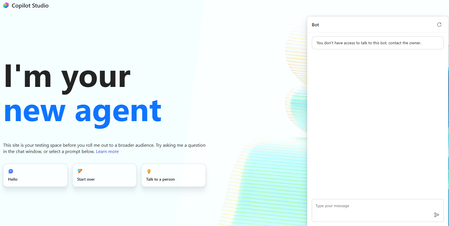
You don't have access to talk to this bot, contact the owner. copilot studio
I created a copilot studio agent and then embedded it inside a code app. It works fine but i am facing the below error. You don't have access to talk to this bot, contact the owner. copilot studio I have provided Microsoft based authentication and am an owner so will have access to the bot. Yet facing the above issue. Is there something i am missing900Views0likes2Comments
What is the best file format for an AI agent knowledge base?
This is a best practice sharing the best format for an agent and show you why you should convert your PPT, PDF, WORD into a TXT markdown. I had an issue with my agent, time taken to answer was too long, and usually we spend a lot of time asking: What is the best prompt? Why is my agent slow? Why does retrieval sometimes work and sometimes fail? How can I improve answer quality? But I realised I was asking another question much less often: What is actually the best file format for the knowledge base? PDF? Raw text? Markdown? Pre-chunked text? Semantic sections? Context-enriched text? And more importantly: How much does the format alone affect agent performance? I tried to find a quantified benchmark answering this specific question, with the same agent, same source knowledge and same questions, but different knowledge representations. I couldn't find one that really answered what I wanted to measure. So I decided to run the experiment myself on a real case. My first exploratory tests were already surprising: depending on the representation, the agent could be significantly faster and more accurate, despite working from the exact same source information. So I decided to push the test further. My objective I want to identify, without assumptions and based on actual evaluation data, how a long document should be prepared for an LLM knowledge base so that the agent can retrieve, understand, ground and answer from it as reliably as possible. I focused on five dimensions: Answer quality Retrieval reliability Source grounding / citations Execution time Robustness across single-turn and multi-turn questions The broader question I'm trying to answer is: How should we structure knowledge so that an LLM can retrieve and use it as reliably as possible? The test case I deliberately chose a document that isn't particularly friendly for RAG: a 46-page European regulation, https://eur-lex.europa.eu/eli/reg/2011/1169/oj?locale=fr, on the provision of food information to consumers. The information is distributed across articles, definitions, exceptions, annexes, tables, numerical thresholds and cross-references. That makes it useful for testing retrieval: answering correctly often requires finding a very specific piece of information while preserving enough context to understand how it applies. I used the native PDF as the baseline and created 6 additional knowledge-base representations of the same document: Raw TXT Markdown Chunk-ready TXT RAG-oriented units Semantic TXT Contextual TXT One rule: same knowledge, same agent, same instructions, same questions. Only the knowledge representation changes. The benchmark I used two evaluation sets: 42 single-turn questions testing broad coverage of the document: direct facts, thresholds, exceptions, annexes, lists and cross-references. 5 multi-turn conversations containing 13 questions, to see what happens when a user asks a question and then follows up with things like: "And in this case?" "What are the exceptions?" "And for dietary fibre?" This gave me: 47 evaluated test cases / 55 actual questions per format Across all 7 formats: 329 evaluated conversations 385 user questions executed First results Metric Native PDF Best structured representation Overall pass rate 66.0% 85.1% - Contextual TXT Best single-turn score 69.0% 88.1% - Chunk-ready TXT Multi-turn benchmark 40% 80% - Contextual TXT Multi-turn execution time 14m24 5m54 Total benchmark time 44m31 24m49 The quality gap was already substantial: 66.0% → 85.1% That's +19.1 percentage points while keeping the underlying knowledge unchanged. I also saw a major difference in execution time. On the multi-turn test: 14m24 → 5m54 That's approximately 2.4× faster. Across the complete benchmark: 44m31 → 24m49 Around 44% less execution time. These timings represent the complete agent evaluation pipeline, so they shouldn't be interpreted as pure LLM inference latency. But the difference under identical test conditions is large enough that I want to understand it better. Findings There wasn't one format dominating every benchmark. Chunk-ready TXT scored highest on independent questions: 88.1%, while Contextual TXT performed better across multi-turn conversations and finished with the highest overall score. That may suggest that the way we optimise a document for isolated retrieval isn't exactly the same as the way we should prepare it for conversational retrieval. In the contextual version, I tried to make every section understandable when retrieved independently by keeping useful information around it: Source references Section context Retrieval cues Relevant cross-references For regulatory documents, this seems particularly important. A numerical value retrieved alone can be meaningless without knowing which rule it belongs to, under which conditions it applies, and whether another article contains an exception. Where I am now This remains an exploratory benchmark: One document One domain One agent setup One evaluation framework One run per configuration There are plenty of things I still want to test: repeated runs, retrieval-level evaluation, token consumption, larger knowledge bases, other document types, chunk sizes, overlap, contextual headers, and more. But these first results already convinced me that the preparation of the knowledge base deserves much more attention when evaluating an agent. We often spend hours refining instructions while the same information may behave very differently depending on how it reaches the retrieval layer. Next step I'll share the prompts, knowledge-base formats and evaluation methodology on GitHub so the experiment can be reproduced and challenged. I'll keep enriching the repository as I test new formats, improve the evaluation set and add new results. If people here have ideas, edge cases or formats worth testing, I'd genuinely like to include some of them in the next iteration. What would you test next?899Views3likes3CommentsNew workflow designer accessing environment variables
Hi, I really enjoy using the new workflow designer. I've a triggered workflow (Email arrives) that I added into a solution. I'd like to use environment variables from within the workflow. The variables and the workflow are in the same solution. Unfortunatly the environment variables are not visible like they were in the old designer. How can I access them ? Thanks in advance700Views0likes4CommentsPower Automate Flows Created Outside Copilot Studio Not Appearing in Tools
Hello everyone, I'm facing an issue with Copilot Studio and would appreciate your advice. Context I have several Power Automate flows that I created directly from: https://make.powerautomate.com My goal is to use these flows as tools within a Copilot Studio agent. All components are in the same Power Platform environment. What I've verified The flows use the "When an agent calls a flow" trigger. The flows end with "Respond to the agent". The flows are saved and published. The agent and flows are added to the same Solution. The solution has been published. I am using the same account and environment for both Power Automate and Copilot Studio. The Issue Flows that are created directly from Copilot Studio appear correctly under: Tools → Add Tool However, flows created from Power Automate (make.powerautomate.com) do not appear in the Tools list, even though they have the same trigger and response configuration. Question Are there additional requirements for a Power Automate flow to be discoverable by Copilot Studio? For example: Does the flow need to be an Agent Flow rather than a standard Cloud Flow? Are there known synchronization or caching issues between Power Automate and Copilot Studio? Is there a specific setting, solution configuration, or publishing step that I may have missed? Any guidance or experience with a similar issue would be greatly appreciated. Thank you!699Views0likes5Comments
Saving a Model Generated File in SharePoint - New Copilot Studio
Hi everyone, I have spent the last two days trying to solve a problem that to me should be a straightforward functionality. I have an agent I made which generates Word file reports. The agent is Cluade Opus 4.8 and it generates the file wonderfully as per my brand guidelines. The document in not a simple content file. Rather these documents can get complex based on the user requirement. Currently the document generates fine and the user gets a popup to download the file. I however need the file to be saved in our share SharePoint library. I created a workflow tool that accepts a file input and then saves it to SharePoint, however when I tried to configure this tool in the agent, the file input parameter was not showing. I then tried to set up a workflow which accepts a url, but the agent cannot seem to access any url or pass it to my workflow. Using a create file tool within the agent and having the agent fill in the file name and content parameters was slow, and the agent was actually attempting to rewrite the file byte-by-byte which lead to the file being re-created and is not scalable for large files. Based on the agent, this is how the file is currently saved: "The file is saved inside my sandboxed container at: /app/created/Sample_Report.docx /app/created/ is a special output directory: any file I place there is automatically packaged by the platform and returned to you as the chat attachment (the Sample_Report.docx chip you see). This is a private, ephemeral location inside my container — it is not a shared network path, and it is not the SharePoint library. Neither you nor the SharePoint tool can reach /app/created/ directly; the platform's attachment mechanism is the only bridge out of it, and as we established, that bridge delivers a direct download rather than a hosted HTTPS URL. So to be precise: the file exists only (a) here in my container at /app/created/Sample_Report.docx, and (b) as the downloadable attachment the platform generated from it. It has not been saved to SharePoint." I need this functionality working as I will have several automations flows around report generation so no human will be available to download the file from within Copilot. Note: I cannot use the old copilot studio as the file generation capabilities are not on par with the new copilot studio experience. The same agent model does not output files, and the create word file node does not output files at the depth and formatting complexity I require. Can anyone please help with a reliable way to get the file save in SharePoint from the New Copilot Studio experience? I'm at my wits end here.Solved599Views0likes1Comment
New Agent Experience - Adding Excel Tool
Hello everyone, I want an agent in the new Copilot Studio experience to read the latest row from an Excel table and then append a new row. Has anyone successfully configured the Excel Online (Business) tools dynamically in the new Copilot Studio experience? Which values should be passed for Location, Document Library/Drive, and File, etc.? In preview, the agent fails but when I prompt it, it ends up adding the row. If anyone could also guide me to resources to learn about how to configure tools in the new experience, I would even be more grateful. Thank you !500Views0likes2Comments
Copilot Studio Agent Shows Usage Limit Error Despite Low Credit Usage
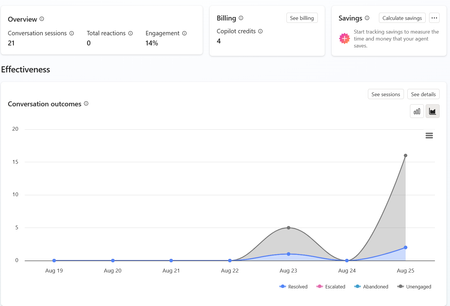
a { text-decoration: none; color: #464feb; } tr th, tr td { border: 1px solid #e6e6e6; } tr th { background-color: #f5f5f5; } Hi everyone, We are experiencing an issue with a Copilot Studio agent and would appreciate any guidance from the community. Scenario: The agent works correctly in the Copilot Studio test environment and responds as expected. However, after integrating the same agent into our web application, users receive the following error: "This agent is currently unavailable. It has reached its usage limit. Please try again later." Additional Information: In Copilot Studio Usage Monitoring, we can only see approximately 4 credits consumed. Based on the reported consumption, we would not expect a usage limit to have been reached. The issue occurs only when accessing the agent through the web application. The Copilot Studio test interface continues to work normally. Questions: Has anyone experienced a similar issue? Could this be related to licensing, capacity allocation, authentication, or channel configuration? Is there any difference in credit consumption or capacity enforcement between the Copilot Studio test environment and embedded web channels? Are there additional monitoring locations where we can verify the actual credit usage and capacity status? Any insights or recommendations would be greatly appreciated.399Views0likes1CommentToken Limit Exceeded? What's Actually Going On and What to Do About It ?
Hi All, Please check out my latest blog on “Token Limit Exceeded” would love to hear your thoughts https://techcommunity.microsoft.com/blog/1c769f9e-c0b0-45a7-af52-fecceca10bb2/token-limit-exceeded-whats-actually-going-on-and-what-to-do-about-it-/4536271300Views0likes0Comments