analytics
845 TopicsLearn What to Do When You Hit Capacity in Azure Databricks!
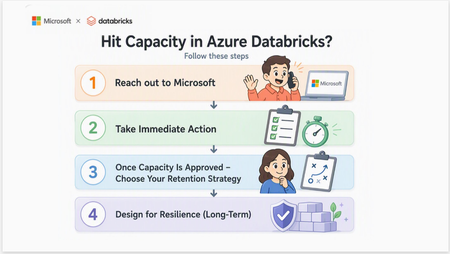
Microsoft's Cloud Architects: Manu Mehta manumehta, Chris Walk cwalk, Eduardo Dos Santos eduardomdossantos, Maria Hito mariahito, Kiran Raja Ch KiranRaja, Paul Singh PaulSingh, Aladdin Alchalabi AladdinAlchalabi and Rafia Aqil Rafia_Aqil Start Here: Engage Microsoft Capacity constraints in Azure Databricks are not an Azure Databricks product issue. Azure Databricks does not own or reserve compute, it dynamically provisions VMs from Azure when clusters are created or scaled. This means cluster creation, autoscaling, or job execution can stall when the underlying VM SKUs are constrained at the regional level. The fastest path to resolution is a structured conversation with your Microsoft account team, who can engage the Azure capacity intake process on your behalf. Create a Quota Support Ticket via Microsoft Support and bring the following to your account team with your Support Ticket Number. Each field maps directly to what capacity intake teams will ask for: missing fields slow the request. What to Prepare Before You Reach Out Your Account Team Field What Capacity Intake Needs Example Subscription IDs The exact Azure subscriptions that will host the workspaces and clusters 7ebee83d-7923-426c-8449-59fd4dff25ab Region(s) Primary region, plus any acceptable alternates East US 2 VM family / SKU Specific series and version requested Eadsv5, ESv4, DSv4, DSv2 Core count / new limit Total vCPU or core count per SKU 10,000 cores for Eadsv5 Workload characteristic CPU-bound vs. memory/shuffle-heavy vs. IO-heavy; batch vs. streaming vs. SQL “Memory-intensive ETL with large joins and shuffles” Scale and timing When you need it, ramp profile, peak vs. steady state “Need by month-end; ramp from 2,000 to 9,650 cores over Q3” Business context Business use case “Migration off AWS” What “Capacity” Really Means: A Layered Mental Model Before diving into fixes, it is important to understand what is actually happening behind the scenes. Capacity constraints can occur at three distinct layers, and solving them requires addressing each one. Layer 1: Azure Infrastructure This is the layer most teams underestimate. Capacity here is governed by: VM SKU availability in the region. D-series and E-series: the two most common Databricks worker families: have repeatedly hit capacity constraints across multiple Azure regions, causing cluster creation failures, autoscale stalls, and provisioning delays. Regional supply constraints, which are dynamic and shared across all Azure tenants. vCPU quotas and limits per subscription, which are separate from regional supply. Quota is your subscription’s limit to deploy resources (like a credit card limit); regional capacity is the underlying infrastructure available. Both must be sufficient. Mechanism Guarantees Capacity Costs Money when idle Discount vCPU quota No No N/A Instance pool Best effort Yes (VM only, no DBU) No Reserved Instance No N/A Yes Savings Plan No N/A Yes CRG Yes, within SLA Yes No, but RI/SP can apply Serverless Platform-Managed No N/A Layer 2: Azure Databricks Platform The Azure Databricks control plane has its own published ceilings that your architecture must proactively respect. Key limits from the official Azure Databricks resource limits documentation: Resource Limit Scope Jobs created per hour 10,000 Workspace Tasks running simultaneously 2,000 Workspace (Run Job and For Each parent tasks excluded) Parent tasks running simultaneously (Run Job / For Each) 750 Workspace SQL warehouses 1,000 Workspace Attached notebooks or execution contexts 145 Cluster Virtual machines 25,000 Per subscription per region Note: For limits marked as non-fixed in the official documentation, you can request an increase through your Azure Databricks account team. Reference: https://learn.microsoft.com/en-us/azure/databricks/resources/limits Layer 3: Workload (Spark Execution) Even when both lower layers cooperate, Spark’s own execution model can produce capacity-like symptoms: Parallelism and task distribution, which dictate how many cores a job can usefully consume. Memory pressure from joins, shuffles, and skewed keys. IO demand and caching behavior, including Delta cache effectiveness and Spark cache misuse. Understanding these layers is critical. Retries sometimes succeed because capacity is dynamic: as other workloads complete, nodes are released back to Azure and briefly become available. Recognizing When You’ve Hit Capacity Capacity issues rarely present as a single clean error. Instead, they appear as inconsistent behaviors: Clusters stuck in Pending state Autoscaling fails or never reaches the desired size Jobs intermittently fail to start Retry attempts sometimes succeed These inconsistencies occur because capacity is shared across Azure tenants and fluctuates throughout the day. Running workloads outside peak business hours in the impacted region’s time zone is one of the most effective short-term mitigations. Inconsistent symptoms are not the same as unknowable ones. Before escalating, confirm what you are actually looking at. Several very different problems produce the symptoms above, and only one of them is a regional capacity shortage. 1. Where to look first Start with the cluster's termination reason and event log in the Azure Databricks workspace. Then cross-check the Azure Activity Log for the workspace's managed resource group over the same time window, which shows the VM allocation attempt and its result. 2. Match signal to the clause What you observe Points to Review What to do Cluster-provider launch or stockout failure Regional capacity for that VM size Immediate Actions, below Quota, core, or vCPU limit referenced Subscription quota, not capacity Request a quota increase — capacity may be fine VM size unavailable in the region or zone Availability restriction, not a transient shortage Switch VM SKU or Family below, retrying will not help Pool returns INSTANCE_POOL_MAX_CAPACITY_FAILURE A Databricks pool ceiling you configured Raise the pool's maximum capacity Cluster starts normally but jobs run slowly, spill, or OOM Workload design, not capacity Why Adding more Nodes is Not Always the Answer, below Only the first row is a genuine Azure capacity constraint. The others are resolved without any capacity conversations 3. Check quota before you conclude capacity Quota and capacity fail in similar ways but are resolved through entirely different paths. Compare current usage against the limit for the VM series and region in question. If usage is below the limit and allocation still fails, the constraint is regional capacity. If usage it at the limit, it is quota and an increase may resolve it outright. Immediate Actions: How to Unblock Your Workloads When you are actively hitting capacity constraints, speed matters. Please reach out to your Microsoft Account team and try these mitigations that are ordered from quickest to most involved. Retry and Run During Off-Peak Hours Capacity availability changes throughout the day as workloads complete and release VMs. Running outside peak business hours for the impacted region significantly improves success rates. Retrying is bounded, not unlimited. As a rule of thumb, retry two or three times across different hours, including at least one off-peak window in the impacted region's time zone. If the same VM size and region fall consistently across a full business day, stop treating it as transient; open a support ticket, engage your account team, and evaluate VM families in parallel. If the workload is production critical with a fixed deadline, or if failures are blocking a migration or cutover already in flight, escalate immediately without waiting for the retry window. Switch VM SKU or Family If a specific VM SKU is constrained, switching to another can immediately unblock provisioning. Move within the same family (for example, DSv4 → DSv5) Or switch families entirely (for example, D-series → F-series or L-series) Choosing the Right VM Family Most Databricks environments default to D-series (general purpose) and E-series (memory optimized). These are also the most heavily used and most capacity-constrained VM families. Consider alternatives based on your workload: VM Family Best For When to Use Trade-off D-series General workloads Default choice Often constrained in high-demand regions E-series Memory-heavy Spark jobs Joins, shuffles, analytics High demand; higher cost F-series CPU-intensive jobs Parsing, transformations Lower memory per core L-series IO-heavy workloads Delta caching, large datasets Higher cost; large local NVMe Practical decision framework: Memory-bound workloads (joins, shuffles): Move from E-series to L-series. Similar memory per core, plus large local NVMe for Delta caching. CPU-bound workloads: Move from D-series to F-series. Higher CPU performance at lower cost. IO-heavy or cache-sensitive workloads: L-series can significantly improve performance and reduce shuffle pressure. Implement Regional Diversity in your Databricks workload As Azure capacity constraints are region and SKU-specific, it is important to build architectural flexibility into your Databricks deployments. For critical or large-scale workloads, consider deploying multiple Databricks workspaces across different Azure regions to reduce dependency on any single region’s capacity. This approach enables: improved resilience to regional capacity constraints greater flexibility in workload placement Important: Multi-region deployment requires deliberate architecture, including deploying separate workspaces and replicating data and configurations across regions; it is not automatic. Why Adding More Nodes Is Not Always the Answer When jobs slow down, the instinct is to scale compute. With Spark, more nodes do not always solve the problem. Common workload issues that masquerade as capacity problems: Data skew Excessive shuffle operations Inefficient partitioning Overuse of UDFs In some workloads, shuffle operations can grow significantly larger than the original input data, placing substantial pressure on compute, memory, disk I/O, and network resources. Because shuffle workloads are distributed across the cluster, adding nodes can improve performance by increasing parallelism. However, that benefit reaches a limit when the bottleneck is caused by data skew, oversized shuffle partitions, network-intensive data movement, or data explosion from joins and aggregations. In these scenarios, the workload becomes constrained by the shuffle pattern itself, and simply adding more nodes does not address the root cause. Instead, the shuffle strategy, partitioning approach, or query design should be optimized. Smarter optimization strategies: Reduce shuffle through repartitioning and query optimization Enable Photon for faster execution Optimize Delta tables using Z-ordering and compaction Leverage caching strategically (not just Spark cache: use the Delta/disk cache) These optimizations can reduce your dependency on scarce VM capacity altogether. Review optimization strategies: The Complete Guide to Azure Databricks Cost Optimization | Microsoft Community Hub. What to Do When Your Capacity Is Approved Once Azure approves your capacity request, retaining it requires active steps. Because Azure capacity is dynamic and shared, approved capacity is held only while compute remains actively deployed and running. This is especially important in highly constrained regions. Microsoft recommends the following: Configure an Instance Pool For workloads that cannot yet use serverless compute, configure an Azure Databricks Instance Pool with a minimum number of idle nodes aligned to your production requirements. An instance pool pre-allocates and maintains a set of idle, ready-to-use VM instances. When a cluster is created from the pool, it draws from these warm nodes: eliminating the need to request new VMs from the regional Azure capacity pool between job runs. Key behaviors: The pool holds a minimum number of nodes continuously, keeping them warm and immediately available. Clusters attached to the pool pull from warm nodes, avoiding re-acquisition from Azure between runs. No DBU charges apply while nodes are idle in the pool. Azure VM infrastructure costs do apply for all minimum idle instances. Size the pool conservatively: aligned to production need only: to balance capacity retention against ongoing cost. Important: Instance pools hold idle nodes on a best-effort basis. Periodic platform events can recycle pool nodes, briefly causing the pool to fall below its configured minimum idle count while Azure re-acquires replacement nodes. Pools significantly improve availability and startup latency, but they do not change the fact that the underlying VMs are still requested from Azure on demand. They are not a hard reservation. Reference: https://learn.microsoft.com/en-us/azure/databricks/compute/pools You can launch a pool's instances against an Azure capacity reservation group by setting the capacity_reservation_group field in the pool's azure_attributes to the group's resource ID. Configure it through the Instance Pools API or the Azure Databricks SDKs. The same requirements apply as for clusters: on-demand instances only, and only workspaces that use VNet injection. Designing for Resilience: Long-Term Best Practices To avoid repeated capacity issues, your architecture needs to evolve beyond reactive mitigations. Plan Ahead with Azure Capacity Reservation Groups For organizations running mission-critical Azure Databricks workloads, Azure Capacity Reservation Groups (CRGs) can provide additional predictability by reserving VM capacity in advance for your Databricks compute resources. Rather than competing for available regional capacity during periods of high demand, reserved capacity helps ensure that the required VM families are available when clusters need to scale or start, Reference: Databricks Clusters API documentation. Note: Before you commit to a reservation, know three things: Auto-termination stops saving VM costs. When a cluster terminates, its reserved capacity returns to an unused state and continues billing at the full VM rate. A pool backed by a reservation is not billed twice. If a team already pays for minimum idle pool nodes in a constrained region, a reservation at comparable spend converts best-effort capacity into SLA-backed capacity. Confirm that the cluster is actually using the reservation. Creating the reservation proves Azure set capacity aside, but it does not prove Databricks is drawing on it. Start a cluster, then check that allocated instances on the reservation rose by the expected node count. If it stays at zero, the usual causes are a VM size mismatch, availability not set to ON_DEMAND_AZURE, a workspace on the Databricks-managed VNet, or the RBAC actions never granted. Note also that omitting capacity_reservation_group when editing an instance pool silently clears it. Step-by-Step Instructions: Attaching a CRG to Databricks is done only through the Clusters/Instance Pools API or the Databricks SDKs, it is not available in the compute UI. Prerequisites VNet-injected workspace only. The workspace must be deployed into your own VNet. Workspaces on the default Databricks-managed VNet cannot use a CRG. On-demand instances only. The cluster/pool must use ON_DEMAND_AZURE availability. Spot and serverless are not eligible. Same region. Create the CRG in the same Azure region as the workspace. Matching VM size. Reserve the exact VM SKU(s) your cluster uses (driver and workers). Sufficient subscription quota for that SKU and core count. Go to the CRG resource -> Access Control -> Add role assignment and add the below roles to the workspace (i.e. databricks-login-prod) Enterprise Application: Microsoft.Compute/capacityReservationGroups/read Microsoft.Compute/capacityReservationGroups/deploy/action Microsoft.Compute/capacityReservationGroups/capacityReservations/read Microsoft.Compute/capacityReservationGroups/capacityReservations/deploy/action Step 1: Create the CRG and reservation in Azure az group create -l eastus -g myResourceGroup az capacity reservation group create \ -n myCapacityReservationGroup -l eastus -g myResourceGroup --zones 1 2 3 az capacity reservation create \ -c myCapacityReservationGroup -n myCapacityReservation \ -l eastus -g myResourceGroup --sku Standard_D2s_v3 --capacity 5 --zone 1 Note: If you want to create the CRG from the Azure Portal you can do the following: Set Subscription, Resource group, Name, and Region (use the same region as your Databricks workspace). Optionally pick Availability zones. Add one or more reservations: Reservation name, Instances (quantity), and VM size (match your cluster's driver/worker SKU). Example here: reservation-eadsv5, 5 × Standard_D4s_v3. Confirm the summary (price, basics, reservations), then click Create. Step 2 Attach the CRG to the cluster (Clusters API or SDK) This would be the Azure Databricks compute cluster, the Spark cluster you create inside your Azure Databricks workspace (Compute → Create compute, or a job cluster). You add an azure_attributes block to the cluster definition. The snippet below is a fragment that goes inside the cluster's JSON, alongside the normal cluster fields. You provide the CRG resource ID; Azure picks a matching reservation within the group. databricks clusters edit --json '{ "cluster_id": "<existing-cluster-id>", "spark_version": "15.4.x-scala2.12", "node_type_id": "Standard_D4s_v3", "num_workers": 4, "azure_attributes": { "availability": "ON_DEMAND_AZURE", "capacity_reservation_group": "/subscriptions/<subscription-id>/resourceGroups/<resource-group>/providers/Microsoft.Compute/capacityReservationGroups/<crg-name>" } }' The cluster's node_type_id (VM SKU) has to be the same VM size you reserved in the CRG (Step 1). If the reservation is Standard_D4s_v3, the cluster's node type must also be Standard_D4s_v3, or it won't draw from the reservation. For instance pools, set the same capacity_reservation_group field via the Instance Pools API or SDK (If you omit the field when editing a pool, Databricks clears any CRG already configured on it). Plan for Capacity Early Understand VM quotas and limits before you need them: not after a constraint occurs. Avoid designing a single SKU. Build flexibility into cluster configurations so you can switch families without re-engineering jobs. Standardize Compute Configurations Consistent, policy-driven environments make it easier to adapt when capacity constraints occur. Use Databricks Cluster Policies to constrain cluster creation to approved, available VM families: this prevents teams from inadvertently requesting constrained SKUs. Also, consider enforcing the CRG setting through a Databricks compute policy, so teams launch only against approved, reserved capacity. Move Toward Serverless Where Possible Serverless compute abstracts capacity management away from the customer. As the Databricks platform expands serverless support, migrating eligible workloads is the most durable long-term strategy. Azure continues to expand infrastructure capacity, but there are no guaranteed timelines for relief in constrained regions. Note: If your workload supports serverless compute, Databricks recommends using serverless compute instead of pools or classic VM-backed clusters. Serverless removes dependency on specific VM SKUs and regional capacity: scaling is managed by the platform with significantly improved availability. Reference: https://learn.microsoft.com/en-us/azure/databricks/serverless-compute. For eligible workloads: including Databricks Jobs (automated workflows), Databricks SQL Warehouses, and Delta Live Tables: serverless compute eliminates VM SKU dependency entirely. Configuration guidance is available in the Azure Databricks deployment guide, Development Section, Step 9. Multi-Region Strategy for Critical Workloads For the most critical workloads, evaluate a multi-region deployment as part of your business's continuity planning. This is a significant architectural investment: see the FAQ for the full scope: but it is the only approach that provides true regional redundancy. Coordinate this with your Microsoft account team. Reference: Azure Databricks & Microsoft Fabric Disaster Recovery: The Complete Better‑Together Strategy for Cloud Architects Know the Difference: Azure Capacity Reservations vs. Reserved Instances vs. Savings Plans When planning Azure infrastructure, it is important to separate capacity assurance from cost optimization. Although these options are sometimes discussed together, they solve different problems. On-Demand Capacity Reservations (ODCR) are designed to reserve compute capacity for workloads that need to run now. They are useful when an organization needs capacity for an eligible VM size in a specific region or availability zone. ODCRs generally offer flexibility because they do not require a long-term commitment and can be canceled when no longer needed. Future Capacity Reservations (FCR) support planned capacity requirements for a future need-by date. They are useful for migrations, major launches, seasonal events, and other predictable workload ramps that require advance capacity planning. In comparison, Azure Reserved VM Instances and Azure Savings Plans for Compute are primarily commercial constructs. Reserved Instances provide discounts for predictable, consistently running workloads through a one-year or three-year commitment. Savings Plans offer broader flexibility by applying discounts to eligible compute usage in exchange for an hourly spending commitment. The key takeaway is simple: capacity reservations address infrastructure availability, while Reserved Instances and Savings Plans address pricing. Organizations can use them together, pairing a capacity reservation with an applicable pricing benefit to improve both workload readiness and cost efficiency. Final Takeaways Capacity issues are infrastructure-level constraints, not Databricks product failures VM family selection is critical: do not rely solely on D-series and E-series Workload optimization can reduce dependency on scarce resources before requesting more capacity Serverless compute is Microsoft’s preferred long-term recommendation for eligible workloads Architectural flexibility: multi-SKU, multi-region awareness is your best defense against future constraints FAQ Why do retries work? Capacity in Azure regions is shared across all tenants and fluctuates throughout the day as workloads complete and release VMs. A retry succeeds when capacity temporarily frees up. Retrying during off-peak hours improves success rates significantly. Why does capacity fluctuate during the day? Capacity is a function of regional supply and concurrent demand. As workloads complete, nodes are released back to Azure. Peak business hours in the impacted region’s time zone tend to be the tightest windows. Why are instance pools not a hard reservation? Pools hold a minimum number of nodes on a best-effort basis. Periodic platform events recycle pool nodes, so a pool can briefly fall below its configured minimum idle count while Azure re-acquires replacement nodes. Setting minimum idle to 0 avoids paying for idle VMs at the cost of slower acquisition time. Pools significantly improve availability and startup latency but do not guarantee capacity at the Azure infrastructure level. Why does serverless behave differently from classic clusters? Serverless compute removes customer control over individual VM SKUs. Databricks manages the underlying capacity across a shared pool. SKU-swap and pool-based mitigations do not apply. Customer-side levers reduce to retry and off-peak scheduling. The trade-off is that serverless is the simplest and most reliable option when the workload supports it. Why is changing regions a last resort? Region changes require redeployment of the Azure Databricks workspace and migration of all dependent artifacts: jobs, clusters, libraries, networking (private endpoints, VNet injection), Unity Catalog assignments, identities, and source data. The destination region must be validated for the same SKU and zonal configuration. For these reasons, region change should always be coordinated with the Microsoft account team and attempted only after preferred mitigations have been exhausted. Why does VM family selection matter so much for capacity? Different VM families have different supply curves. D-series and E-series are the most requested Databricks worker families and the ones most frequently constrained. Choosing a SKU based on whether the workload is memory/shuffle-heavy, CPU-bound, or IO-heavy improves both performance and the probability that capacity is available. The capacity team often steers customers toward newer-generation alternatives when supply differs by generation version. What does the Microsoft account team actually do? They route the request into the Azure capacity intake process, advise alternate SKUs and regions, surface zonal vs. regional considerations, and provide forward visibility into known constraints. The customer’s job is to bring a complete, accurate workload profile so the account team can advocate effectively. It is also recommended to open an Azure Support ticket. This will save time later, as the capacity planning teams would like to track issues and requests via a support ticket. Once an Azure Support ticket is opened, the ticket number should be shared to the Microsoft Account Team, at a minimum to the Customer Success Account Manager (CSAM), if one is assigned to your organization.468Views1like0CommentsThe Gap Between Applications and Analytics, and "How Lakebase Solves It"
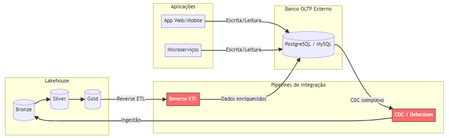
The Problem Nobody Likes to Admit. Imagine this scenario: your data team has built a flawless lakehouse. Ingest pipelines, bronze/silver/gold tiers, gleaming dashboards. Everything is working perfectly. Until someone asks: "And the production app? Where does it store the transactional data?" That's where the headache begins. You need a separate OLTP database (Postgres, MySQL, DynamoDB...), CDC pipelines to bring data into the lakehouse, reverse ETL to return enriched data to the app, and an infrastructure team to keep it all running. The result? Data silos, synchronization latency, operational complexity, and ever-increasing costs. Traditional Architecture (and Its Pain Points) Here's how most companies operate today: Pain points in this architecture: Multiple tools and suppliers for managing Significant latency between writing on OLTP and availability on Lakehouse. Fragmented governance — Unity Catalog doesn't see the external bank. High operational costs associated with synchronization pipelines. What is Lakebase? Lakebase is a fully managed Postgres database natively integrated with the Databricks Data Intelligence Platform. It is designed to bridge the gap between transactional (OLTP) and analytical (OLAP) workloads, unifying everything into a single ecosystem . In simple terms: it's like having a high-performance Postgres server living inside your lakehouse , with unified governance via Unity Catalog, native bidirectional synchronization, and modern capabilities such as autoscaling, scale-to-zero, and database branching. The New Architecture with Lakebase: What changes? Zero external database infrastructure Native bidirectional synchronization (no Debezium, no Airflow, no pain) Unified governance through the Unity Catalog A single control plane for OLTP + OLAP The Architectural Innovations of Lakebase Lakebase is not "just another managed Postgres." It brings modern data engineering concepts to the transactional world. 1. Separation of Compute and Storage Unlike traditional data banks where CPU and disk are coupled, Lakebase completely separates computing resources from storage. This means you scale each independently, paying only for what you use. 2. Copy-on-Write Storage The storage system uses a copy-on-write approach. In practice, when you create a branch of the database, there is no data duplication —only the changes are stored separately. This makes operations like branching and restoring virtually instantaneous. 3. Autoscaling and Scale-to-Zero The compute system automatically adjusts its capacity based on demand. During periods of inactivity, the database scales to zero , eliminating costs. When a request arrives, it "wakes up" in seconds. Database Branching: Git for Your Data This is probably the most innovative feature. Just as developers create branches in Git to work on isolated features, Lakebase allows you to create branches for the entire database . Powerful use cases: Development : each developer has their own branch of the database, without interfering with production. Migration testing : test schema changes in an isolated branch before applying them to production. Instant Restore : Restore the database to any point in time (configurable window from 0 to 30 days) by creating a branch from that point. Two-Way Synchronization: The End of Reverse ETL One of the biggest advantages is the native synchronization between Lakehouse and Lakebase: Synced Tables (Lakehouse → Lakebase) Unity Catalog tables are automatically synchronized to Lakebase, allowing applications to query rich analytical data with low latency. Supports Snapshot, Triggered, and Continuous modes. Lakehouse Sync (Lakebase → Lakehouse) Transactional data from Lakebase is continuously replicated to Delta tables in the Unity Catalog using Change Data Capture (CDC). The destination tables follow the SCD Type 2 standard , maintaining a complete history of changes. This completely eliminates the need for: External CDC tools (Debezium, Fivetran) Reverse ETL pipelines (Census, Hightouch) Custom synchronization jobs in Airflow/Prefect Three Strategic Use Cases Feature Serving for Real-Time ML Lakebase functions as an online store for Databricks' Feature Store. Features computed in the lakehouse are synchronized via Synced Tables to Lakebase, from where ML models query them with millisecond latency. State of AI Agents AI agents need to persist state between requests — conversation context, action history, workflow data. Lakebase provides a native transactional database to store this state with ACID consistency. Transactional Data for Applications Databricks Apps (or any external application) can use Lakebase as their primary database. The integration is native: simply add the Lakebase project as a resource in your app. Additionally, the Data API offers a PostgREST-compatible REST interface for direct HTTP access. Comparison: Before and After Availability Lakebase Autoscaling is available in the following AWS regions: us-east-1, us-east-2,us-west-2 ca-central-1, sa-east-1 eu-central-1, eu-west-1,eu-west-2 ap-south-1, ap-southeast-1,ap-southeast-2 The presence in sa-east-1 is particularly relevant for us in the Brazilian community, ensuring low latency for applications hosted in Brazil. Conclusion Lakebase represents a paradigm shift: instead of treating OLTP and OLAP as separate worlds that need complex "bridges," it unifies them into a single platform. For Brazilian data teams, this means: Fewer tools to manage and integrate. Fewer pipelines that silently break down at 3 a.m. More time focused on generating value with data. Real governance across the entire data lifecycle — from transactional writing to the executive dashboard. Lakehouse finally has its native transactional database. And it speaks Postgres. This post was inspired by concepts from the official Databricks documentation. For more technical details, please refer to the Lakebase documentation . Wiliam Rosa Data Engineer | Machine Learning Engineer linkedin.com/in/wiliamrosa Blog: https://wiliamrosa.github.io236Views1like3Comments
MECM Licensing Use Rights
I need confirmation on the following : Is SQL Server tech rights are included for use with MECM site database and is a separate SQL server license is required solely for the MECM database? Whether the SQL Server use rights provided with MECM support the implementation of HA configuration for the MECM enviroment?105Views0likes1CommentEnabling the Compliance Security Profile (CSP) for HIPAA on Azure Databricks
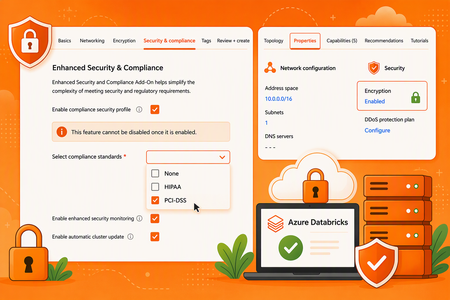
Microsoft Architect's: Aladdin Alchalabi AladdinAlchalabi, Kiran Raja KiranRaja, Peter Lenges PeterLenges, Jessica Reece jareece, Benjamin Coughtry bcoughtry, Anishek Kamal anishekkamal, Tayo Akigbogun takigbogun, Eric Kwashie ekwashie, Peter Lo PeterLo and Rafia Aqil Rafia_Aqil Peer Reviewed: Ted Kim tedkim and Arvind Periyasamy ArvindPeriyasamy Purpose and WHY Azure Databricks has put in place controls to meet the unique compliance needs of highly regulated industries. The requirement for the compliance security profile (CSP) is a joint effort between Microsoft and Databricks for Azure-Databricks workspaces. The value proposition of the compliance security profile is that it provides Customers significantly more hardening and security features. Mandatory Deadline: The Compliance Security Profile (CSP) becomes mandatory for processing HIPAA, HITRUST, and IRAP regulated data on Azure-Databricks by September 1, 2026. Key Dates: Enable the Compliance Security Profile and select HIPAA by September 1, 2026. Prepare for Azure Virtual Network encryption enforcement beginning February 1, 2027. Compliance Responsibility: Enabling CSP supports applicable technical controls but does not, by itself, establish HIPAA compliance. Compliance is a shared responsibility among the customer, Microsoft, and Databricks. Customers must evaluate their administrative, physical, and technical safeguards and confirm that an applicable Microsoft Business Associate Agreement is in place. Enabling CSP on Workspaces These requirements are checked and enforced on new workspaces today, with enforcement on existing workspaces expected in the future; where prerequisites are missing, clusters may fail to start. Prerequisite Requirement Costs There is a 10% cost of the Azure Databricks product spend within each workspace where CSP is enabled. **Review with your account team for any grace period during which the Enhanced Security & Compliance (ESC) add-on is available at no charge. After the grace period ends, a 10% DBU upcharge applies. Enhanced Security & Compliance add-on For existing workspaces: From Azure portal, click the Settings > Security & compliance on an existing Azure Databricks workspace: **Review Note #2 below Azure VNet encryption Azure Virtual Network encryption must be enabled on the Azure Databricks workspace VNet. Infrastructure as code: Update the encryption block on your VNet resource. In Terraform, that's azurerm_virtual_network. Azure portal: Toggle encryption on the VNet (Overview → Properties → Encryption). Command line: Enable it with the Azure CLI or PowerShell. **Review Note #4 below Supported VM instance types Use a VM series that supports VNet encryption and verify compatibility before enabling the profile. **This does not apply to serverless compute. NOTE: Confirm your workspace is using Premium Pricing tier. The profile can be enabled when a workspace is created or on an existing workspace, through the Azure portal, the Azure CLI, PowerShell, an ARM template, or Terraform. Only the Public Preview, Private Preview, and Beta features listed in this section are supported for workspaces with the compliance security profile enabled: Compliance security profile - Azure Databricks | Microsoft Learn Currently, the compliance security profile checks and enforces only the use of specific VM instance types, not the enablement of Azure Virtual Network encryption. Enforcement of the Azure Virtual Network encryption requirement begins on February 1, 2027, including on workspaces that already have the compliance security profile enabled. This flexibility shall allow customers more time to set up VNET encryption. This has been updated in documentation today (See ‘Important’ box). Regarding rollback, CSP can be reversed via a support ticket, if no regulated data has been processed on a particular workspace. Plan for possible effects on cluster startup, networking, feature availability, maintenance operations, and cost. A closer look at VNet encryption CSP is enabled per Databricks workspace, but VNet encryption is applied at the VNet level. Enabling it for a Databricks workload therefore affects every resource within that VNet, not just the workspace. A common approach in a hub-and-spoke design is to leave the hub VNet unencrypted and encrypt only the spoke VNet. The hub typically holds shared services such as the DNS resolver, while the spoke hosts the Databricks workspaces that require CSP. What does it mean for a VNet to be encrypted? An encrypted VNet is a security measure that protects VM-to-VM traffic. Data is encrypted in transit through a DTLS tunnel. This is platform-level encryption, applied automatically to traffic within your VNet and across peered VNets. It requires no changes to your operating system or applications. What happens to my VM-to-VM traffic? Qualifying VM-to-VM traffic is encrypted. Traffic involving unqualified instances simply keeps flowing unencrypted. The only enforcement available today is AllowUnencrypted. Important clarifications Encrypting the VNet does not guarantee all traffic within it will be encrypted. The only traffic that gets encrypted is VM-to-VM traffic where both the source and destination VMs are (1) on a supported SKU and (2) have Accelerated Networking enabled on the network interface. Encrypting the VNet does not drop or break traffic from unsupported SKUs. The only supported GA setting today is to allow unencrypted traffic, so non-qualifying traffic is still permitted; it just isn't encrypted. A future DropUnencrypted setting will drop that traffic instead for further hardening. It isn't available yet, and it's currently unknown whether it will become a required setting for CSP. Review the following recommended steps The steps below represent a validated implementation pattern. The exact network design can vary by environment, but the same prerequisite, isolation, and end-to-end validation principles should be applied. Validated implementation step Recommended approach and expected outcome Isolated sandbox workspace Enable CSP first in a representative non-production workspace. This avoids irreversible changes to DEV or production while the network topology, dependencies, VM compatibility, and operational behavior are validated. Enable CSP and select HIPAA Enable the Compliance Security Profile and select HIPAA under Settings > Security & compliance before processing PHI after September 1, 2026. Enable VNet encryption Enable VNet encryption. **Review Azure Virtual Network encryption limitations: What is Azure Virtual Network encryption? - Azure Virtual Network | Microsoft Learn Start a classic cluster Confirm that a classic cluster starts successfully after CSP and VNet encryption prerequisites are applied. This validates that the selected compute path and VM types remain operational. Validate storage connectivity Confirm storage connectivity continue to work. Confirm rollout readiness Proceed to DEV and production only after the complete private connectivity path, cluster startup, storage access, DNS resolution, data pipelines, and performance have been validated from end to end. Things to Review Enablement is permanent Enabling the compliance security profile, or adding a compliance standard, is intended to be a permanent change. You cannot remove the profile or an individual standard from a workspace that has ever processed regulated data; to revert, you must delete the workspace and create a new one. Validate the configuration in an isolated, representative non-production workspace before enabling DEV or production. Inventory and Assessment Identify Regulated Workspaces: Catalogue all existing Azure-Databricks workspaces. Determine which ones currently process, or are planned to process, data subject to HIPAA, HITRUST, or IRAP. Review Data Pipelines: Map out all data ingress and egress points for these identified workspaces, including connections to on-premises data sources, other cloud services, and external APIs. This helps identify potential network impacts. Verify Prerequisites Before Rollout: Confirm that selected VM instance types support VNet encryption and that every required CSP and networking setting is in place, because missing prerequisites can prevent clusters from starting. Enablement Method: Choose the appropriate tooling for enablement of Azure Portal, Azure CLI, PowerShell, ARM templates, or Terraform to ensure consistency and automation. Keep sensitive data out of customer-defined fields You are solely responsible for ensuring that PHI or other sensitive information is never entered into customer-defined input fields. These include workspace names, compute and resource names, tags, job names, job run names, network names, credential names, storage account names, and Git repository IDs or URLs, all of which may be stored, processed, or accessed outside the compliance boundary. What Changes After Enabling Compliance Security Profile On CSP-enabled workspaces, Partner-powered AI features are disabled by default and some assistive features such as Genie Code are also disabled; a workspace admin can re-enable them if required. In addition, only the specific preview features listed in the compliance security profile documentation are supported. No other Public Preview, Private Preview, or Beta feature may be used to process regulated data. Compliance Security Profile (CSP) enhances the security posture of Azure Databricks by enabling a hardened compute image, enhanced security monitoring, and automatic cluster updates. With automatic cluster updates enabled, classic compute resources are periodically updated and may restart during configured maintenance windows, so production schedules should be planned accordingly. Enhanced security monitoring deploys security monitoring agents on supported compute resources and generates logs that security teams can ingest and analyze. When deploying through ARM templates, CSP, enhancedSecurityMonitoring, and automaticClusterUpdate are configurable security and compliance settings that can be specified as part of the workspace deployment. Why GPU-accelerated compute may be affected Azure Databricks supports several GPU families, but Azure VNet encryption currently documents a narrower GPU list. Please review the list here: What is Azure Virtual Network encryption? - Azure Virtual Network | Microsoft Learn References Compliance security profile: https://learn.microsoft.com/en-us/azure/databricks/security/privacy/security-profile Configure enhanced security and compliance settings: https://learn.microsoft.com/en-us/azure/databricks/security/privacy/enhanced-security-compliance HIPAA, Azure Databricks, Microsoft Learn: https://learn.microsoft.com/en-us/azure/databricks/security/privacy/hipaa What is Azure Virtual Network encryption: https://learn.microsoft.com/en-us/azure/virtual-network/virtual-network-encryption-overview Create a Virtual Network with encryption: https://learn.microsoft.com/en-us/azure/virtual-network/how-to-create-encryption?tabs Hashicorp azurerm_virtual_network: azurerm_virtual_network | Resources | hashicorp/azurerm | Terraform | Terraform Registry1.7KViews2likes0CommentsYour Sentinel AMA Logs & Queries Are Public by Default - AMPLS Architectures to Fix That
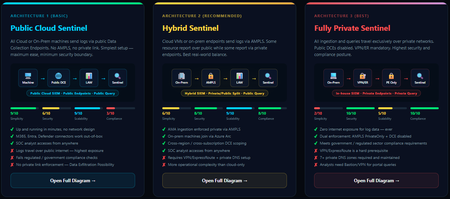
When you deploy Microsoft Sentinel, security log ingestion travels over public Azure Data Collection Endpoints by default. The connection is encrypted, and the data arrives correctly — but the endpoint is publicly reachable, and so is the workspace itself, queryable from any browser on any network. For many organisations, that trade-off is fine. For others — regulated industries, healthcare, financial services, critical infrastructure — it is the exact problem they need to solve. Azure Monitor Private Link Scope (AMPLS) is how you solve it. What AMPLS Actually Does AMPLS is a single Azure resource that wraps your monitoring pipeline and controls two settings: Where logs are allowed to go (ingestion mode: Open or PrivateOnly) Where analysts are allowed to query from (query mode: Open or PrivateOnly) Change those two settings and you fundamentally change the security posture — not as a policy recommendation, but as a hard platform enforcement. Set ingestion to PrivateOnly and the public endpoint stops working. It does not fall back gracefully. It returns an error. That is the point. It is not a firewall rule someone can bypass or a policy someone can override. Control is baked in at the infrastructure level. Three Patterns — One Spectrum There is no universally correct answer. The right architecture depends on your organisation's risk appetite, existing network infrastructure, and how much operational complexity your team can realistically manage. These three patterns cover the full range: Architecture 1 — Open / Public (Basic) No AMPLS. Logs travel to public Data Collection Endpoints over the internet. The workspace is open to queries from anywhere. This is the default — operational in minutes with zero network setup. Cloud service connectors (Microsoft 365, Defender, third-party) work immediately because they are server-side/API/Graph pulls and are unaffected by AMPLS. Azure Monitor Agents and Azure Arc agents handle ingestion from cloud or on-prem machines via public network. Simplicity: 9/10 | Security: 6/10 Good for: Dev environments, teams getting started, low-sensitivity workloads Architecture 2 — Hybrid: Private Ingestion, Open Queries (Recommended for most) AMPLS is in place. Ingestion is locked to PrivateOnly — logs from virtual machines travel through a Private Endpoint inside your own network, never touching a public route. On-premises or hybrid machines connect through Azure Arc over VPN or a dedicated circuit and feed into the same private pipeline. Query access stays open, so analysts can work from anywhere without needing a VPN/Jumpbox to reach the Sentinel portal — the investigation workflow stays flexible, but the log ingestion path is fully ring-fenced. You can also split ingestion mode per DCE if you need some sources public and some private. This is the architecture most organisations land on as their steady state. Simplicity: 6/10 | Security: 8/10 Good for: Organisations with mixed cloud and on-premises estates that need private ingestion without restricting analyst access Architecture 3 — Fully Private (Maximum Control) Infrastructure is essentially identical to Architecture 2 — AMPLS, Private Endpoints, Private DNS zones, VPN or dedicated circuit, Azure Arc for on-premises machines. The single difference: query mode is also set to PrivateOnly. Analysts can only reach Sentinel from inside the private network. VPN or Jumpbox required to access the portal. Both the pipe that carries logs in and the channel analysts use to read them are fully contained within the defined boundary. This is the right choice when your organisation needs to demonstrate — not just claim — that security data never moves outside a defined network perimeter. Simplicity: 2/10 | Security: 10/10 Good for: Organisations with strict data boundary requirements (regulated industries, audit, compliance mandates) Quick Reference — Which Pattern Fits? Scenario Architecture Getting started / low-sensitivity workloads Arch 1 — No network setup, public endpoints accepted Private log ingestion, analysts work anywhere Arch 2 — AMPLS PrivateOnly ingestion, query mode open Both ingestion and queries must be fully private Arch 3 — Same as Arch 2 + query mode set to PrivateOnly One thing all three share: Microsoft 365, Entra ID, and Defender connectors work in every pattern — they are server-side pulls by Sentinel and are not affected by your network posture. Please feel free to reach out if you have any questions regarding the information provided.757Views3likes2CommentsThe Complete Guide to Azure Databricks Cost Optimization
Co-Authored by: Sanjeev Nair Sanjeev Nair and Rafia Aqil Rafia_Aqil This guide walks through a proven approach to Azure Databricks cost optimization, structured in three phases: 1. Discovery, 2. Cluster/Data/Code Best Practices, and 3. Team Alignment & Next Steps. Phase 1: Discovery Assessing Your Current State The following questions are designed to guide your initial assessment and help you identify areas for improvement. Documenting answers to each will provide a baseline for optimization and inform the next phases of your cost management strategy. Environment & Organization Cluster Management Cost Optimization Data Management Performance Monitoring Future Planning What is the current scale of your Databricks environment? How many workspaces do you have? How are your workspaces organized (e.g., by environment type, region, use case)? How many clusters are deployed? How many users are active? What are the primary use cases for Databricks in your organization? Data engineering Data science Machine learning Business intelligence How are clusters currently managed? Manual configuration Automated scripts Databricks REST API Cluster policies What is the average cluster uptime? Hours per day Days per week What is the average cluster utilization rate? CPU usage Memory usage What is the current monthly spend on Databricks? Total cost Breakdown by workspace Breakdown by cluster What cost management tools are currently in use? Azure Cost Management Third-party tools Are there any existing cost optimization strategies in place? Reserved instances Spot instances Cluster auto-scaling What is the current data storage strategy? Data lake Data warehouse Hybrid What is the average data ingestion rate? GB per day Number of files What is the average data processing time? ETL jobs Machine learning models What types of data formats are used in your environment? Delta Lake Parquet JSON CSV Other formats relevant to your workloads What performance monitoring tools are currently in use? Databricks Ganglia Azure Monitor Third-party tools What are the key performance metrics tracked? Job execution time Cluster performance Data processing speed Are there any planned expansions or changes to the Databricks environment? New use cases Increased data volume Additional users What are the long-term goals for Databricks cost optimization? Reducing overall spend Improving resource utilization & cost attribution Enhancing performance Understanding Databricks Cost Structure Total Cost = Cloud Cost + DBU Cost Cloud Cost: Compute (VMs, networking, IP addresses), storage (ADLS, MLflow artifacts), other services (firewalls), cluster type (serverless compute, classic compute) DBU Cost: Workload size, cluster/warehouse size, photon acceleration, compute runtime, workspace tier, SKU type (Jobs, Delta Live Tables, All Purpose Clusters, Serverless), model serving, queries per second, model execution time Diagnose Cost and Issues Effectively diagnosing cost and performance issues in Databricks requires a structured approach. Use the following steps and metrics to gain visibility into your environment and uncover actionable insights. 1. Identify Costly Workloads Account Console Usage Reports: Review usage reports to identify usage breakdowns by product, SKU name, and custom tags. Usage Breakdown by Product and SKU: Helps you understand which services and compute types (clusters, SQL warehouses, serverless options) are consuming the most resources. Custom Tags for Attribution: Tags allow you to attribute costs to teams, projects, or departments, making it easier to identify high-cost areas. Workflow and Job Analysis: By correlating usage data with workflows and jobs, you can pinpoint long-running or resource-heavy workloads that drive costs. Focus on Long-Running Workloads: Examine workloads with extended runtimes or high resource utilization. Key Question: Which pipelines or workloads are driving the majority of your costs? Governance Hub: is a centralized, account-level UI for monitoring and managing governance across Databricks. Note this is a beta feature, we will update this article as we get more information and use-cases on this feature. Now That You’ve Identified Long-Running Workloads, Review These Key Areas: 2. Review Cluster Metrics CPU Utilization: Track guest, iowait, idle, irq, nice, softirq, steal, system, and user times to understand how compute resources are being used. Memory Utilization: Monitor used, free, buffer, and cached memory to identify over- or under-utilization. Key Question: Is your cluster over- or under-utilized? Are resources being wasted or stretched too thin? 3. Review SQL Warehouse Metrics Live Statistics: Monitor warehouse status, running/queued queries, and current cluster count. Time Scale Filter: Analyze query and cluster activity over different time frames (8 hours, 24 hours, 7 days, 14 days). Peak Query Count Chart: Identify periods of high concurrency. Completed Query Count Chart: Track throughput and query success/failure rates. Running Clusters Chart: Observe cluster allocation and recycling events. Query History Table: Filter and analyze queries by user, duration, status, and statement type. Key Question: Is your SQL Warehouse over- or under-utilized? Are resources being wasted or stretched too thin? 4. Review Spark UI Stages Tab: Look for skewed data, high input/output, and shuffle times. Uneven task durations may indicate data skew or inefficient data handling. Jobs Timeline: Identify long-running jobs or stages that consume excessive resources. Stage Analysis: Determine if stages are I/O bound or suffering from data skew/spill. Executor Metrics: Monitor memory usage, CPU utilization, and disk I/O. Frequent garbage collection or high memory usage may signal the need for better resource allocation. 4.1. Spark UI: Storage & Jobs Tab Storage Level: Check if data is stored in memory, on disk, or both. Size: Assess the size of cached data. Job Analysis: Investigate jobs that dominate the timeline or have unusually long durations. Look for gaps caused by complex execution plans, non-Spark code, driver overload, or cluster malfunction. 4.2. Spark UI: Executor Tab Storage Memory: Compare used vs. available memory. Task Time (Garbage Collection): Review long tasks and garbage collection times. Shuffle Read/Write: Measure data transferred between stages. 5. Additional Diagnostic Methods System Tables in Unity Catalog: Query system tables for cost attribution and resource usage trends. Cost Observability Queries Tagging Analysis: Use tags to identify which teams or projects consume the most resources. Dashboards & Alerts: Set up cost dashboards and budget alerts for proactive monitoring. Phase 2: Cluster/Code/Data Best Practices Alignment Cluster UI Configuration and Cost Attribution Effectively configuring clusters/workloads in Databricks is essential for balancing performance, scalability, and cost. Tunning settings and features when used strategically can help organizations maximize resource efficiency and minimize unnecessary spending. Key Configuration Strategies 1. Reduce Idle Time: Clusters to incur costs even when not actively processing workloads. To avoid paying for unused resources: Enable Auto-Terminate: Set clusters automatically shut down after a period of inactivity. This simple setting can significantly reduce wasted spending. Enable Autoscaling: Workloads fluctuate in size and complexity. Autoscaling allows clusters to dynamically adjust the number of nodes based on demand: Automatic Resource Adjustment: Scale up for heavy jobs and scale down for lighter loads, ensuring you only pay for what you use. It significantly enhances cost efficiency and overall performance. For serverless and streaming, using Delta Live Tables with autoscaling is recommended. This approach leads to better resource management and reliability. Use Spot Instances: For batch processing and non-critical workloads, spot instances offer substantial cost savings: Lower VM Costs: Spot instances are typically much cheaper than standard VMs. However, they are not recommended for jobs requiring constant uptime due to potential interruptions. Considerations: Azure Spot VMs are intended for non-critical, fault-tolerant tasks. They can be evicted without notice, risking production stability. No SLA guarantees mean potential downtime for critical applications. Using Spot VMs could lead to reliability issues in production environments. Leverage Photon Engine: Photon is Databricks’ high-performance, vectorized query engine: Accelerate Large Workloads: Photon can dramatically reduce runtime for compute-intensive tasks, improving both speed and cost efficiency. Keep Runtimes Up to Date: Using the latest Databricks runtime ensures optimal performance and security: Benefit from Improvements: Regular updates include performance enhancements, bug fixes, and new features. Apply Cluster Policies: Cluster policies help standardize configurations and enforce cost controls across teams: Governance and Consistency: Policies can restrict certain settings, enforce tagging, and ensure clusters are created with cost-effective defaults. Optimize Storage: type impacts both performance and cost: Switch from HDDs to SSDs: SSDs provide faster caching and shuffle operations, which can improve job efficiency and reduce runtime. Tag Clusters for Cost Attribution: Tagging clusters enables granular tracking and reporting: Visibility and Accountability: Use tags to attribute costs to specific teams, projects, or environments, supporting better budgeting and chargeback processes. Select the Right Cluster Type: Different workloads require different cluster types, see table below for Serverless vs Classic Compute: Feature Classic Compute Serverless Compute Control Full control over config & network Minimal control, fully managed by Databricks Startup Time Slower (unless pre-warmed) Instant Cost Model Hourly, supports reservations Pay-per-use, elastic scaling Security VNet injection, private endpoints NCC-based private connectivity Best For Heavy ETL, ML, compliance workloads Interactive queries, unpredictable demand Job Clusters: Ideal for scheduled jobs and Delta Live Tables. All-Purpose Clusters: Suited for ad-hoc analysis and collaborative work. Single-Node Clusters: Efficient for simple exploratory data analysis or pure Python tasks. Serverless Compute: Scalable, managed workloads with automatic resource management. 11. Monitor and Adjust Regularly: review cluster metrics and query history: Continuous Optimization: Use built-in dashboards to monitor usage, identify bottlenecks, and adjust cluster size or configuration as needed. Code Best Practices Avoid Reprocessing Large Tables Use a CDC (Change Data Capture) architecture with Delta Live Tables (DLT) to process only new or changed data, minimizing unnecessary computation. Ensure Code Parallelizes Well Write Spark code that leverages parallel processing. Avoid loops, deeply nested structures, and inefficient user-defined functions (UDFs) that can hinder scalability. Reduce Memory Consumption Tweak Spark configurations to minimize memory overhead. Clean out legacy or unnecessary settings that may have carried over from previous Spark versions. Prefer SQL Over Complex Python Use SQL (declarative language) for Spark jobs whenever possible. SQL queries are typically more efficient and easier to optimize than complex Python logic. Modularize Notebooks Use %run to split large notebooks into smaller, reusable modules. This improves maintainability. Use LIMIT in Exploratory Queries When exploring data, always use the LIMIT clause to avoid scanning large datasets unnecessarily. Monitor Job Performance Regularly review Spark UI to detect inefficiencies such as high shuffle, input, or output. Review the below table for optimization opportunities: Spark stage high I/O - Azure Databricks | Microsoft Learn Databricks Code Performance Enhancements & Data Engineering Best Practices By enabling the below features and applying best practices, you can significantly lower costs, accelerate job execution, and build Databricks pipelines that are both scalable and highly reliable. For more guidance review: Comprehensive Guide to Optimize Data Workloads | Databricks. Feature / Technique Purpose / Benefit How to Use / Enable / Key Notes Disk Caching Accelerates repeated reads of Parquet files Set spark.databricks.io.cache.enabled = true Dynamic File Pruning (DFP) Skips irrelevant data files during queries, improves query performance Enabled by default in Databricks Low Shuffle Merge Reduces data rewriting during MERGE operations, less need to recalculate ZORDER Use Databricks runtime with feature enabled Adaptive Query Execution (AQE) Dynamically optimizes query plans based on runtime statistics Available in Spark 3.0+, enabled by default Deletion Vectors Efficient row removal/change without rewriting entire Parquet file Enable in workspace settings, use with Delta Lake Materialized Views Faster BI queries, reduced compute for frequently accessed data Create in Databricks SQL Optimize Compacts Delta Lake files, improves query performance Run regularly, combine with ZORDER on high-cardinality columns ZORDER Physically sorts/co-locates data by chosen columns for faster queries Use with OPTIMIZE, select columns frequently used in filters/joins Auto Optimize Automatically compacts small files during writes Enable optimizeWrite and autoCompact table properties Liquid Clustering Simplifies data layout, replaces partitioning/ZORDER, flexible clustering keys Recommended for new Delta tables, enables easy redefinition of clustering keys File Size Tuning Achieve optimal file size for performance and cost Set delta.targetFileSize table property Broadcast Hash Join Optimizes joins by broadcasting smaller tables Adjust spark.sql.autoBroadcastJoinThreshold and spark.databricks.adaptive.autoBroadcastJoinThreshold Shuffle Hash Join Faster join alternative to sort-merge join Prefer over sort-merge join when broadcasting isn’t possible, Photon engine can help Cost-Based Optimizer (CBO) Improves query plans for complex joins Enabled by default, collect column/table statistics with ANALYZE TABLE Data Spilling & Skew Handles uneven data distribution and excessive shuffle Use AQE, set spark.sql.shuffle.partitions=auto, optimize partitioning Data Explosion Management Controls partition sizes after transformations (e.g., explode, join) Adjust spark.sql.files.maxPartitionBytes, use repartition() after reads Delta Merge Efficient upserts and CDC (Change Data Capture) Use MERGE operation in Delta Lake, combine with CDC architecture Data Purging (Vacuum) Removes stale data files, maintains storage efficiency Run VACUUM regularly based on transaction frequency Phase 3: Team Alignment and Next Steps Implementing Cost Observability and Taking Action Effective cost management in Databricks goes beyond configuration and code—it requires robust observability, granular tracking, and proactive measures. Below outlines how your teams can achieve this using system tables, tagging, dashboards, and actionable scripts. Cost Observability with System Tables Databricks Unity Catalog provides system tables that store operational data for your account. These tables enable historical cost observability and empower FinOps teams to analyze spend independently. System Tables Location: Found inside the Unity Catalog under the “system” schema. Key Benefits: Structured data for querying, historical analysis, and cost attribution. Action: Assign permissions to FinOps teams so they can access and analyze dedicated cost tables. Enable Tags for Granular Tracking Tagging is a powerful feature for tracking, reporting, and budgeting at a granular level. Classic Compute: Manually add key/value pairs when creating clusters, jobs, SQL Warehouses, or Model Serving endpoints. Use cluster policies to enforce custom tags. Serverless Compute: Create budget policies and assign permissions to teams or members for serverless workloads. Action: Tag all compute resources to enable detailed cost attribution and reporting. Track Costs with Dashboards and Alerts Databricks offers prebuilt dashboards and queries for cost forecasting and usage analysis. Dashboards: Visualize spend, usage trends, and forecast future costs. Prebuilt Queries: Use top queries with system tables to answer meaningful cost questions. Budget Alerts: Set up alerts in the Account Console (Usage > Budget) to receive notifications when spend approaches defined thresholds. Build Culture of Efficiency To go beyond technical fixes and build a culture of efficiency, by focusing on the below strategic actions: Collaborate with Internal Engineers: Spend time with engineering teams to understand workload patterns and optimization opportunities. Peer Reviews and Code Audits: Conduct regular code review sessions and peer reviews to ensure best practices are followed for Spark jobs, data pipelines, and cluster configurations. Create Internal Best Practice Documentation: Develop clear guidelines for writing optimized code, managing data, and maintaining clusters. Make these resources easily accessible for all teams. Implement Observability Dashboards: Use Databricks’ built-in features to create dashboards that track spend, monitor resource utilization, and highlight anomalies. Set Alerts and Budgets: Configure alerts for long-running workloads and establish budgets using prebuilt Databricks capabilities to prevent cost overruns. 5. Azure Reservations and Azure Savings Plan When optimizing Databricks costs on Azure, it’s important to understand the two main commitment-based savings options: Azure Reservations and Azure Savings Plans. Both can help you reduce compute costs, but they differ in flexibility and how savings are applied. Which Should You Choose? Reservations are ideal if you have stable, predictable Databricks workloads and want maximum savings. Savings Plans are better if you expect your compute needs to change, or if you want a simpler, more flexible way to save across multiple services. Pro Tip: You can combine both options—use Reservations for your baseline, always-on Databricks clusters, and Savings Plans for bursty, variable, or new workloads. Summary Table: Action Steps It’s critical to monitor costs continuously and align your teams with established best practices, while scheduling regular code review sessions to ensure efficiency and consistency. Area Best Practice / Action System Tables Use for historical cost analysis and attribution Tagging Apply to all compute resources for granular tracking Dashboards Visualize spend, usage, and forecasts Alerts Set budget alerts for proactive cost management Scripts/Queries Build custom analysis tools for deep insights Cluster/Data/Code Review & Align Regularly review best practices, share findings, and align teams on optimization Save on your Usage Consider Azure Reservations and Azure Savings Plan544Views2likes0Comments
From Doubt to Victory: How I Passed Microsoft SC-200
Hey everyone! I wanted to share my journey of how I went from doubting my chances to successfully passing the Microsoft SC-200 exam. At first, the idea of taking the SC-200 seemed overwhelming. With so many topics to cover, especially with the integration of Microsoft security technologies, I wasn’t sure if I could pull it off. But after months of studying and staying consistent, I finally passed! 🎉 Here’s what worked for me: Study Plan: I created a structured study schedule and stuck to it. I broke down each section of the exam objectives and allocated time for each part. Authentic Exam Questions: I used it-examstest for practice exams. Their realistic test format helped me get a good grasp of the exam pattern. Plus, the explanations for the answers were super helpful in understanding the concepts. Practice Exams: I did multiple mock tests. Honestly, they helped me more than I expected! They boosted my confidence, and I could pinpoint areas where I needed to improve. SC-200 Study Materials: I relied on a combination of online courses, books, and video resources. Watching the study videos and taking notes helped me retain the information better. Don’t Cram: I didn’t leave things to the last minute. It took me about 2-3 months of consistent study to get comfortable with the material. I made sure to take breaks and not burn myself out. Passing this exam felt amazing! If you're in the same boat and feeling uncertain, just stick with it! It’s a challenging exam, but with the right tools and preparation, you can do it. Keep pushing forward, and good luck to everyone! 💪 Would be happy to answer any questions if anyone has them!2.8KViews1like8CommentsStep by Step Guide to Ontology and Plan for Financial Service
What We Will Build In this guide, we will construct a complete Fabric IQ solution that accomplishes the following: First, a Lakehouse that ingests publicly available data including bank financials, P2P lending statistics, borrower demographics, and licensing information. Second, a Semantic Model that defines the analytical layer with proper dimensions, measures, and relationships. Third, an Ontology that elevates these tables into business entities such as Bank, P2P Platform, Borrower, and Loan, connected by meaningful relationships and governed by regulatory rules. Fourth, a Planning sheet that enables supervisors to forecast enforcement workloads, allocate examination budgets, and model scenarios based on live data. Step 1: Preparing the Data Foundation in Fabric Lakehouse Every Fabric IQ solution begins with data. Before we can model business semantics or build planning sheets, we need a well structured Lakehouse that holds our source data in a governed and queryable format. Creating the Lakehouse Navigate to your Fabric workspace and create a new Lakehouse. In this example, we have named it P2PLendingLH, housed within the workspace P2P Lending CrossSector Demo. The Lakehouse serves as the Bronze and Silver layer of our medallion architecture, storing both raw ingested data and transformed analytical tables. Data Sources and Tables The Lakehouse is populated with data from publicly available publications. The table structure follows a dimensional modeling pattern with clear separation between dimension tables (prefixed with dim_) and relationship tables (prefixed with rel_). The following tables form the foundation of our model: Table Name Description dim_bank Bank profiles including KBMI tier, total assets, CAR, NPL, channeling exposure percentage dim_borrower Borrower demographics with credit score, employment type, province, and risk segment dim_p2p_platform Licensed P2P lending operators with TWP90 rate, outstanding balance, and total borrowers dim_loan Individual loan records with amount, tenure, interest rate, and repayment status dim_supervisor_team supervisory teams and their regional assignments dim_channeling_agreement Bank to P2P channeling contracts and exposure limits In addition to dimension tables, several relationship tables capture the connections between entities. These include rel_bank_channels_platform (which bank funds which P2P platform), rel_borrower_takes_loan (linking borrowers to their loans), rel_loan_funded_by_bank (tracing the funding chain), rel_platform_issues_loan (connecting platforms to the loans they originate), and rel_supervisor_oversees_platform and rel_supervisor_oversees_bank (mapping supervisory responsibility). Step 2: Creating the Semantic Model With data in the Lakehouse, the next step is to create a Semantic Model that defines the analytical interface. The Semantic Model is a Power BI construct that organizes your tables into a star schema with proper relationships, hierarchies, and measures. More importantly for our purpose, this Semantic Model will later serve as the blueprint from which we generate our Ontology. Generating the Model from Lakehouse From within the Lakehouse, click on "New semantic model" in the toolbar. A dialog appears allowing you to name your model and select which tables to include. In our case, we select all dimension and relationship tables to ensure the Ontology will have full visibility into the data landscape. Figure 1. Creating a new Direct Lake semantic model from the P2PLendingLH Lakehouse, selecting dimension and relationship tables for inclusion. Notice that the dialog shows the workspace name (P2P Lending CrossSector Demo) and provides a searchable list of all available tables. The Direct Lake mode is automatically selected, which means the Semantic Model will query data directly from the Lakehouse parquet files without importing a copy. This is important for our use case because it ensures that when regulator publishes updated monthly statistics and the Lakehouse is refreshed, the Semantic Model and subsequently the Ontology will reflect the latest data. Configuring Relationships and Properties After creation, the Semantic Model opens in the editing view where you can configure relationships, add calculated measures, and define display properties. The model view shows the entity cards with their fields and the lines connecting related tables. Figure 2. The Semantic Model editor showing entity cards for dim_bank and dim_borrower, with relationship lines and the full table listing in the Data panel. In the screenshot above, you can see two of the core dimension tables. The dim_bank table contains fields such as bank_id, bank_type, channeling_exposure_pct, channeling_total, name, regulator_team, and total_assets. The dim_borrower table holds borrower_id, credit_score, employment_type, name, province, and risk_segment. The Data panel on the right reveals the complete set of tables available in this model, including all the relationship tables that define the connections between entities. At this stage, you should verify that all necessary relationships are correctly established. For example, dim_bank should connect to rel_bank_channels_platform through bank_id, and dim_p2p_platform should connect to rel_platform_issues_loan through platform_id. These relationships are what enable the Ontology to reason across domains in the next step. You may also want to add calculated measures at this point, such as a weighted average TWP90 across all platforms funded by a specific bank, or a total channeling exposure as a percentage of the bank's total assets. These measures will be carried forward into the Ontology and can be used by AI agents for natural language querying. Step 3: Generating the Ontology This is the step where the magic of Fabric IQ truly comes alive. The Ontology transforms your Semantic Model from a reporting layer into an intelligence layer. While the Semantic Model answers the question "what does the data look like," the Ontology answers the question "what does the data mean." What the Ontology Does An Ontology in Fabric IQ is a machine understandable vocabulary of your business. It consists of entity types (the things in your environment, such as Bank, Borrower, or P2P Platform), properties (the facts about those entities, such as a bank's NPL ratio or a platform's TWP90 rate), and relationships (the ways entities connect, such as a Bank channels funding to a P2P Platform). Beyond static modeling, the Ontology also supports rules and constraints that can trigger automated actions when business conditions are met. Generating from the Semantic Model To create the Ontology, open your Semantic Model and look for the "Generate Ontology" button in the toolbar. Clicking it opens the generation dialog, which presents three key value propositions: Unify models into a semantic layer allows you to align concepts across domains and modeling paradigms, bringing banking data and P2P lending data into a shared vocabulary. Model expressively enables you to capture complex relationships, domain specific rules, and actions that drive business workflows, such as triggering an alert when a P2P platform's TWP90 crosses the 5 percent regulatory threshold. Reason over events and temporal patterns means that the Ontology can use sequences and trends to inform decisions and automation, such as detecting three consecutive months of TWP90 deterioration. Figure 3. The Ontology generation dialog, creating a new Ontology named NewP2P from the existing Semantic Model within the P2P Lending CrossSector Demo workspace. In the dialog, you specify the workspace (P2P Lending CrossSector Demo) and give your Ontology a name (in this example, NewP2P). After clicking Create, Fabric IQ analyzes the Semantic Model's structure, identifies entity types from dimension tables, infers relationships from the foreign key connections, and generates a navigable graph that represents your business domain. Enriching the Ontology with Rules Once the Ontology is generated, you can enrich it with business rules that reflect regulatory requirements. For the P2P lending use case, the following rules are particularly relevant: Rule Name Condition Action Elevated TWP90 P2P Platform TWP90 exceeds 5 percent Flag platform as high risk and alert PVML supervisor Contagion Risk Bank channeling exposure to flagged P2P platform exceeds 10 percent of portfolio Alert Banking supervisor and recommend joint examination Youth Overleveraged Borrowers aged 19 to 34 represent more than 60 percent of a platform's portfolio AND TWP90 is above average Trigger consumer protection review and education program allocation CAR Threshold Bank CAR drops below 10 percent while having active P2P channeling agreements Escalate to Kepala Eksekutif Pengawas Perbankan These rules integrate with Fabric Activator, enabling the Ontology to automatically initiate business processes through alerts and automated actions. This means that when new monthly P2P statistics are ingested and a platform's TWP90 crosses the threshold, the system does not wait for an analyst to discover it manually. The rule fires, the alert is sent, and the supervisory workflow begins. Querying with Natural Language One of the most powerful capabilities enabled by the Ontology is the ability to query across domains using natural language through a Data Agent. Because the Ontology defines the business vocabulary and binds it to real data, a supervisor can ask questions like: "Which banks have channeling agreements with P2P platforms whose TWP90 is currently above 5 percent, and what is their total exposure?" The Data Agent resolves this query by traversing the Ontology graph: from the Bank entity through the channels_funding_to relationship to P2P Platform, filtering by the TWP90 property, and aggregating the channeling_total measure. Step 4: Setting Up Planning Sheets While the Ontology tells you what is happening in your business right now, the Plan item in Fabric IQ helps you decide what should happen next. Planning in Fabric IQ brings budgeting, forecasting, and scenario modeling directly into the same environment where your data lives, eliminating the disconnect between analytical insights and forward looking decisions. Creating a Planning Sheet To create a Plan, navigate to your workspace and select New Item followed by Plan (preview). After naming the plan and connecting it to your Semantic Model, you can begin building Planning sheets that pull dimensions and measures directly from the same data that powers your Ontology. In the screenshot below, we see a Planning sheet named "Planning P2P" that presents a tabular view of all P2P lending platforms alongside their key risk metrics. Figure 4. The Planning sheet showing P2P lending platforms with their TWP90 rates, total outstanding balances (in trillions of Rupiah), total borrower counts (in thousands), and risk categories. The Planning sheet is structured with the platform name and risk_category as row dimensions, and three critical measures as values: Sum of twp90_rate, Sum of total_outstanding (displayed in trillions of Rupiah), and Sum of total_borrowers (displayed in thousands). The risk_category column provides an immediate visual classification of each platform's health status, with categories such as Elevated and Very High clearly indicating where supervisory attention should be directed. Looking at the data, several insights emerge immediately. DanaBijak and DanaCepat both carry a Very High risk category, with TWP90 rates of 18.77 and 17.79 respectively. CashWagon ID shows an Elevated risk designation despite a comparatively modest TWP90 of 8.26, likely due to its substantial outstanding balance of 144.97 thousand borrowers. The aggregate row at the top reveals the industry total: a combined TWP90 of 365.38 (this is a sum across all platforms), total outstanding of 29.86 trillion Rupiah, and 7,281.55 thousand borrowers across the monitored universe. Using Planning for Supervisory Resource Allocation The real power of the Planning sheet becomes apparent when supervisors begin using it for forward looking decisions. Consider the following scenarios that can be modeled directly within the Planning interface: Enforcement Forecasting: Based on the current data showing multiple platforms in the Very High risk category, supervisors can forecast the expected volume of warning letters and administrative sanctions for the coming quarter. If historical patterns show that each Very High platform typically receives two to three rounds of correspondence before resolution, the planning sheet can project staffing requirements for the enforcement team. Budget Allocation: The Planning sheet can incorporate budget dimensions alongside risk metrics. If the current quarterly examination budget allows for on site visits to 15 platforms, the risk category column helps prioritize which platforms should be visited first. The forecast capability can then project whether the budget is sufficient given the current risk trajectory, or whether a reallocation request should be submitted.907Views0likes1CommentApproaches to Integrating Azure Databricks with Microsoft Fabric: The Better Together Story!
Azure Databricks and Microsoft Fabric can be combined to create a unified and scalable analytics ecosystem. This document outlines eight distinct integration approaches, each accompanied by step-by-step implementation guidance and key design considerations. These methods are not prescriptive—your cloud architecture team can choose the integration strategy that best aligns with your organization’s governance model, workload requirements and platform preferences. Whether you prioritize centralized orchestration, direct data access, or seamless reporting, the flexibility of these options allows you to tailor the solution to your specific needs.7.1KViews9likes1CommentTableau to Power BI Migration: Semantic Layer-First Approach for Cloud Architects
Author's: Mahjabin Ahmed, Yassine El Ouardi, Lavanya Sreedhar LavanyaSreedhar, Peter Lo PeterLo, Aryan Anmol aryananmol, Shreya Harvu shreyaharvu and Rafia Aqil Rafia_Aqil In this guide, we provide practical guidance for migrating from Tableau to Power BI, with a focus on technical best practices and architecture. Unifying business intelligence on the Microsoft Fabric platform, enterprises gain closer integration with Microsoft 365 (Teams, Copilot, Excel). For cloud solution architects and BI developers, a successful migration is not just about rebuilding dashboards in a new tool. It requires thoughtful architectural planning and a shift to a more model-centric approach to BI. Why Semantic Layer-First Architecture Matters The Traditional Migration Challenge Most Tableau to Power BI migrations follow a dashboard-centric approach: teams attempt to replicate existing Tableau workbooks, calculated fields, and LOD (Level of Detail) expressions directly into Power BI reports. While this may seem efficient initially, it creates significant downstream challenges: Duplicated logic: Each report embeds its own calculations and business rules, leading to conflicting KPIs across the organization Maintenance overhead: Changes to business logic require updating dozens or hundreds of individual reports Governance gaps: Without centralized definitions, semantic drift occurs—different teams calculate "Revenue" or "Active Customer" differently Scalability issues: As data volumes grow, report-level transformations become performance bottlenecks The Semantic Layer-First Alternative Microsoft's recommended approach centers on semantic models (formerly called datasets)—centralized, governed data models that separate business logic from visualization. In this architecture: The payoff is substantial: when data evolves or business rules change, you update the semantic model once, and all dependent reports automatically reflect the changes—no manual redesign required. Understanding Migration Complexity: Simple to Very Complex Dashboards Not all Tableau dashboards are created equal. The migration strategy should align with dashboard complexity, and the semantic layer approach becomes increasingly valuable as complexity grows. Follow a Step-by-Step Migration Strategy Migrating from Tableau to Power BI is not a one-click effort – it requires a mix of automated and manual refactoring, plus a sound change management plan. Below are key strategies and best practices for a successful migration: Audit your Tableau estate: Start by taking inventory of all existing Tableau workbooks, data sources, and dashboards. Determine what needs to be migrated (focus on high-value, widely used reports first) and identify any redundant or obsolete content that can be retired rather than converted. Conduct a proof-of-concept (PoC): Before migrating everything, pick a representative complex dashboard (or a subset of your data) and perform a pilot migration. This will help you validate that Power BI can connect to your data (e.g. setting up the Power BI gateways for on-premises sources), test performance (Import vs DirectQuery modes), and experiment with replicating key visuals or calculations. Use the PoC to uncover any surprises early – for example, test that any Level of Detail expressions or table calculations in Tableau can be re-created in DAX. The lessons learned here should inform your overall project plan. Use a phased migration approach: Plan to run Tableau and Power BI in parallel for some period, rather than switching everything at once. Migrate in waves – for example, by business unit or subject area – and incorporate user feedback as you go. This phased approach reduces risk and allows your team to improve the process with each iteration. It also gives end users time to adjust gradually. Migrate high-impact dashboards first: Prioritize the migration of key reports and dashboards that are critical to the business or have the most usage. Delivering these early wins will not only surface any technical challenges to solve but will also help demonstrate the value of Power BI’s capabilities to stakeholders. Early success builds buy-in and momentum for the rest of the migration. Reimagine (don’t just replicate) the experience: It’s rarely possible – or desirable – to exactly re-create every Tableau visualization pixel-for-pixel in Power BI. Embrace the opportunity to focus on business questions and improve user experience with Power BI’s features. For example, rather than replicating a complex Tableau workaround, you might implement a cleaner solution in Power BI using native features (like bookmarks, drilldowns, or simpler navigation between pages). Engage business users and subject matter experts during this redesign to ensure the new reports meet their needs. Enable dataset reusability: One major benefit of the Power BI approach is the ability to create shared datasets and dataflows. As you migrate, look for opportunities to create central semantic models (datasets) that can serve multiple reports. For instance, if several Tableau workbooks are all using similar data about sales, you can create one central Sales dataset in Power BI. Report creators across the organization can then build different Power BI reports on that single dataset without duplicating data or logic. This reduces maintenance and promotes a “build once, reuse often” strategy. Provide training and support: Expect a learning curve for teams moving to Power BI – especially those who are very fluent in Tableau. Plan for user upskilling and training programs. Establish a support community or office hours where new users can ask questions and get help. If possible, identify Power BI champions or recruit a Power BI Center of Excellence (COE) team who can guide others. During the transition, ensure there are subject matter experts (SMEs) available to address questions and validate that the new reports are correct. Manage change and expectations: It’s important to communicate why the organization is moving to Power BI (e.g. benefits like deeper integration, lower TCO, better governance) to get buy-in from end users. Some users may be resistant to change, especially if they’ve invested a lot of time in mastering Tableau. Prepare to handle varying responses – emphasize the personal benefits (like improved performance, new capabilities, or career growth with popular skills) to encourage adoption. Also, involve influential business users early and gather their feedback, so they feel ownership in the new solution. Establish governance from Day 1: Don’t wait until after migration to think about governance. Use this chance to set up Power BI governance aligned to best practices. Decide on important aspects such as workspace naming conventions, who can create or publish content, how you’ll monitor usage and costs, and how to manage data access and security (for example, designing a strategy for RLS/OLS/CLS, and deciding when to use per-user datasets vs. organizational semantic models). Good governance will ensure your shiny new Power BI environment doesn’t sprawl into chaos over time. Allow time for adjustment and iteration: Finally, be patient and iterative. Depending on the scale of your organization and the number of Tableau assets, a full migration can take months or even a year or more. Plan realistic transition periods where both systems might coexist. Continuously refine your approach with each wave of migration. Power BI’s frequent update cadence (monthly releases) means new features may emerge even during your project – stay updated, as new capabilities could simplify your migration (for example, the introduction of field parameters or Copilot might let you modernize certain Tableau features more easily). Reimagine (don’t just replicate) the experience (Step 5): Phase 1: Assessment and Planning 1. Audit Your Tableau Estate Inventory all workbooks, data sources, and calculated fields Identify high-traffic dashboards (prioritize for early migration) Categorize by complexity (Simple/Medium/Complex/Very Complex) 2. Design Your Semantic Architecture Map Tableau data sources to Power BI data sources (DirectQuery, Import, or Direct Lake) Plan star schema for fact/dimension tables Identify shared calculations that should live in semantic models vs. report-specific logic 3. Choose Storage Modes Source Type Recommended Mode Rationale Databricks Delta Lake Direct Lake Real-time analytics, no refresh lag Azure SQL Database DirectQuery or Import Based on data volume and refresh SLAs On-Premises SQL Server Import (via Gateway) Network latency considerations Excel/CSV files Import Small reference data Phase 2: Build the Semantic Layer 1. Create Star Schema Data Models Tableau often relies on flat, denormalized datasets. Power BI performs best with star schemas: Fact tables: Transactional data (sales, orders, events) with foreign keys to dimensions Dimension tables: Descriptive attributes (customers, products, dates) with primary keys Relationships: One-to-many from dimension to fact, leveraging bidirectional filtering sparingly 2. Migrate Calculations to DAX Measures Convert Tableau calculated fields to DAX measures in the semantic model: --Example of DAX: -- Define as measure: Total Revenue = SUMX( 'Sales', 'Sales'[Quantity] * 'Sales'[Unit Price] ) 2.1 Use Copilot to Accelerate DAX Development Leverage Copilot in Power BI Desktop to generate and validate DAX: Describe the calculation in natural language Copilot suggests DAX syntax Review, test, and refine 2.2 Document your Semantic Model Invest in creating an AI-ready foundation for your semantic model. AI systems need to understand unique business contexts in order to prioritize correct information to provide consistent and reliable responses to your end users. Name Tables and Columns Clearly: Avoid ambiguity in your semantic model. Use human-readable, business-friendly names. Avoid abbreviations, acronyms, or technical terms. This improves Copilot’s ability to interpret user intent. Create Meaningful Measures: Define reusable DAX measures for key business metrics (e.g., Revenue, Profit Margin). AI features rely on these to generate insights and summaries. Document Semantic Model objects: Add descriptions and synonyms to your Tables, Columns and measures. This enhances natural language querying and improves Copilot’s contextual understanding. Build an AI Data Schema: prepare your semantic model for AI by utilizing tooling features such as Prep data for AI. Phase 3: Understanding Migration Complexity: Simple to Very Complex Dashboards Not all Tableau dashboards are created equal. The migration strategy should align with dashboard complexity, and the semantic layer approach becomes increasingly valuable as complexity grows. 1. Dashboard Conversion Best Practices Think in "pages" not "sheets": Power BI reports combine multiple visuals per page; group related visuals logically Use slicers for interactivity: Replace Tableau filters with Power BI slicers and filter pane Leverage bookmarks for navigation: Create dynamic report experiences with show/hide containers Simple Complexity Level Category Tableau Feature Power BI Equivalent Microsoft Fabric Enhancements Best Practice Notes Data Model Single custom SQL Power Query for data shaping and ETL. OneLake Shortcuts for unified data access. Use star schema for optimized performance; push logic into the semantic layer rather than visuals. Calculations Basic IF/ELSE, SUM Data Analysis Expressions (DAX) for measures and calculated columns. Copilot for Power BI to assist with DAX creation. Fabric IQ for natural language queries. Centralize calculations in semantic models for consistency and governance. Medium Complexity Level Category Tableau Feature Power BI Equivalent Fabric Enhancements Best Practice Notes Data Model Multiple custom SQL (up to 3) Connect live to databases (Azure Databricks): DirectQuery in Power BI Connect with cloud data sources: Power BI data sources OneLake Shortcuts for unified access without databricks compute cost. Semantic Models can combine multiple sources. Optimize with star schema; Prefer OneLake Shortcuts for performance; avoid heavy transformations in visuals. Calculations Nested IFs, CASE Data Analysis Expressions (DAX) for measures and calculated columns. Copilot for Power BI to assist with DAX creation. Fabric Data Agent for conversational BI. Fabric IQ for natural language queries: Fabric IQ Centralize logic in semantic models; use Copilot for automation and validation; keep calculations reusable. Reporting Tooltip format in Bar and Map visuals Select All/Clear option for Single Select dropdown Standard tooltips offer help tooltips, text, and background formatting. Dynamic tooltip will be able to create the Tooltip page and reuse it in multiple visuals The customization is so much better than the OOB tooltips Create report tooltip pages in Power BI - Power BI | Microsoft Learn Use Clear All Slicers Button. Disable Single Select, Add Clear All Slicers button, Customize the Button and Use the Button Complex Complexity Level Category Tableau Feature Power BI Equivalent Fabric Enhancements Best Practice Notes Data Model Multiple sources Create relationship using more than one column Composite Models in Power BI (DirectQuery + Import) for combining multiple sources, also connect to various cloud services. Dataflows for pre-processing. Power BI allows a relationship between 2 tables based on only one active column. OneLake Shortcuts for unified access without Azure Databricks compute cost; Microsoft Fabric Dataflows Gen2 offers multiple ways to ingest, transform, and load data efficiently. Consolidate sources into semantic models; use Direct Lake for performance; Plan and design data model to comply with star schema supported by Power BI Relationship DAX USERELATIONSHIP DAX for activating relationships in Power BI for a specific calculation Calculations LOD, window functions Data Analysis Expressions (DAX) for measures and calculated columns. Copilot to assist with complex DAX. Fabric IQ Ontology for semantic alignment. Change how visuals interact in a Power BI report. Centralize calculations in semantic layer; use variables in DAX for readability and performance. Fabric Data Agent for a conversational BI. Very Complex Complexity Level Category Tableau Feature Power BI Equivalent Fabric Enhancements Best Practice Notes Data Model Multi-source, Excel, SQL Composite Models in Power BI (DirectQuery + Import) for combining multiple sources, also connect to various cloud services. Dataflows for pre-processing. OneLake Shortcuts for unified access; Connector overview build-in support. Mirroring for real-time sync. Combine multiple sources into well-structured semantic models for consistency and optimized performance. Calculations Predictive logic Data Analysis Expressions (DAX) for measures and calculated columns. Fabric AutoML, ML models, AI Insights, Python/R, Notebook‑based ML (Spark/Scikit‑Learn), Fabric AI Functions, Fabric IQ Ontology Fabric Data Agent for a conversational BI. Centralize logic in semantic models; leverage Copilot for automation and parameter-driven workflows. Prepare for Copilot. 2. Tableau Feature Equivalents Tableau Feature Power BI Equivalent Microsoft Learn Link Calculated Fields DAX Measures DAX Documentation Parameters Field Parameters / Bookmarks Use report readers to change visuals Actions Drillthrough / Bookmarks Drillthrough Tableau Prep Power Query / Dataflows Differences between Dataflow Gen1 and Dataflow Gen2 Tableau Server Power BI Service What is Power BI? Overview of Components and Benefits Phase 4: Governance and Deployment Workspace Planning (Dev / Test / Prod Separation) A proper workspace strategy is essential for governed deployments in Fabric and Power BI. Fabric supports separate Development, Test, and Production stages using Deployment Pipelines, enabling controlled promotions of semantic models, reports, dataflows, notebooks, lakehouses, and other items. You can assign each workspace to a pipeline stage (Dev → Test → Prod) to ensure safe lifecycle management. Sensitivity Labeling (Microsoft Purview Information Protection) Sensitivity labels allow governed classification and protection of data across Fabric items. Sensitivity labels can be applied directly to Fabric items (semantic models, reports, dataflows, etc.) through the item's header flyout or the item settings. Labels from Microsoft Purview Information Protection enforce data access rules and help organizations meet compliance requirements. Endorsement & Certification (Promoted, Certified, Master Data) Endorsement improves discoverability and trust in shared organizational content. Promoted: Item creators mark content as recommended for broader use. Certified: Administrators or authorized reviewers validate content meets organizational quality standards. Master Data: Indicates authoritative single‑source‑of‑truth items such as semantic models or lakehouses. All Fabric items except dashboards can be promoted or certified; data‑containing items can be designated as Master Data. Monitoring & Capacity Planning Determine the appropriate size for fabric capacity when migrating from Tableau to PowerBI. The Fabric SKU Estimator can generate a SKU recommendation (estimate) for your capacity requirements. Ensuring performance and cost efficiency requires ongoing monitoring of your Fabric capacity. Microsoft recommends evaluating workloads using Fabric Capacity Metrics and planning SKU sizes based on real usage. Fabric uses bursting and smoothing to handle spikes while enforcing capacity limits. Monitoring helps identify high compute usage, background refreshes, and interactive workloads to optimize performance. Fabric Data Source Connections (OneLake+ Manage Connections) Microsoft Fabric is designed as an end‑to‑end analytics platform that integrates data from many different source systems into a unified environment powered by OneLake, Data Factory, Real‑Time Analytics, Dataflows , Lakehouses, Warehouses, and Mirrored Databases. The Strategic Advantage: Semantic Layer + Fabric IQ The semantic layer-first approach sets the foundation for the next evolution in enterprise analytics. Fabric IQ (announced at Ignite 2025) is Microsoft's semantic intelligence platform that auto-elevates semantic models into ontologies—structured knowledge graphs that power AI agents, Copilot experiences, and cross-domain data reasoning. What this means for your migration: Semantic models you build today become the foundation for AI-driven analytics tomorrow Data Agents can reason across multiple semantic models, answering questions that span domains Business users transition from "report consumers" to "data explorers" via natural language interfaces Conclusion: Build for the Future, Not Just for Today Migrating from Tableau to Power BI is more than a technology swap—it's an opportunity to re-architect your analytics strategy for the cloud-native, AI-powered era. The semantic layer-first approach requires upfront investment in data modeling, DAX expertise, and Fabric platform adoption. But the payoff is transformative: Consistency: Single source of truth for all business metrics Scalability: Semantic models that serve hundreds of reports and thousands of users Agility: Changes to business logic propagate instantly across the enterprise Future-readiness: Foundation for Fabric IQ, Data Agents, and AI-driven insights Start your migration with the end in mind: not just convert dashboards, but a modern, governed, AI-ready analytics platform that scales with your business. Addressing Key Migration Concerns (1) Why a semantic‑layered model approach is better than recreating Tableau dashboards A semantic‑layered modeling approach is the optimal strategy for migration and is significantly more effective than attempting to recreate Tableau dashboards exactly as they exist. By contrast, Power BI and Fabric encourage a semantic model–first architecture, where all business rules, relationships, calculations, and transformations are centralized in a governed model that serves many dashboards. The approach not only provides consistency and reuse across the enterprise but also ensures that report authors build on a single certified version of the truth. (2) How semantic-layered model approach reduces the constant redesign caused by changing data needs. A semantic‑layered modeling approach directly addresses concern about constant changes and frequent redesigns of dashboards when data evolves. With a semantic layer, changes are absorbed in the model layer—so the logic is updated once and flows automatically into all dependent reports. Combined with Fabric features like OneLake shortcuts, Direct Lake mode, and centralized governance, the semantic layer drastically reduces breakage, minimizes rework, and ensures scalability as data continues to grow and shift. Additional Resources Direct Lake in Microsoft Fabric Create Fabric Data Agents OneLake Shortcuts Write DAX queries with Copilot - DAX Prepare Your Data for AI - Power BI | Microsoft Learn4.7KViews4likes2Comments