agent builder
36 Topics
Copilot Studio + SharePoint: Markdown (.md) Files in Doc Libraries Supported as Knowledge Sources?
Hi all, We’ve been doing some deeper testing with Copilot Studio agents grounded in SharePoint knowledge sources, and I’m hoping to clarify whether what we’re seeing is a known limitation or an undocumented gap. Scenario A Copilot Studio agent uses SharePoint document libraries as a knowledge source The library contains Markdown (.md) files that are intentionally used as canonical design references The same .md files: ✅ Work well when uploaded directly to the agent ❌ Are not retrievable or citable when stored in a SharePoint library and added as a SharePoint knowledge source To help with grounding, we created modern SharePoint index pages that: Explain what the markdown collections are (Patterns, ADRs, Guardrails) Link directly to the canonical folders and files Explicitly state that the .md files are the source of truth The agent can: Discover and summarize the index pages correctly Understand that .md artifacts exist and where they live But it cannot: Read the content of the individual .md files Apply a specific pattern or ADR from those files in a design conversation Cite them as sources, even when permissions and search indexing are confirmed What We’ve Checked Permissions (agent user has access) Folder depth (kept shallow) Search results (markdown files appear in SharePoint search) SharePoint indexing status Work IQ enabled Same content works when attached directly to the agent This behavior also seems consistent with what others have reported here: Markdown works when uploaded directly Markdown retrieval degrades when hosted in SharePoint libraries Questions for the Product Team / Community Are Markdown (.md) files in SharePoint document libraries officially supported as Copilot Studio knowledge sources today? If yes, are there specific constraints (file size, rendering, parsing, indexing) that differ from Word/PDF? If no (or “not yet”), is this a known limitation on the roadmap? Is the recommended pattern to: Convert important markdown files into .aspx pages, or Use thin “index / summary” pages and keep markdown canonical until retrieval improves? We’re happy to adapt our information architecture — just trying to align with the intended platform direction rather than work against it. Thanks in advance for any guidance or clarification. This capability is extremely powerful, and clearer expectations here would help a lot of teams make the right design tradeoffs.4.2KViews15likes9CommentsWelcome let's get started
Welcome to the Copilot Studio Community on Microsoft Tech Community! We're thrilled to announce that Copilot Studio now has a dedicated home on the Microsoft Tech Community, and we'd love for you to be part of it from day one. Whether you're just getting started with building Agents in Agent Builder or you are a pro building agents and automations with Copilot Studio, this is your space to: Ask questions and get answers from the community and Microsoft experts Share what you've built — show off your agents, flows, and use cases Stay up to date on the latest features, releases, and best practices Connect with peers across industries who are shaping the future of AI-powered work The community is open to everyone, from first-time explorers to seasoned pros. Every question asked and every insight shared makes this a better resource for all of us. We can't wait to see what you build. Welcome!267Views7likes3CommentsWhat is the best file format for an AI agent knowledge base?
This is a best practice sharing the best format for an agent and show you why you should convert your PPT, PDF, WORD into a TXT markdown. I had an issue with my agent, time taken to answer was too long, and usually we spend a lot of time asking: What is the best prompt? Why is my agent slow? Why does retrieval sometimes work and sometimes fail? How can I improve answer quality? But I realised I was asking another question much less often: What is actually the best file format for the knowledge base? PDF? Raw text? Markdown? Pre-chunked text? Semantic sections? Context-enriched text? And more importantly: How much does the format alone affect agent performance? I tried to find a quantified benchmark answering this specific question, with the same agent, same source knowledge and same questions, but different knowledge representations. I couldn't find one that really answered what I wanted to measure. So I decided to run the experiment myself on a real case. My first exploratory tests were already surprising: depending on the representation, the agent could be significantly faster and more accurate, despite working from the exact same source information. So I decided to push the test further. My objective I want to identify, without assumptions and based on actual evaluation data, how a long document should be prepared for an LLM knowledge base so that the agent can retrieve, understand, ground and answer from it as reliably as possible. I focused on five dimensions: Answer quality Retrieval reliability Source grounding / citations Execution time Robustness across single-turn and multi-turn questions The broader question I'm trying to answer is: How should we structure knowledge so that an LLM can retrieve and use it as reliably as possible? The test case I deliberately chose a document that isn't particularly friendly for RAG: a 46-page European regulation, https://eur-lex.europa.eu/eli/reg/2011/1169/oj?locale=fr, on the provision of food information to consumers. The information is distributed across articles, definitions, exceptions, annexes, tables, numerical thresholds and cross-references. That makes it useful for testing retrieval: answering correctly often requires finding a very specific piece of information while preserving enough context to understand how it applies. I used the native PDF as the baseline and created 6 additional knowledge-base representations of the same document: Raw TXT Markdown Chunk-ready TXT RAG-oriented units Semantic TXT Contextual TXT One rule: same knowledge, same agent, same instructions, same questions. Only the knowledge representation changes. The benchmark I used two evaluation sets: 42 single-turn questions testing broad coverage of the document: direct facts, thresholds, exceptions, annexes, lists and cross-references. 5 multi-turn conversations containing 13 questions, to see what happens when a user asks a question and then follows up with things like: "And in this case?" "What are the exceptions?" "And for dietary fibre?" This gave me: 47 evaluated test cases / 55 actual questions per format Across all 7 formats: 329 evaluated conversations 385 user questions executed First results Metric Native PDF Best structured representation Overall pass rate 66.0% 85.1% - Contextual TXT Best single-turn score 69.0% 88.1% - Chunk-ready TXT Multi-turn benchmark 40% 80% - Contextual TXT Multi-turn execution time 14m24 5m54 Total benchmark time 44m31 24m49 The quality gap was already substantial: 66.0% → 85.1% That's +19.1 percentage points while keeping the underlying knowledge unchanged. I also saw a major difference in execution time. On the multi-turn test: 14m24 → 5m54 That's approximately 2.4× faster. Across the complete benchmark: 44m31 → 24m49 Around 44% less execution time. These timings represent the complete agent evaluation pipeline, so they shouldn't be interpreted as pure LLM inference latency. But the difference under identical test conditions is large enough that I want to understand it better. Findings There wasn't one format dominating every benchmark. Chunk-ready TXT scored highest on independent questions: 88.1%, while Contextual TXT performed better across multi-turn conversations and finished with the highest overall score. That may suggest that the way we optimise a document for isolated retrieval isn't exactly the same as the way we should prepare it for conversational retrieval. In the contextual version, I tried to make every section understandable when retrieved independently by keeping useful information around it: Source references Section context Retrieval cues Relevant cross-references For regulatory documents, this seems particularly important. A numerical value retrieved alone can be meaningless without knowing which rule it belongs to, under which conditions it applies, and whether another article contains an exception. Where I am now This remains an exploratory benchmark: One document One domain One agent setup One evaluation framework One run per configuration There are plenty of things I still want to test: repeated runs, retrieval-level evaluation, token consumption, larger knowledge bases, other document types, chunk sizes, overlap, contextual headers, and more. But these first results already convinced me that the preparation of the knowledge base deserves much more attention when evaluating an agent. We often spend hours refining instructions while the same information may behave very differently depending on how it reaches the retrieval layer. Next step I'll share the prompts, knowledge-base formats and evaluation methodology on GitHub so the experiment can be reproduced and challenged. I'll keep enriching the repository as I test new formats, improve the evaluation set and add new results. If people here have ideas, edge cases or formats worth testing, I'd genuinely like to include some of them in the next iteration. What would you test next?961Views3likes3CommentsMCP (Model Context Protocol)
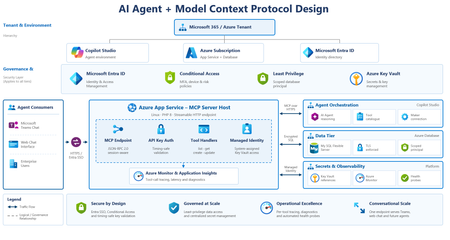
gave an AI agent write access to a production system. Not a demo. A real internal tool people depend on. It can now read, create, and update records - in plain language, from a chat window. Four things I learned building it with MCP (Model Context Protocol): 1. The tool description IS the interface. The agent doesn't read your code. It reads one sentence describing each tool, and decides from that alone whether to call it. Write "internal API test" → ignored forever. Write "creates and updates support tickets" → fires correctly. We spent 15 years designing UIs for humans. The design surface is now a sentence a model reads. 2. Agents can't click "Sign in." Any auth flow expecting a browser redirect silently breaks an agent connection. Machine access and human access need separate doors into the same house. 3. MCP errors don't mean what you think. My server returned success on every request -and the agent still failed. A "404" in MCP means session expired, not wrong URL. New protocol, new error vocabulary. 4. Least privilege stops being optional the moment an agent can write. A human with too many permissions makes occasional mistakes. An agent makes them at machine speed, confidently, while explaining why it was right. Why this matters: MCP turns "integrate AI into our systems" from a bespoke project into a standard interface. Expose capabilities, describe them clearly, and any compliant agent can use them. Same shift APIs caused 20 years ago - except the consumer isn't a program following rigid contracts. It's a model deciding at runtime what to call and why. The interfaces we built for humans aren't going away. They're just no longer the only way in. Activate to view larger image,101Views1like0Comments
Copilot Studio Agent Unable to Retrieve Usable DOCX/XLSX Content from OneDrive (and SharePoint)
Hi everyone, I'm building a Copilot Studio agent that needs to read and process Word (.docx) and Excel (.xlsx) files stored in OneDrive. The agent can successfully locate files and retrieve metadata, but it appears unable to retrieve Office files as usable binary content. I tested the behaviour using the OneDrive Get file content action: A text file (test.txt) was returned correctly and matched the original file contents exactly. A Word file (Test.docx) was returned beginning with the ZIP signature PK and contained recognisable DOCX entries such as [Content_Types].xml and _rels/.rels. However, the returned payload also contained large numbers of Unicode replacement characters (�). The returned content appears to be a text string rather than binary data or base64 content. Because Office files are ZIP-based binary formats, the returned payload cannot be reconstructed into a valid .docx or .xlsx file, preventing downstream libraries such as python-docx and openpyxl from opening the file. Is there any way to resolve this issue?792Views1like6Comments
New Agent experience - how to add Fabric data agent
When using the new (Agent) experience in Copilot studio how can you add Fabric Data agent as connected agent ? There does not seem to be an option. Also should adding it as an MCP server be supported (under Tools) ? https://learn.microsoft.com/en-us/fabric/data-science/data-agent-mcp-server says the following: Currently, you can use the Fabric data agent MCP server only in VS Code. If you're using your own MCP client, it can also work, as long as you set up authentication Has anyone tried this? If yes, by using with authentication? OAuth2? Thanks363Views1like2Comments
How to use agents response as an input to a topic?
Hi I would like to use the agents reponse to store it in a word or excel file. For that, I would like to use the response provided by the agent, pass it on to my custom topic which triggers an agentic workflow to store the agents response in a word or excel file. I cannot sort out how to pick the agents response and pass it on to my custom topic, any help will be highly appreciated, thanks!180Views1like1Comment