sqlserverazurevm
52 TopicsSQL Server on Azure VMs makes history with the first audited SQL Server TPC-H result in the cloud!
I am thrilled to share that SQL Server 2025 running on an Azure F64amds_v7 virtual machine, an AMD EPYC-based offering, has achieved an audited TPC-H result of 1,667,428 QphH@1000GB 1 . This is the first official, audited TPC-H result for SQL Server on cloud infrastructure! This is currently the top performing result for SQL Server on the TPC-H 1,000 GB benchmark. Why this TPC-H benchmark is different We do a lot of performance testing here at Microsoft. If you've read our previous blogs, you've seen us use various tools like HammerDB to run TPC style workloads against different VM sizes and storage configurations, and you've probably noticed the footnote at the bottom explaining that those results aren't comparable to published TPC benchmarks. Those studies are super useful for comparing VM series and storage options, but they don't carry the same weight as an audited, industry-standard benchmark. That's what makes this result different. The TPC (Transaction Processing Performance Council) defines a strict set of rules for how a benchmark must be run, priced, and documented so that results from different vendors and platforms can be fairly compared. Every published result must be reviewed by an independent TPC auditor, and the full disclosure report is made available to anyone who wants to dig into the details. SQL Server has been a fixture on the TPC results lists for decades because of the way it can push a system to its limits, and SQL Server TPC-H results have historically been published on physical hardware. Getting an audited TPC-H benchmark on a cloud VM was not a small undertaking. The TPC specifications were written with on-premises, OEM hardware in mind, so it took years of work with the auditor to determine how to run and price a benchmark on a cloud VM while still adhering to every standard. One important part of that work was proving that cloud infrastructure could meet the same durability expectations as traditional hardware. The TPC benchmark includes tests for ACID compliance to guarantee that the system is durable as well as fast. For SQL Server, that means an acknowledged write must remain durable not just at the database layer, but across every layer involved in the write path: Windows, the Azure platform, and the underlying storage devices. The audit forced us to explain that end-to-end durability chain, including how the platform protects committed data through failure and recovery scenarios. In that sense, the benchmark was not only a performance proof point, but also an externally audited validation that Azure’s storage architecture can support the reliability expectations of enterprise SQL Server workloads. The results for the TPC-H benchmark We started planning this more than three years ago, and it's so cool to finally see it posted on the TPC website! Here's a look at the system configuration and results 1 : Azure F64amds_v7 VM Processor 1x AMD EPYC 9V45 @ 2.60 GHz Cores / Threads 64 / 64 Memory 512 GiB Storage Premium SSD v2 managed disks + local ephemeral NVMe Database SQL Server 2025 Enterprise Edition Operating system Windows Server 2025 Datacenter Database size 1 TB (scale factor 1,000) QphH@1000GB 1,667,428 Price/Performance $558.17 USD per kQphH@1000GB Check that out! That's a single virtual machine in the cloud chewing through a 1 TB decision-support workload at more than 1.6 million queries per hour on the composite TPC-H performance metric. So, what’s special about Azure F64amds_v7? Featuring the AMD EPYC CPUs, with 64 full physical cores, SQL Server workloads get the much-needed platform capabilities to power through even the most complicated, compute-hungry queries. It's a great demonstration of just how far SQL Server on Azure VMs has come. You can find every last detail in the Executive Summary and Full Disclosure Report on the TPC website. What this means for you For years, we've been telling customers that moving SQL Server to Azure doesn't mean giving up performance. Many of you have some of your most demanding, mission-critical SQL Server workloads still running on-premises, often because of a lingering worry that the cloud just can't keep up with a big, beefy on-prem server. Now we have an independently audited, industry-standard benchmark showing that it absolutely can! If you've been holding back on modernizing your largest SQL Server workloads because of performance concerns, this is a great time to take another look. SQL Server on Azure VMs gives you the same SQL Server engine you know and love, full control over the OS and instance, and the performance to handle your heaviest workloads, plus all the value-add capabilities of the SQL IaaS Agent extension and the flexibility to scale as your needs change. For workloads that need deep OS control, instance-level compatibility, or a straightforward migration path, Azure VMs continue to be a great option. A word about SQL Server price-performance You may have noticed the price-performance number in the table above and thought "wait a minute, I thought Azure had the best price-performance for SQL Server?!" That's a fair question, and since price-performance is a topic near and dear to my heart, I want to address it head on. To keep results comparable, TPC has strict rules about how a benchmarked system is priced, and some of those rules don't map neatly to how customers actually pay for SQL Server in Azure: Pricing must be publicly available list pricing. That means we couldn't take advantage of Azure Hybrid Benefit, which many of you use to bring your existing Windows Server and SQL Server licenses with Software Assurance to Azure. SQL Server licensing was priced as three years of pay-as-you-go. Traditional on-premises benchmark results typically price license-only SQL Server, amortized over three years. In this result, SQL Server licensing accounts for roughly two-thirds of the total three-year system cost of $930,701. The VM compute itself is only about 7%. The storage was provisioned for the maximum capability of the VM. The Premium SSD v2 disks were configured with more IOPS than the TPC-H workload needed, and with Premium SSD v2, you pay for the IOPS and throughput you provision. In the real world, you have a lot more flexibility: Azure Hybrid Benefit, reservations or savings plans, right-sizing your Premium SSD v2 storage for the IOPS and throughput your workload actually needs (and scaling it up or down on the fly!), and choosing the right VM series and size for your workload. Also keep in mind that Azure costs account for things like electricity, datacenter space, infrastructure management etc. – things you need to worry about on-premises that aren’t accounted for in the benchmark pricing. So, while the published TPC price-performance number is important for benchmark comparability, it isn't a recipe for what a customer's optimized Azure deployment should cost. As with any SQL Server question, the answer to "what will it cost me?" is "it depends," and we'll be digging into exactly that in an upcoming blog on how to optimize the price-performance of high-performance SQL Server workloads on Azure VMs. Stay tuned! What's next This is just the beginning! Be sure to check out the full result on the TPC website, and keep an eye out for an upcoming episode of Data Exposed where we'll dig deeper into the benchmark and what it means for your SQL Server workloads. And as always, stay tuned as we continue to deliver innovations that make Azure the best place to run SQL Server! 1 Result referenced is current as of October 12, 2026. Azure F64amds_v7 Virtual Machine: 1,667,428 QphH@1000GB, $558.17 USD/kQphH@1000GB, available 10/06/26. TPC Benchmark™, TPC-H™, and QphH™ are trademarks of the Transaction Processing Performance Council. For more information, visit www.tpc.org. AMD is the high performance and adaptive computing leader, powering the products and services that help solve the world’s most important challenges. Our technologies advance the future of the data center, embedded, gaming and PC markets. Founded in 1969 as a Silicon Valley start-up, the AMD journey began with dozens of employees who were passionate about creating leading-edge semiconductor products. AMD has grown into a global company setting the standard for modern computing, with many important industry firsts and major technological achievements along the way.452Views1like0Comments
BULKADMIN role support for SQL Server on Linux is now Generally Available
Starting with SQL Server 2025 CU9 and SQL Server 2022 CU27, SQL Server on Linux supports the bulkadmin fixed server role and the ADMINISTER BULK OPERATIONS permission for performing bulk data import operations without requiring users to be members of the sysadmin fixed server role. This capability enables you to use operations such as BULK INSERT and OPENROWSET(BULK...) while following a least-privilege security model. Previously on SQL Server on Linux, these operations required sysadmin membership. With this GA (Generally Available) release, organizations running SQL Server on Linux can provide users with the permissions required for bulk data loading without granting broader sysadmin privileges, improving alignment with the principle of least privilege. The feature applies to SQL Server on Linux, including on-premises, SQL Server on Azure VMs and container deployments. Learn more: BULK INSERT (Transact-SQL) - SQL Server | Microsoft Learn Announcing Preview of bulkadmin role support for SQL Server on Linux | Microsoft Community Hub180Views0likes0CommentsAnnouncing flexible provisioning for SQL Server on Linux Azure VMs (Public Preview)
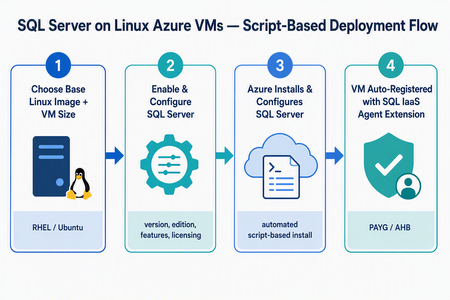
What’s changing We’re introducing a new script-based deployment experience for provisioning SQL Server on Linux Azure Virtual Machines (VMs). This experience replaces the earlier model that relied on pre-created SQL Server on Linux Marketplace images, which have been deprecated. Pre-created SQL Server on Linux Marketplace images are no longer available for new provisioning through the Azure portal, the Azure SQL hub, Azure CLI, or PowerShell. Instead, SQL Server is now installed and configured during VM provisioning using a flexible, automated, script-based workflow. The result is a more adaptable and supportable deployment model that keeps SQL Server on Linux Azure VMs fully supported, reduces image-maintenance overhead, and makes it easier to adopt the latest Linux distributions, VM families, and configuration options - all while giving you more control over your SQL Server setup. Why the new model matters Greater flexibility and control — choose your Linux distribution, SQL Server version, edition, and even bring your own mssql.conf to tailor the configuration. Faster access to innovation — new Linux versions and Azure capabilities are picked up automatically, without waiting for a new baked image to be published. Automatic registration built in — every VM is registered with the SQL IaaS Agent extension by default, unlocking licensing flexibility, compliance, and richer visibility. A dynamic, guided UI — the portal enables or disables options based on supported operating system, SQL Server, and licensing combinations, so you only see valid choices. Supported Linux distributions The script-based deployment experience supports the following distributions, and future versions are picked up automatically as they become supported — no manual intervention required: Distribution Supported versions Red Hat Enterprise Linux (RHEL) RHEL 9, RHEL 10 (and future versions) Ubuntu Ubuntu 22.04, Ubuntu 24.04, Ubuntu 26.04 (and future versions) Automatic registration applies to both Red Hat Enterprise Linux and Ubuntu, across all their supported versions. Automatic registration with the SQL IaaS Agent extension SQL Server on Linux VMs deployed through this experience are automatically registered with the SQL Server IaaS Agent extension. Registration creates a SQL virtual machine resource in Azure (separate from the VM resource) and unlocks: Licensing flexibility — choose Pay-As-You-Go (PAYG) or Azure Hybrid Benefit (AHB), and switch between them anytime with no downtime. Compliance — a simplified way to meet Azure Hybrid Benefit product-term requirements without per-resource registration forms. Visibility and telemetry — clear license-type visibility, subscription-level tracking, and better operational insight from the Azure portal, CLI, or PowerShell. Note: Automatic registration is enabled by default during deployment. You can unregister or re-register a VM after deployment through the Azure portal, Azure CLI, or PowerShell. The end-to-end flow at a glance Experience: The “Create a virtual machine” tab Use this flow if you’re starting from the familiar VM creation experience in the Azure portal. In the Azure portal, go to Virtual machines (or Create a resource → Virtual machine) and select Create. On the Basics tab, select your project details (subscription, resource group), instance details, and a supported Linux base image — RHEL 9, RHEL 10, Ubuntu 22.04, or Ubuntu 24.04. Choose your VM size, authentication, and inbound ports as usual. Go to the Advanced tab and select the Install SQL Server checkbox. This enables SQL Server provisioning on the VM. A new SQL Server settings tab becomes available. Open it to configure your SQL Server deployment: SQL Server version — e.g., SQL Server 2025 or SQL Server 2022. Edition — Enterprise, Standard, Developer, Express, and Evaluation editions (options adjust to the selected version). Licensing model — Pay-As-You-Go (PAYG, default) or Azure Hybrid Benefit (AHB). Advanced configuration — Upload a custom mssql.conf file to set SQL connectivity, Azure Key Vault integration, and the tuned performance profile. Select Review + create, review the configuration summary, and select Create. Azure provisions the VM, then automatically installs and configures SQL Server and registers the VM with the SQL IaaS Agent extension. Managing licensing after deployment Because your VM is registered with the SQL IaaS Agent extension, you can change the licensing model anytime — with no downtime and no restart of the VM or SQL Server service. Azure portal: Go to the SQL virtual machine resource → Settings → SQL Server configuration → Manage. Azure CLI az sql vm update -n <VM_NAME> -g <RESOURCE_GROUP> --license-type AHUB Azure PowerShell: Set-AzSqlVM -Name <VM_NAME> -ResourceGroupName <RESOURCE_GROUP> -LicenseType AHUB Note: Switching between PAYG and AHB is immediate, incurs no additional cost, and does not restart the VM or the SQL Server service. Wrapping up The move to script-based deployment modernizes how you provision SQL Server on Linux Azure VMs. By replacing deprecated pre-created Marketplace images with a flexible, automated, script-based flow — and by registering every VM with the SQL IaaS Agent extension automatically — you get more choice, faster access to new Linux and SQL Server versions, and a cleaner path to licensing flexibility, compliance, and visibility. Whether you start from the Create a virtual machine tab or the Azure SQL hub, you get the same guided experience across RHEL 9, RHEL 10, Ubuntu 22.04, Ubuntu 24.04, and future versions. Ready to try it? Head to a Create a virtual machine option in the Azure portal. We’d love your feedback — let us know how the new experience works for your workloads in the comments.279Views1like0CommentsMove to Modern SQL Server Licensing with Confidence
Why eligible customers should move to pay-as-you-go licensing (PAYG) For eligible SQL Server workloads, PAYG should be the preferred licensing approach when moving away from licenses and Software Assurance. It aligns billing with measured usage, adapts as the estate changes, and reduces the operational burden of managing fixed license quantities. The transition requires deliberate resource-configuration updates, but the result is a more flexible and manageable licensing model. Align cost with measured usage: Adopt consumption-based billing for eligible SQL Server resources instead of maintaining fixed license allocations. Scale without repeated license true-ups: Let billing adjust as workloads are added, removed, migrated, resized, or used intermittently. Manage licensing through Azure: Use Azure-based controls to review resource-level licensing and improve visibility across the estate. Reduce license administration: Spend less time tracking fixed quantities and aligning individual resources with license inventory. Optimize committed consumption: After establishing stable PAYG usage, evaluate applicable Azure savings plans or reservations to help reduce costs. Guidance for transitioning your resource settings Once your organization decides to adopt PAYG for eligible SQL Server workloads, update the license configuration on each resource so billing reflects that decision. A commercial or licensing change alone does not update resource-level settings. Plan this configuration work as part of the transition rather than treating it as a follow-up. Starting early gives teams time to validate security, networking, Azure Arc connectivity, billing, and operational processes before switching the broader estate. Automate the transition to pay-as-you-go SQL licensing at scale Choose the transition approach that fits your estate PowerShell for a controlled bulk change Use PowerShell when you need a targeted transition across a defined tenant, subscription, resource group, or resource scope. Discover and review resources before making changes. Test the transition with a limited scope. Update eligible resources in bulk when the organization is ready. Validate the resulting license configuration and billing signals. Azure Policy for ongoing governance Use Azure Policy to transition existing SQL resources to PAYG and continuously enforce the desired licensing configuration. Azure Policy helps identify configuration drift, maintain compliance, and automatically remediate non-compliant resources at scale. Define the approved license configuration for eligible resources. Assign policy at the appropriate subscription or resource group scope. Monitor compliance through centralized Azure views. Remediate resources that drift from the approved configuration. Recommended path to PAYG Commit to the PAYG target. Confirm which eligible workloads will move and identify the teams responsible for licensing, Azure, security, networking, and SQL operations. Prepare the estate. For SQL Server running outside of Azure, connect to Azure Arc. Inventory eligible SQL resources and confirm that Azure Arc connectivity and required organizational approvals are in place. Prove the transition. Test resource updates and billing behavior in a limited resource group or subscription. Move at scale. Use PowerShell for a controlled bulk transition, then apply Azure Policy for ongoing governance where appropriate. Verify and operate. Review the resulting configuration, monitor compliance, and reassess as the SQL estate grows or changes. Evaluate commitment-based savings. After establishing a stable PAYG usage pattern, assess whether an applicable Azure savings plan or reservation could reduce costs. Review eligibility, coverage, and commitment terms with your Microsoft representative. Learn more Automate the transition to pay-as-you-go SQL licensing at scale Manage licensing and billing of SQL Server enabled by Azure Arc Pricing guidance for SQL Server on Azure VMs Azure SQL Database pricing Eligibility, billing treatment, prerequisites, and available licensing options vary by resource and licensing arrangement. Review the applicable Microsoft terms and product guidance, and consult your Microsoft representative or licensing specialist as needed.855Views0likes2Comments
Preview: SQL Assessment for SQL Server on Azure Virtual Machines
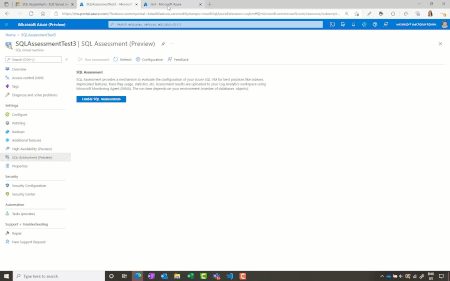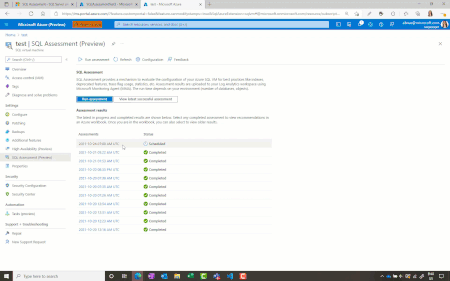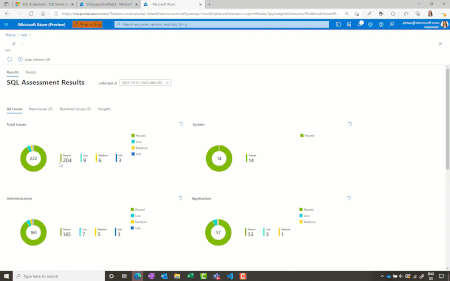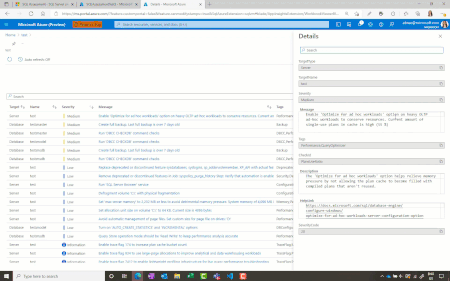
SQL Assessment feature will evaluate your SQL Server on Azure VM against configuration best practices to determine if your system is healthy and setup for success. This feature is available on the SQL virtual machine resource page and is currently in preview.6.9KViews2likes1CommentAnnouncing Preview of bulkadmin role support for SQL Server on Linux
Bulk data import using operations like BULK INSERT and OPENROWSET(BULK…) BULK INSERT (Transact-SQL) - SQL Server | Microsoft Learn is fundamental to ETL and data ingestion workflows. On SQL Server running on Linux, these operations have traditionally required sysadmin privileges, making it difficult to follow least‑privilege security practices. With the preview of BULKADMIN role support for SQL Server on Linux, this gap is addressed. Starting with SQL Server 2025 (17.x) CU3 and SQL Server 2022 CU24, administrators can grant the bulkadmin role or the ADMINISTER BULK OPERATIONS permission to enable bulk imports without full administrative access. This capability has long been available on SQL Server on Windows and is now extended to Linux, bringing consistent and more secure bulk data operations across platforms. Bulk import operation Bulk import operations enable fast, large‑volume data loading into SQL Server tables by reading data directly from external files instead of row‑by‑row inserts. Learn more Use BULK INSERT or OPENROWSET (BULK...) to Import Data to SQL Server - SQL Server | Microsoft Learn Who this is for DBAs, Data engineers, ETL developers and application engineers who want to perform bulk data imports without over‑privileging users. Why this matters Improved security posture: Eliminates the need for sysadmin access for bulk operations, enforcing least‑privilege security principle and reducing security risk. Better operational flexibility: Allows DBAs to safely delegate bulk data ingestion to application, ETL, and operational teams without expanding the attack surface. Parity with SQL Server on Windows: Closes a long‑standing gap between SQL Server on Windows and Linux, simplifying cross‑platform administration. Designed with layered security controls on Linux Bulk operations on Linux continue to enforce additional security checks beyond SQL permissions. Administrators must explicitly configure: Linux file system permissions for the SQL Server service account Approved bulk load directories using mssql-conf (by configuring the path through bulkadmin.allowedpathslist setting in mssql-conf) This ensures, SQL Server can only read data from explicitly allowed locations, reducing the risk of unauthorized file access. Learn more: For a quick overview, the typical flow to enable bulk import operations on SQL Server on Linux looks like this: Install SQL Server 2025 (17.x) CU3 Grant BULKADMIN role or ADMINISTER BULK OPERATIONS permission Configure allowed directories and required filesystem permissions Run bulk import operations using BULK INSERT or OPENROWSET (BULK...) For detailed guidance and example, refer to the official documentation: 👉 Configure bulk import operations for SQL Server on Linux Summary With BULKADMIN role support on SQL Server for Linux, customers can now enable bulk data imports without compromising security. This enhancement delivers better role separation, security best practices, and a smoother operational experience for SQL Server on Linux. We encourage customers to explore this capability and adopt least privileged bulk data workflows in their Linux environments.411Views0likes0Comments
Smarter Parallelism: Degree of parallelism feedback in SQL Server 2025
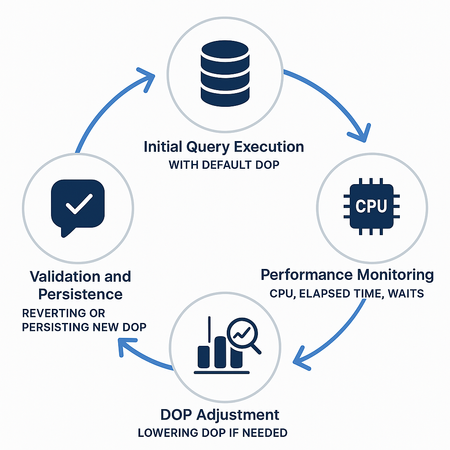
🚀 Introduction With SQL Server 2025, we have made Degree of parallelism (DOP) feedback an on by default feature. Originally introduced in SQL Server 2022, DOP feedback is now a core part of the platform’s self-tuning capabilities, helping workloads scale more efficiently without manual tuning. The feature works with database compatibility 160 or higher. ⚙️ What Is DOP feedback? DOP feedback is part of the Intelligent Query Processing (IQP) family of features. It dynamically adjusts the number of threads (DOP) used by a query based on runtime performance metrics like CPU time and elapsed time. If a query that has generated a parallel plan consistently underperforms due to excessive parallelism, the DOP feedback feature will reduce the DOP for future executions without requiring recompilation. Currently, DOP feedback will only recommend reductions to the degree of parallelism setting on a per query plan basis. The Query Store must be enabled for every database where DOP feedback is used, and be in a "read write" state. This feedback loop is: Persistent: Stored in Query Store. Persistence is not currently available for Query Store on readable secondaries. This is subject to change in the near future, and we'll provide an update to it's status after that occurs. Adaptive: Adjusts a query’s DOP, monitors those adjustments, and reverts any changes to a previous DOP if performance regresses. This part of the system relies on Query Store being enabled as it relies on the runtime statistics captured within the Query Store. Scoped: Controlled via the DOP_FEEDBACK database-scoped configuration or at the individual query level with the use of the DISABLE_DOP_FEEDBACK query hint. 🧪 How It Works Initial Execution: SQL Server compiles and executes a query with a default or manually set DOP. Monitoring: Runtime stats are collected and compared across executions. Adjustment: If inefficiencies are detected, DOP is lowered (minimum of 2). Validation: If performance improves and is stable, the new DOP is persisted. If not, the DOP recommendation will be reverted to the previously known good DOP setting, which is typically the original setting that the feature used as a baseline. At the end of the validation period any feedback that has been persisted, regardless of its state (i.e. stabilized, reverted, no recommendation, etc.) can be viewed by querying the sys.query_store_plan_feedback system catalog view: SELECT qspf.feature_desc, qsq.query_id, qsp.plan_id, qspf.plan_feedback_id, qsqt.query_sql_text, qsp.query_plan, qspf.state_desc, qspf.feedback_data, qspf.create_time, qspf.last_updated_time FROM sys.query_store_query AS qsq INNER JOIN sys.query_store_plan AS qsp ON qsp.query_id = qsq.query_id INNER JOIN sys.query_store_query_text AS qsqt ON qsqt.query_text_id = qsq.query_text_id INNER JOIN sys.query_store_plan_feedback AS qspf ON qspf.plan_id = qsp.plan_id WHERE qspf.feature_id = 3; 🆕 What’s New in SQL Server 2025? Enabled by Default: No need to toggle the database scoped configuration on, DOP feedback is active out of the box. Improved Stability: Enhanced validation logic ensures fewer regressions. Better Integration: Works seamlessly with other IQP features like Memory Grant feedback , Cardinality Estimation feedback, and Parameter Sensitive Plan (PSP) optimization. 📊 Visualizing the Feedback Loop 🧩 How can I see if DOP feedback is something that would be beneficial for me? Without setting up an Extended Event session for deeper analysis, looking over some of the data in the Query Store can be useful in determining if DOP feedback would find interesting enough queries for it to engage. At a minimum, if your SQL Server instance is operating with parallelism enabled and has: o a MAXDOP value of 0 (not generally recommended) or a MAXDOP value greater than 2 o you observe multiple queries have execution runtimes of 10 seconds or more along with a degree of parallelism of 4 or greater o and have an execution count 15 or more according to the output from the query below SELECT TOP 20 qsq.query_id, qsrs.plan_id, [replica_type] = CASE WHEN replica_group_id = '1' THEN 'PRIMARY' WHEN replica_group_id = '2' THEN 'SECONDARY' WHEN replica_group_id = '3' THEN 'GEO SECONDARY' WHEN replica_group_id = '4' THEN 'GEO HA SECONDARY' ELSE TRY_CONVERT(NVARCHAR (200), qsrs.replica_group_id) END, AVG(qsrs.avg_dop) as dop, SUM(qsrs.count_executions) as execution_count, AVG(qsrs.avg_duration)/1000000.0 as duration_in_seconds, MIN(qsrs.min_duration)/1000000.0 as min_duration_in_seconds FROM sys.query_store_runtime_stats qsrs INNER JOIN sys.query_store_plan qsp ON qsp.plan_id = qsrs.plan_id INNER JOIN sys.query_store_query qsq ON qsq.query_id = qsp.query_id GROUP BY qsrs.plan_id, qsq.query_id, qsrs.replica_group_id HAVING MIN(qsrs.min_duration)/1000000.0 >= 10 ORDER BY dop desc, execution_count desc; 🧠 Behind the Scenes: How Feedback Is Evaluated DOP feedback uses a rolling window of recent executions (typically 15) to evaluate: Average CPU time Standard deviation of CPU time Adjusted elapsed time* Stability of performance across executions If the adjusted DOP consistently improves efficiency without regressing performance, it is persisted. Otherwise, the system reverts to the last known good configuration (also knows as the default dop to the system). As an example, if the dop for a query started out with a value of 8, and DOP feedback determined that a DOP of 4 was an optimal number; if over the period of the rolling window and while the query is in the validation phase, if the query performance varied more than expected, DOP feedback will undo it's change of 4 and set the query back to having a DOP of 8. 🧠 Note: The adjusted elapsed time intentionally excludes wait statistics that are not relevant to parallelism efficiency. This includes ignoring buffer latch, buffer I/O, and network I/O waits, which are external to parallel query execution. This ensures that feedback decisions are based solely on CPU and execution efficiency, not external factors like I/O or network latency. 🧭 Best Practices Enable Query Store: This is required for DOP feedback to function. Monitor DOP feedback extended events SQL Server provides a set of extended events to help you monitor and troubleshoot the DOP feedback lifecycle. Below is a sample script to create a session that captures key events, followed by a breakdown of what each event means. IF EXISTS (SELECT * FROM sys.server_event_sessions WHERE name = 'dop_xevents') DROP EVENT SESSION [dop_xevents] ON SERVER; GO CREATE EVENT SESSION [dop_xevents] ON SERVER ADD EVENT sqlserver.dop_feedback_analysis_stopped, ADD EVENT sqlserver.dop_feedback_eligible_query, ADD EVENT sqlserver.dop_feedback_provided, ADD EVENT sqlserver.dop_feedback_reassessment_failed, ADD EVENT sqlserver.dop_feedback_reverted, ADD EVENT sqlserver.dop_feedback_stabilized -- ADD EVENT sqlserver.dop_feedback_validation WITH ( MAX_MEMORY = 4096 KB, EVENT_RETENTION_MODE = ALLOW_SINGLE_EVENT_LOSS, MAX_DISPATCH_LATENCY = 30 SECONDS, MAX_EVENT_SIZE = 0 KB, MEMORY_PARTITION_MODE = NONE, TRACK_CAUSALITY = OFF, STARTUP_STATE = OFF ); ⚠️ Note: The extended event that has been commented out (dop_feedback_validation) is part of the debug channel. Enabling it may introduce additional overhead and should be used with caution in production environments. 📋 DOP Feedback Extended Events Reference Event Name Description dop_feedback_eligible_query Fired when a query plan becomes eligible for DOP feedback. Captures initial runtime stats like CPU time and adjusted elapsed time. dop_feedback_analysis_stopped Indicates that SQL Server has stopped analyzing a query for DOP feedback. Reasons include high variance in stats or the optimal DOP has already been achieved. dop_feedback_provided Fired when SQL Server provides a new DOP recommendation for a query. Includes baseline and feedback stats. dop_feedback_reassessment_failed Indicates that a previously persisted feedback DOP was reassessed and found to be invalid, restarting the feedback cycle. dop_feedback_reverted Fired when feedback is rolled back due to performance regression. Includes baseline and feedback stats. dop_feedback_stabilized Indicates that feedback has been validated and stabilized. After stabilization, additional adjustment to the feedback can be made when the system reassesses the feedback on a periodic basis. 🔍 Understanding the feedback_data JSON in DOP feedback In the "How it works" section of this article, we had provided a sample script that showed some of the data that can be persisted within the sys.query_store_plan_feedback catalog view. When DOP feedback stabilizes, SQL Server stores a JSON payload in the feedback_data column of that view, figuring out how to interpret that data can sometimes be challenging. From a structural perspective, the feedback_data field contains a JSON object with two main sections; LastGoodFeedback and BaselineStats. As an example { "LastGoodFeedback": { "dop": "2", "avg_cpu_time_ms": "12401", "avg_adj_elapsed_time_ms": "12056", "std_cpu_time_ms": "380", "std_adj_elapsed_time_ms": "342" }, "BaselineStats": { "dop": "4", "avg_cpu_time_ms": "17843", "avg_adj_elapsed_time_ms": "13468", "std_cpu_time_ms": "333", "std_adj_elapsed_time_ms": "328" } } Section Field Description LastGoodFeedback dop The DOP value that was validated and stabilized for future executions. avg_cpu_time_ms Average CPU time (in milliseconds) for executions using the feedback DOP. avg_adj_elapsed_time_ms Adjusted elapsed time (in milliseconds), excluding irrelevant waits. std_cpu_time_ms Standard deviation of CPU time across executions. std_adj_elapsed_time_ms Standard deviation of adjusted elapsed time. BaselineStats dop The original DOP used before feedback was applied. avg_cpu_time_ms Average CPU time for the baseline executions. avg_adj_elapsed_time_ms Adjusted elapsed time for the baseline executions. std_cpu_time_ms Standard deviation of CPU time for the baseline. std_adj_elapsed_time_ms Standard deviation of adjusted elapsed time for the baseline. One method that can be used to extract this data could be to utilize the JSON_VALUE function: SELECT qspf.plan_id, qs.query_id, qt.query_sql_text, qsp.query_plan_hash, qspf.feature_desc, -- LastGoodFeedback metrics JSON_VALUE(qspf.feedback_data, '$.LastGoodFeedback.dop') AS last_good_dop, JSON_VALUE(qspf.feedback_data, '$.LastGoodFeedback.avg_cpu_time_ms') AS last_good_avg_cpu_time_ms, JSON_VALUE(qspf.feedback_data, '$.LastGoodFeedback.avg_adj_elapsed_time_ms') AS last_good_avg_adj_elapsed_time_ms, JSON_VALUE(qspf.feedback_data, '$.LastGoodFeedback.std_cpu_time_ms') AS last_good_std_cpu_time_ms, JSON_VALUE(qspf.feedback_data, '$.LastGoodFeedback.std_adj_elapsed_time_ms') AS last_good_std_adj_elapsed_time_ms, -- BaselineStats metrics JSON_VALUE(qspf.feedback_data, '$.BaselineStats.dop') AS baseline_dop, JSON_VALUE(qspf.feedback_data, '$.BaselineStats.avg_cpu_time_ms') AS baseline_avg_cpu_time_ms, JSON_VALUE(qspf.feedback_data, '$.BaselineStats.avg_adj_elapsed_time_ms') AS baseline_avg_adj_elapsed_time_ms, JSON_VALUE(qspf.feedback_data, '$.BaselineStats.std_cpu_time_ms') AS baseline_std_cpu_time_ms, JSON_VALUE(qspf.feedback_data, '$.BaselineStats.std_adj_elapsed_time_ms') AS baseline_std_adj_elapsed_time_ms FROM sys.query_store_plan_feedback AS qspf JOIN sys.query_store_plan AS qsp ON qspf.plan_id = qsp.plan_id JOIN sys.query_store_query AS qs ON qsp.query_id = qs.query_id JOIN sys.query_store_query_text AS qt ON qs.query_text_id = qt.query_text_id WHERE qspf.feature_desc = 'DOP Feedback' AND ISJSON(qspf.feedback_data) = 1; 🧪 Why This Matters This JSON structure is critical for: Debugging regressions: You can compare baseline and feedback statistics to understand if a change in DOP helped or hurt a set of queries. Telemetry and tuning: Tools can be used to parse this JSON payload to surface insights in performance dashboards. Transparency: It provides folks that care about the database visibility into how SQL Server is adapting to their workload. 📚 Learn More Intelligent Query Processing: degree of parallelism feedback Degree of parallelism (DOP) feedback Intelligent query processing in SQL databases Microsoft SQL Server1.8KViews1like0CommentsAnnouncement: Upcoming Changes to SQL Server on Linux Virtual Machine (VM) Provisioning in Azure
We’re making an important update to how customers provision SQL Server on Linux virtual machines (VMs) in Azure. What’s Changing? Starting soon, Linux-based SQL Server Virtual Machine (VM) images published by Microsoft will be removed from the Azure Marketplace. As a result, these SQL Server on Linux images will no longer be visible in the Azure SQL hub during VM provisioning, nor accessible via CLI, Azure Portal, or PowerShell scripts. This change is part of our broader effort to simplify and modernise the provisioning experience for SQL Server Linux on Azure. Why Are We Making This Change? We’re transitioning away from image-based provisioning to a script-based model that offers greater flexibility, automation, and control. This fresh approach will allow customers to: Choose their preferred supported Linux distribution (RHEL, SLES or Ubuntu (Pro)) Select SQL Server version and edition Configure licensing options Customise deployment parameters through scripts and ability to add VM extensions. This shift ensures a more consistent and extensible experience across all supported platforms. When Will This Happen? The deprecation of Linux VM images will begin shortly and will be completed over the next couple of months. During this transition, customers may notice the SQL Server on Linux based Azure marketplace image listings may not be available. What Should You Do? For the Azure Virtual Machines deployed using the SQL on Linux Azure marketplace images in the past they'd continue to work, but if you’re planning to deploy new SQL Server on Linux based Azure Virtual Machines, please follow the below steps: Manual installation is recommended during this transition period. Start by creating a Linux Virtual Machine using the Azure Portal, CLI, or PowerShell. Once the VM is provisioned, follow the official SQL Server installation documentation to complete the setup. VM Creation Guidance: You can refer to this guide for step-by-step instructions on creating an Azure Linux-based virtual machine: https://learn.microsoft.com/en-us/azure/virtual-machines/linux/quick-create-portal Choosing a Linux Distribution: Feel free to select the distribution that best fits your requirements. For a list of endorsed Linux distributions on Azure, see: Linux distributions endorsed on Azure - Azure Virtual Machines | Microsoft Learn Please note, SQL Server is officially supported only on the following Linux distributions. Based on the distribution you choose, refer to the corresponding documentation for SQL Server installation guidance: Red Hat Enterprise Linux (RHEL) SUSE Linux Enterprise Server (SLES) Ubuntu For more details on supported distributions refer to: SQL Server 2025 - Supported Linux distributions SQL Server 2022 - Supported Linux distributions A new script-based provisioning experience is coming soon - stay tuned for announcements. We’ll continue to share updates through the Azure portal, documentation, and this blog.1.4KViews3likes0Comments