sqlserverazurevm
52 Topics
BULKADMIN role support for SQL Server on Linux is now Generally Available
Starting with SQL Server 2025 CU9 and SQL Server 2022 CU27, SQL Server on Linux supports the bulkadmin fixed server role and the ADMINISTER BULK OPERATIONS permission for performing bulk data import operations without requiring users to be members of the sysadmin fixed server role. This capability enables you to use operations such as BULK INSERT and OPENROWSET(BULK...) while following a least-privilege security model. Previously on SQL Server on Linux, these operations required sysadmin membership. With this GA (Generally Available) release, organizations running SQL Server on Linux can provide users with the permissions required for bulk data loading without granting broader sysadmin privileges, improving alignment with the principle of least privilege. The feature applies to SQL Server on Linux, including on-premises, SQL Server on Azure VMs and container deployments. Learn more: BULK INSERT (Transact-SQL) - SQL Server | Microsoft Learn Announcing Preview of bulkadmin role support for SQL Server on Linux | Microsoft Community Hub20Views0likes0CommentsDynamic Data Masking – What it is, What it isn’t, and How to use it effectively
In this post, we’ll explain the core purpose of Dynamic Data Masking feature (to ease application development) Dynamic Data Masking - SQL Server | Microsoft Learn, how it works, and its proper use cases – as well as its limitations. If you’re considering using Dynamic Data Masking (DDM) or reviewing your data security strategy, this information will help you make informed decisions. What Dynamic Data Masking is designed for Dynamic Data Masking was introduced in SQL Server 2016 as a built-in method to mask sensitive data in query results. DDM intercepts the results of a query before they leave the database engine and replaces certain pieces of data with a masked representation. For example, with DDM you can configure that any query on the email column returns values like jXXX@XXXX.com instead of the real email address – without changing the stored data. The feature was designed to simplify the application developer’s job: if you need to hide or obfuscate data for privacy, you can do it centrally and declaratively in the database, rather than writing custom code in every application. In essence, with DDM, masking rules are defined once in the database and enforced automatically on query results for non-privileged users. This removes the need to duplicate masking logic across applications and reports. By default, developers and analysts see masked data, helping prevent accidental or casual exposure of sensitive information, which prevents “shoulder surfing” leaks. How Does DDM differ from other security features Dynamic Data Masking affects only what users see in query results—it does not protect the underlying data. Unlike encryption Always Encrypted - SQL Server | Microsoft Learn or Row‑Level security Row-Level Security - SQL Server | Microsoft Learn, DDM does not encrypt data, filter rows, or override SQL permissions. Users with elevated privileges (such as UNMASK, db_owner, or sysadmin) always see unmasked data and can modify or remove masking rules. What DDM doesn’t protect against Because DDM operates only at the point of returning query results, it has inherent limitations that users must understand: Inference and query logic: A determined user with database access can often infer the masked data by exploiting query conditions. A curious user could run a series of queries narrowing down, until they pinpoint a specific value or range for a particular column. The database is still comparing the real values under the hood, so these queries work. It’s important to note this is not a bug; it’s expected behavior given DDM’s design. Users with extra permissions: If a user manages to gain higher privileges, such as the ability to alter table schemas, they can directly disable or remove masking. Thus, controlling and auditing who holds such privileges is vital. Metadata exposure: Masking rules and masked columns are discoverable through system metadata. Data moving or copying: Dynamic masking is not a property of the data itself; it’s a property of the table schema in a particular database. Masking is a property of the table schema in a specific database. Backups, copies, or exports may expose unmasked data depending on permissions. Proper use and best practices for DDM Given these design behaviors, how should one use Dynamic Data Masking effectively? Here are the recommendations: Use DDM for reducing development effort: Use DDM when the goal is to reduce development complexity, improve consistency across applications, and provide a cleaner user experience. Combine DDM with other features: Dynamic Data Masking works best as one layer of defense in a “Defense in Depth” strategy. For example if you have Row-Level Security, implementing DDM can add an additional layer of confidentiality by masking columns within the allowed rows. Tightly control privileged access: Pay close attention to those who have roles like db_owner, sysadmin, or CONTROL permissions on the database. Also audit who has the ability to query masked columns and alter schemas or masks. Educate users and stakeholders: Make sure that anyone in your organization who designs security or compliance solutions understands the nature of DDM. It can be misleading if not understood. Monitor for abuse: Implement auditing on your masked tables and columns to catch if someone is attempting to work around DDM and address it. Test your masking configurations: In a non-production environment, perform some tests on your own implementation and validate the results. Conclusion Dynamic Data Masking is most effective when used for its intended purpose: simplifying data masking in applications and reducing accidental data exposure. It improves consistency and developer productivity, but it is not a security boundary. When used as part of a broader defense‑in‑depth strategy, DDM can provide meaningful benefits.26Views0likes0CommentsAnnouncing flexible provisioning for SQL Server on Linux Azure VMs (Public Preview)
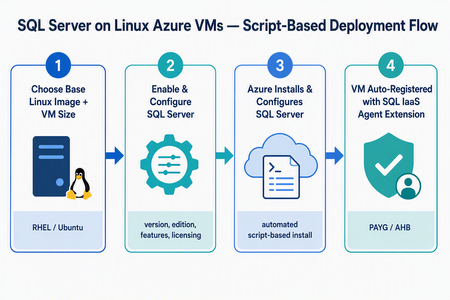
What’s changing We’re introducing a new script-based deployment experience for provisioning SQL Server on Linux Azure Virtual Machines (VMs). This experience replaces the earlier model that relied on pre-created SQL Server on Linux Marketplace images, which have been deprecated. Pre-created SQL Server on Linux Marketplace images are no longer available for new provisioning through the Azure portal, the Azure SQL hub, Azure CLI, or PowerShell. Instead, SQL Server is now installed and configured during VM provisioning using a flexible, automated, script-based workflow. The result is a more adaptable and supportable deployment model that keeps SQL Server on Linux Azure VMs fully supported, reduces image-maintenance overhead, and makes it easier to adopt the latest Linux distributions, VM families, and configuration options - all while giving you more control over your SQL Server setup. Why the new model matters Greater flexibility and control — choose your Linux distribution, SQL Server version, edition, and even bring your own mssql.conf to tailor the configuration. Faster access to innovation — new Linux versions and Azure capabilities are picked up automatically, without waiting for a new baked image to be published. Automatic registration built in — every VM is registered with the SQL IaaS Agent extension by default, unlocking licensing flexibility, compliance, and richer visibility. A dynamic, guided UI — the portal enables or disables options based on supported operating system, SQL Server, and licensing combinations, so you only see valid choices. Supported Linux distributions The script-based deployment experience supports the following distributions, and future versions are picked up automatically as they become supported — no manual intervention required: Distribution Supported versions Red Hat Enterprise Linux (RHEL) RHEL 9, RHEL 10 (and future versions) Ubuntu Ubuntu 22.04, Ubuntu 24.04, Ubuntu 26.04 (and future versions) Automatic registration applies to both Red Hat Enterprise Linux and Ubuntu, across all their supported versions. Automatic registration with the SQL IaaS Agent extension SQL Server on Linux VMs deployed through this experience are automatically registered with the SQL Server IaaS Agent extension. Registration creates a SQL virtual machine resource in Azure (separate from the VM resource) and unlocks: Licensing flexibility — choose Pay-As-You-Go (PAYG) or Azure Hybrid Benefit (AHB), and switch between them anytime with no downtime. Compliance — a simplified way to meet Azure Hybrid Benefit product-term requirements without per-resource registration forms. Visibility and telemetry — clear license-type visibility, subscription-level tracking, and better operational insight from the Azure portal, CLI, or PowerShell. Note: Automatic registration is enabled by default during deployment. You can unregister or re-register a VM after deployment through the Azure portal, Azure CLI, or PowerShell. The end-to-end flow at a glance Experience: The “Create a virtual machine” tab Use this flow if you’re starting from the familiar VM creation experience in the Azure portal. In the Azure portal, go to Virtual machines (or Create a resource → Virtual machine) and select Create. On the Basics tab, select your project details (subscription, resource group), instance details, and a supported Linux base image — RHEL 9, RHEL 10, Ubuntu 22.04, or Ubuntu 24.04. Choose your VM size, authentication, and inbound ports as usual. Go to the Advanced tab and select the Install SQL Server checkbox. This enables SQL Server provisioning on the VM. A new SQL Server settings tab becomes available. Open it to configure your SQL Server deployment: SQL Server version — e.g., SQL Server 2025 or SQL Server 2022. Edition — Enterprise, Standard, Developer, Express, and Evaluation editions (options adjust to the selected version). Licensing model — Pay-As-You-Go (PAYG, default) or Azure Hybrid Benefit (AHB). Advanced configuration — Upload a custom mssql.conf file to set SQL connectivity, Azure Key Vault integration, and the tuned performance profile. Select Review + create, review the configuration summary, and select Create. Azure provisions the VM, then automatically installs and configures SQL Server and registers the VM with the SQL IaaS Agent extension. Managing licensing after deployment Because your VM is registered with the SQL IaaS Agent extension, you can change the licensing model anytime — with no downtime and no restart of the VM or SQL Server service. Azure portal: Go to the SQL virtual machine resource → Settings → SQL Server configuration → Manage. Azure CLI az sql vm update -n <VM_NAME> -g <RESOURCE_GROUP> --license-type AHUB Azure PowerShell: Set-AzSqlVM -Name <VM_NAME> -ResourceGroupName <RESOURCE_GROUP> -LicenseType AHUB Note: Switching between PAYG and AHB is immediate, incurs no additional cost, and does not restart the VM or the SQL Server service. Wrapping up The move to script-based deployment modernizes how you provision SQL Server on Linux Azure VMs. By replacing deprecated pre-created Marketplace images with a flexible, automated, script-based flow — and by registering every VM with the SQL IaaS Agent extension automatically — you get more choice, faster access to new Linux and SQL Server versions, and a cleaner path to licensing flexibility, compliance, and visibility. Whether you start from the Create a virtual machine tab or the Azure SQL hub, you get the same guided experience across RHEL 9, RHEL 10, Ubuntu 22.04, Ubuntu 24.04, and future versions. Ready to try it? Head to a Create a virtual machine option in the Azure portal. We’d love your feedback — let us know how the new experience works for your workloads in the comments.110Views1like0CommentsMove to Modern SQL Server Licensing with Confidence
Why eligible customers should move to pay-as-you-go licensing (PAYG) For eligible SQL Server workloads, PAYG should be the preferred licensing approach when moving away from licenses and Software Assurance. It aligns billing with measured usage, adapts as the estate changes, and reduces the operational burden of managing fixed license quantities. The transition requires deliberate resource-configuration updates, but the result is a more flexible and manageable licensing model. Align cost with measured usage: Adopt consumption-based billing for eligible SQL Server resources instead of maintaining fixed license allocations. Scale without repeated license true-ups: Let billing adjust as workloads are added, removed, migrated, resized, or used intermittently. Manage licensing through Azure: Use Azure-based controls to review resource-level licensing and improve visibility across the estate. Reduce license administration: Spend less time tracking fixed quantities and aligning individual resources with license inventory. Optimize committed consumption: After establishing stable PAYG usage, evaluate applicable Azure savings plans or reservations to help reduce costs. Guidance for transitioning your resource settings Once your organization decides to adopt PAYG for eligible SQL Server workloads, update the license configuration on each resource so billing reflects that decision. A commercial or licensing change alone does not update resource-level settings. Plan this configuration work as part of the transition rather than treating it as a follow-up. Starting early gives teams time to validate security, networking, Azure Arc connectivity, billing, and operational processes before switching the broader estate. Automate the transition to pay-as-you-go SQL licensing at scale Choose the transition approach that fits your estate PowerShell for a controlled bulk change Use PowerShell when you need a targeted transition across a defined tenant, subscription, resource group, or resource scope. Discover and review resources before making changes. Test the transition with a limited scope. Update eligible resources in bulk when the organization is ready. Validate the resulting license configuration and billing signals. Azure Policy for ongoing governance Use Azure Policy to transition existing SQL resources to PAYG and continuously enforce the desired licensing configuration. Azure Policy helps identify configuration drift, maintain compliance, and automatically remediate non-compliant resources at scale. Define the approved license configuration for eligible resources. Assign policy at the appropriate subscription or resource group scope. Monitor compliance through centralized Azure views. Remediate resources that drift from the approved configuration. Recommended path to PAYG Commit to the PAYG target. Confirm which eligible workloads will move and identify the teams responsible for licensing, Azure, security, networking, and SQL operations. Prepare the estate. For SQL Server running outside of Azure, connect to Azure Arc. Inventory eligible SQL resources and confirm that Azure Arc connectivity and required organizational approvals are in place. Prove the transition. Test resource updates and billing behavior in a limited resource group or subscription. Move at scale. Use PowerShell for a controlled bulk transition, then apply Azure Policy for ongoing governance where appropriate. Verify and operate. Review the resulting configuration, monitor compliance, and reassess as the SQL estate grows or changes. Evaluate commitment-based savings. After establishing a stable PAYG usage pattern, assess whether an applicable Azure savings plan or reservation could reduce costs. Review eligibility, coverage, and commitment terms with your Microsoft representative. Learn more Automate the transition to pay-as-you-go SQL licensing at scale Manage licensing and billing of SQL Server enabled by Azure Arc Pricing guidance for SQL Server on Azure VMs Azure SQL Database pricing Eligibility, billing treatment, prerequisites, and available licensing options vary by resource and licensing arrangement. Review the applicable Microsoft terms and product guidance, and consult your Microsoft representative or licensing specialist as needed.720Views0likes2Comments
Preview: SQL Assessment for SQL Server on Azure Virtual Machines
SQL Assessment feature will evaluate your SQL Server on Azure VM against configuration best practices to determine if your system is healthy and setup for success. This feature is available on the SQL virtual machine resource page and is currently in preview.6.9KViews2likes1CommentAnnouncing Preview of bulkadmin role support for SQL Server on Linux
Bulk data import using operations like BULK INSERT and OPENROWSET(BULK…) BULK INSERT (Transact-SQL) - SQL Server | Microsoft Learn is fundamental to ETL and data ingestion workflows. On SQL Server running on Linux, these operations have traditionally required sysadmin privileges, making it difficult to follow least‑privilege security practices. With the preview of BULKADMIN role support for SQL Server on Linux, this gap is addressed. Starting with SQL Server 2025 (17.x) CU3 and SQL Server 2022 CU24, administrators can grant the bulkadmin role or the ADMINISTER BULK OPERATIONS permission to enable bulk imports without full administrative access. This capability has long been available on SQL Server on Windows and is now extended to Linux, bringing consistent and more secure bulk data operations across platforms. Bulk import operation Bulk import operations enable fast, large‑volume data loading into SQL Server tables by reading data directly from external files instead of row‑by‑row inserts. Learn more Use BULK INSERT or OPENROWSET (BULK...) to Import Data to SQL Server - SQL Server | Microsoft Learn Who this is for DBAs, Data engineers, ETL developers and application engineers who want to perform bulk data imports without over‑privileging users. Why this matters Improved security posture: Eliminates the need for sysadmin access for bulk operations, enforcing least‑privilege security principle and reducing security risk. Better operational flexibility: Allows DBAs to safely delegate bulk data ingestion to application, ETL, and operational teams without expanding the attack surface. Parity with SQL Server on Windows: Closes a long‑standing gap between SQL Server on Windows and Linux, simplifying cross‑platform administration. Designed with layered security controls on Linux Bulk operations on Linux continue to enforce additional security checks beyond SQL permissions. Administrators must explicitly configure: Linux file system permissions for the SQL Server service account Approved bulk load directories using mssql-conf (by configuring the path through bulkadmin.allowedpathslist setting in mssql-conf) This ensures, SQL Server can only read data from explicitly allowed locations, reducing the risk of unauthorized file access. Learn more: For a quick overview, the typical flow to enable bulk import operations on SQL Server on Linux looks like this: Install SQL Server 2025 (17.x) CU3 Grant BULKADMIN role or ADMINISTER BULK OPERATIONS permission Configure allowed directories and required filesystem permissions Run bulk import operations using BULK INSERT or OPENROWSET (BULK...) For detailed guidance and example, refer to the official documentation: 👉 Configure bulk import operations for SQL Server on Linux Summary With BULKADMIN role support on SQL Server for Linux, customers can now enable bulk data imports without compromising security. This enhancement delivers better role separation, security best practices, and a smoother operational experience for SQL Server on Linux. We encourage customers to explore this capability and adopt least privileged bulk data workflows in their Linux environments.358Views0likes0Comments
Smarter Parallelism: Degree of parallelism feedback in SQL Server 2025
🚀 Introduction With SQL Server 2025, we have made Degree of parallelism (DOP) feedback an on by default feature. Originally introduced in SQL Server 2022, DOP feedback is now a core part of the platform’s self-tuning capabilities, helping workloads scale more efficiently without manual tuning. The feature works with database compatibility 160 or higher. ⚙️ What Is DOP feedback? DOP feedback is part of the Intelligent Query Processing (IQP) family of features. It dynamically adjusts the number of threads (DOP) used by a query based on runtime performance metrics like CPU time and elapsed time. If a query that has generated a parallel plan consistently underperforms due to excessive parallelism, the DOP feedback feature will reduce the DOP for future executions without requiring recompilation. Currently, DOP feedback will only recommend reductions to the degree of parallelism setting on a per query plan basis. The Query Store must be enabled for every database where DOP feedback is used, and be in a "read write" state. This feedback loop is: Persistent: Stored in Query Store. Persistence is not currently available for Query Store on readable secondaries. This is subject to change in the near future, and we'll provide an update to it's status after that occurs. Adaptive: Adjusts a query’s DOP, monitors those adjustments, and reverts any changes to a previous DOP if performance regresses. This part of the system relies on Query Store being enabled as it relies on the runtime statistics captured within the Query Store. Scoped: Controlled via the DOP_FEEDBACK database-scoped configuration or at the individual query level with the use of the DISABLE_DOP_FEEDBACK query hint. 🧪 How It Works Initial Execution: SQL Server compiles and executes a query with a default or manually set DOP. Monitoring: Runtime stats are collected and compared across executions. Adjustment: If inefficiencies are detected, DOP is lowered (minimum of 2). Validation: If performance improves and is stable, the new DOP is persisted. If not, the DOP recommendation will be reverted to the previously known good DOP setting, which is typically the original setting that the feature used as a baseline. At the end of the validation period any feedback that has been persisted, regardless of its state (i.e. stabilized, reverted, no recommendation, etc.) can be viewed by querying the sys.query_store_plan_feedback system catalog view: SELECT qspf.feature_desc, qsq.query_id, qsp.plan_id, qspf.plan_feedback_id, qsqt.query_sql_text, qsp.query_plan, qspf.state_desc, qspf.feedback_data, qspf.create_time, qspf.last_updated_time FROM sys.query_store_query AS qsq INNER JOIN sys.query_store_plan AS qsp ON qsp.query_id = qsq.query_id INNER JOIN sys.query_store_query_text AS qsqt ON qsqt.query_text_id = qsq.query_text_id INNER JOIN sys.query_store_plan_feedback AS qspf ON qspf.plan_id = qsp.plan_id WHERE qspf.feature_id = 3; 🆕 What’s New in SQL Server 2025? Enabled by Default: No need to toggle the database scoped configuration on, DOP feedback is active out of the box. Improved Stability: Enhanced validation logic ensures fewer regressions. Better Integration: Works seamlessly with other IQP features like Memory Grant feedback , Cardinality Estimation feedback, and Parameter Sensitive Plan (PSP) optimization. 📊 Visualizing the Feedback Loop 🧩 How can I see if DOP feedback is something that would be beneficial for me? Without setting up an Extended Event session for deeper analysis, looking over some of the data in the Query Store can be useful in determining if DOP feedback would find interesting enough queries for it to engage. At a minimum, if your SQL Server instance is operating with parallelism enabled and has: o a MAXDOP value of 0 (not generally recommended) or a MAXDOP value greater than 2 o you observe multiple queries have execution runtimes of 10 seconds or more along with a degree of parallelism of 4 or greater o and have an execution count 15 or more according to the output from the query below SELECT TOP 20 qsq.query_id, qsrs.plan_id, [replica_type] = CASE WHEN replica_group_id = '1' THEN 'PRIMARY' WHEN replica_group_id = '2' THEN 'SECONDARY' WHEN replica_group_id = '3' THEN 'GEO SECONDARY' WHEN replica_group_id = '4' THEN 'GEO HA SECONDARY' ELSE TRY_CONVERT(NVARCHAR (200), qsrs.replica_group_id) END, AVG(qsrs.avg_dop) as dop, SUM(qsrs.count_executions) as execution_count, AVG(qsrs.avg_duration)/1000000.0 as duration_in_seconds, MIN(qsrs.min_duration)/1000000.0 as min_duration_in_seconds FROM sys.query_store_runtime_stats qsrs INNER JOIN sys.query_store_plan qsp ON qsp.plan_id = qsrs.plan_id INNER JOIN sys.query_store_query qsq ON qsq.query_id = qsp.query_id GROUP BY qsrs.plan_id, qsq.query_id, qsrs.replica_group_id HAVING MIN(qsrs.min_duration)/1000000.0 >= 10 ORDER BY dop desc, execution_count desc; 🧠 Behind the Scenes: How Feedback Is Evaluated DOP feedback uses a rolling window of recent executions (typically 15) to evaluate: Average CPU time Standard deviation of CPU time Adjusted elapsed time* Stability of performance across executions If the adjusted DOP consistently improves efficiency without regressing performance, it is persisted. Otherwise, the system reverts to the last known good configuration (also knows as the default dop to the system). As an example, if the dop for a query started out with a value of 8, and DOP feedback determined that a DOP of 4 was an optimal number; if over the period of the rolling window and while the query is in the validation phase, if the query performance varied more than expected, DOP feedback will undo it's change of 4 and set the query back to having a DOP of 8. 🧠 Note: The adjusted elapsed time intentionally excludes wait statistics that are not relevant to parallelism efficiency. This includes ignoring buffer latch, buffer I/O, and network I/O waits, which are external to parallel query execution. This ensures that feedback decisions are based solely on CPU and execution efficiency, not external factors like I/O or network latency. 🧭 Best Practices Enable Query Store: This is required for DOP feedback to function. Monitor DOP feedback extended events SQL Server provides a set of extended events to help you monitor and troubleshoot the DOP feedback lifecycle. Below is a sample script to create a session that captures key events, followed by a breakdown of what each event means. IF EXISTS (SELECT * FROM sys.server_event_sessions WHERE name = 'dop_xevents') DROP EVENT SESSION [dop_xevents] ON SERVER; GO CREATE EVENT SESSION [dop_xevents] ON SERVER ADD EVENT sqlserver.dop_feedback_analysis_stopped, ADD EVENT sqlserver.dop_feedback_eligible_query, ADD EVENT sqlserver.dop_feedback_provided, ADD EVENT sqlserver.dop_feedback_reassessment_failed, ADD EVENT sqlserver.dop_feedback_reverted, ADD EVENT sqlserver.dop_feedback_stabilized -- ADD EVENT sqlserver.dop_feedback_validation WITH ( MAX_MEMORY = 4096 KB, EVENT_RETENTION_MODE = ALLOW_SINGLE_EVENT_LOSS, MAX_DISPATCH_LATENCY = 30 SECONDS, MAX_EVENT_SIZE = 0 KB, MEMORY_PARTITION_MODE = NONE, TRACK_CAUSALITY = OFF, STARTUP_STATE = OFF ); ⚠️ Note: The extended event that has been commented out (dop_feedback_validation) is part of the debug channel. Enabling it may introduce additional overhead and should be used with caution in production environments. 📋 DOP Feedback Extended Events Reference Event Name Description dop_feedback_eligible_query Fired when a query plan becomes eligible for DOP feedback. Captures initial runtime stats like CPU time and adjusted elapsed time. dop_feedback_analysis_stopped Indicates that SQL Server has stopped analyzing a query for DOP feedback. Reasons include high variance in stats or the optimal DOP has already been achieved. dop_feedback_provided Fired when SQL Server provides a new DOP recommendation for a query. Includes baseline and feedback stats. dop_feedback_reassessment_failed Indicates that a previously persisted feedback DOP was reassessed and found to be invalid, restarting the feedback cycle. dop_feedback_reverted Fired when feedback is rolled back due to performance regression. Includes baseline and feedback stats. dop_feedback_stabilized Indicates that feedback has been validated and stabilized. After stabilization, additional adjustment to the feedback can be made when the system reassesses the feedback on a periodic basis. 🔍 Understanding the feedback_data JSON in DOP feedback In the "How it works" section of this article, we had provided a sample script that showed some of the data that can be persisted within the sys.query_store_plan_feedback catalog view. When DOP feedback stabilizes, SQL Server stores a JSON payload in the feedback_data column of that view, figuring out how to interpret that data can sometimes be challenging. From a structural perspective, the feedback_data field contains a JSON object with two main sections; LastGoodFeedback and BaselineStats. As an example { "LastGoodFeedback": { "dop": "2", "avg_cpu_time_ms": "12401", "avg_adj_elapsed_time_ms": "12056", "std_cpu_time_ms": "380", "std_adj_elapsed_time_ms": "342" }, "BaselineStats": { "dop": "4", "avg_cpu_time_ms": "17843", "avg_adj_elapsed_time_ms": "13468", "std_cpu_time_ms": "333", "std_adj_elapsed_time_ms": "328" } } Section Field Description LastGoodFeedback dop The DOP value that was validated and stabilized for future executions. avg_cpu_time_ms Average CPU time (in milliseconds) for executions using the feedback DOP. avg_adj_elapsed_time_ms Adjusted elapsed time (in milliseconds), excluding irrelevant waits. std_cpu_time_ms Standard deviation of CPU time across executions. std_adj_elapsed_time_ms Standard deviation of adjusted elapsed time. BaselineStats dop The original DOP used before feedback was applied. avg_cpu_time_ms Average CPU time for the baseline executions. avg_adj_elapsed_time_ms Adjusted elapsed time for the baseline executions. std_cpu_time_ms Standard deviation of CPU time for the baseline. std_adj_elapsed_time_ms Standard deviation of adjusted elapsed time for the baseline. One method that can be used to extract this data could be to utilize the JSON_VALUE function: SELECT qspf.plan_id, qs.query_id, qt.query_sql_text, qsp.query_plan_hash, qspf.feature_desc, -- LastGoodFeedback metrics JSON_VALUE(qspf.feedback_data, '$.LastGoodFeedback.dop') AS last_good_dop, JSON_VALUE(qspf.feedback_data, '$.LastGoodFeedback.avg_cpu_time_ms') AS last_good_avg_cpu_time_ms, JSON_VALUE(qspf.feedback_data, '$.LastGoodFeedback.avg_adj_elapsed_time_ms') AS last_good_avg_adj_elapsed_time_ms, JSON_VALUE(qspf.feedback_data, '$.LastGoodFeedback.std_cpu_time_ms') AS last_good_std_cpu_time_ms, JSON_VALUE(qspf.feedback_data, '$.LastGoodFeedback.std_adj_elapsed_time_ms') AS last_good_std_adj_elapsed_time_ms, -- BaselineStats metrics JSON_VALUE(qspf.feedback_data, '$.BaselineStats.dop') AS baseline_dop, JSON_VALUE(qspf.feedback_data, '$.BaselineStats.avg_cpu_time_ms') AS baseline_avg_cpu_time_ms, JSON_VALUE(qspf.feedback_data, '$.BaselineStats.avg_adj_elapsed_time_ms') AS baseline_avg_adj_elapsed_time_ms, JSON_VALUE(qspf.feedback_data, '$.BaselineStats.std_cpu_time_ms') AS baseline_std_cpu_time_ms, JSON_VALUE(qspf.feedback_data, '$.BaselineStats.std_adj_elapsed_time_ms') AS baseline_std_adj_elapsed_time_ms FROM sys.query_store_plan_feedback AS qspf JOIN sys.query_store_plan AS qsp ON qspf.plan_id = qsp.plan_id JOIN sys.query_store_query AS qs ON qsp.query_id = qs.query_id JOIN sys.query_store_query_text AS qt ON qs.query_text_id = qt.query_text_id WHERE qspf.feature_desc = 'DOP Feedback' AND ISJSON(qspf.feedback_data) = 1; 🧪 Why This Matters This JSON structure is critical for: Debugging regressions: You can compare baseline and feedback statistics to understand if a change in DOP helped or hurt a set of queries. Telemetry and tuning: Tools can be used to parse this JSON payload to surface insights in performance dashboards. Transparency: It provides folks that care about the database visibility into how SQL Server is adapting to their workload. 📚 Learn More Intelligent Query Processing: degree of parallelism feedback Degree of parallelism (DOP) feedback Intelligent query processing in SQL databases Microsoft SQL Server1.8KViews1like0CommentsAnnouncement: Upcoming Changes to SQL Server on Linux Virtual Machine (VM) Provisioning in Azure
We’re making an important update to how customers provision SQL Server on Linux virtual machines (VMs) in Azure. What’s Changing? Starting soon, Linux-based SQL Server Virtual Machine (VM) images published by Microsoft will be removed from the Azure Marketplace. As a result, these SQL Server on Linux images will no longer be visible in the Azure SQL hub during VM provisioning, nor accessible via CLI, Azure Portal, or PowerShell scripts. This change is part of our broader effort to simplify and modernise the provisioning experience for SQL Server Linux on Azure. Why Are We Making This Change? We’re transitioning away from image-based provisioning to a script-based model that offers greater flexibility, automation, and control. This fresh approach will allow customers to: Choose their preferred supported Linux distribution (RHEL, SLES or Ubuntu (Pro)) Select SQL Server version and edition Configure licensing options Customise deployment parameters through scripts and ability to add VM extensions. This shift ensures a more consistent and extensible experience across all supported platforms. When Will This Happen? The deprecation of Linux VM images will begin shortly and will be completed over the next couple of months. During this transition, customers may notice the SQL Server on Linux based Azure marketplace image listings may not be available. What Should You Do? For the Azure Virtual Machines deployed using the SQL on Linux Azure marketplace images in the past they'd continue to work, but if you’re planning to deploy new SQL Server on Linux based Azure Virtual Machines, please follow the below steps: Manual installation is recommended during this transition period. Start by creating a Linux Virtual Machine using the Azure Portal, CLI, or PowerShell. Once the VM is provisioned, follow the official SQL Server installation documentation to complete the setup. VM Creation Guidance: You can refer to this guide for step-by-step instructions on creating an Azure Linux-based virtual machine: https://learn.microsoft.com/en-us/azure/virtual-machines/linux/quick-create-portal Choosing a Linux Distribution: Feel free to select the distribution that best fits your requirements. For a list of endorsed Linux distributions on Azure, see: Linux distributions endorsed on Azure - Azure Virtual Machines | Microsoft Learn Please note, SQL Server is officially supported only on the following Linux distributions. Based on the distribution you choose, refer to the corresponding documentation for SQL Server installation guidance: Red Hat Enterprise Linux (RHEL) SUSE Linux Enterprise Server (SLES) Ubuntu For more details on supported distributions refer to: SQL Server 2025 - Supported Linux distributions SQL Server 2022 - Supported Linux distributions A new script-based provisioning experience is coming soon - stay tuned for announcements. We’ll continue to share updates through the Azure portal, documentation, and this blog.1.4KViews3likes0Comments