sql server on azure vms
104 TopicsDatabase Hub in Microsoft Fabric is generally available: your entire database estate in one place
As applications grow, so does the database estate behind them. Many organizations now run hundreds or thousands of databases across cloud, hybrid and multicloud environments. The signals are already there: inventory, health, performance, security, risk and optimization. The hard part is making sense of them, knowing what needs attention and deciding what to do next. Today, we're announcing the general availability of Database Hub in Microsoft Fabric. Database Hub gives you one place to see your whole estate, monitor it at scale and investigate where attention is needed. It covers Azure SQL, Azure Database for PostgreSQL, Azure Cosmos DB, SQL Server and SQL database in Fabric. Everything in this release is built around that idea: one estate, every signal, wherever you work. Get started for free If you're new to Microsoft Fabric, you don't need to set anything up first. Open Database Hub, and you're automatically given a free Fabric license and taken straight to your estate. You only need Fabric capacity to share dashboards, create custom alerts or use Copilot. Generally available today Area What you get Overview A "what needs attention" view across security, performance and optimization, with the top issues and recent signal changes across SQL, PostgreSQL and Cosmos DB Estate inventory A single inventory of supported Azure and Fabric databases, with their issues and suggestions Performance monitoring Near real-time CPU, memory and storage trends, aggregated across the estate and per resource, plus normalized RU and throttled requests for Cosmos DB Security posture Findings such as public network access, missing private endpoints, Microsoft Entra authentication, audit logging and customer-managed keys Investigation The ability to drill from any finding into the affected resource, real-time dashboards and the tools you already use New in general availability: Bulk performance monitoring enablement Monitoring a large estate shouldn't mean configuring it one database at a time. You can now turn on performance monitoring at scale from the Estate view. Select multiple resources and enable performance monitoring data collection for all of them in one step. Start from your inventory. Turn on monitoring in the same place you review your databases, without switching to another portal or tool. Cover more of your estate, faster. Extend monitoring coverage across hundreds of databases without repeating setup for each one. Go from setup to insight. Once data collection is on, monitored resources show up in Performance Monitoring and real-time dashboards. New in general availability: Optimization insights Optimization now sits alongside security and performance in Overview and Estate. It highlights: Resources with a migration assessment ready License model opportunities, such as pay-as-you-go SQL Server instances that aren't reporting usage Now generally available: Real-time dashboards Real-time dashboards for Microsoft SQL, Azure Database for PostgreSQL and Azure Cosmos DB move from preview to general availability. Now generally available: VS Code and SSMS entry points DBAs work in SSMS, and developers work in VS Code. You can now open Database Hub from SSMS and from the Microsoft and MSSQL extensions for VS Code. You land in the same estate view, with the resources you were working on. SSMS VS Code Now generally available: Database Hub CLI skill Ask about estate inventory, health, performance and security posture from GitHub Copilot CLI, VS Code Copilot, Claude Code or Cursor. Get the Database Hub CLI skill from skills-for-fabric, or install it with one command: skills-for-fabric --skill databasehub-cli Then try asking, "How is my database estate doing?" or "Which databases need attention this week?" In preview Public preview: Investigate your estate with Copilot Ask questions about your databases in natural language and get answers grounded in Database Hub data. Explore trends, understand issues and suggestions, and follow up on specific resources. Try prompts such as: "What changed in my databases?" "Which resource should I investigate next?" "Which security findings should I address first?" Public preview: Database Agents Database Agents act as an extra set of eyes on your estate. An agent watches the databases you choose and stays quiet while they're healthy. When something needs your judgment, it raises an issue with supporting evidence and a recommendation. You stay in control: the agent brings the issue to you, and you decide what happens next. Start with the overall finding or select Analyze on a single query to get recommendations for that query. From there, keep investigating with Copilot or go deeper in SSMS. Database Hub is where you see the bigger picture. The database agent alerts you before your users notice. Public preview: Alerts for Azure SQL Database Create alerts from built-in templates or performance charts for one database or many. Alerts can send a Microsoft Teams message or start a Power Automate flow. They're powered by Fabric Activator. Preview: Performance monitoring for SQL Server on Azure VMs Review SQL Server on Azure Virtual Machines in the same Performance Monitoring experience as the rest of your estate. What's next More skills are on the way, including SQL performance monitoring, Cosmos DB performance monitoring and migration skills. Get started today Open Database Hub: https://app.fabric.microsoft.com/workloads/fdh/databaseHub/overview Learn more: https://learn.microsoft.com/en-us/fabric/database/hub Install the Database Hub CLI skill: https://github.com/microsoft/skills-for-fabric/tree/main/skills/databasehub-cli Read more about Database Hub Database Hub in Fabric: Now in Public Preview -Turn Database Signals into Guided Action | Microsoft Community Hub Public Preview: Performance monitoring for Azure SQL in Database Hub | Microsoft Community Hub A Single View of Your PostgreSQL Estate: Database Hub in Public Preview | Microsoft Community Hub Make Estate yours: Focus on the databases and issues you own in Database Hub | Microsoft Community Hub Public Preview: Alerts for Azure SQL Database in Database Hub, powered by Fabric Activator | Microsoft Community Hub Managing security with Database Hub in Fabric: From signals to action | Microsoft Community Hub Database watcher for Azure SQL is retiring: simplify your monitoring with Database Hub | Microsoft Community Hub Ask your database estate a question: Copilot in Database Hub is now in public preview | Microsoft Community Hub439Views3likes2CommentsFuzzy string matching is now generally available across Microsoft SQL
Four native T-SQL functions that tell you how close two strings are, not just whether they’re equal. MICROSFT isn’t MICROSOFT. MARHTA isn’t MARTHA. INV-1O08 isn’t INV-1008. To an equality check, each pair is simply different. To your business, each is a near miss worth catching. Today, fuzzy string matching is generally available in Microsoft SQL. EDIT_DISTANCE tells you MICROSFT is one edit from MICROSOFT. JARO_WINKLER_SIMILARITY scores MARTHA and MARHTA at 96 out of 100. It all runs in T-SQL, right where your data lives, with no external libraries, models, or custom code. Available across all SKUs of: Azure SQL Database Azure SQL Managed Instance SQL database in Microsoft Fabric SQL Server 2025, starting with Cumulative Update 11 (CU11), and later cumulative updates What fuzzy string matching actually means Fuzzy string matching measures how closely two strings resemble each other without requiring an exact match. Think of it as comparing the written form of two values. An exact comparison asks, “Are these equal under our comparison rules?” Fuzzy matching adds, “If not, how close are they?” For an edit-distance algorithm, closeness can be measured by the operations needed to transform one string into the other: FORM swap O and R FROM One adjacent swap makes the strings identical. Insertion, deletion, substitution, and transposition are transformation operations, not assumptions about what originally caused the difference. This is useful for typo-tolerant lookup, candidate duplicate detection, master-data reconciliation, and reviewing text captured by optical character recognition (OCR). It is not the same as understanding meaning. car and automobile are related concepts but have very different character sequences. Nor does a high similarity score establish that two records represent the same person, product, or organization. Fuzzy matching provides evidence for a decision, not the decision itself. Meet the four functions The feature provides two algorithm families, each exposed through a distance function and a similarity function. Function Algorithm Return type How to read the result EDIT_DISTANCE Damerau-Levenshtein (Optimal String Alignment) int Edit count, or an over-budget marker when limited; lower means closer EDIT_DISTANCE_SIMILARITY Damerau-Levenshtein (Optimal String Alignment) int Normalized score from 0 to 100; higher means closer JARO_WINKLER_DISTANCE Jaro-Winkler float Distance from 0 to 1; lower means closer JARO_WINKLER_SIMILARITY Jaro-Winkler int Score from 0 to 100; higher means closer Their signatures are: EDIT_DISTANCE ( character_expression , character_expression [ , maximum_distance ] ) EDIT_DISTANCE_SIMILARITY ( character_expression , character_expression ) JARO_WINKLER_DISTANCE ( character_expression , character_expression ) JARO_WINKLER_SIMILARITY ( character_expression , character_expression ) The inputs can be constants, variables, or columns. Use bounded character types such as varchar(n) or nvarchar(n); varchar(max) and nvarchar(max) are not supported. If an input is NULL, the result is NULL. A first comparison Each example is self-contained, creates no permanent objects, and applies a supported collation (Latin1_General_100_CI_AS_SC) with COLLATE, so you can run it without changing your database collation. ;WITH Pair AS ( SELECT N'Colour' COLLATE Latin1_General_100_CI_AS_SC AS SourceText, N'Color' COLLATE Latin1_General_100_CI_AS_SC AS TargetText ) SELECT SourceText, TargetText, EDIT_DISTANCE(SourceText, TargetText) AS Edits, EDIT_DISTANCE_SIMILARITY(SourceText, TargetText) AS EditScore, JARO_WINKLER_DISTANCE(SourceText, TargetText) AS JwDistance, JARO_WINKLER_SIMILARITY(SourceText, TargetText) AS JwScore FROM Pair; The query returns: Edits EditScore JwDistance, approximately JwScore 1 83 0.033333 97 One deletion removes the u. Both algorithm families recognize a close match, but they express closeness differently. A Jaro-Winkler distance of approximately 0.033333 is not a fractional number of edits. Damerau-Levenshtein (Optimal String Alignment): how many edits? EDIT_DISTANCE and EDIT_DISTANCE_SIMILARITY implement Damerau-Levenshtein (Optimal String Alignment, or OSA), the restricted Damerau-Levenshtein variant. Each permitted operation has a cost of one: Operation Example What changes Insertion CT to CAT Insert A Deletion CART to CAT Delete R Substitution CAT to CUT Replace A with U Adjacent transposition FORM to FROM Swap O and R The distance is the minimum cost of a transformation allowed by this algorithm, so each pair above has a distance of 1. Why “Optimal String Alignment” matters The qualification is important: this is not unrestricted Damerau-Levenshtein. In the Optimal String Alignment variant, the same substring cannot be edited more than once along the transformation. For example, unrestricted Damerau-Levenshtein can transform CA into ABC in two operations: CA -> AC -> ABC swap insert B That sequence re-edits the transposed region. The restricted Damerau-Levenshtein (Optimal String Alignment) algorithm does not allow that transformation path, and the distance is 3, not 2. SELECT EDIT_DISTANCE( N'CA' COLLATE Latin1_General_100_CI_AS_SC, N'ABC' COLLATE Latin1_General_100_CI_AS_SC ) AS Edits; -- Result: 3 For everyday typos this rarely matters, but it does when you compare results with another library or migrate an existing matching implementation. From edit count to similarity An absolute edit count does not tell the whole story. Removing one character from a four-character value changes a larger proportion of the string than removing one character from a six-character value. EDIT_DISTANCE_SIMILARITY normalizes edit distance using the longer input: (1 - (edit_distance / greatest(len(string1), len(string2)))) * 100 For example: CART and CAT: (1 - 1/4) * 100 = 75. Colour and Color: (1 - 1/6) * 100 is approximately 83.33; the function returns the integer 83. A score of 83 measures resemblance; it is not an 83% probability that the values refer to the same thing. Jaro-Winkler: a different way to rank resemblance Sometimes the question is not “How many edits are allowed?” but “Which names are the most plausible matches?” Jaro-Winkler considers matching characters within a positional matching window: a character must occur close enough to its position in the other string to count as a match. It also considers the relative order of those matches, then gives additional weight to a shared prefix. It does not calculate the minimum number of operations needed to transform one string into another. Consider MARTHA and MARHTA. They share the same characters, with T and H out of order, and both start with MAR. ;WITH Names AS ( SELECT NameA COLLATE Latin1_General_100_CI_AS_SC AS NameA, NameB COLLATE Latin1_General_100_CI_AS_SC AS NameB FROM (VALUES (N'MARTHA', N'MARHTA'), (N'CONTOSO HEALTH', N'CONTOSO RETAIL') ) AS n(NameA, NameB) ) SELECT NameA, NameB, EDIT_DISTANCE(NameA, NameB) AS Edits, JARO_WINKLER_DISTANCE(NameA, NameB) AS JwDistance, JARO_WINKLER_SIMILARITY(NameA, NameB) AS JwScore FROM Names ORDER BY JwScore DESC, NameA, NameB; NameA NameB Edits JwDistance, approximately JwScore MARTHA MARHTA 1 0.038889 96 CONTOSO HEALTH CONTOSO RETAIL 5 0.082143 92 Jaro-Winkler is worth evaluating for person and organization names when shared beginnings are meaningful and usually entered correctly. But prefixes can mislead: CONTOSO HEALTH and CONTOSO RETAIL score 92 despite five edits and may be different organizations. The prefix length and scaling factor are fixed; the functions don’t expose parameters for them. Choose Damerau-Levenshtein (OSA) for an explicit edit budget. Evaluate Jaro-Winkler for ranking character-based resemblance when prefix preference fits your data. Use maximum_distance when you only need a threshold Suppose your application accepts candidates within two edits. An exact distance of eight is unnecessary if all you need to know is that the candidate exceeds the budget. The optional maximum_distance argument lets EDIT_DISTANCE stop early once the distance exceeds the threshold. Within the threshold, it returns the actual distance; beyond it, it returns maximum_distance + 1. ;WITH Pairs AS ( SELECT SourceText COLLATE Latin1_General_100_CI_AS_SC AS SourceText, TargetText COLLATE Latin1_General_100_CI_AS_SC AS TargetText FROM (VALUES (N'CART', N'CAT'), (N'FORM', N'FROM'), (N'Chocolate', N'Sweets'), (N'CAT', N'CAT') ) AS p(SourceText, TargetText) ) SELECT SourceText, TargetText, EDIT_DISTANCE(SourceText, TargetText) AS ActualDistance, EDIT_DISTANCE(SourceText, TargetText, 2) AS BoundedDistance FROM Pairs ORDER BY SourceText; Pair ActualDistance BoundedDistance CART / CAT 1 1 CAT / CAT 0 0 Chocolate / Sweets 8 3 FORM / FROM 1 1 The value 3 for Chocolate / Sweets means “over the budget of two”, not “exactly three edits.” Use the bounded form to accept or reject candidates, not to rank how far apart rejected values are. Put it to work: typo-tolerant lookup Let’s return to MICROSFT. We want a short list of catalog values no more than one edit away. DECLARE @query nvarchar(40) = N'MICROSFT'; ;WITH Catalog AS ( SELECT Name COLLATE Latin1_General_100_CI_AS_SC AS Name FROM (VALUES (N'MICROSFT'), (N'MICROSOFT'), (N'CONTOSO') ) AS c(Name) ) SELECT Name, EDIT_DISTANCE( Name, @query COLLATE Latin1_General_100_CI_AS_SC ) AS Distance FROM Catalog WHERE EDIT_DISTANCE( Name, @query COLLATE Latin1_General_100_CI_AS_SC, 1 ) <= 1 ORDER BY Distance, Name; The result contains MICROSFT with distance 0, followed by MICROSOFT with distance 1; CONTOSO is outside the budget. The misspelled catalog entry is included deliberately: exact matches rank first, and the application can offer the alternatives instead of silently rewriting the input. The bounded call filters, while the unbounded call supplies the ranking value. Find candidate duplicates without comparing everyone to everyone Customer deduplication needs both textual resemblance and business context. Comparing every customer with every other customer produces a number of pairs that grows approximately with the square of the row count. A practical first step is blocking: group records using a trusted attribute, then compare names within those groups. ;WITH Customer AS ( SELECT CustomerId, Name COLLATE Latin1_General_100_CI_AS_SC AS Name, PostalCode FROM (VALUES (1, N'MARTHA', N'98052'), (2, N'MARHTA', N'98052'), (3, N'MARTHA', N'10001'), (4, N'ROBERT', N'98052') ) AS c(CustomerId, Name, PostalCode) ) SELECT a.CustomerId AS CustomerA, b.CustomerId AS CustomerB, a.Name AS NameA, b.Name AS NameB, JARO_WINKLER_SIMILARITY(a.Name, b.Name) AS Score FROM Customer AS a JOIN Customer AS b ON a.PostalCode = b.PostalCode AND a.CustomerId < b.CustomerId WHERE JARO_WINKLER_SIMILARITY(a.Name, b.Name) >= 92 ORDER BY Score DESC, CustomerA, CustomerB; Three details make the query useful: Postal-code equality creates the shortlist. Only customers within the same postal code are compared. a.CustomerId < b.CustomerId emits each pair once. It excludes self-comparisons and reversed duplicates such as (2,1) when (1,2) already exists. The similarity filter flags plausible names. MARTHA and MARHTA pass the illustrative cutoff; pairs involving ROBERT do not. The query returns one pair: customer 1 and customer 2, with a similarity score of 96. The other MARTHA, in postal code 10001, is not compared with the 98052 group. That illustrates the trade-off: blocking reduces comparisons but can miss true duplicates when the blocking attribute differs or is wrong. The cutoff of 92 is only illustrative: CONTOSO HEALTH and CONTOSO RETAIL also scored 92 earlier. Confirm candidates with independent evidence, such as a verified email or phone number. Reconcile OCR mistakes within the right business context An invoice reader captures INV-1O08, confusing the letter O with the digit 0. Comparing against every invoice would be risky. Start with the vendor, then allow one character edit: ;WITH Captured AS ( SELECT 10 AS VendorId, N'INV-1O08' COLLATE Latin1_General_100_CI_AS_SC AS Invoice ), ReferenceInvoice AS ( SELECT VendorId, Invoice COLLATE Latin1_General_100_CI_AS_SC AS Invoice FROM (VALUES (10, N'INV-1008'), (10, N'INV-1208'), (20, N'INV-1008') ) AS r(VendorId, Invoice) ) SELECT c.VendorId, c.Invoice AS CapturedInvoice, r.Invoice AS CandidateInvoice, EDIT_DISTANCE(c.Invoice, r.Invoice) AS Edits FROM Captured AS c JOIN ReferenceInvoice AS r ON c.VendorId = r.VendorId WHERE EDIT_DISTANCE(c.Invoice, r.Invoice, 1) <= 1 ORDER BY c.VendorId, r.Invoice; The query returns two candidates for vendor 10: Candidate invoice Transformation Edits INV-1008 Replace O with 0 1 INV-1208 Replace O with 2 1 Vendor 20’s invoice is excluded by the vendor condition. Within vendor 10, both substitutions cost one edit; the function doesn’t know that OCR often confuses O and 0. Attributes such as amount and date must decide which invoice was intended. Useful with AI, without being an AI model These functions require no embeddings, model training, or inference endpoint. They also fit naturally into AI-assisted workflows. For example, a language model might extract CONTOS from a document. The application can use fuzzy matching to shortlist names in its organization directory. The same SQL works if the input came from a person or a batch import instead. DECLARE @entity nvarchar(100) = N'CONTOS'; ;WITH Organization AS ( SELECT OrganizationId, Name COLLATE Latin1_General_100_CI_AS_SC AS Name, CountryCode FROM (VALUES (1, N'CONTOSO', N'US'), (2, N'CONTOSO HEALTH', N'US'), (3, N'CONTOSO RETAIL', N'US'), (4, N'CONTOSO', N'GB') ) AS o(OrganizationId, Name, CountryCode) ) SELECT TOP (5) OrganizationId, Name, JARO_WINKLER_SIMILARITY( Name, @entity COLLATE Latin1_General_100_CI_AS_SC ) AS Score FROM Organization WHERE CountryCode = N'US' AND JARO_WINKLER_SIMILARITY( Name, @entity COLLATE Latin1_General_100_CI_AS_SC ) >= 80 ORDER BY Score DESC, OrganizationId; The query returns three US candidates: CONTOSO with a score of 97, followed by CONTOSO HEALTH and CONTOSO RETAIL at 89 each. The GB record is excluded. Change @entity to N'ZZZZ' and the query returns no rows; the application should treat that as “no match” rather than force a best guess. Fuzzy matching won’t expand an acronym into a company name or resolve related meanings. Use an alias table or a semantic approach for those tasks. Where this fits in the SQL matching toolbox Fuzzy string matching extends existing capabilities; it does not replace them. Question Appropriate tool Example Are these values equal under the intended comparison rules? Equality, joins, and an appropriate collation Match a trusted customer key Does the text contain a known pattern or substring? LIKE, CHARINDEX, PATINDEX Find a known prefix Does the text follow a structured pattern? REGEXP_* functions Validate or extract a formatted value Do these values have similar phonetic representations? SOUNDEX, DIFFERENCE Coarse screening of English-oriented names How far apart are these values in character edits? EDIT_DISTANCE, EDIT_DISTANCE_SIMILARITY Measure edit count or normalized edit similarity How similar are character alignment and prefixes? JARO_WINKLER_DISTANCE, JARO_WINKLER_SIMILARITY Rank plausible name matches Which documents contain relevant words or phrases? Full-text search Linguistic document retrieval Which representations are close in embedding space? Vector similarity/search Semantic retrieval for AI applications For example, SOUNDEX('Robert') and SOUNDEX('Rupert') both return R163: a phonetic signal, which is different from the character-similarity scores announced here. Good to know Collation: The functions support Windows collations and binary (BIN, BIN2) collations. Non-binary SQL_* collations, such as the common default SQL_Latin1_General_CP1_CI_AS, are not supported. Apply COLLATE to the inputs, as the examples do; you don’t need to change the database collation. Scale: Narrow the candidate set with trusted business keys, such as region, vendor, or category, before scoring. Scores: Test thresholds on your own labeled examples. A score is evidence of a possible match, not proof. Get started Azure SQL Database and SQL database in Microsoft Fabric: The functions are available now. Azure SQL Managed Instance: Use the SQL Server 2025 or Always-up-to-date update policy. SQL Server 2025: Install CU11 or later. If you tried the functions in preview, you no longer need the PREVIEW_FEATURES database scoped configuration to use them. Pick a column you already struggle to match, try the examples above on your own data, and see what turns up. Whether you’re cleaning customer records, forgiving a typo in a search box, or grounding an AI-extracted name, fuzzy string matching is now a native part of T-SQL, ready wherever your data lives. We’d love to hear what you build with it. Learn more Fuzzy string matching overview EDIT_DISTANCE reference EDIT_DISTANCE_SIMILARITY reference JARO_WINKLER_DISTANCE reference JARO_WINKLER_SIMILARITY reference98Views0likes0CommentsAsk your database estate a question: Copilot in Database Hub is now in public preview
Most database teams already collect a lot of monitoring data. What they don't have enough of is time to work out what it means. When something looks wrong, the first job is usually to open several portals, find the affected resources, and work out what changed. Database Hub in Microsoft Fabric already brings your Azure, Fabric, on-premises and multicloud databases into one view. Today we're making that view easier to use: Copilot in Database Hub is now in public preview. You can ask questions about your estate in plain language and get answers grounded in what Database Hub already knows about your databases. What you can do with Copilot in Database Hub Area What Copilot helps with Try asking Prioritize Rank the issues across your estate and show how many resources each one affects "What should I fix first?" Performance Find resources near storage, memory or compute capacity, and explain what changed "Are there any performance issues I should know about?" Troubleshooting Investigate slowdowns and blocking that affect your applications "Are there any blocked queries in my database causing delays in app response?" Security Find risky configurations, such as public network access or endpoints without private access "What are the biggest security risks in my environment?" Migration readiness Bring SQL Server assessment results into one answer "Analyze migration readiness across my SQL Server estate" Ask Copilot from wherever you're working Copilot is on every main page in Database Hub. Select Ask Copilot in the top right of the page you're on: Overview: you're looking at the issue counts and want to know what to fix first. Estate: you're going through resources and their issues and want to know which of this matter. Performance monitoring: you're watching metrics for Microsoft SQL, PostgreSQL or Cosmos DB and want to know why something changed. The Copilot pane opens beside the page, so you keep your place while you ask. Database Hub Overview page showing security, performance and optimization issues, with the Ask Copilot selected Ask Copilot button on the Estate and Performance monitoring pages in Database Hub. Get started with suggested questions Copilot opens with suggested questions grouped by the three things teams ask about most: Check performance: How are my databases performing? or Are there any performance issues I should know about? Review security: How secure are my databases?, What should I fix first to improve security? or What are the biggest security risks in my environment? Assess migration readiness: Show my existing SQL Server migration assessment results, or Analyze migration readiness across my SQL Server estate. Ask, follow up, then go deeper Here's a typical investigation: Ask a broad question. "What should I fix first to improve security?" Read the ranked summary. Copilot lists the top findings across your estate, such as endpoints without private access or public network access left on. It shows how many resources each one affects, so the biggest risks come first. Narrow it down. "Which of those are production databases?" or "Show me the resources with public network access enabled." Open the evidence. Go from Copilot's answer to the affected resources in Estate. Each resource lists its issues, such as Public network access is enabled or Memory is near capacity. Then act with the tools and processes you already use, including opening the resource in the Azure portal, SSMS or VS Code. Troubleshoot what's slowing your apps down When users report that an app is slow, the hard part is finding which database is responsible and why. Open Copilot from Performance monitoring and start with the symptom: "Are there any blocked queries in my database causing delays in app response?" "Why did CPU spike on this database in the last hour?" "Which databases are close to their storage, memory or compute limits?" "What changed on this database since yesterday?" Copilot summarizes what it finds and points you to the affected resource. Switch to the Performance monitoring charts to see the trend for yourself before you change anything. Plan your SQL Server migrations For SQL Server teams planning a move, "Analyze migration readiness across my SQL Server estate" collects assessment results into one answer, instead of you checking one server at a time. Follow up with "Which servers have blockers?" to see where to start. How Copilot works Copilot in Database Hub answers from the information Database Hub already has about your estate: your resource inventory, the security, performance and optimization issues it detects, and the performance telemetry it collects. It uses that context to rank, summarize and explain, then links you back to the resource or chart so you can check the evidence. Copilot sees only the resources your own Azure and Fabric permissions allow. It doesn't give you access to anything you couldn't already see. Tips for better answers Start broad, then narrow. Ask "What should I fix first?" and then filter by environment, service or issue type. Name what you care about. A resource name, a time window or a symptom gives you a more specific answer than a general question does. Ask from the right page. Ask about trends from Performance monitoring and about resources and issues from Estate. Check before you act. Use the linked resources and charts to confirm what Copilot found. Built with clear boundaries Grounded in Database Hub. Copilot answers from the information available in Database Hub. Your permissions, nothing more. Copilot works within your existing Azure and Fabric permissions. You stay in control. Copilot helps you understand and prioritize. It doesn't change your databases. Responsible AI. Copilot is powered by AI, so mistakes are possible. Review its answers before you act on them in production. Get started Opt in: Turn on Copilot for your organization. Copilot in Database Hub is an opt-in experience. Nothing is turned on for your users until a Fabric administrator chooses to enable it. In the Fabric admin portal, under Tenant settings > Copilot and AI, enable these settings, and make sure the enabled scope includes the users who need Copilot: Users can use Copilot, AI Agents and other AI experiences powered by Azure OpenAI Users can use Copilot, AI Agents and other AI experiences powered by OpenAI as a Microsoft Subprocessor Data sent to OpenAI as a Microsoft Subprocessor can be processed outside your capacity's geographic region, compliance boundary, or national cloud instance You can turn each setting on for the whole organization or only for specific security groups, so you can start with a pilot group. Important: Review the OpenAI as a Microsoft Subprocessor settings with your security and compliance team before you enable them. See OpenAI as a subprocessor in Microsoft Fabric for data processing commitments and current limitations. Open Database Hub in Microsoft Fabric. Select Ask Copilot on Overview, Estate or Performance monitoring, and start with a suggested question. Frequently asked questions Is Copilot on by default? No. Copilot in Database Hub is opt-in. A Fabric administrator decides whether to enable it and for whom. Which databases does Copilot cover? The same resources Database Hub shows you: Azure SQL, Fabric, on-premises and multicloud databases connected to your hub, within your permissions. Does Copilot need a specific capacity, and how is it billed? Copilot in Fabric needs a paid Fabric capacity (F2 or higher) or a Power BI Premium capacity (P1 or higher). It doesn't need a separate per-user license. Copilot usage is measured in tokens and consumes your Fabric capacity units (CUs). You can track it in the Fabric Capacity Metrics app under the operation name Copilot in Fabric. For rates and examples, see Copilot consumption, usage, and billing in Fabric. To bill all Copilot usage for a group of users to one capacity, see Fabric Copilot capacity. Does Copilot change my databases? No. Copilot helps you understand and prioritize. You make changes with your existing tools and processes. Is Copilot available in government or sovereign clouds? Not currently. OpenAI-operated models aren't available in government clouds (GCC, GCC High, DoD) or sovereign clouds. Why don't I see Ask Copilot? Check with your Fabric administrator that the tenant settings above are enabled and that their scope includes you. Learn more Database Hub overview Overview of Copilot in Fabric Enable and configure Copilot in Microsoft Fabric Copilot and Agent tenant settings OpenAI as a subprocessor in Microsoft Fabric Copilot consumption, usage, and billing in Fabric Fabric Copilot capacity What's next This preview is the start. We'll keep growing what Copilot can answer, based on what you ask it. Tell us what you ask first, and what you wish it could answer: select Feedback in Database Hub.309Views1like0Comments
Public Preview: Performance monitoring for Azure SQL in Database Hub
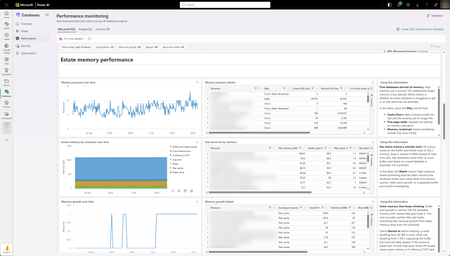
We're excited to announce the public preview of performance monitoring for Azure SQL in Database Hub in Fabric. Performance monitoring brings the health and performance of your SQL estate into Database Hub. You see every supported database in one place and quickly spot the ones that need attention. It works across: Azure SQL Database Azure SQL Managed Instance SQL Server on Azure Virtual Machines SQL Server enabled by Azure Arc Microsoft collects performance-related telemetry, runs the pipeline, and stores the data for you. There's nothing you need to deploy and nothing to operate. Turn it on, and your SQL resources show up on the Performance page in Database Hub, which is free. This post is a deep dive on the performance part of Database Hub. For the full tour, including the Overview, Estate, and Security pages, read Database Hub in Fabric: Now in Public Preview. Get started in three steps Open Database Hub in Fabric. During the preview, a Fabric administrator needs to turn on the Database Hub tenant setting. See the prerequisites. Turn on performance monitoring for your SQL resources. See Enable performance monitoring for Microsoft SQL. Go to the Performance page to see which databases need your attention. See your entire database estate in Database Hub Performance monitoring powers the Performance page in Database Hub. Database Hub is built for when you need to look across all your databases, not just one at a time. It brings your database estate across Azure, on-premises, and other clouds into one place, including: Azure SQL and SQL Server enabled by Azure Arc Azure Database for PostgreSQL Azure Cosmos DB The Performance page comes with prebuilt dashboards, so you can see performance at a glance without building anything yourself. The dashboards are designed to quickly answer two questions: Are my databases healthy? Which ones need my attention? From there, you can drill into resource usage, waits, and session activity to understand what's driving a change in performance. With Database Hub, you can: Get estate-wide visibility into health and performance across database types Investigate the root cause of performance issues across many databases Use AI-assisted analysis to find and explain issues faster To learn more, see What is Database Hub in Fabric? Why we built this Monitoring SQL performance at scale often meant building and running your own monitoring stack. Before you could effectively answer, "Which of my databases need attention right now?" you typically had to: Deploy and configure a collection resource, such as a watcher or an agent Build a telemetry pipeline to move the data Provision a data store, and then pay for it, secure it, and keep it running Build dashboards on top of all of it Repeat for every new server, database, or region That's a lot of work before you see your first chart. And every step is another thing that can break, drift, or quietly stop collecting data. Customers are also turning to AI to make sense of their database estate. They want an AI agent that can spot a performance problem, explain what's causing it, and recommend a fix. But an AI agent is only as good as the data it can reach. It operates best with one consistent source of performance data across every database, not a patchwork of tools and data stores. We heard this feedback loud and clear from customers. You told us you love having at-scale dashboards and ownership of your performance data. You also told us that setting up a telemetry stack was time-consuming, scale limits got in the way, and running the data store added operational burden and cost overhead. One customer put it simply: they wanted to spend less time managing their telemetry infrastructure and more time managing and improving their databases. Performance monitoring keeps the parts you valued and removes the infrastructure you had to manage. That's why it feeds Database Hub directly. You get one place to see your whole estate, and your AI agents get one consistent source of performance data. No infrastructure to manage (or pay for) With performance monitoring, there's no monitoring infrastructure for you to deploy, size, or run. It's all managed by Microsoft, with no scale limits on how many targets you can monitor. Telemetry is collected close to the database engine and sent to a Microsoft-managed telemetry pipeline and data store. Access to that data is governed by Azure role-based access control (RBAC), so people only see telemetry for the resources they already have access to. Consistent telemetry across your SQL estate Performance monitoring collects the same core set of performance data across every supported SQL deployment, whether it runs in Azure, on-premises, or in another cloud. That means one mental model and one set of dashboards in Database Hub, instead of a different tool for every flavor of SQL. The preview collects performance-related telemetry, including: CPU and memory utilization Wait statistics Active sessions Storage I/O and database storage utilization Performance counters Client connections Database properties Availability group, replica, and database replica health Go beyond Database Hub with KQL Database Hub covers the most common performance questions. When you need a view that Database Hub doesn't show, you can query the same telemetry directly with Kusto Query Language (KQL). The telemetry is available through a Microsoft-managed, RBAC-governed endpoint, so you don't need to create or pay for your own Azure Data Explorer cluster. Use it to: Build your own Real-Time Dashboards and reports Connect tools you already use, such as Grafana or Power BI Give an AI agent access to investigate performance across your estate To get started, see Query performance monitoring telemetry. It includes the schema, connection steps, and ready-to-run starter queries. Turn on performance monitoring How you turn on performance monitoring depends on the resource type. For all of the steps in one place, see Enable performance monitoring for Microsoft SQL. Resource type How monitoring is enabled in preview Step-by-step guidance Azure SQL Database Add an extended property to each database you want to monitor. You can also select Enable Performance Monitoring in Database Hub. Azure SQL Database Azure SQL Managed Instance Add an extended property to the master database Azure SQL Managed Instance SQL Server on Azure VMs Turn on a feature flag in the SQL IaaS Agent extension. SQL Server on Azure VMs SQL Server enabled by Azure Arc On by default once the server is connected to Azure Arc. SQL Server enabled by Azure Arc To view performance monitoring data, you need: The Reader role, or a role with higher privileges, on each subscription that contains the resources you want to view. The Microsoft.AzureArcData resource provider registered on each subscription. For steps, see Register the Azure resource provider. Availability Performance monitoring is available in public preview in select Azure regions. For the current list of supported regions, see Regional availability and data handling. Learn more Database Hub in Fabric: Now in Public Preview What is Database Hub in Fabric? Enable performance monitoring for Microsoft SQL Query performance monitoring telemetry Supplemental Terms of Use for Microsoft Azure Previews4.4KViews3likes5Comments
Make Estate yours: Focus on the databases and issues you own in Database Hub
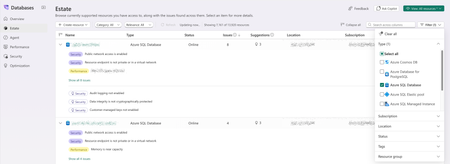
Database Hub in Microsoft Fabric is now in public preview. Estate experience brings every supported database you can access into one inventory, with the issues and suggestions found across them. In a large organization, that can mean thousands of resources. But most people own only part of the estate: a set of production databases, a few subscriptions, one resource group. This post shows how to shape Estate around your part, save it as a custom view, and use it to triage and bring in help. The examples use Azure SQL Database; the same steps work for PostgreSQL and Azure Cosmos DB. Which resources are mine? While in Estate view select Filter to narrow the list by Type, Subscription, Location, Status, Tags, or Resource group. The grid and the resource count update as you select values; Filter (1) shows how many dimensions are active, and Clear all resets them. Looking for one resource? Search across columns matches names, locations, subscriptions, and more. Which issues should I focus on? Each row shows its Issues and Suggestions counts and opens expanded, so findings are readable at a glance: issues with a filled Security or Performance tag, suggestions marked with a lightbulb. Open Category and select Security, Performance, Optimization, or a combination. Use Relevance to keep only resources with Issues or Suggestions. The grid is sorted by issue count, so the resources that need the most attention come first. How do I get back here tomorrow? Once Estate shows what you want, save it. An asterisk after the view name (View: All resources *) means your filters have unsaved changes. Select View > Save. Choose Save as new custom view and give it a name that describes the scope, such as sqlDB-sec-perf-issues. Select Apply. The view now appears under Custom views in the View menu. It saves filters, not results, so you always see the current state of those resources. What's wrong, and what should I do about it? Select an issue to open its detail page. Here, the top database reports Public network access is enabled. The Summary explains why it matters: public reachability increases exposure to credential attacks, scanning, and firewall mistakes. The Recommended action gives the fix and its precondition: Disable public network access after confirming that all clients can connect through approved private connectivity. Resolve in Azure portal opens the resource. Database Hub doesn't change the resource for you; you make the change in the tool that owns it, under your existing permissions. Back returns you to Estate with your view intact. Who can help me fix it? That precondition is often the hard part: confirming every client can connect privately may take your networking or application team. Bring them into the same view. Select View > Share, then Copy link. The link carries your current filters, so a colleague starts from the same scope. Each person still sees only the resources they already have access to; sharing never grants access. Need the list for a change ticket? Select Export view (as .csv). CSV files don't carry sensitivity labels, so handle the file according to your organization's data policies. What needs attention in my part of the estate? Your view isn't limited to Estate. Open Overview, select the same view from the View menu, and every card and chart rescopes to it: the Estate issues summary, the Security, Performance, and Optimization cards with their top issues, and the performance trends. Overview now summarizes your backlog instead of the whole estate. Views are managed in Estate; Manage views (Estate) takes you there. o the resources you own. More in Estate Look up a resource without leaving the list Select a resource name to open its details next to the list: subscription, resource group, and logical server (each linking to the Azure portal), status, location, pricing tier, max storage, and tags. Connection strings for ADO.NET, JDBC, ODBC, PHP, and Go use Microsoft Entra authentication, and Open in Azure portal, Open in VS Code, and Open in SSMS are at the top. The … menu on each row adds quick actions Copy connection string, Open in editor, Enable performance monitoring, Create monitor from template and Set alert from template. Create a database where you work Create resource starts a new database from Estate, grouped by engine: SQL database in Fabric, Azure SQL Database, SQL Server instance, Azure Database for PostgreSQL, and Azure Cosmos DB for NoSQL. Get started Open Estate, filter to the resources you own, focus on the categories you triage, and save the result as a view. Then select it on Overview and start with what needs attention. Database Hub is in public preview; capabilities vary by service and preview configuration. See the Database Hub documentation for supported services and setup, and use Feedback in Database Hub to tell us what you'd like next.330Views1like1CommentAzure Data Studio Retirement
We’re announcing the upcoming retirement of Azure Data Studio (ADS) on February 6, 2025, as we focus on delivering a modern, streamlined SQL development experience. ADS will remain supported until February 28, 2026, giving developers ample time to transition. This decision aligns with our commitment to simplifying SQL development by consolidating efforts on Visual Studio Code (VS Code) with the MSSQL extension, a powerful and versatile tool designed for modern developers. Why Retire Azure Data Studio? Azure Data Studio has been an essential tool for SQL developers, but evolving developer needs and the rise of more versatile platforms like VS Code have made it the right time to transition. Here’s why: Focus on innovation VS Code, widely adopted across the developer community, provides a robust platform for delivering advanced features like cutting-edge schema management and improved query execution. Streamlined tools Consolidating SQL development on VS Code eliminates duplication, reduces engineering maintenance overhead, and accelerates feature delivery, ensuring developers have access to the latest innovations. Why Transition to Visual Studio Code? VS Code is the #1 developer tool, trusted by millions worldwide. It is a modern, versatile platform that meets the evolving demands of SQL and application developers. By transitioning, you gain access to cutting-edge tools, seamless workflows, and an expansive ecosystem designed to enhance productivity and innovation. We’re committed to meeting developers where they are, providing a modern SQL development experience within VS Code. Here’s how: Modern development environment VS Code is a lightweight, extensible, and community-supported code editor trusted by millions of developers. It provides: Regular updates. An active extension marketplace. A seamless cross-platform experience for Windows, macOS, and Linux. Comprehensive SQL features With the MSSQL extension in VS Code, you can: Execute queries faster with filtering, sorting, and export options for JSON, Excel, and CSV. Manage schemas visually with Table Designer, Object Explorer, and support for keys, indexes, and constraints. Connect to SQL Server, Azure SQL (all offerings), and SQL database in Fabric using an improved Connection Dialog. Streamline development with scripting, object modifications, and a unified SQL experience. Optimize performance with an enhanced Query Results Pane and execution plans. Integrate with DevOps and CI/CD pipelines using SQL Database Projects. Stay tuned for upcoming features—we’re continuously building new experiences based on feedback from the community. Make sure to follow the MSSQL repository on GitHub to stay updated and contribute to the project! Streamlined workflow VS Code supports cloud-native development, real-time collaboration, and thousands of extensions to enhance your workflows. Transitioning to Visual Studio Code: What You Need to Know We understand that transitioning tools can raise concerns, but moving from Azure Data Studio (ADS) to Visual Studio Code (VS Code) with the MSSQL extension is designed to be straightforward and hassle-free. Here’s why you can feel confident about this transition: No Loss of Functionality If you use ADS to connect to Azure SQL databases, SQL Server, or SQL database in Fabric, you’ll find that the MSSQL extension supports these scenarios seamlessly. Your database projects, queries, and scripts created in ADS are fully compatible with VS Code and can be opened without additional migration steps. Familiar features, enhanced experience VS Code provides advanced tools like improved query execution, modern schema management, and CI/CD integration. Additionally, alternative tools and extensions are available to replace ADS capabilities like SQL Server Agent and Schema Compare. Cross-Platform and extensible Like ADS, VS Code runs on Windows, macOS, and Linux, ensuring a consistent experience across operating systems. Its extensibility allows you to adapt it to your workflow with thousands of extensions. If you have further questions or need detailed guidance, visit the ADS Retirement page. The page includes step-by-step instructions, recommended alternatives, and additional resources. Continued Support With the Azure Data Studio retirement, we’re committed to supporting you during this transition: Documentation: Find detailed guides, tutorials, and FAQs on the ADS Retirement page. Community Support: Engage with the active Visual Studio Code community for tips and solutions. You can also explore forums like Stack Overflow. GitHub Issues: If you encounter any issues, submit a request or report bugs on the MSSQL extension’s GitHub repository. Microsoft Support: For critical issues, reach out to Microsoft Support directly through your account. Transitioning to VS Code opens the door to a more modern and versatile SQL development experience. We encourage you to explore the new possibilities and start your journey today! Conclusion Azure Data Studio has served the SQL community well,but the Azure Data Studio retirement marks an opportunity to embrace the modern capabilities of Visual Studio Code. Transitioning now ensures you’re equipped with cutting-edge tools and a future-ready platform to enhance your SQL development experience. For a detailed guide on ADS retirement , visit aka.ms/ads-retirement. To get started with the MSSQL extension, check out the official documentation. We’re excited to see what you build with VS Code!36KViews4likes31CommentsGenerally Available: SQL Migration to SQL Server on Azure Virtual Machines in Azure Architecture
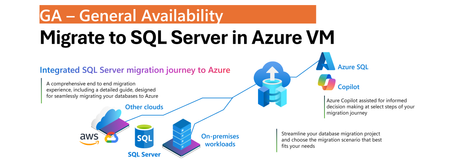
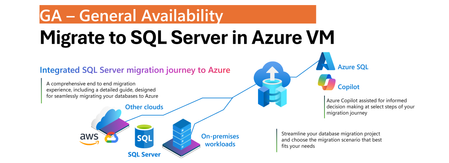
One Migration Experience, More Flexibility Modernizing SQL Server estates is rarely a single-step journey. Organizations often operate across on-premises, hybrid, and cloud environments while balancing application dependencies, operational requirements, and modernization goals. SQL Server migration enabled by Azure Arc simplifies this process by bringing migration activities into a single experience in the Azure portal. With the July 2026 release, we are announcing General Availability of SQL Server on Azure Virtual Machines as a migration target in Azure Arc, allowing customers to have a greater flexibility to choose Azure destination that best aligns with to your needs without introducing additional tools or migration processes. Whether migrating to the fully managed Azure SQL Managed Instance service or to SQL Server running on Azure VMs, the experience remains consistent and familiar. Unified Migration Workflow A key benefit of SQL Server migration enabled by Azure Arc is that the entire migration lifecycle is managed from a single tool in Azure portal. After a SQL Server instance is enabled by Azure Arc, customers can: Assess migration readiness Select a migration target Configure migration settings Monitor migration progress Validate results Perform final cutover All of these activities are performed directly from the Azure portal using a guided workflow designed to simplify migration planning and execution. The prerequisite remains unchanged: source SQL Server instances must be enabled by Azure Arc before migration can begin. The result is a flexible, scalable, and consistent migration experience that supports hybrid realities, reduces operational overhead, and helps customers modernize SQL Server estates at their own pace. Consistent Experience Across Azure SQL Targets Migration to SQL Server on Azure Virtual Machines follows the same operational model already available for Azure SQL Managed Instance migration scenarios. Customers use the same migration dashboard, monitoring experience, and guided workflow regardless of the destination. This consistency reduces learning curves, simplifies operational processes, and enables teams to select the most appropriate Azure SQL platform without changing migration methodology. Online Migration Using Backup and Log Shipping Migration to SQL Server on Azure Virtual Machines uses backup and restore with log shipping to support online migration scenarios while minimizing downtime. The process begins with a full database backup that is restored to the target SQL Server instance running on an Azure Virtual Machine. Transaction log backups that are uploaded continuously by your workflows to Azure Blob Storage are continuously applied to the target database, keeping it closely synchronized with the source environment. Azure Blob Storage serves as the intermediary staging location between source and target systems. To support efficient data movement and restore operations, both the Azure Blob Storage account and the target SQL Server on Azure Virtual Machines must reside in the same Azure region. Within the Azure Arc migration experience, customers select the Azure Blob Storage container that stores the backup files. Azure Arc automatically restores the full backup and continuously applies transaction log backups as they become available. Customers are responsible for configuring and maintaining the continuous upload of transaction log backups to Azure Blob Storage. Customer-Controlled Cutover When the customer is ready to complete migration, upon customer initiated cutover, Azure Arc performs the final synchronization by applying the last uploaded backup and bringing the target database online. This approach gives organizations full control over the migration timeline and cutover window, allowing downtime to be planned according to business requirements while reducing operational complexity. Learn More To learn more about SQL Server migration enabled by Azure Arc, see: Migration Overview For information about migrating to SQL Server in Azure VM, see: Migrate to SQL Server in Azure VM1.2KViews0likes1CommentGenerally Available: SQL Migration to SQL Server on Azure Virtual Machines in Azure Architecture
One Migration Experience, More Flexibility Modernizing SQL Server estates is rarely a single-step journey. Organizations often operate across on-premises, hybrid, and cloud environments while balancing application dependencies, operational requirements, and modernization goals. SQL Server migration enabled by Azure Arc simplifies this process by bringing migration activities into a single experience in the Azure portal. With the July 2026 release, we are announcing General Availability of SQL Server on Azure Virtual Machines as a migration target in Azure Arc, allowing customers to have a greater flexibility to choose Azure destination that best aligns with to your needs without introducing additional tools or migration processes. Whether migrating to the fully managed Azure SQL Managed Instance service or to SQL Server running on Azure VMs, the experience remains consistent and familiar. Unified Migration Workflow A key benefit of SQL Server migration enabled by Azure Arc is that the entire migration lifecycle is managed from a single tool in Azure portal. After a SQL Server instance is enabled by Azure Arc, customers can: Assess migration readiness Select a migration target Configure migration settings Monitor migration progress Validate results Perform final cutover All of these activities are performed directly from the Azure portal using a guided workflow designed to simplify migration planning and execution. The prerequisite remains unchanged: source SQL Server instances must be enabled by Azure Arc before migration can begin. The result is a flexible, scalable, and consistent migration experience that supports hybrid realities, reduces operational overhead, and helps customers modernize SQL Server estates at their own pace. Consistent Experience Across Azure SQL Targets Migration to SQL Server on Azure Virtual Machines follows the same operational model already available for Azure SQL Managed Instance migration scenarios. Customers use the same migration dashboard, monitoring experience, and guided workflow regardless of the destination. This consistency reduces learning curves, simplifies operational processes, and enables teams to select the most appropriate Azure SQL platform without changing migration methodology. Online Migration Using Backup and Log Shipping Migration to SQL Server on Azure Virtual Machines uses backup and restore with log shipping to support online migration scenarios while minimizing downtime. The process begins with a full database backup that is restored to the target SQL Server instance running on an Azure Virtual Machine. Transaction log backups that are uploaded continuously by your workflows to Azure Blob Storage are continuously applied to the target database, keeping it closely synchronized with the source environment. Azure Blob Storage serves as the intermediary staging location between source and target systems. To support efficient data movement and restore operations, both the Azure Blob Storage account and the target SQL Server on Azure Virtual Machines must reside in the same Azure region. Within the Azure Arc migration experience, customers select the Azure Blob Storage container that stores the backup files. Azure Arc automatically restores the full backup and continuously applies transaction log backups as they become available. Customers are responsible for configuring and maintaining the continuous upload of transaction log backups to Azure Blob Storage. Customer-Controlled Cutover When the customer is ready to complete migration, upon customer initiated cutover, Azure Arc performs the final synchronization by applying the last uploaded backup and bringing the target database online. This approach gives organizations full control over the migration timeline and cutover window, allowing downtime to be planned according to business requirements while reducing operational complexity. Learn More To learn more about SQL Server migration enabled by Azure Arc, see: Migration Overview For information about migrating to SQL Server in Azure VM, see: Migrate to SQL Server in Azure VM417Views0likes0Comments3 Reasons Enterprise SQL Server Migrations Slow Down - and How to Avoid Them
Summary Many of Enterprises around the globe have relied on SQL Server for over 3 decades to run their mission critical business applications. Their SQL Server estates face pressure from downtime risk, cost volatility, end of support timelines and modernization demands. As these customers get ready to modernize their data to use the latest capabilities of A.I and cloud native application trends, they want to migrate and modernize their SQL Servers to use Azure SQL with a modernization strategy built on confidence of customer success. Enterprise migrations rarely fail because of migration tools. They slow down because organizations struggle to answer three questions: How much downtime can we tolerate? What will it cost after migration? Are we choosing the right target platform? The organizations that answer these questions early move faster and with less risk. For the DB Administrators, Data architects, application architect and cloud-cost decision makers there are important technical considerations before, during and after data modernization to avoid long term costs and operational concerns. The Microsoft SQL Team has helped many customers modernize their SQL. We discuss important guidelines that can help resolve the 3 major concerns that block or slow SQL Server migration and modernization in Enterprises. This is covered in the episode of DataExposed for which this companion blog goes into the details. What are important triggers that cause customers and partners to consider SQL modernization? There are many business triggers that force Enterprises to migrate their data to public cloud. As SQL Server 2012 to SQL Server 2016 are already in the end of support stage of their lifecycle, customers need to upgrade SQL Server in place or migrate to AzureSQL. Due to cyber security threats, customers are feeling more vulnerable to attackers. Moving their data into a secure environment is essential for protecting not just their data but their business. Customers are reporting the need to free up IT dollars to invest into other parts of the business that may need it more. These may be anything from datacenter contract expirations, need for Hardware refreshes to software license renewals. As the business grows or becomes cyclical, there is surge in demand. Capacity constraints become a barrier for such expansions. These are triggers that cause them to rethink their data modernization strategy. Data modernization and moving the data to a elastic, scalable, secure and resilient data platform such as Azure SQL, becomes essential. The Three Migration Blockers However, data modernization and migration is not without any risk. Based on our customers experience, here are three key reasons that we have commonly encountered that halt or slow down SQL modernization. 1. Downtime Risk Business stakeholders often require strict service level commitments before authorizing production cutovers. Even when migrations are technically feasible, organizations may delay projects if they believe downtime windows could impact revenue, customer experience, or regulatory obligations. Most customers are still offered offline migration paths which can take hours to days, even though zero-downtime migrations are possible which take seconds to minutes. 2. Cost uncertainty Many modernization projects are approved based on expected cost savings. However, if infrastructure sizing, licensing assumptions, storage consumption, or disaster recovery requirements are not evaluated properly, the actual operational cost can exceed initial expectations. Cost uncertainty often slows executive approval processes and extends migration timelines. 3. Compatibility and Feature Fit When migrating SQL Server, Azure SQL has several deployment offerings from IaaS to PaaS. These include SQL Server on Azure VM, Azure SQL Managed Instance, Azure SQL DB Hyperscale and Azure SQL in Microsoft Fabric. Many customers maybe using SQL Server features like Cross-database queries, CLR, SSIS, SQL Agent, and linked servers. They make a safe decision to lift and shift migrate to SQL Server on Azure VMs IaaS instead of modernizing to a PaaS service like Azure SQL Managed Instance. However, in the process, they lose the opportunity to use the PaaS capabilities, manageability and AI/Fabric capabilities in Azure by making this choice. Enterprise Architects, Application Architects, Database developers and DB Administrators have to make the right choice taking both development as well as operational costs and compatibility when they make their SQL modernization decisions. Here are best practices some of the biggest and successful SQL migrations have used to make the migration and modernization journey with confidence. While we cannot disclose specific customer names, these guidelines are based on helping many large to small Enterprise customers. Azure SQL Managed Instance as the Resiliency Anchor Azure SQL Managed Instance is often the platform that helps organizations overcome all three concerns simultaneously because it combines near-full SQL Server compatibility with platform-as-a-service benefits. Azure SQL Managed Instance (Azure SQL MI) Next-gen General Purpose is now generally available, bringing a built-in performance and scale upgrade for General Purpose workloads, including up to 500 databases per instance, up to 32 TB storage, lower latency, and higher IOPS. The release also adds more flexible cost-performance tuning with independent vCore, IOPS, and memory scaling, plus faster management operations to adapt to changing workload demand. For enterprise SQL Server modernization, this positions Azure SQL MI as a stronger path for high-compatibility migrations that need better price-performance without moving to a full replatform. Let us dive deeper into how this helps address the downtime risk concerns by enables three levels of resiliency and high availability features. Local Redundancy Azure SQL Managed Instance provides first layer of Local Redundancy — built into every Azure SQL MI instance at no extra cost. Azure SQL Managed Instance uses local redundancy by default to keep workloads available during node, VM, rack, maintenance, and other local failures within a single datacenter, with Service Fabric orchestrating failover. In General Purpose (including Next-gen GP), this is implemented as stateless compute plus remote stateful storage; during failover, the engine process moves to another compute node and reattaches data, which can cause temporary performance impact due to cold cache. In Business Critical, local redundancy uses multiple synchronized replicas with local SSD storage (Always On-like architecture), enabling fast failover and read scale-out on secondaries.Next-gen General Purpose is an architectural upgrade to the existing General Purpose service tier that uses an upgraded remote storage layer that stores instance data and log files on Elastic SAN instead of page blobs and maintains it locally. Local redundancy protects against local infrastructure issues. This gives you a 99.99% SLA but not full datacenter/zone disasters, so zone redundancy (where supported) or disaster recovery (DR) options like failover groups/geo-restore are needed for broader resilience. Zone Redundancy The second layer is Zone Redundancy, which is accomplished placing data replicas across availability zones. Your Azure SQL MI resources are distributed across multiple availability zones within a region. This protects against the failure of an entire datacenter because each Azure availability zone is a separate physical location with independent power, cooling and networking. It relies on synchronous replication using zone-redundant storage for General Purpose. For Business critical, it uses Always On Availability group replicas across zones for Business Critical. Always On availability group technology replicates data changes from the primary instance to standby replicas in other availability zones. In the event of an outage, there's an automatic failover that seamlessly transitions one of the standby replicas to be prima. These replicas are always in sync — which means zero data loss. Failover typically happens in under 30 seconds, and your SLA jumps to 99.995%. Failover Groups The third layer is Failover Groups. This is your cross-region disaster recovery solution. It asynchronously replicates all user databases to a secondary Azure SQL MI instance in a different Azure region. Because it is asynchronous replication, there is potential for momentary data loss in the case of a datacenter outage. But it still protects the data against the worst case failure — a full regional outage. If the replica is a standby replica, there is no license required and it is used only for disaster recovery. Using these options, business stakeholders can get their assurance that they have Enterprise grade availability and resiliency platform of AzureSQL for running their mission critical workloads. You can read more about these HA and Resiliency options in Microsoft Learn. Cost Governance for Enterprise Buyers The total cost of data modernization and migration is not a one-time estimate but an ongoing one. In this case, Azure SQL MI provides Enterprise DB Administrators many levers through pricing model choice, right-sizing, elasticity, serverless options and dev/test free tiers. Let us explore how these can be combined for smart cost estimations. Lets also look at the best offering for the cost-conscious Enterprises - Azure SQL DB Hyperscale. With Azure SQL DB Hyperscale, you get the SQL Server engine, T-SQL compatibility, High Availability, Disaster recovery, security, backups, and management all bundled into the service price. No separate cost for SQL Server license. Hyperscale separates compute and storage that can scale independently and does not force you to overprovision. You have to only pay what you use which is ideal for seasonal workloads, Dev/Test, SaaS applications, predictable daytime trends, and up to 60% savings when you use Elastic pools. Azure Hybrid benefit (AHB)- Azure Hybrid Benefit lets you bring your existing SQL Server investments to Azure and reduce compute costs, accelerating your ROI from cloud migration while preserving all the benefits of Azure SQL Azure SQL DB Free offer – is the strongest product offering. Enterprises can use all features of Azure SQL at no cost for up to 10 Azure SQL DB free-tier. 100,000 vCore-seconds of serverless compute per month, 32GB data storage, 32 GB backup storage, serverless auto-scaling and auto-pause if you hit the limit per month. Run your POCs at no cost and evaluate before you move to Azure SQLDB, especially SMB& some enterprise Azure SQL Managed Instance also offers 1 free Azure SQL MI instance per Azure subscription giving you 720vCore hours per month, 64GB storage, up to 500 databases, automated backups and 12 months free. And if data migration is not possible due to data compliance or data proximity purposes, Azure Arc Pay-As-You-Go (PAYG) gives you cloud-style SQL licensing for servers running anywhere—on-premises, at the edge, or in other clouds. Instead of making large up-front licensing investments, you only pay for SQL Server while it's running, while still gaining access to Azure Arc management, security, monitoring, and modernization capabilities. For seasonal, variable, or growth-oriented workloads, PAYG can improve cash flow and reduce licensing complexity. Reserved instances allow Enterprise customers to commit to using Azure SQL resource for a period of one or three years to receive a significant discount. This option combined with AHB can save you even more up to 80%. We have a comprehensive licensing guide for on-premises SQL Server for your reference. Azure SQL enables a variety of cloud cost-models for a wide range of enterprise workload needs to help Enterprise cloud cost decision makers and DB Administrators make the right choice for their workloads. Target selection guidance While Azure SQL has multiple deployment options to migrate your on-premises work loads, it is critical to make the right choice long term. Customers can install SQL Server on-premises, they can use Azure SQL deployment options, and also run SQL Server in other clouds like Amazon Web Services and Google Cloud. If there is an Enterprise workload that is not ready to modernize, you have the ability to lift and shift into SQL Server in Azure VM. It is a low cost migration option, because the application does not need any modification and it gives DB Administrators full control over the SQL server and underlying Windows or Linux OS. This can be a first step to modernization for some customers who are risk-averse. For those Enterprise customers who are willing to modernize their workloads and SQL Server instances, Azure SQL DB Hyperscale is the best option. Azure SQL Database Hyperscale helps organizations modernize their most demanding database workloads with virtually unlimited growth, high performance, and cloud-scale economics. Customers can scale storage and compute independently, support large multi-terabyte databases, accelerate application performance with read-scale replicas, and eliminate the operational complexity of managing infrastructure, backups, patching, and high availability. They can build cloud-native applications or cloud-enable existing applications. However, if Enterprise customers want good compatibility with their on-premises SQL Server but continue down the modernization path - their best option is Azure SQL Managed Instance. They can modernize the instance and not impact the application as there is no application change required. Applications will continue to work and the DB Administrators do not need to worry about managing infrastructure and all the overhead that comes with managing, self-managing your SQL Server virtual machines. For SQL Server customers, PostgreSQL may look like an attractive low cost option. However, it requires re-platforming that could add significant hidden cost due to retraining all their DBAs and their developers to do performance optimization, performance best practices and operational maintenance. Lastly, our same SQL engine is also available to customers as a SaaS-ified version, Fabric SQL database as well. All these options use the exact same SQL engine which makes it easier for Database developers and DB Administrators continue to use the same expertise, tools and process. Making the right choice of Azure SQL deployment is not just on the fastest way to modernize but the right long term approach. Conclusion and Next steps Enterprise SQL Server migrations rarely stall because of migration technology. More often, they are delayed by concerns around downtime, cost predictability, and platform selection. Organizations that address these questions early can accelerate modernization while reducing operational risk. Azure SQL provides multiple modernization paths—from SQL Server on Azure Virtual Machines to Azure SQL Managed Instance and Azure SQL Database—allowing organizations to balance compatibility, operational simplicity, resiliency, and cost efficiency based on their business requirements. As modernization initiatives accelerate, the most successful projects are those that treat migration not as a one-time infrastructure event, but as a long-term platform strategy. Whether its the newest and the fastest way for us to migrate customers, we have all the comprehensive Copilot enabled AI-assisted migration tooling, technical training and support you need. Look for more blogs, whitepapers, guides and training based on best practices used real-world data modernization projects.536Views0likes0CommentsRegex support for LOB types in T-SQL—available in Azure SQL & SQL Server 2025
At a glance — Native regular expression (regex) functions in T-SQL now accept varchar(max) and nvarchar(max) inputs of up to 2 MB across all seven regex functions, including the two table-valued functions (REGEXP_MATCHES and REGEXP_SPLIT_TO_TABLE). This capability ships in SQL Server 2025 CU5 and is already available in Azure SQL Database, SQL Database in Fabric and Azure SQL Managed Instance configured with the Always-up-to-date update policy. It will reach Managed Instances on the SQL Server 2025 update policy as part of the CU5 rollout. You no longer need to split log files, HTML documents, or large JSON payloads into 8,000-byte chunks just to run a pattern match. 1. Introduction Regular expressions have long been a cornerstone of modern data processing — used for validation, parsing, transformation, and extracting structured insights from unstructured text. With SQL Server 2025 and Azure SQL, regex is now a first-class T-SQL capability, removing the historical need to rely on SQLCLR functions or application-tier processing. While the initial release made native regex broadly available, large-object (LOB) inputs were not yet supported on every function. CU5 closes that gap. Under the hood, T-SQL regex implements POSIX Extended Regular Expression (ERE) semantics, augmented by a curated set of Perl-style features, and is powered by the RE2 engine. RE2 is a linear-time, non-backtracking implementation, which means it is not susceptible to catastrophic backtracking (a class of denial-of-service issue commonly known as ReDoS). That guarantee becomes far more important when the input is a 1.8 MB log blob than when it is an 8,000-byte string. Release timeline Milestone What shipped Ignite 2025 — General Availability Regex went GA in SQL Server 2025 and Azure SQL. LOB inputs were initially supported only on REGEXP_LIKE, REGEXP_COUNT, and REGEXP_INSTR. LOB support on REGEXP_REPLACE and REGEXP_SUBSTR was deferred, and the two table-valued functions (TVFs) accepted only non-LOB string types. Azure SQL (post-GA service updates) LOB inputs enabled across all seven functions. SQL Server 2025 CU5 LOB inputs up to 2 MB enabled on all seven functions in the SQL Server. What’s new in CU5 varchar(max) and nvarchar(max) inputs are accepted on every regex function. The input string is capped at 2 MB per function call. The pattern is still capped at 8,000 bytes, which is far larger than any maintainable regular expression should ever need. Behavior is consistent between Azure SQL and SQL Server, so code you write today is fully portable. Note — The 2 MB limit applies to the input passed to a single function call, not to the column or row. A single value in a varchar(max) column can still store up to 2 GB; the constraint is that no single regex evaluation can consume more than 2 MB of that value. Prerequisites SQL Server 2025 CU5 or later, or Azure SQL Database, or SQL Database in Fabric or Azure SQL Managed Instance configured with the SQL Server 2025 / Always-up-to-date update policy. The two table-valued functions (REGEXP_MATCHES and REGEXP_SPLIT_TO_TABLE) require database compatibility level 170, unless the database-scoped configuration ALLOW_BUILTIN_TVF_IN_ALL_COMPAT_LEVELS (preview) is enabled. Note — On Azure SQL Managed Instance (Always-up-to-date), this capability is rolling out region by region. It is already live in regions where the rollout has completed and will light up in the remaining regions as the deployment finishes. Instances on the SQL Server 2025 update policy will receive it as part of the CU5 rollout — coming soon. Verify compatibility level (170 required for the TVFs) – SELECT name, compatibility_level FROM sys.databases WHERE name = DB_NAME(); -- If necessary: -- ALTER DATABASE [<your-database>] SET COMPATIBILITY_LEVEL = 170; 2. Working with LOB Data This section demonstrates the CU5 capabilities against a realistic LOB data. We build a LogEntries table whose RawPayload column holds multi-KB to multi-MB chunks of web server and application output, plus an HtmlPages table for HTML cleansing examples. 2.1 Create the sample schema and data IF OBJECT_ID('dbo.LogEntries', 'U') IS NOT NULL DROP TABLE dbo.LogEntries; IF OBJECT_ID('dbo.HtmlPages', 'U') IS NOT NULL DROP TABLE dbo.HtmlPages; CREATE TABLE dbo.LogEntries ( LogId BIGINT IDENTITY(1,1) PRIMARY KEY, Source SYSNAME NOT NULL, IngestedAt DATETIME2(3) NOT NULL DEFAULT SYSUTCDATETIME(), RawPayload VARCHAR(MAX) NOT NULL -- LOB column ); CREATE TABLE dbo.HtmlPages ( PageId INT IDENTITY(1,1) PRIMARY KEY, Url NVARCHAR(2048) NOT NULL, Body NVARCHAR(MAX) NOT NULL -- LOB column (Unicode) ); Now generate realistically large rows. The REPLICATE(CAST(... AS varchar(max)), n) pattern is required because REPLICATE returns NULL when the result would exceed 8,000 bytes unless its first argument is a max type. -- Synthetic web access-log payload (~252 KB in row 1, plus a separate ~586 KB row). DECLARE @logLine VARCHAR(500) = '127.0.0.1 - alice [21/May/2026:10:15:32 +0000] "GET /api/orders/42 HTTP/1.1" 200 1532 ' + 'user-agent="Mozilla/5.0" ip=10.0.0.7 email=alice@contoso.com card=4111-1111-1111-1234' + CHAR(10); DECLARE @bigLog VARCHAR(MAX) = REPLICATE(CAST(@logLine AS VARCHAR(MAX)), 1500) -- ~252 KB + '127.0.0.1 - mallory [21/May/2026:10:16:01 +0000] "POST /login HTTP/1.1" 500 0 ' + 'ip=203.0.113.99 ssn=123-45-6789' + CHAR(10); INSERT INTO dbo.LogEntries (Source, RawPayload) VALUES ('web-01', @bigLog), -- ~252 KB ('web-02', REPLICATE(CAST('OK ' AS VARCHAR(MAX)), 200000)); -- ~586 KB -- Synthetic HTML page (~775 KB / ~396,000 characters). DECLARE @htmlChunk NVARCHAR(MAX) = N'<div class="row"><p>Hello <b>world</b>! Contact <a href="mailto:bob@contoso.com">bob</a>.</p></div>'; INSERT INTO dbo.HtmlPages (Url, Body) VALUES (N'https://contoso.example/page-1', N'<html><head><title>Big Page</title></head><body>' + REPLICATE(@htmlChunk, 4000) + N'</body></html>'); -- Confirm payload sizes in bytes. SELECT LogId, Source, DATALENGTH(RawPayload) AS PayloadBytes FROM dbo.LogEntries; SELECT PageId, DATALENGTH(Body) AS BodyBytes, LEN(Body) AS BodyChars FROM dbo.HtmlPages; Results: LogId Source PayloadBytes 1 web-01 258,110 2 web-02 600,000 PageId BodyBytes BodyChars 1 792,124 396,062 Before CU5, feeding any of these payloads into REGEXP_REPLACE, REGEXP_SUBSTR, REGEXP_MATCHES, or REGEXP_SPLIT_TO_TABLE would have failed with a type-mismatch error or required a LEFT(RawPayload, 8000)-style truncation. The same queries now run end-to-end. 2.2 REGEXP_LIKE — Filter rows by LOB content -- Find logs that contain at least one HTTP 5xx response. SELECT LogId, Source, DATALENGTH(RawPayload) AS PayloadBytes FROM dbo.LogEntries WHERE REGEXP_LIKE(RawPayload, '"[A-Z]+\s[^"]+\sHTTP/1\.[01]"\s5[0-9]{2}\s'); REGEXP_LIKE is a Boolean predicate: it evaluates to true when the pattern matches anywhere in the input and false otherwise. Because it returns a Boolean rather than a bit, use it directly in WHERE, CASE WHEN, IIF, or CHECK constraint contexts — do not compare it with = 1 or = 0 (the parser rejects that syntax). Note — REGEXP_LIKE itself requires database compatibility level 170. The other scalar regex functions (REGEXP_COUNT, REGEXP_INSTR, REGEXP_REPLACE, REGEXP_SUBSTR) are available at all compatibility levels. Results: LogId Source PayloadBytes 1 web-01 258,110 2.3 REGEXP_COUNT — Counting at scale -- Per-row tally of GET requests, POST requests, and 5xx responses -- across the entire LOB payload. SELECT LogId, Source, REGEXP_COUNT(RawPayload, '"GET\s') AS Gets, REGEXP_COUNT(RawPayload, '"POST\s') AS Posts, REGEXP_COUNT(RawPayload, '\s5[0-9]{2}\s') AS ServerErrors FROM dbo.LogEntries; Results: LogId Source Gets Posts ServerErrors 1 web-01 1,500 1 1 2 web-02 0 0 0 2.4 REGEXP_INSTR — Locate the first error -- 1-based character position (or 0 if no match) of the FIRST 5xx response in each payload. SELECT LogId, Source, REGEXP_INSTR(RawPayload, '\s5[0-9]{2}\s', 1, 1, 0) AS FirstErrorPos FROM dbo.LogEntries; Parameter recap: REGEXP_INSTR(string, pattern, start, occurrence, return_option [, flags [, group ]]). A return_option of 0 returns the starting position of the match; 1 returns the position immediately after the last character of the match. Results: LogId Source FirstErrorPos 1 web-01 258,072 2 web-02 0 2.5 REGEXP_REPLACE — Redact sensitive data in place PII redaction over LOB payloads was one of the most-requested CU5 scenarios. Before CU5, it required a custom chunked-replace routine; it is now a single expression. -- Redact credit-card-shaped tokens, U.S. SSN-shaped tokens, and email addresses -- across the entire payload. SELECT LogId, REGEXP_REPLACE( REGEXP_REPLACE( REGEXP_REPLACE( RawPayload, '\b[0-9]{4}[- ]?[0-9]{4}[- ]?[0-9]{4}[- ]?[0-9]{4}\b', '****-****-****-****'), '\b[0-9]{3}-[0-9]{2}-[0-9]{4}\b', '***-**-****'), '\b[A-Za-z0-9._%+\-]+@[A-Za-z0-9.\-]+\.[A-Za-z]{2,}\b', '[redacted-email]' ) AS RedactedPayload FROM dbo.LogEntries; Or strip every HTML tag from an nvarchar(max) page in a single call: SELECT PageId, LEN(Body) AS OriginalLen, LEN(REGEXP_REPLACE(Body, N'<[^>]+>', N'')) AS TextOnlyLen FROM dbo.HtmlPages; Results — the ~775 KB HTML document collapses from 396,062 to 100,008 characters of plain text in a single call: PageId OriginalLen TextOnlyLen 1 396,062 100,008 2.6 REGEXP_SUBSTR — Extract a single value -- Pull the first IPv4 address out of each log payload. SELECT LogId, REGEXP_SUBSTR(RawPayload, '\b(?:[0-9]{1,3}\.){3}[0-9]{1,3}\b', 1, -- start position 1, -- occurrence 'c', -- flags: case-sensitive 0 -- group: 0 returns the whole match ) AS FirstIp FROM dbo.LogEntries; To return the contents of a specific capture group instead of the entire match, pass its 1-based group number as the final argument. Results: LogId FirstIp 1 127.0.0.1 2 NULL 2.7 REGEXP_MATCHES — Every match, set-based This is where the combination of TVF and LOB delivers the largest productivity gain: extract every structured value from a megabyte of unstructured text in a single set-based query, with no client round-trips. REGEXP_MATCHES returns one row per match with these columns: Column Type Description match_id bigint Sequence number of the match (1-based). start_position int 1-based start index of the match. end_position int 1-based end index of the match. match_value same type as string_expression The entire matched substring. substring_matches json JSON array describing each capture group, with the shape [{"value":"…","start":N,"length":N}, …]. -- Every email address in every log payload, alongside its row of origin. SELECT l.LogId, m.match_id, m.match_value AS EmailFound FROM dbo.LogEntries AS l CROSS APPLY REGEXP_MATCHES( l.RawPayload, '\b[A-Za-z0-9._%+\-]+@[A-Za-z0-9.\-]+\.[A-Za-z]{2,}\b' ) AS m ORDER BY l.LogId, m.match_id; Capture groups are even more useful — you can project the parts of every log line as columns by reading from the substring_matches JSON document: -- Parse Common-Log-Format-ish entries into ip, user, status, and bytes columns. -- The pattern has four capture groups, accessed below as $[0] through $[3]. SELECT l.LogId, m.match_id, JSON_VALUE(m.substring_matches, '$[0].value') AS Ip, JSON_VALUE(m.substring_matches, '$[1].value') AS UserName, JSON_VALUE(m.substring_matches, '$[2].value') AS Status, JSON_VALUE(m.substring_matches, '$[3].value') AS Bytes FROM dbo.LogEntries AS l CROSS APPLY REGEXP_MATCHES( l.RawPayload, '^([0-9.]+)\s-\s(\S+)\s\[[^\]]+\]\s"[^"]+"\s([0-9]{3})\s([0-9]+)', 'm' -- multi-line: ^ and $ anchor to each line, not just the whole input ) AS m ORDER BY l.LogId, m.match_id; Important — Without the 'm' flag, the ^ anchor matches only at the start of the entire 250 KB input, so you would receive exactly one match for the first line. The multi-line flag is what unlocks per-line extraction. Results (first two parsed rows): LogId match_id Ip UserName Status Bytes 1 1 127.0.0.1 alice 200 1532 1 2 127.0.0.1 alice 200 1532 2.8 REGEXP_SPLIT_TO_TABLE — Shred a LOB into rows -- Project the entire log payload as one row per non-empty line. SELECT l.LogId, s.ordinal AS [LineNo], s.value AS LineText FROM dbo.LogEntries AS l CROSS APPLY REGEXP_SPLIT_TO_TABLE(l.RawPayload, '\r?\n') AS s WHERE l.LogId = 1 AND s.value <> '' ORDER BY s.ordinal; You now have a tabular projection of a multi-megabyte text blob without leaving the engine. You can feed it into a CTE, aggregate it, join it to dimension tables, or materialize it into a staging table — all set-based. Results (first three rows): LogId ordinal LineText (first 80 chars) 1 1 127.0.0.1 - alice [21/May/2026:10:15:32 +0000] "GET /api/orders/42 HTTP/1.1" 200 1 2 127.0.0.1 - alice [21/May/2026:10:15:32 +0000] "GET /api/orders/42 HTTP/1.1" 200 1 3 127.0.0.1 - alice [21/May/2026:10:15:32 +0000] "GET /api/orders/42 HTTP/1.1" 200 Tip — composing LOB regex pipelines — CROSS APPLY (and OUTER APPLY when you need to preserve rows that produce no matches) is the primary composition primitive. You can stack REGEXP_SPLIT_TO_TABLE (lines) feeding REGEXP_MATCHES (fields per line) feeding ordinary aggregates, all within a single query plan. 2.9 The 2 MB ceiling — strategies for larger inputs The 2 MB limit applies to the input string of a single regex call. If the value passed to a regex function exceeds 2 MB, the call raises an error (error number 19311, severity 16) rather than silently truncating. That is the intended behavior — silent truncation would hide correctness bugs. In practice, 2 MB is a generous ceiling: a single log file or HTML document of that size is already unusual, and most real-world LOB data sit comfortably below it. When individual values do exceed the limit, the most reliable approach is to split them into smaller logical units before they land in the column you want to query — for example, by writing one log line, one document section, or one record per row at ingestion time. Because every regex function (including the two TVFs) shares the same 2 MB ceiling, sharding at query time is not generally feasible; doing it at the load path keeps every regex call well under the limit and avoids per-query workarounds. Bytes vs. characters — The 2 MB limit is measured in bytes, not characters, and the byte count is based on the UTF-8 encoding of the input regardless of the column’s declared type. ASCII characters take 1 byte each, so plain ASCII text can run to roughly two million characters; non-ASCII characters take 2–4 bytes in UTF-8, so fewer characters fit. Keep in mind that DATALENGTH() reports storage size in the column’s own encoding, which may differ from the UTF-8 byte count used by the limit, and LEN() (which counts characters) is best avoided as a sizing check here. To measure the UTF-8 byte length that the limit actually checks, cast the value to varchar(max) under a UTF-8 collation and take its DATALENGTH: SELECT DATALENGTH( CONVERT(varchar(max), Body COLLATE Latin1_General_100_CI_AS_SC_UTF8) ) AS Utf8Bytes FROM dbo.HtmlPages; Anything above 2 * 1024 * 1024 (2,097,152) bytes will be rejected by a regex call on that value. Have a scenario that genuinely needs more than 2 MB? If your workload requires regex evaluation on individual values larger than the current 2 MB ceiling, we would like to hear about it. Please share the details — data shape, payload size, pattern, and business need — on the Azure SQL feedback portal. Customer feedback directly informs how we prioritize future limit changes. 2.10 Cleanup DROP TABLE IF EXISTS dbo.LogEntries; DROP TABLE IF EXISTS dbo.HtmlPages; 3. Summary What changed in CU5 Before CU5 — LOB inputs were accepted on REGEXP_LIKE, REGEXP_COUNT, and REGEXP_INSTR. The remaining functions — REGEXP_REPLACE, REGEXP_SUBSTR, and the two TVFs (REGEXP_MATCHES, REGEXP_SPLIT_TO_TABLE) — required non-LOB string inputs, which often meant truncating with LEFT(..., 8000) or chunking in the application tier. After CU5 (and already in Azure SQL) — All seven functions accept varchar(max) and nvarchar(max) inputs of up to 2 MB. The pattern remains capped at 8,000 bytes. Quick reference Function Returns LOB input (CU5) Common use case REGEXP_LIKE Boolean (predicate) Yes Filter rows in WHERE / CASE / CHECK predicates REGEXP_COUNT int Yes Count occurrences of a pattern REGEXP_INSTR int Yes Position of the nth match REGEXP_REPLACE string Yes Redact, cleanse, or normalize text REGEXP_SUBSTR string Yes Extract a single value REGEXP_MATCHES (TVF) (match_id, start_position, end_position, match_value, substring_matches) Yes Extract every match plus capture groups (via JSON), set-based REGEXP_SPLIT_TO_TABLE (TVF) (value, ordinal) Yes Split a LOB into rows by a regex delimiter Further reading Official documentation: REGEXP_LIKE, REGEXP_COUNT, REGEXP_INSTR, REGEXP_REPLACE, REGEXP_SUBSTR, REGEXP_MATCHES, REGEXP_SPLIT_TO_TABLE. Regular expressions overview. SQL Server 2025 CU5 release notes. Closing thought. Native regex was already a significant quality-of-life improvement when it became generally available. CU5 completes the picture: every function, every input size up to 2 MB, every shape — scalar or table-valued. The next time you are tempted to export a column out of the database in order to grep it, try one of the seven regex functions first. Happy matching. 🧠590Views0likes0Comments