slm
74 TopicsFrom Chat to Decisions: Bringing SLMs into Application Logic with Microsoft Olive and ONNX
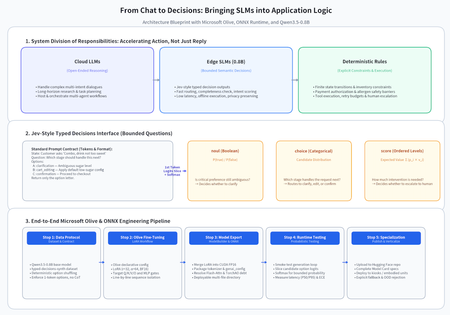
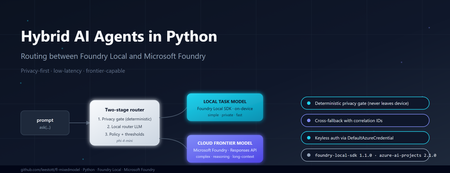
1. Why Jev Matters: Accelerating the Next Action, Not Just the Next Reply Let us return to the automated ordering scenario we have been exploring. A customer says, “I’ll have a combo, but make the drink not too sweet.” A conversational model can produce a friendly response. For the ordering application, however, the real work is just beginning. Has the customer selected a particular combo? Does “not too sweet” map to a supported customization? Should the application ask a question, update the cart, or move to confirmation? The application does not need another paragraph. It needs a decision that advances the workflow. Traditional rules are excellent at explicit constraints: unavailable items cannot be ordered, checkout requires confirmation, and payment requires authorization. Models should not replace these rules. But as inputs become ambiguous and context-dependent, rule trees accumulate branches. At the other extreme, sending every small routing decision through a large model’s reasoning and generation loop can add unnecessary waiting. This is how I think about the value of Jev: turn semantic understanding into structured behavioral decisions, shortening the distance between understanding and action. An ordering application might decompose the conversation into a few bounded questions: Decision Output type Effect on the workflow Is a critical preference still ambiguous? noul: probability for a Boolean question Decide whether to clarify Which stage should handle the request next? choice: candidate action and distribution Route to clarification, cart editing, or confirmation How much human intervention is needed? score: expected value over ordered levels Decide whether to escalate These outputs are not permissions. A model can recommend confirmation, but that recommendation must not bypass inventory checks, allergen rules, or payment authorization. The application still needs explicit state transitions, constraints, and tool boundaries. The lesson I take from our ordering exploration is that structure does more than make an answer easier to parse: it can remove unnecessary decision steps from an agent’s workflow. If questions, options, and execution boundaries are defined in advance, the model does not have to reinvent the process on every turn. One distinction matters before we continue. This project does not fine-tune an official Jev model or reproduce its private implementation. It borrows the Jev-style typed-decision interface idea, follows the prompt conventions of the open-source Hmm project, and explores a deployable component built from our own small model. 2. Where Edge SLMs Fit: Put the Decision Close to the Action Beyond basic rules, the opportunity that interests me most is in vertical applications: can a model make a useful semantic decision where the action actually happens? An SLM—a small language model—is not automatically an edge-ready model. Model size, context length, runtime, memory, and hardware all determine whether it fits a target device. Nevertheless, small models suggest a useful division of responsibilities: Use large models for open-ended problems, small models for frequent and bounded semantic decisions, and deterministic code for constraints and execution. From ordering terminals to embodied systems At an ordering terminal, a local model could recognize a modification request, assess whether required information is complete, and select the appropriate business module. Some decisions could continue during network disruption, and sensitive context could avoid unnecessary transmission. Those benefits depend on the application’s complete data flow, not merely on storing model weights locally. In an embodied system, similar questions become task-level intent decisions: “Is the user asking the robot to approach, or only describing a location?” “Should the task continue, or wait for clarification?” There is an essential boundary here. A language model may participate in task-level decisions, but it should not be the sole mechanism for collision avoidance, emergency stopping, or low-level motion control. Millisecond-scale responsiveness is a worthwhile engineering objective—not an automatic consequence of using a small model or exporting to ONNX. We need to measure the complete path on the target device: input processing, inference, policy evaluation, and tool execution. From one assistant to multi-agent orchestration Multi-agent systems offer another opportunity. A complex request may involve research, planning, execution, and verification, but not every handoff requires an open-ended discussion. A local decision component might determine: Which agent should receive the request? Is the information required for execution complete? Does a tool result need independent review? Should the workflow continue, retry, or ask a human? I am exploring how hosted agents can handle longer orchestration flows while constrained autonomous execution moves work forward. Small models could serve as frequent, local decision points within that design. “Autonomous” does not mean unrestricted: tool permissions, timeouts, retry budgets, and human approval remain application responsibilities. This is a compelling role for ONNX: package a learned decision capability into an artifact that an inference runtime can load, without requiring every deployment target to carry the full training stack. However, ONNX is a deployment path, not a guarantee of portability or performance across all hardware. This workflow exports a CUDA FP16 model. Moving it to a CPU, mobile device, or NPU requires compatible execution providers and operators, and potentially re-export, quantization, and regression evaluation. 3. Fine-Tune a General Decision Component, Then Specialize It Rather than beginning with a complex industry system, I started with a general typed-decision experiment: Qwen3.5-0.8B → Olive LoRA fine-tuning → Olive ModelBuilder export → ONNX probability testing → a Hugging Face publishing workflow. The implementation lives in Qwen3_5_0.8B_FT.ipynb. Its purpose is not to claim that a notebook solves a vertical market. It makes the path from data to a deployable decision capability concrete. Stop one: learn a bounded choice, not a long answer The base model is Qwen/Qwen3.5-0.8B, and the dataset is n4ze3m/typed-decisions-synth. A state can contain several questions. Preprocessing expands each question into a training example while preserving the dataset’s case-level training and validation split. That prevents questions about the same state from leaking across the boundary. Each question becomes a choice among option letters: State (data to evaluate): Help! My payouts have failed for 3 days. I need the money today. Question: Which team should handle this? Options: A: billing — Payments, invoicing, refunds B: technical — Bugs, outages, integrations C: sales — Pricing, upgrades, new accounts Return only the option letter. choice represents categorical options, noul uses false / true, and score uses ordered levels. During preprocessing, choice options are shuffled deterministically using the state and question ID to reduce fixed-position bias. Score levels and Boolean options keep their intended ordering. Several small details protect the contract: use the same chat template, disable thinking, verify that training text begins with the inference prompt, verify that each option letter is one token, and discard examples longer than 768 tokens rather than blindly truncating them. This is not cosmetic data cleanup. It defines the protocol between the model and its application. Stop two: turn experiment settings into an inspectable Olive workflow The notebook builds Microsoft Olive from a fixed source revision. It uses olive finetune --dry_run to generate a version-matched configuration, then adjusts preprocessing and validation. Setting Notebook configuration Fine-tuning method LoRA, rank 32, alpha 64 Target modules q_proj/k_proj/v_proj/o_proj and gate_proj/up_proj/down_proj Learning rate and epochs 1e-4, one epoch Sequence length 768 Per-device batch / gradient accumulation 1 / 16 Training / export precision BF16 / FP16 Preprocessing line-by-line, one sequence per question Replacing the default JOIN strategy avoids concatenating independent questions into continuous text. Before training, RunConfig.model_validate(...) checks the configuration. Execution uses Olive’s Python API so failures remain visible in the notebook rather than being hidden behind a generic CalledProcessError. An important difference must remain explicit: this Olive workflow uses standard full-sequence language-model SFT, not Hmm’s candidate-letter hard-label / teacher soft-label mixture. Teacher probabilities are retained for analysis but do not contribute to this training loss. Consequently, Hmm’s accuracy and calibration results cannot be claimed for this 0.8B model. Stop three: export the runtime contract, not just the graph A LoRA adapter is not the deployment endpoint. The base model, adapter, tokenizer, configuration, and runtime must agree. The notebook uses Olive ModelBuilder to export the base model and adapter into CUDA FP16 ONNX. The result includes more than an .onnx file: external weights, tokenizer resources, and genai_config.json are part of the deployable unit. Consumers should load the complete directory. The most instructive part of the process was navigating version boundaries: Boundary encountered Approach in this workflow An unnecessary old TorchAO package conflicted with Transformers Remove it after dependency installation; standard BF16 LoRA does not require it Qwen3.5 kernels fell back to reference implementations Install and check causal-conv1d and Flash Linear Attention Export requested authentication for a public model Explicitly enable anonymous model access Qwen3.5 stored EOS information in text_config Add the top-level value to the local export configuration Newer CUDA packages did not match the runtime environment Pin the notebook’s ORT GPU 1.26.0 / GenAI CUDA 0.14.0 combination The Olive revision expected newer GenAI Builder APIs Add version-specific compatibility handling for this FP16 export path Text export behaved like a multimodal decoder Set exclude_embeds=False to retain token embeddings These are records of this environment, not universal patches. Compatibility code is technical debt: when upgrading, revisit the interfaces and outputs rather than copying the workaround indefinitely. Pinning an Olive commit also does not make the complete experiment reproducible. A stronger release record should include base-model and dataset revisions, the full dependency set, GPU and driver details, and the final publishing commit. Stop four: ask two different questions in testing The first question is: does the model run? The standalone Python test script loads the export, reads a validation example, generates an answer, and extracts an option letter. This is a smoke test for the model, tokenizer, and generation loop—not the end of quality evaluation. The second question is: can the application use the decision? Following Hmm’s approach, the ONNX probability cell reads logits at the first generated position after the prompt, selects only the valid option-letter logits, and applies softmax: # candidate_logits contains only valid first-token option logits. shifted = candidate_logits - candidate_logits.max() probabilities = np.exp(shifted) probabilities /= probabilities.sum() For options A, B, and C, this is a distribution over those three choices. It does not establish that the candidate set is complete or provide absolute confidence across every possible answer. The application then interprets the result: noul reads P(true), choice selects the highest-probability option, and score computes an expected value over ordered levels. The example’s confidence formula, (n × p_max - 1) / (n - 1), measures how concentrated the distribution is. It is not a calibrated probability of correctness. Evaluation therefore needs several lenses. Accuracy, candidate NLL, and ECE describe decision quality. P50/P95 latency, peak memory, fallback rate, and task completion on the target device describe application value. The notebook’s full validation-metric cell currently uses the PyTorch/PEFT path; the ONNX cell tests example probabilities. The former is not an evaluation report for the latter. Comparing candidate distributions and actual decisions before and after export remains necessary. This article does not claim unrecorded training times, accuracy improvements, or demonstrated millisecond edge latency. Stop five: publication begins the vertical journey The notebook contains a workflow to upload the ONNX directory and a Model Card to lokinfey/Qwen3_5_0.8B_jev. This is the configured publishing destination, not a claim that this article verified the remote upload. The Model Card should explain the base model, dataset, training-objective differences, runtime versions, intended use, and outstanding evaluation. Authentication uses interactive token entry rather than embedding credentials in source files or commit history. Once the general pipeline exists, specialization becomes the important work. In ordering, that means defining real business states and actions: menu version, cart contents, modification history, missing information, mandatory clarification, and operations that always require customer confirmation. Vertical data should reflect those boundaries, with validation splits based on conversations or business entities. Low confidence, out-of-distribution inputs, and rule conflicts need explicit rejection or escalation paths. The objective is not to force a choice for every request. It is to help the system move forward appropriately within known limits. 4. Conclusion: The Opportunity Is a Shorter Decision Path, Not a Smaller Chat Window An ordering clarification, a robot’s task-level intent check, and a local handoff in a multi-agent workflow share the same underlying problem: the system has tools, but it still needs to decide when to use them, who should act, and when to stop. Jev-style structured decisions offer an interface perspective. SLMs offer the possibility of moving some semantic judgments closer to the device. Microsoft Olive organizes fine-tuning and export into a workflow. ONNX Runtime provides an execution path for deployment. Together, they suggest something more useful than a smaller chatbot: a measurable, constrained, replaceable decision component. The direction I want to keep testing combines hosted agents for long-running coordination, edge small models for frequent local decisions, and deterministic code for business and safety boundaries. Success should be measured less by whether the reply sounds intelligent and more by whether the system completes the right action faster and more reliably. That is the next step from conversation to decisions. Implementation and references Fine-tuning notebook Microsoft Olive ONNX Runtime GenAI Qwen3.5-0.8B base model Hmm model card and prompt format typed-decisions-synth dataset234Views2likes0CommentsFrom Jev to Your Laptop: Building "System One" Decision Models in ONNX with Mobius
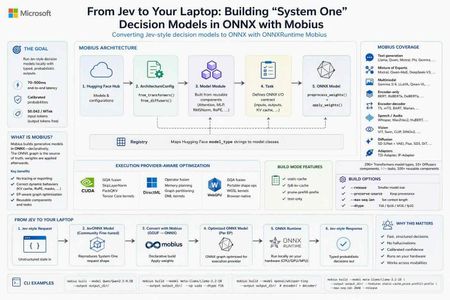
0. Why I'm writing this now Two things landed on my radar in the same week. First, TypeSafe AI published "Introducing System One Models & Jev" (Sep 15, 2026) and the developer community immediately started arguing about it. The pitch is unusual: instead of another chat model, Jev is described as "a new class of frontier models built to make fast, structured decisions that software can use directly." The post frames Jev as "a frontier-intelligence function call: unstructured state in, typed probabilistic decisions out" — and notes that while "Jev gives up string generation, it's optimized for structured outputs and can't hallucinate." The numbers in that post are what got everyone's attention: end-to-end response times of 70ms–500ms versus 3–329 seconds for frontier LLMs, input tokens at $0.042/MTok with output tokens free, and a claim that every answer arrives with a calibrated probability — "higher confidence means higher accuracy." The name itself is a thesis: TypeSafe named Jev after William Stanley Jevons, expecting that "every order of magnitude drop in the cost of intelligence unlocks orders of magnitude more use cases." Second — and this is the part that matters for anyone who builds on Microsoft's AI stack — onnxruntime/mobius has been quietly shipping at a furious pace. It's the piece of infrastructure that makes it realistic to take a model like this, in whatever format it arrives, and run it as an ONNX graph on hardware you control. So I built the bridge. kinfey/JevONNX takes an open, community-fine-tuned model that reproduces the System One request shape, converts it from GGUF to CPU ONNX with Mobius, and serves typed probabilistic decisions locally. This post covers three things: what Mobius is, how it differs from the ONNX Runtime GenAI Model Builder you may already be using, and how the JevONNX sample puts it together. 1. What is Mobius? Mobius builds generative models in ONNX. That preposition is the whole idea. From the repo's own description, Mobius provides "ONNX model definitions for GenAI using the onnxscript.nn API" — model definitions for "LLMs, MoE, multimodal, encoder-only, encoder-decoder, vision, audio, and diffusion models — built directly as ONNX graphs using onnxscript.nn.Module." The key sentence, and the one worth reading twice: "Rather than tracing or exporting PyTorch models, it constructs the ONNX graph declaratively, then applies pretrained HuggingFace weights." Why "declarative construction" is a big deal If you've ever exported a model to ONNX the traditional way, you know the failure modes. You run torch.onnx.export, the tracer executes one concrete path through Python control flow, and anything dynamic — a KV cache branch, a rotary embedding computed with a Python if, a sliding-window mask — either silently bakes in a constant or explodes into an unreadable subgraph. You then spend a week diffing graphs. Mobius inverts this. The graph is the source of truth, written as composable modules, and the weights are applied afterwards. The architecture in the README is four clean layers: HuggingFace Hub │ ▼ ArchitectureConfig ◄── from_transformers() / from_diffusers() │ ▼ Model Module ◄── Reusable Components (Attention, MLP, RMSNorm, RoPE, …) │ ▼ Task ◄── CausalLMTask, VisionLanguageTask, VAETask, DenoisingTask, … │ ▼ ONNX Model ◄── preprocess_weights() + apply_weights() Components — onnxscript.nn.Module building blocks (Attention, MLP, DecoderLayer, RoPE, VisionEncoder, MoELayer…) Models — full architectures composed from those components Tasks — define the ONNX graph's I/O contract (inputs, outputs, KV cache) Registry — maps HuggingFace model_type strings to model classes Adding a new architecture becomes writing a model definition, not debugging an exporter. Mobius even ships developer skills in .agents/skills/ (adding-a-new-model, reusable-components, moe-models, multimodal-models, writing-tests, writing-rewrite-rules) so an AI coding agent can do the legwork with you. Coverage This isn't a toy. The repo claims 290+ Transformers model types and 10 Diffusers component types across 40+ task types and 100+ reusable components, spanning: Category Examples Text generation Llama 2/3/4, Mistral, Qwen 2/2.5/3/3.5/3.6, Phi-3/3.5, Gemma 1/2/3/4, Granite, GPT-2, OPT, OLMo, SmolLM3 Mixture of Experts PhiMoE, GPTOSS, Mixtral, OLMoE, DeepSeek-V2/V3, Qwen2-MoE, Qwen3-MoE, Qwen3-Next, GLM-4-MoE, Arctic, DBRX, Jamba Multimodal Gemma 3/4, Phi-4MM (vision + audio + LoRA), LLaVA, InternVL2, MiniCPM-V 4.6, Qwen2.5-VL, Qwen3-VL, Pixtral Encoder-only BERT, RoBERTa, ALBERT, DeBERTa, DistilBERT, ELECTRA, XLNet Encoder-decoder BART, T5/mT5, Marian, M2M-100, Pegasus, BigBird-Pegasus Speech-to-text Whisper, Moonshine, Moonshine Streaming, FastConformer-RNNT, FunASR, GLM-ASR, Qwen3-ASR, SenseVoice Audio Wav2Vec2, HuBERT, WavLM, SpeechT5 Vision ViT, BEiT, DeiT, DINOv2, Swin, CLIP, SigLIP Diffusion Stable Diffusion (UNet + VAE + ControlNet), Flux, SD3, DiT, QwenImage / Qwen-Image-Edit-2509, HunyuanDiT, CogVideoX Adapters T2I-Adapter, IP-Adapter The five-minute version pip install -e . from mobius import build pkg = build("meta-llama/Llama-3.2-1B") pkg.save("output/llama-3.2-1b/") Static KV cache, when you know your max sequence length up front: from mobius import build, CausalLMTask task = CausalLMTask(static_cache=True, max_seq_len=2048) pkg = build("meta-llama/Llama-3.2-1B", task=task) pkg.save("output/llama-3.2-1b-static/") EP-aware optimization — the graph itself is tuned per execution provider, "each with the right set of fused kernels and lowering passes applied automatically": # CUDA: GQA fusion, SkipLayerNorm, PackQKV pkg = build("meta-llama/Llama-3.2-1B", execution_provider="cuda", dtype="f16") # WebGPU: GQA fusion, Shape ops replaced with portable alternatives pkg = build("meta-llama/Llama-3.2-1B", execution_provider="webgpu", dtype="f16") And the CLI, which is what we'll use later: mobius build --model Qwen/Qwen2.5-0.5B --output output_dir/ mobius build --model meta-llama/Llama-3.2-1B --output output_dir/ --ep cuda --dtype f16 mobius build --model openai/whisper-tiny --output output_dir/ # encoder/ + decoder/ Build-mode toggles use a cargo-style --features flag — available features are static-cache, fp8-kv-cache, prune-prefill-prefix, and text-only: mobius build --model meta-llama/Llama-3.2-1B --output output_dir/ \ --features static-cache,prune-prefill-prefix --max-seq-len 2048 --release strips build-time debug and provenance metadata to reduce saved model size, while preserving functional metadata keyed with the mobius. prefix. 2. Mobius vs. the ONNX Runtime GenAI Model Builder This is the question I get every time I demo Mobius, so let's be precise. Both are Microsoft tools, both produce ONNX, and they are not competitors — they sit at different points on the same pipeline. The ONNX Runtime GenAI Model Builder describes itself as the tool "for quickly creating optimized and quantized ONNX models within a few minutes that run with ONNX Runtime GenAI." Its output is a deployment-ready package: model.onnx plus genai_config.json plus tokenizer files, wired for the onnxruntime-genai runtime. Its architecture list is explicitly curated — AMD OLMo, ChatGLM, DeepSeek, ERNIE 4.5, Gemma, gpt-oss, Granite, Granite MoE Hybrid, HunYuan Dense V1, InternLM2, LFM2, LFM2 MoE, Llama, Mistral, Nemotron, Phi, Qwen, SmolLM3, Whisper — and the README states plainly that "it is intended for supporting the latest, popular state-of-the-art models." Mobius, by contrast, is a model-definition library: a component algebra for describing generative architectures as ONNX graphs, with a registry mapping HuggingFace model_type strings to model classes. Here's how I'd separate them: Dimension ORT GenAI Model Builder Mobius Primary goal Produce a deployment-ready GenAI package, fast Define and construct the ONNX graph itself Output contract model.onnx + genai_config.json + tokenizer, targeted at the ORT GenAI runtime ONNX model package; you choose the runtime (plain ORT sessions included) How the graph is made Per-architecture builder subclasses (LlamaModel, QwenModel, Phi3MiniModel, WhisperModel…) overriding make_layer / make_attention / make_moe Declarative onnxscript.nn.Module composition from reusable Components → Models → Tasks Breadth Curated list of ~19 popular families, text + Whisper 290+ Transformers types, 10 Diffusers component types, 40+ tasks — including vision, audio, and diffusion Extending it Add a builder subclass inside the onnxruntime-genai tree Add a model definition from existing components; shipped .agents/skills/ guide it Tuning surface Rich --extra_options for quantization and runtime behavior (QMoE, paged attention, KV-cache quantization, QDQ, CUDA/WebGPU graph capture…) --features build toggles + execution_provider= EP-aware graph lowering + dtype control Diffusion / multi-component pipelines Not the target First-class (--model Qwen/Qwen-Image-2512 builds all components) When I reach for it "I have a Phi/Llama/Qwen chat model and I want an int4 CPU/CUDA package running under ORT GenAI today" "My architecture is hybrid, unusual, multimodal, diffusion, or I need graph-level control over what gets emitted" Notably, the two overlap on real capabilities. The Model Builder also consumes GGUF and handles Qwen3.5-class features (compact state updates, recurrent-operator selection). Mobius also emits ORT-GenAI-compatible metadata — though the repo is honest about limits: for Mage-VL, "ORT GenAI export is currently rejected because the runtime cannot supply its required patch_positions input or Mage-VL's 1D decoder positions." That single line tells you exactly where the boundary sits: the Model Builder is bounded by what the GenAI runtime can express; Mobius is bounded by what ONNX can express. My rule of thumb as an advocate: if your model is on the Model Builder's supported list and you want the GenAI runtime's generation loop, use the Model Builder — it is faster and gives you a complete package. The moment you're off that list, or you need the graph itself to be a first-class artifact you can reason about and modify, Mobius is the tool. The JevONNX sample is squarely in the second category. Let's look at why. 3. The sample: converting a Jev-style decision model to CPU ONNX Repo: github.com/kinfey/JevONNX 3.1 The honest framing first Jev is TypeSafe's proprietary model. You can't download it and convert it, and this project doesn't pretend otherwise. What the community did do is interesting: n4ze3m/Qwen3.5-4B-Hmm is "an experimental open-model attempt to reproduce the central idea and request shape of the System One workflow introduced with Jev." It works by "fine-tuning Qwen3.5-4B to answer typed questions through option probabilities instead of ordinary generated text." The README of JevONNX is emphatic about the boundaries, and I want to repeat them here rather than bury them: "Hmm is not Jev, is not affiliated with TypeSafe AI, and does not reproduce Jev's proprietary model architecture, parallel sampler, performance, calibration, or type-safety guarantees. The Hmm model card explicitly states that it is less capable than Jev." And: "The reproduction is behavioral rather than architectural." The distinction, straight from the project's comparison table: Property Jev Hmm in this project Model design Native System One Model Qwen3.5-4B fine-tuned to reproduce the typed-decision concept Output mechanism Native typed probabilistic outputs First-token option-letter probabilities Multiple questions Designed for parallel sampling Jev-like request shape, implemented as one model pass per question Output types Schema-constrained structured values noul, choice, and score adapter Runtime here TypeSafe service Local ONNX Runtime CPU Guarantees As documented by TypeSafe No equivalent guarantee is claimed The mechanism is refreshingly legible: the adapter turns each typed question into an exact multiple-choice prompt, then "reads the first generated-token logits for A, B, C, and subsequent option letters and normalizes them into probabilities." No JSON parsing, no retry-on-malformed-output, no regex. The probability distribution is the answer. 3.2 Why this needs Mobius specifically Qwen3.5 is a hybrid architecture, and that's the whole reason this is a Mobius story. The exported model has 32 hybrid decoder layers. Linear-attention layers carry conv_state and recurrent_state; full-attention layers carry key/value caches. In this artifact, full-attention layers sit at indices 3, 7, 11, 15, 19, 23, 27, and 31. The practical consequence, quoted from the README: "The prompt is processed one token at a time while every present.* output is fed back into its corresponding past_key_values.* input. This differs from a conventional decoder-only example that can prefill an entire prompt in one call." That is a graph-shape problem. You cannot handwave it with a config flag — you need the exported graph's state contract to be explicit and inspectable, which is exactly what declarative construction gives you. The implementation "follows the structure of Mobius examples/text_generation.py while adding the hybrid-state handling required by Qwen3.5." 3.3 The conversion pipeline n4ze3m/Qwen3.5-4B-Hmm-Q4_K_M.gguf │ SHA-256 verification ▼ Mobius GGUF reader/importer │ metadata and tensor mapping │ Qwen3.5 hybrid graph construction │ Q4_K_M → packed quantized target storage │ CPU execution-provider optimization ▼ onnx_outputs/ ├── model.onnx ├── model.onnx.data ├── quantization_report.json ├── tokenizer.json ├── tokenizer_config.json ├── chat_template.jinja └── cpu_test_summary.json │ ▼ ONNX Runtime CPUExecutionProvider │ token-by-token hybrid-state prefill │ first-token A/B/C/… probabilities ▼ typed decision JSON response One command does the conversion: mobius build-gguf Qwen3.5-4B-Hmm-Q4_K_M.gguf \ --output onnx_outputs \ --ep cpu \ --dtype f32 \ --release Two details worth internalizing: --dequantize is intentionally not used. Keeping quantized storage "substantially reduc[es] the output size compared with a fully dequantized FP32 model." The external-data file is still ~2.6 GB — imagine it dequantized. Don't trust the preset, read the report. "Q4_K conversion can involve a lossy affine repack; inspect quantization_report.json rather than assuming source-preset fidelity." This is the kind of line that separates a demo from a deployment. 3.4 Reproducibility — the part I actually want you to copy Every pin, in a table, in the README: Component Revision GGUF repository n4ze3m/Qwen3.5-4B-Hmm GGUF revision c27fa3c627dfaced343c6ba9d3a0d00243a3be51 GGUF filename Qwen3.5-4B-Hmm-Q4_K_M.gguf GGUF SHA-256 5e03cb057049c56b421bd3c506d77fd8e0a77996bb8464148a02cfc3caac5229 Mobius revision 6b27a3f08b8b5d08ba9b14b416e3b435942bb0bd Tokenizer repository Qwen/Qwen3.5-4B Tokenizer revision 851bf6e806efd8d0a36b00ddf55e13ccb7b8cd0a The notebook builds a Mobius wheel from the pinned Git source rather than installing a prebuilt package. On a project moving at 500+ commits, that is not paranoia — that is the only way your conversion is still reproducible next month. 3.5 Running it Two files carry the project: Qwen3_5_4B_Hmm_GGUF_to_CPU_ONNX_Mobius_fixed.ipynb (the Colab conversion and validation workflow) and run_hmm_onnx.py (the standalone typed-decision runner). Run the notebook in a high-memory Colab CPU runtime; it writes to /content/onnx_outputs on Colab and .mobius_colab_run/onnx_outputs elsewhere. Then: python run_hmm_onnx.py --model-dir .mobius_colab_run/onnx_outputs python run_hmm_onnx.py --model-dir .mobius_colab_run/onnx_outputs --request request.json A request is state plus typed questions: { "state": "Help! My payouts have failed for 3 days. I need the money today.", "questions": { "is_urgent": { "type": "noul", "instructions": "Does this message convey urgency?" }, "department": { "type": "choice", "instructions": "Which team should handle this?", "criteria": { "billing": "Payments, invoicing, refunds", "technical": "Bugs, outages, integrations", "sales": "Pricing, upgrades, new accounts" } }, "priority": { "type": "score", "instructions": "How urgent is this request?", "criteria": ["Not urgent", "Normal", "Urgent", "Critical"] } } } From Python: from pathlib import Path from run_hmm_onnx import HmmOnnx model = HmmOnnx(Path(".mobius_colab_run/onnx_outputs")) response = model.decide({ "state": "Help! My payouts have failed for 3 days.", "questions": { "is_urgent": { "type": "noul", "instructions": "Does this message convey urgency?", } }, }) print(response) 3.6 The three decision types noul — a nullable-style yes/no probability; the probability of the true option: { "type": "noul", "noul": 0.9745 } choice — the highest-probability key, all normalized option probabilities, and a confidence value measuring how peaked the distribution is: { "type": "choice", "choice": "billing", "probabilities": { "billing": 0.7216, "technical": 0.2759, "sales": 0.0025 }, "confidence": 0.5823 } score — the expected numeric level, the level legend, normalized probabilities, and confidence: { "type": "score", "score": 2.6653, "legend": { "0": "Not urgent", "1": "Normal", "2": "Urgent", "3": "Critical" }, "probabilities": { "0": 0.0061, "1": 0.0361, "2": 0.2443, "3": 0.7135 }, "confidence": 0.618 } Look at that score output for a second. You don't get "this is critical." You get 2.6653 — a distribution leaning hard on Critical but with real mass on Urgent. That's a number your routing code can threshold on, log, and A/B test. It's the difference between an LLM that says it's confident and a distribution you can actually calibrate against. One constraint: Hmm is trained with 26 option letters. Larger option sets are handled by splitting them into groups of 25 and adding a none_of_these option to each group, matching the reference Hmm server strategy. 3.7 Does it actually run? Yes — the README reports the generated model executed directly on an Apple Silicon CPU with ONNX Runtime. A 4B hybrid-architecture model, converted from GGUF, running typed decisions on a laptop CPU with no service dependency. 4. What I'd tell a room of developers The System One idea is portable even where the model isn't. You can't run Jev locally, but the shape — state in, typed decisions with probabilities out — is something you can prototype today with an open model and an ONNX graph. As TypeSafe puts it, structured outputs "slot into ordinary software as fuzzy decision rules: classify, route, score, extract, or branch where hand-written logic is too brittle." That's a pattern, not a product. Probabilities are the actual product. The reason this class of model matters isn't speed alone. TypeSafe's argument is sharp: "If a model can do a task 95% of the time but doesn't say when it's in the 5%, it can't automate that task." Every engineer who has shipped an LLM feature has felt that exact wall. Set expectations honestly. JevONNX is an educational reproduction. It gives you noul/choice/score on a local CPU. It does not give you Jev's calibration, parallel sampler, or type-safety guarantees — and the project says so in its own README. Ship that caveat with your demo. Mobius is the infrastructure bet worth learning. When a new architecture shows up — hybrid attention, a novel MoE routing scheme, a three-model multimodal export — the question stops being "will the exporter support it?" and becomes "which components do I compose?" That is a much better question to be asking. Links Mobius — https://github.com/onnxruntime/mobius (docs: https://onnxruntime.github.io/mobius/) ONNX Runtime GenAI Model Builder — https://github.com/microsoft/onnxruntime-genai/tree/main/src/python/py/models JevONNX sample — https://github.com/kinfey/JevONNX Introducing System One Models & Jev — https://typesafe.ai/blog/introducing-system-one-models-and-jev Hugging face - https://huggingface.co/lokinfey/Qwen3_5_4B_Hmm_ONNX1.3KViews1like0CommentsBuilding HIPAA-Compliant Medical Transcription with Local AI
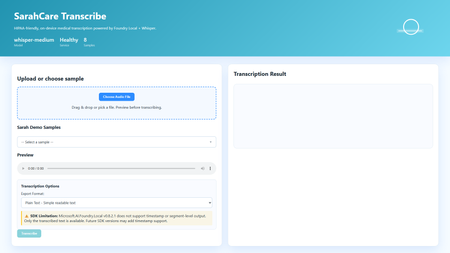
Building HIPAA-Compliant Medical Transcription with Local AI Introduction Healthcare organizations generate vast amounts of spoken content, patient consultations, research interviews, clinical notes, medical conferences. Transcribing these recordings traditionally requires either manual typing (time-consuming and expensive) or cloud transcription services (creating immediate HIPAA compliance concerns). Every audio file sent to external APIs exposes Protected Health Information (PHI), requires Business Associate Agreements, creates audit trails on third-party servers, and introduces potential breach vectors. This sample solution lies in on-premises voice-to-text systems that process audio entirely locally, never sending PHI beyond organizational boundaries. This article demonstrates building a sample medical transcription application using FLWhisper, ASP.NET Core, C#, and Microsoft Foundry Local with OpenAI Whisper models. You'll learn how to build sample HIPAA-compliant audio processing, integrate Whisper models for medical terminology accuracy, design privacy-first API patterns, and build responsive web UIs for healthcare workflows. Whether you're developing electronic health record (EHR) integrations, building clinical research platforms, or implementing dictation systems for medical practices, this sample could be a great starting point for privacy-first speech recognition. Why Local Transcription Is Critical for Healthcare Healthcare data handling is fundamentally different from general business data due to HIPAA regulations, state privacy laws, and professional ethics obligations. Understanding these requirements explains why cloud transcription services, despite their convenience, create unacceptable risks for medical applications. HIPAA compliance mandates strict controls over PHI. Every system that touches patient data must implement administrative, physical, and technical safeguards. Cloud transcription APIs require Business Associate Agreements (BAAs), but even with paperwork, you're entrusting PHI to external systems. Every API call creates logs on vendor servers, potentially in multiple jurisdictions. Data breaches at transcription vendors expose patient information, creating liability for healthcare organizations. On-premises processing eliminates these third-party risks entirely, PHI never leaves your controlled environment. US State laws increasingly add requirements beyond HIPAA. California's CCPA, New York's SHIELD Act, and similar legislation create additional compliance obligations. International regulations like GDPR prohibit transferring health data outside approved jurisdictions. Local processing simplifies compliance by keeping data within organizational boundaries. Research applications face even stricter requirements. Institutional Review Boards (IRBs) often require explicit consent for data sharing with external parties. Cloud transcription may violate study protocols that promise "no third-party data sharing." Clinical trials in pharmaceutical development handle proprietary information alongside PHI, double jeopardy for data exposure. Local transcription maintains research integrity while enabling audio analysis. Cost considerations favor local deployment at scale. Medical organizations generate substantial audio, thousands of patient encounters monthly. Cloud APIs charge per minute of audio, creating significant recurring costs. Local models have fixed infrastructure costs that scale economically. A modest GPU server can process hundreds of hours monthly at predictable expense. Latency matters for clinical workflows. Doctors and nurses need transcriptions available immediately after patient encounters to review and edit while details are fresh. Cloud APIs introduce network delays, especially problematic in rural health facilities with limited connectivity. Local inference provides <1 second turnaround for typical consultation lengths. Application Architecture: ASP.NET Core with Foundry Local The sample FLWhisper application implements clean separation between audio handling, AI inference, and state management using modern .NET patterns: The ASP.NET Core 10 minimal API provides HTTP endpoints for health checks, audio transcription, and sample file streaming. Minimal APIs reduce boilerplate while maintaining full middleware support for error handling, authentication, and CORS. The API design follows OpenAI's transcription endpoint specification, enabling drop-in replacement for existing integrations. The service layer encapsulates business logic: FoundryModelService manages model loading and lifetime, TranscriptionService handles audio processing and AI inference, and SampleAudioService provides demonstration files for testing. This separation enables easy testing, dependency injection, and service swapping. Foundry Local integration uses the Microsoft.AI.Foundry.Local.WinML SDK. Unlike cloud APIs requiring authentication and network calls, this SDK communicates directly with the local Foundry service via in-process calls. Models load once at startup, remaining resident in memory for sub-second inference on subsequent requests. The static file frontend delivers vanilla HTML/CSS/JavaScript, no framework overhead. This simplicity aids healthcare IT security audits and enables deployment on locked-down hospital networks. The UI provides file upload, sample selection, audio preview, transcription requests, and result display with copy-to-clipboard functionality. Here's the architectural flow for transcription requests: Web UI (Upload Audio File) ↓ POST /v1/audio/transcriptions (Multipart Form Data) ↓ ASP.NET Core API Route ↓ TranscriptionService.TranscribeAudio(audioStream) ↓ Foundry Local Model (Whisper Medium locally) ↓ Text Result + Metadata (language, duration) ↓ Return JSON/Text Response ↓ Display in UI This architecture embodies several healthcare system design principles: Data never leaves the device: All processing occurs on-premises, no external API calls No data persistence by default: Audio and transcripts are session-only, never saved unless explicitly configured Comprehensive health checks: System readiness verification before accepting PHI Audit logging support: Structured logging for compliance documentation Graceful degradation: Clear error messages when models unavailable rather than silent failures Setting Up Foundry Local with Whisper Models Foundry Local supports multiple Whisper model sizes, each with different accuracy/speed tradeoffs. For medical transcription, accuracy is paramount—misheard drug names or dosages create patient safety risks: # Install Foundry Local (Windows) winget install Microsoft.FoundryLocal # Verify installation foundry --version # Download Whisper Medium model (optimal for medical accuracy) foundry model add openai-whisper-medium-generic-cpu:1 # Check model availability foundry model list Whisper Medium (769M parameters) provides the best balance for medical use. Smaller models (Tiny, Base) miss medical terminology frequently. Larger models (Large) offer marginal accuracy gains at 3x inference time. Medium handles medical vocabulary well, drug names, anatomical terms, procedure names, while processing typical consultation audio (5-10 minutes) in under 30 seconds. The application detects and loads the model automatically: // Services/FoundryModelService.cs using Microsoft.AI.Foundry.Local.WinML; public class FoundryModelService { private readonly ILogger _logger; private readonly FoundryOptions _options; private ILocalAIModel? _loadedModel; public FoundryModelService( ILogger logger, IOptions options) { _logger = logger; _options = options.Value; } public async Task InitializeModelAsync() { try { _logger.LogInformation( "Loading Foundry model: {ModelAlias}", _options.ModelAlias ); // Load model from Foundry Local _loadedModel = await FoundryClient.LoadModelAsync( modelAlias: _options.ModelAlias, cancellationToken: CancellationToken.None ); if (_loadedModel == null) { _logger.LogWarning("Model loaded but returned null instance"); return false; } _logger.LogInformation( "Successfully loaded model: {ModelAlias}", _options.ModelAlias ); return true; } catch (Exception ex) { _logger.LogError( ex, "Failed to load Foundry model: {ModelAlias}", _options.ModelAlias ); return false; } } public ILocalAIModel? GetLoadedModel() => _loadedModel; public async Task UnloadModelAsync() { if (_loadedModel != null) { await FoundryClient.UnloadModelAsync(_loadedModel); _loadedModel = null; _logger.LogInformation("Model unloaded"); } } } Configuration lives in appsettings.json , enabling easy customization without code changes: { "Foundry": { "ModelAlias": "whisper-medium", "LogLevel": "Information" }, "Transcription": { "MaxAudioDurationSeconds": 300, "SupportedFormats": ["wav", "mp3", "m4a", "flac"], "DefaultLanguage": "en" } } Implementing Privacy-First Transcription Service The transcription service handles audio processing while maintaining strict privacy controls. No audio or transcript persists beyond the HTTP request lifecycle unless explicitly configured: // Services/TranscriptionService.cs public class TranscriptionService { private readonly FoundryModelService _modelService; private readonly ILogger _logger; public async Task TranscribeAudioAsync( Stream audioStream, string originalFileName, TranscriptionOptions? options = null) { options ??= new TranscriptionOptions(); var startTime = DateTime.UtcNow; try { // Validate audio format ValidateAudioFormat(originalFileName); // Get loaded model var model = _modelService.GetLoadedModel(); if (model == null) { throw new InvalidOperationException("Whisper model not loaded"); } // Create temporary file (automatically deleted after transcription) using var tempFile = new TempAudioFile(audioStream); // Execute transcription _logger.LogInformation( "Starting transcription for file: {FileName}", originalFileName ); var transcription = await model.TranscribeAsync( audioFilePath: tempFile.Path, language: options.Language, cancellationToken: CancellationToken.None ); var duration = (DateTime.UtcNow - startTime).TotalSeconds; _logger.LogInformation( "Transcription completed in {Duration:F2}s", duration ); return new TranscriptionResult { Text = transcription.Text, Language = transcription.Language ?? options.Language, Duration = transcription.AudioDuration, ProcessingTimeSeconds = duration, FileName = originalFileName, Timestamp = DateTime.UtcNow }; } catch (Exception ex) { _logger.LogError( ex, "Transcription failed for file: {FileName}", originalFileName ); throw; } } private void ValidateAudioFormat(string fileName) { var extension = Path.GetExtension(fileName).TrimStart('.'); var supportedFormats = new[] { "wav", "mp3", "m4a", "flac", "ogg" }; if (!supportedFormats.Contains(extension.ToLowerInvariant())) { throw new ArgumentException( $"Unsupported audio format: {extension}. " + $"Supported: {string.Join(", ", supportedFormats)}" ); } } } // Temporary file wrapper that auto-deletes internal class TempAudioFile : IDisposable { public string Path { get; } public TempAudioFile(Stream sourceStream) { Path = System.IO.Path.GetTempFileName(); using var fileStream = File.OpenWrite(Path); sourceStream.CopyTo(fileStream); } public void Dispose() { try { if (File.Exists(Path)) { File.Delete(Path); } } catch { // Ignore deletion errors in temp folder } } } This service demonstrates several privacy-first patterns: Temporary file lifecycle management: Audio written to temp storage, automatically deleted after transcription No implicit persistence: Results returned to caller, not saved by service Format validation: Accept only supported audio formats to prevent processing errors Comprehensive logging: Audit trail for compliance without logging PHI content Error isolation: Exceptions contain diagnostic info but no patient data Building the OpenAI-Compatible REST API The API endpoint mirrors OpenAI's transcription API specification, enabling existing integrations to work without modifications: // Program.cs var builder = WebApplication.CreateBuilder(args); // Configure services builder.Services.Configure( builder.Configuration.GetSection("Foundry") ); builder.Services.AddSingleton(); builder.Services.AddScoped(); builder.Services.AddHealthChecks() .AddCheck("foundry-health"); var app = builder.Build(); // Load model at startup var modelService = app.Services.GetRequiredService(); await modelService.InitializeModelAsync(); app.UseHealthChecks("/health"); app.MapHealthChecks("/api/health/status"); // OpenAI-compatible transcription endpoint app.MapPost("/v1/audio/transcriptions", async ( HttpRequest request, TranscriptionService transcriptionService, ILogger logger) => { if (!request.HasFormContentType) { return Results.BadRequest(new { error = "Content-Type must be multipart/form-data" }); } var form = await request.ReadFormAsync(); // Extract audio file var audioFile = form.Files.GetFile("file"); if (audioFile == null || audioFile.Length == 0) { return Results.BadRequest(new { error = "Audio file required in 'file' field" }); } // Parse options var format = form["format"].ToString() ?? "text"; var language = form["language"].ToString() ?? "en"; try { // Process transcription using var stream = audioFile.OpenReadStream(); var result = await transcriptionService.TranscribeAudioAsync( audioStream: stream, originalFileName: audioFile.FileName, options: new TranscriptionOptions { Language = language } ); // Return in requested format if (format == "json") { return Results.Json(new { text = result.Text, language = result.Language, duration = result.Duration }); } else { // Default: plain text return Results.Text(result.Text); } } catch (Exception ex) { logger.LogError(ex, "Transcription request failed"); return Results.StatusCode(500); } }) .DisableAntiforgery() // File uploads need CSRF exemption .WithName("TranscribeAudio") .WithOpenApi(); app.Run(); Example API usage: # PowerShell $audioFile = Get-Item "consultation-recording.wav" $response = Invoke-RestMethod ` -Uri "http://localhost:5192/v1/audio/transcriptions" ` -Method Post ` -Form @{ file = $audioFile; format = "json" } Write-Output $response.text # cURL curl -X POST http://localhost:5192/v1/audio/transcriptions \ -F "file=@consultation-recording.wav" \ -F "format=json" Building the Interactive Web Frontend The web UI provides a user-friendly interface for non-technical medical staff to transcribe recordings: SarahCare Medical Transcription The JavaScript handles file uploads and API interactions: // wwwroot/app.js let selectedFile = null; async function checkHealth() { try { const response = await fetch('/health'); const statusEl = document.getElementById('status'); if (response.ok) { statusEl.className = 'status-badge online'; statusEl.textContent = '✓ System Ready'; } else { statusEl.className = 'status-badge offline'; statusEl.textContent = '✗ System Unavailable'; } } catch (error) { console.error('Health check failed:', error); } } function handleFileSelect(event) { const file = event.target.files[0]; if (!file) return; selectedFile = file; // Show file info const fileInfo = document.getElementById('fileInfo'); fileInfo.textContent = `Selected: ${file.name} (${formatFileSize(file.size)})`; fileInfo.classList.remove('hidden'); // Enable audio preview const preview = document.getElementById('audioPreview'); preview.src = URL.createObjectURL(file); preview.classList.remove('hidden'); // Enable transcribe button document.getElementById('transcribeBtn').disabled = false; } async function transcribeAudio() { if (!selectedFile) return; const loadingEl = document.getElementById('loadingIndicator'); const resultEl = document.getElementById('resultSection'); const transcribeBtn = document.getElementById('transcribeBtn'); // Show loading state loadingEl.classList.remove('hidden'); resultEl.classList.add('hidden'); transcribeBtn.disabled = true; try { const formData = new FormData(); formData.append('file', selectedFile); formData.append('format', 'json'); const startTime = Date.now(); const response = await fetch('/v1/audio/transcriptions', { method: 'POST', body: formData }); if (!response.ok) { throw new Error(`HTTP ${response.status}: ${response.statusText}`); } const result = await response.json(); const processingTime = ((Date.now() - startTime) / 1000).toFixed(1); // Display results document.getElementById('transcriptionText').value = result.text; document.getElementById('resultDuration').textContent = `Duration: ${result.duration.toFixed(1)}s`; document.getElementById('resultLanguage').textContent = `Language: ${result.language}`; resultEl.classList.remove('hidden'); console.log(`Transcription completed in ${processingTime}s`); } catch (error) { console.error('Transcription failed:', error); alert(`Transcription failed: ${error.message}`); } finally { loadingEl.classList.add('hidden'); transcribeBtn.disabled = false; } } function copyToClipboard() { const text = document.getElementById('transcriptionText').value; navigator.clipboard.writeText(text) .then(() => alert('Copied to clipboard')) .catch(err => console.error('Copy failed:', err)); } // Initialize window.addEventListener('load', () => { checkHealth(); loadSamplesList(); }); Key Takeaways and Production Considerations Building HIPAA-compliant voice-to-text systems requires architectural decisions that prioritize data privacy over convenience. The FLWhisper application demonstrates that you can achieve accurate medical transcription, fast processing times, and intuitive user experiences entirely on-premises. Critical lessons for healthcare AI: Privacy by architecture: Design systems where PHI never exists outside controlled environments, not as a configuration option No persistence by default: Audio and transcripts should be ephemeral unless explicitly saved with proper access controls Model selection matters: Whisper Medium provides medical terminology accuracy that smaller models miss Health checks enable reliability: Systems should verify model availability before accepting PHI Audit logging without content logging: Track operations for compliance without storing sensitive data in logs For production deployment in clinical settings, integrate with EHR systems via HL7/FHIR interfaces. Implement role-based access control with Active Directory integration. Add digital signatures for transcript authentication. Configure automatic PHI redaction using clinical NLP models. Deploy on HIPAA-compliant infrastructure with proper physical security. Implement comprehensive audit logging meeting compliance requirements. The complete implementation with ASP.NET Core API, Foundry Local integration, sample audio files, and comprehensive tests is available at github.com/leestott/FLWhisper. Clone the repository and follow the setup guide to experience privacy-first medical transcription. Resources and Further Reading FLWhisper Repository - Complete C# implementation with .NET 10 Quick Start Guide - Installation and usage instructions Microsoft Foundry Local Documentation - SDK reference and model catalog OpenAI Whisper Documentation - Model architecture and capabilities HIPAA Compliance Guidelines - HHS official guidance Testing Guide - Comprehensive test suite documentationAgents League: The Esports-Inspired Hackathon Where AI Agents Battle for Glory
Ready to put your AI skills to the ultimate test? Agents League is here, a dynamic, esports-inspired developer challenge that brings the thrill of live competition to the world of agentic AI. Whether you're a seasoned AI developer or just getting started, this is your chance to build, compete, and win. What is Agents League? Agents League is a week-long hackathon running as part of AI Skills Fest (June 4–14, 2026). Unlike traditional hackathons, Agents League combines live AI coding battles, asynchronous project submissions, and a thriving Discord community all competing for a total prize pool of $55,000 USD. This isn't just about building it's about showcasing what's possible with agentic AI in a format that's fast, competitive, and globally accessible. Three Challenge Tracks Pick One or Compete in All 1. Creative Apps Build innovative applications using GitHub Copilot for AI-assisted development. Show off your creativity and demonstrate how AI can accelerate app creation from concept to code. 2. Reasoning Agents Create intelligent agents using Microsoft Foundry that solve complex problems through multi-step reasoning. This track is all about building agents that can think, plan, and execute. 3. Enterprise Agents Build business-ready knowledge agents integrated with Microsoft 365 Copilot, authored in Copilot Studio. Perfect for developers focused on real-world enterprise solutions. Live Microsoft Reactor Events—Don't Miss the Battles! The heart of Agents League beats through live Microsoft Reactor events. Watch experts go head-to-head in live coding battles, learn cutting-edge techniques, and get inspired for your own submissions: Event What You'll Learn Creative Apps Battle See GitHub Copilot in action as experts build innovative apps live Reasoning Agents Battle Watch multi-step reasoning agents come to life with Microsoft Foundry Enterprise Agents Battle Learn to build M365-integrated agents with Copilot Studio 👉 View the full event series Key Dates Registration Deadline: June 12, 2026, 12:00 PM PT Hacking Period: June 4–14, 2026 Submission Deadline: June 14, 2026, 11:59 PM PT What You Get Live coding battles with expert demonstrations Curated technical experiences and on-demand content Learning resources on Microsoft Learn and AI Skills Navigator Community support through Discord GitHub-based submissions for transparent, collaborative judging Why Participate? Agents League isn't just another hackathon. It's designed as a streamlined, competitive format that: ✅ Fits into your schedule with focused, time-boxed challenges ✅ Provides real-world product innovation experience ✅ Offers global accessibility—participate from anywhere ✅ Demonstrates the latest capabilities of agentic AI, including new IQ tools ✅ Connects you with a passionate developer community Ready to Enter the Arena? Register Now for Agents League Before you register: Review the Hackathon Rules and Regulations for prize categories and judging criteria Join the Microsoft Reactor event series for live battles and learning Check out the Microsoft Event Code of Conduct Join the Conversation Have questions? Want to connect with fellow competitors? Join the Agents League community on Discord and start strategizing with developers from around the world. Whether you're building creative apps, reasoning agents, or enterprise solutions—the arena awaits. May the best agent win! 🏆 Agents League hackathon is open to the public and offered at no cost. Government employees should check with their employers to ensure participation is permitted in accordance with applicable policies. Related Links: Agents League Hackathon Registration Microsoft Reactor Series AI Skills FestToken Economics: The New FinOps for Agentic AI
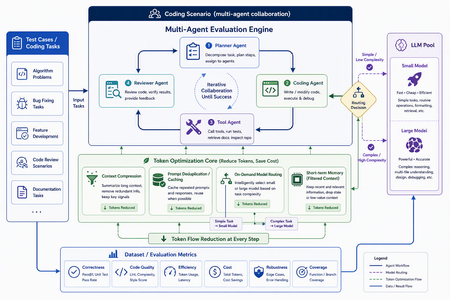
In AI applications, tokens are now cost — and token economics deserves architectural attention For a long time, AI application design started with model capability: Can the model write code? Can it reason? Can it use tools? Can it handle long context? Those questions still matter, but in the age of agentic applications, they are no longer sufficient. The more important production question is this: How many tokens does the architecture burn to complete one useful task? A classic chat application often maps one user turn to one model call. An agentic system is different. One user goal can trigger planning, retrieval, tool selection, tool execution, result interpretation, reflection, repair, and summarization. The user sees one instruction; the system may execute dozens of model calls behind the scenes. Tokens are no longer just a measure of text length. They become a measure of system design, runtime behavior, developer workflow, and business cost. GitHub Copilot’s 2026 move to usage-based billing through GitHub AI Credits captures the industry shift clearly. Usage is now aligned with token consumption, including input, output, and cached tokens. That matters because Copilot has evolved from an in-editor assistant into an agentic platform that can handle long, multi-step coding sessions across repositories. In that world, a tiny prompt and a multi-hour autonomous coding workflow should not be treated as the same economic unit. Token economics is therefore not about telling developers to “write shorter prompts.” It is about designing systems where: useful context is preserved, while noise is removed; repeated context is cached or deduplicated; simple tasks do not pay for frontier models; short-term state is managed structurally instead of copied repeatedly; every model call is metered, comparable, and governed. In short: token economics is the practice of making agentic AI economically sustainable. Scenario thinking: GitHub Copilot billing, Copilot SDK, GPT-5.5, Anthropic, and MAI-Code Model The new GitHub Copilot billing model provides a useful framing for developers. Copilot is no longer only autocomplete. It is becoming a programmable agentic platform. It can use models, call tools, work across files, stream responses, and participate in long-running coding workflows. With the GitHub Copilot SDK, developers can embed that agentic runtime into their own applications, services, and developer tools. That is powerful, but it also changes the cost model. Once an agent loop becomes programmable, token cost also needs to become programmable. If a system can plan, call tools, edit files, retry, repair, and summarize, it also needs to meter, route, cache, compress, and evaluate. EvalAgentic gives this idea a concrete playground. The project groups models into cost and capability tiers: Tier Example models Example price / 1K tokens Typical use LARGE claude-opus-4.8, gpt-5.5 $0.030 Agents, code generation, multi-step reasoning MID gpt-5.4-mini $0.012 Dialogue, summarization, extraction TINY gpt-5-mini $0.001 Classification, keyword matching, rule-like tasks This tiering lets us reason about real scenarios: GPT-5.5-class models are valuable for hard reasoning and engineering workflows, but they should not be the default for every step. Using a frontier model for simple classification is like hiring a principal architect to label folders. Anthropic high-capability models can be excellent for complex reasoning and coding, but they benefit from routing discipline. Requirements analysis, test interpretation, deployment explanation, and code generation may not need the same model tier. MAI-Code Model-style coding models should be treated as specialized capability layers. Their value is not just “better code generation”; it is deciding when code-specialized intelligence should be invoked in a larger agent pipeline. The real question is not “Which model is the best?” It is: Which model is the most economical and reliable for this step of this workflow? Four engineering techniques for saving tokens Context Compression: turn long text into executable structure Implementation principle Context Compression converts long natural-language context into the structured information an agent actually needs. Business documents are often verbose: resumes, contracts, product manuals, requirements, and support logs contain narrative text, boilerplate, repeated explanations, and low-value context. The next agent step may only need a few fields. EvalAgentic demonstrates this with a long resume-like input that is compressed into a compact JSON object. Instead of injecting the full original text into every prompt, the system extracts key fields and dynamically injects only the data required by the current task. A practical compression pipeline includes: Redundancy detection — identify long-tail text, repeated descriptions, stale history, and low-value context. Structured extraction — use Copilot or a mid-tier model to transform prose into JSON, tables, or typed schemas. Dynamic injection — inject only the fields needed for the next step. Recoverable references — preserve source pointers so compressed context remains auditable. How to evaluate Prompt token reduction before and after compression. Answer quality and task success rate. Schema fidelity and missing-field rate. Latency improvement. Cost per successful task. Compression is not summarization. Summaries are designed for humans. Structured compression is designed for agents. Prompt Deduplication / Cache: stop paying twice for the same context Implementation principle Many agent systems waste tokens because they repeatedly send the same context. The same resume, contract, repository README, user profile, API documentation, or business rule can be copied across turns and agents. Prompt Deduplication / Cache applies a simple principle: if context has already been processed, do not pay to process it again unless it has changed. A concrete design includes: compute a hash or semantic key for source context; reuse extracted structured results when content is identical or equivalent; apply a TTL for repeated entities, such as the 24-hour cache pattern shown in EvalAgentic; organize stable prompt prefixes to benefit from provider-level prompt caching where available; store shared context in an artifact store or memory layer so multiple agents do not copy the same blob. How to evaluate Cache hit rate. Cached token ratio. Duplicate prompt rate. Cost delta before and after caching. Correctness under cache, especially stale-cache failures. Caching is not “save everything forever.” Good caching knows when to reuse and when to invalidate. On-Demand Model Routing: let task complexity decide model tier Implementation principle On-Demand Model Routing routes each request to the cheapest model that can complete the task reliably. The entry point can use a rule tree, a lightweight classifier, or a hybrid complexity score. EvalAgentic’s routing tree is intentionally easy to explain: INCOMING REQUEST └─ Prompt < 500 tokens? ── YES ─→ TINY: classify / extract └─ NO ──→ multi-step reasoning? ├─ NO ─→ MID: dialogue / summary └─ YES ─→ LARGE: agent / code The engineering logic is straightforward: simple classification and keyword matching go to TINY; summarization and structured conversion go to MID; multi-step reasoning, coding, cross-file changes, and orchestration go to LARGE; code-specialized models such as MAI-Code Model can be placed in the coding phase rather than used across the whole pipeline. How to evaluate Routing accuracy. Cost per route. Quality regression by tier. Escalation rate from small models to larger models. End-to-end success rate. Routing does not mean “always use the smallest model.” It means frontier intelligence is reserved for the steps where it actually changes the outcome. Short-term Memory: preserve state instead of replaying history Implementation principle Short-term Memory controls context growth across multi-turn and multi-agent workflows. Without it, agents often replay the full conversation history, full tool outputs, and full intermediate reasoning on every turn. The context grows; quality may not improve; the bill definitely does. A better design stores state structurally: user goal; current plan; tool outputs and references; failure reasons; next actions; handoff artifacts between agents. In a multi-agent coding pipeline, the Requirements Agent should hand off a structured spec. The Coding Agent should read that spec, not the entire prior conversation. The Testing Agent should consume testable artifacts, not every word produced by the Coding Agent. How to evaluate Context growth curve across turns. Memory retrieval precision. Rework rate caused by missing state. Recovery quality after failed steps. Average input tokens per turn. Short-term memory is not about remembering everything. It is about remembering the next useful thing. EvalAgentic as a concrete evaluation example EvalAgentic is effective as an evangelism project because it turns token economics into an observable before/after system. The architecture has five layers: Frontend — frontend/index.html provides Tabs A / B / C, live SSE logs, and before/after charts. API — backend/server.py exposes FastAPI routes and Server-Sent Events streaming. Orchestration — eval.py handles A/B evaluation; coding_agents.py handles the multi-agent coding scenario. Core — compressor.py, router.py, gh_models.py, and token_meter.py implement compression, routing, Copilot SDK calls, and token metering. Providers — GitHub Copilot SDK and Microsoft Agent Framework provide model access and agent orchestration. Tab A: Compression comparison Tab A compares long-form context before and after structured compression. The key message is that token saving does not come from writing a clever sentence. It comes from converting verbose context into a structured artifact that downstream agents can consume efficiently. Tab B: On-demand model routing Tab B demonstrates that cost is not only about raw token count. If a system routes simple tasks to cheaper tiers and reserves expensive models for complex reasoning, total cost can fall even if some token counts increase. This is a subtle but important point: token economics is not token starvation; it is model portfolio optimization. Tab C: Coding scenario — multi-agent with Agent Framework Tab C is the most persuasive demo. The same deliverable — a Taobao-like goods-list site with HTML + JavaScript frontend, Flask backend, and Docker deployment — is produced twice by a four-agent pipeline: Requirements Agent; Coding Agent; Testing Agent; Deployment Agent. The before pipeline uses no compression and sends every agent to GPT-5.5 / LARGE. The after pipeline injects a compressed JSON spec and uses on-demand routing: requirements can use MID, coding can use LARGE, testing can use MID, and deployment can use TINY. This mirrors real enterprise development. Architecture and complex code generation may deserve frontier models. Test interpretation, deployment packaging, and simple validation often do not. Summary and refinement based on the project diagrams The EvalAgentic README describes three important visuals: the architecture flow, the routing tree, and the token-meter design. Together, they form a governance loop: User Scenario ↓ Context Compression ↓ Prompt Deduplication / Cache ↓ On-Demand Model Routing ↓ Short-term Memory ↓ Token Metering & Budget Actions ↓ Before / After Evaluation Optimize the path, not only the prompt Many teams start token optimization by editing prompt wording. That helps, but the largest waste usually lives in the execution path: how many calls are made, how much context is repeated, how often tools retry, and whether every step uses the same expensive model. EvalAgentic makes the path visible through A/B comparisons. Token Meter is the control plane of cost governance EvalAgentic’s token_meter.py uses a non-invasive interceptor pattern: INTERCEPTOR (@token_meter) ↓ COUNTER CORE: accounting / budget threshold / trigger ↓ ACTION HUB: throttle (>80% budget) / rollback (>budget) This is the right architectural instinct. Production systems need thresholds, throttling, rollback, and traceability. Without those controls, one retry loop can quietly turn a small user request into a budget incident. Cost metrics must be evaluated with quality metrics A system that cuts cost by 80% but drops success rate by 50% is not optimized. It is broken more cheaply. The evaluation matrix should combine cost, quality, latency, and reliability: Dimension Metric Why it matters Cost Cost per successful task Measures the real unit economics Token Input / output / cached tokens Identifies compression and cache opportunities Quality Pass rate / regression rate Ensures cheaper tiers do not break outcomes Efficiency Latency / retry count Prevents cheap models from causing expensive retries Governance Budget breach / rollback count Validates runtime control Narrative A simple three-line narrative works well for demos: Token is no longer a technical detail. It is the bill of your architecture. EvalAgentic shows the same scenario before and after cost-aware design. The goal is not to make models cheaper; the goal is to make agent systems economically governable. For a developer audience, the sharper version is: A good agent does not use the biggest model everywhere. It uses the right intelligence at the right step, with the right context, under the right budget. Practical recommendations for real projects Establish a token baseline first. Measure input, output, retries, tool calls, and cost per scenario before optimizing. Make compression a component, not a prompt habit. Define schemas, cache policies, and fallback behavior. Introduce a model routing matrix. Route by task type, complexity, risk, latency, and cost. Define handoff contracts between agents. Pass structured artifacts, not endless conversation history. Evaluate every optimization with A/B tests. Compare cost, quality, latency, and stability. Add budget actions. Throttle at a threshold, rollback on breach, and add circuit breakers for failed retries. Closing: token economics is the second curve of agent engineering The first phase of AI application development was about calling models. The second phase was about putting models into products. The next phase of agentic AI is about running those systems reliably, affordably, and governably. EvalAgentic matters because it turns Context Compression, Prompt Deduplication / Cache, On-Demand Model Routing, and Short-term Memory into something developers can run, compare, and explain. It moves token economics from opinion to instrumentation. Future AI applications will not only ask: How smart is this agent? They will ask: How many tokens does it spend per completed task? Which model did it use? Did it hit cache? Did retries run away? Did the system reserve frontier intelligence for the steps that deserved it? References kinfey/EvalAgentic GitHub Copilot is moving to usage-based billing Updates to GitHub Copilot billing and plans Copilot SDK - GitHub Docs8.4KViews4likes0CommentsKVStream: Smarter Memory Management for On-Device Language Model Inference
On-Device LLMs Are Starved for Memory Intelligence The shift toward on-device language model inference is accelerating. Platforms like Microsoft's Foundry Local, Ollama, and llama.cpp now make it possible to run capable models such as Phi-3-mini and Llama 3 entirely on local hardware, no cloud dependency, no data leaving the device. This is a meaningful leap for privacy-sensitive applications, offline scenarios, and latency-critical workloads. But on-device/edge inference surfaces a class of performance problems that cloud-based serving largely abstracts away. Memory is the bottleneck. When a language model generates text, it builds a Key-Value (KV) cache a memory structure that stores intermediate attention states so it doesn't have to recompute them for every new token. On a cloud server with hundreds of gigabytes of HBM (Hardware Bandwidth Memory), wasting KV cache memory is a rounding error. On a developer workstation or a GPU/NPU-equipped edge device, it is the difference between a usable system and a stalled one. The typical on-device runtime allocates KV cache memory statically and per-sequence. This creates three concrete problems: Fragmentation and over-reservation. A model has no way of knowing in advance how long a response will be. So, runtimes allocate a worst-case maximum context window of memory for every request even if the actual response is short. The result is a fragmented memory pool where most of the reserved space sits idle while queued requests wait for a slot to open. Research confirms the scale of this waste: production settings with variable-length or concurrent requests typically discard 60–80% of KV memory under monolithic static allocation; paged designs reduce this to under 5%. No batching across requests. Most local runtimes process one request at a time. If you fire four concurrent questions at Foundry Local or Ollama without a batching layer, they queue sequentially. Throughput scales linearly with latency instead of benefiting from the parallel processing the underlying hardware supports. Continuous batching the technique of admitting new sequences mid-generation rather than waiting for the whole batch to drain has been shown to yield up to 36.9× throughput improvement in the original Orca study, with production deployments regularly achieving 2–5× over static batching. Redundant computation. Real-world applications consistently include a shared system prompt instructions that tell the model how to behave. With a RAG pipeline or a chat assistant, the same few hundred tokens get prefilled on every single request, burning compute and TTFT (time-to-first-token) unnecessarily. External prefix caching layers addressing this problem have demonstrated up to 15× throughput improvement on multi-round workloads. These are not hypothetical inefficiencies. In practice, they translate to sluggish multi-turn conversation, poor throughput when multiple users or agent loops share the same local model, and wasted hardware potential on capable machines that could be doing much more. Crucially, while some of the cloud-scale inference engines embed these techniques internally, there is no equivalent orchestration layer for on-device runtimes a gap that enterprise deployments and the research community are now actively calling. Introducing KVStream: A Middleware Layer for Local LLM Runtimes KVStream is a lightweight Python middleware that sits between the application and any local LLM runtime, adding production-grade memory management and scheduling without requiring you to modify the backend or the client. The design principle is deliberate: KVStream is not a new inference engine. It does not replace Foundry Local or any other runtime. Instead, it solves the orchestration layer that on-device runtimes currently leave unaddressed the gap between a single model server and an application that expects the reliability and throughput of a managed serving system. KVStream exposes a fully OpenAI-compatible API on http://localhost:8080/v1. Any existing client the openai Python SDK, LangChain, httpx, or a curl command connects to it without modification. The backend continues to run unchanged. Architecture KVStream is composed of four cooperating subsystems. Understanding how they interact clarifies why the gains are meaningful and composable. 1.Paged KV-Cache Allocator: Inspired by the paged attention mechanism, KVStream manages KV cache memory as a pool of fixed-size pages (or blocks), each holding a configurable number of token states (default: 16 tokens per block). Rather than reserving a contiguous worst-case buffer per sequence, the allocator assigns pages on demand and reclaims them when a sequence finishes. Each sequence owns a logical page table, a mapping from logical page indices to physical block slots. Pages can be shared across sequences (enabling prefix deduplication) and migrated between GPU and CPU (enabling pre-emption). For Foundry Local and Ollama, this operates in soft-inject mode, the page table controls admission and logical accounting, while the actual KV tensors stay inside the backend. For llama.cpp, which exposes a /slots API for saving and restoring raw KV state, KVStream can operate in hard-inject mode, it manages a real tensor pool and performs zero re-compute cache reuse by physically restoring KV state between requests. 2.Continuous Batching Scheduler: The scheduler merges multiple queued sequences into a single batched forward pass, up to a configurable max_batch_size. Critically, it uses continuous batching new sequences can be admitted mid-generation, filling slots vacated by completed requests rather than waiting for the entire batch to finish. Two scheduling priorities are supported: fcfs (first-come, first-served): straightforward FIFO, best for fairness. sjf (shortest-job-first): minimizes average TTFT by prioritizing requests with shorter expected output lengths. When GPU page blocks are exhausted and a new sequence must be admitted, the scheduler applies a preemption policy: swap: the lowest-priority active sequence's pages are migrated to CPU RAM. The sequence resumes when GPU blocks become available again. recompute: pages are freed and the sequence is re-queued from scratch, lower memory overhead, higher latency for the preempted request. 3.Prefix Cache: The prefix cache deduplicates the KV computation for any shared token prefix across requests like system prompts, few-shot examples, RAG preambles, or any stable instruction block. The mechanism works in three steps: After a request completes its prefill phase, KVStream hashes the prompt tokens in block-aligned chunks and stores the canonical block table for that prefix. On a subsequent request whose prompt starts with the same prefix, the new sequence forks the canonical block table via copy-on-write, no re-computation occurs. Entries expire after a configurable TTL (default: 1 hour), or can be evicted manually. The practical consequence: in any application with a stable system prompt, only the first request pays the prefill cost for that prompt. Every subsequent request skips it entirely, reducing TTFT in proportion to the length of the shared prefix. 3.OpenAI-Compatible Proxy KVStream wraps all of the above behind a standard /v1/chat/completions interface. It handles both streaming (SSE) and non-streaming responses, translates between the OpenAI request format and the backend's native API, and serves a /health, /status, and /metrics endpoint for observability. The /status endpoint returns live scheduler and memory state: { "scheduler": { "waiting": 2, "running": 8, "swapped": 0, "gpu_blocks_free": 184, "gpu_utilization": 0.281 }, "prefix_cache": { "cached_prefixes": 3, "total_prefix_hits": 12, "cached_tokens": 768 } } A Prometheus-compatible /metrics endpoint is also available, with a pre-configured Grafana dashboard included in the Docker Compose stack. Getting Started with Foundry Local: Microsoft's Foundry Local is the primary integration target for KVStream. Foundry Local provides a high-quality on-device inference runtime with strong model support (Phi-3-mini, Phi-3.5, and others), NPU acceleration, and direct integration with the Windows AI platform. KVStream's Foundry backend adds continuous batching and prefix caching on top of that foundation without any changes to the Foundry runtime itself. Installation: pip install kvstream Start the KVStream Proxy: # 1. Start Foundry Local (if not already running) foundrylocal serve # 2. Start KVStream in front of it kvstream serve --backend foundry --model phi-3-mini --port 8080 KVStream's Foundry backend includes auto-discovery, if Foundry Local assigns an ephemeral OS port (which it typically does), KVStream scans localhost to locate the active service automatically, so you do not need to hardcode the backend port. Connect your existing client — unchanged: from openai import OpenAI client = OpenAI( base_url="http://localhost:8080/v1", api_key="not-required", ) response = client.chat.completions.create( model="phi-3-mini", messages=[ {"role": "system", "content": "You are a helpful assistant."}, {"role": "user", "content": "Explain paged attention in simple terms."}, ], max_tokens=512, ) print(response.choices[0].message.content) Any client that speaks the OpenAI protocol like LangChain, httpx, or a raw HTTP call, connects here without modification. Maximize prefix cache hits: Put the system prompt first; KVStream caches it after the first request and skips its computation for every subsequent one. import asyncio from openai import AsyncOpenAI client = AsyncOpenAI(base_url="http://localhost:8080/v1", api_key="not-required") SYSTEM = "You are an expert assistant specialized in on-device AI." async def ask(question: str) -> str: r = await client.chat.completions.create( model="phi-3-mini", messages=[ {"role": "system", "content": SYSTEM}, # cached after first call {"role": "user", "content": question}, ], max_tokens=256, ) return r.choices[0].message.content async def main(): questions = [ "What is NPU acceleration?", "How does Phi-3-mini differ from larger models?", "What is token streaming?", ] # KVStream batches these automatically; system prompt computed once answers = await asyncio.gather(*[ask(q) for q in questions]) for q, a in zip(questions, answers): print(f"Q: {q}\nA: {a}\n") asyncio.run(main()) Tuning memory for hardware: The single most impactful configuration knob is the GPU block pool size. For soft-inject mode (Foundry Local, Ollama), this controls admission concurrency, not actual VRAM allocation by KVStream. A practical starting table is as follows, Device VRAM / RAM num_gpu_blocks Suitable models (E.g.,) 4 GB 64 phi-3-mini 8 GB 128 llama3-8b, mistral-7b 16 GB 256 llama3-8b (q8) 24 GB 512 llama3-70b (q4), mixtral Via YAML configuration: # kvstream.yaml backend: type: foundry model: phi-3-mini memory: num_gpu_blocks: 128 num_cpu_blocks: 256 block_size: 16 scheduler: max_batch_size: 8 preemption_policy: swap priority: fcfs prefix_cache: enabled: true ttl_seconds: 3600 min_match_tokens: 16 Benchmarking KVStream ships with a built-in benchmarking command: kvstream bench \ --url http://localhost:8080 \ --model phi-3-mini \ --concurrency 8 \ --prompt-len 128 \ --output-len 64 \ --total-requests 100 Example output: ┌──────────────────────────┐ │ KVStream Benchmark │ ├──────────────┬───────────┤ │ Requests │ 100 │ │ Concurrency │ 8 │ │ Errors │ 0 │ │ Throughput │ 12.4 req/s│ │ p50 │ 612 ms │ │ p99 │ 1840 ms │ └──────────────┴───────────┘ KVStream covers the most common local inference runtimes today Foundry Local, Ollama, llama.cpp, and LM Studio through a single, consistent interface. If you are building on Foundry Local and running into the throughput or memory fragmentation issues described here, KVStream is designed to slot in with a single command and zero changes to your application code. pip install kvstream kvstream serve --backend foundry --model phi-3-mini The full integration guide, configuration reference, and Docker deployment instructions are available in the KVStream Documentation on Github. We are always looking to improve! If you want to help make KVStream even better, check out our Contributing Guide to get started on your first pull request.482Views0likes1CommentHybrid AI Agents in Python: Routing Between Foundry Local and Microsoft Foundry
Why hybrid, and why now If you build AI features today, you are caught between three forces. Users want low latency and strong privacy. Product teams want frontier reasoning capability. Finance teams want predictable cost. No single model satisfies all three. Run everything on a small on-device model and you bottleneck on complex questions. Send everything to a frontier cloud model and you pay for trivial requests, leak sensitive data across a network boundary, and add hundreds of milliseconds of latency to greetings. The pragmatic answer is hybrid inference: a lightweight local model classifies every request first, simple or sensitive ones stay on the device, and only the genuinely hard or frontier-capability requests escalate to the cloud. Microsoft now ships both halves of that pattern as supported Python SDKs — foundry-local-sdk for on-device inference and azure-ai-projects for Microsoft Foundry cloud models. This post walks through a working reference implementation that combines them behind a single ask() call. The full source is at github.com/leestott/fl-mixedmodel. It is Python-only, secretless by design, and ships with a Gradio diagnostics UI, a CLI demo mode, and a full pytest suite. The contract: one schema, two paths The most important architectural decision is that callers never know which path served a request. Every response, local or cloud, returns the same dataclass: class InferencePath(str, Enum): LOCAL = "local" CLOUD = "cloud" LOCAL_FALLBACK = "local_fallback" # cloud attempted, fell back to local CLOUD_FALLBACK = "cloud_fallback" # local attempted, fell back to cloud @dataclass class AgentResponse: answer: str path: InferencePath model: str reason: str confidence: float latency_ms: float correlation_id: str prompt_tokens: Optional[int] = None completion_tokens: Optional[int] = None fallback: bool = False fallback_reason: Optional[str] = None metadata: dict = field(default_factory=dict) This is what makes the design honest. The router can change, the cloud model can be swapped from gpt-4o to gpt-5.4 , fallback policies can flip — and the calling code never breaks. The four InferencePath values give you full observability without leaking implementation details into the API surface. Architecture in one diagram ┌─────────────┐ prompt ┌──────────────────────────┐ │ caller │ ──────────► │ HybridAgentService │ └─────────────┘ │ .ask(prompt) │ └────────────┬─────────────┘ │ ┌────────────▼─────────────┐ │ RoutingPolicy │ │ 1. Heuristic gate │ │ 2. Local router LLM │ │ 3. Hard policy gates │ └─────┬─────────────┬──────┘ │ │ LOCAL ◄┘ └► CLOUD │ │ ┌──────────▼──┐ ┌──────▼───────┐ │ Foundry │ │ Microsoft │ │ Local SDK │ │ Foundry │ │ (phi-4-mini)│ │ (gpt-5.4) │ └─────────────┘ └──────────────┘ Best practice: the two-stage router pattern Before walking through the implementation, it is worth stating the design pattern explicitly, because it is the part that generalises beyond this specific repo. The cleanest design for hybrid inference is a two-stage router. Stage 1 — local router. A small local model performs intent and complexity classification first. It does not answer the question; it decides where the question should go. Stage 2 — route the answer. If the prompt is simple, private, latency-sensitive, or clearly within local capability, route to a local task model on the device. If the prompt is complex, needs deeper reasoning, a larger context window, or a capability unavailable locally, escalate to a cloud frontier model in Microsoft Foundry. Microsoft's current guidance for the cloud side is to use the Responses API and choose one of two control modes: Pass a specific deployment name (for example gpt-5.4 ) when you want deterministic control over which model serves the request, which is the right choice for regulated workloads, repeatable evaluations, or cost ceilings. Pass model-router as the deployment when you want Microsoft Foundry to automatically select the best available cloud model for each request. This is a sensible default for general-purpose agents where you would rather let the platform optimise the model choice as new ones are released. The reference repo exposes both as environment variables so you can switch without code changes: # .env.example FOUNDRY_CLOUD_MODEL_DEPLOYMENT=gpt-5.4 # deterministic FOUNDRY_CLOUD_ROUTER_DEPLOYMENT=model-router # auto-select Best practice: pin the right SDK versions Two SDKs do the heavy lifting and both have had recent breaking changes, so version discipline matters. Local development — foundry-local-sdk . The current public guidance is to use the Foundry Local SDK package foundry-local-sdk , which provides model discovery, download, cache, load, unload, chat completions, embeddings, audio transcription, and an optional built-in web service. Use version 1.1.0, released on 5 May 2026. Earlier versions used an OpenAI-compatible client surface that has since been replaced by the FoundryLocalManager → load_model → get_chat_client → complete_chat chain shown above. Pin it explicitly: # requirements.txt foundry-local-sdk>=1.1.0 Cloud orchestration and agents — azure-ai-projects . For cloud-side orchestration, Microsoft's current Python guidance is to use azure-ai-projects , which the docs describe as part of the Microsoft Foundry SDK and as the entry point for agents, deployments, connections, datasets, evaluations, and an OpenAI-compatible client returned by get_openai_client() . The current PyPI listing shows azure-ai-projects 2.1.0. Pin it explicitly: # requirements.txt azure-ai-projects>=2.1.0 azure-identity>=1.17.0 If you find yourself reading old samples that import azure.ai.inference as the cloud entry point, or that initialise Foundry Local through a raw openai.OpenAI(base_url=...) client, you are looking at pre-2026 patterns. The current shape is what the reference repo uses: FoundryLocalManager.initialize(Configuration(...)) for the device and AIProjectClient(...).get_openai_client() for the cloud. Stage 1: a deterministic privacy gate Before any model touches a prompt, a deterministic heuristic classifier scans for sensitive patterns — passwords, API keys, SSN/NHS numbers, PII signals, explicit "do not share" flags. If the heuristic returns PrivacyClass.RESTRICTED , the prompt is forced local. The router LLM is not called. The cloud provider is not called. The decision is auditable from a single regex pass. # app/routing/policy.py def decide(self, prompt: str, correlation_id: str = "") -> RoutingDecision: hint, privacy, complexity, h_reason = self._heuristic.classify(prompt) # Hard gate: restricted content never leaves the device if privacy == PrivacyClass.RESTRICTED: return self._make_decision( target=RouteTarget.LOCAL, confidence=1.0, reason=f"Policy hard-gate: {h_reason}", privacy=privacy, complexity=complexity, deterministic=True, correlation_id=correlation_id, ) # Hard gate: very high complexity always goes to cloud if complexity == ComplexityBand.VERY_HIGH: return self._make_decision( target=RouteTarget.CLOUD, confidence=1.0, reason="Policy hard-gate: very_high complexity requires frontier model", ... ) This is the most important responsible-AI control in the whole system. If your privacy review depends on an LLM correctly classifying every prompt, you do not have a privacy control — you have a probability distribution. Deterministic gates first, model judgement second. Stage 2: a local LLM as the router For everything that passes the privacy gate, a small local model classifies whether the prompt needs frontier capability. This is the bit that surprises most engineers: you can do useful routing with a 4B parameter model running on a laptop CPU. The router does not need to answer the question. It only needs to classify it. The reference implementation uses phi-4-mini via Foundry Local. Initialising it is two lines: # app/providers/local_provider.py (excerpt) from foundry_local import FoundryLocalManager from foundry_local.models import Configuration self._manager = FoundryLocalManager.initialize( Configuration(app_name="hybrid-agent") ) self._router_model = self._manager.load_model(self._config.local_router_alias) self._chat_client = self._router_model.get_chat_client() response = self._chat_client.complete_chat( messages=[ {"role": "system", "content": ROUTER_SYSTEM_PROMPT}, {"role": "user", "content": prompt}, ], ) The router prompt asks for a strict JSON response: { "target": "local|cloud", "confidence": 0.0-1.0, "complexity": "low|medium|high|very_high", "reason": "..." } . The application parses it, applies the confidence threshold from config (default 0.6), and falls back to the heuristic decision if the router LLM is unsure or its JSON is malformed. The router never blocks the answer path — that is a deliberate reliability choice. Cloud inference via Microsoft Foundry When the policy returns RouteTarget.CLOUD , the request goes through AIProjectClient , which gives you an openai.OpenAI -compatible client wired to your Foundry project with DefaultAzureCredential . No API keys. No secrets in .env . # app/providers/cloud_provider.py (excerpt) from azure.ai.projects import AIProjectClient from azure.identity import DefaultAzureCredential self._project = AIProjectClient( endpoint=self._config.foundry_project_endpoint, credential=DefaultAzureCredential(), ) self._openai_client = self._project.get_openai_client() response = self._openai_client.chat.completions.create( model=self._config.foundry_cloud_model_deployment, # e.g. "gpt-5.4" messages=messages, max_completion_tokens=max_tokens, ) A subtle gotcha worth flagging: gpt-5 and o-series deployments reject the legacy max_tokens parameter and require max_completion_tokens . They also reject custom temperature values. The reference repo handles this by trying the new parameter first and falling back to the legacy one only when the API returns the specific unsupported parameter error. That keeps the same code working against older deployments without forking the provider. Graceful degradation: the fallback paths Hybrid systems fail in interesting ways. The cloud can be down. The local model can throw because the GPU ran out of memory. A reasoning model can return an empty completion. The service handles all of these by attempting the alternative path and labelling the response so observability stays honest: Cloud route fails → local fallback. The response carries path=LOCAL_FALLBACK , fallback=true , and a populated fallback_reason . The user gets an answer instead of an error. Local route fails → cloud fallback, but only if privacy class is not RESTRICTED. A sensitive prompt that the local model could not handle never leaks to the cloud as a fallback. It returns a clear error instead. This is the second hard gate in the system. Both fail. A structured error response with a correlation ID, never a stack trace. That last rule — fallback respects privacy class — is the kind of decision that is easy to skip and impossible to bolt on later. Encode it once in the service layer and your privacy reviewers will thank you. What it looks like in practice The diagnostics panel in the Gradio UI shows the routing decision live: path, model, confidence, latency, privacy class, complexity band, and the full JSON response. Five canonical scenarios shake out the entire decision tree: "hello" → path=local, confidence=1.0, complexity=low . Heuristic only. No router LLM call. ~3 seconds end-to-end with phi-4-mini cached. "explain transformer self-attention in depth with maths" → path=cloud, model=gpt-5.4, complexity=high . Router LLM classifies, hard gate confirms. "my password is hunter2, suggest a stronger one" → path=local, privacy=restricted, deterministic=true . Privacy gate fires before any model sees it. "summarise this 8 KB document" with cloud unavailable → path=cloud_fallback (local handles it, response is labelled). Complex prompt with local model error → path=local_fallback , fallback_reason populated. You can reproduce all five without any models installed by running python -m app.main --demo . The demo mode swaps the providers for deterministic stubs so you can validate the routing logic and the response schema in under a second on any machine. Operational lessons learned Some things the reference implementation only gets right because it got them wrong first: Pick a non-reasoning model for the router. Reasoning-tuned local models (Phi-4-reasoning, o-style) wrap their output in <think> blocks and blow your JSON parser. phi-4-mini is faster and more reliable for classification. Cache the local model. First load can take 30–60 seconds while Foundry Local downloads weights. Initialise the service once at process startup, not per request. Use correlation IDs everywhere. The service attaches one per request and the structured JSON logger emits it on every event. When you are debugging a fallback path across two model providers, this is the difference between five minutes and five hours. Run the privacy heuristic on every fallback path too. A naive implementation might route locally, fail, and then send the same sensitive prompt to the cloud as a "graceful" fallback. That is not graceful, it is a data leak. Keep configuration in .env and out of code. Privacy mode, fallback toggles, confidence threshold, model aliases — all environment-driven. The config.py module is the only place that reads them. Responsible AI in a hybrid topology Hybrid does not make responsible AI harder, but it does make it different. Three controls earn their keep: Data residency by default. The local path keeps prompts and answers on the device. For RESTRICTED content this is mandatory; for everything else it is a free latency and cost win. Auditability. Every routing decision is logged with the deterministic reason, the heuristic class, the router LLM output, the confidence, and the correlation ID. You can answer "why did this prompt go to the cloud?" months later. Keyless auth. DefaultAzureCredential means there is no API key to leak, rotate, or commit by accident. The repo's .gitignore , SECURITY.md , and pre-push checklist enforce this end-to-end. Try it Five minutes, no Azure account needed for the demo: git clone https://github.com/leestott/fl-mixedmodel.git cd fl-mixedmodel python -m venv .venv .venv\Scripts\activate # Windows # source .venv/bin/activate # macOS / Linux pip install -r requirements.txt python -m app.main --demo # all five scenarios, no models required To run with real models, install Foundry Local, copy .env.example to .env , set your FOUNDRY_PROJECT_ENDPOINT , then: az login python -m app.main --ui --port 7860 Where to go next Repository: github.com/leestott/fl-mixedmodel — full source, tests, specification, screenshots. Foundry Local SDK: pypi.org/project/foundry-local-sdk and the Foundry Local docs. Azure AI Projects SDK: pypi.org/project/azure-ai-projects and the Microsoft Foundry docs. Azure Identity: DefaultAzureCredential reference. Phi-4-mini: Phi-4-mini on Hugging Face. Key takeaways The best-practice pattern is a two-stage router: local model classifies first, then either a local task model or a Microsoft Foundry cloud model answers. For cloud control, use the Responses API with either a named deployment (deterministic) or model-router (auto-select). Pin foundry-local-sdk >= 1.1.0 (5 May 2026) and azure-ai-projects >= 2.1.0 . The 2026 SDK surfaces are not backwards-compatible with pre-2026 samples. Hybrid inference is a routing problem, not a model problem. A small local model is enough to classify the request. Deterministic privacy gates beat probabilistic ones. Code the rules; let the LLM judge only what is left. Return the same response schema from every path. Label fallbacks honestly. Carry a correlation ID everywhere. Keep auth keyless with DefaultAzureCredential and your .env out of git. Test the routing decisions, not just the model outputs. Demo mode and a strong pytest suite pay back every time you swap a model. Hybrid AI is not a compromise between local and cloud. It is the supervisor pattern applied to inference — fast and private where you can be, frontier where you have to be, observable everywhere. The hard part is the contract, not the models.611Views1like0CommentsBuilding an On-Device Voice Assistant with Microsoft Foundry Local
Why on-device voice still matters Most "voice AI" tutorials assume your audio leaves the machine. You ship a WAV to Whisper-API, your transcript to GPT-4, and a synthesized response back over the wire. That works — but it also means three round trips, three per-token bills, and three places your user's voice gets logged. The new wave of small, hardware-optimised models changes the trade-off. NVIDIA's Nemotron Speech Streaming En 0.6B is a 600M-parameter streaming ASR model published into the Microsoft Foundry Local catalog. Paired with a small chat model like qwen2.5-0.5b or phi-4-mini , you can run the entire capture → transcribe → reason → respond loop in-process on a developer laptop, with no API keys and no network egress. This post walks through how the fl-nemotron sample does it, the SDK pitfalls we hit on the way, and the design decisions that made the pipeline reliable. What we're building A browser-hosted assistant served by FastAPI at http://127.0.0.1:8000 . The page captures microphone audio, posts it to /api/transcribe , then streams the chat reply back over Server-Sent Events from /api/chat . All inference runs locally through two Foundry Local models loaded into the same process. The shape of the pipeline: Microphone (browser MediaRecorder) │ WebM/Opus blob ▼ Client-side WAV encoder (16 kHz, mono, PCM-16) │ multipart/form-data ▼ FastAPI /api/transcribe │ ▼ Nemotron Speech Streaming En 0.6B (Foundry Local audio client) │ transcript text ▼ Chat LLM e.g. qwen2.5-0.5b (Foundry Local chat client) │ streamed tokens ▼ FastAPI /api/chat → SSE → browser bubble The version that bit us: foundry-local-sdk >= 1.1.0 Before any code, the single most important fact about this project: The Nemotron Speech Streaming model only appears in the Foundry Local 1.1.x catalog. Older SDKs (0.5.x / 0.6.x) cannot resolve the alias nemotron-speech-streaming-en-0.6b and fail with model not found . The module name also changed in 1.1.0 — it is now foundry_local_sdk (with the underscore- sdk suffix), not foundry_local . The pip wheel for foundry-local-core is bundled, so there is no separate MSI / winget install to worry about. Pin it explicitly: pip install --upgrade "foundry-local-sdk>=1.1.0,<2" And verify before anything else: python -c "import importlib.metadata as m; print('sdk', m.version('foundry-local-sdk'))" # expect: sdk 1.1.0 Loading both models from one manager The 1.1.x SDK exposes a single FoundryLocalManager that owns the runtime. Each loaded model gives you back a per-model OpenAI-compatible client — get_chat_client() for text models and get_audio_client() for ASR. There is no need to bring your own openai Python package; the SDK ships its own thin client. The wrapper used in the repo ( src/foundry_client.py ) does this: from foundry_local_sdk import Configuration, FoundryLocalManager FoundryLocalManager.initialize(Configuration(app_name="fl-nemotron")) manager = FoundryLocalManager.instance chat_model = manager.load_model("qwen2.5-0.5b") stt_model = manager.load_model("nemotron-speech-streaming-en-0.6b") chat_client = chat_model.get_chat_client() audio_client = stt_model.get_audio_client() Both models are downloaded on first use into the Foundry Local cache and stay resident for the lifetime of the process. On a laptop with 16 GB RAM, the combined working set sits comfortably under 4 GB. The transcription surprise The first naive approach was the obvious one: with open(wav_path, "rb") as f: result = audio_client.transcribe(file=f, model="nemotron-speech-streaming-en-0.6b") That call fails on Nemotron. The bundled ONNX Runtime GenAI in foundry-local-core does not register the nemotron_speech multi-modal model type that the standard AudioClient.transcribe() path tries to instantiate. The error surfaces as a cryptic model-type registration failure deep inside the native runtime. The fix is to use the streaming session API instead — a different native entry point ( core_interop.start_audio_stream ) that the streaming model does support. The repo isolates this in src/_nemotron_live.py : def transcribe_wav_live(audio_client, wav_path, *, language="en"): with wave.open(str(wav_path), "rb") as w: sample_rate = w.getframerate() channels = w.getnchannels() sample_width = w.getsampwidth() pcm = w.readframes(w.getnframes()) session = audio_client.create_live_transcription_session() session.settings.sample_rate = sample_rate session.settings.channels = channels session.settings.bits_per_sample = sample_width * 8 session.settings.language = language session.start() # Feed PCM in ~100 ms chunks from a worker thread, then stop. bytes_per_sec = sample_rate * channels * sample_width chunk_bytes = max(bytes_per_sec // 10, 1024) def _pusher(): try: for offset in range(0, len(pcm), chunk_bytes): session.append(pcm[offset:offset + chunk_bytes]) finally: session.stop() threading.Thread(target=_pusher, daemon=True).start() parts = [] for resp in session.get_stream(): for cp in getattr(resp, "content", []) or []: text = getattr(cp, "text", "") or getattr(cp, "transcript", "") or "" if text: parts.append(text) return " ".join(p.strip() for p in parts if p.strip()).strip() Two things to notice: Push from a thread, read from the main coroutine. session.append() is a blocking write into the native stream and session.get_stream() is a blocking generator. Run one in a worker thread so the other can drain in parallel — otherwise you deadlock the session. Chunk to ~100 ms. Smaller chunks (e.g. 10 ms) spend more time crossing the FFI boundary than transcribing; larger chunks (e.g. 1 s) hold back partial results and hurt perceived latency. Always session.stop() . Without it the generator never terminates and the request hangs. The other transcription surprise: browsers don't send WAV Inside the browser, MediaRecorder defaults to audio/webm; codecs=opus . That's great for size but bad for our STT model, which expects a 16-bit mono PCM WAV at a known sample rate. Decoding WebM/Opus server-side would require ffmpeg as a runtime dependency — which is exactly the kind of friction this project exists to remove. The cleaner solution is to encode WAV on the client. AudioContext.decodeAudioData already understands WebM/Opus, so the page can decode the recording, resample to 16 kHz, mix to mono, and emit a PCM-16 WAV blob in 30 lines of JavaScript: // Inside src/static/index.html async function webmToWav(blob) { const ctx = new (window.AudioContext || window.webkitAudioContext)({ sampleRate: 16000 }); const buf = await ctx.decodeAudioData(await blob.arrayBuffer()); // Mix to mono const ch = buf.numberOfChannels; const mono = new Float32Array(buf.length); for (let c = 0; c < ch; c++) { const data = buf.getChannelData(c); for (let i = 0; i < data.length; i++) mono[i] += data[i] / ch; } return encodeWav(mono, 16000); } function encodeWav(samples, sampleRate) { const buffer = new ArrayBuffer(44 + samples.length * 2); const view = new DataView(buffer); // RIFF header writeStr(view, 0, "RIFF"); view.setUint32(4, 36 + samples.length * 2, true); writeStr(view, 8, "WAVE"); // fmt chunk writeStr(view, 12, "fmt "); view.setUint32(16, 16, true); // PCM chunk size view.setUint16(20, 1, true); // PCM format view.setUint16(22, 1, true); // mono view.setUint32(24, sampleRate, true); view.setUint32(28, sampleRate * 2, true); // byte rate view.setUint16(32, 2, true); // block align view.setUint16(34, 16, true); // bits per sample // data chunk writeStr(view, 36, "data"); view.setUint32(40, samples.length * 2, true); // PCM-16 samples let o = 44; for (let i = 0; i < samples.length; i++, o += 2) { const s = Math.max(-1, Math.min(1, samples[i])); view.setInt16(o, s < 0 ? s * 0x8000 : s * 0x7FFF, true); } return new Blob([view], { type: "audio/wav" }); } Now the server's /api/transcribe endpoint just writes the bytes to a temp file and hands them to transcribe_wav_live() — no audio decoding libraries on the Python side. Wiring it into FastAPI The server ( src/app.py ) is deliberately small. The notable detail is that the same process holds both Foundry Local model handles for its entire lifetime, so there is no warm-up cost per request: @app.post("/api/transcribe") async def transcribe(audio: UploadFile = File(...)): data = await audio.read() with tempfile.NamedTemporaryFile(suffix=".wav", delete=False) as f: f.write(data); path = f.name text = _ai_client.transcribe(path) return {"text": text} @app.post("/api/chat") async def chat(req: ChatRequest): if req.stream: return StreamingResponse( _sse(_ai_client.stream_completion(req.messages)), media_type="text/event-stream", ) return {"text": _ai_client.chat_completion(req.messages)} Streaming uses Server-Sent Events because they are trivially supported in both fetch() and the FastAPI runtime, and they don't require a WebSocket upgrade through any proxy a developer might have in front of localhost . What it looks like The repo includes screenshots of the running UI: a welcome screen with both models loaded, a streamed haiku reply, an inline code block with copy-to-clipboard, and the recording state for the microphone. Performance, honestly This is a small-model, CPU-friendly stack. On an Arm64 Surface running the x64 SDK under emulation: First model load (cold cache): tens of seconds — downloads ~600 MB for Nemotron and ~400 MB for qwen2.5-0.5b . Subsequent loads (warm cache): a few seconds per model. End-to-end transcription of a 5-second utterance: well under a second after warm-up. First chat token from qwen2.5-0.5b : typically 200–500 ms; full short reply within 1–2 s. On x64 silicon with a recent CPU the numbers improve substantially, and the SDK will pick the best execution provider it finds (CPU / DirectML / CUDA) for each model. Trade-offs to know about Model quality. qwen2.5-0.5b is a 500M-parameter model. It is fast and small enough to ship on a laptop, but it is not GPT-4. Swap in phi-4-mini or mistral-nemo-12b-instruct if you have the RAM and want better reasoning — the wrapper accepts any chat alias in the Foundry Local catalog. STT is English-only here. The current Nemotron streaming model in the catalog is ...-en-0.6b . Multilingual variants are likely to follow. Browser microphone needs a real browser. Headless / automated browsers (Playwright, Puppeteer) deny getUserMedia by default. Open the page in Edge / Chrome / Firefox to grant the permission and capture audio for real. No agent framework yet. This sample is deliberately a single-turn loop over a chat client — there is no tool calling, planning, or multi-agent orchestration. Adding the Microsoft Agent Framework on top would be a natural next step for richer behaviour. Responsible AI considerations Running locally removes the cloud-egress class of privacy concerns, but it does not remove responsibility: Disclose recording. The browser prompts for mic permission; your UI should make it obvious when capture is active. The sample shows a red ⏹ button and a "Recording…" banner for that reason. Don't log raw audio. The sample writes audio to a per-request NamedTemporaryFile and deletes it after transcription. Treat the WAV as sensitive data even when it never leaves the device. Small models hallucinate. A 0.5B chat model is great for snappy local replies, but unsuitable for high-stakes answers. Pair it with retrieval, ground it on your own data, or escalate to a larger model when accuracy matters. Try it Clone github.com/leestott/fl-nemotron. ./setup.ps1 (or ./setup.sh ) to create a virtualenv and install the pinned SDK. python scripts/prefetch.py nemotron-speech-streaming-en-0.6b qwen2.5-0.5b to download both models. .venv\Scripts\uvicorn.exe app:app --app-dir src --port 8000 Open http://127.0.0.1:8000 in a real browser and click the 🎤 button. Where to go next Foundry Local documentation — official docs for the runtime, catalog, and SDK. microsoft/Foundry-Local — upstream samples and issue tracker. NVIDIA Nemotron model family — background on the speech and language models being published into the catalog. leestott/fl-nemotron — the full source for this post. Key takeaways Pin foundry-local-sdk >= 1.1.0 . Earlier SDKs cannot see the Nemotron Speech Streaming model. Use the LiveAudioTranscriptionSession API for Nemotron, not AudioClient.transcribe() . Encode WAV in the browser. It eliminates a heavy server-side ffmpeg dependency for a few lines of JS. Push audio chunks on a worker thread and drain the response generator on the main one to avoid deadlocks. A small Foundry Local chat model plus Nemotron STT gives you a credible local voice loop in a single Python process — no cloud, no keys, no data egress.Fine-Tuning Language Models with Azure AI Foundry: A Detailed Guide
What is Azure AI Foundry? Azure AI Foundry is a comprehensive platform designed to simplify the development, deployment, and management of AI models. It provides a user-friendly interface and powerful tools that enable developers to create custom AI solutions without needing extensive machine learning expertise. Key Features of Azure AI Foundry One-Button Fine-Tuning: A streamlined process that allows users to fine-tune models with minimal configuration. Integration with Development Tools: Seamless integration with popular development environments, particularly Visual Studio Code. Support for Multiple Models: Access to a variety of pre-trained models, including the Phi family of models. Understanding Fine-Tuning Fine-tuning is the process of taking a pre-trained model and adapting it to a specific dataset or task. This is particularly useful when the base model has been trained on a large corpus of general data but needs to perform well on a narrower domain. Why Fine-Tune? Improved Performance: Fine-tuning can significantly enhance the model's accuracy and relevance for specific tasks. Reduced Training Time: Starting with a pre-trained model reduces the amount of data and time required for training. Customization: Tailor the model to meet the unique needs of your application or business. One-Button Fine-Tuning in Azure AI Foundry Step-by-Step Process Select the Model: Log in to Azure AI Foundry and navigate to the model selection interface. Choose Phi-3 or another small language model from the available options. Prepare Your Data: Ensure your dataset is formatted correctly. Typically, this involves having a set of input-output pairs that the model can learn from. Upload your dataset to Azure AI Foundry. The platform supports various data formats, making it easy to integrate your existing data. Initiate Fine-Tuning: Locate the one-button fine-tuning feature within the Azure AI Foundry interface. Click the button to start the fine-tuning process. The platform will handle the configuration and setup automatically. Monitor Progress: After initiating fine-tuning, you can monitor the process through the Azure portal. The portal provides real-time updates on training metrics, allowing you to track the model's performance as it learns. Evaluate the Model: Once fine-tuning is complete, evaluate the model's performance using a validation dataset. Azure AI Foundry provides tools for assessing accuracy, precision, recall, and other relevant metrics. Deploy the Model: After successful evaluation, you can deploy the fine-tuned model directly from Azure AI Foundry. The platform supports various deployment options, including REST APIs and integration with other Azure services. Using the AI Toolkit in Visual Studio Code Overview of the AI Toolkit The AI Toolkit for Visual Studio Code enhances the development experience by providing tools specifically designed for AI model management and fine-tuning. This integration allows developers to work within a familiar environment while leveraging powerful AI capabilities. Key Features of the AI Toolkit 1) Model Management: Easily manage and switch between different models, including Phi-3 and Ollama models. 2) Data Handling: Simplified data upload and preprocessing tools to prepare datasets for training. 3) Real-Time Collaboration: Collaborate with team members in real-time, sharing insights and progress on AI projects. How to Use the AI Toolkit 1) Install the AI Toolkit: Open Visual Studio Code and navigate to the Extensions Marketplace. Search for "AI Toolkit" and install the extension. 2) Connect to Azure AI Foundry: Once installed, configure the toolkit to connect to your Azure AI Foundry account. This will allow you to access your models and datasets directly from Visual Studio Code. 3) Fine-Tune Models: Use the toolkit to initiate fine-tuning processes directly from your development environment. Monitor training progress and view logs without leaving Visual Studio Code. 4) Consume Ollama Models: The AI Toolkit supports the consumption of Ollama models, providing additional flexibility in your AI projects. This feature allows you to integrate various models seamlessly, enhancing your application's capabilities. Microsoft ONNX Live for Fine-Tuning What is Microsoft ONNX Live? Microsoft ONNX Live is a platform that allows developers to deploy and optimize AI models using the Open Neural Network Exchange (ONNX) format. ONNX is an open-source format that enables interoperability between different AI frameworks, making it easier to deploy models across various environments. Key Features of Microsoft ONNX Live Model Optimization: ONNX Live provides tools to optimize models for performance, ensuring they run efficiently in production environments. Cross-Framework Compatibility: Models trained in different frameworks (like PyTorch or TensorFlow) can be converted to ONNX format, allowing for greater flexibility in deployment. Real-Time Inference: ONNX Live supports real-time inference, enabling applications to utilize AI models for immediate predictions. Fine-Tuning with ONNX Live Model Conversion: If you have a model trained in a different framework, you can convert it to ONNX format using tools provided by Microsoft. This conversion allows you to leverage the benefits of ONNX Live for deployment and optimization. Integration with Azure AI Foundry: Once your model is in ONNX format, you can integrate it with Azure AI Foundry for fine-tuning. The one-button fine-tuning feature can be used to adapt the ONNX model to your specific dataset. Optimization Techniques: After fine-tuning, you can apply various optimization techniques available in ONNX Live to enhance the model's performance. Techniques such as quantization and pruning can significantly reduce the model size and improve inference speed. Deployment: Once optimized, the model can be deployed directly from Azure AI Foundry or ONNX Live. This deployment can be done as a REST API, allowing easy integration with web applications and services. Additional Resources To further enhance your understanding and capabilities in fine-tuning language models, consider exploring the following resources: Phi-3 Cookbook: This comprehensive guide provides insights into getting started with Phi models, including best practices for fine-tuning and deployment. Explore the Phi-3 Cookbook. Ignite Fine-Tuning Workshop: This workshop offers a hands-on approach to learning about fine-tuning techniques and tools. It includes real-world scenarios to help you understand the practical applications of fine-tuning. Visit the GitHub Repository. Conclusion Fine-tuning language models like Phi-3 using Azure AI Foundry, combined with the AI Toolkit in Visual Studio Code and Microsoft ONNX Live, provides a powerful and efficient workflow for developers. The one-button fine-tuning feature simplifies the process, while the integration with ONNX Live allows for optimization and deployment flexibility. By leveraging these tools, you can enhance your AI applications, ensuring they are tailored to meet specific needs and perform optimally in production environments. Whether you are a seasoned AI developer or just starting, Azure AI Foundry and its associated tools offer a robust ecosystem for building and deploying advanced AI solutions. References Microsoft Docs Links Fine-Tuning Models in Azure OpenAI Azure AI Services Documentation Azure Machine Learning Documentation Microsoft Learn Links Develop Generative AI Apps in Azure Fine-Tune a Language Model Azure AI Foundry Overview Get started with AI Toolkit for Visual Studio Code2.3KViews0likes0CommentsIf You're Building AI on Azure, ECS 2026 is Where You Need to Be
Let me be direct: there's a lot of noise in the conference calendar. Generic cloud events. Vendor showcases dressed up as technical content. Sessions that look great on paper but leave you with nothing you can actually ship on Monday. ECS 2026 isn't that. As someone who will be on stage at Cologne this May, I can tell you the European Collaboration Summit combined with the European AI & Cloud Summit and European Biz Apps Summit is one of the few events I've seen where engineers leave with real, production-applicable knowledge. Three days. Three summits. 3,000+ attendees. One of the largest Microsoft-focused events in Europe, and it keeps getting better. If you're building AI systems on Azure, designing cloud-native architectures, or trying to figure out how to take your AI experiments to production — this is where the conversation is happening. What ECS 2026 Actually Is ECS 2026 runs May 5–7 at Confex in Cologne, Germany. It brings together three co-located summits under one roof: European Collaboration Summit — Microsoft 365, Teams, Copilot, and governance European AI & Cloud Summit — Azure architecture, AI agents, cloud security, responsible AI European BizApps Summit — Power Platform, Microsoft Fabric, Dynamics For Azure engineers and AI developers, the European AI & Cloud Summit is your primary destination. But don't ignore the overlap, some of the most interesting AI conversations happen at the intersection of collaboration tooling and cloud infrastructure. The scale matters here: 3,000+ attendees, 100+ sessions, multiple deep-dive tracks, and a speaker lineup that includes Microsoft executives, Regional Directors, and MVPs who have built, broken, and rebuilt production systems. The Azure + AI Track - What's Actually On the Agenda The AI & Cloud Summit agenda is built around real technical depth. Not "intro to AI" content, actual architecture decisions, patterns that work, and lessons from things that didn't. Here's what you can expect: AI Agents and Agentic Systems This is where the energy is right now, and ECS is leaning in. Expect sessions covering how to design agent workflows, chain reasoning steps, handle memory and state, and integrate with Azure AI services. Marco Casalaina, VP of Products for Azure AI at Microsoft, is speaking if you want to understand the direction of the Azure AI platform from the people building it, this is a direct line. Azure Architecture at Scale Cloud-native patterns, microservices, containers, and the architectural decisions that determine whether your system holds up under real load. These sessions go beyond theory you'll hear from engineers who've shipped these designs at enterprise scale. Observability, DevOps, and Production AI Getting AI to production is harder than the demos suggest. Sessions here cover monitoring AI systems, integrating LLMs into CI/CD pipelines, and building the operational practices that keep AI in production reliable and governable. Cloud Security and Compliance Security isn't optional when you're putting AI in front of users or connecting it to enterprise data. Tracks cover identity, access patterns, responsible AI governance, and how to design systems that satisfy compliance requirements without becoming unmaintainable. Pre-Conference Deep Dives One underrated part of ECS: the pre-conference workshops. These are extended, hands-on sessions typically 3–6 hours that let you go deep on a single topic with an expert. Think of them as intensive short courses where you can actually work through the material, not just watch slides. If you're newer to a particular area of Azure AI, or you want to build fluency in a specific pattern before the main conference sessions, these are worth the early travel. The Speaker Quality Is Different Here The ECS speaker roster includes Microsoft executives, Microsoft MVPs, and Regional Directors, people who have real accountability for the products and patterns they're presenting. You'll hear from over 20 Microsoft speakers: Marco Casalaina — VP of Products, Azure AI at Microsoft Adam Harmetz — VP of Product at Microsoft, Enterprise Agent And dozens of MVPs and Regional Directors who are in the field every day, solving the same problems you are. These aren't keynote-only speakers — they're in the session rooms, at the hallway track, available for real conversations. The Hallway Track Is Not a Cliché I know "networking" sounds like a corporate afterthought. At ECS it genuinely isn't. When you put 3,000 practitioners, engineers, architects, DevOps leads, security specialists in one venue for three days, the conversations between sessions are often more valuable than the sessions themselves. You get candid answers to "how are you actually handling X in production?" that you won't find in documentation. The European Microsoft community is tight-knit and collaborative. ECS is where that community concentrates. Why This Matters Right Now We're in a period where AI development is moving fast but the engineering discipline around it is still maturing. Most teams are figuring out: How to move from AI prototype to production system How to instrument and observe AI behaviour reliably How to design agent systems that don't become unmaintainable How to satisfy security and compliance requirements in AI-integrated architectures ECS 2026 is one of the few places where you can get direct answers to these questions from people who've solved them — not theoretically, but in production, on Azure, in the last 12 months. If you go, you'll come back with practical patterns you can apply immediately. That's the bar I hold events to. ECS consistently clears it. Register and Explore the Agenda Register for ECS 2026: ecs.events Explore the AI & Cloud Summit agenda: cloudsummit.eu/en/agenda Dates: May 5–7, 2026 | Location: Confex, Cologne, Germany Early registration is worth it the pre-conference workshops fill up. And if you're coming, find me, I'll be the one talking too much about AI agents and Azure deployments. See you in Cologne.