serverless
221 TopicsOrchestrate Azure Container Apps Jobs with Apache Airflow
Azure Container Apps (ACA) Jobs are a great way to run work that starts, does something, and finishes: nightly batch, data processing, ETL, ML scoring, report generation. They scale to zero, bill per execution, and run any container you give them. But the moment your "one job" becomes "a set of jobs that depend on each other," a gap appears: How do I run twenty jobs in parallel, wait for all of them, then run one more job only if they all succeeded — and retry just the one that failed? A single ACA Job can't express that on its own. What you're describing is an orchestrator, and the most widely adopted one in the data world is Apache Airflow. This post introduces two open-source templates that connect the two, so Airflow becomes the brain and ACA Jobs become the muscle. Pick the one that matches what you already run: airflow-on-aca-jobs: you already have Airflow. Drop in an operator and point it at ACA Jobs. Host nothing new. airflow-hosted-on-aca: you don't have Airflow. Get a full one running on Azure Container Apps with one command. Both use the same operator and the same DAGs, so you can start with one and move to the other later without rewriting your workflows. See Airflow orchestrate real ACA Job executions with parallel fan-out, dependency ordering, and automatic retries. Why ACA Jobs need an orchestrator A plain ACA Job is great at one thing: run this container to completion, then stop. That covers a scheduled job or a one-off task perfectly. Real pipelines need more than that: Dependency ordering: step B runs only after step A succeeds. Parallel fan-out: launch one execution per file, per store, or per partition, all at once, then wait for the whole batch. Per-task retries: if one execution in a batch of fifty fails, retry just that one, not the other forty-nine. Backfills and scheduling: re-run yesterday's pipeline, or run every night with a full history of what happened. These are the problems an orchestrator solves. Instead of building that logic yourself, you let Airflow handle the graph, the scheduling, and the retries, while ACA Jobs run the compute. You get serverless, scale-to-zero workers, and you didn't have to stand up a scheduler to get them. The operator that ties them together Both templates ship the same small plugin: an Airflow operator called AzureContainerAppsJobOperator . In a DAG it looks like any other task: report_sales = AzureContainerAppsJobOperator( task_id="report_store_sales", subscription_id="{{ var.value.azure_subscription_id }}", resource_group="{{ var.value.aca_resource_group }}", job_name="{{ var.value.aca_job_name }}", image="python:3.12-slim", command=["python", "-c", MY_PROGRAM], env_vars={"STORE_NAME": "Seattle"}, deferrable=True, ) A few things make this operator easy to work with: Per-execution overrides. It takes the ACA Job you point it at and overrides the image , command , args , and env_vars for that run. You can drive many different workloads from a single ACA Job definition, and you don't need to build or push a custom image just to try something. The example above runs the stock python:3.12-slim image with an inline program. Deferrable by default. With deferrable=True , Airflow frees its worker slot while the ACA Job runs and resumes when it finishes. That means your fan-out width is bounded by ACA, not by how many Airflow workers you have. You can launch dozens of parallel executions cheaply. No secrets required. Authentication resolves in a sensible order: an Airflow Connection if you set one, otherwise an AZURE_ACCESS_TOKEN environment variable, otherwise DefaultAzureCredential (managed identity). In Azure, the hosted template uses a managed identity so nothing sensitive is stored in Airflow at all. Because both templates share this operator, a DAG written for one runs unchanged on the other. Option 1: Bring your own Airflow (host nothing) Choose airflow-on-aca-jobs if you already run Airflow: Azure Managed Airflow, MWAA, Astronomer, or your own deployment. You keep that Airflow exactly as it is and simply teach it to talk to ACA Jobs. +------------------------------------------+ | Your Airflow (you host it, unchanged) | | runs AzureContainerAppsJobOperator | +------------------------------------------+ | | ACA Jobs REST API v +------------------------------------------+ | ACA Job (Azure Container Apps) | | | | store 1 | store 2 | ... | store N | | parallel executions -> scale to zero | +------------------------------------------+ Your existing Airflow runs the operator; ACA Jobs run the work. You host nothing new. Adoption is three small steps: Copy the operator into your Airflow's plugins/ folder. Add a DAG that uses AzureContainerAppsJobOperator . Set three Airflow Variables so the operator knows which job to drive: Airflow Variable Value azure_subscription_id your subscription id aca_resource_group the resource group holding the ACA Job aca_job_name the ACA Job name That's the whole integration. Nothing new to host, no extra scheduler or database, no custom image. ACA Jobs just become another task type Airflow can call. If you want a job to point at first, the template includes an Azure Developer CLI ( azd ) deployment that stands up a sample ACA Job for you: git clone https://github.com/hetvip2/airflow-on-aca-jobs cd airflow-on-aca-jobs azd up # deploys a sample ACA Job, prints its resource group + name Then copy airflow/plugins/ and airflow/dags/ into your Airflow, set the three Variables, and trigger the DAG. Option 2: Airflow hosted on ACA (turnkey) Choose airflow-hosted-on-aca if you don't already have an orchestrator and want one running next to your jobs. One command provisions the whole thing on Azure Container Apps: azd up | v +------------------------------------------+ | Airflow control plane on ACA | | web | scheduler | triggerer | | Postgres (metadata) + Azure Files (dags)| | Managed Identity - no secrets stored | +------------------------------------------+ | | ACA Jobs REST API v +------------------------------------------+ | ACA Job (Azure Container Apps) | | | | store 1 | store 2 | ... | store N | | parallel executions -> scale to zero | +------------------------------------------+ One command deploys the whole Airflow control plane on ACA, right next to the jobs it drives. git clone https://github.com/hetvip2/airflow-hosted-on-aca cd airflow-hosted-on-aca azd env new my-airflow azd up # prints your Airflow URL when it finishes azd up deploys a complete, working Airflow control plane on ACA: airflow-web, airflow-scheduler, and airflow-triggerer running as Container Apps on LocalExecutor, so there's no Celery or Redis to operate. A Postgres metadata database. A user-assigned managed identity with permission to call the ACA Jobs API, so the operator authenticates with no secrets stored in Airflow. A sample ACA Job for Airflow to drive out of the box. Your DAGs and plugins live on a mounted Azure Files share, so you ship new workflows by re-uploading files rather than rebuilding an image: cp my_dag.py airflow/dags/ azd hooks run postprovision # uploads dags + plugins to the share Airflow picks up the change within a minute. You now own a real orchestrator, hosted serverlessly on the same platform as your jobs. Which one should you pick? Option 1: airflow-on-aca-jobs Option 2: airflow-hosted-on-aca Best when You already run Airflow You don't have Airflow yet Setup Copy the operator + a DAG + 3 Variables azd up (one command) Who hosts Airflow You do (unchanged) Azure Container Apps Authentication Connection or short-lived token Managed identity, nothing stored Ownership Lowest: nothing new to run Turnkey: a full orchestrator you own The important part: the workload never changes. The same DAG and the same operator drive the same ACA Job executions in both. Start wherever you are today, and switch later with zero changes to your pipelines. See it end to end Picture a retailer that wants one number every night: total sales across all stores. Each store reports its own sales as a separate ACA Job execution, all running in parallel. When every store is in, a final job adds them into the company total. That one workflow exercises exactly what a plain Job can't do alone: parallel fan-out: one ACA Job execution per store, all at once dependency ordering: the roll-up runs only after every store reports per-task retries: if a store's execution fails, Airflow retries just that store, and the nightly total still lands In Airflow's Graph view you watch the store tasks light up together, then the roll-up run last. In the Azure portal you watch real executions appear under your ACA Job and scale back to zero when they finish. Same job, same DAG, whichever template you chose. Call to action If you run batch, ETL, or any multi-step work on Azure Container Apps Jobs, give one of these templates a try: Already have Airflow? Start with airflow-on-aca-jobs. Need an orchestrator? Start with airflow-hosted-on-aca. Both are open source, deploy with azd up , and share the same operator so you can move between them freely. Try them out and let us know what you orchestrate.476Views1like3CommentsBring Your Own Orchestrator to Azure Container Apps Jobs
Azure Container Apps Jobs are a good fit for batch processing, ETL, machine learning, reports, and other tasks that run to completion. But when those tasks have dependencies, retries, or fan-out, you still need an orchestrator. Many teams already have one. The community-maintained Bring Your Own Orchestrator collection provides 13 templates that connect existing workflow engines to Azure Container Apps Jobs. The collection is also listed in the Microsoft Azure Container Apps template index. The idea is simple: Your orchestrator manages schedules, dependencies, retries, and workflow history. Azure Container Apps Jobs runs each containerized task and reports the result. You keep the control plane your team knows while ACA Jobs provides the execution layer. How it works Each integration follows the same flow: The orchestrator authenticates to Azure. It starts an ACA Job execution. It waits for that execution to succeed or fail. It uses the result to continue, retry, or stop the workflow. Your orchestrator ---> Azure Container Apps Job ^ | +---- execution result ---+ The templates package this flow in the native model of each platform: an Airflow operator, a Temporal Activity, an Argo workflow template, a Camunda service task, or visual actions in Logic Apps and n8n. The workload container stays independent of the orchestrator that launched it. Choose the orchestrator that fits the workflow There is no single best orchestrator for every workload. The useful question is which control plane matches the way your team models work. When this describes your team Start with Why You already operate Airflow Airflow on ACA Jobs Adds an ACA Jobs operator without replacing your Airflow deployment You need a complete Airflow environment Airflow hosted on ACA Deploys the Airflow control plane and the ACA Jobs integration Your workflows are Kubernetes-native and run from AKS Argo Workflows Uses Argo workflow templates and AKS workload identity You model long-running business processes in BPMN Camunda 8 Connects Camunda service tasks to ACA Job executions You use JSON-defined microservice workflows Conductor Uses Conductor workers and native FORK_JOIN workflows You need durable replay, heartbeats, and resilient retries Temporal Keeps Temporal as the durable control plane while ACA Jobs runs the workload You build asset-centric Python data pipelines Dagster Uses Dagster resources, ops, and dynamic mapping You build general Python flows and task automation Prefect Uses Prefect tasks, flows, and mapped execution You prefer visual automation and SaaS integrations n8n Provides visual workflows for starting and observing ACA Jobs You use Azure-native data pipelines Azure Data Factory and Fabric Provides pipeline definitions for Azure data integration workflows You need connector-rich application integration Logic Apps Standard Uses stateful workflows, connectors, and native control flow You want Azure-native, code-first durable orchestration Durable Functions Uses durable orchestrations, activities, retries, and fan-out/fan-in You already operate a Dapr-enabled workflow host Dapr Workflow Demonstrates Dapr Workflow directing external ACA Job workloads The Bring Your Own Orchestrator catalog keeps this comparison current and links to deployment instructions for every option. Before production The existing-orchestrator templates are designed around managed identity, scoped Azure RBAC, failure handling, and native fan-out/fan-in examples. Their fan-out samples default to five shards and accept configurations from 1 to 50. Treat higher shard counts as configuration support, not a throughput guarantee. Test them against your Azure quotas, orchestrator limits, and downstream systems. Two template-specific boundaries are worth calling out: Dapr Workflow is a preview architecture Azure Container Apps Jobs do not host Dapr sidecars. The Dapr workflow runtime must run in a separate Dapr-enabled host and start ACA Jobs through Azure Resource Manager. The template is therefore labeled preview architecture. Fabric still needs a native workspace run The Azure Data Factory path has live validation. The included Fabric pipeline is structurally validated but still needs a native run in a Fabric workspace. Each repository README documents its validation scope and limitations. Get started Open the template catalog. Choose the orchestrator your team already uses. Review that template's prerequisites and validation notes. Deploy the sample ACA Job with azd up . Run the single-job example, then test fan-out and failure behavior. For example, if Airflow is already your standard: git clone https://github.com/hetvip2/airflow-on-aca-jobs cd airflow-on-aca-jobs azd up The exact setup differs by orchestrator, but the target remains ACA Jobs. Try the templates Compare all 13 orchestrator templates and choose the control plane that matches your team. Review the Azure Container Apps Jobs documentation for triggers, permissions, and platform limits. Browse the ACA community template collections to find the collection in the Microsoft Azure Container Apps repository. Closing thoughts Using Azure Container Apps Jobs should not require an orchestrator migration. Keep the workflow engine your team already trusts and use ACA Jobs for containerized task execution. Explore all 13 options in the Bring Your Own Orchestrator to Azure Container Apps Jobs collection. References Azure Container Apps Jobs overview Azure Container Apps Jobs management API Managed identities in Azure Container Apps Azure Developer CLI documentation Bring Your Own Orchestrator template catalog Azure Container Apps community template collections617Views1like0CommentsAzure Container Apps Express for Shipping Container Apps Fast
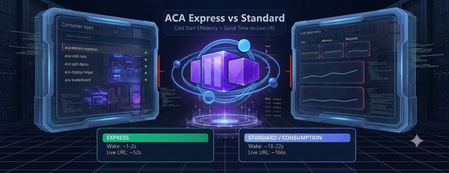
ACA Express Apps are a strong fit for teams that need to ship quickly and can't afford long platform setup cycles. This includes startups, internal platform teams, and product groups deploying APIs, web apps, or agent endpoints that scale with uneven demand. If the priority is fast path-to-production, predictable wake-up behavior, and minimal infrastructure overhead, this model is likely the right choice. To put real numbers behind that, I built a live demo that races Express against a Consumption environment on the same app. The measurements below come from that demo, not from a spec sheet. MicroVMs make cold starts practical Cold start delays usually come from rebuilding runtime state whenever an app wakes up. ACA Express Apps reduce that overhead with MicroVM-based startup paths built for fast boot and isolation. The result is faster instance readiness without trading off security. The gap shows up clearly when both apps have scaled all the way to zero. Waking from a genuine cold start, Express comes back in about 1.5 seconds. The same app in a Consumption environment takes about 20 seconds to answer the first request. Both were measured live in the browser, from request to first response. Disk and memory state restore is the speed multiplier State restoration skips the app's internal boot sequence entirely. Instead of replaying the same initialization work on every start, ACA Express Apps can restore disk and memory state so the app starts closer to ready. That reduces time-to-first-request and smooths scale events, especially for framework-heavy workloads. It's also what lets scale-to-zero stay practical: the app costs nothing while idle, but the wake-up penalty stays in the low single-digit seconds instead of the tens of seconds you'd otherwise pay. Environmentless changes the deployment experience Skipping the environment setup completely changes the deployment workflow. Teams can ship the container app without first managing environment sprawl, while still getting the runtime foundations they need. For fast-moving teams, that means less setup overhead and a shorter path to production. You can see how little there is to fill in. Creating an Express app is a single short form. There is no environment to stand up first. And once it's created, the manage view gives you the live URL, status, and the basics you need to operate it. The numbers, side by side Everything below was measured on the same container image, in the West Central US region. What's measured Express Consumption Cold start from zero (request to first response) ~1.5 s ~20 s Environment provisioning ~14 s ~120 s First-time deploy (environment + app, zero to live URL) ~52 s ~166 s App deploy only (environment already exists) ~30 s ~30 s Express is much faster on the two steps that build infrastructure from scratch: cold start and environment provisioning. Once an environment already exists, the two are about the same. Express isn't a different app runtime, it's the same platform with the first-time setup cost stripped down. Get started Express is in public preview. You can have a container on a live URL in the time it takes to read this post. 📖 Azure Container Apps Express overview — concepts, capabilities, and the current feature support matrix. 🚀 Create your first Express app — the CLI commands and portal steps to get an app running. 🛠️ New Container Apps portal — create and manage Express apps in the streamlined UI. 🧪 Test Express apps locally — validate your container before you deploy. ❓ Express FAQ — preview status, limits, regions, and how Express relates to standard Container Apps. 👉 Deploy an Express app · Read the docs · Browse the FAQ When speed matters, ACA Express is the best tool for deploying containers. It skips the platform setup delays without sacrificing reliability under load.615Views2likes1CommentHow to build long-running MCP tools on Azure Functions
Recently, a customer building servers with the Azure Functions MCP extension reached out and asked: How do I handle tools that take longer than the client is willing to wait? This becomes especially relevant when tool calls move beyond simple request/response into multi-step workflows and long-running operations. At the same time, MCP is evolving to address exactly this. The Tasks extension is introduced in the 2026-07-28 release candidate, defining a standard way to model long-running work. In this post, we’ll walk through how to build long-running MCP tools on Azure Functions using Durable Functions , a framework for authoring stateful, long-running workflows as ordinary code, with checkpointing, scaling, and recovery handled automatically. MCP tools today Today, MCP tools are fundamentally request/response: the client issues a tools/call the server returns a result This works well for fast operations, but breaks down when: workflows take minutes execution depends on multiple steps latency is unpredictable In practice, clients enforce their own tool-call timeouts. These aren't standardized by the MCP spec and vary per client, but they're often in the ~30–60 second range. If a tool exceeds that window: In practice, clients often enforce short timeouts. If a tool exceeds that window: the client times out the agent observes a failed call the underlying work may still be running So the core issue is that you have synchronous tool calls don’t naturally model long-running work. The MCP Tasks extension The Tasks extension to address this. With the extension, a server can respond to a tools/call with an asynchronous task handle instead of a final result, and the client drives the lifecycle from there: tasks/get: poll the task's status tasks/update: submit input back to the server if the task reaches input_required tasks/cancel: cancel an in-flight task A task carries a status ("working", "input_required", "completed", "failed", or "cancelled") and on completion, the final result. Task creation is server-directed: the client advertises support by including the extension in its per-request capabilities, and the server decides per request whether to return a task. A server won't return a task to a client that hasn't advertised support. It's important to note that Tasks rely on ecosystem support. Clients must advertise the extension, and MCP SDKs must implement the task lifecycle, before servers can use it. So while Tasks is now a defined extension, broad client and SDK support is still in progress. Implement long-runng tasks with Durable Functions today Until the Tasks extension is broadly supported across clients, we need a pattern that works with existing request/response clients and supports long-running execution. The following samples show how, using Durable Functions: Python NET The long-running work in this sample mines a short chain of blocks. Each block requires solving a computational puzzle where the system keeps trying different inputs until it finds one that produces a result matching a specific pattern (for example, starting with a certain number of zeros). Because this involves lots of trial and error, it naturally takes time, making it a good example of a long-running workflow. The server in the sample exposes two tools: start_mining Starts a Durable Functions orchestration to mine the blocks Waits briefly (within a configurable budget) Returns result inline if completed within budget OR returns workflow_id if still running get_mining_result Takes the workflow_id Returns the current state, e.g. "completed", "running", "failed", or "not_found" To ensure that the agent calls the tools in the right order, workflow_id is a required parameter of get_mining_result, so the agent can't poll without starting a mining run first. Also, the "running" response carries a poll_after_seconds and a next instruction, ensuring the agent to poll again if work is not done rather than give up or assume completion. Even so, the poll path still relies on the agent correctly remembering, and not hallucinating, the workflow_id it was handed. If it garbles or invents an id, the poll lands on the wrong instance or none at all (which is why get_mining_result returns "not_found" rather than guessing). What changes with the Tasks extension Once the Tasks extension is fully implemented across clients and SDKs, the model becomes simpler and more reliable: the server returns a Task handle, the client manages the polling and lifecyle calls, and the SDK tracks execution state. This removes a key limitation of today’s solution, which requires the agent to remember and correctly pass identifiers like workflow_id. Call to action Try out the sample and let us know whether it addresses your MCP needs around long-running or workflow type tools!655Views0likes0CommentsIntroducing Azure Container Apps Sandboxes: Secure Infrastructure for Agentic Workloads
Today we are announcing the public preview of Azure Container Apps Sandboxes - a new first-class resource type that gives you fast, secure, ephemeral compute environments with built-in suspend and resume. This is the underlying infrastructure on which products like Cloud sandboxes in GitHub Copilot, Foundry Hosted Agents, and Azure Container Apps Express are built, you now have the opportunity to build your solutions leveraging this infrastructure. Azure Container Apps Sandboxes unlocks two massive opportunities. For platform developers and ISVs, sandboxes give you the same isolated compute fabric that powers many Microsoft products. You get the building blocks to create your own multi-tenant platform on proven, enterprise-scale infrastructure. For AI agents, sandboxes become a self-configurable tool that lets agents extend their own capabilities on the fly. An agent can spin up a fresh sandbox in milliseconds and use it to execute untrusted code, compile source, test HTTP requests against a live app, launch a browser session, or tackle whatever needs a quick and scalable infrastructure. On one side it empowers humans to build platforms, on the other it empowers agents to build their own capabilities. Both get enterprise-grade isolation, instant startup, and snapshot-based persistence out of the box. We'll walk through the resource model, sandbox lifecycle, the features that set Sandboxes apart - like snapshots, lifecycle policies, network egress controls, volumes, and managed identities - and show you how to get started with the portal and CLI. What Are Container Apps Sandboxes? Container Apps Sandboxes are secure, isolated compute environments that start in sub-second time, scale to thousands, and cost nothing when idle. Each sandbox runs in its own hardware-isolated microVM boundary - fully separated from the host, the platform, and every other sandbox. You bring your own Open Container Initiative (OCI) image, and Sandboxes handle the rest: provisioning from prewarmed pools, strong multi-tenant isolation, and snapshot-based suspend/resume that preserves full memory and disk state across sessions. There are many ways Sandboxes can help you build your next project - here are a few: Your own build & test systems - wire a Sandbox into your CI/CD flow to run builds while your laptop stays cool. Agents that can run anything safely - an agent spawns a sandbox, executes work inside it, and returns the output with no agent host privileges required. Agent swarms - decompose a research question, spawn N sandbox workers in parallel (each pinned to its own image and egress policy), and synthesize the result. Early access customers are already unlocking significant benefits by leveraging Azure Container Apps Sandboxes. "With Azure Container Apps sandboxes, SitecoreAI can safely enable agents to take real action. The combination of multi-tenant isolation, rapid scale-out, and full automation allows Sitecore to run long-lived, autonomous agents that securely execute code, manage workflows, and interact with enterprise systems within secure, governed environments. With this foundation, we can build agents that do real work: assembling content, personalizing experiences, and optimizing campaigns in production. Agents that operate continuously, learn from results, and improve over time, so our customers get better outcomes without giving up control." - Mo Cherif, VP of AI and Innovation, Sitecore "We got early access to Azure Container Apps Sandboxes, and got the first prototype integrated with Atlas AI in hours, and it's already shaping a new Atlas AI capability that we plan to launch in preview in Q3. It gives every Atlas AI agent a safe, sandboxed workspace (file system, terminal, code execution) on a customer's live data in Cognite Data Fusion. The value: Industrial process, reliability, and production engineers spend days and weeks on questions like "which wells are underperforming and why?" These questions are tractable but expensive, so they are asked rarely and decisions are made on gut feel. With this, an agent pulls the data, runs the analysis, cross-references maintenance and inspection records, and returns a cited draft in minutes. Sandboxes make it practical: Aligned feature set, per-customer isolation, pause/resume across multi-day investigations, scale-to-zero economics." - Kelvin Sundli, Product manager, Atlas AI, Cognite Resource Model: Sandbox Groups and Sandboxes The top-level ARM resource is Microsoft.App/SandboxGroups. A Sandbox Group is the management boundary for a collection of sandboxes that share configuration - think of it like a Container Apps Environment, but purpose-built for sandboxes. When you create a Sandbox Group, you specify: Subscription, Resource Group, and Region Sandbox defaults (optional): default CPU, memory, disk, max sandbox count, and default idle timeout Networking: optionally deploy into a custom VNet with a dedicated subnet for private networking Identity: System or user assigned Entra identity. Individual sandboxes are created within a Sandbox Group. Each sandbox has its own source (disk image or snapshot), resource tier, lifecycle policy, network egress policy, environment variables, ports, volumes, and connections. Sandbox Lifecycle Sandboxes have a well-defined lifecycle with the following states: State Description Creating Provisioning the sandbox from a disk image or snapshot Running Actively executing - backed by a live microVM Idle System-suspended after inactivity; can auto-resume on the next request Suspended Full state (memory + disk) preserved as a snapshot; no compute costs Resuming Restoring from a suspended or idle state - sub-second for most workloads Stopped User-initiated stop; can be resumed Stopping Graceful shutdown in progress Deleting Teardown in progress The key insight here is the distinction between Idle and Suspended. When a sandbox goes idle (e.g., no traffic for a configured timeout), the system can automatically suspend it and capture a snapshot. When a new request arrives, the sandbox resumes transparently. This gives you scale-to-zero economics with stateful compute - something that wasn't possible before without significant custom engineering. Disk Images: Bring Your Own Container Sandboxes boot from Disk Images - Open Container Initiative (OCI) images converted into an optimized root filesystem format. You point to any OCI image (public or private registry), and the platform builds a bootable disk image from it. You can start with public, pre-built images maintained by the platform (for example, Ubuntu base images), or bring your own private images. For private registries, you can authenticate with username/token or use a user-assigned managed identity for Azure Container Registry (ACR) – integrated with Azure as you expect. Snapshots: Full-State Persistence Snapshots capture the complete state of a running sandbox - memory, disk, and all running processes. When you resume a sandbox from a snapshot, every process, open file handle, and in-memory data structure is restored exactly as it was. A snapshot captures the full state of a running sandbox: memory pages, disk, processes. Two ways to make one - automatically on suspend, or manually on demand. Three things they're great for: Checkpointing mid-task so a long-running agent can resume exactly where it left off Cloning an environment that's already warm - dependencies installed, caches populated, services running Shipping a "ready-to-go" state that resumes in sub-second instead of cold-booting Snapshots are free during the preview, after which they will be stored as Azure Blob Storage at standard rates. Each snapshot records the source sandbox, resource allocation (CPU, memory, disk), and container metadata - so what you get back is exactly what you snapshotted. Resource Tiers Every sandbox is assigned to a resource tier that determines its CPU, memory, and disk allocation: Tier CPU Memory Disk XS 0.25 vCPU 0.5 GB 5 GB S 0.5 vCPU 1 GB 10 GB M (default) 1vCPU 2 GB 20 GB L 2 vCPU 4 GB 40 GB XL 4 vCPU 8 GB 80 GB When creating a sandbox from a snapshot, the resource tier is inherited from the snapshot and cannot be changed - this ensures the restored environment has the exact resources it was running with when the snapshot was taken. Lifecycle Policies: Auto-Suspend and Auto-Delete Every sandbox can be configured with lifecycle policies that automate state transitions and cleanup: Auto-Suspend Idle timeout: How long a sandbox can sit idle before being suspended (configurable: 1m, 2m, 5m, 10m, 30m, 60m) Suspend mode: Disk + Memory (default): Full snapshot including memory state - resume picks up exactly where you left off, with all processes and in-memory data intact. Disk: Only the disk is preserved; the VM restarts fresh on resume. Useful when you only need file persistence, not process continuity. Auto-Delete Automatically delete sandboxes after a configurable number of days of inactivity Prevents accumulation of abandoned sandboxes that consume snapshot storage These lifecycle policies are what make Sandboxes economically viable at scale. A platform serving thousands of tenants can configure aggressive idle timeouts (say, 60 seconds) with Memory suspend mode, and each tenant's sandbox disappears from the billing meter almost immediately - but resumes in sub-second time the moment they return. Network Egress Policy For scenarios involving untrusted code - AI agents executing LLM-generated scripts, multi-tenant SaaS with user-submitted workloads - controlling outbound network access is critical. Sandboxes provide a per-sandbox Network Egress Policy: Default action: Allow or Deny all outbound traffic Host rules: Domain-pattern rules (e.g., *.github.com → Allow) to permit specific destinations Custom CIDR rules: Network-level rules for IP ranges (e.g., 10.0.0.0/8 → Deny) Skip egress proxy: Option to bypass the egress proxy entirely when custom VNet routing handles policy enforcement This means you can run a sandbox in a deny-by-default posture and allowlist only the specific endpoints it needs (your API server, a package registry, etc.) - without setting up NSGs or firewall appliances. Managed Volumes: Persistent and Shared Storage Sandboxes support two types of mountable volumes, both managed by Microsoft: Volume Type Backed By Best For Managed Azure Blob Azure Blob Storage Shared data across sandboxes, file uploads/downloads, persistent artifacts Managed Data Disk Azure Disk Storage High-performance storage for databases, build caches, large working sets - only available to one sandbox at a time Blob volumes come with a built-in file explorer in the portal - you can browse, upload, download, create folders, and drag-and-drop files directly. Data Disk volumes provide dedicated block storage with configurable sizes. Secrets and Identity Secrets Sandbox Groups support key-value secrets scoped to the group. Secrets can be created, edited, and referenced by sandboxes within the group. These secrets can be used in egress policies to modify requests with transform or header-injection rules, without exposing the secrets to code running inside the sandbox. Managed Identity Sandbox Groups support both system-assigned and user-assigned managed identities, with full RBAC role assignment management. This means your sandboxes can authenticate to Azure services (Key Vault, Storage, Cosmos DB, etc.) without managing credentials - the same identity model you use everywhere else in Azure. MCP Connectors and Triggers ACA Sandboxes now supports managed connectors through the Model Context Protocol (MCP), giving sandboxes access to external APIs - including Microsoft 365, Salesforce, ServiceNow, GitHub, and 1,400+ other systems - without managing credentials directly. Attach a Connector Gateway to your sandbox group, and every sandbox in the group can call external APIs through a standardized MCP interface at runtime. Pair connectors with triggers to build event-driven automation: route an Outlook email to a sandbox that triages it with an AI agent, or react to a SharePoint file upload by extracting and processing the document all without writing glue code. Triggers can fire a shell command inside a sandbox or invoke an HTTP endpoint the sandbox exposes, so your automation shapes fit naturally around your workload. The integration is built on the new Connector Namespace service (az connector-namespace), the same runtime behind Logic Apps and Power Platform connectors, now available as a programmable layer for sandboxes. See the end-to-end samples for runnable azd up-deployable examples covering email triage and document automation scenarios. The Portal Experience Azure Container Apps Sandboxes are only available in the new Azure Container Apps portal that provides a rich, IDE-like experience for working with sandboxes. Creating a Sandbox The portal offers multiple creation paths: Standard Sandbox - full configuration control over source, resources, lifecycle, networking, and volumes GitHub Copilot Sandbox - preset, Copilot CLI ready to go, GitHub credentials can be wired through the Access Token before the sandbox is created Claude Sandbox - Claude CLI pre-installed, ready for agentic coding inside the sandbox Using Coding Agents (Copilot CLI / Claude Code) If you live inside Copilot CLI or Claude Code, you don't need to learn a new CLI. Install the azure-sandbox skill once and your agent picks up the right skills: # GitHub Copilot CLI # Add as a plugin marketplace /plugin marketplace add microsoft/azure-container-apps # Install all skills /plugin install sandboxes@Azure-Container-Apps # Claude Code claude plugin add microsoft/azure-container-apps The skill runs prerequisite checks silently (az --version, az account show, node --version, aca --version), prompts only if something's missing, and maps natural-language asks to the right aca commands. Bundled runbooks cover Copilot CLI BYOK (bring your own Azure OpenAI key), the deploy-a-web-app walkthrough, and shell setup. Sandbox Detail Page Once your sandbox is running, the detail page gives you immediate access to the sandbox terminal and additional details, such as - Network Audit - real-time egress traffic log showing allowed and denied requests Monitor - live CPU, memory, disk, and network utilization charts Connectors - attached connections with an "Add" action Volumes - mounted volumes with an "Add" action Log Stream - streaming container logs Processes - running process list inside the sandbox Files - file explorer to browse the sandbox filesystem The toolbar actions let you manage the state of the sandbox - Resume or Stop. In the Ellipsis menu (⁝) you can find additional settings to manage network Egress Policy and ingress (Add port), take a Snapshot of the sandbox, Commit (save disk state as a new disk image), set Lifecycle Policy or permanently Delete the sandbox. Finally, you can see additional Details in a side panel. Getting Started with the CLI and Python SDK All sandbox and sandbox-group operations go through the aca CLI. There are no az containerapp sandbox commands, - az is only used for az login, az account show, and resource-group management. Install (CLI) # Mac, Linux curl -fsSL https://aka.ms/aca-cli-install | sh # Windows irm https://aka.ms/aca-cli-install-ps | iex Run aca --help to get started. Install (Python SDK) pip install azure-containerapps-sandbox For more details, quick start and examples on ACA CLI and Python SDK, please go to https://sandboxes.azure.com Evolution from Dynamic Sessions If you've used Azure Container Apps Dynamic Sessions, Sandboxes are the next evolution of that capability. Everything Sessions can do, Sandboxes can do - and significantly more: Capability Dynamic Sessions Sandboxes Sub-second startup ✓ ✓ Strong isolation ✓ ✓ Custom container images ✓ ✓ Custom VNet integration ✓ (Partial) ✓ Suspend/resume with Memory and Disk snapshots - ✓ Lifecycle policies (auto-suspend, auto-delete) - ✓ Network egress policy (per-sandbox) - ✓ Persistent managed volumes (Blob, Data Disk) - ✓ Managed identity (system + user-assigned) - ✓ Secrets management - ✓ Configurable resource tiers - ✓ Direct access to sandbox in Portal experience - ✓ We will continue to support Dynamic Sessions, but all new investment goes into Sandboxes. If you're building new workloads on isolated ephemeral compute, start with Sandboxes. How It All Fits Together ACA Sandboxes is a platform primitive. It's the foundation on which multiple Microsoft products are already built - including ACA Express, Cloud sandboxes in GitHub Copilot, and Foundry Hosted Agents. When you build on Sandboxes, you're building on the same infrastructure that powers Microsoft's own portfolio. This is the evolution of what we shared with Project Legion in 2024. Legion described the internal infrastructure; Sandboxes exposes it as a customer-facing primitive that you can use directly. What's Next • Deeper Azure integrations - first-class connectivity with Azure networking, identity, storage, and AI services • Enhanced SDK and CLI - richer programmatic experiences for managing sandboxes at scale • More Microsoft services built on Sandboxes - this is just the beginning Get Started Today • Portal: https://sandboxes.azure.com/ • Documentation: Azure Container Apps Sandboxes • Pricing: Azure Container Apps Pricing (per-second vCPU/memory billing, scale-to-zero, snapshots at Blob Storage rates) We'd love to hear your feedback. You can ask questions, or file issues on the Azure Container Apps GitHub (prefix with [Sandbox] for Sandboxes-specific issues).8KViews3likes1CommentIntroducing the Azure Functions serverless agents runtime (preview)
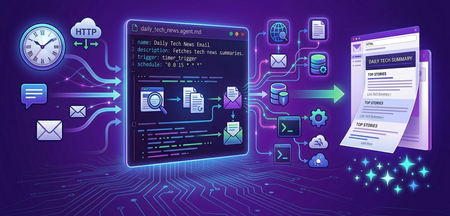
We're thrilled to announce the Azure Functions serverless agents runtime, now in public preview. It brings a new, markdown-first programming model for building AI agents as a first-class workload on Azure Functions, with the event-driven triggers, scale-to-zero economics, and operational integrations you know and love from the platform. A few things you could build in a matter of minutes: A daily briefing agent that wakes up on a timer, scours the web, and drops a summary in your Outlook inbox every morning. A Teams chat agent that triggers on every message and answers your team's questions, looking up data across your connected systems. An on-call troubleshooting agent that investigates incidents by querying logs in Azure Data Explorer and reports back what it found. Each one is a single markdown file with instructions plus a trigger, and deployed like any other function app and running on the Flex Consumption plan. Why a serverless agents runtime Building production agents today usually means stitching together a framework, a hosting layer, message queues, identity, secrets, observability, and a long list of per-service integrations. Most of that work is plumbing, not the agent. Azure Functions has spent years making event-driven compute simple: declare a trigger, write the handler, get autoscale and managed identity for free. The serverless agents runtime applies that same model to agents: Agents are the unit of work. You define behavior in natural language, not boilerplate. Trigger agents from almost any event. HTTP requests, timers, queues, database changes, Teams messages, Outlook mail, and more. Tools, MCP servers, connectors, and sandboxed execution are declared, not coded. Deploy and operate like any function app. Flex Consumption for scale-to-zero and per-second billing, managed identity, VNet integration, Application Insights, and the same deployment tools you already use. Markdown-first: what an agent looks like An agent is a .agent.md file. Your app can have multiple agents, each with its own metadata that declares the trigger. The markdown body becomes the agent's instructions. Here's a timer-triggered agent that summarizes the day's tech news and emails it: --- name: Daily Tech News Email description: Fetches top tech news and emails a summary daily. trigger: type: timer_trigger args: schedule: "0 0 15 * * *" --- You are a news assistant. When triggered, do the following: 1. Scour the web for today's top tech news headlines. Use reputable sources; Include links to the original articles. 2. Summarize the top stories in a concise, well-formatted HTML email body. 3. Email the summary to $TO_EMAIL with the subject "Daily Tech News Summary" followed by today's date. That's the whole function. Drop the file into your app, deploy, and it runs on the schedule. No framework wiring, no service-specific integration code. Your agents can share configuration and capabilities through a few files alongside the agent definitions. agents.config.yaml declares system tools and the default model. mcp.json lists the MCP servers your agents can call, including MCP-enabled Azure connections. A /tools folder holds custom Python tools and a /skills folder holds reusable prompt fragments. Everything here is optional and available to every agent automatically when present. In this example, the agent uses a Container Apps dynamic session to browse the web with Playwright, and a Microsoft Office 365 connection (exposed as an MCP server) to send the email: # agents.config.yaml system_tools: dynamic_sessions_code_interpreter: endpoint: $ACA_SESSION_POOL_ENDPOINT model: $AZURE_OPENAI_DEPLOYMENT // mcp.json { "servers": { "office365": { "type": "http", "url": "$MICROSOFT_365_CONNECTION_MCP_ENDPOINT", "auth": { "scope": "https://apihub.azure.com/.default" } } } } The function app's managed identity authenticates to the connection's MCP endpoint, so there are no secrets to manage. Any Azure connector that supports MCP, or any remote MCP server, can be added the same way. Any of these global settings can be overridden per agent in the agent's metadata. What you get in the preview Triggers across the Azure Functions catalog. HTTP, Timer, Queue, Service Bus, Event Hubs, Cosmos DB, Blob, Event Grid, plus new connection-backed triggers like Teams messages, Outlook mail, and calendar events. 1,400+ Azure connectors as tools. Create a connection, enable its MCP endpoint, and an agent can send mail, post to Teams, create records, query data, all without integration code or auth plumbing. Any remote MCP server as tools. Use any remote MCP server. Sandboxed code and browser automation. Run code or a Playwright-powered browser in Azure Container Apps dynamic sessions, isolated per agent session. Built-in chat UI, HTTP API, and MCP server endpoint with no extra code. Custom Python tools in a tools/ folder and reusable skills in a skills/ folder, shared across agents. Pluggable model providers. Microsoft Foundry, Azure OpenAI, and OpenAI out of the box. Where this fits The serverless agents runtime is designed for the agents most enterprises actually need to build: Scheduled background agents that summarize, monitor, or reconcile on a timer. Event-driven assistants that react to messages, emails, alerts, and database changes. Cross-system agents that tie multiple SaaS and enterprise apps together through connections. Trigger with a Teams message, look up the customer in Salesforce, send an email, and update a database record, all from one agent. Conversational front-ends that pair an HTTP or chat-UI entry point with the same agents your event triggers invoke. Agents as MCP servers that other agents and MCP clients can integrate with directly. We want your feedback The serverless agents runtime is in public preview, and we're actively building it out with input from real customer workloads. Tell us what you build, what's missing, and where the model should go next. Get started Docs: aka.ms/azure-functions-agents-docs Building agents on Azure Functions has never been easier. We can't wait to see what you create with the serverless agents runtime!3.5KViews2likes0CommentsAzure Functions MCP Extension: What's New at Build 2026
The Azure Functions MCP extension has had a breakout year! Since its initial preview, the extension has grown from a single trigger type into a full-featured platform for building remote MCP servers: with tool, resource, and prompt triggers across multiple languages, MCP Apps for interactive UIs, built-in MCP authentication, and feature enhancements. Here's what's new and what it means for developers building MCP servers on Azure Functions. The full MCP primitive set: Tools, resources, and prompts When the MCP extension first shipped, it supported tool triggers. Declare a function as an MCP tool, and any MCP client can discover and call it. That was the starting point. Since then, we've shipped the remaining MCP primitives: Resource triggers: expose a function as an MCP resource. Prompt triggers: expose a function as an MCP prompt, letting clients request structured prompt templates from your server. Like tool triggers, resource and prompt triggers are supported in multiple languages including .NET, Java, Python, TypeScript, and JavaScript. MCP Apps: interactive UI from your MCP server MCP Apps let your tools return interactive user interfaces instead of plain text. Combine tool triggers with resource triggers, and your MCP server can serve rich, rendered experiences to MCP-aware clients. The Azure Functions MCP extension supports MCP Apps natively, meaning the same function app that exposes tools and resources can also serve UI components. The launch blog post on the Azure Apps Blog walked through the pattern in detail. For .NET developers, the new fluent builder API (available in the latest NuGet release) makes it easier to compose MCP Apps by chaining tool and resource definitions in a declarative style. MCP authentication The extension supports built-in MCP authentication, implementing the requirements of the MCP auth spec. All samples in the aka.ms/remote-mcp repo enable built-in MCP auth by default with Microsoft Entra ID as the identity provider. Samples have also been updated to demonstrate how to exchange tokens in the On-Behalf-Of (OBO) flow, so your MCP tools can access downstream APIs using the invoking user's identity. Auth configuration in the Azure portal: Preview at Build is a one-click experience in the Azure portal for configuring built-in MCP auth. No more manual app registration creating, configuration and wiring to the server. Just open your server app on the portal and click to enable MCP auth. Try it out! Feature enhancements Beyond the headline primitives and auth, the extension has shipped a steady stream of capabilities the past few months. The following are the notable additions. Structured content Structured content lets you return machine-readable JSON metadata alongside your tool's response via the `structuredContent` field. Clients that support it can programmatically consume the data (e.g. parse fields, render tables, drive downstream logic) rather than just displaying text. Clients that don't support it still get the regular content blocks as a fallback. Rich content types Tools aren't limited to returning plain text. The extension supports the full set of MCP content block types, e.g. `TextContent`, `ImageContent`, `AudioContent`, `ResourceLink`, and `EmbeddedResource`, so your tools can return images, audio clips, references to resources, and inline file content alongside text. Input and output schemas `WithInputSchema` and `WithOutputSchema` give you explicit control over the JSON schemas advertised for your tools. This is especially useful when the auto-generated schema from function parameters doesn't capture the full contract. For example, when your tool accepts a complex nested object or returns a specific shape that clients depend on. Input and output schemas are currently supported in .NET, with support for other languages coming soon. builder.ConfigureMcpTool("SearchDocs") .WithOutputSchema(""" { "type": "object", "properties": { "results": { "type": "array", "items": { "type": "string" } }, "query": { "type": "string" } }, "required": ["results", "query"] } """); Fluent configuration APIs in .NET A set of fluent builder APIs that let you configure MCP primitives declaratively in `Program.cs`: ConfigureMcpTool: add properties, metadata, input/output schemas, or promote a tool to an MCP App ConfigureMcpResource: attach metadata to resources ConfigureMcpPrompt: define prompt arguments and metadata builder.ConfigureMcpTool("sayhello") .WithProperty("name", McpToolPropertyType.String, "Name of the user", required: true) .WithMetadata("ui", new { resourceUri = "ui://index.html" }); What's next Usage of the MCP extension has grown steadily since its preview launch. Tool execution volume has increased 15x over the past several months as more customers move from experimentation to production. As adoption grows, so do the expectations. Developers building production MCP servers are hitting real friction around auth complexity, client configuration, and observability. We're continuing to invest in the extension to address these gaps and help customers be more successful building and hosting MCP servers on Azure Functions. Here's where we're focusing next. Continued auth simplification Auth remains the biggest barrier to getting an MCP server into production. We'll work on: Smoother client setup: making it easier to connect any MCP client to an authenticated Azure Functions MCP server, not just VS Code. Simplified OBO flow: streamlining the experience of On-Behalf-Of authentication so developers can delegate user identity to downstream services with less configuration. Our goal: the secure path should be the easy path. Deeper integration with Microsoft Foundry We'll build tighter integration between Azure Functions MCP servers and Microsoft Foundry. This includes surfacing MCP servers in Foundry Toolbox, a new feature introduced to help Foundry agents discover and consume tools from a single endpoint. Developers will be able to publish an MCP server from Functions and have it available to Foundry agents through Toolbox without manual endpoint configuration. Continued feature enhancement We prioritize based on feedback from the community raised in our GitHub repo. For example, support for streaming output and pagination are top items in our backlog today based on user demand. We also track the MCP spec's evolution closely and will continue shipping support for strategic features as they land. Examples of proposals we're following: MCP Tasks: the Tasks extension (SEP-2663) defines a standard pattern for async, long-running tool calls with durable task handles. This replaces hand-rolled polling patterns and aligns well with Functions' execute-and-return model. Stateless MCP: SEP-2575 proposes removing the mandatory initialization handshake, which is a natural fit for serverless platforms like Azure Functions where fresh instances can handle any request. Have something you'd like us to prioritize? Let us know by filing a request on GitHub. Get started Samples: Samples showcasing most up-to-date features: aka.ms/remote-mcp Documentation: Model Context Protocol for Azure Functions MCP Extension GitHub repo: Azure Functions MCP Extension709Views1like0CommentsAnnouncing Go support in Azure Functions (Preview)
We're excited to announce that Azure Functions now supports Go as a first-class language, available today in public preview on the Flex Consumption plan. Go developers can now build event-driven, serverless applications using idiomatic Go, the standard toolchain they already love, and the full breadth of Azure Functions triggers, bindings, and operational capabilities. TL;DR: Write Functions in Go using a new code-first programming model and SDK (azure-functions-golang-worker). Use triggers across HTTP, Timer, Service Bus, Event Hubs, Event Grid, Cosmos DB, and Blob Storage. Why Go on Azure Functions Go has become a default choice for cloud-native APIs, platform services, networking tools, and high-throughput integration workloads. Until now, teams that standardized on Go on Azure had to either: Use Azure Functions through the custom handlers protocol, missing out on a first-class developer experience, or Build and operate their own serving, scaling, and eventing infrastructure on containers or VMs. With first-class Go support, those teams get the productivity of Go plus the operational leverage of serverless: automatic scaling, pay-per-use billing, integrated triggers across the Azure ecosystem, and built-in observability, without leaving the Go ecosystem. What's in the preview A new Go programming model and SDK: a code-first, idiomatic way to register Functions and declare triggers using functional options. Support for popular triggers: HTTP, Timer, Service Bus (queues and topics), Event Hubs, Event Grid, Cosmos DB, and Blob Storage. More to come. Native Go build pipeline: go build produces a single static binary that the Functions host invokes directly. No function.json, no interop shims at request time. Integrated observability: Application Insights logging, metrics, and distributed tracing. End-to-end tooling: local development with a preview build of Azure Functions Core Tools. Deployment via Core Tools, zip deploy, or GitHub Actions. Flex Consumption: fast elastic scale, scale-to-zero, per-second billing, VNet integration, and always-ready instances. A quick look at the programming model The Go model is code-first: you register functions and declare triggers in Go, with compile-time checks and full IDE support. No separate JSON metadata to keep in sync. Here's a minimal HTTP-triggered Function: package main import ( "fmt" "net/http" "github.com/azure/azure-functions-golang-worker/sdk" "github.com/azure/azure-functions-golang-worker/worker" ) func main() { app := sdk.FunctionApp() app.HTTP("hello", hello, sdk.WithMethods("GET", "POST"), sdk.WithAuth("anonymous"), ) worker.Start(app) } func hello(w http.ResponseWriter, r *http.Request) { name := r.URL.Query().Get("name") if name == "" { name = "world" } fmt.Fprintf(w, "Hello, %s!", name) } Notice the HTTP handler is a plain http.HandlerFunc, the same signature you'd use with net/http or any Go web framework. There's nothing Functions-specific to learn at the handler level. Registering other triggers The same pattern works across triggers. Non-HTTP handlers take a context.Context plus a typed payload: import ( "context" "log" "github.com/azure/azure-functions-golang-worker/sdk" "github.com/azure/azure-functions-golang-worker/sdk/bindings" ) // Timer: runs every 10 seconds func onTimer(ctx context.Context, t bindings.TimerInfo) error { log.Printf("timer fired; past due=%v", t.IsPastDue) return nil } app.Timer("cleanup", onTimer, sdk.WithSchedule("*/10 * * * * *"), ) // Service Bus queue func onOrder(ctx context.Context, msg bindings.ServiceBusMessage) error { log.Printf("order %s: %s", msg.MessageId, string(msg.Body)) return nil } app.ServiceBusQueue("processOrder", onOrder, sdk.WithQueueName("orders"), sdk.WithConnection("ServiceBusConnection"), ) // Event Hubs func onEvent(ctx context.Context, e bindings.EventHubMessage) error { log.Printf("event seq=%d body=%s", e.SequenceNumber, string(e.Body)) return nil } app.EventHub("ingest", onEvent, sdk.WithEventHubName("telemetry"), sdk.WithConnection("EventHubConnection"), ) // Cosmos DB change feed func onChange(ctx context.Context, docs []bindings.CosmosDocument) error { for _, d := range docs { log.Printf("doc %s: %s", d.ID, string(d.Data)) } return nil } app.CosmosDB("onChange", onChange, sdk.WithDatabase("ToDoList"), sdk.WithContainer("Items"), sdk.WithConnection("CosmosDBConnection"), ) // Event Grid func onGridEvent(ctx context.Context, e bindings.EventGridEvent) error { log.Printf("%s: %s", e.EventType, e.Subject) return nil } app.EventGrid("onEvent", onGridEvent) Extension triggers: real Azure SDK clients For triggers like Blob Storage, the Go SDK injects a fully-typed Azure SDK client directly into your handler. You opt in with a blank import, so your binary only includes the extensions you actually use: import ( "context" "io" "log" "github.com/Azure/azure-sdk-for-go/sdk/storage/azblob/blob" "github.com/azure/azure-functions-golang-worker/sdk" _ "github.com/azure/azure-functions-golang-worker/triggers/blob" // registers blob trigger client factory "github.com/azure/azure-functions-golang-worker/worker" ) func onUpload(ctx context.Context, client *blob.Client) error { log.Printf("blob: %s", client.URL()) resp, err := client.DownloadStream(ctx, nil) if err != nil { return err } defer resp.Body.Close() data, err := io.ReadAll(resp.Body) if err != nil { return err } log.Printf("size=%d", len(data)) return nil } app.Blob("onUpload", onUpload, sdk.WithPath("uploads/{name}"), sdk.WithConnection("AzureWebJobsStorage"), sdk.WithSource("EventGrid"), ) The handler receives a *blob.Client from github.com/Azure/azure-sdk-for-go/sdk/storage/azblob/blob, the same client you'd use in any other Go app. Because it's a real SDK client, you can DownloadStream blobs of any size without buffering the whole payload through the worker. Dependencies stay isolated per extension, so apps that don't use Blob never pull in azblob or azidentity. Project layout A Go function app is just a regular Go module plus the standard Functions config files: my-function-app/ ├── host.json ├── local.settings.json ├── go.mod ├── go.sum └── main.go No function.json and no generated metadata. Triggers are declared in main.go. go build, go test, and go mod tidy all just work. Get started Quickstart Install the preview tooling, scaffold your first Go function app, run it locally, and deploy to Flex Consumption. We can't wait to see what you build. Welcome to Functions, Gophers.617Views4likes0Comments