postgresql on azure
28 TopicsWolters Kluwer scales tax and accounting software with PostgreSQL on Azure
This blog was authored by Sven Hubert, Associate Director IT Operations at Wolters Kluwer, Oliver Heimlich, Lead Product Software Engineer at Wolters Kluwer, Volker Krebs, DevOps Engineer at Wolters Kluwer As part of Wolters Kluwer, a global leader in professional information, software solutions, and services, Wolters Kluwer Tax & Accounting Germany develops software that helps tax advisory firms and midsize businesses streamline payroll, bookkeeping, banking, and tax compliance. With decades of experience, we are a leading technology partner in the industry's transition towards an integrated digital ecosystem. More than 6,000 tax advisory firms and 14,000 midsize businesses rely on our solutions, which process 2.5 million payslips every month, 2.5 million tax returns annually, and support 15% of Germany’s annual financial statements. All these applications run on PostgreSQL, but their data requirements vary significantly, from transactional accounting and dense payroll data to complex tax structures requiring frequent recalculation. At the same time, decades-long customer relationships mean years of historical data must remain readily accessible. Combined, those demands have helped drive our PostgreSQL data from about 6 TB in early 2026 to nearly 10 TB by September 2026, and it's still roughly doubling every year. Keeping ahead of that kind of growth is what led us to adopt elastic clusters in Azure Database for PostgreSQL, enabling us to scale PostgreSQL horizontally as our data volumes and workloads continue to expand. Looking for a more sustainable way to scale Our PostgreSQL architecture has evolved as our business has grown. Before moving to Azure Database for PostgreSQL three years ago, we managed PostgreSQL ourselves on Azure infrastructure, which meant our team was responsible for server patching, backups, and day-to-day database operations. Azure Database for PostgreSQL gave us the managed platform-as-a-service (PaaS) model we wanted and reduced that operational burden. But our data kept growing. Reaching 6 TB was not a hardware problem. We could still scale vertically with relatively little operational effort. The challenge was that the growing size of our datasets increasingly affected PostgreSQL's day-to-day operation. By that point, 42 tables exceeded 10 GB and several had grown beyond 100 GB. Larger tables and indexes made maintenance tasks, queries, updates, and retention-driven cleanup operations more expensive, and a single poorly performing query could impact the wider system. Our engineers were manually creating or tuning indexes in production almost every week, consuming roughly half of one engineer's time, while peak memory usage approached 90%. We wanted to retain the managed experience of Azure Database for PostgreSQL while gaining the ability to scale horizontally. With our data continuing to roughly double each year, it became clear that we needed a more sustainable scaling model. Finding a path to horizontal scale Those requirements narrowed the field quickly. We wanted to stay on PostgreSQL so we could preserve our existing data-access layer and the time-based partitioning we'd already built with pg_partman. Any new solution also needed to run on Microsoft Azure and provide a managed PaaS experience rather than require us to manage the infrastructure ourselves. Data residency requirements limited our options even further: we needed high availability and disaster recovery in multiple German regions. We evaluated several options, running proof-of-concept tests on synthetic banking data. But it was hard to find one that supported development and CI testing without requiring a live cluster and was also available in two German regions. When elastic clusters in Azure Database for PostgreSQL reached general availability in both Germany West Central and Germany North, we had our path forward. Elastic clusters use the Citus extension to turn PostgreSQL into a distributed database. It's still PostgreSQL, so scaling out is transparent to our applications, and we keep the managed-service model we already relied on. We also had a head start because our custom data-access layer was already sharding-aware from that earlier proof-of-concept work. The move meant extending a partitioning strategy we understood, not rewriting the application from scratch. Getting that architecture right took longer than the cutover itself. Across roughly 400 tables, we decided which ones to distribute by tenant, which to replicate as reference tables, and which also needed pg_partman's time-based partitioning layered on top. That combination mattered because our data is both multi-tenant and long-lived, with some customers' records going back decades. We spent about three months on that design and cleanup work as well as continuous testing to ensure a smooth and short migration. The production migration itself ran over a single weekend earlier this year, when we used pgcopydb to move roughly 6.4 TB of data onto the new cluster. What we learned as an early adopter Working with elastic clusters at production scale taught us things we hadn't seen in smaller test environments, particularly around connection pooling. We hadn't used PgBouncer in our previous architecture, so we initially ran elastic clusters without it as well. But distributing and partitioning our data multiplied the number of shards, and in Citus, memory cost per connection scales with shard count. Adding PgBouncer reduced our physical connections to close to one-sixth of their previous level, helping us use cluster resources far more efficiently. We also learned that the test environment has to match production exactly, not just the data but every configuration setting. We enabled high availability only after the production migration, and that surfaced an issue we hadn't seen in testing. Now we validate failover, health probes, and traffic routing with high availability enabled before making any changes to the cluster. However, being early to the platform also meant we didn't have to work through issues like that on our own. We had direct access to the Azure Database for PostgreSQL product group throughout the project, beyond the standard support model. That relationship has become an ongoing feedback loop, where we bring current challenges and upcoming requirements to Microsoft's team, test new capabilities against our own environment, and help shape what matters most as the platform evolves. Leaving weekly database troubleshooting behind We went into this migration primarily looking for a more sustainable way to scale. What exceeded our expectations was the performance improvement we saw after the migration and the relatively short tuning and optimization work that followed. Before the migration, some queries encountered multi-second I/O waits as the database grew larger. Since then, average statement execution time has stabilized below 20 milliseconds, and peak memory now stays consistently below 80%. The weekly cycle of hunting slow queries and hand-building new indexes has stopped completely. Long-standing performance tickets have been closed as "not reproducible," and work that had consumed close to half of one engineer's time now requires only occasional attention. That shift means our engineers spend less time chasing the next database bottleneck and more time building the features our customers use. That matters on the development side, too: roughly 100 developers work against the databases across development, test, integration, and production, with around two dozen systems running at once. Once we'd proven the configuration in production, rolling it out across those environments was straightforward. We use the same Terraform provisioning scaled down to inexpensive single-node clusters, and a plain Citus Docker container for local work. Preparing for the next doubling Just as important, we now have room to keep scaling. The growth that took us from roughly 6 TB to nearly 10 TB hasn't slowed, and we don't expect it to. As that data grows, we need our applications to keep performing for the thousands of firms and businesses that rely on them every day. But for the first time, that expansion feels like something our architecture is designed for rather than something we're constantly reacting to. Today, our production deployment of elastic clusters in Azure Database for PostgreSQL runs across six nodes. As data volumes continue to increase, we expect to add a seventh and eighth, testing the scale-out process against a restored production backup before applying it live. With elastic clusters, we can now scale both horizontally and vertically as our capacity needs change. And we're continuing to work with Microsoft on what comes next, from further optimizing connection pooling to major PostgreSQL version upgrades, as we prepare for the next doubling and the one after that.127Views1like0CommentsThe Invisible Storage Leak: How Replication Slots Can Fill Azure PostgreSQL Flexible Server Storage
Understanding WAL in PostgreSQL PostgreSQL uses Write-Ahead Logging (WAL) to guarantee durability and consistency. Every change made to the database is first recorded in WAL before being written to data files. The following activities generate WAL: INSERT operations UPDATE operations DELETE operations VACUUM operations CREATE INDEX ALTER TABLE Bulk data loads Maintenance operations A common misconception is that WAL generation is only significant for large transactions. Database workloads with frequent data modifications continuously generate WAL throughout the day. Why Replication Slots Exist Imagine a primary server generating WAL files while a replica becomes temporarily unavailable. Without replication slots, PostgreSQL would eventually remove older WAL files to reclaim storage space. To prevent this, PostgreSQL uses replication slots. A replication slot tracks the WAL position required by a specific replica and prevents PostgreSQL from deleting WAL files that have not yet been consumed. This mechanism significantly improves replication reliability. The Hidden Side Effect Replication slots solve one problem but introduce another. When a replica stops consuming WAL, PostgreSQL continues retaining WAL files because the replication slot indicates they are still required. The database may function normally. Applications may run without issues. Database size may remain unchanged. Yet storage usage continues increasing. This often times comes as a surprise, because the growth isn't coming from tables or indexes. It comes from retained transaction logs. Microsoft documentation specifically notes that replication slots automatically retain WAL required by replicas and warns that inactive replication slots can cause significant storage growth on the primary server. Let’s explore some common scenarios that can lead to unexpected storage growth due to WAL retention Scenario 1: Replica Lag Replica lag is perhaps the most common cause of WAL accumulation. Consider a workload generating: 50 GB WAL per day If the replica falls behind and remains several days behind the primary: The primary cannot remove WAL because the replica still requires it. Even though replication is technically working, retained WAL continues to grow. Common causes include: Network latency High write workloads Long-running transactions Resource bottlenecks on replicas What to do Monitor replication lag and primary storage using Azure Monitor metrics. Investigate sustained or increasing replication lag and address the underlying cause. Continue monitoring storage while the replica catches up, as accumulated WAL may remain until it is no longer required. See the “How to investigate” section below for steps to monitor replication lag, check replication slots, and correlate WAL retention with storage growth. Scenario 2: Broken Replica When a replica becomes unavailable due to infrastructure, maintenance, or recovery issues, WAL required by the replica can accumulate on the primary and contribute to storage growth. When the replica is unavailable: What to do Restore the replica if it is still required. Monitor replication lag and primary storage using Azure Monitor metrics while the replica is unavailable. If the replica has been permanently removed, verify that its associated replication slot is no longer required before removing the slot. Do not remove a replication slot simply because it is inactive. Confirm that no replica or other replication consumer still depends on it. See the “How to investigate” section below for steps to identify inactive replication slots and measure retained WAL. Scenario 3: Deleted Logical Replication Subscriber If a logical replication subscriber is removed but its replication slot remains on the publisher, the slot can continue retaining WAL even though the subscriber is no longer consuming it. What to do Confirm whether the subscriber has been permanently removed. If the associated replication slot is no longer required, it can be removed after verifying that no replication consumer depends on it. See the “How to investigate” section below for steps to identify inactive logical replication slots and measure retained WAL. Scenario 4: WAL Retention Becomes the Largest Storage Consumer One of the most interesting escalation cases occurs when WAL occupies more storage than business data. For example: Component Size Database Data 500 GB Indexes 120 GB WAL Retention 1.8 TB At this point, the actual application data is no longer the primary storage consumer. The retained WAL becomes the dominant storage workload. You will commonly see symptoms like: Stable database size Continuously increasing storage utilization Unexpected storage alerts Auto-grow events What to do Identify replication slots retaining significant WAL. Monitor Storage Used and Storage Percentage in Azure Monitor. Resolve the underlying replication issue rather than relying on additional storage alone. See the “How to investigate” section below for steps to identify replication slots and measure retained WAL. Scenario 5: Primary Server Enters Read-Only Mode The most severe outcome is storage exhaustion. According to Microsoft documentation, when retained WAL causes storage utilization to reach critical thresholds, Flexible Server can automatically switch to read-only mode to prevent disk-full scenarios. The sequence typically looks like: At this stage, the server prevents further modifications, which can result in application write failures and service impact. Microsoft also notes that disk-full conditions can affect operational activities such as backups and WAL archiving This behavior has been observed in real-world storage exhaustion incidents where storage consumption reached critical levels and database write operations were affected. What to do Monitor Storage Percentage and Storage Used in Azure Monitor. Check whether retained WAL is contributing to storage growth. Resolve the underlying replication or replication-slot issue where applicable. Configuring alerts on Storage Percentage for approaching disk-full conditions. How to Investigate Review Azure Monitor Metrics and Configure Alerts Monitor: Use Azure Monitor Metrics to track storage consumption and replication health over time. In the Azure portal, open your Flexible Server and use Monitoring > Metrics (Metrics Explorer) to review the relevant storage and replication metrics. You can also select Dashboards with Grafana from the server menu to use the built-in Grafana monitoring experience. Transaction Log Storage Used (txlogs_storage_used) to track transaction log/WAL storage consumption. Storage Used Monitor the amount of storage currently consumed and look for sustained or unexpected growth. Storage Percentage: Monitor how much of the provisioned storage is being consumed and watch for a steady increase toward the available capacity. Read Replica Lag (physical_replication_delay_in_seconds): Shows replica lag in seconds on an individual read replica. Max Logical Replication Lag (logical_replication_delay_in_bytes): Shows the maximum WAL backlog retained for logical replication. Max Physical Replication Lag (physical_replication_delay_in_bytes): Shows the largest physical replication backlog on the primary server. Learn more about Monitor here. Learn more about Dashboards with Grafana here. Alert: Use Azure Metric alerts for proactive monitoring and alerting. Create metric alerts based on the backlog and storage limits that the workload can tolerate. Useful starting examples include: Alert when Max Logical Replication Lag exceeds the acceptable logical replication backlog. Alert when Read Replica Lag remains above 300 seconds. Alert when Storage Percentage exceeds 80%. For configuration steps, see Configure metric alerts for Azure Database for PostgreSQL Flexible Server. 2. Check Replication Slots For logical replication, first monitor Max Logical Replication Lag (logical_replication_delay_in_bytes) in Azure Monitor to identify whether the replication backlog is increasing. If the metric shows a sustained or increasing backlog, check the replication slots to identify inactive consumers: SELECT slot_name, slot_type, restart_lsn, inactive_since FROM pg_replication_slots WHERE active='f'; Note: " inactive_since" column only exists in PostgreSQL 17 and later. This query identifies inactive replication slots. Investigate each inactive slot to determine whether its replication consumer is temporarily unavailable or whether the slot is no longer required. 3. Check Replica Status For read replicas, start by monitoring replication lag in Azure Monitor. Use Read Replica Lag (physical_replication_delay_in_seconds) on each replica and Max Physical Replication Lag (physical_replication_delay_in_bytes) on the primary server to identify replicas that are falling behind. If Azure Monitor indicates persistent or increasing replication lag, check the replication state from the primary: SELECT usename, application_name, state, sync_state, replay_lag FROM pg_stat_replication; Use the replication state and replay_lag to understand whether the replica is keeping up: state = streaming: WAL is actively being streamed to the replica. state = catchup: The replica is connected but is working through a WAL backlog. replay_lag: Helps identify delay in WAL replay on the replica. 4. Measure Retained WAL Before measuring WAL retained by individual replication slots, review the following metrics in Azure Monitor: Transaction Log Storage Used (txlogs_storage_used): helps determine whether transaction/WAL log usage is increasing. Storage Percentage (storage_percent): shows overall storage utilization as a percentage. Storage Free (storage_free): shows the remaining available storage. Reviewing these metrics together helps determine whether increasing transaction-log usage is contributing to overall storage pressure. If transaction-log storage is increasing, use the following query to determine how much WAL is being retained by each replication slot: SELECT slot_name, pg_size_pretty( pg_wal_lsn_diff(pg_current_wal_lsn(),restart_lsn)) AS retained_wal FROM pg_replication_slots; restart_lsn represents the earliest WAL position that may still be required by the replication slot. retained_wal estimates the amount of WAL between the slot’s restart_lsn and the current WAL position. A large or steadily increasing retained_wal can indicate that the slot is not advancing fast enough and WAL is accumulating. Compare retained_wal across slots to identify which slot is associated with the largest WAL retention. Preventative Measures ✅ Monitor replication lag and overall storage utilization. ✅ Configure Azure Monitor alerts for replication lag and storage percentage. ✅ Regularly review replication slots ✅ Remove unused slots only after confirming that no replication consumer depends on them. ✅ Validate replica health after maintenance activities ✅ Include replication slot checks in operational runbooks Conclusion By proactively monitoring replication lag, replica health, replication slots, and storage metrics, administrators can identify issues like lagging replicas and inactive replication slots early, helping prevent unexpected storage growth caused by retained WAL.137Views2likes0CommentsSeptember 2026 Recap: Azure Database for PostgreSQL
Save the date for POSETTE 2027 Mark your calendar for March 30–31, 2027, when POSETTE: An Event for Postgres returns for its sixth year. Organized by the PostgreSQL team at Microsoft in partnership with AMD, this free virtual developer conference brings together PostgreSQL experts, developers, users, and contributors from around the world to share knowledge and expertise. The call for proposals is expected to open later in November. Visit PosetteConf.com for the latest updates. Features💡 Cross-Tenant Customer Managed Key (CMK) now Generally Available In September, cross-tenant customer-managed key (CMK) support became generally available for Azure Database for PostgreSQL flexible server. This capability enables independent software vendors (ISVs) and other service providers to host PostgreSQL resources in their tenant while their customers retain control of encryption keys stored in Azure Key Vault or Azure Managed HSM in a separate Microsoft Entra tenant. Using a multitenant application and user-assigned managed identity, organizations can maintain tenant separation while meeting data-protection and key-governance requirements. Learn more about cross-tenant customer-managed keys for Azure Database for PostgreSQL. Database Hub in Microsoft Fabric: A Single View of Your PostgreSQL Estate (Preview) Database Hub in Microsoft Fabric is now in public preview with support for Azure Database for PostgreSQL flexible server. One place to discover, monitor, and secure your entire database estate across PostgreSQL, Azure SQL, Azure Cosmos DB, and Azure SQL Server. No more hopping between portals and per-server dashboards. What you can do today: Estate view automatically discovers the PostgreSQL flexible servers you can access through Microsoft Entra ID and Azure RBAC, with filters for subscription, resource group, and tags. Security posture flags issues and suggestions such as Microsoft Entra authentication, public network access, and customer-managed keys. Fleet monitoring tracks CPU, memory, storage, IOPS, connections, and read replica lag across your servers. Spot what needs attention, then jump straight to the Azure portal or VS Code to act. No data movement, no agents. Learn more: A Single View of Your PostgreSQL Estate: Database Hub in Public Preview Azure Backup for PostgreSQL Flexible Server (v2) Public preview Azure Backup for PostgreSQL Flexible Server (v2) is now in Public Preview, bringing a redesigned, physical snapshot-based backup architecture that removes several key limitations of v1. You can now protect databases up to 32 TB on Premium SSD v1 and 64 TB on Premium SSD v2, compared with the previous 1 TB limit, and schedule daily or weekly backups with incremental backups after the first full backup, improving from v1’s weekly full backup cadence. V2 also introduces support for elastic clusters and Restore as Server, allowing recovery directly to a target flexible server or elastic cluster instead of restoring files to a storage account and manually importing them. Long-term retention remains available for up to 10 years, with additional protection through capabilities such as WORM immutability, soft delete, and multi-user authorization. Learn more: Azure Backup for PostgreSQL flexible server and elastic cluster (v2) is now in public preview | Microsoft Community Hub Azure PostgreSQL Learning Byte 🎓 PostgreSQL Skills Did you kow that with PostgreSQL Skills you can bring expert guidance, live database context, execution tools, and built-in validation into the development workflow? With 32 expert sub-skills, you can build capabilities such as vector search and row-level security, troubleshoot query performance, and manage high availability, disaster recovery, upgrades, and authentication. The plugin detects the environment automatically and routes each request to the right guidance, with one installation that works across GitHub Copilot CLI, VS Code, Claude Code, and Codex CLI. Learn more: Postgres Skills: Give Your AI Agent PostgreSQL Expertise214Views2likes0CommentsPostgres Trip Report from Postgres Summit US 2026
Photo gallery: Microsoft team at Postgres Summit US 2026 Postgres Summit US 2026 was a conference of connections: between database internals and the infrastructure underneath them, between AI ideas and production engineering, and between the people building PostgreSQL today and those who will carry it forward. For anyone who could not be in New York, this report captures the talks, technical questions, hallway conversations, and community moments that defined the week. The event also opened a new chapter. After years as PGConf NYC, the conference returned as Postgres Summit US, bringing more than 240 developers, DBAs, architects, contributors, technology leaders, and partners to Convene on Broadway from September 30 through October 2. The Microsoft team contributed six sessions across performance, replication, infrastructure, benchmarking, AI, developer tools, and community sustainability. Around those talks was a much larger program shaped by speakers and attendees from across the PostgreSQL ecosystem. 01 - Microsoft speaker highlights 02 - What the wider program was talking about 03 - Workshops and the hallway track 04 - The conversations continued after the slides 05 - What we brought home from New York 06 - Explore the Postgres Summit US 2026 program Gratitude for the organizers, speakers, sponsors, and attendees 01 - Microsoft speaker highlights Abe Omorogbe and Jared Meade: "Tour of Postgres on Azure with HorizonDB, Agentic workflows, & VS Code." Their end-to-end tour moved from HorizonDB's shared-storage architecture, rapid failover, and elastic read scale to SQL-declared chunking and embedding pipelines, durable incremental processing, intelligent product search, Copilot CLI Postgres skills, and an interactive VS Code query-plan visualizer. Although the demos used Microsoft technology, the engineering message applied broadly: production AI needs a dependable data layer, observable workflows, and tools that help developers understand what the database is doing. Microsoft Azure HorizonDB Documentation Landing Page | Microsoft Learn Claire Giordano delivered two talks that connected PostgreSQL's technical foundations with its future. In "A Secret Decoder Ring for Postgres Replication: A Beginner's Guide," Claire turned the alphabet soup of logical, physical, streaming, synchronous, and asynchronous replication into approachable mental models tied to high availability, disaster recovery, read scaling, migrations, WAL, and Patroni. In "Building the next generation of Postgres contributors: what's working & what's getting in the way," she marked PostgreSQL's 30th anniversary by examining the project through three lenses: the soul of its people and culture, the machine of its workflows and governance, and the fuel of economics and funding. Together, the talks asked both how PostgreSQL keeps data moving and how the community keeps itself moving. Divya Bhargov: "Same Postgres, Moving Ground: How Infrastructure Changes Shape Database Behavior." Divya explored a production reality that applies to every environment: PostgreSQL can remain stable while VM families, storage layers, operating systems, kernels, and networking stacks change underneath it. Drawing from large-scale operational experience, she showed why teams should correlate database symptoms with infrastructure transitions before assuming every behavioral change originated inside PostgreSQL. Gayathri Paderla: "PostgreSQL Performance Mysteries: When Low IOPS Still Means High Latency." Gayathri unpacked real production cases where latency increased even though familiar signals such as IOPS, query duration, CPU pressure, and indexing did not point to the cause. The trail instead led through memory behavior, cache eviction, PostgreSQL shared buffers, the operating system page cache, and storage interactions. The session showed how to correlate pg_buffercache, pg_stat_statements, wait events, storage behavior, and cache-warming techniques such as pg_prewarm. The practical lesson was memorable: low IOPS does not mean storage is uninvolved, and a normal query metric does not mean the application is experiencing normal latency. Here are the slides from the talk. PostgreSQL Performance Mysteries When low IOPS still means high latency - Speaker Deck Richard Yen: "Pushing PostgreSQL to the Limit: How to Benchmark Hardware with Postgres." Richard challenged the numbers used to sell hardware and cloud storage. Massive advertised IOPS or throughput does not tell a DBA whether the real limit will be storage, CPU bandwidth, PostgreSQL locks, checkpoints, archive_mode overhead, or autovacuum interference. His session focused on building an impartial PostgreSQL benchmarking harness, instrumenting both system and database metrics, and avoiding synthetic-test traps that can produce confident but misleading conclusions. Pushing PostgreSQL to the Limit: How to Benchmark Hardware with Postgres 02 - What the wider program was talking about Beyond the Microsoft sessions, the schedule showed where PostgreSQL engineering is headed. The keynote "Lessons Learned from Developing Agentic AI Tooling for Postgres" set a practical tone for AI. Other sessions explored hybrid search, agent memory, AI-agent security, PostgreSQL 19, planner behavior, VACUUM, index prefetching, change data capture, driver maintenance, Kubernetes migrations, replication, and zero-downtime operations. The breadth of the program mattered. Healthcare, financial services, government, SaaS, analytics, and cloud-native teams have different workloads, but they share the same production requirements: reliability, security, predictable performance, recovery, regional availability, and a clear way to choose the right platform for each workload. The question is no longer simply whether PostgreSQL is enterprise ready. It is how each organization should use PostgreSQL without creating unnecessary operational complexity. 03 - Workshops and the hallway track The workshop track made the conference approachable for people at different stages of their PostgreSQL journey. Sessions such as "Getting Comfortable with Postgres," "Postgres DBA Basics Nobody Told You,"And "Locks, Monitoring & the Config That Matters" turned administration, configuration, troubleshooting, and performance concepts into hands-on practice. That mix of beginner-friendly learning and deep technical sessions is one of the best things about PostgreSQL conferences. Photo gallery: hands-on learning and community conversations 04 - The conversations continued after the slides The Day 1 reception gave everyone time to compare notes after the first full program, and many of the best exchanges continued at sponsor booths, over dinner, and between sessions. Engineers compared production lessons. Contributors heard directly from users. Teams discovered that problems they had considered unique were often shared by people at other companies. That hallway track is difficult to capture in an agenda, but it is a big reason people travel to PostgreSQL events. Postgres Summit US is organized by the United States PostgreSQL Association (PgUS) and supported by volunteer organizers, reviewers, speakers, and sponsors. The sponsor community included cloud providers, database companies, observability vendors, and open-source specialists. Microsoft was proud to participate, but the event's real strength came from the range of people willing to share what they had built, what had failed, and what they had learned. 05 - What we brought home from New York Microsoft brought home five key takeaways from Postgres Summit US 2026: Production AI is now a PostgreSQL architecture and operations discussion. The community is moving beyond AI prototypes toward dependable data foundations, secure agent access, observable pipelines, hybrid search, and production-ready developer tooling. Infrastructure changes can affect database behavior even when PostgreSQL itself has not changed. VM, storage, operating-system, kernel, and networking changes must be considered when diagnosing PostgreSQL performance and reliability. Observability and explainability are essential at scale. Effective diagnosis requires correlating PostgreSQL internals, query behavior, memory, caching, wait events, infrastructure metrics, and storage behavior rather than relying on one familiar metric. Organizations want to consolidate more workloads on PostgreSQL without increasing operational complexity. Customers expect simpler operations, predictable performance, stronger recovery, high availability, and clear guidance for selecting the right PostgreSQL platform. Community knowledge sharing remains one of PostgreSQL’s greatest strengths. Technical sessions, workshops, hallway conversations, and candid production lessons help practitioners, contributors, and new community members learn from one another. These takeaways reinforce Microsoft’s continued investment in PostgreSQL performance, developer experiences, AI integration, operational reliability, and open-source collaboration. The transition from PGConf NYC to Postgres Summit US felt appropriate. The event still had the technical depth, welcoming hallway conversations, and practical learning that people value, but the scope was broader. AI-enabled applications are moving into production, PostgreSQL 19 is opening new possibilities, and operators are asking sharper questions about reliability and performance. Microsoft will continue investing in PostgreSQL performance, developer experiences, AI integration, and open-source collaboration. We are already looking forward to the next gathering. Microsoft booth, reception, community dinner, and New York moments 06 - Explore the Postgres Summit US 2026 program Conference schedule :https://postgresql.us/events/postgressummitus2026/schedule/ Conference sessions and abstracts: https://postgresql.us/events/postgressummitus2026/sessions/ Gratitude for the organizers, speakers, sponsors, and attendees A conference like this only happens because many people contribute behind the scenes. Thank you to Postgres Summit US, the volunteer organizers, the program committee, the speakers who did the work behind every slide and demo, the sponsors who helped make the event possible, and the attendees who brought thoughtful questions and real production experience into every room. To everyone who shared a lesson, asked a difficult question, demonstrated a new idea, or welcomed someone new to the community: thank you. Hopefully these photos and highlights give you a feel for the energy in New York. See you at the next PostgreSQL gathering.139Views2likes0CommentsWhat sustained PostgreSQL performance really requires: Lessons from an independent benchmark
Coauthored by Jared Meade and Teneil Lawrence For teams running transaction-intensive applications, database performance is rarely about a single specification. More vCores can help, but compute is only one part of the equation. Storage performance, workload concurrency, high availability, and database configuration all influence how a PostgreSQL workload performs under sustained demand. That is why we recently commissioned Principled Technologies to independently evaluate Azure Database for PostgreSQL and Amazon RDS for PostgreSQL using a high-concurrency OLTP workload. In the configurations tested, Azure Database for PostgreSQL – flexible server delivered 72.7% higher throughput without high availability and 79.2% higher throughput with high availability than the tested Amazon RDS for PostgreSQL configurations. Those results are compelling, but the more useful story for teams evaluating a Postgres managed service is what sits behind them. The study reinforces an important principle for planning database infrastructure: sustained performance depends on how compute, storage, availability, and workload characteristics work together. Putting PostgreSQL performance to the test Principled Technologies used HammerDB 5.0 and its TPROC-C workload, which is derived from TPC-C and designed to simulate a transaction-intensive environment. The test used a 3,000-warehouse database and evaluated performance across increasing numbers of virtual users. The study compared: Azure Database for PostgreSQL – flexible server using a Standard_D16s_v6 compute instance with Premium SSD v2 storage Amazon RDS for PostgreSQL using a db.m7i.4xlarge instance with gp3 storage Both configurations used 16 vCPUs, 64 GB of memory, and 2,048 GB of storage. The Azure configuration provisioned 80,000 IOPS and 1,200 MB/s of storage throughput, while the Amazon RDS configuration provisioned 40,000 IOPS and 1,200 MB/s. Both environments were configured with wal_level=logical. Principled Technologies tested each platform both with and without high availability enabled. For Azure, that meant zone-redundant high availability. For Amazon RDS, the study used Single-AZ and Multi-AZ configurations. To measure sustained rather than momentary performance, each test included a 30-minute warm-up followed by a 30-minute measurement period and a five-minute cooldown. Each configuration was tested three times, with the database restored between runs, and the median result was reported. The results showed: Without HA: Azure Database for PostgreSQL achieved 51,134 new orders per minute (NOPM), compared with 29,605 NOPM for the tested Amazon RDS configuration, a 72.7% advantage. With HA: Azure achieved 53,620 NOPM, compared with 29,907 NOPM for the tested Amazon RDS configuration, a 79.2% advantage. Just as importantly for teams designing resilient applications, Principled Technologies found that enabling zone-redundant HA did not meaningfully reduce throughput on the Azure configuration tested. These findings apply to the specific configurations and methodology evaluated in the report. Every PostgreSQL workload is different, which is why independent benchmarks are most valuable as a starting point for your own performance evaluation. Performance is a system, not a single number It can be tempting to look at a database benchmark and attribute the result to one component. In practice, PostgreSQL performance is more interconnected. A transaction-intensive workload can be constrained by CPU, storage IOPS, throughput, latency, query behavior, connection patterns, or a combination of these factors. Increasing the capability of one layer will not automatically improve application performance if another layer becomes a bottleneck. Storage is an especially important part of that equation for OLTP workloads. The Azure configuration in the Principled Technologies study used Premium SSD v2, which gives customers flexibility to configure storage capacity, IOPS, and throughput independently, within supported limits. That flexibility can help teams align storage resources more closely with the characteristics of their workload instead of treating storage capacity and performance as the same sizing decision. The benchmark should not be interpreted as showing that storage alone produced the performance difference. The results reflect the complete configurations tested, including Dv6 compute, Premium SSD v2, PostgreSQL configuration, and the characteristics of the TPROC-C workload. The practical takeaway is straightforward: understanding where your workload is constrained is essential to making the right scaling decision. Expanding storage choices for demanding PostgreSQL workloads We are continuing to expand the storage options available for Azure Database for PostgreSQL, giving customers more flexibility as workload requirements evolve. Azure Ultra Disk is now available in preview for Azure Database for PostgreSQL, providing another storage option for I/O-intensive workloads that require high levels of IOPS and throughput with low latency. Like Premium SSD v2, Ultra Disk allows customers to configure storage capacity and performance independently within supported limits. We are also bringing storage autogrow for Premium SSD v2, helping customers address a different operational challenge: capacity growth. Storage autogrow is designed to automatically increase provisioned storage as available capacity becomes constrained, reducing the need for teams to manually manage storage expansion. These capabilities were not used in the Principled Technologies benchmark, and they should not be viewed as drivers of the results. Instead, they represent the next step in giving PostgreSQL teams more options to match storage infrastructure to their application requirements. That distinction matters. A workload approaching its storage capacity limit has a different problem from one constrained by IOPS or latency. Autogrow can help address capacity management, while a workload with demanding I/O requirements may warrant evaluating a different storage configuration or tier. The goal is always to give teams the flexibility to make that choice based on evidence. So how do you make that decision? Start with the workload Benchmarks can provide a useful reference point, but the best performance plan starts with your own application. As you evaluate PostgreSQL infrastructure, consider a few questions: What does peak demand look like? Measure sustained and peak transaction volume rather than relying only on averages. Where is the workload constrained? Look across CPU utilization, IOPS, throughput, storage latency, query execution, and connection behavior. How quickly is the database growing? Capacity requirements and performance requirements do not always grow at the same rate. What availability architecture does the application require? Test performance with the same HA configuration you expect to use in production. Does your test reflect production behavior? Representative data volumes, concurrency, query patterns, and transaction characteristics matter. The Principled Technologies study provides one useful data point. Under the specific 16-vCPU configurations and TPROC-C methodology tested, Azure Database for PostgreSQL - flexible server delivered higher OLTP throughput than the tested Amazon RDS for PostgreSQL configurations, both with and without high availability enabled. For us, the takeaway goes beyond the benchmark percentage. As PostgreSQL workloads become more demanding, teams need the ability to align compute, storage, and availability with the characteristics of their applications. With Dv6 compute, Premium SSD v2, expanding storage capabilities such as Ultra Disk, and greater automation for storage management, Azure Database for PostgreSQL Flexible Server continues to give teams more options for doing exactly that. Read the full Principled Technologies report to explore the configurations, methodology, and results, and use the findings as a starting point for testing the workloads that matter most to your applications.June 2025 Recap: Azure Database for PostgreSQL
Hello Azure Community, We have introduced a range of exciting new features and updates to Azure Database for PostgreSQL in June. From general availability of PG 17 to public preview of the SSD v2 storage tier for High Availability, there have been some significant feature announcements across multiple areas in the last month. Stay tuned as we dive deeper into each of these feature updates. Before that, let’s look at POSETTE 2025 highlights. POSETTE 2025 Highlights We hosted POSETTE: An Event for Postgres 2025 in June! This year marked our 4th annual event featuring 45 speakers and a total of 42 talks. PostgreSQL developers, contributors, and community members came together to share insights on topics covering everything from AI-powered applications to deep dives into PostgreSQL internals. If you missed it, you can catch up by watching the POSETTE livestream sessions. If this conference sounds interesting to you and want to be part of it next year, don’t forget to subscribe to POSETTE news. Feature Highlights General Availability of PostgreSQL 17 with 'In-Place' upgrade support General Availability of Online Migration Migration service support for PostgreSQL 17 Public Preview of SSD v2 High Availability New Region: Indonesia Central VS Code Extension for PostgreSQL enhancements Enhanced role management Ansible collection released for latest REST API version General Availability of PostgreSQL 17 with 'In-Place' upgrade support PostgreSQL 17 is now generally available on Azure Database for PostgreSQL flexible server, bringing key community innovations to your workloads. You’ll see faster vacuum operations, richer JSON processing, smarter query planning (including better join ordering and parallel execution), dynamic logical replication controls, and enhanced security & audit-logging features—backed by Azure’s five-year support policy. You can easily upgrade to PostgreSQL 17 using the in-place major version upgrade feature available through the Azure portal and CLI, without changing server endpoints or reconfiguring applications. The process includes built-in validations and rollback safety to help ensure a smooth and reliable upgrade experience. For more details, read the PostgreSQL 17 release announcement blog. General Availability of Online Migration We're excited to announce that Online Migration is now generally available for the Migration service for Azure Database for PostgreSQL! Online migration minimizes downtime by keeping your source database operational during the migration process, with continuous data synchronization until cut over. This is particularly beneficial for mission-critical applications that require minimal downtime during migration. This milestone brings production-ready online migration capabilities supporting various source environments including on-premises PostgreSQL, Azure VMs, Amazon RDS, Amazon Aurora, and Google Cloud SQL. For detailed information about the capabilities and how to get started, visit our Migration service documentation. Migration service support for PostgreSQL 17 Building on our PostgreSQL 17 general availability announcement, the Migration service for Azure Database for PostgreSQL now fully supports PostgreSQL 17. This means you can seamlessly migrate your existing PostgreSQL instances from various source platforms to Azure Database for PostgreSQL flexible server running PostgreSQL 17. With this support, organizations can take advantage of the latest PostgreSQL 17 features and performance improvements while leveraging our online migration capabilities for minimal downtime transitions. The migration service maintains full compatibility with PostgreSQL 17's enhanced security features, improved query planning, and other community innovations. Public Preview of SSD v2 High Availability We’re excited to announce the public preview High availability (HA) support for the Premium SSD v2 storage tier in Azure Database for PostgreSQL flexible server. This support allows you to enable Zone-Redundant HA using Premium SSD v2 during server deployments. In addition to high availability on SSDv2 you now get improved resiliency when using Premium SSD v2 with zone-redundant HA, helping customers build resilient, high-performance PostgreSQL applications with minimal overhead. This feature is particularly well-suited for mission-critical workloads, including those in financial services, real-time analytics, retail, and multi-tenant SaaS platforms. Key Benefits of Premium SSD v2: Flexible disk sizing: Scale from 32 GiB to 64 TiB in 1-GiB increments Fast failovers: Planned or unplanned failovers typically around 10 seconds Independent performance configuration: Achieve up to 80,000 IOPS and 1,200 Mbps throughput without resizing your disk. Baseline performance: Free throughput of 125 MB/s and 3,000 IOPS for disks up to 399 GiB, and 500 MB/s and 12,000 IOPS for disks 400 GiB and above at no additional cost. For more details, please refer to the Premium SSD v2 HA blog. New Region: Indonesia Central New region rollout! Azure Database for PostgreSQL flexible server is now available in Indonesia Central, giving customers in and around the region lower latency and data residency options. This continues our mission to bring Azure PostgreSQL closer to where you build and run your apps. For the full list of regions visit: Azure Database for PostgreSQL Regions. VS Code Extension for PostgreSQL enhancements The brand-new VS code extension for PostgreSQL launched in mid-May and has already garnered over 122K installs from the Visual Studio Marketplace! And the kickoff blog about this new IDE for PostgreSQL in VS Code has had over 150K views. This extension makes it easier for developers to seamlessly interact with PostgreSQL databases. We have been committed to make this experience better and have introduced several enhancements to improve reliability and compatibility updates. You can now have better control over service restarts and process terminations on supported operating systems. Additionally, we have added support for parsing additional connection-string formats in the “Create Connection” flow, making it more flexible and user-friendly. We also resolved Entra token-fetching failures for newly created accounts, ensuring a smoother onboarding experience. On the feature front, you can now leverage Entra Security Groups and guest accounts across multiple tenants when establishing new connections, streamlining permission management in complex Entra environments. Don’t forget to update to the latest version in the marketplace to take advantage of these enhancements and visit our GitHub repository to learn more about this month’s release. If you learn best by video, these 2 videos are a great way to learn more about this new VS Code extension: POSETTE 2025: Introducing Microsoft’s VS Code Extension for PostgreSQL Demo of using VS code extension for PostgreSQL Enhanced role management With the introduction of PostgreSQL 16, a strict role hierarchy structure has been implemented. As a result, GRANT statements that were functional in PostgreSQL 11-15 may no longer work in PostgreSQL 16. We have improved the administrative flexibility and addressed this limitation in Azure Database for PostgreSQL flexible server across all PostgreSQL versions. Members of ‘azure_pg_admin’ can now manage, and access objects owned by any role that is non-restricted, giving control and permission over user-defined roles. To learn more about this improvement, please refer to our documentation on roles. Ansible collection released for latest REST API version A new version of Ansible collection for Azure Database for PostgreSQL flexible server is now released. Version 3.6.0 now includes the latest GA REST API features. This update introduces several enhancements, such as support for virtual endpoints, on-demand backups, system-assigned identity, storage auto-grow, and seamless switchover of read replicas to a new site (Read Replicas - Switchover), among many other improvements. To get started with using please visit flexible server Ansible collection link. Azure Postgres Learning Bytes 🎓 Using PostgreSQL VS code extension with agent mode The VS Code extension for PostgreSQL has been trending amongst the developer community. In this month's Learning Bytes section, we want to share how to enable the extension and use GitHub Copilot to create a database in Agent Mode, add dummy data, and visualize it using the Agent Mode and VS Code extension. Step 1: Download the VS code Extension for PostgreSQL Step 2: Check GitHub Copilot and Agent mode is enabled Go to File -> Preferences -> Settings (Ctrl + ,). Search and enable "chat.agent.enabled" and "pgsql copilot.enable". Reload VS Code to apply changes. Step 3: Connect to Azure Database for PostgreSQL Use the extension to enter instance details and establish a connection. Create and view schemas under Databases -> Schemas. Step 4: Visualize and Populate Data Right-click the database to visualize schemas. Ask the agent to insert dummy data or run queries. Conclusion That's all for the June 2025 feature updates! We are dedicated to continuously improve Azure Database for PostgreSQL with every release. Stay updated with the latest updates to our features by following this link. Your feedback is important and helps us continue to improve. If you have any suggestions, ideas, or questions, we’d love to hear from you. Share your thoughts here: aka.ms/pgfeedback We look forward to bringing you even more exciting updates throughout the year, stay tuned!1.1KViews3likes0Comments
Postgres MCP Server: Connect AI coding agents to PostgreSQL
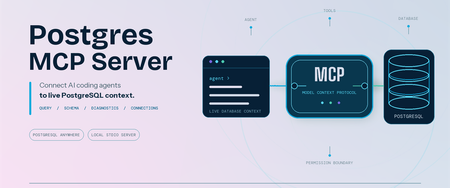
Coding agents can write SQL, troubleshoot applications, and reason about data. Useful database work starts with your schema and environment context. We are pleased to announce that Microsoft has open-sourced the Postgres MCP Server under the MIT License. Built entirely in Rust for fast, resource-efficient operation, it connects Model Context Protocol (MCP) compatible coding agents to PostgreSQL, so your agent can inspect real database context and run permitted operations. The server works with PostgreSQL locally, on-premises, on Azure, AWS, GCP, or through another PostgreSQL-compatible service. It is built for anyone who works with PostgreSQL through a coding agent, including application developers, database administrators, data professionals, platform engineers, and PostgreSQL enthusiasts. Give AI agents live PostgreSQL context The Postgres MCP Server exposes PostgreSQL operations as tools that your coding agent can call. After connecting to a profile, ask: "List the tables in my PostgreSQL database." "Show me the ten most recent orders." "Generate the schema for these tables and indexes." "What is slowing down my PostgreSQL server?" The tools let your agent: Generate queries and run analytics. Run read-only SQL or use separate tools for data and schema changes. Explore and design schemas. Inspect tables, indexes, functions, sequences, and other database objects before generating database changes. Diagnose performance. Detect server capabilities and collect focused performance metrics for the server and its queries. Manage connections. Create named connection profiles, connect to the right database, and switch between environments without placing credentials in the MCP client configuration. Install and connect securely Prerequisites: Node.js 22 or later, which includes npm and npx. Linux x64 or arm64, macOS x64 or arm64, or Windows x64. Windows on Arm uses x64 emulation. An MCP-compatible coding agent or client. A reachable PostgreSQL or wire-compatible database and a database role with the permissions needed for your intended tasks. No separate installation is required when you use npx; it downloads and runs the package for you. If you prefer the postgres-mcp command to be available globally, install the package: npm install --global @Microsoft/postgres-mcp The examples use npx. With a global installation, replace npx -y Microsoft/postgres-mcp with postgres-mcp. Create a profile and store its password: npx -y @Microsoft/postgres-mcp connection add local \ "postgresql://postgres@localhost:5432/postgres" npx -y @Microsoft/postgres-mcp connection set-password local The server stores the password in your operating system keyring, separate from the profile. For headless or CI environments without a keyring, use the environment-based connection option. Add the server to clients that use the mcpServers configuration: { "mcpServers": { "postgres": { "command": "npx", "args": ["-y", "@microsoft/postgres-mcp", "run"] } } } Configuration formats and file locations differ by client. The Postgres MCP usage guide includes examples for supported clients. For Azure Database for PostgreSQL, the server can use Microsoft Entra ID when a saved profile does not contain a password. PostgreSQL role permissions remain the security boundary. New profiles permit write tools unless you set access_mode: ro. For exploration, combine that setting with a read-only database role. Your MCP client controls approval prompts, and CSV tools can read only from approved local paths. Add expert PostgreSQL skills The open-source Postgres Skills repository complements the MCP server with expert guidance for query performance, indexing, vector search, security, operations, Azure workflows, and AI and knowledge graph scenarios. These reusable instructions help coding agents apply PostgreSQL best practices when investigating an issue or completing a task, while the MCP server supplies the live database context and permitted operations needed to act on that guidance. Next steps Explore the Postgres MCP Server repository. Review the Postgres MCP usage and security guide. Follow the Postgres Skills plugin setup guide. Share feedback or contribute through Postgres MCP GitHub issues. Thank you!1.6KViews0likes1Comment
Rethinking Memory Management for Azure HorizonDB on Disaggregated Storage
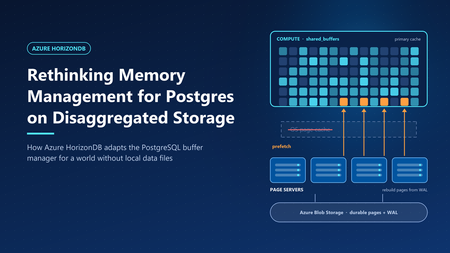
In Smarter Storage for Azure HorizonDB, we described how HorizonDB moves durability, replication, checkpointing, and recovery out of PostgreSQL and into a purpose-built storage layer. The compute node writes only the write-ahead log (WAL). Data pages are rebuilt and stored by remote page servers. That design raises an obvious question: if PostgreSQL no longer reads and writes its own data files, what happens to its memory management? PostgreSQL's buffer manager was built around a specific partner: the operating system's page cache. Many of its defaults and heuristics only make sense because the kernel is quietly doing a lot of work underneath. HorizonDB removes that partner. This post explains which assumptions broke, and the changes we made to the PostgreSQL engine, so memory works well on disaggregated storage. What PostgreSQL assumes about the kernel PostgreSQL stores each table and index as ordinary files and accesses them with buffered I/O. Every page therefore can live in two places in memory: in PostgreSQL's own buffer pool (shared_buffers) and in the operating system's page cache. This "double buffering" is a deliberate part of the design, and it shapes several behaviors. A modest buffer pool. The PostgreSQL documentation suggests starting shared_buffers at about 25% of system memory. Much of the rest is expected to act as kernel file cache. A page evicted from shared_buffers is often still in the kernel cache, so reading it back costs a memory copy rather than a disk read. Prefetching is a hint to the kernel. When PostgreSQL knows it will need a page soon—during a bitmap heap scan, for example—it calls posix_fadvise with POSIX_FADV_WILLNEED. The kernel starts reading the page into its cache. A later read finds it there. PostgreSQL itself never allocates a buffer for the prefetched page. Sequential scans rely on kernel readahead. For sequential access, the kernel detects the pattern and reads ahead automatically, so PostgreSQL can issue fewer explicit hints. Ring buffers protect the cache. Large sequential scans, VACUUM, and bulk writes such as COPY use a small private ring of buffers—from a few hundred kilobytes to a few megabytes—instead of the whole buffer pool. A scan of a table much larger than memory therefore cannot push the working set out of shared_buffers. This is safe because a page that cycles through the ring is usually still in the kernel cache if it is needed again. Writes are cheap and deferred. When a dirty buffer is evicted, PostgreSQL writes it to the kernel cache, which flushes it to disk later. The background writer cleans buffers ahead of eviction so that queries rarely wait for a write. Checkpoints write all dirty pages and call fsync to make them durable. Each of these behaviors assumes that a miss in shared_buffers is usually cheap, and that writing a page means writing it to a local file. What changes in HorizonDB Figure 1. Compute memory layout: Community PostgreSQL vs. Azure HorizonDB. In HorizonDB, permanent tables and indexes do not exist as local files on the compute node. There is no kernel page cache holding database pages. A miss in shared_buffers must be served by the remote storage layer: Tier Where it lives Typical role Shared buffers Compute memory Working set; all pages are read and modified here SSD cache Compute local disk Extends shared buffers; holds cached copies of pages Page servers Remote storage fleet Page cache of the current version of every page Azure Blob Storage Remote, zone-redundant Durable backing store for pages and WAL A page that falls out of memory no longer drops into a free kernel cache. It may require a network round trip to a page server, which is much more expensive than a memory read. Writes change too. Because page servers rebuild pages from WAL, "writing" a dirty page on the compute node does not mean copying it anywhere. PostgreSQL only has to make sure the WAL describing the change is durable - a rule it already enforces before any page write. Taken together, this inverts the trade-offs behind PostgreSQL's defaults. Memory is no longer one of two caches. It is the primary cache. Design principle: shared buffers are the primary cache We organized the engine changes around one principle. shared_buffers is the primary cache, eliminating the memory overhead of double buffering and improving memory efficiency. Every page that is about to be needed should arrive in memory before the query asks for it. The following sections describe the engine changes that implement it. 1. Size shared buffers for the machine Without a kernel cache to share memory with, leaving 75% of RAM to the operating system would waste most of it. HorizonDB sizes shared_buffers automatically at 60–70% of the compute node's memory, depending on the size of the instance. The remaining memory is left for connections, query execution memory such as sorts and hashes, and the operating system. 2. Retire ring buffers Ring buffers exist so that a large scan can use a few megabytes of memory and rely on the kernel cache for anything it needs again. In HorizonDB, there is no such safety net. Recycling a small ring means that every page the scan touches is read, used once, and discarded—and a second scan of the same table must fetch everything again from storage. Ring buffers also exist to limit write traffic: a bulk operation that dirties pages in a small ring must write them out quickly. HorizonDB doesn't need to write dirty data pages back to disk at all, so that motivation disappears as well. HorizonDB therefore disables buffer ring strategies. Sequential scans, VACUUM, and bulk loads use the shared buffer pool like any other query. This is a trade-off, not a free win. A very large scan can now displace pages from shared_buffers that other queries were using. Two factors limit the cost. First, clock-sweep replacement tracks how often each buffer is used, so frequently accessed pages outlive pages a scan touched only once—and buffer replacement is an area we continue to improve. Second, pages that leave shared_buffers are not simply lost: HorizonDB can keep them close by in the local SSD cache. How it decides and what goes there is a story for a separate post. 3. Prefetch directly into shared buffers On a local disk, a prefetch miss costs a disk seek. On disaggregated storage, it costs a network round trip. Hiding that latency matters even more, so HorizonDB makes prefetching explicit, aggressive, and memory aware. Prefetch requests go to the page servers. When PostgreSQL issues a prefetch, HorizonDB sends a read request for the page to the page server that owns it, and does not wait for the answer. Each backend keeps a set of outstanding requests by default, so dozens of page reads overlap instead of running one after another. Sequential scans prefetch explicitly. PostgreSQL's read stream mechanism, which drives sequential scans and other block-range reads, normally avoids prefetching sequential blocks because it expects kernel readahead to cover them. HorizonDB turns that assumption off, so sequential reads are prefetched like any other access pattern. Responses land in their final buffer. In stock PostgreSQL, a prefetch only warms the kernel cache, so the later read still has to copy the page into shared_buffers. In HorizonDB, the page server's response goes straight into a shared buffer. When the query asks for the page, it is already in memory, with no extra copy and no second request to storage. These are only some of the prefetch optimizations we have built into the engine. Others use custom prefetch implementations and logic that tunes how far ahead each query reads. All of them share one goal: hiding storage latency so queries spend less time waiting on I/O and more time doing useful work. What this means for you As a fully managed service, our goal is to delight customers with a best-in-class PostgreSQL experience. You shouldn't have to think about kernel caches, buffer rings, or prefetch windows—that is our job. HorizonDB retains full PostgreSQL compatibility, so applications keep the familiar Postgres programming interface while the engine is tuned to deliver predictable performance on the storage underneath683Views5likes1CommentA Single View of Your PostgreSQL Estate: Database Hub in Public Preview
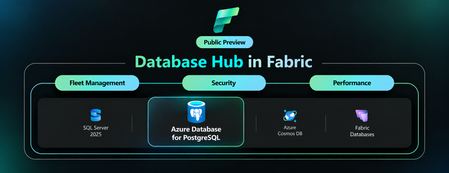
By Varun Dhawan, Matt McFarland, Erdem Tuna from Microsoft PostgreSQL team Azure Database for PostgreSQL support in Database Hub is now in public preview, bringing fleet visibility, security posture, and performance monitoring into one place. This preview is part of the broader vision outlined in our SQLCon Barcelona 2026 announcement: bringing database signals together so teams can see where attention is needed and take a well-informed next step. Here, we focus on the Azure PostgreSQL experience in Database Hub. Database Hub in Microsoft Fabric lets you monitor existing flexible servers in their Azure subscriptions and regions, without moving or mirroring data or building a new customer-managed telemetry pipeline. Baseline monitoring uses existing Azure Monitor metrics. Available capabilities vary by database service. Start with a practical question: Which PostgreSQL servers show sustained memory pressure, and which should I investigate first? Follow the three views below to narrow the scope and compare trends. See the PostgreSQL monitoring guide for setup and preview details. 1. Start with an estate-wide Overview Overview brings cross-engine findings and performance summaries into one starting point. Spot a signal worth investigating, such as elevated PostgreSQL memory usage, then open Estate to focus on the relevant resources. Figure 1: Overview combines cross-engine findings with performance summaries, including PostgreSQL, to help prioritize investigation. Illustrative mockup with sample data. 2. Focus on your Azure PostgreSQL estate In Estate, select the PostgreSQL view and filter by subscription or resource group to define the scope for the memory-pressure investigation. Compare the flexible servers you can access before choosing resources to examine: Filter your PostgreSQL estate by subscription or resource group to focus on the servers you manage. Review a flexible server's resource details in one place. The inventory represents server instances, not each database hosted inside them. Save and share a custom view for a scope you revisit regularly. Colleagues see only the resources their existing permissions allow. Figure 2: Estate filtered to PostgreSQL, bringing flexible server resources, status, findings, and subscription context into one inventory. Illustrative mockup with sample data. Once you have scoped your estate, switch to Performance and select the PostgreSQL servers you want to investigate. 3. Review security posture and performance Security posture In public preview, Database Hub assesses four aspects of your Azure PostgreSQL security configuration: Microsoft Entra authentication: identify servers where it is not enabled. Encryption at rest using customer-managed keys: review key management against your organization's policy. A server using service-managed keys is still encrypted at rest. Microsoft Entra authentication enforced: review whether Microsoft Entra authentication is required, rather than only available as an option. Public Network Access Disabled: review public exposure against your network policy. The private networking guidance explains the virtual network integration option. Performance monitoring In Performance, select the PostgreSQL dashboard and use CPU, memory, and storage summaries to identify servers that need a closer look. You can also review disk activity, connections, failed connections, and applicable read-replica lag. For the memory-pressure question, compare server trends over the same interval to distinguish sustained pressure from a brief spike. Use the Azure Monitor metric reference to match units and aggregation. Missing data is not proof of good health. Figure 3: Performance monitoring with PostgreSQL selected, illustrating utilization summaries and trends for closer investigation. Illustrative mockup with sample data. When a server needs a deeper look, continue in the Azure portal and PostgreSQL tools using the monitoring and diagnostics guidance. Preview scope: Monitoring is metric-based; query-level diagnostics remain in native PostgreSQL tools. Security findings are not a complete compliance audit. Database Hub does not automatically tune, resize, or remediate PostgreSQL servers. Check the servers selected in Performance: dashboard scope can differ from the Estate inventory. Why this matters if you run Postgres at scale Database Hub doesn't replace your PostgreSQL expertise or native tools. It reduces the work of finding which servers need attention, alongside your other supported database engines including SQL Database and Cosmos DB. The Database Hub FAQ explains the access boundaries and how the experiences fit together. Get started Review the Database Hub documentation and PostgreSQL prerequisites, then: Enable the preview: Ask your Fabric administrator to enable Users can access the Database hub (preview) in Tenant settings. Check access: Use a Microsoft Entra identity with Reader or greater permissions on each subscription containing the servers you want to monitor. Start here: open Database Hub in Microsoft Fabric. Scope your estate: In Estate, choose View: PostgreSQL and filter to the subscriptions or resource groups you manage. Compare servers: In Performance, select PostgreSQL, choose the servers to compare, and set the same time range and aggregation. Access boundary: Resource visibility and shared views do not grant permission to query databases. Existing PostgreSQL authentication and network controls still apply. As your PostgreSQL estate grows, Database Hub brings the bigger picture into focus, helping you see where attention is needed and take a more informed next step. We're excited to bring Azure PostgreSQL into this shared experience. Explore the public preview in Microsoft Fabric and discover a simpler way to stay on top of your PostgreSQL estate.445Views3likes2Comments
Database Change Management - Azure Database for PostgreSQL, GitHub Actions and Liquibase OSS
Introduction Database Change Management (DCM) is a comprehensive process of managing all changes to the database schema, objects, reference data, and code over the lifetime of an application. It encompasses version control, testing, deployment, and tracking of database evolutions in a consistent, reliable, and auditable manner. In modern DevOps practices, treating database changes just like application code helps maintain integrity across environments and reduces the risk of errors. Handling Database Change Management using Git Integrating database change management with GitHub brings the rigor, predictability, and safety of standard software development to relational database schemas. Much like application code deployments, where features are developed on feature branches, peer-reviewed via Pull Requests (PRs), and merged only after passing automated test suites. When integrated with GitHub Actions, database deployments transition from manual, error-prone runbooks executed by DBAs into fully automated, repeatable pipelines. When a pull request is merged into the master branch, GitHub triggers a workflow that automatically validates changelogs, dry-runs SQL changes against ephemeral test databases, and updates staging or production database servers, ensuring that database schema structures remain in perfect, synchronized step with the application code they support. Approach To implement database change management, multiple tools and frameworks must be used to handle automation, integrated approach and version management. Following Azure, Git and open-source tools will be used in this approach: Azure database for PostgreSQL (or Azure SQL database) GitHub repo GitHub actions Liquibase (open-source DB version control tool) Database schema migrations (using tools like Liquibase) are treated as declarative, version-controlled source files. This alignment allows teams to leverage the key advantages of Git: A single source of truth for database state A comprehensive and immutable audit trail of who modified what and when Ability to easily revert problematic schema changes by rolling back code commits. Tool Used – Liquibase Liquibase is an open-source, database-independent schema migration tool that treats database changes as code to automate continuous integration and deployment (CI/CD) pipelines. It operates by evaluating a user-defined core manifest file known as a Changelog, which contains granular, ordered tracking units called ChangeSets authored in SQL, YAML or JSON. When executed against a target database instance, the Liquibase engine checks the database's internal DATABASECHANGELOG tracking table to identify previously applied changesets by matching their unique combination of ID, Author, execution Filep and tag. Unexecuted changes (written in JSON or YAML) are dynamically translated via specialized JDBC drivers into dialect-specific SQL (such as PostgreSQL, SQL Server etc.) and executed within a single transaction wrapper. Beyond structural upgrades (update), Liquibase provides robust operational functionalities including Rollback capabilities, which allow to revert schema states back to targeted baseline schema tags or specific timestamps by executing explicit, user-defined “--rollback” blocks in reverse chronological order. Furthermore, it features comprehensive schema difference management via the “diff” and diff-changelog engines. This allows engineers to perform automated schema drift detection by comparing an active database against a reference baseline (or another active environment), instantly identifying disparities in tables, columns, indexes, or constraints, and auto-generating the exact operational changesets required to bring the environments back into structural synchronization. Migration-based Approach When managing database migrations, Liquibase provides three structural configuration patterns to declare and execute schema changes across environments: SQL, YAML, and JSON. Sample of SQL Changelog is given below. It follows SQL syntax of native database engine (PostgreSQL in this case): The Formatted SQL approach is highly recommended for database administrators and developers who require low-level control, as it uses standard, platform-native SQL scripts annotated with special comment tokens (like --changeset and --rollback) to direct the Liquibase parser. In contrast, the YAML and JSON approaches use a database-agnostic, declarative key-value abstraction model. Instead of raw DDL, developers define structural states using structural objects (such as “createTable” or “addColumn” fields). The Liquibase engine dynamically compiles these JSON/YAML objects into dialect-specific SQL using target JDBC drivers at runtime, while automatically inferring the exact inverse commands required for database rollbacks. Regardless of whether a team implements raw SQL for precise indexing and database-specific performance optimizations or leverages the strict serialization of JSON/YAML to maintain standardized, cross-platform migrations, all three file types integrate seamlessly into version control as a single source of truth for CI/CD automation. Versioning and Repeatable Migrations Liquibase governs schema versioning and repeatable migrations through a combination of tracking states and distinct changeset configurations. Unlike traditional application version numbering, Liquibase applies a state-driven versioning model where every discrete schema modification is tracked as an individual, ordered “changeset” identified by a unique composite key consisting of the id, author, changelog file and tag. When a deployment pipeline runs, the Liquibase engine queries the target database’s internal DATABASECHANGELOG table to evaluate this composite key signature; if the key exists, the migration is skipped to preserve environment stability. Architecture Overview A robust database change management architecture involves several key Azure components working together. At the core is Azure Database for PostgreSQL (Flexible Server) as the production-grade target database, often deployed with private endpoint connectivity to restrict network access. GitHub hosts the repository containing Liquibase migration scripts. GitHub Actions orchestrates CI/CD pipelines; a self-hosted runner, placed within the same Azure Virtual Network (VNet) as the database, executes Liquibase commands to apply migrations securely with minimal network latency. Secrets such as database connection strings and credentials are stored securely in Azure Key Vault or GitHub Secrets. Workflows use the Azure/login and azure/get-keyvault-secrets actions to fetch Azure secrets at runtime. GitHub secrets are fetched automatically when referenced in the workflow. Liquibase updates the “DATABASECHANGELOG” table on the PostgreSQL instance each time a migration is applied, providing full tracking. This formation ensures that all database changes are automated, auditable, and under version control. Following are the architectural components: GitHub repo containing the DDL/DCL scripts to be applied to the database engine. GitHub actions containing the workflow that can be scheduled based on push or commit or at a time. GitHub actions self-hosted runner on Azure VM. Azure PostgreSQL database instance where changes are to be applied. Following architecture uses same SQL scripts for multi-environment deployment. Azure Database for PostgreSQL Configuration Azure Database for PostgreSQL should be configured with a private endpoint and integrated into the Virtual Network to ensure self-hosted runner has secure, internal access. Appropriate database schemas should already be available. User account that is to be used for Liquibase migrations should have necessary access like create and modify tables, “DATABASECHANGELOG” table which Liquibase uses to track applied migrations. GitHub “secrets” or Azure Key Vault should be used to store database connection and user details. Rollback action can be used to revert database changes, however, point-in-time restore (PITR) backups should be enabled so that database can be reverted to previous states if migration causes unintended effects. Set firewall rules to restrict public access, configure SSL connections to enforce encrypted traffic for database communication. Azure Monitor should be used to capture audit logs. GitHub Actions and Self-hosted Runner GitHub Actions workflows will execute Liquibase commands, set up a self-hosted runner within the same VNet as the Azure Database fir PostgreSQL server. Provision a lightweight Azure VM (Linux recommended). Following software needs to be installed: OpenJDK Liquibase “psql” PostgreSQL client tool. GitHub Actions runner application and register it with the repository, assigning it labels (e.g., self-hosted) so workflows can target it. Attach Azure managed identity (system or user assigned) with necessary RBAC permissions to retrieve secrets from Azure Key Vault at runtime and connect to database. Liquibase Configuration Liquibase configuration contains two files as mentioned below: Changelog file – Database SQL statements pertaining to the changes. This file is the major component of the configuration as it would contain SQL statements that are to be applied to the database. E.g. postgresdb.changelog.sql. The file should follow Liquibase formatted SQL syntax. liquibase.properties – Contains peripheral details like schema and changelog configuration. Following are the key configuration parameters: changeLogFile=postgres_changelog/postgresdb.changelog.sql : Location of database changelog file relative to the location of where liquibase.properties file is stored. defaultSchemaName : Schema name in postgres database where changes will be applied. liquibaseSchemaName : Schema name in postgres database where Liquibase tracking tables will be created. logLevel : Level of logging by Liquibase execution. databaseChangeLogTableName and databaseChangeLogLockTableName : Liquibase tracking tables. Keep the default values. Setup & Execution Steps Please use the following GitHub repo to download all resources required for implementation. https://github.com/deepcontent2208/db_change_mgmt_liquibase_github.git CI/CD Pipeline Configuration CI Pipeline The Continuous Integration (CI) workflow in GitHub Actions should focus on validating migration scripts before they are merged into the main branch. Use triggers on pull requests targeting main. Begin steps by checking out the repository using actions/checkout@v4, ensuring that the sql migration and “liquibase.properties” files are available locally. Database authentication details can be stored either in Azure Key Vault or GitHub Secrets. These details will be extracted dynamically during workflow execution. Following is the code snippet for extraction: Next, execute Liquibase validate CI, by invoking CI GitHub workflow. Capture and report any validation errors to prevent faulty migrations from entering the code base. CD Pipeline Continuous Deployment (CD) workflows apply the validated migrations to target environments. Use on-demand triggers with workflow_dispatch for production deployments to avoid accidental changes. In your workflow configuration, after actions/checkout@v4, authenticate and fetch Key Vault secrets similarly to the CI pipeline. You may add environment approvals (GitHub Environments) for prod. 3 different CD workflows are being used – “Database Deployment”, “Database Rollback” and “Database Schema Drift”. Following is the architecture of schema deployment; it uses same repo to deploy across environments. Invoke Liquibase CD workflow pipeline to implement the changes. The same pipeline/workflow will work for DEV, QA and PROD as it is parameterized. Workflow will use the same SQL changelog file for all environments to ensure schema consistency across environments unless developers decide to use different SQL changelogs for different environments. Following snippet shows parameters for workflow execution. Release “tag” should be provided with proper tags. It will ensure Rollback can be done to the provided “tag”. Conclusion Database change management is critical for maintaining application integrity and enabling continuous delivery. Liquibase provides a mature and reliable framework for tracking, versioning, and applying schema changes and rollback in a production environment. By integrating Liquibase with Azure Database for PostgreSQL, Azure SQL Database, Azure SQL MI, GitHub Actions, a self-hosted runner, and Azure Key Vault, teams can establish fully automated and secure CI/CD pipelines for databases. Adopting migration-based workflows, enforcing version control, leveraging environment parity, and following best practices reduces deployment risks and supports auditing and compliance requirements. As database schemas evolve, having an auditable history and the ability to apply changes in a controlled, repeatable way empowers development teams to innovate while preserving data integrity.487Views4likes2Comments