observability
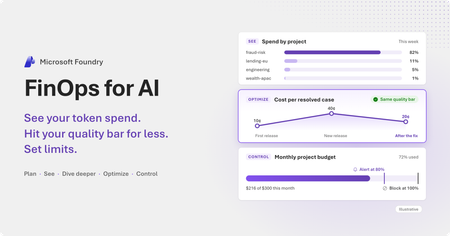
67 TopicsFinOps in Microsoft Foundry: see your token spend, hit your quality bar for less, and set limits
An end-to-end walkthrough of FinOps for AI in Microsoft Foundry: plan what an agent should cost, see where the spend goes, find out why it changed, hit your quality bar for less, and set limits.301Views0likes0CommentsYour Agents Are Running. But Are They Safe and Compliant?
An AI agent can perform perfectly and still violate your organization’s policies. Picture an enterprise running hundreds of agents across customer service, financial transactions, and internal workflows. Every operational dashboard looks healthy: tasks are completing and targets are being met. But are those agents using approved models? Accessing only authorized tools? Running the required safety protections? And when one violates a requirement, can an administrator tell which policy failed, which asset is affected, and what to change? An operationally healthy fleet isn’t necessarily a safe or compliant one. As organizations move from experimenting with individual agents to running AI across business-critical operations, it’s no longer enough to define policies and trust each team to implement them. Enterprises need to enforce the controls that matter at runtime, verify those controls actually work, and confirm, across the fleet, that they’re in place. That’s what Microsoft Foundry Safety brings together. It’s the home for the capabilities that keep agents inside the boundaries you set: Foundry Guardrails: safety controls a developer configures and Foundry applies at runtime. agent controls: the managed policy engine underneath Guardrails, enforcing deterministic rules, classifiers, and LLM-based judgments across frameworks and clouds. Safety Rubric Evaluators: spec-driven evaluations that measure whether a control actually holds, before and after you ship. AI Red Teaming Agent: adversarial probing that finds failures before an attacker does. Compliance dashboard: the new experience that confirms, across your entire fleet, that these controls are assigned, in place, and holding. Each of these has its own story. Governing hundreds or thousands of agents is a different challenge than building one. The new Manage experience in Microsoft Foundry brings fleet inventory, operational telemetry, cost, and compliance into a single view. The Foundry Governance blog walks through Fleet, Operations, and Cost in depth. This post, however, focuses on the capabilities that tells you whether your fleet is safe and compliant. Compliance: from requirements to action At the center of this experience is Foundry Manage → Compliance, bringing together relevant governance signals from Azure Policy, Microsoft Defender for Cloud, and Microsoft Purview. Four complementary views help administrators investigate their AI estate: Compliance view What it helps answer Policy Which organizational policies apply, and where are violations occurring? Asset Is a particular agent, model deployment, or toolbox compliant? Security posture Which security recommendations require attention? Data security & governance What Purview coverage and data-security findings are relevant to my AI assets? Understand compliance from the policy or the asset Administrators and developers come to Compliance with different questions. An administrator may start with an organization-wide requirement and ask which resources violate it, across a subscription or resource group. A developer is more likely to start with a particular agent and ask which policy it failed, why, and what needs to change. The Policy and Asset views support these complementary workflows. Through its integration with Azure Policy, Microsoft Foundry brings organizational governance into the context of your AI estate. Administrators can define and assign policies at the appropriate scope, review compliance status, identify violating assets, and investigate policy requirements. These capabilities span model deployments, agent configurations, tools, network egress, and safety controls, as outlined below: Policy category What organizations can govern Models Restrict deployments to approved models or publishers and enforce model eligibility requirements, such as excluding preview models. Agents Govern approved agent types and trusted Hosted Agent container images. Tools Govern tool usage and connections, including approved tool types, MCP endpoints, and connectors. Network egress Control which outbound destinations hosted agents are permitted to access. Safety controls Establish requirements for safety guardrails, such as harmful-content filtering, jailbreak protection, indirect-attack protection, and custom controls. For example, an organization might establish a policy restricting AI deployments to an approved set of models. In Manage → Compliance → Policy, an administrator can review the assigned policy, examine its scope and configured parameters, understand whether it is compliant, and identify the exact model deployments that violate the requirement. They can also inspect the policy definition, enforcement effect, and available evaluation details to understand why an asset is noncompliant. For changes to assignments or exemptions, Foundry links to the relevant Azure Policy management experience. Audit and Deny provide different levels of control. Audit identifies noncompliant resources without blocking operations. Where supported, Deny prevents new noncompliant create or update operations, while existing resources that violate the policy remain flagged until remediated. The effects available depend on the specific policy definition. This gives administrators a clearer view of not just which policies exist, but where they apply, how they are configured, and which resources require attention. The Asset view provides the complementary perspective. Starting from a flagged customer-support agent, a developer or administrator can examine the relevant policy evaluations and identify the cause: perhaps a disallowed model deployment or a missing required protection. The agent may be operating successfully from an application perspective while remaining noncompliant. Operational health and policy compliance are not the same thing. And knowing a violation exists is only useful if you can act on it. Foundry connects the affected asset to the requirement and the relevant management experience, helping teams determine whether to update a configuration, enable a protection, or follow an Azure Policy workflow. From compliance requirements to safety controls enforced at runtime Configuration compliance is essential, but agents introduce another challenge: an agent can be configured correctly and still attempt an action that violates a business rule. Imagine a financial-services agent offering a new credit product to a customer who has disclosed financial hardship, or an agent attempting a transaction above its authorized limit. These are runtime behavioral requirements that depend on what the agent is doing in the moment. That's why we're bringing more flexible safety controls into the Foundry developer experience. Define safety controls once. Apply them automatically at runtime. With Microsoft Foundry Guardrails, developers can configure safety controls through Build → Guardrails or programmatically through the API. These controls include supported built-in safety protections, such as harmful-content filtering and prompt-attack protection. The architecture is also evolving to support more expressive organization-specific requirements through deterministic business rules and LLM-based judgments. Once a guardrail policy is configured and assigned to a supported agent, Foundry automatically applies its supported controls at runtime. Developers don't need to build a separate policy-evaluation and enforcement integration for the supported Foundry-hosted execution path. The runtime invokes the applicable protections at supported intervention points and applies their decisions as part of execution. Behind this experience are our investments in the open-source Agent Control Specification (ACS), Agent Hooks, and the managed agent controls service. Agent Hooks defines where the runtime can intervene; ACS defines the policy evaluation contract; the managed service evaluates supported policies; and the Foundry runtime enforces the returned decisions. For example, consider an insurance agent processing a policyholder's request to change a beneficiary. An organization might want to require verified identity context before the update, use an LLM judge to detect possible coercion requiring escalation, and apply built-in classifiers to relevant content risks. These are illustrative policy patterns, with availability depending on the supported controls and intervention points. Developers define the boundaries. Foundry handles runtime application of assigned, supported guardrails. Azure Policy complements this experience by establishing and auditing supported organizational requirements; an Azure Policy assignment is not a prerequisite for a properly assigned guardrail to operate at runtime. For more on the underlying architecture and cross-framework integration, see agent controls announcement. Check that the control actually works: Safety Rubric Evaluators Enforcing a control and verifying it holds are two different things. Safety Rubric Evaluators (preview), built on our open-source ASSERT work, turn a plain-language safety policy plus your agent’s own definition and traces into a structured set of Allowed and Disallowed behaviors, then score conversations on two independent metrics, whether the agent did something disallowed, and whether it refused something legitimate. Measuring those separately matters: the easiest way to drive unsafe outputs to zero is to make an agent refuse everything ambiguous, and a single blended score would hide that over-refusal. Teams can generate a rubric from a policy, review and version it in the Evaluator Catalog, and re-run it before and after a mitigation to confirm a fix reduced risk without breaking legitimate user workflows. Together, the pieces form a loop: Guardrails and agent controls enforce policy at runtime, Safety Rubric Evaluators and AI Red Teaming measure whether it holds, and Compliance confirms coverage across the fleet. (Read the Safety Rubric Evaluators deep dive →) Security and data governance belong in the same view Compliance doesn't stop at resource policies and runtime guardrails. An AI resource can meet its configuration requirements and still have security weaknesses or data-exposure risks. Security posture: Microsoft Defender for Cloud The Security posture view surfaces relevant Defender for Cloud recommendations for supported resources. For example, an administrator may discover a recommendation to disable local key-based authentication on a Foundry resource, see which AI resource is affected, and navigate to Defender for deeper investigation and remediation. Data security and governance: Microsoft Purview The Data security & governance view brings relevant Microsoft Purview information into Foundry, including supported coverage information, agent interactions, and prioritized data-security findings. As agents retrieve documents and process sensitive records, administrators can investigate relevant data-protection signals in the context of their AI estate, then use Purview for specialized management and remediation. From compliance signals to action An administrator may begin in Fleet or the Policy view to assess an organization-wide requirement, identify noncompliant assets, and navigate to Azure Policy for an assignment change or exemption. A developer may begin with an agent in the Asset view, inspect the specific violation, and update its model, tool configuration, or guardrails. Both benefit from seeing the requirement and the affected asset in the same Foundry management experience. If an agent is experiencing errors or elevated latency, Operations provides relevant telemetry. If the concern is infrastructure security, teams can investigate in Defender. If it involves sensitive enterprise information, Purview provides its specialized data-security workflows. These systems retain distinct responsibilities for policy evaluation, runtime enforcement, and evidence. What changes is that teams no longer have to begin their investigations with disconnected information scattered across multiple systems. Foundry connects the AI assets organizations build with the policies, protections, and governance insights they need to operate them responsibly. Get started Building an agent that works is only the beginning. The next challenge is building an AI fleet your organization can confidently operate and govern. With Microsoft Foundry Safety, we’re bringing the capabilities that keep agents safe into one place: Guardrails and agent controls to enforce policy at runtime, Safety Rubric Evaluators and AI Red Teaming to verify it holds, and the new Compliance experience to confirm coverage across the fleet. Together with the broader Manage experience — fleet inventory, operational monitoring, and cost — these help organizations move from defining policies to enforcing, verifying, and confirming them. Ready to explore? Start in Microsoft Foundry: Manage your AI fleet: Discover your agents, models, and other AI assets across supported scopes, and understand fleet-level activity and health. Explore Compliance: Navigate to Manage → Compliance to investigate organizational policies, noncompliant assets, security recommendations, and data-governance insights. Understand Azure Policy: Learn how to establish organizational requirements, manage policy assignments, and review compliance results. Configure runtime safety with Foundry Guardrails: Navigate to Build → Guardrails or use the supported API to define and assign safety controls that Foundry automatically applies to supported agents at runtime.72Views0likes0CommentsFrom Policy to Practice: Built-In CIS Benchmarks on Azure - Flexible, Hybrid-Ready
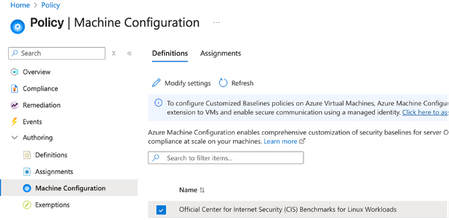
Security is more important than ever. The industry-standard for secure machine configuration is the Center for Internet Security (CIS) Benchmarks. These benchmarks provide consensus-based prescriptive guidance to help organizations harden diverse systems, reduce risk, and streamline compliance with major regulatory frameworks and industry standards like NIST, HIPAA, and PCI DSS. In our previous post, we outlined our plans to improve the Linux server compliance and hardening experience on Azure and shared a vision for integrating CIS Benchmarks. Today, that vision has turned into reality. We're now announcing the next phase of this work: Center for Internet Security (CIS) Benchmarks are now available on Azure for all Azure endorsed distros, at no additional cost to Azure and Azure Arc customers. With today's announcement, you get access to the CIS Benchmarks on Azure with full parity to what’s published by the Center for Internet Security (CIS). You can adjust parameters or define exceptions, tailoring security to your needs and applying consistent controls across cloud, hybrid, and on-premises environments - without having to implement every control manually. Thanks to this flexible architecture, you can truly manage compliance as code. How we achieve parity To ensure accuracy and trust, we rely on and ingest CIS machine-readable Benchmark content (OVAL/XCCDF files) as the source of truth. This guarantees that the controls and rules you apply in Azure match the official CIS specifications, reducing drift and ensuring compliance confidence. What’s new under the hood At the core of this update is kompli - a lightweight, open-source module developed by the Azure Core Linux team. It evaluates Linux systems directly against industry-standard benchmarks like CIS, supporting both audit and, in the future, auto-remediation. This enables accurate, scalable compliance checks across large Linux fleets. Here you can read more about kompli. Dynamic rule evaluation The new compliance engine supports simple fact-checking operations, evaluation of logic operations on them (e.g., anyOf, allOf) and Lua based scripting, which allows to express complex checks required by the CIS Critical Security Controls - all evaluated natively without external scripts. Scalable architecture for large fleets When the assignment is created, the Azure control plane instructs the machine to pull the latest Policy package via the Machine Configuration agent. kompli is integrated as a light-weight library to the package and called by Machine Configuration agent for evaluation – which happens every 15-30minutes. This ensures near real-time compliance state without overwhelming resources and enables consistent evaluation across thousands of VMs and Azure Arc-enabled servers. Future-ready for remediation and enforcement While the Public Preview starts with audit-only mode, the roadmap includes per-rule remediation and enforcement using technologies like eBPF for kernel-level controls. This will allow proactive prevention of configuration drift and runtime hardening at scale. Please reach out if you interested in auto-remediation or enforcement. Extensibility beyond CIS Benchmarks The architecture was designed to support other security and compliance standards as well and isn’t limited to CIS Benchmarks. The compliance engine is modular, and we plan to extend the platform with STIG and other relevant industry benchmarks. This positions Azure as a platform for a place where you can manage your compliance from a single control-plane without duplicating efforts elsewhere. Collaboration with the CIS This milestone reflects a close collaboration between Microsoft and the CIS to bring industry-standard security guidance into Azure as a built-in capability. Our shared goal is to make cloud-native compliance practical and consistent, while giving customers the flexibility to meet their unique requirements. We are committed to continuously supporting new Benchmark releases, expanding coverage with new distributions and easing adoption through built-in workflows, such as moving from your current Benchmark version to a new version while preserving your custom configurations. Certification and trust We can proudly announce that kompli has met all the requirements and is officially certified by the CIS for Benchmark assessment, so you can trust compliance results as authoritative. Minor benchmark updates will be applied automatically, while major version will be released separately. We will include workflows to help migrate customizations seamlessly across versions. Key Highlights Built-in CIS Benchmarks for Azure Endorsed Linux distributions Full parity with official CIS Benchmarks content and certified by the CIS for Benchmark Assessment Flexible configuration: adjust parameters, define exceptions, tune severity Hybrid support: enforce the same baseline across Azure, on-prem, and multi-cloud with Azure Arc Reporting format in CIS tooling style Supported use cases Certified CIS Benchmarks for all Azure Endorsed Distros - Audit only (L1/L2 server profiles) Hybrid / On-premises and other cloud machines with Azure Arc for the supported distros Compliance as Code (example via Github -> Azure OIDC auth and API integration) Compatible with GuestConfig workbook What’s next? Our next mission is to bring the previously announced auto-remediation capability into this experience, expand the distribution coverage and elevate our workflows even further. We’re focused on empowering you to resolve issues while honoring the unique operational complexity of your environments. Stay tuned! Get Started Documentation link for this capability Enable CIS Benchmarks in Machine Configuration and select the “Official Center for Internet Security (CIS) Benchmarks for Linux Workloads” then select the distributions for your assignment, and customize as needed. In case if you want any additional distribution supported or have any feedback for kompli – please open an Azure support case or a Github issue here Relevant Ignite 2025 session: Hybrid workload compliance from policy to practice on Azure Connect with us at Ignite Meet the Linux team and stop by the Linux on Azure booth to see these innovations in action: Session Type Session Code Session Name Date/Time (PST) Theatre THR 712 Hybrid workload compliance from policy to practice on Azure Tue, Nov 18/ 3:15 PM – 3:45 PM Breakout BRK 143 Optimizing performance, deployments, and security for Linux on Azure Thu, Nov 20/ 1:00 PM – 1:45 PM Breakout BRK 144 Build, modernize, and secure AKS workloads with Azure Linux Wed, Nov 19/ 1:30 PM – 2:15 PM Breakout BRK 104 From VMs and containers to AI apps with Azure Red Hat OpenShift Thu, Nov 20/ 8:30 AM – 9:15 AM Theatre THR 701 From Container to Node: Building Minimal-CVE Solutions with Azure Linux Wed, Nov 19/ 3:30 PM – 4:00 PM Lab Lab 505 Fast track your Linux and PostgreSQL migration with Azure Migrate Tue, Nov 18/ 4:30 PM – 5:45 PM PST Wed, Nov 19/ 3:45 PM – 5:00 PM PST Thu, Nov 20/ 9:00 AM – 10:15 AM PST1.9KViews0likes3CommentsImprove production agents with closed-loop evaluations in Microsoft Foundry
A production agent can lose accuracy or cost too much without a single code change. As live traffic grows, new user requests expose gaps in the agent instructions. At the same time, newer models can offer better quality or lower operating cost. Yet editing prompts by hand or swapping models in place risks breaking workflows that already work. The diagram uses v1 and v2 for the active baseline and candidate; Microsoft Foundry assigns the actual version numbers. Prerequisites and integration responsibilities Before implementing this workflow, verify these platform resources and application components: Microsoft Foundry resources: Deploy a hosted agent with the Agent Optimizer SDK. Connect Application Insights, deploy approved models, and grant Microsoft Entra ID permissions. Application team responsibilities: Supply the sandboxed tool test harness, reviewed outcome labels ( ground_truth ), the CI/CD release policy script, and session canary routing ( version_indicator ). How the scheduled loop runs end to end A scheduled GitHub Actions workflow or an Azure Monitor alert starts each cycle across Microsoft Foundry and GitHub Actions. On each run, the workflow reads recent continuous evaluation scores, Application Insights error metrics, and newly approved model deployments. When triage confirms an agent quality drop or a scheduled model evaluation, the workflow samples recent traces into a dataset for human label review. Next, Agent Optimizer searches across instructions, skills, tool descriptions, and models on your training and validation datasets. Your release automation applies the selected candidate and opens a pull request for engineer review. It then gates promotion on a held-out regression suite and updates .agent_configs/baseline/ after promotion. 1. Monitor live traffic with continuous evaluation Safe promotion starts with measuring the active production configuration, which serves as the baseline for every comparison against a proposed candidate. On live traffic, Microsoft Foundry continuous evaluation scores execution traces to track how quality, tool use, latency, and cost change over time: Tool output versus reply ( groundedness ). Checks whether the reply has support in the supplied context, flagging unsupported completion claims. Instructions versus actions ( task_adherence ). Checks whether the agent followed its system prompt rules during the conversation. Query versus tool calls ( tool_call_accuracy and intent_resolution ). Verifies that the agent selected the right tool and arguments for the user's request. Safety and trace rules ( indirect_attack and span checks). Flags injected instructions while span checks detect tool errors and repeated write calls. Triage alerts and set the optimization objective When a quality alert fires, check Application Insights traces and Azure Monitor metrics first. Separate an agent configuration issue from other operational changes before running an optimizer job: Backend or tool outages. Rising tool timeouts or API errors call for infrastructure recovery before you tune the agent. Traffic-mix shifts. A surge in a new request type may require new tools, policy rules, or test coverage before optimization. Evaluator or rubric updates. A changed grader prompt or threshold shifts scores even when agent behavior is unchanged. Confirm that a configuration change can address the issue, or start a run from a scheduled review or new model deployment. Define the objective up front: Optimization objective Primary target Mandatory requirements Improve quality Achieve a target score gain on failing task categories and meet the required quality floor Preserve scores in existing categories, pass all critical safety and business checks, and stay within cost and latency limits Reduce operating cost Lower token and model cost across the agent workload Meet the quality floor, stay within the allowed variation margin, pass all critical checks, and stay within latency limits 2. Turn production traces into isolated, executable datasets Once monitoring identifies what to improve, the next step is building the evaluation datasets for Agent Optimizer and CI/CD. Microsoft Foundry trace dataset generation ( project_client.datasets.begin_create_generation_job ) samples production traces from Application Insights into a versioned dataset registered in your project. When you set max_samples , Microsoft Foundry uses MinHash sampling to filter out repetitive messages and select diverse conversations. Pinning agent_version samples behavior from one known release while redacting private content ( redact_private_content=True ) by default. In a tool-using workflow such as an order refund agent, flagged traces often expose three failure patterns: Unsafe retries after a tool timeout. The agent calls a write tool such as submit_refund , and the call times out with outcome_unknown . The agent repeats the write request before it checks the first request's status. The backend must also prevent duplicate transactions. Premature completion claims on asynchronous work. The agent skips get_refund_status and reports a refund as completed while backend processing remains pending . Prompt injection inside untrusted tool data. The agent obeys injected text inside a customer return note ( untrusted_return_note ) and reports an unverified status. Figure 1. The agent checks the refund status after a timed-out submission. The tool sequence shows how it handles an unknown outcome. Bridge the gap from recorded traces to safe test execution A generated trace dataset captures the conversation history from production. Turning those recorded interactions into safe, repeatable evaluation cases requires verified expected outcomes and a sandboxed test backend. Keep all evaluation runs isolated from live payment APIs and customer databases: Review expected outcomes ( ground_truth ). Inspect each sampled trace and add the reviewed business outcome ( status , order_id , refund_id , and reason ) to ground_truth . Preserve the original captured response as the historical record. Isolate tool execution in a test harness. Bind each evaluation case to controlled tool doubles and a resettable test database or ledger snapshot. Every evaluation run executes fresh tool calls against this sandbox. Keep optimizer data separate from the release regression suite. Split reviewed cases into training and validation datasets ( 2a ) for Agent Optimizer, and reserve a held-out regression suite ( 2b ) for CI/CD release gating. Keep all requests from the same incident in one data split. Figure 2. This example dataset uses synthetic interactions to illustrate the production trace workflow. Reviewers verify expected outcomes and pair each case with isolated test state. 3. Configure eval.yaml and evaluators against fixed requirements With the datasets registered in Microsoft Foundry, define how each run is scored. Use eval.yaml to bind your baseline agent configuration, the training and validation datasets, evaluators, and approved model search space: name: Refund agent configuration search agent: name: refund-release-loop kind: hosted model: gpt-5.4-mini config: .agent_configs/baseline/metadata.yaml dataset: name: refund-loop-training version: "1" validation_dataset: name: refund-loop-validation version: "1" evaluators: - builtin.task_adherence - name: refund-state version: "3" options: eval_model: gpt-5.4-mini optimization_model: gpt-5.4 max_candidates: 4 optimization_config: model_search_space: - gpt-5.4-mini - gpt-5.4 Keep the held-out regression suite ( refund-loop-release ) in a separate CI/CD evaluation configuration so Agent Optimizer cannot access or overfit those cases during search. Keep release criteria independent of candidate instructions Prompt evaluators such as builtin.task_adherence help spot instruction drift, while Agent Optimizer rewrites instructions.md and SKILL.md to improve performance. Grade every candidate against fixed business requirements kept outside the editable agent configuration: Evaluator type What it checks on each fresh sandboxed run How it protects the release gate Semantic and rubric evaluators Grades the reply against fixed task-level criteria , mapped grounding context, and ground truth Allows better phrasing or model changes while enforcing business rules and grounded claims Custom code evaluator Inspects the tool call sequence, structured JSON output, and resulting sandbox ledger state Blocks duplicate write calls, skipped status checks, and mismatched transaction states To use builtin.groundedness on tool-supported claims, pass serialized tool outputs as grounding context and map that field in your evaluator inputs. Before testing, set your quality floor, target gain or cost savings, and allowed regression margin. Semantic evaluation permits harmless wording changes. The regression margin defines the largest acceptable quality loss. Assess sampling uncertainty separately. Microsoft Foundry custom code evaluators inspect the candidate's tool events and sandbox state snapshot directly. The following illustrative check blocks duplicate refund submissions and status claims that disagree with the verification tool or ledger: # Illustrative custom code evaluator logic submissions = [e for e in events if e["tool"] == "submit_refund"] if len(submissions) > 1: failures.append("repeated_submission") verifications = [e["result"] for e in events if e["tool"] == "get_refund_status"] claimed = output.get("status") if claimed in {"completed", "pending", "failed"}: if not verifications or verifications[-1].get("status") != claimed: failures.append("unverified_claim") if not ledger or ledger[-1].get("status") != claimed: failures.append("claim_state_mismatch") Because custom code evaluators run in an isolated environment without network access, the evaluation harness attaches the resulting sandbox state snapshot to each evaluation item. 4. Run Agent Optimizer on your evaluation dataset Once eval.yaml is ready, run Agent Optimizer from your agent project root: azd ai agent optimize The command detects eval.yaml automatically. Agent Optimizer is in preview; see the optimization quickstart for supported flags and regions. During the job, it scores .agent_configs/baseline/ , proposes up to max_candidates revisions from training tasks, and ranks candidates on validation_dataset : Optimization target Baseline input What Agent Optimizer changes Instruction tuning instructions.md Rewrites the system prompt with explicit constraints, step ordering, and output format rules Skill improvement skills/<name>/SKILL.md Refines domain skill descriptions, bodies, and activation criteria while keeping their purpose intact Tool optimization tools.json Clarifies function and parameter descriptions without changing the executable tool schema Model selection model_search_space in eval.yaml Tests candidate model deployments from the approved list in your Foundry project Load the selected instructions, skills, model, and tool descriptions at runtime with load_config() . Keep application logic, authorization, and tool contracts outside the optimization scope. For an illustrative submit_refund timeout, a candidate can update the refund skill and tool descriptions to check get_refund_status first. The configuration diff shows the intended changes, while evaluation provides evidence that the agent follows your business rules. Figure 3. The comparison ranks four candidates on validation runs. The selected candidate refines the skill and tool descriptions. 5. Gate the candidate in GitHub Actions CI/CD After you select a candidate in Agent Optimizer, apply its configuration to .agent_configs/ and open a pull request for review: azd ai agent optimize apply --candidate <candidate-id> In GitHub Actions, the workflow signs in to Azure with Microsoft Entra ID. It then runs a four-step release gate while live traffic stays on v1 : Deploy the candidate version ( v2 ). Run azd deploy --no-prompt to register the candidate container without changing the endpoint selector ( v1 ). Evaluate both pinned versions on the held-out suite ( 2b ). Run cloud evaluations on refund-loop-release for v1 and v2 (or azd ai agent eval run per version). Retrieve complete grades and resource metrics. Collect all evaluator scores, latency metrics, and model token counts from both completed runs. Enforce the release policy. Compare v2 against v1 using the objective from Step 1, and exit non-zero when the policy fails: Release check result Outcome on the held-out regression suite CI/CD gate action Quality objective pass Candidate clears the quality floor, meets the required quality gain after accounting for sampling uncertainty, passes all critical checks, and stays within resource limits Pass the release gate and permit canary verification Cost objective pass Candidate reduces measured model spend (using model token pricing), clears the quality floor, stays within the allowed regression margin, and passes all critical checks Pass the release gate and permit canary verification Insufficient gain or savings Candidate misses the target quality gain or measured cost reduction Keep the baseline active Regression or critical failure Candidate drops below the quality floor or triggers repeated_submission , unverified_claim , or claim_state_mismatch Fail the workflow and block release Separate evaluation job health from agent task performance. Every test case must return a complete evaluation record and all required evaluator scores; missing records or failed evaluator jobs always block release. Score recorded agent execution errors (such as a malformed response) as task failures. This lets a candidate repair a broken baseline case, such as an illustrative outcome_unknown timeout retry. Fixing one failure mode alone does not satisfy every release requirement. In Figure 4, the gate blocks promotion when the run shows category regressions, excess token usage, or incomplete baseline evidence. Figure 4. GitHub Actions deploys the candidate version, blocks release when the held-out regression suite fails, and skips endpoint promotion. 6. Run a canary release, promote, and prepare the next cycle Passing the held-out regression suite provides evidence that the candidate meets the requirements covered by those tests. Verify live traffic in four steps before full promotion: Smoke-test the deployed version. Send synthetic sessions with version_indicator set to v2 to verify container startup, credentials, and tool connections. Route canary sessions against a live control. Microsoft Foundry hosted endpoints send 100 percent of default traffic to v1 . Set your minimum sample count, observation window, and thresholds before starting. Route a slice of new sessions ( 5% , then 25% ) to v2 via version_indicator alongside matching v1 control traffic. Wait for settled outcomes. Hold the canary stage until v1 and v2 collect enough continuous evaluation scores, Azure Monitor metrics, and settled refund outcomes. Promote, hold, or roll back: Canary and post-deployment evidence Release action Candidate meets quality, latency, and settled outcome thresholds against live v1 control traffic during the canary window Promote v2 by switching the Microsoft Foundry endpoint version selector to v2 for all new default sessions Sample size is still below the minimum count or asynchronous transactions are still settling Hold the current canary percentage and continue collecting evidence Candidate quality falls below the required floor, exceeds the allowed regression margin against control, or triggers critical tool errors or Azure Monitor alerts Roll back routing for new sessions to v1 , stop or drain active v2 sessions, and reconcile affected records Plan for both session routing and backend state during a rollback. During a canary, clearing version_indicator sends new sessions to the default version ( v1 ). After promotion, rolling back requires switching the Microsoft Foundry endpoint selector back to v1 . Existing v2 sessions continue on v2 until you stop them explicitly (for example, with project_client.agents.stop_session ) or let them drain. For transactions already submitted during the canary window, use backend idempotency keys and compensating reversals to keep customer records consistent. Reset the baseline and refresh held-out cases for the next loop After promoting v2 to 100 percent of default traffic, your release automation records its configuration in .agent_configs/baseline/ as the new comparison baseline. Keep v1 available until all in-flight v1 sessions finish. To keep the held-out regression suite representative of current traffic, periodically add fresh reviewed production traces to both your training datasets and your release suite. This reduces the risk of repeated candidate selection gradually overfitting a single fixed test set. Next steps: Implement continuous evaluation and CI/CD gating Use these paths to set up the workflow in Microsoft Foundry: Enable continuous evaluation and trace datasets. Configure production monitoring on your deployed agent and convert production conversations into trace datasets. Create your evaluation suite and custom evaluators. Prepare eval.yaml and datasets for Agent Optimizer, add custom evaluators, and run cloud evaluations. Optimize and automate CI/CD releases. Follow the Agent Optimizer overview, the optimization quickstart, and the hosted agent CI/CD guide to gate deployments in GitHub Actions.550Views0likes0CommentsAn engineering guide to Claude Code on Microsoft Foundry with Azure API Management
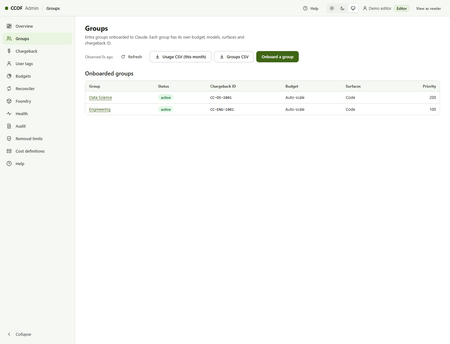
An engineering guide to my Claude Code on Foundry implementation: what users get, the Azure/APIM architecture, deployment and group onboarding, client setup, operational checks and scaling boundaries.719Views1like0CommentsAnnouncing the Open-Source Release of ML Video Codec (MLVC)
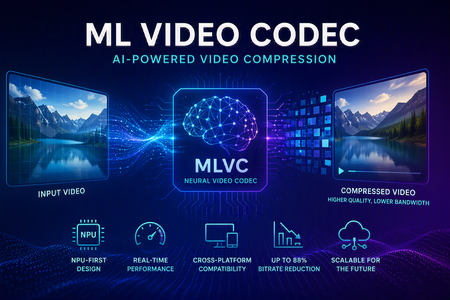
Video codecs compress video for transmission or storage, reducing bandwidth and storage requirements. MLVC is a modern machine-learning-based codec that uses substantially less bandwidth than conventional codecs, improving streaming and video-call quality—especially on constrained or unreliable networks—while lowering delivery and storage costs. MLVC is the product iteration of DCVC (Deep Contextual Video Compression) family of NVC (Neural Video Codec), open sourced by Microsoft Research since 2021, with improved compression efficiency, real-time performance on commodity Neural Processing Units (NPUs), and cross-platform support. We recently published this work in the paper MLVC: Multi-platform Learned Video Codec for Real-World Deployment. We are releasing the source code because we believe the next generation of video coding will be built openly, and we want the broader community — researchers, video codec engineers, platform vendors, product teams, as well as general developer community — to build it with us. Why MLVC Traditional video codecs (e.g., H.264/AVC, H.265/HEVC) have served the industry for a long time, but each generation requires enormous engineering effort for incremental gains and needs dedicated hardware which takes years to become commonly available. MLVC replaces conventional primitives — motion estimation, transforms, entropy modeling — with end-to-end learned neural compression, trained directly against rate-distortion objectives, and run on general-purpose NPU devices. The table below compares MLVC to popular video codecs, showing its lower bitrate and resulting savings in bandwidth and storage. Resolution vs H.264 vs H.265 360p 87.8% 75.5% 540p 82.7% 65.4% For example, for 360p video at 30 fps, where H.264 requires 1 Mbps, MLVC requires roughly 122 kbps for equivalent quality — about one-eight the bitrate under real-time conditions. The inference compute was kept approximately equal for the 360p and 540p resolutions. These results are based on a P.910 subjective test and are based on the Video Conferencing Dataset (VCD) dataset that we developed and also recently released as an open-source project. The following video demo illustrates the extent of quality enhancement achieved by MLVC relative to H.265/HEVC at the same bitrate of 200kbps (please watch by opening in a new window for better demonstration) \ Beyond video compression efficiency, MLVC also offers: NPU-first design. MLVC is built to run almost entirely on the AI accelerators already shipping in modern devices — Apple Neural Engine, Qualcomm and Intel NPUs — at no more than 50% NPU utilization, leaving NPU headroom for the rest of the system. Real-time execution at the targeted operating points. Demonstrated 540p at 30 fps on Apple, Intel, and Qualcomm hardware. A scaling-law trajectory. Empirically, MLVC's coding efficiency improves with increased model capacity and additional training compute. Content-adaptive behavior out of the box, without hand-tuned Rate Distortion Optimization heuristics. Already running in Microsoft Teams MLVC is more than just a research concept for Microsoft. We are currently rolling it out in Microsoft Teams, where it is being validated on real peer-to-peer video calls with active telemetry and A/B testing. The integration runs alongside fallback to conventional video codecs for hardware or reliability constraints — the kind of mixed-environment deployment that real products need. The scaling and reliability insights from this rollout are shaping the codec and its roadmap. We welcome your contributions We can not cover every use case, every device class, or every content domain by ourselves. That is why we are open sourcing MLVC. If you work on: Streaming, Video On Demand (VOD), or live broadcast Real-time communication and conferencing Cloud gaming or remote rendering Surveillance, drones, or robotics Mobile capture, Augmented Reality (AR) / Virtual Reality (VR), or volumetric video Codec hardware, NPUs, or inference runtimes We would love your help. Contributions of all kinds are welcome, including model improvements, training recipes, new platform ports and conversion targets, runtime backends, domain-specific fine-tunes, evaluation tooling, bug reports, and feedback on what is missing for your scenario. We particularly welcome platform ports that expand NPU coverage and efficiency improvements that push the rate-distortion frontier. What's in the release The MLVC repository is available at https://github.com/microsoft/mlvc and shared under the MIT License. It includes: MLVC model source code of the full network architecture. Trained model weights ready to run. Training scripts used to produce shipping models. Training data collection documentation to help reproduce and improve MLVC. Platform conversion scripts to target different NPUs and runtimes. Issues and pull requests will be open from day one. A follow-up release will add a C++ codec library, simplifying integration into real-world applications. Where we're heading Our long-term goal with MLVC is to create an open, learned video codec that meets or exceeds the coding efficiency of the best conventional codecs across the full range of video content, runs efficiently on the AI hardware already shipping in client and cloud devices, scales with compute the way modern ML systems do, and evolves in the open at the pace of the ML community rather than the pace of standardization cycles. In the near term that means stabilizing 540p real-time performance, expanding hardware coverage, and improving loss resilience. In the medium term: higher resolution, e.g., 1080p, and broader streaming scenarios. In the long term: an open video codec ecosystem that meaningfully replaces legacy stacks where it makes sense to. We can't create the future of MLVC alone. We're glad you're here, and we are looking forward to building the next-generation video codec with you. Who are we MLVC is brought to you by the following awesome folks working on the project at Microsoft: Ross Cutler, Ando Saabas, Tanel Pärnamaa, Ardi Loot, Haiyan Xie, Lauri Ehrenpreis, Andrei Znobishchev, Martin Lumiste, Evgenii Indenbom, Yan Lu, Bin Li, Jiahao Li, Naba Kumar, Babak Naderi, Juhee Cho, Badal Yadav, Jinxin Zhou, Tianyu Ding, Patrick Gregory. — The MLVC Team, Microsoft17KViews0likes5CommentsClosing the AI Agent Governance Gap with Microsoft Foundry
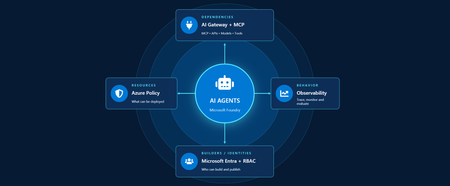
Developers are shipping agents faster than security teams can catalog them. As organizations move beyond pilots and begin operating dozens or hundreds of agents, one question keeps coming up: how do we actually get visibility into our AI agents across our environment? In this article, we'll walk through how Azure services can help establish visibility, guardrails, and cost accountability across your AI estate. Governance for AI happens across four layers: Resources – who can create new AI resources Builders – who can develop and publish agents in a certain scope Behavior – how agent outputs are evaluated, monitored, and governed Dependencies – what models, tools, APIs, and MCP servers agents can interact with Most organizations already have governance controls for identities, networking, and compliance. The challenge isn't creating new controls. It's connecting existing controls into an operating model that works for AI agents. Below we walk through each area and go a bit deeper on how to close the gap. Setting up boundaries with Azure Policy First, let's start in the Azure portal with Azure Policy. Azure Policy lets you set guardrails on what can be deployed in your environment and flags or blocks anything that doesn't comply. For AI workloads, the built-in definitions range from limiting models that people in your organization can deploy to locking down the network through enabling private endpoints. Some policies you get started with: Foundry model deployments should only use approved models: Restricts deployments to models or publishers your organization has explicitly approved Foundry model deployments should meet eligibility requirements (preview): Applies rules based on model attributes like preview vs. GA status and distribution source Azure AI Services resources should have key access disabled: Makes Microsoft Entra ID the only entry point The full list of policies related to Azure AI Services are available here: List of built-in policy definitions - Azure Policy | Microsoft Learn Why this comes first: Policy checks resources before they are created, so it proactively keeps your environment aligned with your standards. Implementing role-based access control (RBAC) Once these boundaries are in place, the next step is RBAC. Setting RBAC up early ensures that people and identities building agents have the right scope for what they actually need to do. Foundry roles only apply when you authenticate using Microsoft Entra ID. If you're using key-based authentication instead, the key grants full access with without role restrictions. API keys are convenient for quick development usage but when moving towards production, Microsoft Entra ID is the preferred method. Roles can be assigned at three scopes: the Foundry resource, a Foundry project, or an individual agent itself. Below is an example of how different personas within organization can map to a certain scope for creating and building agents with Foundry. Here's how each role in the diagram compares, from least to most privileged: Role Privilege Level What it does in Microsoft Foundry Foundry Agent Consumer Least Interact with agent endpoints in a project. This is your least-privilege role for people who only need to use agents. Foundry User Low Grants reader access to the Foundry project, the Foundry resource, and data actions for your Foundry project. Least-privilege access role for developers building and testing agents. Foundry Project Manager Medium This role lets you perform management actions on Foundry projects, build and develop with projects, and conditionally assign the Foundry User role to other user principals. Foundry Account Owner Higher Grants full access to manage Foundry projects and resources, and lets you assign the Foundry User role to other user principals. Foundry Owner Highest Grants full access to manage Foundry projects and resources to build and develop with projects. This role can also assign the Foundry User, ACR, and monitoring roles to users in the environment. Source: Role-based access control for Microsoft Foundry - Microsoft Foundry | Microsoft Learn For the agent resources themselves, assign managed identities rather than API keys since it lowers the risk of having compromised credentials. Note if you're scripting RBAC permissions: these roles were recently renamed from Azure AI User, Azure AI Owner, Azure AI Account Owner, and Azure AI Project Manager. The role IDs and permissions didn't change, so use the role definition GUID in your code to avoid issues while the rename rolls out. Observability in Microsoft Foundry Governance requires more than access control. Organizations also need evidence of how agents are being used. Observability provides the audit trail needed to investigate incidents, understand usage patterns, and track costs. The Foundry Control Plane brings these observability and governance tools together in one place, alongside services like Azure Monitor, Microsoft Entra, Microsoft Purview, and Azure Policy. In the Foundry portal, tracing is a good starting point. Once you connect an Application Insights resource to your project, Foundry turns on tracing automatically so every run, including the ones you test in the playground, is logged. After it is completed, you can search by Response ID or Trace ID to see the conversation history, token usage, run steps, tool calls, and inputs and outputs between the user and the agent. For more granular queries, you can write KQL to dive into individual agent runs or use the prebuilt Grafana dashboards in Azure Monitor. With client-side tracing, you can also export traces to observability tools you may already use, such as Datadog or Jaeger. Note: Permissions required for viewing this telemetry requires the Log Analytics Reader role on the connected Application Insights resource, and Privileged Monitoring Data Reader on top of that if the underlying Log Analytics tables are protected. Alongside all of these monitoring features, every agent comes with content safety guardrails and evaluations let you test and optimize performance before and after you publish your agents. When agents get published to Microsoft Teams and Microsoft 365 Copilot, Microsoft 365 admins can approve usage requests. These requests can be further scoped to a limited group for pilot testing/department usage or the full organization. Adding an AI gateway Observability tells you what your agents are doing, but how do you actually control them? This is where Azure API Management comes in. Once you have more than one agent, model deployment, or multiple teams consuming them, you need a single enforcement point between the agents and the resources they call. Adding Azure API Management in front of Microsoft Foundry gives you: Rate limiting and load balancing across regions and model deployments Consistent authentication and quota policies for model and tool traffic Usage tracking per team or cost center so you can accurately charge back to different departments Governed access to your custom and remote MCP servers Note: When choosing MCP servers, start with trusted, enterprise supported sources (GitHub, Microsoft, internally developed servers, etc.) that have documented security controls, enterprise authentication, clear ownership, and least-privilege permissions. Treat community MCP servers as untrusted until they have undergone a formal security review and are verified by organizations. Adding an AI gateway completes the governance picture. Azure Policy governs what can be deployed. RBAC governs who can build and manage agents. Observability provides evidence of how agents behave in production. The AI gateway extends governance into runtime, controlling how agents interact with models, tools, and external systems. Combined, these layers help organizations move beyond simply building agents to operating them responsibly at scale. Extend governance across the wider estate A few directions to take this further: MCP registry in Azure API Center – As MCP usage grows, you can create an approved inventory of MCP servers and APIs that can be used across an organization. Microsoft Agent 365 – Microsoft's enterprise control plane for AI agents. It gives every agent its own Microsoft Entra Agent ID and published Foundry agents sync to its registry automatically. This gives your IT team one place to run access reviews, lifecycle policies, and owner attestation across every agent in the tenant, including shadow agents discovered outside Foundry. Copilot Studio – when you add an MCP tool, you can point it at the API Management URL instead of the direct remote endpoint to gain additional observability through the gateway. GitHub Copilot – you can apply the same AI gateway-fronted MCP registry, applied to the developer side. Microsoft Purview – data classification, DLP, audit, and AI interaction governance across the wider estate. Where to go next Looking for a quick start? Turn on the three Azure Policy definitions above in audit mode against a non-production subscription and see what gets flagged that is out of compliance. Ready to design the end-to-end pattern? Take a look at this Cloud Adoption Framework guidance on AI governance and governing Azure platform services for AI. Want to go deeper on agent observability? Start with these articles around Application Insights integrations with Foundry: Use Insights in Microsoft Foundry and Monitor AI Agents with Application Insights Governing AI agents doesn't require starting from scratch. The identity, policy, monitoring, and cost controls you already use for the rest of your Azure estate can extend to AI workloads. Start with one layer, connect the next, and build a governance foundation that grows with your AI adoption.886Views3likes0Comments
Your Agents Need More Than a Place to Run
In architecture reviews with enterprise teams moving their first agentic applications toward production, I often hear the same plan: the team has containerized their agent and intends to run it on the managed Kubernetes cluster the organization already trusts. The reasoning is sensible, since the platform team knows the tooling and security has approved the network model, and for the first use case or two it is often the right call. Having watched this unfold in my years leading AgenticAI customer engineers and forward deployed engineers, and now helping customers reach production on Azure, I want to describe what happens next, before leaders commit rather than after. One thing to note is Azure supports multiple ways to build and operate agents. Foundry Agent Service provides an integrated managed runtime around your agent code. Azure Kubernetes Service supports teams that need Kubernetes-level control or want to extend an established platform, while Azure Container Apps provides managed container hosting. These services can work together. The decision is which capabilities and responsibilities best fit the workload. Where the cluster is the right answer A stateless retrieval application, a document extraction pipeline, or a classification job is a web service that happens to call a model, and a container platform runs web services well. A large retail customer of mine ran an invoice extraction agent on containers for over a year with almost no issues, and I never suggested they move it. The cluster remains the right home for several other situations as well. LLM invocations embedded inside existing microservices, event driven, or batch pipelines fit container platforms naturally. Genuine constraints such as air-gapped or sovereign environment, regions where a managed service is not yet offered are a good reason to run your own stack, and strong engineering team that already operates at that level can be a real asset. Even when the agents themselves move to a managed runtime, the tool servers, business APIs, and data services those agents call, often stay on your cluster, so they are complementary far more often than they are competitors. The problem is that these early wins can make agents seem like just another workload. Where the wheels come off The first failure is the state. A research agent that plans, searches, and synthesizes for ninety minutes is a long-running stateful process, while a Kubernetes pod is a disposable container the scheduler may restart at any time. A financial services team I worked with lost costly research run to a routine node upgrade, and responded as capable engineers do by building checkpointing, a durable store, and a resume mechanism. It worked, but they now owned a piece of infrastructure they had to keep correct as their agent's framework changed beneath it. A managed agent runtime absorbs this. Hosted agents in Foundry Agent Service, as one example, give every session a VM-isolated sandbox with a persistent file system, a durable state store that survives crashes and restarts and can hold checkpoints for frameworks such as LangGraph or Microsoft Agent Framework, and a resilient execution mode that recovers long-running work after a process interruption. The second is the human-in-the-loop. A commercial insurance customer’s claims agent needed sign-off from an adjuster and sometimes a second reviewer, with days between steps. Stopping an agent cleanly at the moment it needs a decision, holding its full session for four days without paying to keep it running, and resuming it correctly when the approval arrives is not something a container orchestrator gives out the box. The team built agent session suspend and resume, a queue, a durable state store, notifications, and an approval interface, and ended up with a small workflow engine nobody had planned to own. In hosted agents, an idle session is deprovisioned with its state persisted and restored onto fresh compute when the same session ID returns, so an agent waiting on an approval cost nothing while it waits, and sessions are retained for up to thirty days of inactivity. The approval experience remains yours to design, which is where your engineers' time should go. The third is multi-turn conversation, which quietly pushes teams into building their own context management system. The first version appends each turn to history, and within few turns the history outgrows the context window while cost and latency climb. So, the team adds truncation, then summarization, then retrieval of earlier turns, then per-user and per-tenant scoping, then expiry and deletion rules for privacy. An industrial customer's safety compliance assistant, with conversations stretching across days, followed exactly this path and ended up with a bespoke thread store and summarization pipeline nobody had budgeted for. Its first serious incident came when a summary silently dropped a compliance-relevant instruction. With the Responses protocol in hosted agents in Foundry, conversation history is a durable, platform-managed record keyed by a conversation ID and reachable from any channel, so the thread store is no longer yours to build, although deciding what to summarize or retrieve remains a design choice for your agent. The fourth is identity. On a cluster, the path of least resistance is a shared service account, and in one review a security architect asked which actions had been taken on behalf of which user, only to learn that the logs could not say. Hosted agents create a dedicated Microsoft Entra agent identity for each agent at deploy time, use on-behalf-of flows to act with the user's delegated permissions in interactive scenarios and the agent's own identity in autonomous ones, and keep the agent identifiable for audit in both cases. The fifth is per-user session isolation, which is the difference between an agent that serves many people and an agent that mixes them up. Agents read files, run code, and hold working data, and on a shared pod the default is that many users share a process, a file system, and often a cache. Giving every user session its own sandboxed environment and storage, so that one person's documents and intermediate results can never surface in another's, means engineering hard isolation boundaries and proving them to your security team. Hosted agents make a VM-isolated sandbox per session the default, and their durable state store can partition items per end user, so one store is safe to share across the users of a multitenant agent. And lastly, Evaluation and optimization are where the gap widens. The largest difference between teams that scale and those that stall is evaluation. Because agents are probabilistic and multi-step, staging tests often miss failures such as a wrong tool choice or a policy violation deep in a task. One customer’s agent passed every offline check but degraded unnoticed for weeks after a model update because evaluation stopped at release. Mature teams continuously evaluate production traces, combine automated judges with sampled human review, and red-team regularly.Once quality is measurable, teams can deliberately balance prompts, models, tools, latency, and cost. One team cut per-task cost by routing simple steps to smaller models after evaluation confirmed quality held. Self-built stacks require teams to assemble and maintain tracing, datasets, judges, and release gates. Hosted agents instead combines default OpenTelemetry traces with continuous evaluation, adversarial testing, and datasets generated from agent instructions. Staged closed-loop optimization uses those traces to improve instructions, tool descriptions, and model selection without extra plumbing. The real cost is the velocity gap Leaders usually expect me to quantify the initial build, and that is the smaller number. A team of four building the first agent often becomes ten or twelve within a year, and a growing share of them are maintaining a runtime for agents rather than building agents that serve the business. The enterprise has quietly created an internal agent infrastructure company in a field where the patterns for memory, tools, evaluation, and safety are rewritten every few months, while hyperscalers put hundreds of engineers on exactly this problem and ship at a cadence no single platform group can match. Foundry Agent Service, for instance, bundle content safety guardrails into the runtime and route outbound traffic through a customer virtual network, capabilities that platform teams otherwise assemble one integration at a time. This plumbing does not differentiate your organization, so the question is whether your scarcest engineers should spend years on it or on the workflows, data, and judgment only your company has. This is also why the technology companies held up as examples are a poor template. Many built their own runtimes because managed options did not yet exist and had large platform organizations to carry the load. Even they tend to invest in a custom runtime for the first handful of use cases and then migrate as managed services mature, because the maintenance burden compounds while the strategic value of owning the plumbing does not. What I would do as the leader I am not arguing against Kubernetes or for moving everything tomorrow. Comparable managed runtimes exist across the hyperscalers, and I use hosted agents as the running example only because it is the one I know best from the inside. Managed agent services are still maturing, some workloads have real data residency or customization needs, and abstraction always constrains something. What I am arguing for is a deliberate choice for each use case, guided by three questions: whether the agent must outlive a single request by running long, waiting on humans, or remembering across sessions whether it must act with its own identity, auditable delegation, and policy enforcement whether your team would be building anything a managed service already provides, and who will still maintain it in two years. Key takeaways Match the runtime to the workload. Containers on your existing cluster suit stateless, short-lived agents, while long-running, human-in-the-loop, and memory-dependent agents need capabilities your platform team was never hired to build. Count the hidden team. The real cost of self-hosting is the growing group of engineers maintaining state, identity, memory, guardrails, and tracing instead of solving business problems. Make evaluation continuous and connected to production traces. Pre-release testing alone will miss the drift and trajectory failures that hurt you, and optimization of quality, cost, and latency depends on that evaluation data. Follow the pattern of the leaders, not their early architecture. Companies that built custom runtimes did so before managed options matured, and most of them move toward managed services as those options improve. A practical place to begin is your roadmap for the next twelve months. Sort each use case into stateless and short-lived or long-running and human-dependent, and for every agent in the second group put a price on the engineers who would maintain the runtime rather than the business logic. I would like to hear how you have drawn this line, and where a managed service was not yet ready for something you needed.1KViews2likes0Comments