monitoring
10 TopicsAzure SQL Hyperscale Looks Healthy, but Logins Are Failing: Troubleshooting Partial Availability
Can an Azure SQL database look healthy while your users can't log in? Yes. It happens when the health signals and your application are measuring different things. We see this question in support cases fairly often: "Availability looked fine, so why couldn't my application connect?" This post explains why the two can disagree, especially on Hyperscale, and how to collect the evidence that shows what really happened. A quick look at Hyperscale Hyperscale separates compute from storage. At a high level: Compute replicas run your queries. These are the primary, plus any high-availability (HA) and named replicas. Each one keeps a local cache of hot data. Page servers store the data and serve pages the compute replica doesn't have cached. The log service receives the transaction log and passes changes on to the other components. This design is what makes Hyperscale scale so well. It also means "the database" is several components working together, and they don't all fail together. The Hyperscale architecture overview covers this in more detail. "Available" isn't one thing These are four questions that sound similar but aren't: Signal What it really tells you Service or resource availability The database is online at the platform level Primary replica health The compute node serving your writes is working normally Login success rate New connections are actually completing Query latency Work is finishing in a reasonable time once connected Storage can be healthy while the compute replica is struggling. The database can be online while some logins fail. And a health check can succeed between two failed attempts. Healthy storage + degraded compute ≠ healthy application experience. A real-world pattern In a recent Hyperscale case, the customer saw intermittent login failures and slow reads from remote storage on the primary replica. The storage components themselves looked healthy. The database was never fully down, and some health checks kept succeeding while the application had trouble connecting. Customer impact ended after a failover moved the workload to a different, healthy replica. However, the exact underlying cause on the original replica wasn't confirmed. The failover fixed the symptoms, and that tells you the problem was tied to that specific replica. It doesn't tell you why. Recovering service and finding the root cause are separate results, and an RCA should make clear which of the two it reached. Why averages hide the problem Most dashboards show data averaged over 1 minute, 5 minutes or 1 hour. A short burst of failures disappears in those averages. Suppose a probe connects every 5 seconds, and 6 attempts fail in a 30-second burst: View Probes Failures Success rate The 5-minute window containing the burst 60 6 90.0% The full hour 720 6 99.2% Your users felt a real outage. The hourly chart looks almost perfect. Measure what your users experience Platform metrics are useful but run your own lightweight probe from where your application runs. Here's a simple Python example: import time, csv, datetime, pyodbc CONN = ("Driver={ODBC Driver 18 for SQL Server};" "Server=tcp:<server>.database.windows.net,1433;" "Database=<db>;Encrypt=yes;Authentication=ActiveDirectoryMsi;") REGION = "<app-region>" with open("sql_probe.csv", "a", newline="") as f: w = csv.writer(f) while True: ts = datetime.datetime.now(datetime.timezone.utc).isoformat() login_ms = query_ms = None ok, err = False, "" try: t0 = time.perf_counter() conn = pyodbc.connect(CONN, timeout=15) login_ms = round((time.perf_counter() - t0) * 1000) t1 = time.perf_counter() conn.cursor().execute("SELECT 1").fetchone() query_ms = round((time.perf_counter() - t1) * 1000) conn.close() ok = True except pyodbc.Error as e: err = str(e)[:200] w.writerow([ts, ok, login_ms, query_ms, err, REGION]) f.flush() time.sleep(5) Each row records: The UTC timestamp Whether the connection succeeded Login time Time for a simple query The SQL error, if any The region the probe ran from Keep the raw rows rather than only averages. If login time rises before failures begin, that's often the earliest warning you'll get. Lining up the evidence When something goes wrong, put these side by side in UTC: Application errors, with error numbers and connection IDs Your probe results Resource Health and Service Health events Database performance data, such as sys.dm_db_resource_stats and Query Store wait statistics. See Hyperscale performance diagnostics for Hyperscale-specific waits. Any failover, scale or deployment events If you open a support case, include: The exact UTC time windows Sample error messages, with error numbers Connection IDs Your probe data Which application hosts or regions were affected With that information, we can start investigating straight away instead of spending the first day collecting it. Build for partial failure Retry transient errors with a retry limit, exponential backoff and jitter. (See our previous post on maintenance and failover.) Set sensible connection and command timeouts, so a slow login doesn't hold up a thread indefinitely. Alert on probe failures and login time, not just on platform availability. Know how to recover. For example, knowing when a failover is appropriate, and who can request it, saves time during an incident. Summary "Is the database online?" is often too simple a question. Ask instead: Can my application connect, how long does that take, and how fast are queries once connected? Measure those directly, at a fine enough granularity, and short partial outages stop being invisible.Lessons Learned #542: Reviewing Historical Azure SQL Database Storage Growth
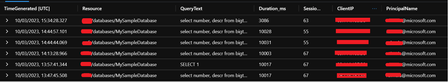
This week I worked on a service request where our customer needed to understand how an Azure SQL Database had grown over time. This information can be useful for capacity planning, cost analysis, and performance reviews. There are several possible approaches, depending on whether we need to review recent historical data that is still available in Azure Monitor, or whether we need to start collecting long-term historical data from now on. In this lesson learned, I would like to summarize some of the options available. 1. Reviewing recent historical data using Azure Monitor metrics The first point to clarify is how Azure Monitor metrics retention works. Most Azure platform metrics are retained for up to 93 days. However, a single Azure Monitor Metrics chart can query no more than 30 days of data at a time. This means that, if the data is still within the Azure Monitor retention window, we might need to review the metric in 30-day intervals. For Azure SQL Database storage usage, the metric commonly used is Data space used 2. Exporting metrics to Log Analytics for long-term analysis If the requirement is to perform long-term analysis, I would like to recommended option is to enable Diagnostic Settings on the Azure SQL Database and send the metrics to a Log Analytics workspace. Azure SQL Database diagnostic telemetry can be exported to different destinations, including: Log Analytics workspace Storage Account Event Hubs Using Log Analytics provides a very flexible way to query, aggregate, and visualize the data by using KQL. Once the metrics are available in Log Analytics, we can calculate the monthly database growth. For example: AzureMetrics | where ResourceProvider =~ "MICROSOFT.SQL" | where ResourceId == "/SUBSCRIPTIONS/your subscription/RESOURCEGROUPS/yourresourcegroup/PROVIDERS/MICROSOFT.SQL/SERVERS/yourserver/DATABASES/yourdatabase" | where MetricName == "storage" | summarize arg_max(TimeGenerated, Average) by Month = startofmonth(TimeGenerated) | project Month, DataSpaceUsedGB = round(Average / 1024 / 1024 / 1024, 2) | order by Month asc This query takes the last available value for each month and converts the metric from bytes to GB. Depending on the analysis requirements, the query can be customized. 3. Creating a custom database space usage history process If we need more control, or if we want to collect more granular database-level information, another option is to create a custom process that periodically captures the current database space usage into a table. This approach can be useful when we want to keep the information inside the database itself and avoid depending on external telemetry storage for this specific requirement. For example, the following table can be used to store daily or weekly snapshots: CREATE TABLE dbo.DatabaseSpaceUsageHistory ( SnapshotTimeUtc datetime2(3) NOT NULL DEFAULT SYSUTCDATETIME(), DatabaseName sysname NOT NULL, DataAllocatedMB decimal(19,2) NULL, DataUsedMB decimal(19,2) NULL, DataUnusedMB decimal(19,2) NULL, LogAllocatedMB decimal(19,2) NULL ); --Example collection query: INSERT INTO dbo.DatabaseSpaceUsageHistory ( DatabaseName, DataAllocatedMB, DataUsedMB, DataUnusedMB, LogAllocatedMB ) SELECT DB_NAME() AS DatabaseName, SUM(CASE WHEN type_desc = 'ROWS' THEN size END) * 8.0 / 1024 AS DataAllocatedMB, SUM(CASE WHEN type_desc = 'ROWS' THEN FILEPROPERTY(name, 'SpaceUsed') END) * 8.0 / 1024 AS DataUsedMB, ( SUM(CASE WHEN type_desc = 'ROWS' THEN size END) - SUM(CASE WHEN type_desc = 'ROWS' THEN FILEPROPERTY(name, 'SpaceUsed') END) ) * 8.0 / 1024 AS DataUnusedMB, SUM(CASE WHEN type_desc = 'LOG' THEN size END) * 8.0 / 1024 AS LogAllocatedMB FROM sys.database_files; This process can be executed daily, weekly, or monthly using the automation method that best fits the environment. This approach provides more control over the data collected, the retention period, and the frequency of collection.Lessons Learned #555: The First 60 Seconds of a Production Incident: Stop, Scope, Correlate
When a critical production incident starts, the first message we often receive is something like: “The database is down.” At that moment, everything suddenly becomes urgent. Engineers open monitoring dashboards. Someone starts checking logs. Another person reviews CPU and memory. Someone else asks whether there was a deployment. Connections are tested. Metrics are queried. Teams are contacted. All of these actions may eventually be necessary. But there is a more important question to answer first: What exactly does “down” mean? After working on many production incidents, one lesson becomes increasingly clear: The first 60 seconds are not about solving the incident. They are about defining the incident. A vague problem description can send troubleshooting in many different directions. A precise problem statement dramatically reduces the investigation space. This article describes a simple approach that can be applied during the first moments of an incident: Stop. Scope. Correlate. 1. Stop: Define What “Down” Actually Means The first mistake during many incidents is assuming that everyone understands the problem in the same way. Consider the statement: “The database is unavailable.” That statement could mean many different things: Applications cannot establish new connections. Existing connections are still working, but new connections fail. Queries are timing out. A specific login cannot authenticate. One database is inaccessible. One application is failing while other applications work correctly. Performance degradation makes the service appear unavailable. The application returns HTTP 500 errors, but the database itself is healthy. Connections fail intermittently. A failover is occurring. DNS or networking issues prevent the application from reaching the database. These scenarios require completely different investigation paths. Before opening ten different tools, try to transform the original statement into something more specific. For example: Instead of: “The database is down.” Try to reach something like: “Since approximately 14:32 UTC, new application connections to Database A have intermittently failed with login errors, while existing sessions remain active.” Now we have something we can investigate. The problem statement contains: a timestamp, a specific database, a specific symptom, affected connection behavior, and an indication that the issue may be intermittent. That is already much more valuable than the original alert. 2. Scope: Determine the Blast Radius Once we understand the symptom, the next question is: Who or what is affected? This is sometimes called determining the blast radius. The scope can immediately eliminate entire categories of possible causes. Ask questions such as: Is one user affected or every user? Is one application affected or several applications? Is one database affected or all databases? Are all connection types affected? Are existing connections healthy while new connections fail? Are only specific clients or drivers affected? Imagine the following situation. Application A reports database connectivity failures. However: Application B connects successfully. SSMS connects successfully. Azure metrics show the database is available. Existing sessions continue executing queries. This changes the investigation dramatically. The problem may not be: “Azure SQL is unavailable.” It may instead be: “Application A cannot establish new connections.” That distinction is extremely important. A large percentage of troubleshooting time can be saved simply by identifying the correct scope early. 3. Build the Timeline The next critical dimension is time. During an incident, timestamps are evidence. Ask: When did the issue start? Is there an exact timestamp? How long did it last? Is the issue continuous or intermittent? Did the problem recover automatically? Did the issue occur once or multiple times? Was there another event immediately before the problem? A good incident timeline may look like this: 14:31:52 UTC – Application operating normally 14:32:08 UTC – First connection error reported 14:32:10 UTC – Database failover detected 14:32:14 UTC – Additional login failures 14:32:18 UTC – New connections begin succeeding 14:32:20 UTC – Application fully recovere Now the investigation is no longer based on assumptions. We have a five-to-ten-second window that can be correlated with platform telemetry, database events, application logs, networking information, and deployment history. Without the timeline, engineers may analyze hours of logs. With the timeline, the investigation becomes focused. 4. Correlate Before Changing Anything The next step is correlation. Once we understand the symptom, scope, and timeline, we can ask: What changed at the same time? Useful correlation sources may include: application deployments, infrastructure changes, configuration changes, database failovers, scaling operations, maintenance events, firewall changes, authentication changes, networking events, DNS changes, resource utilization, query regressions, blocking, deadlocks, connection pool behavior, driver updates, platform events. etc The key word here is correlation. It is tempting during an incident to immediately change something. For example: restart the application, restart a service, scale the database, clear the connection pool, change configuration, rebuild an index, modify a query, fail over manually. Sometimes these actions are necessary. But every change also modifies the evidence. A restart may restore the service while simultaneously removing valuable diagnostic information. Whenever possible: Collect evidence before changing the environment. 5. Use Multiple Sources of Evidence Production incidents rarely provide the complete answer in one telemetry source. A better approach is to correlate multiple sources. For a database-related incident, we may investigate: Application telemetry Application logs may reveal: connection failures, authentication errors, request latency, retry attempts, timeout exceptions, HTTP errors, dependency failures. Platform metrics Cloud metrics may help determine: service availability, CPU utilization, storage pressure, connection count, throttling, resource saturation. Database telemetry Database-level information may include: active sessions, waits, blocking, query performance, login failures, failover events, resource statistics. Query Store For performance incidents, Query Store can be extremely valuable. It may help identify: query regressions, plan changes, increased execution duration, abnormal CPU consumption, changes in execution frequency. Deployment history Always ask: What changed recently? Many incidents have a strong temporal relationship with: application deployments, schema changes, configuration modifications, infrastructure updates, new releases, security changes. The goal is not to assume that the most recent change caused the incident. The goal is to determine whether the events correlate. 6. Avoid Starting With a Tool One common troubleshooting pattern is: “Open the monitoring portal.” or: “Run this query.” or: “Check this log.” Tools are essential, but tools should follow the investigation strategy. The investigation should determine which tool we need. Not the other way around. If the problem is authentication, the investigation path may focus on: login errors, authentication configuration, identity providers, user mappings, connection strings. If the problem is performance, the investigation may focus on: Query Store, waits, blocking, execution plans, resource utilization. If the problem is connectivity, we may investigate: DNS, network paths, firewalls, drivers, retries, connection pools. A clear problem definition tells us where to look. 7. Ask the Same Questions Every Time One of the most effective improvements teams can make is standardizing the first questions asked during incidents. A simple initial checklist could be: Symptom: What exactly is failing? Scope: Who or what is affected? Timeline: When did it start? Error: What exact error message or error code is being returned? Frequency: Is the issue continuous, intermittent, or already recovered? Changes: What changed immediately before the incident? Evidence : Which telemetry sources can confirm the behavior? These questions are intentionally simple. During a high-severity incident, simplicity is valuable. 8. The First 60 Seconds Framework We can summarize the approach in four steps. 1. Define: What does the reported symptom actually mean? 2. Scope: Determine the blast radius. 3. Timeline: Identify exactly when the problem occurred. 4. Correlate Connect the symptom with telemetry, events, and recent changes. Only after these steps should we decide the deeper troubleshooting path. 9. Speed Is Important, but Direction Is More Important During critical incidents, teams naturally want to move quickly. That is the correct instinct. But speed without direction can create noise. Ten engineers investigating ten different theories at the same time may generate enormous activity without producing clarity. A well-defined incident allows teams to divide the investigation intelligently. For example: One engineer investigates application telemetry. Another checks database telemetry. Another reviews platform events. Another investigates recent deployments. Another builds the incident timeline. All of them are now investigating the same defined problem. That is very different from everyone independently trying to determine what the problem might be.Monitoring Azure SQL Data Sync Errors Using PowerShell
Azure SQL Data Sync is a powerful service that enables data synchronization between multiple databases across Azure SQL Database and on‑premises SQL Server environments. It supports hybrid architectures and distributed applications by allowing selected data to synchronize bi‑directionally between hub and member databases using a hub‑and‑spoke topology. However, one of the most common operational challenges faced by support engineers and customers using Azure SQL Data Sync is: ❗ Lack of proactive monitoring for sync failures or errors By default, Azure SQL Data Sync does not provide native alerting mechanisms that notify administrators when synchronization operations fail or encounter issues. This can result in silent data drift or synchronization delays that may go unnoticed in production environments. In this blog, we’ll walk through how to monitor Azure SQL Data Sync activity and detect synchronization errors using Azure PowerShell commands. Why Monitoring Azure SQL Data Sync Matters Azure SQL Data Sync works by synchronizing data between: Hub Database (must be Azure SQL Database) Member Databases (Azure SQL Database or SQL Server) Sync Metadata Database (stores sync configuration and logs) All synchronization activity—including errors, failures, and successes—is logged internally within the Sync Metadata Database and exposed through Azure SQL Sync Group logs. Monitoring these logs enables: Detection of sync failures Identification of schema mismatches Validation of sync completion Troubleshooting of sync group issues Verification of last successful sync activity Prerequisites Before monitoring Azure SQL Data Sync activity, ensure the following: Azure PowerShell module (Az.Sql) is installed You have access to the Azure SQL Data Sync resources Proper authentication and subscription context are configured Install and import the required module if not already available: # Install Azure PowerShell module if not already installed Install-Module -Name Az -Repository PSGallery -Force # Import the SQL module Import-Module Az.Sql Authenticate to Azure: # Login to Azure Connect-AzAccount -TenantId "<tenant-id>" # Set subscription context Set-AzContext -SubscriptionId "<subscription-id>" These commands enable access to Azure SQL Sync Group monitoring operations. Monitoring Sync Group Status To retrieve Sync Group details, define the required variables: # Define variables $resourceGroup = "rg-datasync-demo" $serverName = "<hub-server-name>" $databaseName = "HubDatabase" $syncGroupName = "SampleSyncGroup" # Get sync group details Get-AzSqlSyncGroup -ResourceGroupName $resourceGroup ` -ServerName $serverName ` -DatabaseName $databaseName ` -SyncGroupName $syncGroupName | Format-List Note: The LastSyncTime property returned by Get-AzSqlSyncGroup may sometimes display a value such as 1/1/0001, even when synchronization operations are completing successfully. To obtain accurate synchronization timestamps, it is recommended to use Sync Group Logs instead. Monitoring Sync Activity Using Logs (Recommended) To monitor synchronization activity and retrieve detailed sync status, use: # Get sync logs for the last 24 hours $startTime = (Get-Date).AddHours(-24).ToString("yyyy-MM-ddTHH:mm:ssZ") $endTime = (Get-Date).ToString("yyyy-MM-ddTHH:mm:ssZ") Get-AzSqlSyncGroupLog -ResourceGroupName $resourceGroup ` -ServerName $serverName ` -DatabaseName $databaseName ` -SyncGroupName $syncGroupName ` -StartTime $startTime ` -EndTime $endTime This command retrieves: Sync operation timestamps Sync status Error messages Activity details Sync Group Logs provide more reliable monitoring information than the Sync Group status output alone. Retrieving the Last Successful Sync Time To determine the most recent successful synchronization operation: # Get the most recent successful sync timestamp $startTime = (Get-Date).AddDays(-7).ToString("yyyy-MM-ddTHH:mm:ssZ") $endTime = (Get-Date).ToString("yyyy-MM-ddTHH:mm:ssZ") Get-AzSqlSyncGroupLog -ResourceGroupName $resourceGroup ` -ServerName $serverName ` -DatabaseName $databaseName ` -SyncGroupName $syncGroupName ` -StartTime $startTime ` -EndTime $endTime | Where-Object { $_.Details -like "*completed*" -or $_.Type -eq "Success" } | Select-Object -First 1 Timestamp, Type, Details This helps administrators validate whether synchronization is occurring as expected across the sync topology. Filtering for Synchronization Errors To identify failed or problematic sync operations: # Get only error logs Get-AzSqlSyncGroupLog -ResourceGroupName $resourceGroup ` -ServerName $serverName ` -DatabaseName $databaseName ` -SyncGroupName $syncGroupName ` -StartTime $startTime ` -EndTime $endTime | Where-Object { $_.LogLevel -eq "Error" } Filtering logs by error type allows for: Rapid identification of failed sync attempts Analysis of failure causes Early detection of data consistency risks Key Takeaways Azure SQL Data Sync does not provide native alerting for sync failures Sync Group Logs offer detailed monitoring of sync operations Get-AzSqlSyncGroupLog provides accurate timestamps and status Monitoring logs enables detection of silent sync failures PowerShell can be used to proactively monitor synchronization health References Azure SQL Data Sync Error Monitoring GitHub Repository What is SQL Data Sync for Azure?236Views0likes0CommentsLesson Learned #508: Monitoring Wait Stats and Handling Large Data Set
Sometimes, we get asked how much data the client application is receiving from Azure SQL Database, along with the time spent and the number of rows returned. I would like to share a simple example that allows us to approximate these details. I hope that you could find useful.1.5KViews0likes0CommentsLesson Learned #491: Monitoring Blocking Issues in Azure SQL Database
Time ago, we wrote an article Lesson Learned #22: How to identify blocking issues? today, I would like to enhance this topic by introducing a monitoring system that expands on that guide. This PowerShell script not only identifies blocking issues but also calculates the total, maximum, average, and minimum blocking times.2.3KViews0likes0CommentsLesson Learned #8: Monitoring the geo-replicated databases.
First published on MSDN on Oct 31, 2016 We received multiple requests in order to have answered the following questions: Is there needed a maintenance plan for geo-replicated databases? How to monitor the geo-replicated databasesAnswering the question: "Is it needed a maintenance plan for geo-replicated databases?",No, there is not needed because is you have a maintenance plan for rebuilding indexes and update statistics for the primary database, these command will be executed in all geo-replicated databases that you have.Lesson Learned #421:Understanding and Troubleshooting Transaction Log Truncation in Azure SQL DB
Azure SQL Database, Microsoft's cloud-based database service, manages many administrative functions automatically, such as backups and patching. However, understanding the behavior of the transaction log, especially its truncation, remains crucial. This article delves into potential reasons why a transaction log might not truncate as expected and offers steps to investigate and address these concerns.2.2KViews0likes0CommentsLesson Learned #7: Monitoring the transaction log space of my database
First published on MSDN on Oct 31, 2016 In many support cases, our customers want to monitor the available space for the transaction log space for their database or to know what caused an error when the transaction is full.3.9KViews1like0Comments