monitoring
316 TopicsOpen-Weight Models in Microsoft Foundry
Open-weight models can be valuable, but they are not automatically cheaper, safer, or more controllable. In Microsoft Foundry, the right decision depends on deployment path, licensing, data-processing location, quota, support posture, operational ownership, safety controls, and lifecycle risk. Do not treat all visible or downloadable models as open source; review the license first. Start with Serverless API when a supported Foundry Model meets the workload need. Use partner/community models only after Marketplace, Product Terms, and regional availability checks. Treat managed compute as a preview path for open-source or custom models, not a production default. Validate data processing location, quota, safety controls, support model, and lifecycle before committing. Why this matters Open-weight models are now part of serious enterprise AI planning. Teams consider them for cost control, technical flexibility, transparency, data residency, regulatory pressure, and the ability to build in-house capability. But the useful question is not whether an open-weight model is better than a proprietary managed model. The useful question is which deployment and operating model fits the workload. Use precise language Open source does not simply mean that model weights or code are visible. The Open Source Initiative defines open source through license requirements such as free redistribution, source code access, derived works, non-discrimination, and technology-neutral terms. Many AI models are better described as open-weight: weights may be available or inspectable, but the license can still restrict use, redistribution, or competition. Architecture should not start until license and use rights are reviewed. Four adoption paths Microsoft Foundry gives teams several ways to use models. Foundry Models sold by Azure are hosted and operated by Azure, billed through the Azure subscription, covered by Azure service-level agreements, and supported by Microsoft. This is usually the lowest-friction production path when a supported model meets the requirement. Foundry Models from partners and community expand provider choice, but some are Non-Microsoft Products under Product Terms and can require Azure Marketplace subscription, purchase permissions, billing-country availability, and publisher-term review. Serverless API is documented as the preferred and most capable Foundry deployment option for Foundry Models, including models sold by Azure and select partner/community models. Managed compute is different. It hosts open-source, partner, and custom models on dedicated GPU capacity that Foundry manages. Microsoft owns the GPU topology, runtime, container image, and security patching, while the customer chooses the model, deployment template, accelerator family, and scaling behavior. However, managed compute is public preview, has no SLA, and is not recommended for production workloads in current documentation. A fully self-managed path can offer maximum control, but the organization owns the serving runtime, patching, scaling, observability, safety controls, and cost optimization. Decision criteria Start with workload fit. If a managed model satisfies accuracy, latency, region, and governance needs, avoid extra operational burden. Consider open-weight options when you need specific model behavior, weight-level control, a dedicated GPU path, specialized deployment templates, or a license that supports your intended use. Then test the economics. Token billing, reserved throughput, and hourly accelerator billing behave differently. Open-weight is not automatically cheaper once runtime efficiency, scale-to-zero behavior, GPU quota, engineering time, monitoring, and incident response are included. Data residency and availability Deployment choice also affects data processing. Serverless deployment types can process inferencing data globally, within a Microsoft-specified data zone, or in a single region depending on the selected tier. Model availability varies by provider, deployment type, region, quota, subscription, and cloud. Foundry guidance says to verify project region, feature support, model availability, quota, dependent services, and sovereign cloud constraints before production rollout. Responsible AI and safety Responsible AI is not optional because a model is open-weight. Microsoft Foundry guidance frames production readiness around discovering risks, protecting model and runtime behavior, and governing with monitoring and compliance integrations. In managed compute public preview, built-in content filtering is not part of the managed compute data path; applications that need request or response filtering should call Azure AI Content Safety APIs directly. That limitation can be decisive for production. Lifecycle and procurement risk Model lifecycle matters. Foundry Models move through Preview, Generally Available, Legacy, Deprecated, and Retired stages. Preview models are not recommended for production, and some generally available models from selected providers follow a shorter lifecycle than the standard lifecycle. Procurement also matters. Marketplace plans can require a valid payment method, purchase permissions, review of terms, and country or region availability. A model being visible in a catalog is not the same as being approved for a regulated workload. Recommended operating pattern Use Foundry Models sold by Azure when they meet the requirement and you want the simplest production support model. Use partner/community models when capability or provider choice matters and Marketplace and Product Terms are acceptable. Use managed compute for experimentation, evaluation, controlled preview adoption, or cases where dedicated GPU hosting of open-source or custom models is worth the constraints. Use self-managed hosting only when the organization is prepared to operate the full platform. Decision guide Production checklist Is the model sold by Azure, from a partner/community provider, managed compute, or self-managed? Does the license permit the intended commercial, regulated, or redistribution use case? Is the model GA, Preview, Deprecated, or approaching retirement? Who supports the model and runtime, and what SLA or preview terms apply? Where is inferencing data processed for the selected deployment path? What quota, billing model, accelerator capacity, and fallback option apply? Which safety controls are built in, and which must the application add? What will the team do if the model becomes unavailable, too expensive, or operationally risky? Conclusion Open-weight models should be adopted because they fit a workload, not because they are popular. The strongest enterprise pattern is disciplined choice: verify legal rights, choose the lowest-burden deployment path that satisfies the requirement, validate data and region constraints, measure cost with real traffic, and add safety and monitoring before production use.How to maintain and update Azure Function Connector deployed via WEBSITE_RUN_FROM_PACKAGE?
Background We recently completed a migration from the legacy Microsoft Sentinel Box connector to the newer Box Events (CCP) connector. During the migration we discovered that the legacy Box connector was implemented using: Azure Functions JWT authentication WEBSITE_RUN_FROM_PACKAGE The Function App is configured as: WEBSITE_RUN_FROM_PACKAGE=https://aka.ms/sentinel-BoxDataConnector-functionapp and the Azure Function therefore operates in read-only mode because it is running directly from the package referenced by that URL. The migration to the new Box Events (CCP) connector has been successful and is now ingesting data into BoxEventsV2_CL using Client Credentials Grant (CCG) authentication. What prompted the question While reviewing the legacy Azure Function deployment, we noticed that: The Box Solution GitHub repository has received updates over time. The Box Solution itself has been updated (currently v3.16 in our environment). Analytics, parsers, and connector components have evolved. The legacy Azure Function deployment still appears to be tied to the original package referenced by WEBSITE_RUN_FROM_PACKAGE. This raised a broader lifecycle and maintenance question: Questions 1. Is the package referenced by: https://aka.ms/sentinel-BoxDataConnector-functionapp still actively maintained and republished by Microsoft? 2. If updates are made to the Box Solution source code or supporting files in the GitHub repository, are those updates expected to flow automatically to existing Azure Function deployments that use WEBSITE_RUN_FROM_PACKAGE? 3. If updates do not automatically flow to existing deployments, what was the intended maintenance model for customers using the legacy Azure Function connector? For example, were customers expected to: Continue using the Microsoft-hosted package URL indefinitely? Periodically redeploy using updated templates? Download and self-maintain the Function App package? Modify the Function App to stop using WEBSITE_RUN_FROM_PACKAGE? 4. Prior to the introduction of the Box Events (CCP) connector, how were customers expected to apply updates, dependency changes, security fixes, and other improvements to existing Box Azure Function deployments? 5. Is migration to the Box Events (CCP) connector now considered the only supported path for customers wishing to remain current with Microsoft Sentinel Box integrations? Reason for asking The goal is not to troubleshoot the new CCP connector. Rather, we are trying to better understand the support and maintenance lifecycle of the legacy Azure Function-based Box connector and how Microsoft intended customers to remain current when deployments were originally made using a Microsoft-hosted WEBSITE_RUN_FROM_PACKAGE endpoint. Any clarification from the Box Solution maintainers or Microsoft Sentinel team would be appreciated. NB I came across this notice after following some links from the Box Solution listed in Azure. https://github.com/Azure/Azure-Sentinel/blob/master/Solutions/known_issues.md#known-issue-2--solution-re-deployment-or-update That seems to indicate that somehow we are meant to Redeploy the entire package when there is an update and then somehow copy / update all the Custom Analytics Rules and Automations. Is there no way to merge the new modules and updates without basically having to start over with a side-by-side deployment?36Views0likes0CommentsAnnouncing the Open-Source Release of ML Video Codec (MLVC)
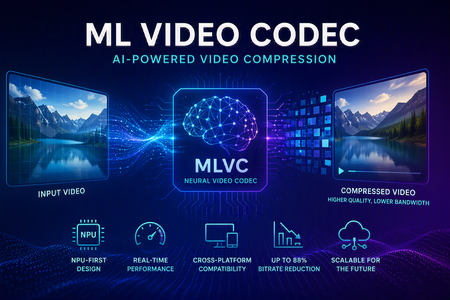
Video codecs compress video for transmission or storage, reducing bandwidth and storage requirements. MLVC is a modern machine-learning-based codec that uses substantially less bandwidth than conventional codecs, improving streaming and video-call quality—especially on constrained or unreliable networks—while lowering delivery and storage costs. MLVC is the product iteration of DCVC (Deep Contextual Video Compression) family of NVC (Neural Video Codec), open sourced by Microsoft Research since 2021, with improved compression efficiency, real-time performance on commodity Neural Processing Units (NPUs), and cross-platform support. We recently published this work in the paper MLVC: Multi-platform Learned Video Codec for Real-World Deployment. We are releasing the source code because we believe the next generation of video coding will be built openly, and we want the broader community — researchers, video codec engineers, platform vendors, product teams, as well as general developer community — to build it with us. Why MLVC Traditional video codecs (e.g., H.264/AVC, H.265/HEVC) have served the industry for a long time, but each generation requires enormous engineering effort for incremental gains and needs dedicated hardware which takes years to become commonly available. MLVC replaces conventional primitives — motion estimation, transforms, entropy modeling — with end-to-end learned neural compression, trained directly against rate-distortion objectives, and run on general-purpose NPU devices. The table below compares MLVC to popular video codecs, showing its lower bitrate and resulting savings in bandwidth and storage. Resolution vs H.264 vs H.265 360p 87.8% 75.5% 540p 82.7% 65.4% For example, for 360p video at 30 fps, where H.264 requires 1 Mbps, MLVC requires roughly 122 kbps for equivalent quality — about one-eight the bitrate under real-time conditions. The inference compute was kept approximately equal for the 360p and 540p resolutions. These results are based on a P.910 subjective test and are based on the Video Conferencing Dataset (VCD) dataset that we developed and also recently released as an open-source project. The following video demo illustrates the extent of quality enhancement achieved by MLVC relative to H.265/HEVC at the same bitrate of 200kbps (please watch by opening in a new window for better demonstration) \ Beyond video compression efficiency, MLVC also offers: NPU-first design. MLVC is built to run almost entirely on the AI accelerators already shipping in modern devices — Apple Neural Engine, Qualcomm and Intel NPUs — at no more than 50% NPU utilization, leaving NPU headroom for the rest of the system. Real-time execution at the targeted operating points. Demonstrated 540p at 30 fps on Apple, Intel, and Qualcomm hardware. A scaling-law trajectory. Empirically, MLVC's coding efficiency improves with increased model capacity and additional training compute. Content-adaptive behavior out of the box, without hand-tuned Rate Distortion Optimization heuristics. Already running in Microsoft Teams MLVC is more than just a research concept for Microsoft. We are currently rolling it out in Microsoft Teams, where it is being validated on real peer-to-peer video calls with active telemetry and A/B testing. The integration runs alongside fallback to conventional video codecs for hardware or reliability constraints — the kind of mixed-environment deployment that real products need. The scaling and reliability insights from this rollout are shaping the codec and its roadmap. We welcome your contributions We can not cover every use case, every device class, or every content domain by ourselves. That is why we are open sourcing MLVC. If you work on: Streaming, Video On Demand (VOD), or live broadcast Real-time communication and conferencing Cloud gaming or remote rendering Surveillance, drones, or robotics Mobile capture, Augmented Reality (AR) / Virtual Reality (VR), or volumetric video Codec hardware, NPUs, or inference runtimes We would love your help. Contributions of all kinds are welcome, including model improvements, training recipes, new platform ports and conversion targets, runtime backends, domain-specific fine-tunes, evaluation tooling, bug reports, and feedback on what is missing for your scenario. We particularly welcome platform ports that expand NPU coverage and efficiency improvements that push the rate-distortion frontier. What's in the release The MLVC repository is available at https://github.com/microsoft/mlvc and shared under the MIT License. It includes: MLVC model source code of the full network architecture. Trained model weights ready to run. Training scripts used to produce shipping models. Training data collection documentation to help reproduce and improve MLVC. Platform conversion scripts to target different NPUs and runtimes. Issues and pull requests will be open from day one. A follow-up release will add a C++ codec library, simplifying integration into real-world applications. Where we're heading Our long-term goal with MLVC is to create an open, learned video codec that meets or exceeds the coding efficiency of the best conventional codecs across the full range of video content, runs efficiently on the AI hardware already shipping in client and cloud devices, scales with compute the way modern ML systems do, and evolves in the open at the pace of the ML community rather than the pace of standardization cycles. In the near term that means stabilizing 540p real-time performance, expanding hardware coverage, and improving loss resilience. In the medium term: higher resolution, e.g., 1080p, and broader streaming scenarios. In the long term: an open video codec ecosystem that meaningfully replaces legacy stacks where it makes sense to. We can't create the future of MLVC alone. We're glad you're here, and we are looking forward to building the next-generation video codec with you. Who are we MLVC is brought to you by the following awesome folks working on the project at Microsoft: Ross Cutler, Ando Saabas, Tanel Pärnamaa, Ardi Loot, Haiyan Xie, Lauri Ehrenpreis, Andrei Znobishchev, Martin Lumiste, Evgenii Indenbom, Yan Lu, Bin Li, Jiahao Li, Naba Kumar, Babak Naderi, Juhee Cho, Badal Yadav, Jinxin Zhou, Tianyu Ding, Patrick Gregory. — The MLVC Team, Microsoft16KViews0likes5CommentsBuild a Tenant-Wide Microsoft Foundry Model Operations Dashboard
As AI projects move from pilots to production, model deployments often spread across subscriptions, regions, and application teams. A practical operations dashboard gives platform, engineering, governance, and finance teams one shared view of what is deployed, how it is used, what it costs, and where quota or capacity risk is forming. The operating problem Microsoft Foundry brings agents, models, tools, monitoring, tracing, evaluations, RBAC, networking, and policy controls under a unified platform surface. That is a strong foundation, but enterprise operations still need a view that cuts across the way Azure is usually organized: multiple subscriptions, resource groups, regions, business units, and application teams. The goal is not to replace product dashboards. The goal is to add a management-group or tenant-wide operating layer that answers simple but urgent questions: Which models are deployed? Which teams own them? Which deployments use Standard, priority, batch, or provisioned throughput? Where are token usage and PTU utilization rising? Which subscriptions are approaching quota pressure? Which costs should be allocated to which product or environment? Design principle: keep the dashboard about deployment and operations metadata. Do not collect prompts, completions, customer data, or other application payloads unless a separate privacy, security, and compliance design explicitly requires it. A practical reference architecture Use three data planes. First, build the inventory plane with Azure Resource Graph, because Resource Graph is designed for efficient, large-scale querying across subscriptions and tenants. Combine account-level resource data with deployment-level data from the Azure AI Services deployments API, which lists deployments associated with a Cognitive Services account. Normalize subscription, resource group, region, account, deployment name, model name, model version, deployment type, SKU or capacity, tags, owner, environment, and business unit. Build the telemetry plane with Azure Monitor. Public Azure OpenAI monitoring guidance describes dashboards for HTTP requests, token-based usage, PTU utilization, and fine-tuning. Azure Monitor supported metrics and resource log references provide the authoritative place to check what is available for each resource type and how exportability works. For exploratory operations views, Azure Workbooks are a good fit because they combine logs, metrics, parameters, Azure Resource Graph, Azure Resource Manager, JSON, and other data sources in one interactive report. Build the finance plane with Cost Management APIs or exports. Cost Management automation guidance supports retrieving and managing cost data, including for larger datasets that need offline analysis. The Cost Management Query API supports usage queries at scopes such as subscription, resource group, billing account, management group, billing profile, and invoice section, subject to permissions. Power BI can be useful for leadership reporting, but the Cost Management connector has agreement constraints; direct connector support is documented for Enterprise Agreement and direct Microsoft Customer Agreement customers, while unsupported agreements should use exports. Separate inventory, usage, cost, and quota Do not treat every signal as the same kind of data. Inventory is mostly current-state metadata. Usage is time-series behavior. Cost is billing-scope data that may lag and must be joined carefully by resource identity, meter, and tags. Quota is a capacity-control signal, not a spend signal. Azure OpenAI quota is not enforced at tenant level; Microsoft Learn states that the highest quota restriction is scoped at the Azure subscription level. That means an executive dashboard can summarize quota posture broadly, but engineering views should still preserve subscription, model, region, and deployment-type detail. Provisioned throughput deserves a dedicated view. Microsoft documents PTU as dedicated model processing capacity for predictable throughput and latency, billed per PTU per hour or through reservations. That makes PTU utilization, idle capacity, traffic predictability, and latency requirement visible design inputs rather than after-the-fact finance questions. Dashboard views that matter Start with a few durable views rather than a large reporting program. The most useful first version usually includes: Executive summary: deployment count, model families, regions, monthly cost trend, and quota risk. Inventory: deployments by subscription, resource group, region, model, version, deployment type, owner, and environment. Operations: request volume, token trends, errors, latency indicators, and PTU utilization where available. Cost allocation: spend by owning team, application, environment, and deployment type. Governance hygiene: missing tags, ownerless deployments, old model versions, and regional concentration. Decision guidance Choose the reporting surface by audience. Platform engineers usually need Workbooks because they support operational drill-down and can combine Azure Monitor and Resource Graph. Finance teams often need Power BI because it supports broader cost modeling and distribution. Application owners need a small scorecard: their deployments, their usage, their costs, their quota posture, and their next required action. Production considerations and limitations Require tags before reporting on ownership. Dashboards cannot create accountability if resources do not carry owner, application, environment, and cost-center metadata. Use least-privilege access. Cost, inventory, and telemetry sources may require different permissions and scopes. Check portal-version language. Some public monitoring guidance is explicitly marked for the Foundry classic portal, so avoid assuming identical behavior in every new portal experience. Verify regional availability. Model availability varies by region, and deployment lifecycle settings such as automatic model updates should be reviewed before making standardization claims. Respect metric export limits. Azure Monitor notes that some metrics have export constraints, especially around multidimensional metrics and diagnostic settings. Implementation checklist Define the dashboard audience and the decisions it must support. Inventory Foundry and Azure OpenAI resources across subscriptions with Azure Resource Graph. List deployments per account and normalize deployment metadata. Route or query Azure Monitor metrics and logs needed for usage and PTU views. Add Cost Management queries or exports at the correct billing scope. Join by resource ID and tags; flag missing ownership metadata. Publish an Azure Workbook for operations and a Power BI model only where agreement support and permissions fit. Review model versions, quota posture, and PTU utilization on a fixed cadence. Conclusion A tenant-wide model operations dashboard is a practical bridge between AI experimentation and AI platform management. It does not need to be complex on day one. Start with inventory, usage, cost, quota, and ownership. Keep application content out of scope. Preserve subscription-level quota detail. Then evolve the dashboard into a repeatable operating rhythm for model lifecycle, cost control, capacity planning, and governance.251Views0likes0Comments
Microsoft Defender XDR / Defender for Endpoint data connectors inconsistent failures
Hello, We are deploying our SOC (Sentinel) environments via Bicep. Now the Defender XDR ( MicrosoftThreatProtection) and Defender for Endpoint ( MicrosoftDefenderAdvancedThreatProtection) data connectors are failing to deploy inconsistantly. It seems to be a known issue due to the following posts: - https://github.com/Azure/SimuLand/issues/23 - https://techcommunity.microsoft.com/t5/microsoft-sentinel/quot-missing-consent-invalid-license-quot-defender-for-endpoint/m-p/3027212 - https://github.com/Azure/Azure-Sentinel/issues/5007 Next to this issue I see almost no development on the data connectors API, is there some news to be spread how to enable data connectors automated in the future, since it seems to be moving to Content Hub. It is hard to find any docs about how to deploy this for example via Bicep!? Also I have a question regarding 'Tenant-based Microsoft Defender for Cloud (Preview)' data connector. We deploy this now via GenericUI data connector kind, but this has no option to enable it via automation. Same as the question in the previous paragraph, how would this be made possible?1.2KViews0likes1CommentGovernance Boundaries in Microsoft Foundry
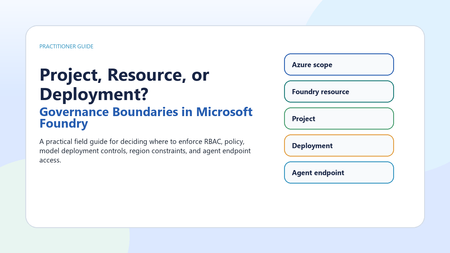
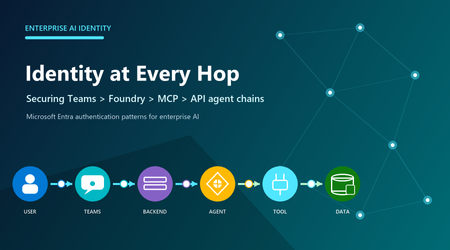
Microsoft Foundry governance works best when teams separate broad Azure controls from Foundry resource controls, project access, model deployment configuration, and agent endpoint permissions. This article provides a practical boundary map for production decisions, with public references and a checklist for implementation. Use Azure subscription and resource group scope for enterprise-wide policy, allowed regions, tagging, budgets, and inherited access. Use the Foundry resource as the administrative, security, networking, monitoring, and shared deployment boundary. Use projects for team and workload organization, not as the only place to enforce enterprise controls. Use model deployments to govern runtime model version, deployment type, capacity, filters, and rate behavior. Use agent-scope access for narrow endpoint consumption, and prefer Microsoft Entra ID over API keys for production. Why this matters Microsoft Foundry is becoming the shared place where teams build agents, deploy models, connect tools, evaluate behavior, and operate AI systems. That consolidation is useful, but it also creates a practical governance question: should a control live at the Azure subscription, the Foundry resource, the project, the model deployment, or the agent endpoint? The answer matters because each boundary enforces a different kind of decision. A five-boundary mental model Start with the broadest boundary and move inward. The subscription or resource group is where enterprise Azure governance usually begins: allowed regions, required tags, cost grouping, resource locks, inherited role assignments, and Azure Policy initiatives. The Foundry resource is the administrative and security boundary for a Foundry environment. Microsoft describes it as the single management plane for agents, models, and tools, with unified RBAC, networking, and policies. Separate control plane from data plane The cleanest design conversations separate management actions from runtime actions. Control-plane decisions include creating resources and projects, assigning roles, configuring networking, creating connections, and deploying models. Data-plane activity includes inference, agent interaction, evaluation jobs, content safety calls, tracing, and monitoring. A role or lock that protects a resource from deletion does not automatically govern every runtime action. Production governance should deliberately combine Azure RBAC, Foundry RBAC, Azure Policy, network controls, deployment settings, and application logic. RBAC guidance Use Microsoft Entra ID for production wherever possible. Microsoft states that API keys are convenient for prototyping but coarse-grained, hard to audit per user, and not recommended for production least-privilege scenarios. Foundry roles are designed for Foundry-specific workflows: for example, builders, project managers, account owners, and agent consumers. Azure roles still matter for subscription, resource group, and role-assignment authority. Be conservative: check the current role table for the exact operation because model deployment, project building, agent publishing, and inference can use different permission surfaces. Deployment governance is runtime governance A model deployment is not just a model choice. It is where runtime posture becomes concrete. Deployment type affects where inferencing data can be processed: Global deployments may process in any Azure region, Data Zone deployments keep processing within the Microsoft-specified US, EU, or APAC data zone, and Standard deployments process in the deployment region. That makes deployment type a compliance and architecture decision, not only a performance or price decision. Policy, preview, and availability Azure Policy can enforce or audit important Foundry-adjacent requirements, including key access, customer-managed keys, private link, network restrictions, managed identity, model eligibility, and content filtering. Several AI/model-specific policy definitions are marked Preview, so treat them as promising controls rather than production defaults unless your organization accepts preview terms. Foundry also documents a tag to hide preview surfaces and custom RBAC patterns to block selected preview operations. Recommended operating pattern Use resource groups and subscriptions for enterprise policy, cost, and environment separation. Use separate Foundry resources when environments need different networking, keys, quotas, or administrative ownership. Use projects for team and workload separation inside a governed resource. Use model deployments to isolate runtime configuration, model version, data-processing posture, filters, and capacity. Use agent-scope access only when a consumer needs one agent endpoint, not the whole project. Prefer Entra ID and managed identities, and disable or tightly govern local key access where production controls require it. Decision guide Production checklist Which boundary owns this control: Azure scope, Foundry resource, project, deployment, or agent endpoint? Is the action control plane or data plane? Is the model or feature generally available or Preview? Where can inferencing data be processed for the chosen deployment type? Which role grants only the needed permission at the narrowest useful scope? Is enforcement handled by RBAC, Azure Policy, network isolation, deployment configuration, or application code? Have region, quota, model availability, dependent services, Marketplace terms, and cloud environment been verified? Conclusion Governance in Microsoft Foundry is not a single switch. It is a layered design. Put enterprise constraints at Azure scope, shared platform controls at the Foundry resource, team workflows in projects, runtime posture in deployments, and consumer permissions at the agent endpoint. That separation keeps governance understandable, auditable, and easier to change as models, regions, deployment types, and platform features evolve.187Views0likes0CommentsIdentity at Every Hop
Use delegated On-Behalf-Of access only when a downstream service must enforce the signed-in user's permissions. Use a managed or agent identity for unattended work. At every hop, obtain a token for the intended audience instead of forwarding one issued for another service. Model every hop as a boundary A Teams request can involve a user, Teams app or bot, application backend, Foundry project or agent, MCP server, and protected API. Each component may use a different principal, token audience, permission model, and consent boundary. Decide whose authority each downstream resource should evaluate, then grant that principal only the required access. For a Teams tab, getAuthToken() returns a JWT whose audience is the application's client ID. Send it to the backend over HTTPS and validate signature, issuer, audience, expiry, and tenant. It is not a general-purpose Microsoft Graph token. Bot SSO uses the Bot Framework token service; documented SSO supports one-to-one and group chats, not channel scope. Do not authorize from a display name, email, or client-parsed claim. The backend must establish the trusted principal first, then apply application authorization. Teams SSO gets identity into the application; it does not grant automatic access to Foundry, a tool, Graph, or business data. Exchange tokens when user authority must travel OAuth 2.0 OBO is for a middle-tier API calling another API under a signed-in user's delegated authority. The backend validates Token A, authenticates as a confidential client, and exchanges Token A at the tenant-specific Entra endpoint. Entra returns Token B for the downstream audience and scopes. Present Token B only to that resource. OBO requires a user principal and delegated scopes. An app-only token cannot be used as the OBO assertion; use client credentials or managed identity when no user is present. Never relay the backend token to Graph, MCP, or another API. Relay breaks audience enforcement and can conflict with Conditional Access. Surface interaction-required claims challenges back to the client instead of hiding them as generic server failures. Assign the correct Foundry identity An agent identity is a specialized Entra service principal. Unpublished agents share a project-level development identity; publishing creates a distinct production agent identity. Permissions do not transfer automatically, so assign downstream roles to the published identity. At runtime, Agent Service obtains a scoped token for the target service; the audience is that service's resource identifier, not necessarily the MCP endpoint URL. Apply Foundry RBAC at the narrowest useful scope. Foundry Agent Consumer is for invocation, Foundry User is for building and testing, and Foundry Project Manager supports project management and publishing. Prefer Entra authentication: resource keys provide coarse access and bypass these role distinctions. Role names may still appear under older Azure AI labels during rollout. Treat MCP authorization as an explicit design MCP defines tool discovery and invocation; it does not make a server trusted. For remote servers, choose no authentication only for intentionally public services. Otherwise use custom keys, custom OAuth, a user Entra token, project managed identity, or agent identity according to who must be authorized. A configured connection does not grant downstream permission by itself. Toolbox can centralize credential injection, refresh, versioning, and policy behind an MCP-compatible endpoint. Allow-list required tools, require approval for risky writes, and log tool names, authorization outcomes, and approvals without logging tokens. Prefer managed identities or federated credentials to stored secrets. For user-owned mail, files, or other delegated resources, choose supported user passthrough or OBO. For background jobs, use workload identity. When every published agent needs distinct permissions and audit, use its distinct agent identity. Use project managed identity only when all agents in that project should share the same Azure access after explicit risk review. Practical identity checklist Multitenant sign-in does not make every downstream exchange cross-tenant. Customer consent creates a service principal in the customer tenant, but Foundry's built-in OAuth identity passthrough requires the user's tenant to match the Foundry project tenant. Define tenant placement, administrator consent, issuer validation, and offboarding; use a validated custom OAuth design when built-in passthrough cannot meet the requirement. Troubleshoot from the resource that rejected the request. A 401 usually points to a missing, expired, malformed, or wrong-audience token. A 403 usually means the identity is recognized but lacks permission, although service firewalls can also return 403. DNS failures, TCP timeouts, and private-endpoint routing errors are not repaired by adding RBAC. Question Production decision Whose authority? User: delegated OBO. Workload: managed or agent identity. Correct token? Validate issuer, audience, tenant, lifetime, scopes, and claims. Correct principal? Reassign target RBAC after publishing creates a new identity. Tool governance? Allow-list tools; approve side effects; broker shared credentials. Cross-tenant? Design consent and offboarding; built-in passthrough requires matching user and Foundry tenants. Failure class? Separate 401, 403, consent, DNS, firewall, routing, and timeout evidence. Conclusion Design identity before connecting tools. Ask who the downstream service should authorize, exchange tokens for the correct audience, and scope RBAC to the resulting principal. Validate consent, renewal, revocation, tool approval, and network reachability one hop at a time.173Views0likes0CommentsLessons Learned #555: The First 60 Seconds of a Production Incident: Stop, Scope, Correlate
When a critical production incident starts, the first message we often receive is something like: “The database is down.” At that moment, everything suddenly becomes urgent. Engineers open monitoring dashboards. Someone starts checking logs. Another person reviews CPU and memory. Someone else asks whether there was a deployment. Connections are tested. Metrics are queried. Teams are contacted. All of these actions may eventually be necessary. But there is a more important question to answer first: What exactly does “down” mean? After working on many production incidents, one lesson becomes increasingly clear: The first 60 seconds are not about solving the incident. They are about defining the incident. A vague problem description can send troubleshooting in many different directions. A precise problem statement dramatically reduces the investigation space. This article describes a simple approach that can be applied during the first moments of an incident: Stop. Scope. Correlate. 1. Stop: Define What “Down” Actually Means The first mistake during many incidents is assuming that everyone understands the problem in the same way. Consider the statement: “The database is unavailable.” That statement could mean many different things: Applications cannot establish new connections. Existing connections are still working, but new connections fail. Queries are timing out. A specific login cannot authenticate. One database is inaccessible. One application is failing while other applications work correctly. Performance degradation makes the service appear unavailable. The application returns HTTP 500 errors, but the database itself is healthy. Connections fail intermittently. A failover is occurring. DNS or networking issues prevent the application from reaching the database. These scenarios require completely different investigation paths. Before opening ten different tools, try to transform the original statement into something more specific. For example: Instead of: “The database is down.” Try to reach something like: “Since approximately 14:32 UTC, new application connections to Database A have intermittently failed with login errors, while existing sessions remain active.” Now we have something we can investigate. The problem statement contains: a timestamp, a specific database, a specific symptom, affected connection behavior, and an indication that the issue may be intermittent. That is already much more valuable than the original alert. 2. Scope: Determine the Blast Radius Once we understand the symptom, the next question is: Who or what is affected? This is sometimes called determining the blast radius. The scope can immediately eliminate entire categories of possible causes. Ask questions such as: Is one user affected or every user? Is one application affected or several applications? Is one database affected or all databases? Are all connection types affected? Are existing connections healthy while new connections fail? Are only specific clients or drivers affected? Imagine the following situation. Application A reports database connectivity failures. However: Application B connects successfully. SSMS connects successfully. Azure metrics show the database is available. Existing sessions continue executing queries. This changes the investigation dramatically. The problem may not be: “Azure SQL is unavailable.” It may instead be: “Application A cannot establish new connections.” That distinction is extremely important. A large percentage of troubleshooting time can be saved simply by identifying the correct scope early. 3. Build the Timeline The next critical dimension is time. During an incident, timestamps are evidence. Ask: When did the issue start? Is there an exact timestamp? How long did it last? Is the issue continuous or intermittent? Did the problem recover automatically? Did the issue occur once or multiple times? Was there another event immediately before the problem? A good incident timeline may look like this: 14:31:52 UTC – Application operating normally 14:32:08 UTC – First connection error reported 14:32:10 UTC – Database failover detected 14:32:14 UTC – Additional login failures 14:32:18 UTC – New connections begin succeeding 14:32:20 UTC – Application fully recovere Now the investigation is no longer based on assumptions. We have a five-to-ten-second window that can be correlated with platform telemetry, database events, application logs, networking information, and deployment history. Without the timeline, engineers may analyze hours of logs. With the timeline, the investigation becomes focused. 4. Correlate Before Changing Anything The next step is correlation. Once we understand the symptom, scope, and timeline, we can ask: What changed at the same time? Useful correlation sources may include: application deployments, infrastructure changes, configuration changes, database failovers, scaling operations, maintenance events, firewall changes, authentication changes, networking events, DNS changes, resource utilization, query regressions, blocking, deadlocks, connection pool behavior, driver updates, platform events. etc The key word here is correlation. It is tempting during an incident to immediately change something. For example: restart the application, restart a service, scale the database, clear the connection pool, change configuration, rebuild an index, modify a query, fail over manually. Sometimes these actions are necessary. But every change also modifies the evidence. A restart may restore the service while simultaneously removing valuable diagnostic information. Whenever possible: Collect evidence before changing the environment. 5. Use Multiple Sources of Evidence Production incidents rarely provide the complete answer in one telemetry source. A better approach is to correlate multiple sources. For a database-related incident, we may investigate: Application telemetry Application logs may reveal: connection failures, authentication errors, request latency, retry attempts, timeout exceptions, HTTP errors, dependency failures. Platform metrics Cloud metrics may help determine: service availability, CPU utilization, storage pressure, connection count, throttling, resource saturation. Database telemetry Database-level information may include: active sessions, waits, blocking, query performance, login failures, failover events, resource statistics. Query Store For performance incidents, Query Store can be extremely valuable. It may help identify: query regressions, plan changes, increased execution duration, abnormal CPU consumption, changes in execution frequency. Deployment history Always ask: What changed recently? Many incidents have a strong temporal relationship with: application deployments, schema changes, configuration modifications, infrastructure updates, new releases, security changes. The goal is not to assume that the most recent change caused the incident. The goal is to determine whether the events correlate. 6. Avoid Starting With a Tool One common troubleshooting pattern is: “Open the monitoring portal.” or: “Run this query.” or: “Check this log.” Tools are essential, but tools should follow the investigation strategy. The investigation should determine which tool we need. Not the other way around. If the problem is authentication, the investigation path may focus on: login errors, authentication configuration, identity providers, user mappings, connection strings. If the problem is performance, the investigation may focus on: Query Store, waits, blocking, execution plans, resource utilization. If the problem is connectivity, we may investigate: DNS, network paths, firewalls, drivers, retries, connection pools. A clear problem definition tells us where to look. 7. Ask the Same Questions Every Time One of the most effective improvements teams can make is standardizing the first questions asked during incidents. A simple initial checklist could be: Symptom: What exactly is failing? Scope: Who or what is affected? Timeline: When did it start? Error: What exact error message or error code is being returned? Frequency: Is the issue continuous, intermittent, or already recovered? Changes: What changed immediately before the incident? Evidence : Which telemetry sources can confirm the behavior? These questions are intentionally simple. During a high-severity incident, simplicity is valuable. 8. The First 60 Seconds Framework We can summarize the approach in four steps. 1. Define: What does the reported symptom actually mean? 2. Scope: Determine the blast radius. 3. Timeline: Identify exactly when the problem occurred. 4. Correlate Connect the symptom with telemetry, events, and recent changes. Only after these steps should we decide the deeper troubleshooting path. 9. Speed Is Important, but Direction Is More Important During critical incidents, teams naturally want to move quickly. That is the correct instinct. But speed without direction can create noise. Ten engineers investigating ten different theories at the same time may generate enormous activity without producing clarity. A well-defined incident allows teams to divide the investigation intelligently. For example: One engineer investigates application telemetry. Another checks database telemetry. Another reviews platform events. Another investigates recent deployments. Another builds the incident timeline. All of them are now investigating the same defined problem. That is very different from everyone independently trying to determine what the problem might be.
Unexpected $22,000 Azure Marketplace Charge With No Meaningful Warning or Support Escalation
I am hoping someone from Microsoft, Azure Support, or the community can help point me in the right direction because we have reached a point where we genuinely do not know what else to do. Our company participates in an Azure Sponsorship program and has historically operated primarily using sponsorship credits. Recently, we deployed Claude models through Azure AI Foundry under the understanding that our Azure usage was generally being covered through our sponsorship. We later discovered that Claude is considered an Azure Marketplace charge and is therefore excluded from Azure Sponsorship credits. We understand that distinction now. The problem is everything that happened around it. In approximately three days, our company accumulated roughly $22,000 CAD in direct charges. At no point during the deployment process did we receive what I would consider a clear or meaningful warning that: Claude usage would not be covered by our Azure Sponsorship credits. The deployment would result in direct Marketplace charges. We were beginning to accumulate significant charges outside of our sponsorship. Our spending had suddenly increased dramatically beyond our normal usage pattern. We also had a budget configured, but it did not provide us with a meaningful warning before these charges accumulated. We discovered the approximately $22,000 charge almost by accident while reviewing another area of the Azure portal. Had we not happened to look at that page, I do not know how much higher the charges could have become. The Support Experience Has Been Even More Frustrating Since discovering the issue, I have been trying to work through Microsoft's support channels. Microsoft documentation indicates that billing support is available, but actually reaching someone with the ability to review this situation has been extremely difficult. We have repeatedly been directed to create support requests, but the process either prevents us from creating the appropriate ticket or directs us to other support channels. We have also received automated guidance recommending that we use certain cost-management and monitoring capabilities, despite some of those capabilities being unavailable or limited under the legacy sponsorship subscription we are operating under. In another support case, Microsoft simply closed the ticket without asking us and without resolving the issue. That has been one of the most concerning parts of this experience. We are trying to actively resolve a significant financial issue, and instead of getting an escalation path, tickets are being redirected, answered with generic information, or closed. What We Are Looking For At this point, I am simply trying to reach someone at Microsoft who has the authority to actually review this situation. I would greatly appreciate guidance on any of the following: How to escalate an Azure Marketplace billing dispute beyond Azure Sponsorship support. How to reach an Azure billing or Marketplace escalation team that can review exceptional circumstances. Whether there is a formal billing dispute or invoice review process for this type of situation. How to escalate a support case when an existing case has been closed without resolution. Whether someone from Microsoft can review the circumstances surrounding these charges rather than only confirming that Marketplace charges are excluded from sponsorship credits. We have been Microsoft and Azure customers in good faith, and we attempted to put spending controls in place. We are not trying to avoid legitimate usage costs. We are asking Microsoft to review a situation where approximately $22,000 CAD accumulated in roughly three days without a meaningful warning or intervention, followed by a support experience where we have struggled to reach anyone with the authority to help. If anyone from Microsoft or the Azure community can help identify the correct escalation path, I would sincerely appreciate it.247Views1like1CommentApplying Site Reliability Engineering to Autonomous AI Agents
If you practice SRE, you already have a mental model for running reliable production systems. You define SLOs. You track error budgets. You use circuit breakers to stop cascading failures. You run chaos experiments to find weaknesses before customers do. You treat every operational decision as a tradeoff between reliability and velocity. That mental model transfers directly to AI agents. It just needs four new ideas. In the Agent Governance Toolkit: Architecture Deep Dive, Policy Engines, Trust, and SRE for AI Agents, we covered Agent SRE briefly as one of AGT's nine packages: SLOs, error budgets, circuit breakers, chaos engineering, and progressive delivery, adapted from the patterns your SRE team already applies to microservices. Several teams asked for the full story. This is it. Agent SRE is one of the more novel parts of the toolkit. The policy engine, zero-trust identity, and execution sandboxing have clear analogs in existing security practice. Agent SRE explores newer ground. Established patterns for defining SLOs for AI agent behavior, building chaos experiments for LLM provider failures, or applying error budgets to agent autonomy are still emerging across the industry. We built these capabilities because running agents in production without them is the equivalent of running a fleet of microservices without circuit breakers, health checks, or an on-call runbook. This post is for SRE teams, platform engineers, and anyone responsible for running AI agents in production. You do not need to be an AI specialist. If you know what a burn rate is, you are ready for this. The Problem: Agents Fail in Ways Your Existing SRE Tooling Cannot See When a service fails, your observability stack tells you: latency went up, error rate crossed the SLO threshold, the circuit breaker opened. You page the on-call engineer. They look at traces and find the slow database query. When an AI agent fails, your observability stack is silent. The agent returned HTTP 200. Latency was normal. Error rate was zero. But the agent quietly approved a transaction it was not authorized to approve, hallucinated a database path and wrote to the wrong table, or got stuck in a reasoning loop that consumed $800 of LLM API budget before anyone noticed. These are not infrastructure failures. They are behavioral failures. And they are invisible to monitoring tools built for stateless, deterministic services, because those tools only watch for crashes and timeouts. They do not watch for wrong behavior. This gap is the problem Agent SRE was designed to solve. The solution borrows everything from the SRE playbook and adds one concept that extends it: the Safety SLI. The Safety SLI: A New Reliability Dimension Traditional SLIs measure system behavior from the user's perspective: latency, availability, error rate, throughput. They answer: did the service respond correctly? For AI agents, correctness is not enough. An agent that responds correctly but acts outside its authorized scope has not succeeded. It has failed in a way that none of your existing SLIs can detect. The Safety SLI answers a different question: did the agent act within policy? from agent_sre import SLO, ErrorBudget from agent_sre.slo.indicators import PolicyCompliance # Define a safety SLO: 99% of agent actions must comply with policy safety_slo = SLO( name="safety-compliance", indicators=[ PolicyCompliance( target=0.99, window="7d", ), ], error_budget=ErrorBudget( total=0.01, # 1% budget (1 - 0.99 target) window_seconds=2592000, # 30-day window burn_rate_alert=2.0, # warn at 2x sustainable rate burn_rate_critical=5.0, # page at 5x sustainable rate ), ) When an agent's policy compliance rate drops below 99%, the error budget starts burning. The ErrorBudget tracks consumption automatically and exposes burn rate alerts through its firing_alerts() method. When the budget is exhausted, the configured exhaustion_action determines the system response: from agent_sre.slo.objectives import ExhaustionAction # Configure what happens when error budget is exhausted safety_slo = SLO( name="safety-compliance", indicators=[PolicyCompliance(target=0.99, window="7d")], error_budget=ErrorBudget( total=0.01, window_seconds=2592000, burn_rate_alert=2.0, # fires at 2x sustainable burn rate burn_rate_critical=5.0, # fires at 5x sustainable burn rate exhaustion_action=ExhaustionAction.CIRCUIT_BREAK, # suspend agent when budget is gone ), ) # In your monitoring loop, check for firing alerts alerts = safety_slo.error_budget.firing_alerts() for alert in alerts: print(f"Alert firing: {alert.name} (severity: {alert.severity})") # Check budget status print(f"Budget remaining: {safety_slo.error_budget.remaining_percent:.1f}%") print(f"Current burn rate: {safety_slo.error_budget.burn_rate():.2f}x") print(f"Exhausted: {safety_slo.error_budget.is_exhausted}") This is the governance dial from the other direction. The error budget is not just a metric: it is the mechanism that drives agent autonomy decisions. An agent with a clean 30-day safety record earns autonomy. An agent whose budget is burning at 5x the sustainable rate triggers a critical alert, and when the budget is exhausted, the exhaustion_action fires: ALERT, THROTTLE, FREEZE_DEPLOYMENTS, or CIRCUIT_BREAK. The graduated response mirrors what SRE teams already do with service SLOs, applied to agent behavior. There are multiple SLI dimensions built into Agent SRE. Safety SLIs and Performance SLIs track different aspects of the same agent: SLI Type What It Measures Target Pattern When Budget Burns Safety SLI PolicyCompliance -- fraction of actions within authorized scope >= 99% Restrict capabilities, increase human oversight Performance SLI TaskSuccessRate, ResponseLatency, CostPerTask Configurable per workload Alert, throttle, or circuit-break LLM provider Additional built-in indicators include ToolCallAccuracy, DelegationChainDepth, HallucinationRate, and CalibrationDeltaSLI. Both SLOs feed into the same error budget dashboard. An agent can have excellent performance but a degrading safety record, or perfect safety compliance and terrible cost efficiency. You need both dimensions to understand whether an agent is production-ready. Circuit Breakers: Governing Agent Failure Modes That Don't Exist in Microservices Circuit breakers for services protect against one failure mode: a backend that is slow or unreachable. The pattern is CLOSED -> OPEN -> HALF_OPEN. You know it well. Agent SRE implements the same state machine for failure modes that are specific to autonomous reasoning systems and do not exist in traditional microservice architectures: from agent_sre.cascade.circuit_breaker import CircuitBreakerConfig, CircuitBreaker from agent_sre.chaos.engine import FaultType config = CircuitBreakerConfig( failure_threshold=5, # Open after 5 failures in the window recovery_timeout_seconds=60, # Stay OPEN for 60s before HALF_OPEN half_open_max_calls=3, # Allow 3 probes in HALF_OPEN ) breaker = CircuitBreaker(agent_id="analyst-agent-001", config=config) # Failure modes tracked by the circuit breaker: tracked_faults = [ FaultType.POLICY_BYPASS, # Agent exceeds authorized scope FaultType.ERROR_INJECTION, # Upstream model API fails FaultType.TIMEOUT_INJECTION, # Tool calls exceed time budget FaultType.TRUST_PERTURBATION, # Agent trust score falls below threshold FaultType.DEADLOCK_INJECTION, # Agent stuck in iterative reasoning ] Each failure mode has different circuit-breaking semantics: Failure Mode What Triggers It Circuit-Break Behavior Policy bypass Action denied by policy engine Count toward threshold; log with full context LLM provider error HTTP 5xx from model API Immediately open; route to fallback model if configured Tool timeout Tool call exceeds timeout_ms Count toward threshold; cancel in-flight call Trust score degradation Agent trust score drops below configured floor Open; escalate to Ring 3 (untrusted) until score recovers Reasoning loop / deadlock Token or iteration count exceeds budget Open; trigger human review before resuming The reasoning loop breaker deserves attention. A microservice cannot get stuck reasoning. An AI agent absolutely can, and when it does, the failure is not an error code: it is an agent that keeps calling tools, consuming tokens, and generating audit events indefinitely. The circuit breaker detects this pattern from the iteration count and token budget and terminates the loop: # Reasoning loop detection configuration loop_detection_config = { "max_iterations": 15, # Hard stop after 15 reasoning steps "max_tokens_per_session": 50000, # Hard stop on token consumption "repetition_threshold": 0.85, # Stop if >85% of recent actions repeat prior ones "on_detection": "circuit_break_and_escalate", } The state machine behaves identically to what you know from Hystrix or Resilience4j. What changes is the definition of "failure." CLOSED (serving) | | failure_threshold crossed for any tracked fault v OPEN (rejecting -- agent action denied, fallback or human-in-loop fires) | | recovery_timeout expires v HALF_OPEN (probe -- limited requests allowed through) | |-- success_threshold met --> CLOSED |-- any failure --> OPEN (reset timeout) Chaos Engineering for Agents: Fault Injection for Autonomous Systems The only way to know if your agent system is resilient is to break it intentionally. Traditional chaos engineering targets infrastructure: kill a pod, inject network latency, saturate a disk. Agent chaos engineering targets the failure modes specific to autonomous reasoning systems. Agent SRE ships fault injection templates that cover the failure modes teams consistently underestimate until they hit production: from agent_sre.chaos.engine import ChaosExperiment, Fault, FaultType # Experiment 1: LLM provider degrades -- model returns valid responses but with # increased latency and occasional malformed outputs experiment = ChaosExperiment( name="llm-degradation-resilience", target_agent="analyst-agent-001", description="Test agent behavior under degraded LLM provider", faults=[ Fault.latency_injection(target="llm-provider", delay_ms=8000), Fault.error_injection(target="llm-provider", rate=0.05), ], duration_seconds=300, ) # Experiment 2: Trust score manipulation -- simulates an agent receiving # messages from a peer with a spoofed trust score trust_experiment = ChaosExperiment( name="trust-manipulation-resilience", target_agent="orchestrator-001", faults=[ Fault( fault_type=FaultType.TRUST_PERTURBATION, target="did:mesh:orchestrator-001", params={"spoofed_score": 950}, ), ], duration_seconds=120, ) # Experiment 3: Tool timeout cascade -- multiple tools time out simultaneously, # testing whether the agent abandons gracefully or enters a reasoning loop cascade_experiment = ChaosExperiment( name="tool-timeout-cascade", target_agent="analyst-agent-001", faults=[ Fault.timeout_injection(target="database.read", delay_ms=30000), Fault.timeout_injection(target="api.call", delay_ms=30000), ], duration_seconds=180, ) # Run the experiment experiment.start() # ... inject faults during agent execution ... resilience = experiment.calculate_resilience( baseline_success_rate=0.95, experiment_success_rate=0.87, recovery_time_ms=48000, ) experiment.complete(resilience=resilience) print(f"Resilience score: {resilience.overall}/100 -- {'PASSED' if resilience.passed else 'FAILED'}") Additional fault types built into the chaos engine cover: prompt injection attempts, privilege escalation, data exfiltration attempts, identity spoofing, deadlock injection, and contradictory instruction scenarios. Each maps to a FaultType enum value and can be composed into multi-fault experiments. Important: The chaos engine records that a fault was injected and triggers the governance response pipeline. Actual infrastructure-level fault injection (network partition, process kill) should be implemented using your existing chaos tooling (Chaos Mesh, Gremlin, Azure Chaos Studio, or similar). Agent SRE governs the agent's behavioral response to faults; it does not own infrastructure manipulation. These two layers are designed to compose. Each chaos experiment produces a structured resilience score via calculate_resilience(), which compares baseline and experiment success rates. A score of 90+ with passed=True means the agent maintained at least 90% of its baseline performance under fault conditions. Teams use this to set minimum resilience thresholds for production readiness. Replay Debugging: Reproduce Behavioral Failures Exactly Infrastructure incidents are reproducible because infrastructure is deterministic. AI agent incidents are hard to reproduce because agent behavior depends on model state, context window content, and the sequence of tool call results, none of which are preserved by default after a session ends. Agent SRE's replay engine records every agent session as a replayable artifact: the full trace at each step, every tool call with its inputs and outputs, every policy evaluation with its decision, and every trust score at the time of each inter-agent message. from agent_sre.replay.capture import TraceStore from agent_sre.replay.engine import ReplayEngine, ReplayMode # Traces are captured automatically when SRE tracing is active store = TraceStore( backend="azure_blob", retention_days=30, ) # When an incident occurs, replay the session exactly engine = ReplayEngine(store=store) # Full replay: re-run the session against the same recorded inputs # Uses recorded tool outputs -- no live tool calls -- so replay is deterministic result = await engine.replay( trace_id="trace_2026_05_a7f3b2", mode=ReplayMode.FULL, ) for step in result.steps: print(f"Step {step.index}: {step.action} -> {step.decision}") # Divergence analysis: replay with a policy change applied # Shows exactly which actions would have been blocked under the new policy diff_result = await engine.diff( trace_id="trace_2026_05_a7f3b2", policy_override="policies/stricter-v2.yaml", ) for diff in diff_result.diffs: if diff.description: print(f"Step {diff.span_name}: was {diff.original}, " f"would be {diff.replayed} under new policy") The divergence analysis is the feature teams use most. When a policy change is proposed, you replay recent production traces against the new policy to see how many actions would have been blocked, which sessions would have failed, and what the error budget impact would have been. Policy changes stop being guesswork. Progressive Delivery: Safely Rolling Out New Agent Capabilities When you ship a new service version, you do not send it to all traffic at once. You use canary deployments, feature flags, or traffic splitting. You watch the SLOs. If they degrade, you roll back. Agent SRE brings the same discipline to agent capability rollout. When you expand an agent's authorized scope, giving it write access it did not have, connecting it to a new tool, or raising its trust floor, you do not expand to the full fleet immediately. You expand progressively, with automated SLO gates controlling each stage. from agent_sre.delivery.rollout import ( AnalysisCriterion, CanaryRollout, RollbackCondition, RolloutStep, ) rollout = CanaryRollout( name="database-write-capability", steps=[ RolloutStep( name="canary", weight=0.05, # 5% of agents get the new capability duration_seconds=86400, # 24 hours analysis=[ AnalysisCriterion(metric="safety_sli", threshold=0.995), AnalysisCriterion(metric="performance_sli", threshold=0.90), AnalysisCriterion( metric="error_budget_consumed", threshold=0.10, comparator="lte", # canary can burn at most 10% ), ], ), RolloutStep( name="early-adopters", weight=0.25, # 25% traffic duration_seconds=172800, # 48 hours analysis=[ AnalysisCriterion(metric="safety_sli", threshold=0.990), AnalysisCriterion(metric="performance_sli", threshold=0.88), ], ), RolloutStep( name="general-availability", weight=1.0, # 100% traffic duration_seconds=604800, # 1 week of full observation analysis=[ AnalysisCriterion(metric="safety_sli", threshold=0.990), AnalysisCriterion(metric="performance_sli", threshold=0.85), ], ), ], rollback_conditions=[ RollbackCondition(metric="safety_sli", threshold=0.95, comparator="lte"), ], ) # Start the rollout -- SLO gates evaluate at each step rollout.start() # Advance to next step when analysis criteria pass if rollout.advance(): print(f"Advanced to step: {rollout.current_step.name}") print(f"Progress: {rollout.progress_percent:.0f}%") The SLO gate at each step is the same mechanism as a CI/CD quality gate, but measured on live production behavior rather than test results. An agent capability that degrades the safety SLI during canary does not promote to the next step. If a RollbackCondition fires, the rollout rolls back automatically. This is the mechanism that makes it operationally safe to expand agent autonomy: every expansion is measurable, every measurement gates the next expansion, and rollback is automatic. Health Checks and Backpressure Traditional health checks answer: is the service alive? For agents, alive is not enough. A healthy agent is one that is alive, operating within policy, consuming resources within budget, and maintaining a trust score above the Ring threshold it was assigned. # Agent health check covering multiple dimensions health = await agent_health_check( agent_id="analyst-agent-001", dimensions=[ "liveness", # Is the agent process running? "policy_compliance", # Is safety SLI above threshold? "trust_score", # Is trust score above Ring floor? "resource_budget", # Is token/API spend within limits? "tool_availability", # Are the tools the agent needs reachable? ], ) # health.status: "healthy" | "degraded" | "unhealthy" # health.dimensions: per-dimension pass/fail with values # health.recommended_action: "none" | "restrict" | "suspend" | "terminate" When health checks report degradation, backpressure controls engage before the circuit breaker opens. Backpressure is the earlier, softer response: accept fewer concurrent tasks, reject low-priority work, drain in-flight tasks gracefully before the situation escalates. # Backpressure configuration backpressure_config = { "backpressure_threshold": 0.80, # Engage when resource utilization > 80% "max_concurrent": 5, # Hard cap on simultaneous agent tasks "priority_shedding": True, # Drop low-priority tasks first "drain_timeout_seconds": 30, # Allow in-flight tasks to complete } The ordering matters: backpressure first, then circuit breaker, then suspension. Each stage is recoverable. Each stage preserves more agent state than the next. The SRE principle of graduated response applies to agents exactly as it applies to services. Observability: Governance Metrics Flow Into Your Existing Stack Agent SRE does not ask you to adopt a new observability platform. Governance metrics are exported through the same adapters your infrastructure monitoring already uses, including OpenTelemetry, Prometheus, Datadog, and others. from agent_sre.tracing.exporters import configure_exporters configure_exporters( backends=[ {"type": "prometheus", "endpoint": "http://prometheus:9090"}, {"type": "opentelemetry", "endpoint": "http://otel-collector:4317"}, ], include_metrics=[ "slo.safety_sli", # Per-agent safety compliance rate "slo.error_budget_remaining", # Error budget in percentage "slo.burn_rate", # Current burn rate vs sustainable "circuit_breaker.state", # CLOSED / OPEN / HALF_OPEN "circuit_breaker.failure_count", "trust_score.current", # Agent trust score (0-1000) "trust_score.ring", # Current execution ring "chaos.experiments_run", # Chaos experiment telemetry "health.status", # Aggregate health status "backpressure.load", # Current load vs threshold ], ) Key governance metrics available in your existing dashboards: Metric What It Tells You Alert Condition slo.safety_sli Fraction of agent actions within policy < 0.99 slo.burn_rate Rate at which error budget is consumed > 2.0 (warn), > 5.0 (page) slo.error_budget_remaining Budget left for the SLO window < 20% circuit_breaker.state Current breaker state per agent OPEN or HALF_OPEN trust_score.ring Execution ring (privilege level) Ring 3 (untrusted) health.status Aggregate health across all dimensions degraded or unhealthy If you are already running Grafana dashboards for your services, a governance dashboard for your agent fleet is a new data source and a new set of panels, not a new monitoring stack. The SRE Mental Model for Agents: Four New Concepts Everything in Agent SRE is built on the SRE mental model you already have, extended with four concepts that adapt traditional reliability thinking for autonomous systems: Traditional SRE Agent SRE Equivalent What Changes Latency SLI Safety SLI Correctness of *action*, not speed of *response* Error budget Autonomy budget Burns on policy violations, not just errors Circuit breaker Behavioral circuit breaker Opens on wrong *behavior*, not just failure codes Canary deployment Capability rollout Rolls out *scope*, not just code The governance insight is that error budgets work in both directions for agents. A service's error budget only decreases. An agent's autonomy is also a budget: it grows when the safety SLI is strong and shrinks when it degrades. The error budget mechanism becomes the operational mechanism for expanding and contracting agent autonomy in response to evidence, which is exactly what regulated industries and risk-averse enterprise teams need before they will trust an autonomous agent with consequential actions. Getting Started with Agent SRE pip install agent-sre A minimal Agent SRE integration requires three things: a safety SLO definition, a circuit breaker, and a health check. The progressive delivery and chaos engineering features layer on top when you are ready for them. from agent_sre import SLO, ErrorBudget from agent_sre.slo.indicators import TaskSuccessRate from agent_sre.cascade.circuit_breaker import CircuitBreakerConfig, CircuitBreaker # Step 1: Define your safety SLO slo = SLO( name="production-safety", indicators=[TaskSuccessRate(target=0.99, window="24h")], error_budget=ErrorBudget(total=0.01, burn_rate_alert=2.0, burn_rate_critical=5.0), ) # Step 2: Configure a circuit breaker breaker_config = CircuitBreakerConfig( failure_threshold=5, recovery_timeout_seconds=60, half_open_max_calls=3, ) breaker = CircuitBreaker(agent_id="my-agent", config=breaker_config) # Step 3: Wire into your existing agent loop async def governed_agent_loop(agent, task): # Check health first if not await agent_is_healthy(agent.id): return {"error": "agent suspended", "reason": "health check failed"} # Run within circuit breaker protection async with breaker: result = await agent.run(task) slo.record_event(good=result.policy_compliant) return result The quickstart in the repository walks through a complete setup with safety SLOs, circuit breakers, and a Prometheus dashboard export in under 50 lines. Why This Matters Most AI observability tools today focus on what you might call model quality: hallucination rate, latency, token cost, task completion. These are useful metrics. They are not SRE metrics. They do not answer whether the agent acted within its authorized scope, whether its behavioral error budget is burning at a dangerous rate, or whether it would survive the LLM provider going down. Agent SRE answers those questions using the operational vocabulary that SRE teams already understand: SLOs, error budgets, circuit breakers, chaos experiments, and health checks. The goal is not to replace your observability stack. It is to make agent governance visible inside it. The reliability of an autonomous agent is not a property of the model. It is a property of the governance infrastructure around it. Agent SRE is that infrastructure. Resources GitHub: github.com/microsoft/agent-governance-toolkit Install: pip install agent-sre Tutorials: 40+ tutorials including dedicated Agent SRE walkthroughs for SLO setup, chaos experiments, and progressive delivery Architecture reference: ARCHITECTURE.md OWASP compliance mapping: OWASP-COMPLIANCE.md -- Agent SRE addresses ASI-08 (Cascading Failures) directly through circuit breakers and SLO-based fault detection Part 1 -- Runtime governance: Policy engines, trust, and SRE overview Part 2 -- Shift-left governance: Catching violations before production Part 3 -- Post-hoc accountability: After the agent acts The Agent Governance Toolkit is an open-source project released under the MIT License. All features described in this post are available in the public repository. The `agent-sre` package is currently in public preview; APIs may change before general availability. Questions about Agent SRE in your environment? Open an issue at aka.ms/agent-governance-toolkit or start a discussion in the comments below.1.3KViews1like1Comment