monitoring
319 TopicsHybrid Cloud Architecture: What Should Enterprises Keep On-Premises?
Over the years, I have seen enterprise environments evolve from traditional infrastructure toward hybrid cloud architectures. One important architectural decision is determining which workloads should move to Azure and which should remain on-premises. In my view, this decision should consider: Application dependencies and compatibility. Security and regulatory requirements. Network connectivity and latency. Availability and disaster recovery. Operational complexity and total cost. There is no universal answer. The right architecture depends on the business requirements and the technical realities of each environment. For the Azure community: How do you approach workload placement when designing hybrid cloud environments? Do you start with application dependency mapping, security requirements, cost analysis, or another factor? I'd be interested in hearing your experiences and architectural approaches.11Views0likes0CommentsAzure SQL Hyperscale Looks Healthy, but Logins Are Failing: Troubleshooting Partial Availability
Can an Azure SQL database look healthy while your users can't log in? Yes. It happens when the health signals and your application are measuring different things. We see this question in support cases fairly often: "Availability looked fine, so why couldn't my application connect?" This post explains why the two can disagree, especially on Hyperscale, and how to collect the evidence that shows what really happened. A quick look at Hyperscale Hyperscale separates compute from storage. At a high level: Compute replicas run your queries. These are the primary, plus any high-availability (HA) and named replicas. Each one keeps a local cache of hot data. Page servers store the data and serve pages the compute replica doesn't have cached. The log service receives the transaction log and passes changes on to the other components. This design is what makes Hyperscale scale so well. It also means "the database" is several components working together, and they don't all fail together. The Hyperscale architecture overview covers this in more detail. "Available" isn't one thing These are four questions that sound similar but aren't: Signal What it really tells you Service or resource availability The database is online at the platform level Primary replica health The compute node serving your writes is working normally Login success rate New connections are actually completing Query latency Work is finishing in a reasonable time once connected Storage can be healthy while the compute replica is struggling. The database can be online while some logins fail. And a health check can succeed between two failed attempts. Healthy storage + degraded compute ≠ healthy application experience. A real-world pattern In a recent Hyperscale case, the customer saw intermittent login failures and slow reads from remote storage on the primary replica. The storage components themselves looked healthy. The database was never fully down, and some health checks kept succeeding while the application had trouble connecting. Customer impact ended after a failover moved the workload to a different, healthy replica. However, the exact underlying cause on the original replica wasn't confirmed. The failover fixed the symptoms, and that tells you the problem was tied to that specific replica. It doesn't tell you why. Recovering service and finding the root cause are separate results, and an RCA should make clear which of the two it reached. Why averages hide the problem Most dashboards show data averaged over 1 minute, 5 minutes or 1 hour. A short burst of failures disappears in those averages. Suppose a probe connects every 5 seconds, and 6 attempts fail in a 30-second burst: View Probes Failures Success rate The 5-minute window containing the burst 60 6 90.0% The full hour 720 6 99.2% Your users felt a real outage. The hourly chart looks almost perfect. Measure what your users experience Platform metrics are useful but run your own lightweight probe from where your application runs. Here's a simple Python example: import time, csv, datetime, pyodbc CONN = ("Driver={ODBC Driver 18 for SQL Server};" "Server=tcp:<server>.database.windows.net,1433;" "Database=<db>;Encrypt=yes;Authentication=ActiveDirectoryMsi;") REGION = "<app-region>" with open("sql_probe.csv", "a", newline="") as f: w = csv.writer(f) while True: ts = datetime.datetime.now(datetime.timezone.utc).isoformat() login_ms = query_ms = None ok, err = False, "" try: t0 = time.perf_counter() conn = pyodbc.connect(CONN, timeout=15) login_ms = round((time.perf_counter() - t0) * 1000) t1 = time.perf_counter() conn.cursor().execute("SELECT 1").fetchone() query_ms = round((time.perf_counter() - t1) * 1000) conn.close() ok = True except pyodbc.Error as e: err = str(e)[:200] w.writerow([ts, ok, login_ms, query_ms, err, REGION]) f.flush() time.sleep(5) Each row records: The UTC timestamp Whether the connection succeeded Login time Time for a simple query The SQL error, if any The region the probe ran from Keep the raw rows rather than only averages. If login time rises before failures begin, that's often the earliest warning you'll get. Lining up the evidence When something goes wrong, put these side by side in UTC: Application errors, with error numbers and connection IDs Your probe results Resource Health and Service Health events Database performance data, such as sys.dm_db_resource_stats and Query Store wait statistics. See Hyperscale performance diagnostics for Hyperscale-specific waits. Any failover, scale or deployment events If you open a support case, include: The exact UTC time windows Sample error messages, with error numbers Connection IDs Your probe data Which application hosts or regions were affected With that information, we can start investigating straight away instead of spending the first day collecting it. Build for partial failure Retry transient errors with a retry limit, exponential backoff and jitter. (See our previous post on maintenance and failover.) Set sensible connection and command timeouts, so a slow login doesn't hold up a thread indefinitely. Alert on probe failures and login time, not just on platform availability. Know how to recover. For example, knowing when a failover is appropriate, and who can request it, saves time during an incident. Summary "Is the database online?" is often too simple a question. Ask instead: Can my application connect, how long does that take, and how fast are queries once connected? Measure those directly, at a fine enough granularity, and short partial outages stop being invisible.Lessons Learned #542: Reviewing Historical Azure SQL Database Storage Growth
This week I worked on a service request where our customer needed to understand how an Azure SQL Database had grown over time. This information can be useful for capacity planning, cost analysis, and performance reviews. There are several possible approaches, depending on whether we need to review recent historical data that is still available in Azure Monitor, or whether we need to start collecting long-term historical data from now on. In this lesson learned, I would like to summarize some of the options available. 1. Reviewing recent historical data using Azure Monitor metrics The first point to clarify is how Azure Monitor metrics retention works. Most Azure platform metrics are retained for up to 93 days. However, a single Azure Monitor Metrics chart can query no more than 30 days of data at a time. This means that, if the data is still within the Azure Monitor retention window, we might need to review the metric in 30-day intervals. For Azure SQL Database storage usage, the metric commonly used is Data space used 2. Exporting metrics to Log Analytics for long-term analysis If the requirement is to perform long-term analysis, I would like to recommended option is to enable Diagnostic Settings on the Azure SQL Database and send the metrics to a Log Analytics workspace. Azure SQL Database diagnostic telemetry can be exported to different destinations, including: Log Analytics workspace Storage Account Event Hubs Using Log Analytics provides a very flexible way to query, aggregate, and visualize the data by using KQL. Once the metrics are available in Log Analytics, we can calculate the monthly database growth. For example: AzureMetrics | where ResourceProvider =~ "MICROSOFT.SQL" | where ResourceId == "/SUBSCRIPTIONS/your subscription/RESOURCEGROUPS/yourresourcegroup/PROVIDERS/MICROSOFT.SQL/SERVERS/yourserver/DATABASES/yourdatabase" | where MetricName == "storage" | summarize arg_max(TimeGenerated, Average) by Month = startofmonth(TimeGenerated) | project Month, DataSpaceUsedGB = round(Average / 1024 / 1024 / 1024, 2) | order by Month asc This query takes the last available value for each month and converts the metric from bytes to GB. Depending on the analysis requirements, the query can be customized. 3. Creating a custom database space usage history process If we need more control, or if we want to collect more granular database-level information, another option is to create a custom process that periodically captures the current database space usage into a table. This approach can be useful when we want to keep the information inside the database itself and avoid depending on external telemetry storage for this specific requirement. For example, the following table can be used to store daily or weekly snapshots: CREATE TABLE dbo.DatabaseSpaceUsageHistory ( SnapshotTimeUtc datetime2(3) NOT NULL DEFAULT SYSUTCDATETIME(), DatabaseName sysname NOT NULL, DataAllocatedMB decimal(19,2) NULL, DataUsedMB decimal(19,2) NULL, DataUnusedMB decimal(19,2) NULL, LogAllocatedMB decimal(19,2) NULL ); --Example collection query: INSERT INTO dbo.DatabaseSpaceUsageHistory ( DatabaseName, DataAllocatedMB, DataUsedMB, DataUnusedMB, LogAllocatedMB ) SELECT DB_NAME() AS DatabaseName, SUM(CASE WHEN type_desc = 'ROWS' THEN size END) * 8.0 / 1024 AS DataAllocatedMB, SUM(CASE WHEN type_desc = 'ROWS' THEN FILEPROPERTY(name, 'SpaceUsed') END) * 8.0 / 1024 AS DataUsedMB, ( SUM(CASE WHEN type_desc = 'ROWS' THEN size END) - SUM(CASE WHEN type_desc = 'ROWS' THEN FILEPROPERTY(name, 'SpaceUsed') END) ) * 8.0 / 1024 AS DataUnusedMB, SUM(CASE WHEN type_desc = 'LOG' THEN size END) * 8.0 / 1024 AS LogAllocatedMB FROM sys.database_files; This process can be executed daily, weekly, or monthly using the automation method that best fits the environment. This approach provides more control over the data collected, the retention period, and the frequency of collection.From Policy to Practice: Built-In CIS Benchmarks on Azure - Flexible, Hybrid-Ready
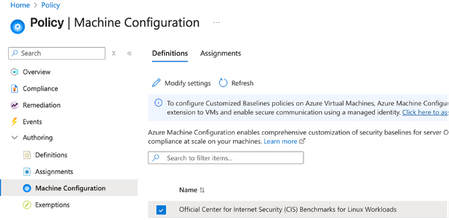
Security is more important than ever. The industry-standard for secure machine configuration is the Center for Internet Security (CIS) Benchmarks. These benchmarks provide consensus-based prescriptive guidance to help organizations harden diverse systems, reduce risk, and streamline compliance with major regulatory frameworks and industry standards like NIST, HIPAA, and PCI DSS. In our previous post, we outlined our plans to improve the Linux server compliance and hardening experience on Azure and shared a vision for integrating CIS Benchmarks. Today, that vision has turned into reality. We're now announcing the next phase of this work: Center for Internet Security (CIS) Benchmarks are now available on Azure for all Azure endorsed distros, at no additional cost to Azure and Azure Arc customers. With today's announcement, you get access to the CIS Benchmarks on Azure with full parity to what’s published by the Center for Internet Security (CIS). You can adjust parameters or define exceptions, tailoring security to your needs and applying consistent controls across cloud, hybrid, and on-premises environments - without having to implement every control manually. Thanks to this flexible architecture, you can truly manage compliance as code. How we achieve parity To ensure accuracy and trust, we rely on and ingest CIS machine-readable Benchmark content (OVAL/XCCDF files) as the source of truth. This guarantees that the controls and rules you apply in Azure match the official CIS specifications, reducing drift and ensuring compliance confidence. What’s new under the hood At the core of this update is kompli - a lightweight, open-source module developed by the Azure Core Linux team. It evaluates Linux systems directly against industry-standard benchmarks like CIS, supporting both audit and, in the future, auto-remediation. This enables accurate, scalable compliance checks across large Linux fleets. Here you can read more about kompli. Dynamic rule evaluation The new compliance engine supports simple fact-checking operations, evaluation of logic operations on them (e.g., anyOf, allOf) and Lua based scripting, which allows to express complex checks required by the CIS Critical Security Controls - all evaluated natively without external scripts. Scalable architecture for large fleets When the assignment is created, the Azure control plane instructs the machine to pull the latest Policy package via the Machine Configuration agent. kompli is integrated as a light-weight library to the package and called by Machine Configuration agent for evaluation – which happens every 15-30minutes. This ensures near real-time compliance state without overwhelming resources and enables consistent evaluation across thousands of VMs and Azure Arc-enabled servers. Future-ready for remediation and enforcement While the Public Preview starts with audit-only mode, the roadmap includes per-rule remediation and enforcement using technologies like eBPF for kernel-level controls. This will allow proactive prevention of configuration drift and runtime hardening at scale. Please reach out if you interested in auto-remediation or enforcement. Extensibility beyond CIS Benchmarks The architecture was designed to support other security and compliance standards as well and isn’t limited to CIS Benchmarks. The compliance engine is modular, and we plan to extend the platform with STIG and other relevant industry benchmarks. This positions Azure as a platform for a place where you can manage your compliance from a single control-plane without duplicating efforts elsewhere. Collaboration with the CIS This milestone reflects a close collaboration between Microsoft and the CIS to bring industry-standard security guidance into Azure as a built-in capability. Our shared goal is to make cloud-native compliance practical and consistent, while giving customers the flexibility to meet their unique requirements. We are committed to continuously supporting new Benchmark releases, expanding coverage with new distributions and easing adoption through built-in workflows, such as moving from your current Benchmark version to a new version while preserving your custom configurations. Certification and trust We can proudly announce that kompli has met all the requirements and is officially certified by the CIS for Benchmark assessment, so you can trust compliance results as authoritative. Minor benchmark updates will be applied automatically, while major version will be released separately. We will include workflows to help migrate customizations seamlessly across versions. Key Highlights Built-in CIS Benchmarks for Azure Endorsed Linux distributions Full parity with official CIS Benchmarks content and certified by the CIS for Benchmark Assessment Flexible configuration: adjust parameters, define exceptions, tune severity Hybrid support: enforce the same baseline across Azure, on-prem, and multi-cloud with Azure Arc Reporting format in CIS tooling style Supported use cases Certified CIS Benchmarks for all Azure Endorsed Distros - Audit only (L1/L2 server profiles) Hybrid / On-premises and other cloud machines with Azure Arc for the supported distros Compliance as Code (example via Github -> Azure OIDC auth and API integration) Compatible with GuestConfig workbook What’s next? Our next mission is to bring the previously announced auto-remediation capability into this experience, expand the distribution coverage and elevate our workflows even further. We’re focused on empowering you to resolve issues while honoring the unique operational complexity of your environments. Stay tuned! Get Started Documentation link for this capability Enable CIS Benchmarks in Machine Configuration and select the “Official Center for Internet Security (CIS) Benchmarks for Linux Workloads” then select the distributions for your assignment, and customize as needed. In case if you want any additional distribution supported or have any feedback for kompli – please open an Azure support case or a Github issue here Relevant Ignite 2025 session: Hybrid workload compliance from policy to practice on Azure Connect with us at Ignite Meet the Linux team and stop by the Linux on Azure booth to see these innovations in action: Session Type Session Code Session Name Date/Time (PST) Theatre THR 712 Hybrid workload compliance from policy to practice on Azure Tue, Nov 18/ 3:15 PM – 3:45 PM Breakout BRK 143 Optimizing performance, deployments, and security for Linux on Azure Thu, Nov 20/ 1:00 PM – 1:45 PM Breakout BRK 144 Build, modernize, and secure AKS workloads with Azure Linux Wed, Nov 19/ 1:30 PM – 2:15 PM Breakout BRK 104 From VMs and containers to AI apps with Azure Red Hat OpenShift Thu, Nov 20/ 8:30 AM – 9:15 AM Theatre THR 701 From Container to Node: Building Minimal-CVE Solutions with Azure Linux Wed, Nov 19/ 3:30 PM – 4:00 PM Lab Lab 505 Fast track your Linux and PostgreSQL migration with Azure Migrate Tue, Nov 18/ 4:30 PM – 5:45 PM PST Wed, Nov 19/ 3:45 PM – 5:00 PM PST Thu, Nov 20/ 9:00 AM – 10:15 AM PST1.9KViews0likes3CommentsHow to maintain and update Azure Function Connector deployed via WEBSITE_RUN_FROM_PACKAGE?
Background We recently completed a migration from the legacy Microsoft Sentinel Box connector to the newer Box Events (CCP) connector. During the migration we discovered that the legacy Box connector was implemented using: Azure Functions JWT authentication WEBSITE_RUN_FROM_PACKAGE The Function App is configured as: WEBSITE_RUN_FROM_PACKAGE=https://aka.ms/sentinel-BoxDataConnector-functionapp and the Azure Function therefore operates in read-only mode because it is running directly from the package referenced by that URL. The migration to the new Box Events (CCP) connector has been successful and is now ingesting data into BoxEventsV2_CL using Client Credentials Grant (CCG) authentication. What prompted the question While reviewing the legacy Azure Function deployment, we noticed that: The Box Solution GitHub repository has received updates over time. The Box Solution itself has been updated (currently v3.16 in our environment). Analytics, parsers, and connector components have evolved. The legacy Azure Function deployment still appears to be tied to the original package referenced by WEBSITE_RUN_FROM_PACKAGE. This raised a broader lifecycle and maintenance question: Questions 1. Is the package referenced by: https://aka.ms/sentinel-BoxDataConnector-functionapp still actively maintained and republished by Microsoft? 2. If updates are made to the Box Solution source code or supporting files in the GitHub repository, are those updates expected to flow automatically to existing Azure Function deployments that use WEBSITE_RUN_FROM_PACKAGE? 3. If updates do not automatically flow to existing deployments, what was the intended maintenance model for customers using the legacy Azure Function connector? For example, were customers expected to: Continue using the Microsoft-hosted package URL indefinitely? Periodically redeploy using updated templates? Download and self-maintain the Function App package? Modify the Function App to stop using WEBSITE_RUN_FROM_PACKAGE? 4. Prior to the introduction of the Box Events (CCP) connector, how were customers expected to apply updates, dependency changes, security fixes, and other improvements to existing Box Azure Function deployments? 5. Is migration to the Box Events (CCP) connector now considered the only supported path for customers wishing to remain current with Microsoft Sentinel Box integrations? Reason for asking The goal is not to troubleshoot the new CCP connector. Rather, we are trying to better understand the support and maintenance lifecycle of the legacy Azure Function-based Box connector and how Microsoft intended customers to remain current when deployments were originally made using a Microsoft-hosted WEBSITE_RUN_FROM_PACKAGE endpoint. Any clarification from the Box Solution maintainers or Microsoft Sentinel team would be appreciated. NB I came across this notice after following some links from the Box Solution listed in Azure. https://github.com/Azure/Azure-Sentinel/blob/master/Solutions/known_issues.md#known-issue-2--solution-re-deployment-or-update That seems to indicate that somehow we are meant to Redeploy the entire package when there is an update and then somehow copy / update all the Custom Analytics Rules and Automations. Is there no way to merge the new modules and updates without basically having to start over with a side-by-side deployment?209Views0likes1Comment
A streaming pipeline can be healthy even when the data isn't complete yet.
One thing worth separating in streaming systems is processing time from event time. A message can arrive late because of a disconnected device, a network delay or an upstream system that buffers events. If downstream aggregations assume every event arrives in chronological order, the resulting windows can be misleading. In event-stream processing, event-time windows and watermarks help define how long the system waits for late events before considering a window sufficiently complete. The exact behaviour depends on the processing engine and its configuration. A few questions come up when designing these pipelines: How late can events realistically arrive? What should happen to events that arrive after the allowed lateness? Does the business require corrected historical aggregates? How do you monitor event-time lag separately from processing latency? There is not one watermark setting that fits every workload. A short delay may reduce reporting latency but increase the number of late events that need separate handling. How do you choose the lateness threshold for Azure streaming workloads, especially when the business expects both low latency and accurate historical results?186Views0likes1CommentMANA out-of-tree (OOT) driver for Linux LTS kernels
The Microsoft Azure Network Adapter (MANA) driver is part of the upstream Linux kernel and provides networking support for Azure Accelerated Networking. Today, we’re announcing an out-of-tree (OOT) driver, so you can use MANA on supported Linux LTS kernels without upgrading your kernel. MANA support is developed upstream in the Linux kernel, and that remains our preferred long-term model. But not every customer can move to a newer kernel quickly. Many customers maintain one standardized Linux image across Azure and other hyperscalers , and adopting a newer kernel just for Azure can mean: Building and maintaining an additional OS image Re-running security and compliance validation Changing an established patching lifecycle Waiting for Linux distribution to backport newer MANA capabilities The OOT driver gives you another option: install MANA separately and keep the supported LTS kernel you already run. How it Works? The OOT package contains the identical upstream MANA driver source, plus a thin compatibility layer that lets it build against older, still-supported LTS kernels. It is not a separate MANA implementation. Rather than upgrading the kernel, you download the source and build the MANA kernel module against the headers of your running kernel. In short: keep your kernel, install the MANA driver. Supported LTS Kernels: Linux 5.15 Linux 6.1 Linux 6.6 Linux 6.12 Linux 6.18 When to Use this OOT-Driver? If your Linux distribution kernel's already provides the MANA capabilities you need, keep using the in-tree driver. Consider the OOT driver only when: You are running a supported LTS kernel The MANA capability/feature you need isn’t available in that kernel You can’t move to a newer kernel yet You maintain a common Linux image across multiple clouds Think of the OOT driver as a bridge to the upstream driver, not a replacement for it. Support Model: The OOT driver is intended for supported, non-EOL Linux LTS kernels. Custom or heavily modified kernels fall outside the normal support scope. For long-term deployments, we recommend using the MANA driver shipped by your Linux distribution whenever it offers the functionality you need. Installing a MANA driver that is not provided or supported by your Linux distribution may affect your vendor support coverage. Before replacing the distribution-provided driver, confirm the support implications with your Linux distribution provider. Looking Ahead: MANA continues to be developed in the open Linux ecosystem, and we’ll keep working with the Linux community and distribution partners to make its capabilities available through standard kernels. At the same time, we recognize that production kernel lifecycles don’t always line up with the upstream release cycle. The MANA OOT driver helps close that gap. GitHub Link : microsoft/linux-kernel-drivers: OOT Linux driver for Azure MANA NIC299Views2likes0CommentsOpen-Weight Models in Microsoft Foundry
Open-weight models can be valuable, but they are not automatically cheaper, safer, or more controllable. In Microsoft Foundry, the right decision depends on deployment path, licensing, data-processing location, quota, support posture, operational ownership, safety controls, and lifecycle risk. Do not treat all visible or downloadable models as open source; review the license first. Start with Serverless API when a supported Foundry Model meets the workload need. Use partner/community models only after Marketplace, Product Terms, and regional availability checks. Treat managed compute as a preview path for open-source or custom models, not a production default. Validate data processing location, quota, safety controls, support model, and lifecycle before committing. Why this matters Open-weight models are now part of serious enterprise AI planning. Teams consider them for cost control, technical flexibility, transparency, data residency, regulatory pressure, and the ability to build in-house capability. But the useful question is not whether an open-weight model is better than a proprietary managed model. The useful question is which deployment and operating model fits the workload. Use precise language Open source does not simply mean that model weights or code are visible. The Open Source Initiative defines open source through license requirements such as free redistribution, source code access, derived works, non-discrimination, and technology-neutral terms. Many AI models are better described as open-weight: weights may be available or inspectable, but the license can still restrict use, redistribution, or competition. Architecture should not start until license and use rights are reviewed. Four adoption paths Microsoft Foundry gives teams several ways to use models. Foundry Models sold by Azure are hosted and operated by Azure, billed through the Azure subscription, covered by Azure service-level agreements, and supported by Microsoft. This is usually the lowest-friction production path when a supported model meets the requirement. Foundry Models from partners and community expand provider choice, but some are Non-Microsoft Products under Product Terms and can require Azure Marketplace subscription, purchase permissions, billing-country availability, and publisher-term review. Serverless API is documented as the preferred and most capable Foundry deployment option for Foundry Models, including models sold by Azure and select partner/community models. Managed compute is different. It hosts open-source, partner, and custom models on dedicated GPU capacity that Foundry manages. Microsoft owns the GPU topology, runtime, container image, and security patching, while the customer chooses the model, deployment template, accelerator family, and scaling behavior. However, managed compute is public preview, has no SLA, and is not recommended for production workloads in current documentation. A fully self-managed path can offer maximum control, but the organization owns the serving runtime, patching, scaling, observability, safety controls, and cost optimization. Decision criteria Start with workload fit. If a managed model satisfies accuracy, latency, region, and governance needs, avoid extra operational burden. Consider open-weight options when you need specific model behavior, weight-level control, a dedicated GPU path, specialized deployment templates, or a license that supports your intended use. Then test the economics. Token billing, reserved throughput, and hourly accelerator billing behave differently. Open-weight is not automatically cheaper once runtime efficiency, scale-to-zero behavior, GPU quota, engineering time, monitoring, and incident response are included. Data residency and availability Deployment choice also affects data processing. Serverless deployment types can process inferencing data globally, within a Microsoft-specified data zone, or in a single region depending on the selected tier. Model availability varies by provider, deployment type, region, quota, subscription, and cloud. Foundry guidance says to verify project region, feature support, model availability, quota, dependent services, and sovereign cloud constraints before production rollout. Responsible AI and safety Responsible AI is not optional because a model is open-weight. Microsoft Foundry guidance frames production readiness around discovering risks, protecting model and runtime behavior, and governing with monitoring and compliance integrations. In managed compute public preview, built-in content filtering is not part of the managed compute data path; applications that need request or response filtering should call Azure AI Content Safety APIs directly. That limitation can be decisive for production. Lifecycle and procurement risk Model lifecycle matters. Foundry Models move through Preview, Generally Available, Legacy, Deprecated, and Retired stages. Preview models are not recommended for production, and some generally available models from selected providers follow a shorter lifecycle than the standard lifecycle. Procurement also matters. Marketplace plans can require a valid payment method, purchase permissions, review of terms, and country or region availability. A model being visible in a catalog is not the same as being approved for a regulated workload. Recommended operating pattern Use Foundry Models sold by Azure when they meet the requirement and you want the simplest production support model. Use partner/community models when capability or provider choice matters and Marketplace and Product Terms are acceptable. Use managed compute for experimentation, evaluation, controlled preview adoption, or cases where dedicated GPU hosting of open-source or custom models is worth the constraints. Use self-managed hosting only when the organization is prepared to operate the full platform. Decision guide Production checklist Is the model sold by Azure, from a partner/community provider, managed compute, or self-managed? Does the license permit the intended commercial, regulated, or redistribution use case? Is the model GA, Preview, Deprecated, or approaching retirement? Who supports the model and runtime, and what SLA or preview terms apply? Where is inferencing data processed for the selected deployment path? What quota, billing model, accelerator capacity, and fallback option apply? Which safety controls are built in, and which must the application add? What will the team do if the model becomes unavailable, too expensive, or operationally risky? Conclusion Open-weight models should be adopted because they fit a workload, not because they are popular. The strongest enterprise pattern is disciplined choice: verify legal rights, choose the lowest-burden deployment path that satisfies the requirement, validate data and region constraints, measure cost with real traffic, and add safety and monitoring before production use.384Views0likes0CommentsAnnouncing the Open-Source Release of ML Video Codec (MLVC)
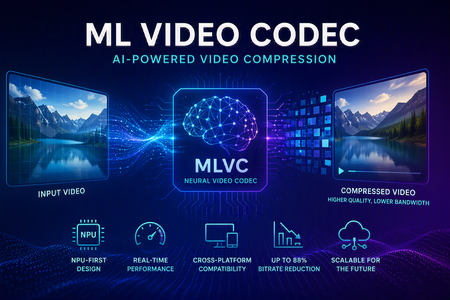
Video codecs compress video for transmission or storage, reducing bandwidth and storage requirements. MLVC is a modern machine-learning-based codec that uses substantially less bandwidth than conventional codecs, improving streaming and video-call quality—especially on constrained or unreliable networks—while lowering delivery and storage costs. MLVC is the product iteration of DCVC (Deep Contextual Video Compression) family of NVC (Neural Video Codec), open sourced by Microsoft Research since 2021, with improved compression efficiency, real-time performance on commodity Neural Processing Units (NPUs), and cross-platform support. We recently published this work in the paper MLVC: Multi-platform Learned Video Codec for Real-World Deployment. We are releasing the source code because we believe the next generation of video coding will be built openly, and we want the broader community — researchers, video codec engineers, platform vendors, product teams, as well as general developer community — to build it with us. Why MLVC Traditional video codecs (e.g., H.264/AVC, H.265/HEVC) have served the industry for a long time, but each generation requires enormous engineering effort for incremental gains and needs dedicated hardware which takes years to become commonly available. MLVC replaces conventional primitives — motion estimation, transforms, entropy modeling — with end-to-end learned neural compression, trained directly against rate-distortion objectives, and run on general-purpose NPU devices. The table below compares MLVC to popular video codecs, showing its lower bitrate and resulting savings in bandwidth and storage. Resolution vs H.264 vs H.265 360p 87.8% 75.5% 540p 82.7% 65.4% For example, for 360p video at 30 fps, where H.264 requires 1 Mbps, MLVC requires roughly 122 kbps for equivalent quality — about one-eight the bitrate under real-time conditions. The inference compute was kept approximately equal for the 360p and 540p resolutions. These results are based on a P.910 subjective test and are based on the Video Conferencing Dataset (VCD) dataset that we developed and also recently released as an open-source project. The following video demo illustrates the extent of quality enhancement achieved by MLVC relative to H.265/HEVC at the same bitrate of 200kbps (please watch by opening in a new window for better demonstration) \ Beyond video compression efficiency, MLVC also offers: NPU-first design. MLVC is built to run almost entirely on the AI accelerators already shipping in modern devices — Apple Neural Engine, Qualcomm and Intel NPUs — at no more than 50% NPU utilization, leaving NPU headroom for the rest of the system. Real-time execution at the targeted operating points. Demonstrated 540p at 30 fps on Apple, Intel, and Qualcomm hardware. A scaling-law trajectory. Empirically, MLVC's coding efficiency improves with increased model capacity and additional training compute. Content-adaptive behavior out of the box, without hand-tuned Rate Distortion Optimization heuristics. Already running in Microsoft Teams MLVC is more than just a research concept for Microsoft. We are currently rolling it out in Microsoft Teams, where it is being validated on real peer-to-peer video calls with active telemetry and A/B testing. The integration runs alongside fallback to conventional video codecs for hardware or reliability constraints — the kind of mixed-environment deployment that real products need. The scaling and reliability insights from this rollout are shaping the codec and its roadmap. We welcome your contributions We can not cover every use case, every device class, or every content domain by ourselves. That is why we are open sourcing MLVC. If you work on: Streaming, Video On Demand (VOD), or live broadcast Real-time communication and conferencing Cloud gaming or remote rendering Surveillance, drones, or robotics Mobile capture, Augmented Reality (AR) / Virtual Reality (VR), or volumetric video Codec hardware, NPUs, or inference runtimes We would love your help. Contributions of all kinds are welcome, including model improvements, training recipes, new platform ports and conversion targets, runtime backends, domain-specific fine-tunes, evaluation tooling, bug reports, and feedback on what is missing for your scenario. We particularly welcome platform ports that expand NPU coverage and efficiency improvements that push the rate-distortion frontier. What's in the release The MLVC repository is available at https://github.com/microsoft/mlvc and shared under the MIT License. It includes: MLVC model source code of the full network architecture. Trained model weights ready to run. Training scripts used to produce shipping models. Training data collection documentation to help reproduce and improve MLVC. Platform conversion scripts to target different NPUs and runtimes. Issues and pull requests will be open from day one. A follow-up release will add a C++ codec library, simplifying integration into real-world applications. Where we're heading Our long-term goal with MLVC is to create an open, learned video codec that meets or exceeds the coding efficiency of the best conventional codecs across the full range of video content, runs efficiently on the AI hardware already shipping in client and cloud devices, scales with compute the way modern ML systems do, and evolves in the open at the pace of the ML community rather than the pace of standardization cycles. In the near term that means stabilizing 540p real-time performance, expanding hardware coverage, and improving loss resilience. In the medium term: higher resolution, e.g., 1080p, and broader streaming scenarios. In the long term: an open video codec ecosystem that meaningfully replaces legacy stacks where it makes sense to. We can't create the future of MLVC alone. We're glad you're here, and we are looking forward to building the next-generation video codec with you. Who are we MLVC is brought to you by the following awesome folks working on the project at Microsoft: Ross Cutler, Ando Saabas, Tanel Pärnamaa, Ardi Loot, Haiyan Xie, Lauri Ehrenpreis, Andrei Znobishchev, Martin Lumiste, Evgenii Indenbom, Yan Lu, Bin Li, Jiahao Li, Naba Kumar, Babak Naderi, Juhee Cho, Badal Yadav, Jinxin Zhou, Tianyu Ding, Patrick Gregory. — The MLVC Team, Microsoft17KViews0likes5CommentsBuild a Tenant-Wide Microsoft Foundry Model Operations Dashboard
As AI projects move from pilots to production, model deployments often spread across subscriptions, regions, and application teams. A practical operations dashboard gives platform, engineering, governance, and finance teams one shared view of what is deployed, how it is used, what it costs, and where quota or capacity risk is forming. The operating problem Microsoft Foundry brings agents, models, tools, monitoring, tracing, evaluations, RBAC, networking, and policy controls under a unified platform surface. That is a strong foundation, but enterprise operations still need a view that cuts across the way Azure is usually organized: multiple subscriptions, resource groups, regions, business units, and application teams. The goal is not to replace product dashboards. The goal is to add a management-group or tenant-wide operating layer that answers simple but urgent questions: Which models are deployed? Which teams own them? Which deployments use Standard, priority, batch, or provisioned throughput? Where are token usage and PTU utilization rising? Which subscriptions are approaching quota pressure? Which costs should be allocated to which product or environment? Design principle: keep the dashboard about deployment and operations metadata. Do not collect prompts, completions, customer data, or other application payloads unless a separate privacy, security, and compliance design explicitly requires it. A practical reference architecture Use three data planes. First, build the inventory plane with Azure Resource Graph, because Resource Graph is designed for efficient, large-scale querying across subscriptions and tenants. Combine account-level resource data with deployment-level data from the Azure AI Services deployments API, which lists deployments associated with a Cognitive Services account. Normalize subscription, resource group, region, account, deployment name, model name, model version, deployment type, SKU or capacity, tags, owner, environment, and business unit. Build the telemetry plane with Azure Monitor. Public Azure OpenAI monitoring guidance describes dashboards for HTTP requests, token-based usage, PTU utilization, and fine-tuning. Azure Monitor supported metrics and resource log references provide the authoritative place to check what is available for each resource type and how exportability works. For exploratory operations views, Azure Workbooks are a good fit because they combine logs, metrics, parameters, Azure Resource Graph, Azure Resource Manager, JSON, and other data sources in one interactive report. Build the finance plane with Cost Management APIs or exports. Cost Management automation guidance supports retrieving and managing cost data, including for larger datasets that need offline analysis. The Cost Management Query API supports usage queries at scopes such as subscription, resource group, billing account, management group, billing profile, and invoice section, subject to permissions. Power BI can be useful for leadership reporting, but the Cost Management connector has agreement constraints; direct connector support is documented for Enterprise Agreement and direct Microsoft Customer Agreement customers, while unsupported agreements should use exports. Separate inventory, usage, cost, and quota Do not treat every signal as the same kind of data. Inventory is mostly current-state metadata. Usage is time-series behavior. Cost is billing-scope data that may lag and must be joined carefully by resource identity, meter, and tags. Quota is a capacity-control signal, not a spend signal. Azure OpenAI quota is not enforced at tenant level; Microsoft Learn states that the highest quota restriction is scoped at the Azure subscription level. That means an executive dashboard can summarize quota posture broadly, but engineering views should still preserve subscription, model, region, and deployment-type detail. Provisioned throughput deserves a dedicated view. Microsoft documents PTU as dedicated model processing capacity for predictable throughput and latency, billed per PTU per hour or through reservations. That makes PTU utilization, idle capacity, traffic predictability, and latency requirement visible design inputs rather than after-the-fact finance questions. Dashboard views that matter Start with a few durable views rather than a large reporting program. The most useful first version usually includes: Executive summary: deployment count, model families, regions, monthly cost trend, and quota risk. Inventory: deployments by subscription, resource group, region, model, version, deployment type, owner, and environment. Operations: request volume, token trends, errors, latency indicators, and PTU utilization where available. Cost allocation: spend by owning team, application, environment, and deployment type. Governance hygiene: missing tags, ownerless deployments, old model versions, and regional concentration. Decision guidance Choose the reporting surface by audience. Platform engineers usually need Workbooks because they support operational drill-down and can combine Azure Monitor and Resource Graph. Finance teams often need Power BI because it supports broader cost modeling and distribution. Application owners need a small scorecard: their deployments, their usage, their costs, their quota posture, and their next required action. Production considerations and limitations Require tags before reporting on ownership. Dashboards cannot create accountability if resources do not carry owner, application, environment, and cost-center metadata. Use least-privilege access. Cost, inventory, and telemetry sources may require different permissions and scopes. Check portal-version language. Some public monitoring guidance is explicitly marked for the Foundry classic portal, so avoid assuming identical behavior in every new portal experience. Verify regional availability. Model availability varies by region, and deployment lifecycle settings such as automatic model updates should be reviewed before making standardization claims. Respect metric export limits. Azure Monitor notes that some metrics have export constraints, especially around multidimensional metrics and diagnostic settings. Implementation checklist Define the dashboard audience and the decisions it must support. Inventory Foundry and Azure OpenAI resources across subscriptions with Azure Resource Graph. List deployments per account and normalize deployment metadata. Route or query Azure Monitor metrics and logs needed for usage and PTU views. Add Cost Management queries or exports at the correct billing scope. Join by resource ID and tags; flag missing ownership metadata. Publish an Azure Workbook for operations and a Power BI model only where agreement support and permissions fit. Review model versions, quota posture, and PTU utilization on a fixed cadence. Conclusion A tenant-wide model operations dashboard is a practical bridge between AI experimentation and AI platform management. It does not need to be complex on day one. Start with inventory, usage, cost, quota, and ownership. Keep application content out of scope. Preserve subscription-level quota detail. Then evolve the dashboard into a repeatable operating rhythm for model lifecycle, cost control, capacity planning, and governance.391Views0likes0Comments