microsoft foundry
15 TopicsStop Drawing Architecture Diagrams Manually: Meet the Open-Source AI Architecture Review Agents
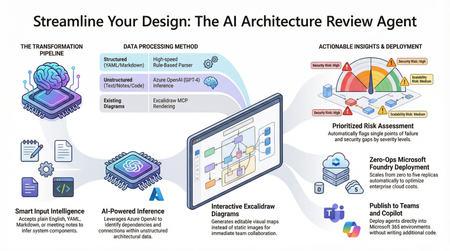
Designing and documenting software architecture is often a battle against static diagrams that become outdated the moment they are drawn. The Architecture Review Agent changes that by turning your design process into a dynamic, AI-powered workflow. In this post, we explore how to leverage Microsoft Foundry Hosted Agents, Azure OpenAI, and Excalidraw to build an open-source tool that instantly converts messy text descriptions, YAML, or README files into editable architecture diagrams. Beyond just drawing boxes, the agent acts as a technical co-pilot, delivering prioritized risk assessments, highlighting single points of failure, and mapping component dependencies. Discover how to eliminate manual diagramming, catch security flaws early, and deploy your own enterprise-grade agent with zero infrastructure overhead.18KViews7likes5CommentsCI/CD for AI Agents on Microsoft Foundry
Introduction Building an AI agent is the straightforward part. Shipping it reliably to production with version control, evaluation-driven quality gates, multi-environment promotion, and enterprise governance is where most teams run into friction. Microsoft Foundry changes this. It is Microsoft's AI app and agent factory: a fully managed platform for building, deploying, and governing AI agents at scale. It provides a first-class agent runtime with built-in lifecycle management, making it possible to apply the same CI/CD rigour you already use for application software to AI agents — regardless of whether you are building containerised hosted agents or declarative prompt-based agents. This post walks through a complete, production-ready reference architecture for doing exactly that. You will find the GitHub Actions workflow, the Azure DevOps pipeline YAML, and the architecture diagram linked throughout. Reference implementation repository: foundry-agents-lifecycle and CI/CD for AI Agents on Microsoft Foundry Why Agent CI/CD Is Different Traditional software pipelines gate releases on test pass/fail. Agent pipelines require an additional, critical layer: evaluation-driven quality gates. Before any agent version can be promoted to the next environment, it must pass three categories of evaluation: Quality — answer correctness, task completion rate, hallucination rate Safety — grounded responses, policy compliance, tool usage validation Performance — token usage per query, p95 response latency A second key difference is the deployment unit. You are not deploying a binary or a container tag in isolation. You are deploying an agent version — an immutable artefact that bundles the model selection, system instructions, tool definitions, and configuration together. This is what enables deterministic promotion and full auditability across environments. "Agents follow a standard CI/CD pattern, but with a critical shift: promotion happens at the agent version level, and release gates are driven by evaluation outcomes, not just test results." Reference Architecture Figure 1: End-to-end CI/CD reference architecture for hosted and prompt-based agents on Microsoft Foundry. The architecture has five logical layers, flowing from developer commit to production monitoring: Layer 1 — Developer Layer The developer layer is a standard source-controlled repository in GitHub or Azure DevOps. It contains: Agent code written in Python or .NET agent.yaml or prompt definition files for prompt-based agents Tool configurations: MCP servers, REST API connectors, or other integrations Infrastructure as Code: Bicep or ARM templates for provisioning the Foundry project and dependencies Layer 2 — CI Pipeline (Build · Validate · Evaluate) Every push or pull request triggers the CI pipeline. It performs five steps: Docker build — for hosted agents, build and tag the container image Static checks — lint with ruff , security scan with bandit , agent YAML schema validation Unit and tool tests — pytest suites covering agent logic and tool integrations Evaluation gate — run evaluation datasets; fail the pipeline if thresholds are breached Image push — push the validated container to Azure Container Registry (ACR) Prompt-based agents skip the Docker build step. Instead, the YAML definition and prompt bundle are validated against schema and evaluated against golden datasets. Layer 3 — CD Pipeline (Multi-stage Promotion) A single agent version is promoted through three Foundry project environments: Stage Environment Activities Gate Stage 1 Dev Foundry Project Deploy vNext version, smoke tests, developer evals Eval quality thresholds Stage 2 Test / QA Foundry Project Scenario tests, HITL validation, safety evaluation Eval gates + human approval Stage 3 Production Foundry Project Promote version, enable endpoint, post-deploy smoke test Required reviewer approval Rollback is straightforward: switch the active version pointer back to the previous agent version. No re-deployment is needed. Layer 4 — Microsoft Foundry Agent Service The Foundry Agent Service runtime provides: Hosted agent runtime — managed container execution supporting Agent Framework, LangGraph, Semantic Kernel, or custom code Prompt-based agent runtime — declarative agent definitions, no container required Built-in lifecycle operations — version, start, stop, rollback Entra Agent Identity — each deployed version receives a dedicated Microsoft Entra managed identity RBAC and policy enforcement — Azure role-based access controls per project Observability — distributed traces, structured logs, and evaluation signals Layer 5 — Monitoring, Governance, and Control Plane Foundry control plane: agent registry, environment configuration, version history OpenTelemetry forwarded to Azure Monitor and Application Insights Continuous evaluation pipelines for ongoing quality, grounding, and safety monitoring Azure Policy and RBAC enforcement at the platform level Environment Topology There are two topology options. We recommend Option A for all production workloads: Option Structure Best for Trade-off A — Recommended Dev Project → Test Project → Prod Project (separate Foundry projects) Enterprise workloads Full isolation, clean RBAC boundaries, easier governance B — Lightweight Single Foundry project with agent version tags (dev/test/prod) Small teams, prototyping Simpler setup, but weaker environment separation Separate projects mean separate RBAC policies, separate connection strings, and separate evaluation signals. A developer service principal has access only to the Dev project; the CI/CD identity has restricted access to promote to Test and Production. Evaluation Gates — The Core Difference Evaluation gates transform a standard software pipeline into an AI-safe deployment pipeline. They run at two points: pre-merge (CI) and pre-promotion (CD). Defining the Gates Category Metric CI threshold Prod threshold Quality Hallucination rate < 5% < 3% Quality Task completion rate > 90% > 95% Safety Grounded response rate > 95% > 98% Safety Policy violations 0 0 Performance p95 latency < 4 000 ms < 3 000 ms Cost Token usage per query Track only Alert on > 20% regression Gate Enforcement (Python) import json import sys def check_gates(results_path: str) -> None: with open(results_path) as f: results = json.load(f) failures = [] if results["hallucination_rate"] > 0.05: failures.append(f"Hallucination rate {results['hallucination_rate']:.1%} exceeds 5% threshold") if results["task_completion_rate"] < 0.90: failures.append(f"Task completion {results['task_completion_rate']:.1%} below 90% threshold") if results["latency_p95_ms"] > 4000: failures.append(f"p95 latency {results['latency_p95_ms']}ms exceeds 4000ms threshold") if results.get("policy_violations", 0) > 0: failures.append(f"Policy violations detected: {results['policy_violations']}") if failures: for f in failures: print(f"GATE FAILED: {f}", file=sys.stderr) sys.exit(1) print("All evaluation gates passed — proceeding to deployment") if __name__ == "__main__": check_gates(sys.argv[1]) Hosted vs Prompt-Based Agents — Pipeline Differences Capability Hosted Agents Prompt-Based Agents Deployment unit Container image + agent definition YAML / prompt configuration bundle Build step required Yes — Docker build + ACR push No — YAML validation only Supported frameworks Agent Framework, LangGraph, Semantic Kernel, custom Foundry declarative runtime Promotion artefact Versioned agent with container image reference Versioned prompt/config bundle CI focus Code quality, tool tests, evaluation Prompt schema validation, evaluation Rollback mechanism Switch active agent version Switch active agent version Runtime management Foundry manages container lifecycle Foundry manages declarative runtime CI Pipeline Walkthrough The following steps are representative of the full GitHub Actions workflow available in github-actions-pipeline.yml alongside this post. Hosted Agent CI # 1. Static checks ruff check . bandit -r src/ -ll python scripts/validate_agent_config.py --config agent.yaml # 2. Tests pytest tests/unit/ -v --tb=short pytest tests/tools/ -v --tb=short # 3. Evaluation gate python scripts/run_evaluations.py \ --dataset eval/datasets/golden_set.jsonl \ --output eval/results/results.json python scripts/check_eval_gates.py \ --results eval/results/results.json \ --max-hallucination 0.05 \ --min-task-completion 0.90 \ --max-latency-p95 4000 # 4. Push container image az acr build \ --registry myregistry.azurecr.io \ --image "myagent:$SHA" \ --file Dockerfile . Prompt-Based Agent CI # Validate YAML / prompt definitions python scripts/validate_agent_config.py --config agent.yaml # Evaluation against golden dataset python scripts/run_evaluations.py \ --dataset eval/datasets/golden_set.jsonl \ --output eval/results/results.json python scripts/check_eval_gates.py \ --results eval/results/results.json CD Pipeline Walkthrough Stage 1 — Dev Deployment python scripts/deploy_agent.py \ --env dev \ --image "myregistry.azurecr.io/myagent:$SHA" \ --foundry-endpoint $FOUNDRY_ENDPOINT_DEV \ --agent-config agent.yaml # Returns the new agent version ID, stored for promotion AGENT_VERSION=$(python scripts/get_active_version.py --env dev) Stage 2 — Promote to Test (after approval gate) python scripts/promote_agent.py \ --from-env dev \ --to-env test \ --agent-version $AGENT_VERSION \ --foundry-endpoint $FOUNDRY_ENDPOINT_TEST # Run scenario tests and safety evaluation python scripts/run_evaluations.py \ --dataset eval/datasets/scenario_set.jsonl \ --output eval/results/test-results.json python scripts/check_eval_gates.py \ --results eval/results/test-results.json \ --max-hallucination 0.03 \ --min-task-completion 0.95 Stage 3 — Promote to Production (after required reviewer approval) python scripts/promote_agent.py \ --from-env test \ --to-env prod \ --agent-version $AGENT_VERSION \ --foundry-endpoint $FOUNDRY_ENDPOINT_PROD # Enable the production endpoint python scripts/enable_agent_endpoint.py \ --agent-version $AGENT_VERSION \ --foundry-endpoint $FOUNDRY_ENDPOINT_PROD Rollback # Switch the active version to the previous known-good version python scripts/promote_agent.py \ --from-env prod \ --to-env prod \ --agent-version $PREVIOUS_AGENT_VERSION \ --foundry-endpoint $FOUNDRY_ENDPOINT_PROD # OR delete the failing version python scripts/delete_agent_version.py \ --agent-version $AGENT_VERSION \ --foundry-endpoint $FOUNDRY_ENDPOINT_PROD Deployment Using the Azure AI Projects SDK The azure-ai-projects SDK provides programmatic control over the full agent lifecycle. This is the recommended approach for CI/CD scripts where you need deterministic, scriptable deployment. from azure.identity import DefaultAzureCredential from azure.ai.projects import AIProjectClient # Connect to the Foundry project client = AIProjectClient( endpoint=FOUNDRY_PROJECT_ENDPOINT, credential=DefaultAzureCredential() ) # List existing agents (useful for idempotent deploy scripts) for agent in client.agents.list(): print(f"Agent: {agent.name} version: {agent.id}") # Create a new agent version (hosted agent) agent = client.agents.create_agent( model="gpt-4o", name="my-enterprise-agent", instructions="You are a helpful assistant ...", tools=[...], # tool definitions metadata={"version": GIT_SHA, "environment": "dev"} ) print(f"Created agent version: {agent.id}") For hosted agents, the SDK call also references the container image pushed to ACR. Refer to the Deploy a hosted agent — Microsoft Foundry documentation for the full SDK flow including container image registration and version polling. Reference Implementation Stack Concern Technology Source control and pipelines GitHub Actions or Azure DevOps Pipelines Infrastructure and agent deployment Azure Developer CLI ( azd up ) Programmatic agent lifecycle azure-ai-projects Python SDK Agent evaluation azure-ai-evaluation Python SDK Agent runtime Microsoft Foundry Agent Service Container registry Azure Container Registry (hosted agents only) Observability OpenTelemetry, Azure Monitor, Application Insights Identity and access Microsoft Entra (Agent ID, OIDC workload identity federation) Governance Azure Policy, RBAC, Foundry control plane Governance and Responsible AI Shipping AI agents at enterprise scale requires governance beyond what a traditional CI/CD pipeline provides. Microsoft Foundry addresses this at the platform level: RBAC per environment — each Foundry project has independent access controls. Developers deploy to Dev; only CI/CD service principals (with audited OIDC tokens) can promote to Test and Production. Agent registry and audit trail — the Foundry control plane records which agent version is active in each environment, who deployed it, and when. This satisfies enterprise audit requirements without additional tooling. Content safety and policy enforcement — Azure Policy governs model access, data handling, and content safety rules at the infrastructure level, not just at the application code level. Policy violations block deployment automatically. Entra Agent Identity — each deployed agent version receives a dedicated, short-lived managed identity. Agents authenticate to downstream services using least-privilege credentials scoped to that specific deployment. Continuous evaluation in production — evaluation pipelines run on sampled production traffic, alerting when quality, safety, or cost metrics drift from their baseline. A key trade-off to be transparent about: evaluation datasets must be maintained and updated as the agent's tasks evolve. Stale datasets produce misleading pass/fail signals. Treat your golden evaluation set as a first-class engineering artefact alongside the agent code itself. Pipeline Files Two pipeline files accompany this reference architecture. Both implement the same four-stage pipeline (CI Build, CI Evaluate, CD Dev, CD Test, CD Production) with environment-appropriate approval gates. github-actions-pipeline.yml — GitHub Actions workflow. Uses GitHub Environments for approval gates and OIDC Workload Identity Federation for passwordless Azure authentication. No stored Azure credentials required. azure-devops-pipeline.yml — Azure DevOps multi-stage YAML pipeline. Uses ADO Environments with required approvers and variable groups per environment. Both pipelines share these security practices: OIDC / Workload Identity Federation — no long-lived Azure credentials stored in pipeline secrets Per-environment variable groups, each with scoped connection strings and endpoints Evaluation quality gates enforced before every promotion step Mandatory human approval before production deployment Summary The full pipeline in one view: Developer commit | CI Pipeline ├── Docker build (hosted agents) / YAML validation (prompt agents) ├── Static checks + unit tests + tool tests └── Evaluation gate ← quality · safety · performance | Agent Version created ← immutable, versioned artefact | CD Pipeline ├── Deploy to Dev → smoke tests + eval gate ├── Promote to Test → scenario tests + HITL + approval gate └── Promote to Prod → enable endpoint + monitoring | Microsoft Foundry Agent Service └── Versioned runtime · Entra identity · RBAC · Observability | Control Plane └── Agent registry · Governance · Continuous evaluation Microsoft Foundry provides the platform primitives — versioned agent deployments, multi-environment Foundry projects, built-in lifecycle management, and an enterprise observability stack — needed to operate AI agents with the same confidence as any production software system. The key takeaway: treat the agent version as your deployment artefact, and evaluation outcomes as your release gate. The rest follows familiar CI/CD patterns you already know and trust. Next Steps Clone the CI/CD Repo at leestott/foundry-cicd Clone the reference demo: foundry-agents-lifecycle on GitHub Set up your environment: Set up your environment for Foundry Agent Service Deploy your first hosted agent: Quickstart: Deploy your first hosted agent Understand hosted agent concepts: Foundry Hosted Agents concepts Automate deployments in CI/CD: Automate deployment of Microsoft Foundry agents Manage agent versions: Manage hosted agents — Microsoft Foundry Deploy via SDK: Deploy a hosted agent — Microsoft Foundry SDK and endpoint reference: Microsoft Foundry SDK and Endpoints reference Azure AI Projects SDK: azure-ai-projects Python SDK Azure Developer CLI: Azure Developer CLI (azd) overview Microsoft Foundry documentation hub: Microsoft Foundry on Microsoft Learn15KViews8likes0CommentsHow to Set Up Claude Code with Microsoft Foundry Models on macOS
Introduction Building with AI isn't just about picking a smart model. It is about where that model lives. I chose to route my Claude Code setup through Microsoft Foundry because I needed more than just a raw API. I wanted the reliability, compliance, and structured management that comes with Microsoft's ecosystem. When you are moving from a prototype to something real, having that level of infrastructure backing your calls makes a significant difference. The challenge is that Foundry is designed for enterprise cloud environments, while my daily development work happens locally on a MacBook. Getting the two to communicate seamlessly involved navigating a maze of shell configurations and environment variables that weren't immediately obvious. I wrote this guide to document the exact steps for bridging that gap. Here is how you can set up Claude Code to run locally on macOS while leveraging the stability of models deployed on Microsoft Foundry. Requirements Before we open the terminal, let's make sure you have the necessary accounts and environments ready. Since we are bridging a local CLI with an enterprise cloud setup, having these credentials handy now will save you time later. Azure Subscription with Microsoft Foundry Setup - This is the most critical piece. You need an active Azure subscription where the Microsoft Foundry environment is initialized. Ensure that you have deployed the Claude model you intend to use and that the deployment status is active. You will need the specific endpoint URL and the associated API keys from this deployment to configure the connection. An Anthropic User Account - Even though the compute is happening on Azure, the interface requires an Anthropic account. You will need this to authenticate your session and manage your user profile settings within the Claude Code ecosystem. Claude Code Client on macOS - We will be running the commands locally, so you need the Claude Code CLI installed on your MacBook. Step 1: Install Claude Code on macOS The recommended installation method is via Homebrew or Curl, which sets it up for terminal access ("OS level"). Option A: Homebrew (Recommended) brew install --cask claude-code Option B: Curl curl -fsSL https://claude.ai/install.sh | bash Verify Installation: Run claude --version. Step 2: Set Up Microsoft Foundry to deploy Claude model Navigate to your Microsoft Foundry portal, and find the Claude model catalog, and deploy the selected Claude model. [Microsoft Foundry > My Assets > Models + endpoints > + Deploy Model > Deploy Base model > Search for "Claude"] In your Model Deployment dashboard, go to the deployed Claude Models and get the "Endpoints and keys". Store it somewhere safe, because we will need them to configure Claude Code later on. Configure Environment Variables in MacOS terminal: Now we need to tell your local Claude Code client to route requests through Microsoft Foundry instead of the default Anthropic endpoints. This is handled by setting specific environment variables that act as a bridge between your local machine and your Azure resources. You could run these commands manually every time you open a terminal, but it is much more efficient to save them permanently in your shell profile. For most modern macOS users, this file is .zshrc. Open your terminal and add the following lines to your profile, making sure to replace the placeholder text with your actual Azure credentials: export CLAUDE_CODE_USE_FOUNDRY=1 export ANTHROPIC_FOUNDRY_API_KEY="your-azure-api-key" export ANTHROPIC_FOUNDRY_RESOURCE="your-resource-name" # Specify the deployment name for Opus export CLAUDE_CODE_MODEL="your-opus-deployment-name" Once you have added these variables, you need to reload your shell configuration for the changes to take effect. Run the source command below to update your current session, and then verify the setup by launching Claude: source ~/.zshrc claude If everything is configured correctly, the Claude CLI will initialize using your Microsoft Foundry deployment as the backend. Once you execute the claude command, the CLI will prompt you to choose an authentication method. Select Option 2 (Antrophic Console account) to proceed. This action triggers your default web browser and redirects you to the Claude Console. Simply sign in using your standard Anthropic account credentials. After you have successfully signed in, you will be presented with a permissions screen. Click the Authorize button to link your web session back to your local terminal. Return to your terminal window, and you should see a notification confirming that the login process is complete. Press Enter to finalize the setup. You are now fully connected. You can start using Claude Code locally, powered entirely by the model deployment running in your Microsoft Foundry environment. Conclusion Setting up this environment might seem like a heavy lift just to run a CLI tool, but the payoff is significant. You now have a workflow that combines the immediate feedback of local development with the security and infrastructure benefits of Microsoft Foundry. One of the most practical upgrades is the removal of standard usage caps. You are no longer limited to the 5-hour API call limits, which gives you the freedom to iterate, test, and debug for as long as your project requires without hitting a wall. By bridging your local macOS terminal to Azure, you are no longer just hitting an API endpoint. You are leveraging a managed, compliance-ready environment that scales with your needs. The best part is that now the configuration is locked in, you don't need to think about the plumbing again. You can focus entirely on coding, knowing that the reliability of an enterprise platform is running quietly in the background supporting every command.1.6KViews1like0CommentsBuilding with Azure OpenAI Sora: A Complete Guide to AI Video Generation
In this comprehensive guide, we'll explore how to integrate both Sora 1 and Sora 2 models from Azure OpenAI Service into a production web application. We'll cover API integration, request body parameters, cost analysis, limitations, and the key differences between using Azure AI Foundry endpoints versus OpenAI's native API. Table of Contents Introduction to Sora Models Azure AI Foundry vs. OpenAI API Structure API Integration: Request Body Parameters Video Generation Modes Cost Analysis per Generation Technical Limitations & Constraints Resolution & Duration Support Implementation Best Practices Introduction to Sora Models Sora is OpenAI's groundbreaking text-to-video model that generates realistic videos from natural language descriptions. Azure AI Foundry provides access to two versions: Sora 1: The original model focused primarily on text-to-video generation with extensive resolution options (480p to 1080p) and flexible duration (1-20 seconds) Sora 2: The enhanced version with native audio generation, multiple generation modes (text-to-video, image-to-video, video-to-video remix), but more constrained resolution options (720p only in public preview) Azure AI Foundry vs. OpenAI API Structure Key Architectural Differences Sora 1 uses Azure's traditional deployment-based API structure: Endpoint Pattern: https://{resource-name}.openai.azure.com/openai/deployments/{deployment-name}/... Parameters: Uses Azure-specific naming like n_seconds, n_variants, separate width/height fields Job Management: Uses /jobs/{id} for status polling Content Download: Uses /video/generations/{generation_id}/content/video Sora 2 adapts OpenAI's v1 API format while still being hosted on Azure: Endpoint Pattern: https://{resource-name}.openai.azure.com/openai/deployments/{deployment-name}/videos Parameters: Uses OpenAI-style naming like seconds (string), size (combined dimension string like "1280x720") Job Management: Uses /videos/{video_id} for status polling Content Download: Uses /videos/{video_id}/content Why This Matters? This architectural difference requires conditional request formatting in your code: const isSora2 = deployment.toLowerCase().includes('sora-2'); if (isSora2) { requestBody = { model: deployment, prompt, size: `${width}x${height}`, // Combined format seconds: duration.toString(), // String type }; } else { requestBody = { model: deployment, prompt, height, // Separate dimensions width, n_seconds: duration.toString(), // Azure naming n_variants: variants, }; } API Integration: Request Body Parameters Sora 1 API Parameters Standard Text-to-Video Request: { "model": "sora-1", "prompt": "Wide shot of a child flying a red kite in a grassy park, golden hour sunlight, camera slowly pans upward.", "height": "720", "width": "1280", "n_seconds": "12", "n_variants": "2" } Parameter Details: model (String, Required): Your Azure deployment name prompt (String, Required): Natural language description of the video (max 32000 chars) height (String, Required): Video height in pixels width (String, Required): Video width in pixels n_seconds (String, Required): Duration (1-20 seconds) n_variants (String, Optional): Number of variations to generate (1-4, constrained by resolution) Sora 2 API Parameters Text-to-Video Request: { "model": "sora-2", "prompt": "A serene mountain landscape with cascading waterfalls, cinematic drone shot", "size": "1280x720", "seconds": "12" } Image-to-Video Request (uses FormData): const formData = new FormData(); formData.append('model', 'sora-2'); formData.append('prompt', 'Animate this image with gentle wind movement'); formData.append('size', '1280x720'); formData.append('seconds', '8'); formData.append('input_reference', imageFile); // JPEG/PNG/WebP Video-to-Video Remix Request: Endpoint: POST .../videos/{video_id}/remix Body: Only { "prompt": "your new description" } The original video's structure, motion, and framing are reused while applying the new prompt Parameter Details: model (String, Optional): Your deployment name prompt (String, Required): Video description size (String, Optional): Either "720x1280" or "1280x720" (defaults to "720x1280") seconds (String, Optional): "4", "8", or "12" (defaults to "4") input_reference (File, Optional): Reference image for image-to-video mode remix_video_id (String, URL parameter): ID of video to remix Video Generation Modes 1. Text-to-Video (Both Models) The foundational mode where you provide a text prompt describing the desired video. Implementation: const response = await fetch(endpoint, { method: 'POST', headers: { 'Content-Type': 'application/json', 'api-key': apiKey, }, body: JSON.stringify({ model: deployment, prompt: "A train journey through mountains with dramatic lighting", size: "1280x720", seconds: "12", }), }); Best Practices: Include shot type (wide, close-up, aerial) Describe subject, action, and environment Specify lighting conditions (golden hour, dramatic, soft) Add camera movement if desired (pans, tilts, tracking shots) 2. Image-to-Video (Sora 2 Only) Generate a video anchored to or starting from a reference image. Key Requirements: Supported formats: JPEG, PNG, WebP Image dimensions must exactly match the selected video resolution Our implementation automatically resizes uploaded images to match Implementation Detail: // Resize image to match video dimensions const targetWidth = parseInt(width); const targetHeight = parseInt(height); const resizedImage = await resizeImage(inputReference, targetWidth, targetHeight); // Send as multipart/form-data formData.append('input_reference', resizedImage); 3. Video-to-Video Remix (Sora 2 Only) Create variations of existing videos while preserving their structure and motion. Use Cases: Change weather conditions in the same scene Modify time of day while keeping camera movement Swap subjects while maintaining composition Adjust artistic style or color grading Endpoint Structure: POST {base_url}/videos/{original_video_id}/remix?api-version=2024-08-01-preview Implementation: let requestEndpoint = endpoint; if (isSora2 && remixVideoId) { const [baseUrl, queryParams] = endpoint.split('?'); const root = baseUrl.replace(/\/videos$/, ''); requestEndpoint = `${root}/videos/${remixVideoId}/remix${queryParams ? '?' + queryParams : ''}`; } Cost Analysis per Generation Sora 1 Pricing Model Base Rate: ~$0.05 per second per variant at 720p Resolution Scaling: Cost scales linearly with pixel count Formula: const basePrice = 0.05; const basePixels = 1280 * 720; // Reference resolution const currentPixels = width * height; const resolutionMultiplier = currentPixels / basePixels; const totalCost = basePrice * duration * variants * resolutionMultiplier; Examples: 720p (1280×720), 12 seconds, 1 variant: $0.60 1080p (1920×1080), 12 seconds, 1 variant: $1.35 720p, 12 seconds, 2 variants: $1.20 Sora 2 Pricing Model Flat Rate: $0.10 per second per variant (no resolution scaling in public preview) Formula: const totalCost = 0.10 * duration * variants; Examples: 720p (1280×720), 4 seconds: $0.40 720p (1280×720), 12 seconds: $1.20 720p (720×1280), 8 seconds: $0.80 Note: Since Sora 2 currently only supports 720p in public preview, resolution doesn't affect cost, only duration matters. Cost Comparison Scenario Sora 1 (720p) Sora 2 (720p) Winner 4s video $0.20 $0.40 Sora 1 12s video $0.60 $1.20 Sora 1 12s + audio N/A (no audio) $1.20 Sora 2 (unique) Image-to-video N/A $0.40-$1.20 Sora 2 (unique) Recommendation: Use Sora 1 for cost-effective silent videos at various resolutions. Use Sora 2 when you need audio, image/video inputs, or remix capabilities. Technical Limitations & Constraints Sora 1 Limitations Resolution Options: 9 supported resolutions from 480×480 to 1920×1080 Includes square, portrait, and landscape formats Full list: 480×480, 480×854, 854×480, 720×720, 720×1280, 1280×720, 1080×1080, 1080×1920, 1920×1080 Duration: Flexible: 1 to 20 seconds Any integer value within range Variants: Depends on resolution: 1080p: Variants disabled (n_variants must be 1) 720p: Max 2 variants Other resolutions: Max 4 variants Concurrent Jobs: Maximum 2 jobs running simultaneously Job Expiration: Videos expire 24 hours after generation Audio: No audio generation (silent videos only) Sora 2 Limitations Resolution Options (Public Preview): Only 2 options: 720×1280 (portrait) or 1280×720 (landscape) No square formats No 1080p support in current preview Duration: Fixed options only: 4, 8, or 12 seconds No custom durations Defaults to 4 seconds if not specified Variants: Not prominently supported in current API documentation Focus is on single high-quality generations with audio Concurrent Jobs: Maximum 2 jobs (same as Sora 1) Job Expiration: 24 hours (same as Sora 1) Audio: Native audio generation included (dialogue, sound effects, ambience) Shared Constraints Concurrent Processing: Both models enforce a limit of 2 concurrent video jobs per Azure resource. You must wait for one job to complete before starting a third. Job Lifecycle: queued → preprocessing → processing/running → completed Download Window: Videos are available for 24 hours after completion. After expiration, you must regenerate the video. Generation Time: Typical: 1-5 minutes depending on resolution, duration, and API load Can occasionally take longer during high demand Resolution & Duration Support Matrix Sora 1 Support Matrix Resolution Aspect Ratio Max Variants Duration Range Use Case 480×480 Square 4 1-20s Social thumbnails 480×854 Portrait 4 1-20s Mobile stories 854×480 Landscape 4 1-20s Quick previews 720×720 Square 4 1-20s Instagram posts 720×1280 Portrait 2 1-20s TikTok/Reels 1280×720 Landscape 2 1-20s YouTube shorts 1080×1080 Square 1 1-20s Premium social 1080×1920 Portrait 1 1-20s Premium vertical 1920×1080 Landscape 1 1-20s Full HD content Sora 2 Support Matrix Resolution Aspect Ratio Duration Options Audio Generation Modes 720×1280 Portrait 4s, 8s, 12s ✅ Yes Text, Image, Video Remix 1280×720 Landscape 4s, 8s, 12s ✅ Yes Text, Image, Video Remix Note: Sora 2's limited resolution options in public preview are expected to expand in future releases. Implementation Best Practices 1. Job Status Polling Strategy Implement adaptive backoff to avoid overwhelming the API: const maxAttempts = 180; // 15 minutes max let attempts = 0; const baseDelayMs = 3000; // Start with 3 seconds while (attempts < maxAttempts) { const response = await fetch(statusUrl, { headers: { 'api-key': apiKey }, }); if (response.status === 404) { // Job not ready yet, wait longer const delayMs = Math.min(15000, baseDelayMs + attempts * 1000); await new Promise(r => setTimeout(r, delayMs)); attempts++; continue; } const job = await response.json(); // Check completion (different status values for Sora 1 vs 2) const isCompleted = isSora2 ? job.status === 'completed' : job.status === 'succeeded'; if (isCompleted) break; // Adaptive backoff const delayMs = Math.min(15000, baseDelayMs + attempts * 1000); await new Promise(r => setTimeout(r, delayMs)); attempts++; } 2. Handling Different Response Structures Sora 1 Video Download: const generations = Array.isArray(job.generations) ? job.generations : []; const genId = generations[0]?.id; const videoUrl = `${root}/${genId}/content/video`; Sora 2 Video Download: const videoUrl = `${root}/videos/${jobId}/content`; 3. Error Handling try { const response = await fetch(endpoint, fetchOptions); if (!response.ok) { const error = await response.text(); throw new Error(`Video generation failed: ${error}`); } // ... handle successful response } catch (error) { console.error('[VideoGen] Error:', error); // Implement retry logic or user notification } 4. Image Preprocessing for Image-to-Video Always resize images to match the target video resolution: async function resizeImage(file: File, targetWidth: number, targetHeight: number): Promise<File> { return new Promise((resolve, reject) => { const img = new Image(); const canvas = document.createElement('canvas'); const ctx = canvas.getContext('2d'); img.onload = () => { canvas.width = targetWidth; canvas.height = targetHeight; ctx.drawImage(img, 0, 0, targetWidth, targetHeight); canvas.toBlob((blob) => { if (blob) { const resizedFile = new File([blob], file.name, { type: file.type }); resolve(resizedFile); } else { reject(new Error('Failed to create resized image blob')); } }, file.type); }; img.onerror = () => reject(new Error('Failed to load image')); img.src = URL.createObjectURL(file); }); } 5. Cost Tracking Implement cost estimation before generation and tracking after: // Pre-generation estimate const estimatedCost = calculateCost(width, height, duration, variants, soraVersion); // Save generation record await saveGenerationRecord({ prompt, soraModel: soraVersion, duration: parseInt(duration), resolution: `${width}x${height}`, variants: parseInt(variants), generationMode: mode, estimatedCost, status: 'queued', jobId: job.id, }); // Update after completion await updateGenerationStatus(jobId, 'completed', { videoId: finalVideoId }); 6. Progressive User Feedback Provide detailed status updates during the generation process: const statusMessages: Record<string, string> = { 'preprocessing': 'Preprocessing your request...', 'running': 'Generating video...', 'processing': 'Processing video...', 'queued': 'Job queued...', 'in_progress': 'Generating video...', }; onProgress?.(statusMessages[job.status] || `Status: ${job.status}`); Conclusion Building with Azure OpenAI's Sora models requires understanding the nuanced differences between Sora 1 and Sora 2, both in API structure and capabilities. Key takeaways: Choose the right model: Sora 1 for resolution flexibility and cost-effectiveness; Sora 2 for audio, image inputs, and remix capabilities Handle API differences: Implement conditional logic for parameter formatting and status polling based on model version Respect limitations: Plan around concurrent job limits, resolution constraints, and 24-hour expiration windows Optimize costs: Calculate estimates upfront and track actual usage for better budget management Provide great UX: Implement adaptive polling, progressive status updates, and clear error messages The future of AI video generation is exciting, and Azure AI Foundry provides production-ready access to these powerful models. As Sora 2 matures and limitations are lifted (especially resolution options), we'll see even more creative applications emerge. Resources: Azure AI Foundry Sora Documentation OpenAI Sora API Reference Azure OpenAI Service Pricing This blog post is based on real-world implementation experience building LemonGrab, my AI video generation platform that integrates both Sora 1 and Sora 2 through Azure AI Foundry. The code examples are extracted from production usage.1.5KViews0likes0CommentsMicrosoft Foundry Model Router: A Developer's Guide to Smarter AI Routing
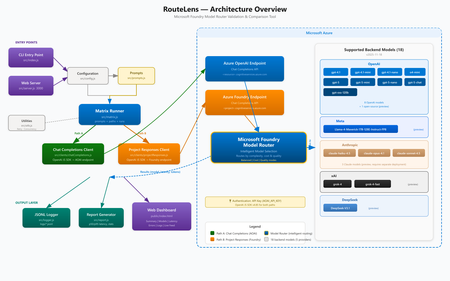
Introduction When building AI-powered applications on Azure, one of the most impactful decisions you make isn't about which model to use, it's about how your application selects models at runtime. Microsoft Foundry Model Router, available through Microsoft Foundry, automatically routes your inference requests to the best available model based on prompt complexity, latency targets, and cost efficiency. But how do you know it's actually routing correctly? And how do you compare its behavior across different API paths? That's exactly the problem RouteLens solves. It's an open-source Node.js CLI and web-based testing tool that sends configurable prompts through two distinct Azure AI runtime paths and produces a detailed comparison of routing decisions, latency profiles, and reliability metrics. In this post, we'll walk through what Model Router does, why it matters, how to use the validator tool, and best practices for designing applications that get the most out of intelligent model routing. What Is Microsoft Founry Model Router? Microsoft Foundry Model Router is a deployment option in Microsoft Foundry that sits between your application and a pool of AI models. Instead of hard-coding a specific model like gpt-4o or gpt-4o-mini , you deploy a Model Router endpoint and let Azure decide which underlying model serves each request. How It Works Your application sends an inference request to the Model Router deployment. Model Router analyzes the request (prompt complexity, token count, required capabilities). It selects the most appropriate model from the available pool. The response is returned transparently — your application code doesn't change. Why This Matters Cost optimization — Simple prompts get routed to smaller, cheaper models. Complex prompts go to more capable (and expensive) ones. Latency reduction — Lightweight prompts complete faster when they don't need a heavyweight model. Resilience — If one model is experiencing high load or throttling, traffic can shift to alternatives. Simplified application code — No need to build your own model-selection logic. The Two Runtime Paths Microsoft Foundry offers two distinct endpoint configurations for hitting Model Router. Even though both use the Chat Completions API, they may have different routing behaviour: Path SDK Endpoint AOAI + Chat Completions OpenAI JS SDK https://.cognitiveservices.azure.com/openai/deployments/ Foundry Project + Chat Completions OpenAI JS SDK (separate client) https://.cognitiveservices.azure.com/openai/deployments/ Understanding whether these two paths produce the same routing decisions is critical for production applications. If the same prompt routes to different models depending on which endpoint you use, that's a signal you need to investigate. Introducing RouteLens RouteLens is a Node.js tool that automates this comparison. It: Sends a configurable set of prompts across categories (echo, summarize, code, reasoning) through both paths. Logs every response to structured JSONL files for post-hoc analysis. Computes statistics including p50/p95 latency, error rates, and model-choice distribution. Highlights routing differences — where the same prompt was served by different models across paths. Provides a web dashboard for interactive testing and real-time result visualization. The Web Dashboard The built-in web UI makes it easy to run tests and explore results without parsing log files: The dashboard includes: KPI Dashboard — Key metrics at a glance: Success Rate, Avg TPS, Gen TPS, Peak TPS, Fastest Response, p50/p95 Latency, Most Reliable Path, Total Tokens Summary view — Per-path/per-category stats with success rate, TPS, and latency Model Comparison — Side-by-side view of which models were selected by each path Latency Charts — Visual bar charts comparing p50 and p95 latencies Error Analysis — Error distribution and detailed error messages Live Feed — Real-time streaming of results as they come in Log Viewer — Browse and inspect historical JSONL log files Model Comparison — See which models were selected by each routing path for every prompt: Live Feed — Real-time streaming of results as they come in: Log Viewer — Browse and inspect historical JSONL log files with parsed table views: Mobile Responsive — The UI adapts to smaller screens: Getting Started Prerequisites Node.js 18+ (LTS recommended) An Azure subscription with a Foundry project Model Router deployed in your Foundry project An API key from your Azure OpenAI / Foundry resource The API version (e.g. 2024-05-01-preview ) Setup # Clone and install git clone https://github.com/leestott/modelrouter-routelens/ cd modelrouter-routelens npm install # Configure your endpoints cp .env.example .env # Edit .env with your Azure endpoints (see below) Configuration The .env file needs these key settings: # Your Foundry / Cognitive Services deployment endpoint # Format: https://<resource>.cognitiveservices.azure.com/openai/deployments/<deployment> # Do NOT include /chat/completions or ?api-version FOUNDRY_PROJECT_ENDPOINT=https://<resource>.cognitiveservices.azure.com/openai/deployments/model-router AOAI_BASE_URL=https://<resource>.cognitiveservices.azure.com/openai/deployments/model-router # API key from your Azure OpenAI / Foundry resource AOAI_API_KEY=your-api-key-here # Azure OpenAI API version AOAI_API_VERSION=2024-05-01-preview</resource></resource></deployment></resource> Running Tests # Full test matrix — sends all prompts through both paths npm run run:matrix # 408 timeout diagnostic — focuses on the Responses path timeout issue npm run run:repro408 # Web UI — interactive dashboard npm run ui # Then open http://localhost:3002 (or the port set in UI_PORT) Understanding the Results Latency Comparison The latency charts show p50 (median) and p95 (tail) latency for each path and prompt category: Key things to look for: Large p50 differences between paths suggest one path has consistently higher overhead. High p95 values indicate tail latency problems — possibly timeouts or retries. Category-specific patterns — If code prompts are slow on one path but fast on another, that's a routing difference worth investigating. Model Comparison The model comparison view shows which models were selected for each prompt: When both paths select the same model, you see a green "Match" indicator. When they differ, it's flagged in red — these are the cases you want to investigate. Error Analysis The errors view helps diagnose reliability issues: Common error patterns: 408 Timeout — The Responses path may take longer for certain prompt categories 401 Unauthorized — Authentication configuration issues 429 Rate Limited — You're hitting throughput limits 500 Internal Server Error — Backend model issues Best Practices for Designing Applications with Model Router 1. Design Prompts with Routing in Mind Model Router makes decisions based on prompt characteristics. To get the best routing: Keep prompts focused — A clear, single-purpose prompt is easier for the router to classify than a multi-part prompt that spans multiple complexity levels. Use system messages effectively — A well-structured system message helps the router understand the task complexity. Separate complex chains — If you have a multi-step workflow, make each step a separate API call rather than one massive prompt. This lets the router use a cheaper model for simple steps. 2. Set Appropriate Timeouts Different models have different latency profiles. Your timeout settings should account for the slowest model the router might select: // Too aggressive — may timeout when routed to a larger model const TIMEOUT = 5000; // 5s // Better — allows headroom for model variation const TIMEOUT = 30000; // 30s // Best — use different timeouts based on expected complexity function getTimeout(category) { switch (category) { case 'echo': return 10000; case 'summarize': return 20000; case 'code': return 45000; case 'reasoning': return 60000; default: return 30000; } } 3. Implement Robust Retry Logic Because the router may select different models on retry, transient failures can resolve themselves: async function callWithRetry(prompt, maxRetries = 3) { for (let attempt = 0; attempt < maxRetries; attempt++) { try { return await client.chat.completions.create({ model: 'model-router', messages: [{ role: 'user', content: prompt }], }); } catch (err) { if (attempt === maxRetries - 1) throw err; // Exponential backoff await new Promise(r => setTimeout(r, 1000 * Math.pow(2, attempt))); } } } 4. Monitor Model Selection in Production Log which model was selected for each request so you can track routing patterns over time: const response = await client.chat.completions.create({ model: 'model-router', messages: [{ role: 'user', content: prompt }], }); // The model field in the response tells you which model was actually used console.log(`Routed to: ${response.model}`); console.log(`Tokens: ${response.usage.total_tokens}`); 5. Use the Right API Path for Your Use Case Based on our testing with RouteLens, consider: Chat Completions path — The standard path for chat-style interactions. Uses the openai SDK directly. Foundry Project path — Uses the same Chat Completions API but through the Foundry project endpoint. Useful for comparing routing behaviour across different endpoint configurations. Note: The Responses API ( /responses ) is not currently available on cognitiveservices.azure.com Model Router deployments. Both paths in RouteLens use Chat Completions. 6. Test Before You Ship Run RouteLens as part of your pre-production validation: # In your CI/CD pipeline or pre-deployment check npm run run:matrix -- --runs 10 --concurrency 4 This helps you: Catch routing regressions when Azure updates model pools Verify that your prompt changes don't cause unexpected model selection shifts Establish latency baselines for alerting Architecture Overview RouteLens sends configurable prompts through two distinct Azure AI runtime paths and compares routing decisions, latency, and reliability. The Matrix Runner dispatches prompts to both the Chat Completions Client (OpenAI JS SDK → AOAI endpoint) and the Project Responses Client ( azure/ai-projects → Foundry endpoint). Both paths converge at Azure Model Router, which intelligently selects the optimal backend model. Results are logged to JSONL files and rendered in the web dashboard. Key Benefits of Model Router Benefit Description Cost savings Automatically routes simple prompts to cheaper models, reducing spend by 30-50% in typical workloads Lower latency Simple prompts complete faster on lightweight models Zero code changes Same API contract as a standard model deployment — just change the deployment name Future-proof As Azure adds new models to the pool, your application benefits automatically Built-in resilience Routing adapts to model availability and load conditions Conclusion Azure Model Router represents a shift from "pick a model" to "describe your task and let the platform decide." This is a natural evolution for AI applications — just as cloud platforms abstract away server selection, Model Router abstracts away model selection. RouteLens gives you the visibility to trust that abstraction. By systematically comparing routing behavior across API paths and prompt categories, you can deploy Model Router with confidence and catch issues before your users do. The tool is open source under the MIT license. Try it out, file issues, and contribute improvements: GitHub Repository Model Router Documentation Microsoft Foundry1.2KViews1like0CommentsStep-by-Step: Deploy the Architecture Review Agent Using AZD AI CLI
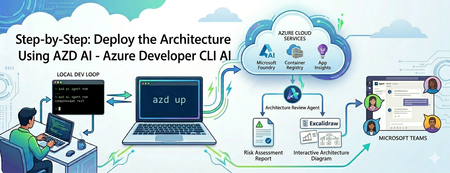
Building an AI agent is easy; operating it is an infrastructure trap. Discover how to use the azd ai CLI extension to streamline your workflow. From local testing to deploying a live Microsoft Foundry hosted agent and publishing it to Microsoft Teams—learn how to do it all without writing complex deployment scripts or needing admin permissions.899Views1like0CommentsBuild and Deploy a Microsoft Foundry Hosted Agent: A Hands-On Workshop
Agents are easy to demo, hard to ship. Most teams can put together a convincing prototype quickly. The harder part starts afterwards: shaping deterministic tools, validating behaviour with tests, building a CI path, packaging for deployment, and proving the experience through a user-facing interface. That is where many promising projects slow down. This workshop helps you close that gap without unnecessary friction. You get a guided path from local run to deployment handoff, then complete the journey with a working chat UI that calls your deployed hosted agent through the project endpoint. What You Will Build This is a hands-on, end-to-end learning experience for building and deploying AI agents with Microsoft Foundry. The lab provides a guided and practical journey through hosted-agent development, including deterministic tool design, prompt-guided workflows, CI validation, deployment preparation, and UI integration. It’s designed to reduce setup friction with a ready-to-run experience. It is a prompt-based development lab using Copilot guidance and MCP-assisted workflow options during deployment. It’s a .NET 10 workshop that includes local development, Copilot-assisted coding, CI, secure deployment to Azure, and a working chat UI. A local hosted agent that responds on the responses contract Deterministic tool improvements in core logic with xUnit coverage A GitHub Actions CI workflow for restore, build, test, and container validation An Azure-ready deployment path using azd, ACR image publishing, and Foundry manifest apply A Blazor chat UI that calls openai/v1/responses with agent_reference A repeatable implementation shape that teams can adapt to real projects Who This Lab Is For AI developers and software engineers who prefer learning by building Motivated beginners who want a guided, step-by-step path Experienced developers who want a practical hosted-agent reference implementation Architects evaluating deployment shape, validation strategy, and operational readiness Technical decision-makers who need to see how demos become deployable systems Why Hosted Agents Hosted agents run your code in a managed environment. That matters because it reduces the amount of infrastructure plumbing you need to manage directly, while giving you a clearer path to secure, observable, team-friendly deployments. Prompt-only demos are still useful. They are quick, excellent for ideation, and often the right place to start. Hosted agents complement that approach when you need custom code, tool-backed logic, and a deployment process that can be repeated by a team. Think of this lab as the bridge: you keep the speed of prompt-based iteration, then layer in the real-world patterns needed to run reliably. What You Will Learn 1) Orchestration You will practise workflow-oriented reasoning through implementation-shape recommendations and multi-step readiness scenarios. The lab introduces orchestration concepts at a practical level, rather than as a dedicated orchestration framework deep dive. 2) Tool Integration You will connect deterministic tools and understand how tool calls fit into predictable execution paths. This is a core focus of the workshop and is backed by tests in the solution. 3) Retrieval Patterns (What This Lab Covers Today) This workshop does not include a full RAG implementation with embeddings and vector search. Instead, it focuses on deterministic local tools and hosted-agent response flow, giving you a strong foundation before adding retrieval infrastructure in a follow-on phase. 4) Observability You will see light observability foundations through OpenTelemetry usage in the host and practical verification during local and deployed checks. This is introductory coverage intended to support debugging and confidence building. 5) Responsible AI You will apply production-minded safety basics, including secure secret handling and review hygiene. A full Responsible AI policy and evaluation framework is not the primary goal of this workshop, but the workflow does encourage safe habits from the start. 6) Secure Deployment Path You will move from local implementation to Azure deployment with a secure, practical workflow: azd provisioning, ACR publishing, manifest deployment, hosted-agent start, status checks, and endpoint validation. The Learning Journey The overall flow is simple and memorable: clone, open, run, iterate, deploy, observe. clone -> open -> run -> iterate -> deploy -> observe You are not expected to memorize every command. The lab is structured to help you learn through small, meaningful wins that build confidence. Your First 15 Minutes: Quick Wins Open the repo and understand the lab structure in a few minutes Set project endpoint and model deployment environment variables Run the host locally and validate the responses endpoint Inspect the deterministic tools in WorkshopLab.Core Run tests and see how behaviour changes are verified Review the deployment path so local work maps to Azure steps Understand how the UI validates end-to-end behaviour after deployment Leave the first session with a working baseline and a clear next step That first checkpoint is important. Once you see a working loop on your own machine, the rest of the workshop becomes much easier to finish. Using Copilot and MCP in the Workflow This lab emphasises prompt-based development patterns that help you move faster while still learning the underlying architecture. You are not only writing code, you are learning to describe intent clearly, inspect generated output, and iterate with discipline. Copilot supports implementation and review in the coding labs. MCP appears as a practical deployment option for hosted-agent lifecycle actions, provided your tools are authenticated to the correct tenant and project context. Together, this creates a development rhythm that is especially useful for learning: Define intent with clear prompts Generate or adjust implementation details Validate behaviour through tests and UI checks Deploy and observe outcomes in Azure Refine based on evidence, not guesswork That same rhythm transfers well to real projects. Even if your production environment differs, the patterns from this workshop are adaptable. Production-Minded Tips As you complete the lab, keep a production mindset from day one: Reliability: keep deterministic logic small, testable, and explicit Security: Treat secrets, identity, and access boundaries as first-class concerns Observability: use telemetry and status checks to speed up debugging Governance: keep deployment steps explicit so teams can review and repeat them You do not need to solve everything in one pass. The goal is to build habits that make your agent projects safer and easier to evolve. Start Today: If you have been waiting for the right time to move from “interesting demo” to “practical implementation”, this is the moment. The workshop is structured for self-study, and the steps are designed to keep your momentum high. Start here: https://github.com/microsoft/Hosted_Agents_Workshop_Lab Want deeper documentation while you go? These official guides are great companions: Hosted agent quickstart Hosted agent deployment guide When you finish, share what you built. Post a screenshot or short write-up in a GitHub issue/discussion, on social, or in comments with one lesson learned. Your example can help the next developer get unstuck faster. Copy/Paste Progress Checklist [ ] Clone the workshop repo [ ] Complete local setup and run the agent [ ] Make one prompt-based behaviour change [ ] Validate with tests and chat UI [ ] Run CI checks [ ] Provision and deploy via Azure and Foundry workflow [ ] Review observability signals and refine [ ] Share what I built + one takeaway Common Questions How long does it take? Most developers can complete a meaningful pass in a few focused sessions of 60-75 mins. You can get the first local success quickly, then continue through deployment and refinement at your own pace. Do I need an Azure subscription? Yes, for provisioning and deployment steps. You can still begin local development and testing before completing all Azure activities. Is it beginner-friendly? Yes. The labs are written for beginners, run in sequence, and include expected outcomes for each stage. Can I adapt it beyond .NET? Yes. The implementation in this workshop is .NET 10, but the architecture and development patterns can be adapted to other stacks. What if I am evaluating for a team? This lab is a strong team evaluation asset because it demonstrates end-to-end flow: local dev, integration patterns, CI, secure deployment, and operational visibility. Closing This workshop gives you more than theory. It gives you a practical path from first local run to deployed hosted agent, backed by tests, CI, and a user-facing UI validation loop. If you want a build-first route into Microsoft Foundry hosted-agent development, this is an excellent place to start. Begin now: https://github.com/microsoft/Hosted_Agents_Workshop_Lab700Views0likes0CommentsHybrid AI Agents in Python: Routing Between Foundry Local and Microsoft Foundry
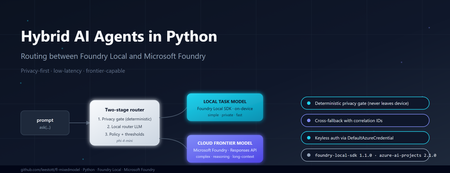
Why hybrid, and why now If you build AI features today, you are caught between three forces. Users want low latency and strong privacy. Product teams want frontier reasoning capability. Finance teams want predictable cost. No single model satisfies all three. Run everything on a small on-device model and you bottleneck on complex questions. Send everything to a frontier cloud model and you pay for trivial requests, leak sensitive data across a network boundary, and add hundreds of milliseconds of latency to greetings. The pragmatic answer is hybrid inference: a lightweight local model classifies every request first, simple or sensitive ones stay on the device, and only the genuinely hard or frontier-capability requests escalate to the cloud. Microsoft now ships both halves of that pattern as supported Python SDKs — foundry-local-sdk for on-device inference and azure-ai-projects for Microsoft Foundry cloud models. This post walks through a working reference implementation that combines them behind a single ask() call. The full source is at github.com/leestott/fl-mixedmodel. It is Python-only, secretless by design, and ships with a Gradio diagnostics UI, a CLI demo mode, and a full pytest suite. The contract: one schema, two paths The most important architectural decision is that callers never know which path served a request. Every response, local or cloud, returns the same dataclass: class InferencePath(str, Enum): LOCAL = "local" CLOUD = "cloud" LOCAL_FALLBACK = "local_fallback" # cloud attempted, fell back to local CLOUD_FALLBACK = "cloud_fallback" # local attempted, fell back to cloud @dataclass class AgentResponse: answer: str path: InferencePath model: str reason: str confidence: float latency_ms: float correlation_id: str prompt_tokens: Optional[int] = None completion_tokens: Optional[int] = None fallback: bool = False fallback_reason: Optional[str] = None metadata: dict = field(default_factory=dict) This is what makes the design honest. The router can change, the cloud model can be swapped from gpt-4o to gpt-5.4 , fallback policies can flip — and the calling code never breaks. The four InferencePath values give you full observability without leaking implementation details into the API surface. Architecture in one diagram ┌─────────────┐ prompt ┌──────────────────────────┐ │ caller │ ──────────► │ HybridAgentService │ └─────────────┘ │ .ask(prompt) │ └────────────┬─────────────┘ │ ┌────────────▼─────────────┐ │ RoutingPolicy │ │ 1. Heuristic gate │ │ 2. Local router LLM │ │ 3. Hard policy gates │ └─────┬─────────────┬──────┘ │ │ LOCAL ◄┘ └► CLOUD │ │ ┌──────────▼──┐ ┌──────▼───────┐ │ Foundry │ │ Microsoft │ │ Local SDK │ │ Foundry │ │ (phi-4-mini)│ │ (gpt-5.4) │ └─────────────┘ └──────────────┘ Best practice: the two-stage router pattern Before walking through the implementation, it is worth stating the design pattern explicitly, because it is the part that generalises beyond this specific repo. The cleanest design for hybrid inference is a two-stage router. Stage 1 — local router. A small local model performs intent and complexity classification first. It does not answer the question; it decides where the question should go. Stage 2 — route the answer. If the prompt is simple, private, latency-sensitive, or clearly within local capability, route to a local task model on the device. If the prompt is complex, needs deeper reasoning, a larger context window, or a capability unavailable locally, escalate to a cloud frontier model in Microsoft Foundry. Microsoft's current guidance for the cloud side is to use the Responses API and choose one of two control modes: Pass a specific deployment name (for example gpt-5.4 ) when you want deterministic control over which model serves the request, which is the right choice for regulated workloads, repeatable evaluations, or cost ceilings. Pass model-router as the deployment when you want Microsoft Foundry to automatically select the best available cloud model for each request. This is a sensible default for general-purpose agents where you would rather let the platform optimise the model choice as new ones are released. The reference repo exposes both as environment variables so you can switch without code changes: # .env.example FOUNDRY_CLOUD_MODEL_DEPLOYMENT=gpt-5.4 # deterministic FOUNDRY_CLOUD_ROUTER_DEPLOYMENT=model-router # auto-select Best practice: pin the right SDK versions Two SDKs do the heavy lifting and both have had recent breaking changes, so version discipline matters. Local development — foundry-local-sdk . The current public guidance is to use the Foundry Local SDK package foundry-local-sdk , which provides model discovery, download, cache, load, unload, chat completions, embeddings, audio transcription, and an optional built-in web service. Use version 1.1.0, released on 5 May 2026. Earlier versions used an OpenAI-compatible client surface that has since been replaced by the FoundryLocalManager → load_model → get_chat_client → complete_chat chain shown above. Pin it explicitly: # requirements.txt foundry-local-sdk>=1.1.0 Cloud orchestration and agents — azure-ai-projects . For cloud-side orchestration, Microsoft's current Python guidance is to use azure-ai-projects , which the docs describe as part of the Microsoft Foundry SDK and as the entry point for agents, deployments, connections, datasets, evaluations, and an OpenAI-compatible client returned by get_openai_client() . The current PyPI listing shows azure-ai-projects 2.1.0. Pin it explicitly: # requirements.txt azure-ai-projects>=2.1.0 azure-identity>=1.17.0 If you find yourself reading old samples that import azure.ai.inference as the cloud entry point, or that initialise Foundry Local through a raw openai.OpenAI(base_url=...) client, you are looking at pre-2026 patterns. The current shape is what the reference repo uses: FoundryLocalManager.initialize(Configuration(...)) for the device and AIProjectClient(...).get_openai_client() for the cloud. Stage 1: a deterministic privacy gate Before any model touches a prompt, a deterministic heuristic classifier scans for sensitive patterns — passwords, API keys, SSN/NHS numbers, PII signals, explicit "do not share" flags. If the heuristic returns PrivacyClass.RESTRICTED , the prompt is forced local. The router LLM is not called. The cloud provider is not called. The decision is auditable from a single regex pass. # app/routing/policy.py def decide(self, prompt: str, correlation_id: str = "") -> RoutingDecision: hint, privacy, complexity, h_reason = self._heuristic.classify(prompt) # Hard gate: restricted content never leaves the device if privacy == PrivacyClass.RESTRICTED: return self._make_decision( target=RouteTarget.LOCAL, confidence=1.0, reason=f"Policy hard-gate: {h_reason}", privacy=privacy, complexity=complexity, deterministic=True, correlation_id=correlation_id, ) # Hard gate: very high complexity always goes to cloud if complexity == ComplexityBand.VERY_HIGH: return self._make_decision( target=RouteTarget.CLOUD, confidence=1.0, reason="Policy hard-gate: very_high complexity requires frontier model", ... ) This is the most important responsible-AI control in the whole system. If your privacy review depends on an LLM correctly classifying every prompt, you do not have a privacy control — you have a probability distribution. Deterministic gates first, model judgement second. Stage 2: a local LLM as the router For everything that passes the privacy gate, a small local model classifies whether the prompt needs frontier capability. This is the bit that surprises most engineers: you can do useful routing with a 4B parameter model running on a laptop CPU. The router does not need to answer the question. It only needs to classify it. The reference implementation uses phi-4-mini via Foundry Local. Initialising it is two lines: # app/providers/local_provider.py (excerpt) from foundry_local import FoundryLocalManager from foundry_local.models import Configuration self._manager = FoundryLocalManager.initialize( Configuration(app_name="hybrid-agent") ) self._router_model = self._manager.load_model(self._config.local_router_alias) self._chat_client = self._router_model.get_chat_client() response = self._chat_client.complete_chat( messages=[ {"role": "system", "content": ROUTER_SYSTEM_PROMPT}, {"role": "user", "content": prompt}, ], ) The router prompt asks for a strict JSON response: { "target": "local|cloud", "confidence": 0.0-1.0, "complexity": "low|medium|high|very_high", "reason": "..." } . The application parses it, applies the confidence threshold from config (default 0.6), and falls back to the heuristic decision if the router LLM is unsure or its JSON is malformed. The router never blocks the answer path — that is a deliberate reliability choice. Cloud inference via Microsoft Foundry When the policy returns RouteTarget.CLOUD , the request goes through AIProjectClient , which gives you an openai.OpenAI -compatible client wired to your Foundry project with DefaultAzureCredential . No API keys. No secrets in .env . # app/providers/cloud_provider.py (excerpt) from azure.ai.projects import AIProjectClient from azure.identity import DefaultAzureCredential self._project = AIProjectClient( endpoint=self._config.foundry_project_endpoint, credential=DefaultAzureCredential(), ) self._openai_client = self._project.get_openai_client() response = self._openai_client.chat.completions.create( model=self._config.foundry_cloud_model_deployment, # e.g. "gpt-5.4" messages=messages, max_completion_tokens=max_tokens, ) A subtle gotcha worth flagging: gpt-5 and o-series deployments reject the legacy max_tokens parameter and require max_completion_tokens . They also reject custom temperature values. The reference repo handles this by trying the new parameter first and falling back to the legacy one only when the API returns the specific unsupported parameter error. That keeps the same code working against older deployments without forking the provider. Graceful degradation: the fallback paths Hybrid systems fail in interesting ways. The cloud can be down. The local model can throw because the GPU ran out of memory. A reasoning model can return an empty completion. The service handles all of these by attempting the alternative path and labelling the response so observability stays honest: Cloud route fails → local fallback. The response carries path=LOCAL_FALLBACK , fallback=true , and a populated fallback_reason . The user gets an answer instead of an error. Local route fails → cloud fallback, but only if privacy class is not RESTRICTED. A sensitive prompt that the local model could not handle never leaks to the cloud as a fallback. It returns a clear error instead. This is the second hard gate in the system. Both fail. A structured error response with a correlation ID, never a stack trace. That last rule — fallback respects privacy class — is the kind of decision that is easy to skip and impossible to bolt on later. Encode it once in the service layer and your privacy reviewers will thank you. What it looks like in practice The diagnostics panel in the Gradio UI shows the routing decision live: path, model, confidence, latency, privacy class, complexity band, and the full JSON response. Five canonical scenarios shake out the entire decision tree: "hello" → path=local, confidence=1.0, complexity=low . Heuristic only. No router LLM call. ~3 seconds end-to-end with phi-4-mini cached. "explain transformer self-attention in depth with maths" → path=cloud, model=gpt-5.4, complexity=high . Router LLM classifies, hard gate confirms. "my password is hunter2, suggest a stronger one" → path=local, privacy=restricted, deterministic=true . Privacy gate fires before any model sees it. "summarise this 8 KB document" with cloud unavailable → path=cloud_fallback (local handles it, response is labelled). Complex prompt with local model error → path=local_fallback , fallback_reason populated. You can reproduce all five without any models installed by running python -m app.main --demo . The demo mode swaps the providers for deterministic stubs so you can validate the routing logic and the response schema in under a second on any machine. Operational lessons learned Some things the reference implementation only gets right because it got them wrong first: Pick a non-reasoning model for the router. Reasoning-tuned local models (Phi-4-reasoning, o-style) wrap their output in <think> blocks and blow your JSON parser. phi-4-mini is faster and more reliable for classification. Cache the local model. First load can take 30–60 seconds while Foundry Local downloads weights. Initialise the service once at process startup, not per request. Use correlation IDs everywhere. The service attaches one per request and the structured JSON logger emits it on every event. When you are debugging a fallback path across two model providers, this is the difference between five minutes and five hours. Run the privacy heuristic on every fallback path too. A naive implementation might route locally, fail, and then send the same sensitive prompt to the cloud as a "graceful" fallback. That is not graceful, it is a data leak. Keep configuration in .env and out of code. Privacy mode, fallback toggles, confidence threshold, model aliases — all environment-driven. The config.py module is the only place that reads them. Responsible AI in a hybrid topology Hybrid does not make responsible AI harder, but it does make it different. Three controls earn their keep: Data residency by default. The local path keeps prompts and answers on the device. For RESTRICTED content this is mandatory; for everything else it is a free latency and cost win. Auditability. Every routing decision is logged with the deterministic reason, the heuristic class, the router LLM output, the confidence, and the correlation ID. You can answer "why did this prompt go to the cloud?" months later. Keyless auth. DefaultAzureCredential means there is no API key to leak, rotate, or commit by accident. The repo's .gitignore , SECURITY.md , and pre-push checklist enforce this end-to-end. Try it Five minutes, no Azure account needed for the demo: git clone https://github.com/leestott/fl-mixedmodel.git cd fl-mixedmodel python -m venv .venv .venv\Scripts\activate # Windows # source .venv/bin/activate # macOS / Linux pip install -r requirements.txt python -m app.main --demo # all five scenarios, no models required To run with real models, install Foundry Local, copy .env.example to .env , set your FOUNDRY_PROJECT_ENDPOINT , then: az login python -m app.main --ui --port 7860 Where to go next Repository: github.com/leestott/fl-mixedmodel — full source, tests, specification, screenshots. Foundry Local SDK: pypi.org/project/foundry-local-sdk and the Foundry Local docs. Azure AI Projects SDK: pypi.org/project/azure-ai-projects and the Microsoft Foundry docs. Azure Identity: DefaultAzureCredential reference. Phi-4-mini: Phi-4-mini on Hugging Face. Key takeaways The best-practice pattern is a two-stage router: local model classifies first, then either a local task model or a Microsoft Foundry cloud model answers. For cloud control, use the Responses API with either a named deployment (deterministic) or model-router (auto-select). Pin foundry-local-sdk >= 1.1.0 (5 May 2026) and azure-ai-projects >= 2.1.0 . The 2026 SDK surfaces are not backwards-compatible with pre-2026 samples. Hybrid inference is a routing problem, not a model problem. A small local model is enough to classify the request. Deterministic privacy gates beat probabilistic ones. Code the rules; let the LLM judge only what is left. Return the same response schema from every path. Label fallbacks honestly. Carry a correlation ID everywhere. Keep auth keyless with DefaultAzureCredential and your .env out of git. Test the routing decisions, not just the model outputs. Demo mode and a strong pytest suite pay back every time you swap a model. Hybrid AI is not a compromise between local and cloud. It is the supervisor pattern applied to inference — fast and private where you can be, frontier where you have to be, observable everywhere. The hard part is the contract, not the models.500Views1like0CommentsMicrosoft Foundry Guardrails Getting in Your Way? Here’s How to Dial Them Down
How This All Started So here’s the story. I just got back from a trip and had a pile of footage sitting on my laptop. Being the lazy (sorry, efficient) person I am, I fired up OpenCode and asked GPT-6 Astra, running on Microsoft Foundry, to cut me a travelogue. Nothing fancy: under two minutes, nice lighting, clean transitions, no cringy effects, a quick QA before showing me, and the output in its own folder. Easy, right? Nope. This is what I got instead: “Image processing blocked due to content policy violation.” Seriously? It’s holiday footage! Nothing even remotely dodgy in there. This is a classic false positive from the default guardrails, and the good news is it’s totally fixable. Let me show you how. My Setup Quick context before we dive in: I’ve got two models deployed on Microsoft Foundry, gpt-6-astra and gpt-6-sol. Both were running on Microsoft’s out-of-the-box guardrail. Step 1: Find the Guardrails Page Head over to the Microsoft Foundry portal, click Build, then hit Guardrails in the left menu. You’ll see three guardrails that Microsoft gives you by default: Microsoft.Default, Microsoft.DefaultV2 and Microsoft.MAIDefault. Microsoft.DefaultV2 is the one every new deployment gets, which is why it’s sitting on both of my models. Here’s the catch: you can’t edit or delete these Microsoft-managed defaults. So instead of tweaking them, we’re going to build our own guardrail and swap it in. Step 2: Create Your Own Guardrail Smash that "Create" button and you’ll land on the Create guardrail page. This is where all the knobs and switches live: Every control has three bits: the risk type, the intervention point (does it check what you send in, what the model spits out, or both?) and the action. The magic trick for loosening things up is flipping the action from Block to Annotate. With Annotate, Foundry still scans the content and tags it in the API response, but it stops slamming the door on your request. So What Does Each Setting Actually Do? Before you go on a switching-off spree, it’s worth knowing what each of these does and what you’re giving up when you loosen it. Here’s the quick tour: Jailbreak: This one catches prompts trying to trick the model into ignoring its rules. On Block, those prompts get rejected outright. On Annotate, they go through with a flag. Turn it off completely and you’re trusting the model’s own training to keep it in line. Network (egress rules): Controls which outbound calls a hosted agent is allowed to make. As the portal points out, it only applies to hosted agents, so for plain model deployments like mine it doesn’t change a thing. Indirect prompt injections: Watches user input and tool responses (files, docs, web pages the model reads) for sneaky instructions someone has planted. Leave it on and your agents are protected when they read outside content; switch it off and a dodgy file could quietly hijack your model. For an agentic tool like OpenCode, which reads files and runs shell commands, I’d honestly keep this one on, even if it’s just on Annotate. Spotlighting (Preview): Tags external content inside the prompt so the model can tell your real instructions apart from random untrusted data. Think of it as an extra seatbelt against indirect attacks. Content harms (Hate, Sexual, Self-harm, Violence): Each of these has a severity slider that starts at Medium blocking, meaning anything rated medium or higher gets blocked. Slide it down to Lowest blocking and only the really nasty stuff gets stopped, which kills off most false positives like mine. The asterisk means these four are mandatory: you can turn the dial down, but you can’t switch them off. Blocklists: Want to ban specific words or phrases, like profanity or your competitor’s name? This is where you do it. It’s off by default. Protected material for code and text: Checks whether the model is about to spit out known copyrighted text (song lyrics, articles and so on) or code lifted from public repos. Block stops it; Annotate lets it through with a flag. Switch it off and you’re rolling the dice on your app reproducing someone else’s copyrighted work. Step 3: Pick Your Models Hit Next and Foundry asks which agents and models you want this guardrail on. Any model you’ve already deployed in your project shows up here. For me that’s gpt-6-astra and gpt-6-sol, so I ticked both. Step 4: Name It and Pick a Streaming Mode One more Next and you’re on the Review page. Give your guardrail a name (I went with NoGuardrails, because subtlety isn’t my thing) and pick a streaming mode. You’ve got two choices: Default: Foundry buffers the response and runs it through the guardrail before each chunk goes out. Nothing reaches the user until it’s been checked. Safest option, but you’ll feel a bit of lag when streaming. Asynchronous: Content streams back the moment it’s generated, with the filters running in the background. Much snappier, but flagged content might flash up briefly before the filter catches it, so your app has to clean up after the fact. Microsoft pitches this for low-latency stuff like internal dev tools, which is exactly my use case. Give the summary a quick once-over, then click Create. Done! Did It Work? Yep! With my shiny new guardrail in place, I fired off the exact same request, this time to GPT-6 Sol. And boom: no more content policy error. The model went straight to work scanning my footage and putting the video together. Wrapping Up Look, Microsoft’s default guardrails are a solid starting point, but they can be a bit trigger-happy when you’re doing perfectly legit stuff like video editing, creative work or internal tooling. Since you can’t touch the defaults, the trick is to roll your own: flip Block to Annotate where it makes sense, drag those content harm sliders down, pick the streaming mode that fits your app, and assign it to your deployments. That’s it! One friendly word of warning though: with great power comes great responsibility. Only loosen what you actually need, keep things like indirect prompt injection detection switched on for any agent that reads files or browses the web, and think twice before doing this on anything customer-facing. And if you want to go further than the portal lets you, like switching content filters off completely, you’ll need to apply to Microsoft for approval first. Happy building!400Views1like2CommentsAdding a Fallback Model to Hermes with Microsoft Foundry
So the plan was simple. Leave the Bedrock configuration untouched, then wire Microsoft Foundry in behind it as a fallback, so Hermes always has somewhere else to go when the primary provider is not responding. A few other reasons pushed me towards Foundry in particular: Redundancy that does not need me. If Bedrock is throttled or out of quota, I want Hermes to fail over on its own rather than waiting for me to notice. A catalogue I already pay for. Foundry puts the latest GPT models next to open-weight and partner models in one place, so I can pick a model that suits the task instead of settling for whatever a single provider happens to offer. Enterprise controls out of the box. Region pinning, private networking, content filters and per-deployment quota all sit in the same portal, which makes the setup far easier to defend to a security reviewer. Learning the mechanics before I need them. Working out how Hermes handles a provider chain is much nicer on a quiet Tuesday than during a live outage. Here is the short version, if you are deciding whether to read on. Time: about thirty minutes if nothing goes wrong. Cost: pay-as-you-go tokens only, and none at all while the fallback sits idle. Result: an assistant that keeps answering when your primary provider stops. Before you start, you will need three things: a machine with Hermes already installed and a working primary provider configured, an Azure subscription with access to Microsoft Foundry in a region you can actually deploy into, and enough quota in that region to create a deployment. One thing that made this easy to justify: Foundry deployments bill per token on the standard pay-as-you-go tier. A fallback provider that never gets invoked costs nothing beyond the requests it actually serves, so the insurance is close to free until the day you need it. Chat surface (CLI, messaging) → Hermes Gateway → Primary Amazon Bedrock → Fallback Microsoft Foundry Figure 1: Where the fallback sits. Every request goes through the Hermes gateway to the primary provider; only when that provider is unavailable does the chain continue to Microsoft Foundry. Part 1: Deploying a Model on Microsoft Foundry The first half of this job happens entirely inside the Microsoft Foundry portal and has nothing to do with Hermes yet. All you are really doing here is making sure your Azure subscription can serve a model, and that you hold an endpoint and key Hermes can authenticate with later. 1. Deploy model in Foundry → 2. Copy endpoint + key → 3. hermes fallback add → 4. Authenticate → 5. Select models, test Figure 2: The whole setup in five moves. The first two happen in the Microsoft Foundry portal (orange); the rest happen on the Hermes machine (blue). Go to Microsoft Foundry > Build > Models > Deploy > Deploy a base model. You can deploy a fine-tuned model instead if you already have one, which works just as well with Hermes. Check the region shown at the top of the portal before you commit, because both model availability and deployment quota differ from one region to the next. Then deploy the model you have selected: In this case I deployed gpt-5.6-sol, which is the model Hermes will fall back to. The choice was deliberate rather than exciting. My primary model on Bedrock is a general-purpose chat model, and a fallback is only useful if the answers it gives feel like a continuation of the same conversation rather than a different assistant wearing the same name. The gpt-5.6-sol deployment matches that behaviour closely, it was available in the region I wanted to pin, and the quota I was granted comfortably covers a day of normal use. If a fallback surprises you the first time it fires, it is the wrong fallback. Once the deployment finishes, open it and take note of two values: the target endpoint URI and the API key. Copy both somewhere safe now, because you will be pasting them into Hermes in the next part. If your organisation rotates keys on a schedule, use a key with the longest life you are allowed, since a fallback secured with a credential that expires quietly stops being a fallback. What to copy Where it lives in the portal Where Hermes asks for it Target endpoint URI Deployment > Endpoint > Target URI "Endpoint" prompt in hermes fallback add API key Deployment > Endpoint > Key "API key" prompt, or choose Entra ID instead Deployment name Deployment > Details > Name Shown in the model list Hermes returns Region Top of the portal, next to the resource Must match the region you deployed into Figure 3: Everything Hermes will ask for, and where to find each value before you leave the portal. Part 2: Adding Foundry to Hermes as a Fallback With the Foundry side sorted, everything from here happens in the Hermes CLI. One thing worth knowing before you start: this is the fallback command, not the primary model command, so your existing Bedrock configuration is left completely alone. Nothing in this section can break what is already working, which makes it a good one to try on a live setup. Run the Hermes fallback command: When Hermes asks which provider to add, choose Azure Foundry. The picker still carries the old name; it is the same service that the portal now calls Microsoft Foundry. Paste the target endpoint URI from your deployment, then authenticate with the API key you copied earlier. Hermes also offers Microsoft Entra ID at this prompt, which is the better option if your organisation would rather not have a static key sitting on the machine. If authentication fails here, check the endpoint before you start suspecting the key. In my experience the endpoint is wrong far more often than the credential is, usually because the deployment name at the end of the URI does not match the deployment you actually created. Once authentication succeeds, Hermes lists the deployments your Foundry resource exposes and asks which ones you want to use. You can select more than one, and the order is not cosmetic: Hermes walks down the chain from top to bottom whenever the provider above is unavailable. Treat that list as a priority order, not a shopping basket. What happens to the primary What Hermes does What you see in the chat Responds normally Routes every request to the primary and never touches the chain Nothing. The fallback stays idle Throttled or out of quota Retries the next provider down the chain on the same request A reply, served by the fallback model Endpoint unreachable Keeps failing over on each new request until the primary recovers Slightly different tone and latency, but a working assistant Every provider fails Returns the error rather than hanging An error worth chasing with hermes status Figure 4: The chain in practice. The fallback only earns its keep in the middle two rows, which is exactly why it is easy to forget you configured it. Part 3: Promoting Foundry to the Primary Model At this stage Foundry is sitting in the back seat as a backup. I wanted to reverse the arrangement and make Foundry the primary while Bedrock slides down into the fallback slot, partly because I preferred keeping day-to-day traffic inside my Azure subscription, and partly because I wanted proof the chain works in both directions. Before promotion After promotion Primary: Amazon Bedrock → Primary: Microsoft Foundry Fallback: Microsoft Foundry → Fallback: Amazon Bedrock Figure 5: The promotion, in effect. Nothing is added or removed; the two providers simply trade places in the chain. There is no dedicated "promote" command in Hermes, so the manual route is a short sequence of steps rather than a single instruction: Select the fallback provider/model as the new primary: hermes model Remove the now-duplicate model from the fallback chain: hermes fallback remove Optionally add the old primary model as a fallback: hermes fallback add Restart the messaging gateway: hermes gateway restart Verify the result: hermes status / hermes fallback list That sequence works, and it is good to know what is happening underneath. But since I already had a working provider configured, I would rather just ask Hermes to rearrange itself. This is the part I genuinely enjoy about the tool: the configuration is something you can talk to, not only something you type commands at. Prompt: Okay now please make the model I configured on Microsoft Foundry into the main model, and make the Bedrock one the fallback model! Hermes rewrites the provider chain on its own and confirms the swap once it is done, which is a great deal less error-prone than running the five commands by hand. Part 4: Testing the Switch Configuration you have not tested is just an assumption with extra steps, so the next thing is to confirm Hermes really is talking to Foundry. Type /model when running Hermes to bring up the model picker. You will be prompted to select a provider first. Pick the Microsoft Foundry entry, then choose the specific deployment from the list underneath it. The active model should switch straight away. Send it a plain "Hello" to check that the deployment actually responds, rather than just looking correct in the menu. Appearing in a dropdown and serving a request are two very different things. A second test is worth the thirty seconds it costs: run hermes status to confirm which provider is live, then hermes fallback list to confirm the chain is ordered the way you intended. The picker tells you what you selected; those two commands tell you what Hermes will actually do at three in the morning. Part 5: The Obstacle, and What It Actually Taught Me Every walkthrough has the part the author quietly leaves out. Here is mine: the wrinkle was not the model, it was capacity. My first attempt deployed into the region closest to me out of habit, and the portal turned it down because there was no capacity left for that model at the tier I asked for. The model was clearly listed in the catalogue; being listed and being deployable in your region, on your subscription, at your quota, are three separate questions. Redeploying in a different region fixed it in a couple of minutes, but it meant the endpoint URI changed, which in turn meant the value I had already pasted into Hermes was stale. Re-running hermes fallback add against the new endpoint sorted it out. The lesson is cheap enough to hand over for free: check quota and regional capacity for your specific subscription before you design a walkthrough, a demo or a production fallback around one deployment. In the Foundry portal, Management then Quota shows exactly what you have been granted per region and per model family, which is the only list that matters. Symptom Likely cause Fix Deployment rejected in the portal No capacity for that model at the tier you asked for, in that region Deploy in another region, or drop to a smaller tier Hermes rejects the credential Endpoint URI does not match the deployment you created Re-copy the target URI from the deployment, not the resource Provider authenticates but lists nothing Key belongs to a different Foundry resource Check you are in the right resource, then re-run hermes fallback add Fallback never fires Chain ordered the wrong way round hermes fallback list, then reorder Figure 6: The four things that went wrong, or nearly did, and what fixed each one. There is a silver lining worth stating plainly. Because the fallback chain was already in place, a deployment that refused to come up did not take the assistant down with it. That is precisely the scenario this whole exercise was meant to cover, and it turned up on day one without me having to simulate it. Command Cheat Sheet Everything used in this walkthrough, collected in one place: hermes fallback add: attach a provider to the fallback chain hermes fallback remove: drop a provider from the chain hermes fallback list: show the chain in priority order hermes model: set the primary model hermes gateway restart: restart the messaging gateway after a change hermes status: confirm which provider is currently live /model: switch models from inside a running session Conclusion Adding Microsoft Foundry as a fallback behind my existing Bedrock setup took an afternoon, and most of that was spent recovering from a regional capacity limit I should have checked first. The work itself is small: deploy a model, copy the endpoint and key, run hermes fallback add, authenticate, pick your deployments. The payoff is that Hermes no longer depends on one provider staying healthy. Three things are worth carrying away from this: Check quota, not just the catalogue. The Foundry catalogue shows what Microsoft offers. It does not show what your subscription and region can actually deploy today. Confirm that first, before you build anything on top of a specific deployment. Order your fallback chain deliberately. Hermes works down the list from top to bottom, so the sequence you choose during setup is the failover policy you are going to live with. Put the model you actually trust at the top. Treat the endpoint as part of the credential. Redeploying in a new region changes the endpoint URI, and a fallback pointed at an endpoint that no longer exists is not a fallback. Re-run the setup whenever the deployment moves. The switch from Bedrock primary to Foundry primary also proved the chain runs in both directions, which is the real point. Provider redundancy is only useful if you have watched it work. Next on my list is deliberately breaking the primary provider to confirm the failover triggers on its own, without me typing a single command. If you run this against a different model, region or provider pairing, I would genuinely like to know how it went, particularly if your quota experience was better than mine. Drop it in the comments.400Views0likes0Comments