microsoft foundry
21 TopicsEnterprise-ready Claude Desktop with Entra ID, APIM, and Microsoft Foundry (No Backend Required)
How I put corporate sign-in in front of Claude Desktop without writing a single line of backend code. TL;DR — In this post, I show how to securely enable Claude Desktop in enterprise environments using Microsoft Entra ID, Azure API Management, and Microsoft Foundry — without deploying a custom backend. This approach removes API keys from endpoints, enforces per-user identity, and aligns fully with Zero Trust principles. Who this is for: Enterprise architects evaluating secure AI client patterns Developers enabling Claude Desktop in regulated environments Platform teams standardizing identity and governance for LLM access Why this post exists: Microsoft Learn's Configure Claude Desktop with Foundry Models only shows the API-key path — a shared key pasted into every user's Claude Desktop config. That's fine for a quick demo, but it's a non-starter for most enterprises (no per-user identity, no MFA / Conditional Access, hard to revoke, hard to audit). This post fills that gap: same Foundry backend, but with Microsoft Entra ID SSO in front via Azure API Management, so each user signs in with their corporate identity and zero secrets land on the laptop. The problem For many teams experimenting with Claude Desktop, the blocker isn't capability — it's enterprise readiness. How do you enforce identity, eliminate shared secrets, and apply governance without standing up a custom backend service to sit in front of the model? If your team wants to use Claude Desktop with your own Anthropic deployment running on Microsoft Foundry, but with a few non-negotiable requirements: No shared API keys floating around on developer laptops. Per-user identity — every request must be attributable to a real person. MFA and Conditional Access must apply, the same way they do for every other internal app. Central rate-limiting and logging — a centralized control plane for governance. Claude Desktop 1.5+ supports a "Gateway SSO" mode where it can sign each user in with OpenID Connect and forward their token to a custom LLM gateway. Azure API Management (APIM) is a perfect fit for that gateway role: it validates the user's Entra ID token, then re-authenticates itself to Foundry behind the scenes. APIM acts as a centralized policy enforcement layer, enabling identity validation, traffic governance, and secure re-authentication to backend AI services without custom code. The end-to-end flow looks like this: %%{init: {'flowchart': {'nodeSpacing': 60, 'rankSpacing': 80, 'useMaxWidth': true}, 'themeVariables': {'fontSize':'16px'}} }%% flowchart TB User([Corporate user]) Claude["Claude Desktop"] Entra["Microsoft Entra ID<br/>(OIDC + MFA + Conditional Access)"] APIM["Azure API Management<br/>validate-jwt → rewrite headers<br/>(policy gateway)"] Foundry["Microsoft Foundry<br/>Claude deployment"] User -- "1. Sign in (browser PKCE)" --> Entra Entra -- "2. ID token" --> Claude Claude -- "3. POST /v1/messages<br/>Authorization: Bearer ID token" --> APIM APIM -- "4. OIDC discovery / JWKS" --> Entra APIM -- "5. x-api-key (or Managed Identity)" --> Foundry Foundry -- "6. Response" --> APIM APIM -- "7. Response" --> Claude classDef azure fill:#0a4d8c,stroke:#0a3a6b,color:#ffffff; classDef client fill:#f3f3f3,stroke:#888,color:#222; class Entra,APIM,Foundry azure; class Claude,User client; Or in plain text: Claude Desktop │ Authorization: Bearer <Entra ID token from the user's browser sign-in> ▼ Azure API Management (<your-apim>) │ ① validate-jwt → verifies user's Entra ID token │ ② re-auths to Foundry with an API key from a Named value │ Authorization stripped, x-api-key injected ▼ Microsoft Foundry /anthropic/v1/messages │ runs Claude (<your-deployment>) ▼ Response back to the user There are no API keys on user devices. Foundry's key lives only inside APIM. And every request carries the user's oid claim, so I can build dashboards and per-user quotas later. What you need before starting An Azure subscription with a Microsoft Foundry (AI Services) account and a Claude deployment. (Throughout this post I'll just call it Foundry.) An API Management instance, any tier. Permission to register applications in Entra ID for your tenant. Claude Desktop 1.5.0 or later. Azure CLI installed locally. Throughout this post I'll use placeholders for resource names: <apim-name> — your API Management service name <resource-group> — the resource group that holds it <foundry-account> — your Foundry account name <deployment-name> — the name of the Claude model deployment on Foundry Step 1 — Register an Entra ID app for Claude Desktop This is the OIDC client Claude Desktop signs users into. Claude Desktop requires a single-tenant, public PKCE client (no client secret) with a loopback redirect URI, configured under the Mobile and desktop applications platform in Entra ID — the only platform that allows any loopback port. I scripted it so the setup is one command and idempotent: # scripts/register-claude-entra-app.ps1 [CmdletBinding()] param( [string] $TenantId = '<your-tenant-id>', [string] $SubscriptionId = '<your-subscription-id>', [string] $ResourceGroup = '<resource-group>', [string] $ApimName = '<apim-name>', [string] $AppDisplayName = 'Claude Cowork gateway', [string] $RedirectUri = 'http://127.0.0.1/callback' ) az account set --subscription $SubscriptionId | Out-Null # 1. Create (or reuse) the app registration $appId = az ad app list --display-name $AppDisplayName --query "[0].appId" -o tsv if (-not $appId) { $appId = az ad app create --display-name $AppDisplayName ` --sign-in-audience AzureADMyOrg --query appId -o tsv } # 2. Configure as public PKCE client with the Mobile/Desktop redirect URI $objectId = az ad app show --id $appId --query id -o tsv $patch = @{ publicClient = @{ redirectUris = @($RedirectUri) } isFallbackPublicClient = $true } | ConvertTo-Json -Depth 5 -Compress az rest --method PATCH ` --uri "https://graph.microsoft.com/v1.0/applications/$objectId" ` --headers "Content-Type=application/json" --body $patch | Out-Null # 3. Ensure a service principal exists $sp = az ad sp list --filter "appId eq '$appId'" --query "[0].id" -o tsv if (-not $sp) { az ad sp create --id $appId | Out-Null } # 4. Push two Named values into APIM for the validate-jwt policy az apim nv create -g $ResourceGroup --service-name $ApimName ` --named-value-id entra-tenant-id --display-name entra-tenant-id ` --value $TenantId --secret false az apim nv create -g $ResourceGroup --service-name $ApimName ` --named-value-id entra-client-id --display-name entra-client-id ` --value $appId --secret false "Client ID: $appId" Run it once. The output prints the client ID you'll need in Claude Desktop later, and it leaves two Named values in APIM ( entra-tenant-id , entra-client-id ) that the gateway policy will reference. ⚠️ Common pitfall: if the redirect URI ends up under the Web platform instead of Mobile and desktop applications, Entra will demand a client secret on token exchange — Claude won't send one and you'll get Token exchange failed (HTTP 401) . The app type can't be changed after creation, so create a new app if that happens. Step 2 — Create the API in APIM In the portal under APIM → APIs → + Add API → HTTP: Field Value Display name Anthropic API Name anthropicapi Web service URL https://<foundry-account>.services.ai.azure.com/anthropic API URL suffix claude Subscription required Off (Entra ID is our only credential) Add two operations under it: Method URL Display name POST /v1/messages Create message GET /v1/models List models The /v1/models operation isn't strictly needed (Foundry's Anthropic surface doesn't implement it), but having it registered means you can decide later whether to stub it out or proxy it. Step 3 — Add an API key for Foundry as a Named value APIM → Named values → + Add: Name: foundry-key Type: Secret Value: paste a key from the Foundry account's Keys and Endpoint blade. This is the only place the key ever lives. Clients never see it. Alternative — keyless with Entra ID (managed identity): If you prefer not to manage a Foundry key at all, enable the APIM instance's system-assigned managed identity (APIM → Identity → System assigned → On), then grant that identity the Foundry User role on the Foundry account (role ID 53ca6127-db72-4b80-b1b0-d745d6d5456d — previously named Azure AI User; Microsoft renamed it but the ID and permissions are unchanged). In Step 4, replace the set-header that injects x-api-key with: <authentication-managed-identity resource="https://cognitiveservices.azure.com" output-token-variable-name="foundry-token" /> <set-header name="Authorization" exists-action="override"> <value>@("Bearer " + (string)context.Variables["foundry-token"])</value> </set-header> Then you can skip the foundry-key Named value entirely. Don't use the legacy Cognitive Services User role — per the Foundry RBAC doc, roles starting with Cognitive Services don't apply to Foundry scenarios. Step 4 — Write the gateway policy This is the core enforcement layer in the architecture. Open APIs → anthropicapi → All operations → Inbound processing → </> and paste: <policies> <inbound> <base /> <!-- USER → APIM: verify Entra ID token from Claude Desktop --> <validate-jwt header-name="Authorization" failed-validation-httpcode="401" failed-validation-error-message="Unauthorized" require-scheme="Bearer"> <openid-config url="https://login.microsoftonline.com/{{entra-tenant-id}}/v2.0/.well-known/openid-configuration" /> <audiences> <audience>{{entra-client-id}}</audience> </audiences> <issuers> <issuer>https://login.microsoftonline.com/{{entra-tenant-id}}/v2.0</issuer> </issuers> </validate-jwt> <!-- APIM → Foundry --> <set-backend-service base-url="https://<foundry-account>.services.ai.azure.com/anthropic" /> <set-header name="x-api-key" exists-action="override"> <value>{{foundry-key}}</value> </set-header> <set-query-parameter name="api-version" exists-action="skip"> <value>2024-05-01-preview</value> </set-query-parameter> </inbound> <backend><base /></backend> <outbound><base /></outbound> <on-error><base /></on-error> </policies> Two things to notice: validate-jwt uses the OIDC discovery URL — JWKS keys are fetched and cached automatically. It rejects any token whose aud claim is not the client ID of our Entra app, which is exactly what we want. The Authorization header from the user is not forwarded — once validate-jwt succeeds, the request is re-authenticated to Foundry with x-api-key . No user token ever leaves APIM. APIM becomes the security boundary — user identity is validated at the edge, and downstream services never see or rely on user tokens. Step 5 — Configure Claude Desktop Open Claude Desktop → Configure third-party inference and fill it in like this: Field Value Connection Gateway Credential kind Interactive sign-in Gateway base URL https://<apim-name>.azure-api.net/claude Client ID (the appId your script printed) Issuer URL https://login.microsoftonline.com/<tenant-id>/v2.0 Authorization URL / Token URL leave empty Bearer token ID token (default) Scopes leave default ( openid profile email offline_access ) Redirect port leave empty (ephemeral) Model discovery Off Model list → Model ID <deployment-name> (your Foundry deployment name) ℹ️ Why Model discovery is Off — Claude Desktop's discovery uses GET /v1/models , and the Foundry /anthropic surface doesn't implement that endpoint, so it 404s. Listing the model manually skips the call entirely. If you want to leave Model discovery On, stub /v1/models in APIM. Add a GET /v1/models operation to your API and give it this inbound policy that returns an Anthropic-shaped response without ever hitting the backend: <policies> <inbound> <base /> <return-response> <set-status code="200" reason="OK" /> <set-header name="Content-Type" exists-action="override"> <value>application/json</value> </set-header> <set-body>@{ return new JObject( new JProperty("data", new JArray( new JObject( new JProperty("id", "<deployment-name>"), new JProperty("type", "model"), new JProperty("display_name", "Claude on Foundry"), new JProperty("created_at", "2026-01-01T00:00:00Z") ) )), new JProperty("has_more", false), new JProperty("first_id", "<deployment-name>"), new JProperty("last_id", "<deployment-name>") ).ToString(); }</set-body> </return-response> </inbound> <backend><base /></backend> <outbound><base /></outbound> <on-error><base /></on-error> </policies> Add one entry per deployment you want to expose. The benefit of stubbing rather than turning discovery off is that adding new models becomes a policy edit — no need to re-export and redeploy Claude Desktop config to every user. Click Apply Changes then Sign in to your organization. Your browser opens to the normal Entra sign-in page; once approved you're returned to the app, and a quick connection test runs. The success indicator is a small green banner: ✅ Inference — 1-token completion in 1449 ms · via identity provider For broader rollout, hit the Export button at the top of the configuration window — it produces a .mobileconfig (macOS) or .reg (Windows) you can push via Intune / Jamf to every user's machine. Step 6 — Verify both hops In APIM → APIs → anthropicapi → Test → POST /v1/messages I sent: Headers: anthropic-version: 2023-06-01 Body: { "model": "<deployment-name>", "max_tokens": 64, "messages": [{"role":"user","content":"hi"}] } Click Send → Trace, and look at two places: Inbound → validate-jwt: should say succeeded and show the decoded claims (your oid , email , etc.). Backend → Request: outbound URL is https://<foundry-account>.services.ai.azure.com/anthropic/v1/messages?api-version=2024-05-01-preview , with x-api-key: **** present and Authorization absent. Backend → Response: 200, with a Claude message JSON body. That confirms both halves of the chain. Bumps I hit along the way A few common issues encountered during setup — sharing so you can skip them: Symptom Cause Fix Claude shows "Your provider's model list hasn't loaded yet" and /v1/models returns 404 Foundry's Anthropic surface doesn't implement that endpoint Turn Model discovery OFF in Claude Desktop and add the deployment name manually Claude shows "Authentication failed" even though sign-in worked The APIM API still had Subscription required = ON, blocking the call before validate-jwt ran with 401: Access denied due to missing subscription key Uncheck Subscription required on the API Portal Test panel shows "Cannot read properties of undefined (reading 'statusCode')" The test console doesn't attach an Entra token, so validate-jwt 401s and the panel's JavaScript crashes Comment out <validate-jwt> temporarily for portal testing, or test via curl with a real token OIDC discovery failed (HTTP 404) in Claude Desktop Pasted the metadata URL into Issuer URL Issuer must end at /v2.0 , not at /.well-known/openid-configuration Token exchange failed (HTTP 401) App registered under Web platform instead of Mobile and desktop applications Create a new app with the right platform — it can't be changed Where this leaves us This pattern is small in moving parts but has outsized architectural impact: Zero secrets on endpoints. Eliminates API-key sprawl across laptops, MDM profiles, and shared vaults. The Foundry key lives only inside APIM — or disappears entirely when you switch APIM to managed identity. Identity, not credentials. Every Claude Desktop user authenticates against Entra ID in their browser, the same as Office or Teams. MFA, Conditional Access, and Entra ID Protection apply automatically — no parallel auth story to maintain. Per-user observability built in. APIM logs carry the user's Entra oid , email , and group claims. That unlocks per-user dashboards, cost allocation, and abuse detection without any client-side instrumentation. Aligned with Zero Trust. Strong identity at the edge, no implicit trust between hops, single policy chokepoint for inspection and rate-limiting, and full revocability through a single Enterprise Application. Optional but trivial keyless path. Flip APIM to system-assigned managed identity + <authentication-managed-identity resource="https://cognitiveservices.azure.com" /> and one Foundry User role assignment (role ID 53ca6127-db72-4b80-b1b0-d745d6d5456d , formerly Azure AI User) on the Foundry account. See the Foundry RBAC doc — don't use any Cognitive Services * roles for Foundry. What I'd add next llm-token-limit and llm-emit-token-metric policies for per-user quotas and cost visibility. App Insights wiring on the API, with a workbook that pivots on the oid claim. Assignment required = Yes on the Entra Enterprise Application + a security group, so only approved users can sign in. Intune deployment of the exported .reg / .mobileconfig so the gateway URL and client ID land on devices automatically. But that's all incremental. The hard part — getting Claude Desktop, Entra ID, APIM, and Foundry to agree on who's allowed to talk to whom — is done. Total elapsed: about an afternoon, most of it spent learning where each portal hides its switches. Useful links Gateway single sign-on with your identity provider — Claude.ai Documentation Configure Claude Desktop with Foundry Models — Microsoft Learn Role-based access control for Microsoft Foundry — Microsoft Learn3.4KViews0likes3CommentsCreating Autonomous Teams Agents Using OpenClaw, MCP, and Azure Container Apps
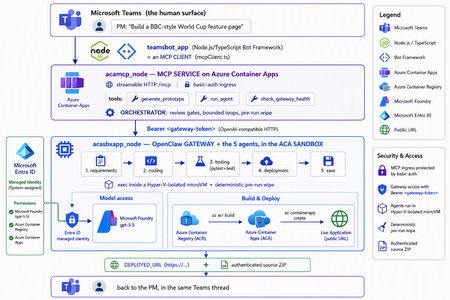
The one shift that changes everything For two years, "AI coding" meant autocomplete. A suggestion appears in your editor, you hit tab, you move on. The agent only existed while you were actively typing. That is no longer the only model. A new category of tools runs asynchronously and autonomously: you message the agent from a chat window — Teams, Slack, Telegram — describe what you want, and walk away. The agent plans, writes code, runs tests, deploys, and hands you back a result. Some of them never sleep: they hold a persistent memory, load their own skills, and act on a schedule without being prompted. This is the world of OpenClaw, Hermes Agent, and the other long-running autonomous agents that exploded across developer culture in 2026. OpenClaw alone crossed 377,000 GitHub stars and millions of active users, becoming — for a while — the most-starred project on GitHub. You install it with one line, connect a channel, and start delegating from your phone. The workflow moves from pair programming to delegation and review. The interactive copilot asks, "What should I write next?" The autonomous agent asks, "What do you need done?" And that reframing is exactly why three questions now keep architects awake: Is it safe? You are handing a self-driving process the ability to run shell commands, touch files, and call APIs. One community report memorably described these agents as a teammate in your group chat who happens to have root access to your codebase. That is not a compliment — it is a threat model. Can it fit into real multi-agent work? A single agent is a demo. Production is a fleet — specialists that hand off to each other with gates in between. Is it flexible and controllable? Autonomy is thrilling right up until the agent packages last week's stale files into this week's deliverable, or loops forever on a failing test. This post answers all three — not with hand-waving, but with a working reference implementation you can clone today: CustomCodingAgentApp in the Multi-AI-Agents-Cloud-Native repo, an "Agentic Prototype Factory" that turns a plain-language idea into a tested, live-on-Azure prototype without leaving the chat window. A product manager types "Build a BBC-style World Cup feature page" in Microsoft Teams. Minutes later they get back a running HTTPS URL and a downloadable source ZIP. Under the hood, five specialized OpenClaw agents powered by Microsoft Foundry gpt-5.5 collaborate in a shared sandbox, run real pytest/Jest suites, and ship the result to Azure Container Apps — all orchestrated behind a Model Context Protocol (MCP) service so any MCP client (GitHub Copilot, Claude, the Teams bot) can drive it. We'll build up to that architecture in the order you should learn it. Part 1 — Long-running autonomous agents, and their two hard problems What actually makes them different A traditional chatbot is text in, text out. It waits for you. An autonomous agent inverts that: Property Traditional chatbot Long-running autonomous agent Execution Responds to a prompt Acts proactively (a "heartbeat" wakes it on a schedule) Scope Words Files, shell, browser, APIs — the real machine Memory This session only Persistent across sessions Interface A web box Any chat channel + the terminal Autonomy None Plans and takes multi-step action on its own Architecturally, OpenClaw is not a library you import — it's a runtime. A single long-running process (the Gateway) bridges your messaging channels to an LLM backend, keeps sessions alive, queues work in ordered lanes, and drives the classic agent loop: call the model → execute the tool calls it asks for → feed results back → repeat until done. There is no rigid step-planner; the model itself steers. That is what makes it feel magical — and what makes it hard to contain. That containment problem has two faces. Hard problem #1 — Security The same properties that make an autonomous agent useful make it dangerous. Full system access + proactive execution + a 32,000-server tool ecosystem is a large, self-driving attack surface. OpenClaw's own short history is the cautionary tale: a critical one-click remote-code-execution CVE early in its life, hundreds of malicious community "skills" discovered on its marketplace, and tens of thousands of gateways found exposed on the open internet. None of this means "don't use autonomous agents." It means: never run one with ambient credentials on a machine you care about. The agent belongs in a box with a hard wall around it. Hard problem #2 — Persistence and continuity Real agent work is long. Refactoring a codebase, researching across dozens of pages, building-testing-deploying an app — these take minutes to hours, far past a single request/response. So the runtime needs durable sessions, a place to keep state, and a workspace that survives across steps. But a persistent workspace that is reused creates its own hazard: state leakage. Files from yesterday's task can contaminate — or get shipped inside — today's result. Continuity and cleanliness pull in opposite directions, and you have to engineer the tension out. One agent is a demo; production is a fleet A single monolithic agent asked to "gather requirements, write the code, test it, deploy it, and package it" will do all four mediocrely and blur the boundaries between them. The production pattern is orchestrator-worker: specialized agents, each with one job, handing off to the next through explicit gates. OpenClaw supports exactly this — it can spawn sub-agents and even dispatch external coding harnesses, acting as a meta-orchestrator rather than a single model. The open question is never whether to go multi-agent; it's where the seams and the guardrails go. The answer to "is it safe?": put the agent in a microVM If the agent needs root to be useful, then give it root — inside a disposable microVM, not on your host. In 2026 there are several credible ways to do this: Kata Containers on AKS — each pod gets its own lightweight VM boundary and guest kernel. Hyperlight Wasm — per-call, snapshot-restored Wasm microVMs for running LLM-generated code. Azure Container Apps dynamic sessions — prewarmed, Hyper-V-isolated sandboxes that start in milliseconds, scale to thousands, and are purpose-built for "secure execution of custom code" and "running LLM-generated scripts." That last one — the ACA sandbox — is the sweet spot for a chat-driven agent factory: strong isolation without you operating a Kubernetes cluster, and an exec API to run commands inside the box. It's what the reference implementation uses. Part 2 — Putting OpenClaw into the ACA sandbox Here is where the repo stops being a diagram and becomes running code. The Agentic Prototype Factory decomposes the "idea → live app" job into five specialized OpenClaw agents that run in sequence, all inside the sandbox: requirements → coding → testing → deployment → save Each is addressable as its own model target on the OpenClaw gateway's OpenAI-compatible API: model value Routes to openclaw / openclaw/default Default agent openclaw/requirements-agent Requirement Agent openclaw/coding-agent Coding Agent openclaw/testing-agent Testing Agent openclaw/deployment-agent Deployment Agent openclaw/save-agent Save & download Agent Control, not vibes: review gates with feedback loops Autonomy without gates is how you get an agent that confidently deploys a broken app. The orchestrator wires the five agents into a graph with hard, bounded gates: Every knob is explicit and lives in server.py: _MAX_TEST_ROUNDS = 3, _MAX_DEPLOY_REVIEW = 2, _DEPLOY_POLL_ATTEMPTS = 12, _DEPLOY_POLL_DELAY_S = 20. The Testing Agent must end each turn with a literal TESTS_PASSED / TESTS_FAILED verdict; the orchestrator won't declare success until it HTTP-checks the deployed URL and inspects the response body — because a ResourceNotFound can happily return an HTTP 200. That is what "flexible and controllable" looks like in practice: the LLM drives creatively inside a deterministic state machine. The deterministic pre-run wipe (solving state leakage) Because the sandbox is reused across runs (fast, cheap), the orchestrator does something disciplined before every run: it wipes all lingering agent workspaces. Stale files from a previous task can never leak into — or be packaged as — the new result. This is the engineered answer to Hard Problem #2. Working with the sandbox's limits, not against them The ACA sandbox exec API is hard-capped at ~120 seconds — shorter than a cold az acr build plus az containerapp create. A naive agent would time out and report failure. The clever bit: those commands finish server-side on Azure even after the client exec disconnects. So deployment is split in two: deploy-build <dir> <app> — installs the deploy helpers, writes a tight .dockerignore, and kicks off the ACR build tagged <app>:latest. If the client drops at ~120s, the image still lands in ACR. deploy-finish <app> — idempotent, polled up to 12×. It reports STILL_BUILDING until the image exists, then fires a --no-wait containerapp create, and finally returns DEPLOYED_URL=https://<fqdn>. This is the single most important lesson of the whole sample: an autonomous agent doesn't need a longer timeout — it needs to understand the durability semantics of the platform it runs on. Part 3 — MCP, and why its security is the whole ballgame The five-agent workflow is powerful, but it would be a silo if the only way to reach it were a bespoke API. Instead, the repo wraps the entire orchestration as a Model Context Protocol (MCP) service (acamcp_node) exposed over streamable HTTP at /mcp, with a tiny, legible tool surface: MCP tool What it does generate_prototype Run the full five-agent workflow end to end run_agent Invoke a single named agent check_gateway_health Liveness / readiness of the OpenClaw gateway The payoff is enormous: any MCP client can now drive the factory — GitHub Copilot, Claude, or the Teams bot we're about to meet. One protocol, many front-ends. But MCP is not just an integration convenience — it's a control plane, and every MCP tool is a privileged capability. In an ecosystem with 32,000+ community servers, "just add an MCP server" is a supply-chain decision. A tool call is code execution by another name. So the security posture has to be deliberate. Here is how the reference implementation hardens it — and the principles are portable to any MCP deployment: Auth in front of the protocol. The MCP ingress sits behind basic auth (MCP_BASIC_AUTH_PASSWORD); the gateway itself requires the gateway token as a bearer credential (Authorization: Bearer <token>). No anonymous tool calls. A tiny, named allowlist — not a blank check. The gateway routes only to six explicit model targets. There is no "run arbitrary agent" escape hatch; the routing table is the allowlist. No secrets in the workload. There are no model API keys anywhere in the running containers — model access is brokered entirely through Entra ID managed identities. The gateway token is stored as a Kubernetes secret and never baked into an image. Private by default. The gateway's OpenAI-compatible endpoint is operator-level access — it stays on private ingress, with TLS and authentication added before anything is ever exposed publicly. Least privilege at the identity layer. The gateway is granted exactly the Foundry roles it needs (Cognitive Services User / Cognitive Services OpenAI User) on the Foundry resource — nothing more. The takeaway for MCP is the same as for the agent itself: treat the protocol as a doorway, and put a guard on the door. Authentication, an explicit allowlist, private ingress, and brokered identity turn MCP from an open blast radius into a governed control plane. Part 4 — The complete solution: Teams + MCP on ACA + OpenClaw on the ACA sandbox Now assemble the three deployable components into one loop: The request lifecycle, end to end A PM sends one sentence in Teams. The teamsbot_app bot — acting as an MCP client via mcpClient.ts — opens an MCP handshake and calls generate_prototype. The MCP service on ACA (acamcp_node) runs the orchestrator: pre-run wipe, then requirements → coding → testing. The OpenClaw gateway in the ACA sandbox (acasbxapp_node) executes each agent, talking to Foundry gpt-5.5 through a managed identity — no keys in the box. Real pytest + Jest suites run inside the sandbox. Fail → loop back (bounded). Pass → deploy. Deployment uses the build + poll split to survive the ~120s exec cap; the app lands in Azure Container Apps and is health-checked body-aware at its live URL. The Save Agent produces an authenticated ZIP download URL. The bot streams each agent's progress back into the Teams thread and returns the running HTTPS URL + source ZIP — optionally auto-opening the project in VS Code Insiders. How the architecture answers the three questions The question How this solution answers it Is it safe? The autonomous agent runs in a Hyper-V-isolated ACA sandbox, not on anyone's laptop. No model keys in the workload — Entra ID managed identity brokers Foundry. MCP behind basic auth; gateway behind a bearer token on private ingress; token as a secret, never in an image. A deterministic pre-run wipe removes cross-run leakage. Does it fit multi-agent work? It is a multi-agent system — five specialist OpenClaw agents with A2A hand-offs and review gates — and because it's exposed via MCP, any client (Copilot, Claude, Teams) can orchestrate it. Is it flexible and controllable? Creativity lives inside a deterministic state machine: explicit TESTS_PASSED/FAILED verdicts, bounded retry loops (_MAX_TEST_ROUNDS, _MAX_DEPLOY_REVIEW), body-aware health checks, and a human approving in the Teams thread. Deploy it yourself The repo ships scripts for all three tiers (the gateway uses the platform's managed identity to reach Foundry — no key handling, no image rebuild): # 1) OpenClaw gateway + the 5 agents (acasbxapp_node) cd acasbxapp_node cp .env.example .env # gateway token, Foundry endpoint, sandbox ids ./scripts/build-openclaw-image.sh # build + push the OpenClaw image to ACR ./scripts/deploy-aks-gateway.sh # grant Foundry roles + deploy # 2) MCP service (acamcp_node) cd ../acamcp_node cp .env.example .env # ACR + cluster; gateway token read from ../acasbxapp_node/.env ./scripts/build-images.sh # build + push the MCP image ./scripts/deploy-aks.sh # secret + manifests to the openclaw namespace ./scripts/smoke-check.sh # verify the MCP handshake # 3) Teams bot (teamsbot_app) — Node.js/TypeScript MCP client cd ../teamsbot_app # configure + run per the folder README, then sideload the Teams app package The reference implementation targets Azure (ACA + AKS) — the OpenClaw gateway and MCP service run as containers, and the code-execution sandbox uses the ACA dynamic-sessions exec API. Keep the gateway on private ingress and add TLS before any public exposure. Final thought Strip away the World Cup demo and a reusable pattern remains — a blueprint for running any long-running autonomous agent in the enterprise: A message-driven agent (OpenClaw / Hermes) + a microVM sandbox (Azure Container Apps dynamic sessions) + an MCP control plane with auth + enterprise identity (Entra ID managed identity) + a human surface (Microsoft Teams). The autonomy that made these agents go viral is the same autonomy that makes security teams nervous. You don't resolve that tension by slowing the agent down — you resolve it by giving it a box with a hard wall, a control plane with a guard on the door, an identity instead of a secret, and a human in the loop. Do that, and "your PM types a sentence, Azure ships an app" stops being a scary demo and becomes something you can actually put in production. Clone it, break it, harden it further: kinfey/Multi-AI-Agents-Cloud-Native → code/CustomCodingAgentApp The chat window is the new terminal. Let's make it a safe one.1.8KViews2likes0CommentsClaude Code on Microsoft Foundry in VS Code — A Practical Setup Guide (with the gotchas)
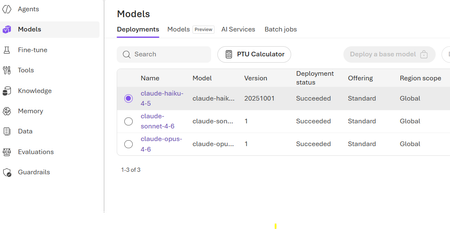
Enables enterprise-grade governance without changing your developer workflow. The official Microsoft Learn article (Configure Claude Code for Microsoft Foundry) gets you ~80% of the way there. The remaining 20%—VS Code settings shape, tenant mismatches, and configuration conflicts like "baseURL and resource are mutually exclusive"—is where most setups fail in practice. This guide walks the full path end-to-end, with the exact JSON that validates, working CLI configuration, and a troubleshooting matrix based on real-world failures. This guidance is based on repeated customer deployments and internal testing across both CLI and VS Code scenarios. TL;DR Setup - Deploy claude-sonnet-4-6 (optionally Haiku + Opus) in a supported region - Grant Cognitive Services User + Foundry User - az login --tenant <tenant> , then launch VS Code via code . Config - CLI: - CLAUDE_CODE_USE_FOUNDRY=1 - ANTHROPIC_FOUNDRY_RESOURCE=<name> - Do NOT set ANTHROPIC_FOUNDRY_BASE_URL at the same time - VS Code: - Use [{ "name": "...", "value": "..." }] format Validate - claude → /status - Expect: API provider: Microsoft Foundry Why run Claude Code on Foundry? Anthropic's Claude Code is a top-tier agentic coding assistant. Running it through Microsoft Foundry instead of Anthropic's public API gives you: Data residency & compliance: prompts and completions stay inside your Azure tenant. Entra ID auth: no API keys to rotate; centralized RBAC. Private networking: works behind VNets/Private Endpoints. Unified billing & quotas: usage shows up on your Azure invoice and in Foundry monitoring. Same model, same CLI, enterprise-grade plumbing underneath. Prerequisites checklist Requirement How to verify Azure subscription with pay-as-you-go billing az account show Foundry resource in supported regions Check your region's model availability in Foundry portal Contributor/Owner on the resource group (for deployments) Azure Portal → IAM Cognitive Services User + Foundry User on the resource (for invoking) Azure Portal → IAM Azure CLI installed and logged in az --version , az login Claude Code CLI installed claude --version VS Code (current) with the Anthropic Claude Code extension Help → About Windows only: Git Bash (from Git for Windows) or WSL2 — Claude Code's runtime requires a POSIX shell bash --version in Git Bash / WSL ⚠️ Claude models in Foundry are currently available in select regions. Check the Foundry portal model catalog for your region's availability (commonly East US 2 and Sweden Central). Step 1 — Deploy the Claude models Claude Code uses three model roles, and it expects a deployment for each: Role Default deployment name Used for Primary claude-sonnet-4-6 general coding (balanced) Fast claude-haiku-4-5 quick edits, file reads Extended thinking claude-opus-4-6 complex reasoning Deploy at least Sonnet to get started. Add Haiku and Opus when you need them — Claude Code will route automatically. If a role-specific model isn't deployed, Claude Code may fall back or fail depending on the task. Deployment names in this guide follow the current Claude 4.x naming exposed in Foundry. Exact versions change over time — check the Foundry model catalog in your region for what's currently available. Foundry Portal: AI Foundry → your project → Build → Models + endpoints → + Deploy model → pick the Anthropic Claude model → Global Standard deployment → name it exactly as above (or remember the name to override later). To discover the current model version before deploying (replace eastus2 with your Foundry region): az cognitiveservices model list -l eastus2 ` --query "[?contains(model.name,'claude')].{name:model.name, version:model.version, format:model.format}" -o table Azure CLI: az cognitiveservices account deployment create ` --name <foundry-resource> ` --resource-group <rg> ` --deployment-name claude-sonnet-4-6 ` --model-name claude-sonnet-4-6 ` --model-version <version> ` --model-format Anthropic ` --sku-name GlobalStandard ` --sku-capacity 1 ✍️ Figure 1: Foundry portal “Models + endpoints” showing the three Claude deployments. Step 2 — Grant yourself the right roles This is the #1 source of silent failures. You need both: Role Role ID Purpose Cognitive Services User a97b65f3-24c7-4388-baec-2e87135dc908 data-plane invocation Foundry User (formerly Azure AI User) 53ca6127-db72-4b80-b1b0-d745d6d5456d Foundry-native permissions $me = az ad signed-in-user show --query id -o tsv $scope = az cognitiveservices account show -n <foundry-resource> -g <rg> --query id -o tsv # Use role IDs — rename-proof (works whether the display name is "Azure AI User" or "Foundry User") az role assignment create --assignee $me --role a97b65f3-24c7-4388-baec-2e87135dc908 --scope $scope # Cognitive Services User az role assignment create --assignee $me --role 53ca6127-db72-4b80-b1b0-d745d6d5456d --scope $scope # Foundry User (formerly Azure AI User) The Foundry RBAC rename (Azure AI User → Foundry User) is rolling out; both role names map to the same role definition (same role ID), depending on tenant rollout state. Use whichever role name your tenant exposes — or use the role IDs above to avoid ambiguity. Step 3 — Install the Claude Code CLI Use the official installer from Anthropic (auto-updates in the background): irm https://claude.ai/install.ps1 | iex claude --version If claude isn't on PATH, restart your shell. The installer drops it under %USERPROFILE%\.local\bin . Step 4 — Sign in to the right tenant If your Foundry resource lives in a tenant different from your default, an az login to the wrong tenant produces the cryptic error: ValueError: Unable to get authority configuration for https://login.microsoftonline.com/<bad-guid>. Authority would typically be in a format of https://login.microsoftonline.com/your_tenant Fix: az login --tenant <foundry-tenant-guid> az account set --subscription <foundry-subscription-guid> az account show # confirm tenant & subscription 💡 You can list every tenant you have access to with: az account list --query "[].{name:name, tenantId:tenantId}" -o table Step 5 — Configure the CLI Set these in the same PowerShell session you'll launch claude from: $env:CLAUDE_CODE_USE_FOUNDRY = "1" $env:ANTHROPIC_FOUNDRY_RESOURCE = "<your-foundry-resource-name>" # Optional: only if your deployment names differ from the defaults $env:ANTHROPIC_DEFAULT_SONNET_MODEL = "claude-sonnet-4-6" $env:ANTHROPIC_DEFAULT_HAIKU_MODEL = "claude-haiku-4-5" $env:ANTHROPIC_DEFAULT_OPUS_MODEL = "claude-opus-4-6" To make them persistent: setx CLAUDE_CODE_USE_FOUNDRY 1 (and so on), then sign out and back in (or restart Explorer). GUI apps like VS Code launched from the Start menu only pick up new user-env vars after the user session refreshes — opening a fresh terminal isn't enough. 🚫 The "mutually exclusive" trap API Error: baseURL and resource are mutually exclusive You'll hit this if you set both ANTHROPIC_FOUNDRY_RESOURCE and ANTHROPIC_FOUNDRY_BASE_URL . Pick one: Most users → ANTHROPIC_FOUNDRY_RESOURCE=<name> (Claude Code builds the URL). Custom subdomain / private endpoint → use ANTHROPIC_FOUNDRY_BASE_URL instead. Step 6 — Verify the CLI claude > /status Expected output: API provider: Microsoft Foundry Microsoft Foundry base URL: https://<resource>.services.ai.azure.com/anthropic Microsoft Foundry resource: <resource> Model: Default (claude-sonnet-4-6) ✍️ Figure 2: /status output confirming API provider: Microsoft Foundry . If you instead see "Anthropic" or it prompts for an Anthropic login, CLAUDE_CODE_USE_FOUNDRY isn't being inherited — see troubleshooting below. Step 7 — Configure the VS Code extension Install Claude Code from the VS Code Marketplace (publisher: Anthropic). Open user settings.json ( Ctrl+Shift+P → Preferences: Open User Settings (JSON)) and add: "claudeCode.environmentVariables": [ { "name": "CLAUDE_CODE_USE_FOUNDRY", "value": "1" }, { "name": "ANTHROPIC_FOUNDRY_RESOURCE", "value": "<your-foundry-resource-name>" } ] 🪤 Schema gotcha. The MS Learn doc currently shows this as a plain {KEY: VALUE} object under the UI label "Claude Code: Environment Variables" . In recent extension versions the actual JSON key is claudeCode.environmentVariables and the value must be an array of {name, value} objects. If you paste the doc's snippet verbatim, VS Code will flag "Missing property name", "Colon expected", "Unknown configuration setting". Use the array form above. Make the extension see your az login The extension inherits environment & credentials from the process that launches VS Code. After az login : # In the same PowerShell where az login succeeded: code . If VS Code was already running, fully quit it (not just close the window) and relaunch from the terminal. Developer: Reload Window is not enough to refresh inherited Azure CLI credentials. ✍️ Figure 3: settings.json with the claudeCode.environmentVariables array form. Step 8 — Try it In VS Code, click the Claude Code (Spark) icon in the sidebar to open the panel. Type: Summarize the structure of this project. You should get a response within a few seconds, and the panel should indicate it's routing through Microsoft Foundry. Run /status inside the panel to confirm API provider: Microsoft Foundry if you want certainty. ✍️ Figure 4: Claude Code panel in VS Code responding through Microsoft Foundry. Troubleshooting matrix Symptom Where it shows up Likely cause Fix API Error: baseURL and resource are mutually exclusive claude CLI on first request Both ANTHROPIC_FOUNDRY_BASE_URL and ANTHROPIC_FOUNDRY_RESOURCE set Unset one. Prefer ANTHROPIC_FOUNDRY_RESOURCE . Unable to get authority configuration for https://login.microsoftonline.com/<guid> claude CLI startup or VS Code panel Wrong tenant ID in az login az login --tenant <correct-guid> ; verify with az account show Failed to get token from azureADTokenProvider: ChainedTokenCredential authentication failed VS Code Claude Code panel Extension didn't inherit az login session Quit VS Code entirely; relaunch with code . from the authed shell Token tenant does not match resource tenant claude CLI or VS Code panel CLI logged into a different tenant than the Foundry resource az login --tenant <foundry-tenant> The model <name> is not available on your foundry deployment claude CLI first use or VS Code model selector Deployment name mismatch Either rename the Foundry deployment, or set ANTHROPIC_DEFAULT_*_MODEL to the actual name 401 / 403 on first request claude CLI or VS Code panel Missing RBAC on the resource Assign Cognitive Services User and Foundry User on the resource scope Claude Code prompts for Anthropic login VS Code Claude Code panel CLAUDE_CODE_USE_FOUNDRY not set in the process Set the env var before launching claude / code . VS Code shows "Unknown Configuration Setting" for claudeCode.environmentVariables VS Code Settings tab Wrong JSON shape Use the array of {name,value} objects form 429 Too Many Requests claude CLI or VS Code panel TPM/RPM exhausted Foundry portal → Operate → Quotas; request increase or reduce parallelism Works in CLI, fails in VS Code extension VS Code Claude Code panel only Env vars set per-shell, not visible to GUI VS Code Use setx (persistent user env) or move them into claudeCode.environmentVariables "Model is not available in region" Foundry portal model deployment step Foundry resource not in a supported region Deploy a new Foundry resource in a supported region, or check model availability Best practices Auth & secrets - Prefer Entra ID over API keys. If you must use a key for CI, store it as a secret (GitHub Actions secret, Key Vault) — never in settings.json (it may sync via Settings Sync). - Scope RBAC at the resource level, not the subscription, for least privilege. Project context - Create a CLAUDE.md at your repo root with stack, conventions, and entry-point commands. Claude Code reads it automatically and the quality jump is significant. - Use .claude/rules/*.md for per-area rules (e.g., test conventions, security rules). Cost & latency - Let Claude Code's auto-routing pick the right role (Sonnet/Haiku/Opus). Don't pin everything to Opus. - Cap context with ANTHROPIC_MAX_TOKENS if you have a strict budget. (Note: not honored by every Claude Code version — check the Claude Code docs for your version.) - Watch token spend in Foundry → Operate → Metrics weekly. Reliability - For team use, deploy all three model roles even if you don't think you need them — silent role-routing failures are confusing. - Tag your Foundry resource ( env=dev|prod , team=... ) for chargeback. Reproducibility - Document the exact env vars and az login --tenant GUID in your team README. - Pin Claude Code CLI version in onboarding docs ( claude --version ) so new joiners hit the same behavior. A note on the MS Learn doc The doc is accurate but skips three things that caused the most friction in real-world deployments: VS Code extension settings shape — the example uses the UI label as a JSON key and an object instead of the array form the schema actually expects. Process inheritance — it says "set the env vars" but doesn't emphasize that the VS Code window must be launched from a shell where both az login and the env vars are live. Reloading the window doesn't help. Mutually exclusive RESOURCE vs BASE_URL — listed in passing, but the error message only appears at first request, after you think everything is configured. If the Microsoft Learn page is updated, treat this post as a companion — same destination, fewer dead ends. What you've got now Claude Code running locally on your machine, talking to your Foundry resource. Entra ID auth — no API keys to manage. Full Foundry telemetry, quotas, and billing. VS Code panel + CLI, both backed by the same setup. Drop a CLAUDE.md in your repo and start shipping. When to Use RESOURCE vs BASE_URL Use RESOURCE (default) - Standard public deployments - No custom networking Use BASE_URL - Private endpoints - Custom DNS / VNet routing Never set both.1.6KViews0likes0CommentsInfrastructure as Code for AI: Building and Deploying Microsoft Hosted Agents with Terraform
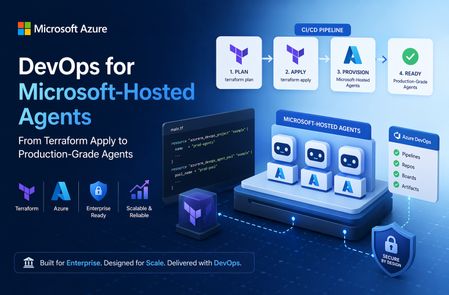
AI agents are no longer experimental. Teams are shipping production-grade agents that retrieve information, call APIs, reason over documents, and orchestrate multi-step workflows at scale. Microsoft Foundry's Hosted Agents service gives you a fully managed runtime for those agents, built on top of the Microsoft Foundry Agent Service, with Microsoft handling the infrastructure, scaling, and runtime lifecycle. The challenge is that provisioning this infrastructure by hand or clicking through the portal, running one-off CLI commands, or relying on undocumented shell scripts, simply does not scale. It introduces configuration drift, makes reproducing environments painful, and creates real governance risk as teams grow. This post walks through how to provision and manage the Azure infrastructure required to run Microsoft Hosted Agents using Terraform. You will leave with working configuration, a clear understanding of the resource model, and practical guidance on where Terraform can take you all the way and where you will need to supplement with the Azure CLI or the Microsoft Foundry Agent Service SDK. What Are Microsoft Hosted Agents? Microsoft Hosted Agents are AI agents deployed and managed within Microsoft Foundry. Microsoft Foundry is Microsoft's unified platform for building, evaluating, and deploying AI applications and agents. It provides: A managed compute runtime — Microsoft provisions and scales the infrastructure so you do not manage VMs or containers. An agent execution environment — agents are defined with instructions, tools (code interpreter, Bing grounding, Azure AI Search, function calling), and a backing model endpoint. Deep Azure integration — identity via Microsoft Entra ID, secrets via Azure Key Vault, storage via Azure Blob, tracing via Azure Monitor and Application Insights. A project-scoped model — each Microsoft Foundry project encapsulates an agent's resources, connections, and deployments within a logical boundary. The "Hosted" distinction matters. You are not running agent code on your own Kubernetes cluster or App Service. Microsoft manages the runtime. Your responsibility is to provision the surrounding infrastructure correctly: the Microsoft Foundry resource, the project, the model deployment, the identity configuration, and the monitoring resources that back it all. That boundary — the infrastructure you own — is exactly what Terraform manages well. Why Terraform for Hosted Agent Deployments? Infrastructure as Code (IaC) is not a new idea, but its importance grows as AI deployments become more complex. Here is why Terraform is a strong choice for Microsoft Foundry deployments specifically: Repeatability: A Terraform configuration produces the same infrastructure every time. Staging mirrors production. Disaster recovery is a terraform apply away. Governance: Infrastructure definitions live in version control alongside application code. Changes are reviewable, auditable, and reversible. This satisfies most enterprise change-management requirements. Scale: Spinning up per-customer or per-team agent environments using Terraform workspaces or module instantiation is far more manageable than manual provisioning. State management: Terraform tracks the actual state of your Azure resources. It detects drift and reconciles it declaratively. Ecosystem: The AzureRM provider is mature, actively maintained by HashiCorp and Microsoft, and covers the majority of Azure services including the Microsoft Foundry resources. Architecture Overview Before writing any Terraform, it helps to understand the resource hierarchy in Microsoft Foundry and how each layer maps to an Azure resource type. The Foundry Resource Hierarchy Microsoft Foundry uses a two-level hierarchy: 1. Foundry Account ( azurerm_cognitive_account , kind: AIServices ) — The top-level AI Services resource. It provides the model endpoint, manages agent execution, and acts as the logical boundary for all projects beneath it. You must set project_management_enabled = true and provide a custom_subdomain_name to enable project creation. In ARM terms this is a Microsoft.CognitiveServices/accounts resource. 2. Foundry Project ( azurerm_cognitive_account_project ) — A child resource scoped within the Foundry Account. Each project has its own agents, model deployments, connections, and data assets. In production, you typically have one project per application, product team, or environment. Figure 1: The Microsoft Foundry resource hierarchy. A single Foundry Account (Cognitive Services, kind AIServices) acts as the top-level container, with Projects scoped beneath it — one per application, team, or environment. Supporting Resources The following Azure resources make up a complete Hosted Agents deployment: Microsoft Foundry Account (AI Services): A single azurerm_cognitive_account of kind AIServices serves as both the Foundry Account and the model endpoint host. Model deployments (e.g. gpt-4.1 ) are provisioned via azurerm_cognitive_deployment within this account. Log Analytics Workspace + Application Insights: Provides observability for agent traces, request logs, and metrics. User-Assigned Managed Identity: Grants the Foundry Account and Projects access to Azure resources without stored credentials. Role Assignments (RBAC): Wires the managed identity to the Foundry Account with least-privilege Cognitive Services permissions. Figure 2: Supporting infrastructure map. The managed identity holds least-privilege RBAC grants to the Microsoft Foundry Account (AI Services) — enabling model access and project management — all within the same resource group. Reference Architecture (Described) A production-ready layout separates concerns across two resource groups: one for shared infrastructure (networking, monitoring) and one for the Microsoft Foundry Account and its projects. The Foundry resource group houses the azurerm_cognitive_account (kind: AIServices) resource and the azurerm_cognitive_account_project instances. The shared resource group holds Log Analytics and Application Insights. A user-assigned managed identity spans both, holding RBAC grants to each backing service. For a dev/test environment you can collapse both into a single resource group. For production, the separation makes cost attribution, access control, and lifecycle management cleaner. Prerequisites Accounts and Permissions An active Azure subscription with the Owner or Contributor + User Access Administrator roles at the subscription or resource group level (role assignments require elevated permission). Foundry access enabled in your subscription. In some tenants you may need to accept terms or request quota for Azure OpenAI. Azure OpenAI quota for the model you intend to deploy (e.g. gpt-4.1 ). Request this via the Azure portal under Quotas in Azure OpenAI Studio. Local Tools Terraform CLI ≥ 1.9 — Install guide Azure CLI ≥ 2.60 — Install guide A code editor (VS Code with the HashiCorp Terraform extension and the Azure Terraform extension is a strong combination). Authentication For local development, authenticate via the Azure CLI. The AzureRM Terraform provider picks this up automatically: az login az account set --subscription "<your-subscription-id>" For CI/CD pipelines, use a service principal with AZURE_CLIENT_ID , AZURE_CLIENT_SECRET , AZURE_TENANT_ID , and AZURE_SUBSCRIPTION_ID environment variables, or — preferably — a workload identity federation (federated credentials) to avoid storing long-lived secrets. GitHub Actions supports OIDC-based workload identity natively. Terraform Fundamentals for Hosted Agents Provider Configuration The hashicorp/azurerm provider is your primary dependency. The new Microsoft Foundry resources ( azurerm_cognitive_account with kind = "AIServices" and azurerm_cognitive_account_project ) require version 4.x of the provider. Pin your version to avoid unexpected breaking changes: terraform { required_version = ">= 1.9" required_providers { azurerm = { source = "hashicorp/azurerm" version = "~> 4.0" } } } provider "azurerm" { features { key_vault { purge_soft_delete_on_destroy = false } resource_group { prevent_deletion_if_contains_resources = true } } subscription_id = var.subscription_id } The features block is required even when empty. The Key Vault setting prevents accidental secret loss during terraform destroy . The resource group setting adds an extra safety net in production. State Management Never use local state for shared or production environments. Store state in Azure Blob Storage with state locking via Azure Blob lease: terraform { backend "azurerm" { resource_group_name = "rg-terraform-state" storage_account_name = "sttfstate<unique>" container_name = "tfstate" key = "ai-agents/prod.tfstate" } } Create the state storage account and container before running terraform init . A bootstrap script or a separate Terraform workspace dedicated to state management are both valid approaches. Known Limitations and Workarounds Terraform coverage of Foundry is improving rapidly but is not yet complete. You should be aware of the following gaps as of mid-2025: Agent definitions are not in Terraform: The actual agent (its system prompt, instructions, tool configuration, and model binding) is created via the Azure AI Agent Service SDK or the Foundry portal, not via Terraform. Terraform provisions the infrastructure; your application code or a post-provisioning script creates the agent. Connections: Some connection types within a Foundry Project (e.g. Azure AI Search, custom connections) may require the Azure CLI or the Foundry SDK. Verify coverage in the AzureRM provider docs before assuming Terraform handles them. Model deployments: azurerm_cognitive_deployment covers OpenAI model deployments and is well-supported. Use this to deploy your model before referencing it from the agent. Private networking: If you need private endpoints for your Foundry Account, additional VNet, subnet, and DNS zone resources are required. This post focuses on the public networking path; private networking is a follow-on topic. Step-by-Step Implementation The following sections build up a complete Terraform configuration. The recommended project structure is a flat module layout for a single environment, with a separate modules/ai-foundry/ directory when you need to reuse the pattern across environments. ai-agents-infra/ ├── main.tf ├── variables.tf ├── outputs.tf ├── versions.tf └── terraform.tfvars 1. Variables Define variables first. Parameterising from the start avoids hard-coded values that create technical debt when you replicate the configuration for staging or production: # variables.tf variable "subscription_id" { type = string description = "Azure subscription ID." } variable "location" { type = string default = "eastus" description = "Azure region for all resources." } variable "environment" { type = string default = "dev" description = "Environment label (dev, staging, prod)." } variable "project_name" { type = string description = "Short name for the project. Used in resource naming." } variable "openai_model_name" { type = string default = "gpt-4.1" description = "Azure OpenAI model to deploy for the agent." } variable "openai_model_version" { type = string default = "2025-04-14" description = "Model version to deploy." } variable "openai_sku_capacity" { type = number default = 10 description = "Tokens-per-minute capacity (in thousands) for the deployment." } 2. Resource Group and Core Infrastructure A single resource group keeps things simple for dev. In production, consider splitting as described in the architecture section above. # main.tf — Resource group and naming locals locals { name_prefix = "${var.project_name}-${var.environment}" tags = { environment = var.environment project = var.project_name managed_by = "terraform" } } resource "azurerm_resource_group" "main" { name = "rg-${local.name_prefix}" location = var.location tags = local.tags } 3. Supporting Services Provision Log Analytics and Application Insights for agent observability and diagnostics. Unlike the legacy Hub-based architecture, the azurerm_cognitive_account (kind AIServices ) does not require a dedicated Storage Account or Key Vault as provisioning dependencies. # main.tf — Monitoring infrastructure data "azurerm_client_config" "current" {} # Log Analytics Workspace (required by Application Insights) resource "azurerm_log_analytics_workspace" "main" { name = "law-${local.name_prefix}" resource_group_name = azurerm_resource_group.main.name location = azurerm_resource_group.main.location sku = "PerGB2018" retention_in_days = 30 tags = local.tags } # Application Insights for agent observability resource "azurerm_application_insights" "main" { name = "appi-${local.name_prefix}" resource_group_name = azurerm_resource_group.main.name location = azurerm_resource_group.main.location workspace_id = azurerm_log_analytics_workspace.main.id application_type = "web" tags = local.tags } 4. User-Assigned Managed Identity A managed identity allows the Foundry Account and its projects to authenticate to Azure services without stored credentials. This is a security best practice and is required for several Microsoft Foundry features. # main.tf — Managed identity for the Microsoft Foundry Account resource "azurerm_user_assigned_identity" "foundry" { name = "id-${local.name_prefix}-foundry" resource_group_name = azurerm_resource_group.main.name location = azurerm_resource_group.main.location tags = local.tags } 5. Microsoft Foundry Account and Model Deployment In the current Microsoft Foundry architecture, a single azurerm_cognitive_account of kind AIServices serves as both the Foundry Account and the model endpoint host. Set project_management_enabled = true and provide a globally unique custom_subdomain_name to enable Foundry Project creation beneath it. # main.tf — Microsoft Foundry Account (AI Services) resource "azurerm_cognitive_account" "foundry" { name = "aisa-${local.name_prefix}" resource_group_name = azurerm_resource_group.main.name location = azurerm_resource_group.main.location kind = "AIServices" sku_name = "S0" project_management_enabled = true custom_subdomain_name = "${replace(local.name_prefix, "-", "")}foundry" tags = local.tags identity { type = "UserAssigned" identity_ids = [azurerm_user_assigned_identity.foundry.id] } } # Deploy the model within the Foundry Account resource "azurerm_cognitive_deployment" "agent_model" { name = var.openai_model_name cognitive_account_id = azurerm_cognitive_account.foundry.id model { format = "OpenAI" name = var.openai_model_name version = var.openai_model_version } sku { name = "Standard" capacity = var.openai_sku_capacity } } Note on quota: The capacity value is in thousands of tokens per minute. A value of 10 means 10,000 TPM. If terraform apply fails with a quota error, reduce this value or request a quota increase via the Azure portal. Note on custom_subdomain_name : This must be globally unique across all Azure AI Services accounts. If provisioning fails with a conflict error, adjust the suffix (e.g. append a random string using the random_string resource). 6. Foundry Project Create a Foundry Project beneath the Foundry Account provisioned in Step 5. Each project scopes its own agents, model connections, and data assets. Use one project per application or team. # main.tf — Microsoft Foundry Project resource "azurerm_cognitive_account_project" "agent_project" { name = "proj-${local.name_prefix}-agents" cognitive_account_id = azurerm_cognitive_account.foundry.id location = azurerm_resource_group.main.location display_name = "Agent Project - ${var.project_name}" description = "Hosted agents project for ${var.project_name}" identity { type = "UserAssigned" identity_ids = [azurerm_user_assigned_identity.foundry.id] } tags = local.tags } 7. RBAC Role Assignments Grant the managed identity the permissions it needs. This is the area most commonly misconfigured in manual deployments. Terraform makes it explicit and auditable. # main.tf — RBAC assignments # AI Services: Foundry identity needs Cognitive Services OpenAI User to call model endpoints resource "azurerm_role_assignment" "foundry_openai" { scope = azurerm_cognitive_account.foundry.id role_definition_name = "Cognitive Services OpenAI User" principal_id = azurerm_user_assigned_identity.foundry.principal_id } # AI Services: Foundry identity needs Cognitive Services Contributor to manage projects resource "azurerm_role_assignment" "foundry_contributor" { scope = azurerm_cognitive_account.foundry.id role_definition_name = "Cognitive Services Contributor" principal_id = azurerm_user_assigned_identity.foundry.principal_id } # Optional: grant your own principal the Azure AI Developer role on the Foundry Account # so you can create and manage agents from your local machine or CI pipeline resource "azurerm_role_assignment" "developer_account" { scope = azurerm_cognitive_account.foundry.id role_definition_name = "Azure AI Developer" principal_id = data.azurerm_client_config.current.object_id } 8. Outputs Export the values your application and post-provisioning scripts will need: # outputs.tf output "resource_group_name" { value = azurerm_resource_group.main.name } output "foundry_account_id" { value = azurerm_cognitive_account.foundry.id } output "ai_foundry_project_id" { value = azurerm_cognitive_account_project.agent_project.id } output "foundry_endpoint" { value = azurerm_cognitive_account.foundry.endpoint } output "openai_deployment_name" { value = azurerm_cognitive_deployment.agent_model.name } output "managed_identity_client_id" { value = azurerm_user_assigned_identity.foundry.client_id } 10. Example terraform.tfvars # terraform.tfvars — do NOT commit this file if it contains sensitive values subscription_id = "xxxxxxxx-xxxx-xxxx-xxxx-xxxxxxxxxxxx" location = "eastus" environment = "dev" project_name = "contoso-agents" openai_model_name = "gpt-4.1" openai_model_version = "2025-04-14" openai_sku_capacity = 10 Figure 3: Terraform deployment workflow. State is stored in an Azure Blob Storage backend, enabling team collaboration and preventing concurrent apply conflicts. Deploying and Validating the Agent Infrastructure Running the Deployment # 1. Initialise — downloads provider plugins and configures the backend terraform init # 2. Validate syntax and configuration terraform validate # 3. Preview what will be created (review carefully before applying) terraform plan -out=tfplan # 4. Apply the plan terraform apply tfplan A full initial apply typically takes 8–15 minutes. The Foundry Account (AI Services) provisioning is the longest step. The model deployment may also take a few minutes to reach a ready state — Terraform handles this with implicit dependency ordering, but you may see brief retries in the output. Verifying the Deployment After apply completes, verify each resource is in a healthy state: # Confirm the resource group and its resources exist az resource list --resource-group "rg-contoso-agents-dev" --output table # Check the Foundry Account (AI Services) is in a Succeeded state az cognitiveservices account show \ --name "aisacontosoagentsdevfoundry" \ --resource-group "rg-contoso-agents-dev" \ --query "properties.provisioningState" # Confirm the model deployment is ready az cognitiveservices account deployment show \ --resource-group "rg-contoso-agents-dev" \ --name "aisacontosoagentsdevfoundry" \ --deployment-name "gpt-4.1" \ --query "properties.provisioningState" Navigate to the Microsoft Foundry portal and confirm your Foundry Account and Project appear. At this point you can create an agent manually in the portal to validate that the model endpoint is reachable and the identity chain works correctly before automating agent creation. Common Deployment Issues Quota exceeded on model deployment: Reduce openai_sku_capacity or request a quota increase in the Azure portal under Azure OpenAI → Quotas. Resource name conflicts: The custom_subdomain_name on the Foundry Account must be globally unique. Use the random_string Terraform resource to append a unique suffix if needed. Role assignment propagation delay: RBAC changes can take 1–2 minutes to propagate. If the Foundry Account cannot access resources immediately after apply, wait a moment and retry. project_management_enabled not set: If azurerm_cognitive_account_project fails with an error about project management, ensure project_management_enabled = true and custom_subdomain_name are set on the parent azurerm_cognitive_account . azurerm_cognitive_account_project not found: Ensure your AzureRM provider version is ~> 4.0 or later. Run terraform init -upgrade if you previously initialised with an older version. Creating an Agent After Infrastructure Provisioning Terraform has provisioned the platform. Now you need to create the agent itself. This is done via the Azure AI Agents SDK (available for Python, C#, JavaScript, and Java) or the Foundry portal. The following Python snippet demonstrates creating a basic agent programmatically after Terraform apply. It uses the outputs from Terraform directly: import os from azure.ai.projects import AIProjectClient from azure.identity import DefaultAzureCredential # These values come from Terraform outputs project_connection_string = os.environ["AI_PROJECT_CONNECTION_STRING"] model_deployment = os.environ["OPENAI_DEPLOYMENT_NAME"] client = AIProjectClient.from_connection_string( credential=DefaultAzureCredential(), conn_str=project_connection_string, ) # Create the hosted agent agent = client.agents.create_agent( model=model_deployment, name="customer-support-agent", instructions=( "You are a helpful customer support assistant. " "Answer questions accurately and concisely. " "If you are unsure, say so rather than guessing." ), ) print(f"Agent created: {agent.id}") Figure 5: Agent runtime architecture. The Foundry Project hosts the Agent Service, which routes requests to the GPT-4.1 model endpoint and optionally invokes tool integrations (Code Interpreter, File Search, Azure Functions, or custom tools). The project connection string is available from the Foundry portal (Project → Overview → Project connection string) or can be constructed from Terraform outputs. Refer to the Azure AI Agents quickstart for the full SDK setup. Operational Considerations Lifecycle Management Terraform's declarative model means updates are incremental by default. To update the OpenAI model version, change openai_model_version in your .tfvars file and run terraform plan to confirm the change before applying. Terraform will delete and recreate the cognitive deployment in-place — be aware this causes brief downtime for the model endpoint. To destroy a complete environment: terraform destroy The prevent_deletion_if_contains_resources feature on the resource group will block destruction if any untracked resources exist, which is a useful safety net in production. Handling Configuration Drift Drift occurs when Azure resources are modified outside of Terraform (portal changes, CLI scripts, other automation). Detect drift with: terraform plan -refresh-only This reports the difference between the Terraform state and the actual resource state without making changes. Schedule this as a drift-detection job in CI to catch out-of-band changes early. Environment Isolation Use Terraform workspaces or separate state files per environment: # Create and switch to a staging workspace terraform workspace new staging terraform workspace select staging terraform apply -var-file="environments/staging.tfvars" Alternatively, use a directory-per-environment layout ( environments/dev/ , environments/prod/ ) with a shared module in modules/ai-foundry/ . The directory layout is more explicit and easier to navigate in a team setting. Cost Control Set a low openai_sku_capacity in dev (e.g. 1 = 1,000 TPM) to limit accidental spend. Tag all resources with environment and project tags (the locals.tags block handles this) to enable cost attribution in Azure Cost Management. Use the Azure Pricing Calculator to estimate monthly costs before deploying to production. The Azure AI Services account (model token usage), Log Analytics, and Application Insights are the primary cost drivers. Consider destroying dev environments overnight using a scheduled CI job that runs terraform destroy and terraform apply on a schedule. CI/CD Integration Automating Terraform via GitHub Actions is straightforward. The following workflow runs plan on pull requests and apply on merge to the main branch: # .github/workflows/terraform.yml name: Terraform Deploy on: push: branches: [main] pull_request: branches: [main] permissions: id-token: write # Required for OIDC workload identity federation contents: read pull-requests: write env: ARM_CLIENT_ID: ${{ secrets.AZURE_CLIENT_ID }} ARM_TENANT_ID: ${{ secrets.AZURE_TENANT_ID }} ARM_SUBSCRIPTION_ID: ${{ secrets.AZURE_SUBSCRIPTION_ID }} ARM_USE_OIDC: "true" jobs: terraform: runs-on: ubuntu-latest environment: ${{ github.ref == 'refs/heads/main' && 'production' || 'staging' }} steps: - uses: actions/checkout@v4 - uses: hashicorp/setup-terraform@v3 with: terraform_version: "~1.9" - name: Terraform Init run: terraform init - name: Terraform Plan run: terraform plan -out=tfplan -var-file="environments/dev.tfvars" - name: Terraform Apply if: github.ref == 'refs/heads/main' run: terraform apply -auto-approve tfplan Figure 4: CI/CD pipeline using GitHub Actions with OIDC workload identity federation. No long-lived secrets are stored — the runner exchanges a JWT for a short-lived Azure token before each Terraform run. Use OIDC workload identity federation to avoid storing long-lived service principal secrets in GitHub. This is the recommended authentication method for GitHub Actions deployments to Azure. Best Practices Modular Terraform Design Once you have a working flat configuration, extract the Foundry resources into a reusable module. A module boundary around the Hub, Project, OpenAI account, and RBAC assignments lets you stamp out new agent environments with a single module call and a new .tfvars file. # environments/staging/main.tf module "agent_platform" { source = "../../modules/ai-foundry" project_name = "contoso-agents" environment = "staging" location = "eastus" subscription_id = var.subscription_id openai_model_name = "gpt-4.1" openai_model_version = "2025-04-14" openai_sku_capacity = 30 } Parameterisation and Environment Configs Never hard-code subscription IDs, tenant IDs, or region names in main.tf . Keep environment-specific values in environments/<env>.tfvars files and commit them to source control (they are config, not secrets). Store actual secrets (service principal credentials, API keys for third-party connections) in Azure Key Vault or GitHub Secrets — not in .tfvars files. Versioning Models and Agent Configurations Treat your openai_model_version and agent instructions as versioned artefacts. When Microsoft releases a new model version, create a pull request that updates the variable value, runs a plan, and documents the expected change. This creates a clear history of when model versions changed and who approved the change. Logging and Monitoring Enable diagnostic settings on the Azure OpenAI account to route request logs and metrics to your Log Analytics workspace. Use Application Insights to capture agent traces from the Azure AI Agents SDK (it integrates with OpenTelemetry). Set up Azure Monitor alerts on OpenAI account errors (4xx/5xx rates) and Log Analytics ingestion failures. Responsible AI Considerations Enable Azure OpenAI content filtering on your deployment. Terraform supports this via the content_filter block in azurerm_cognitive_deployment where the policy allows. Define a clear system prompt that sets agent behaviour boundaries and instructs the agent to decline harmful requests. Log and review agent conversations during early deployment. Microsoft Foundry includes evaluation tools for assessing agent response quality and safety. Apply least-privilege RBAC throughout — the role assignments in this post follow that principle. Conclusion and Next Steps You now have a complete, repeatable Terraform configuration for provisioning the Azure infrastructure required to run Microsoft Hosted Agents via Microsoft Foundry. The key takeaways: Terraform manages the infrastructure layer effectively — the Foundry Account, Project, model deployment, identity, and RBAC. Agent definitions themselves are provisioned via the Azure AI Agents SDK or the Foundry portal as a post-Terraform step. State management, parameterisation, and modular design are non-negotiable for team environments. OIDC-based workload identity is the right authentication model for CI/CD pipelines. Drift detection, environment isolation, and cost tagging are operational necessities, not optional extras. Where to Go Next Add Azure AI Search: Extend the Foundry Project with an Azure AI Search connection and enable the Search tool on your agent for Retrieval-Augmented Generation (RAG). Private networking: Add private endpoints for the Foundry Hub and OpenAI account to lock down ingress to your VNet. Multi-region deployment: Instantiate the Terraform module twice with different regions and use Azure Traffic Manager or Front Door to route requests. GitOps for agents: Store agent definitions (system prompts, tool configurations) as YAML or JSON in your repository and use a CI pipeline to apply them via the Azure AI Agents SDK on every merge, creating a fully declarative agent deployment pipeline. Evaluation pipelines: Use Microsoft Foundry's built-in evaluation capabilities to run automated quality and safety assessments on every new model version or prompt change. References What is Microsoft Foundry? — Microsoft Learn Azure AI Agent Service overview — Microsoft Learn Azure AI Agents quickstart — Microsoft Learn azurerm_cognitive_account — Terraform Registry azurerm_cognitive_account_project — Terraform Registry azurerm_cognitive_deployment — Terraform Registry AzureRM backend — Terraform documentation OIDC workload identity federation with GitHub Actions — Microsoft Learn Azure OpenAI content filtering — Microsoft Learn Install Terraform — HashiCorp Microsoft Foundry portal1.2KViews0likes0CommentsBuilding and Operating a Microsoft Foundry Hosted Agent with GitOps and GitHub Tasks
The Gap Between Prototype and Production Most AI engineering teams can build a working agent in a day. The hard part is not building it; the hard part is operating it. Prompts drift. Tool configurations change without review. Deployments happen from someone's laptop. There is no audit trail, no rollback plan, and no consistent way to promote a change from a development environment to production. GitOps closes that gap. By treating your agent definition, configuration, and infrastructure as version-controlled source code, you get the same delivery discipline that software engineering teams have applied to application code for years. Every change is reviewed, every deployment is automated, and every environment state is traceable to a specific commit. This post shows you how to apply GitOps principles to a Microsoft Foundry Hosted Agent using GitHub as the source of truth and GitHub Tasks and Actions as the automation layer. The result is a repeatable, governed, production-ready delivery model for AI agents. What Is a Microsoft Foundry Hosted Agent? Microsoft Foundry is Microsoft's platform for building, deploying, and operating AI applications and agents. A Hosted Agent is an agent runtime managed by the Foundry platform rather than self-hosted by your team. You supply the agent logic, configuration, and tools; Foundry handles the runtime lifecycle, scaling, and managed infrastructure. In practical terms, a Foundry Hosted Agent is a containerised agent application. You package your agent code, prompt definitions, tool bindings, and environment configuration into a container image. Foundry deploys and manages that container within a Foundry project, connected to models, tools, and observability infrastructure that the platform provides. Teams choose Hosted Agents over self-hosting because: The platform manages runtime infrastructure, patching, and scaling Integration with Azure AI models, managed identity, and observability is built in You can focus engineering effort on agent logic rather than cluster management Foundry projects provide environment and resource isolation without requiring you to provision and manage separate Azure resources for each environment Hosted Agents are a good fit when your team wants strong operational support with minimal platform overhead, when you need clear separation between environments, and when your agents depend on Azure AI capabilities such as Azure OpenAI Service, Azure AI Search, or Model Context Protocol integrations. Why GitOps Matters Specifically for AI Agents GitOps is straightforward for stateless web services: the code changes, the pipeline runs, the container is deployed. AI agents are more complex because there are multiple distinct artefacts that all affect agent behaviour: System prompts and instruction files Tool definitions and external integrations Model selection and configuration (temperature, max tokens, safety settings) Model Context Protocol (MCP) server definitions Orchestration logic and agent workflow code Safety and policy settings Infrastructure and deployment configuration Any one of these can change the behaviour of your agent in ways that are difficult to detect without structured review. A prompt change that looks harmless can alter tone, scope, or factual grounding. A tool configuration change can expose data to unintended callers. A model upgrade can shift response quality unpredictably. Git gives you a single place to version, review, and approve all of these artefacts together. Pull requests give you a structured review gate. Workflow automation gives you validation before anything reaches a deployed environment. Tags and releases give you deployment markers you can roll back to. The discipline of GitOps turns what is often an ad-hoc AI delivery process into a repeatable engineering practice. Reference Architecture The following diagram shows a practical reference architecture for delivering a Microsoft Foundry Hosted Agent through a GitOps model using GitHub. +---------------------------+ | GitHub Repository | | /src /agents /tools | | /prompts /infra | | /.github/workflows | +---------------------------+ | | Pull Request / Push to main v +---------------------------+ | GitHub Actions | | 1. Validate agent config | | 2. Lint and scan code | | 3. Run unit tests | | 4. Build container image | | 5. Push to registry | +---------------------------+ | | Image tag (SHA or semver) v +---------------------------+ | Azure Container Registry | | myregistry.azurecr.io | | my-agent:<sha> | +---------------------------+ | +------+------+ | | v v +----------+ +----------+ | Foundry | | Foundry | | Dev | | Test | | Project | | Project | +----------+ +----------+ | Approval gate (GitHub env) | v +----------+ | Foundry | | Prod | | Project | +----------+ | v +---------------------------+ | Observability | | Azure Monitor / App | | Insights / Foundry Logs | +---------------------------+ Key design decisions in this architecture: The GitHub repository is the single source of truth for all agent artefacts No human deploys directly to any Foundry project; all changes flow through automation Environment promotion requires a GitHub environment approval, creating a governance gate The container image is built once and promoted across environments; the image is not rebuilt per environment Secrets are stored in Azure Key Vault and accessed by the Foundry agent at runtime via managed identity Figure: GitOps delivery pipeline stages from commit to production Repository Structure A well-structured repository separates agent logic from infrastructure and tooling from prompts. The following structure works well in practice: my-foundry-agent/ ├── .github/ │ ├── workflows/ │ │ ├── validate.yml # Runs on every PR │ │ ├── build-deploy.yml # Runs on merge to main │ │ └── rollback.yml # Manual trigger workflow │ └── CODEOWNERS # Review assignments by path ├── src/ │ ├── agents/ │ │ ├── agent.py # Agent entry point and orchestration │ │ └── agent_config.json # Agent metadata and settings │ ├── tools/ │ │ ├── search_tool.py # Tool implementations │ │ └── data_tool.py │ └── prompts/ │ ├── system.txt # System prompt (versioned as plain text) │ └── instructions.txt # Supplementary instructions ├── tests/ │ ├── unit/ # Unit tests for tools and logic │ ├── integration/ # Integration tests against a running agent │ └── smoke/ # Post-deployment smoke tests ├── infra/ │ ├── main.bicep # Foundry project and resource definitions │ └── environments/ │ ├── dev.parameters.json │ ├── test.parameters.json │ └── prod.parameters.json ├── scripts/ │ ├── validate_agent.py # Config validation script │ └── smoke_test.py # Smoke test runner ├── Dockerfile # Container image definition └── docs/ └── architecture.md # Architecture and runbook documentation What belongs where and why: /src/prompts - System prompts as plain text files. Versioning prompts as files means every change goes through a pull request with a diff review, just as code does. /src/agents - Agent orchestration logic and configuration. Keeps the entry point and agent metadata co-located. /src/tools - Tool implementations separated from agent logic. Tool logic changes independently and should be reviewable in isolation. /infra - Infrastructure as code with per-environment parameter files. Environment-specific values live here, never in source files. /tests - Three layers of testing: unit tests for tools, integration tests for the full agent, and smoke tests that run against a deployed environment. /.github/workflows - All automation defined as code. There should be no manual deployment steps that live outside this directory. GitHub Tasks Across the Delivery Lifecycle GitHub Tasks and Issues provide the work tracking layer on top of the GitOps delivery model. Used well, they connect the intention behind a change to its implementation and deployment history. Practical patterns for using GitHub Tasks with agent delivery: Prompt change task - Open an issue to describe why the system prompt is changing. The pull request that changes system.txt closes that issue, creating a permanent link between the rationale and the diff. Tool integration task - When adding a new MCP server or external tool integration, create a task that captures the design decision, security review outcome, and test evidence before the pull request is merged. Model upgrade task - When upgrading the underlying model version, create a task that includes evaluation results and comparison data. The task becomes part of your change audit trail. Rollback task - If a deployment causes quality regressions, create a task to track the rollback, root cause investigation, and corrective action. Automation can open this task automatically when a deployment fails health checks. Dependency on approval - GitHub Tasks can be linked to environment approvals in GitHub Actions. A task in a specific milestone or project column can gate a promotion workflow. The key insight is that GitHub Tasks are not just work management; they are part of your audit trail. A regulatory or security reviewer can follow the chain from a production deployment back through workflow runs, pull request reviews, and the original task that described the intent of the change. End-to-End GitOps Flow The following walk-through describes a realistic developer experience for changing an agent prompt and promoting it to production. A developer opens a GitHub Issue describing the prompt change required and the expected behaviour improvement. The developer creates a feature branch, edits src/prompts/system.txt , and updates any related unit tests. A pull request is opened. The validate workflow runs immediately, checking prompt length, configuration schema, and lint rules. Unit tests run against the changed files. A code reviewer approves the pull request. The CODEOWNERS file ensures that prompt changes require review from the AI engineering team, not just any contributor. On merge to main, the build workflow runs: the container image is built with the new prompt baked in, tagged with the commit SHA, and pushed to Azure Container Registry. The deployment workflow deploys the new image to the Foundry Dev project automatically. Integration and smoke tests run against the deployed dev agent. If tests pass, the workflow pauses at the Test environment gate and requests approval from a named reviewer. After approval, the same image is deployed to Foundry Test. Smoke tests run again. A second approval gate controls promotion to Foundry Prod. If at any point a health check or smoke test fails, the rollback workflow redeploys the previous image tag from the registry. The image tag of the last known-good deployment is stored as a GitHub environment variable. This flow means that no human ever deploys directly to any environment. Every environment state is traceable to a specific commit, image tag, and workflow run. Security and Governance AI agents often have access to sensitive data and external systems. Security and governance cannot be an afterthought. Identity and Access Use managed identity for the Foundry Hosted Agent to access Azure resources. Avoid service principal secrets where Microsoft Entra Workload Identity or managed identity is available. Apply the principle of least privilege: the agent identity should have read access to data sources and limited write access only where the use case requires it. Tool integrations that require API keys or external credentials should retrieve them from Azure Key Vault at runtime, never from environment variables baked into the image. Secrets and Configuration Store secrets in Azure Key Vault. Reference them in your Foundry project configuration using Key Vault references. Store GitHub Actions secrets using repository or environment-scoped secrets. Never echo secrets in workflow logs. Separate environment configuration (endpoints, resource names, capacity settings) from agent logic. Use the /infra/environments/ parameter files for this. Auditability and Review Enforce pull request reviews for all changes to /src/prompts , /src/agents , and /infra via CODEOWNERS. Require status checks to pass before merging. Blocked merges prevent untested changes reaching production. GitHub's workflow run history gives you a complete deployment audit trail. You can answer "what was deployed to prod on Tuesday and who approved it" in seconds. For regulated environments, consider branch protection rules that require signed commits. Safe Rollout Use canary or blue-green patterns where Foundry supports them for high-traffic agents. Always keep the previous image tag available in the registry. Do not delete images on deployment. Document and test your rollback procedure before you need it in production. Observability and Operational Readiness A deployed agent that you cannot observe is an agent you cannot operate. Build observability in from the start. What to Monitor Deployment health - Track whether each Foundry deployment succeeded and the agent is responding. Wire deployment outcomes back to GitHub workflow run status. Model and tool errors - Log tool call failures, model timeout errors, and safety filter activations. Aggregate these in Azure Monitor or Application Insights. Latency - Track end-to-end response latency per agent version. A latency increase after a model or prompt change is an early signal of a quality regression. Token consumption - Monitor token usage per request and per session. Unexpected increases can indicate prompt injection or runaway orchestration loops. Traceability - Log which agent version handled each request. Correlation between the image tag and request traces is essential for debugging production issues. Debugging and Alerting Use structured logging with a consistent schema. Include fields for agent version, session ID, tool called, and outcome. Set up alerts for error rate thresholds and latency percentiles. Alert before users notice the problem. For failed agent runs, ensure logs capture the full conversation context (within your data retention policy) so that developers can reproduce and diagnose the failure. Microsoft Foundry Toolboxes One of the most important additions to the Foundry platform is Toolboxes, currently in Public Preview. If you have ever seen an agent codebase where three different agents each wire the same search tool with their own credentials and slightly different configurations, you already understand the problem Toolboxes solve. A Toolbox is a named, versioned bundle of tools managed centrally in Microsoft Foundry. You define the tools once, configure authentication and access centrally, and publish a single MCP-compatible endpoint. Any agent in any runtime consumes that endpoint without per-tool wiring, custom SDK integration, or duplicated credential management. Figure: Before and after Foundry Toolboxes. Each agent previously managed its own tool connections. With Toolboxes, agents connect to one governed endpoint. The Four Pillars Discover (coming soon) - Find approved tools without browsing long catalogues. Reduces duplication by surfacing what already exists before developers build something new. Build (available today) - Select tools into a named toolbox. Supported types include built-in tools (Web Search, Code Interpreter, File Search, Azure AI Search), MCP servers, Agent-to-Agent (A2A) endpoints, and OpenAPI-defined services. Consume (available today) - A single MCP-compatible endpoint exposes every tool in the toolbox to any agent runtime. Agents that can speak MCP can use a Foundry Toolbox without any Foundry-specific SDK dependency. Govern (coming soon) - Centralised authentication and observability applied to every tool call flowing through the toolbox. Security and platform teams get consistent controls without asking developers to bolt governance onto every agent individually. Toolboxes and GitOps: A Natural Fit Toolboxes are particularly well-suited to a GitOps delivery model because the toolbox definition is a discrete, versioned artefact. Instead of credentials and tool configuration scattered across agent codebases, the toolbox becomes its own managed entity with its own version history. The key design property is that the toolbox endpoint URL is stable. When you promote a new toolbox version to be the default, agents consuming the endpoint pick up the update without any code changes. This means you can update tool configuration, add a new MCP server, or rotate credentials in the toolbox without redeploying every agent that uses it. Figure: Toolbox versioning in a GitOps model. Commits trigger CI validation and deployment of new toolbox versions. The stable endpoint URL allows agents to consume updates without redeployment. Adding a Toolbox to Your Repository In your GitOps repository, toolbox definitions belong in /src/tools/toolbox_config.py or as a declarative configuration file checked into version control. The following example creates a toolbox that combines web search, Azure AI Search over internal documentation, and a GitHub MCP server: # src/tools/toolbox_config.py # Run this via CI to create or update a toolbox version in Foundry. from azure.identity import DefaultAzureCredential from azure.ai.projects import AIProjectClient import os client = AIProjectClient( endpoint=os.environ["FOUNDRY_PROJECT_ENDPOINT"], credential=DefaultAzureCredential() ) toolbox_version = client.beta.toolboxes.create_toolbox_version( toolbox_name="customer-feedback-toolbox", description="Tools for triaging customer feedback: search, docs, and GitHub.", tools=[ { "type": "web_search", "description": "Search approved public documentation sites.", "custom_search_configuration": { "project_connection_id": os.environ["BING_CONNECTION_NAME"], "instance_name": os.environ["BING_INSTANCE_NAME"] } }, { "type": "azure_ai_search", "name": "product-manuals-search", "description": "Search internal product documentation.", "azure_ai_search": { "indexes": [ { "index_name": os.environ["SEARCH_INDEX_NAME"], "project_connection_id": os.environ["SEARCH_CONNECTION_ID"] } ] } }, { "type": "mcp", "server_label": "github", "server_url": "https://api.githubcopilot.com/mcp", "project_connection_id": os.environ["GITHUB_CONNECTION_ID"] } ], ) print(f"Toolbox version created: {toolbox_version.version}") print(f"MCP endpoint: {toolbox_version.mcp_endpoint}") To promote a toolbox version to be the default (the endpoint agents use without specifying a version), add this to your deployment workflow: # Promote toolbox version to default after validation toolbox = client.beta.toolboxes.update( toolbox_name="customer-feedback-toolbox", default_version=toolbox_version.version, ) print(f"Default version is now: {toolbox.default_version}") The stable endpoint for agents consuming this toolbox is: https://<your-project>.services.ai.azure.com/api/projects/<project>/toolbox/customer-feedback-toolbox/mcp?api-version=v1 Attaching the Toolbox to Your Hosted Agent In your agent code, connect to the toolbox via a single MCP tool definition. The agent gains access to every tool in the toolbox without knowing their individual configurations: # src/agents/agent.py (relevant excerpt) from agent_framework import MCPStreamableHTTPTool import httpx, os toolbox_endpoint = os.environ["FOUNDRY_TOOLBOX_ENDPOINT"] http_client = httpx.AsyncClient( auth=_ToolboxAuth(token_provider), # Microsoft Entra bearer token timeout=120.0, ) mcp_tool = MCPStreamableHTTPTool( name="toolbox", url=toolbox_endpoint, http_client=http_client, load_prompts=False, ) # Agent now has access to web search, AI Search, and GitHub MCP # through one tool definition and one authenticated connection. GitOps Workflow Extension for Toolboxes Add a dedicated job to your build-deploy workflow to create and promote toolbox versions as part of the same CI/CD pipeline: deploy-toolbox: name: Deploy Toolbox Version needs: validate runs-on: ubuntu-latest environment: dev permissions: id-token: write contents: read steps: - uses: actions/checkout@v4 - name: Azure login (OIDC) uses: azure/login@v3 with: client-id: ${{ secrets.AZURE_CLIENT_ID_DEV }} tenant-id: ${{ secrets.AZURE_TENANT_ID }} subscription-id: ${{ secrets.AZURE_SUBSCRIPTION_ID }} - name: Create toolbox version in Foundry env: FOUNDRY_PROJECT_ENDPOINT: ${{ vars.FOUNDRY_PROJECT_ENDPOINT_DEV }} BING_CONNECTION_NAME: ${{ vars.BING_CONNECTION_NAME }} BING_INSTANCE_NAME: ${{ vars.BING_INSTANCE_NAME }} SEARCH_INDEX_NAME: ${{ vars.SEARCH_INDEX_NAME }} SEARCH_CONNECTION_ID: ${{ vars.SEARCH_CONNECTION_ID }} GITHUB_CONNECTION_ID: ${{ vars.GITHUB_CONNECTION_ID }} run: python src/tools/toolbox_config.py Key points to note: Toolbox configuration is Python code in source control, reviewed through pull requests like any other change Connection IDs and index names are environment variables from GitHub Actions variables, not hardcoded in the script The same script runs for dev, test, and prod with different environment variable bindings Toolbox version promotion is a separate step from agent deployment, so you can update tools independently of the agent container Because the toolbox endpoint is stable, rolling back a toolbox version does not require rolling back the agent image Common Pitfalls Teams adopting this pattern commonly make the following mistakes. Identifying them early saves significant operational pain later. Treating prompts as unmanaged text. If your system prompt lives in a portal text box rather than a versioned file, you have no history, no review process, and no rollback capability. Move prompts into source control on day one. Deploying manually from the portal. Even one manual deployment breaks the GitOps contract. Your repository no longer reflects the true state of the environment. Automate everything and remove portal deployment permissions from individuals. Mixing environment configuration into source files. Hardcoded endpoint URLs or model deployment names in agent_config.json mean your dev and prod configurations diverge at the source level. Use parameter files and environment variables resolved at deployment time. Poor separation between agent logic and tool logic. When agents and tools are tightly coupled in a single file, a tool change requires a full agent review and redeployment. Keep them separate so they can evolve independently. Not versioning your Toolbox definition. Defining a Foundry Toolbox interactively through the portal gives you no audit trail and no rollback path. The toolbox configuration script belongs in source control alongside your agent code. Skipping evaluation before promotion. Deploying a prompt change without running a structured evaluation against a representative test set is how regressions reach production. Build evaluation into the pull request workflow, not just the deployment workflow. No rollback plan. If your first rollback is unplanned and urgent, it will be slow and stressful. Test your rollback procedure in a non-production environment and document the steps. Ignoring token and cost signals. AI workloads have variable cost profiles. A change that doubles average token consumption per request may be functionally correct but economically unsustainable. Monitor consumption as a first-class signal. Example GitHub Actions Workflow The following workflow runs on pull request validation and on merge to main. It covers the core delivery lifecycle: validate, build, deploy to dev, and smoke test. # .github/workflows/build-deploy.yml name: Build and Deploy Foundry Hosted Agent on: push: branches: - main pull_request: branches: - main env: REGISTRY: myregistry.azurecr.io IMAGE_NAME: my-foundry-agent jobs: validate: name: Validate Agent Configuration runs-on: ubuntu-latest steps: - uses: actions/checkout@v4 - name: Set up Python uses: actions/setup-python@v5 with: python-version: "3.12" - name: Install dependencies run: pip install -r requirements.txt - name: Validate agent config schema run: python scripts/validate_agent.py - name: Run unit tests run: pytest tests/unit/ -v - name: Lint code run: ruff check src/ build: name: Build and Push Container Image needs: validate runs-on: ubuntu-latest if: github.ref == 'refs/heads/main' permissions: id-token: write contents: read outputs: image_tag: ${{ steps.meta.outputs.version }} steps: - uses: actions/checkout@v4 - name: Azure login (OIDC) uses: azure/login@v3 with: client-id: ${{ secrets.AZURE_CLIENT_ID }} tenant-id: ${{ secrets.AZURE_TENANT_ID }} subscription-id: ${{ secrets.AZURE_SUBSCRIPTION_ID }} - name: Log in to Azure Container Registry run: az acr login --name ${{ env.REGISTRY }} - name: Extract metadata id: meta uses: docker/metadata-action@v5 with: images: ${{ env.REGISTRY }}/${{ env.IMAGE_NAME }} tags: | type=sha,format=short - name: Build and push image uses: docker/build-push-action@v7 with: context: . push: true tags: ${{ steps.meta.outputs.tags }} deploy-dev: name: Deploy to Foundry Dev needs: build runs-on: ubuntu-latest environment: dev permissions: id-token: write contents: read steps: - uses: actions/checkout@v4 - name: Azure login (OIDC) uses: azure/login@v3 with: client-id: ${{ secrets.AZURE_CLIENT_ID_DEV }} tenant-id: ${{ secrets.AZURE_TENANT_ID }} subscription-id: ${{ secrets.AZURE_SUBSCRIPTION_ID }} - name: Deploy agent to Foundry Dev project run: | az ai foundry agent deploy \ --project ${{ vars.FOUNDRY_PROJECT_DEV }} \ --image ${{ env.REGISTRY }}/${{ env.IMAGE_NAME }}:${{ needs.build.outputs.image_tag }} \ --environment dev - name: Run smoke tests against dev run: pytest tests/smoke/ -v --base-url ${{ vars.AGENT_URL_DEV }} deploy-test: name: Deploy to Foundry Test needs: deploy-dev runs-on: ubuntu-latest environment: test permissions: id-token: write contents: read steps: - uses: actions/checkout@v4 - name: Azure login (OIDC) uses: azure/login@v3 with: client-id: ${{ secrets.AZURE_CLIENT_ID_TEST }} tenant-id: ${{ secrets.AZURE_TENANT_ID }} subscription-id: ${{ secrets.AZURE_SUBSCRIPTION_ID }} - name: Deploy agent to Foundry Test project run: | az ai foundry agent deploy \ --project ${{ vars.FOUNDRY_PROJECT_TEST }} \ --image ${{ env.REGISTRY }}/${{ env.IMAGE_NAME }}:${{ needs.build.outputs.image_tag }} \ --environment test - name: Run smoke tests against test run: pytest tests/smoke/ -v --base-url ${{ vars.AGENT_URL_TEST }} Key decisions in this workflow: Validation runs on every pull request, not just on merge. Fast feedback catches problems before review. The container image is built once and the image tag is passed forward to deployment jobs. The same artefact is promoted across environments. Authentication uses OIDC federated credentials via azure/login@v3 with id-token: write permissions. No long-lived secrets are stored in GitHub for Azure authentication. The environment: test directive in the deploy-test job triggers a GitHub environment approval gate. A named reviewer must approve before the job runs. Smoke tests run after every deployment. A failed smoke test prevents further promotion. Best Practices Checklist Use this checklist when adopting the GitOps pattern for a Microsoft Foundry Hosted Agent: All agent artefacts, including prompts, tool definitions, model configuration, and Toolbox configuration scripts, are committed to source control No manual deployments to any environment; all changes flow through GitHub Actions workflows Pull request reviews are enforced for all changes to agent logic, prompts, and infrastructure via CODEOWNERS Unit tests cover tool logic; integration tests cover end-to-end agent behaviour; smoke tests cover deployed environments Container images are built once per commit and promoted across environments; images are not rebuilt per environment Environment configuration (endpoints, resource names) lives in parameter files, never in source code Secrets are stored in Azure Key Vault and accessed via managed identity at runtime GitHub environment approval gates control promotion from dev to test to prod Foundry Toolboxes are used to centralise tool definitions, credentials, and access governance across all agents; the toolbox configuration script is version-controlled and deployed through CI/CD Toolbox versions are promoted via the update default_version API step in the deployment workflow, not manually through the portal Latency, error rate, and token consumption are monitored with alerting thresholds The rollback procedure is documented, automated, and has been tested in a non-production environment GitHub Issues are used to record the intent behind significant changes and link to the pull requests that implement them Branch protection rules prevent direct pushes to main and require status checks to pass before merge The previous image tag is retained in the registry and stored as a GitHub environment variable for rollback Conclusion A Microsoft Foundry Hosted Agent is not something you deploy once and forget. Prompts evolve, tools change, models are upgraded, and policy requirements shift. Every one of those changes has the potential to alter agent behaviour in ways that affect users, costs, and compliance posture. GitOps, implemented through GitHub and GitHub Tasks, gives you the operational discipline to manage that complexity. Source control for all artefacts. Pull request review for every change. Automated validation, build, and deployment. Environment promotion gates. A complete audit trail from task to production. These are not bureaucratic overhead; they are the foundation of reliable, trustworthy AI agent operations. The teams that operate AI agents well are the ones that treat them like production software from the start. The investment in pipeline, structure, and governance pays back every time a change goes smoothly, every time a rollback takes minutes rather than hours, and every time a security or compliance reviewer can answer their question from a pull request history rather than a support ticket. Build the discipline in early. Your future self, and your production environment, will benefit from it. References Microsoft Foundry documentation Microsoft Foundry Agent Service documentation Microsoft Foundry Toolboxes documentation Introducing Toolboxes in Foundry (Microsoft Developer Blog) GitHub Actions documentation GitHub Projects and Tasks documentation Azure Container Registry documentation Azure Key Vault documentation Microsoft Entra Managed Identities documentation OpenGitOps Principles1.1KViews0likes0CommentsDevOps for Microsoft Hosted Agents: From Terraform Apply to Production-Grade Agent Delivery
A companion piece to Infrastructure as Code for AI: Building and Deploying Microsoft Hosted Agents with Terraform. Just announced — source-code deploy (preview). Foundry has just added a second Hosted Agent deploy path alongside the container path this post covers. Instead of a container image, you upload a .zip of your source plus a requirements.txt (Python 3.13 / 3.14) or a .csproj (.NET 10), and the Agent Service either builds dependencies for you ( remote_build ) or runs a prebuilt bundle ( bundled ). The version definition uses code_configuration instead of container_configuration — the two are mutually exclusive on a given version. Versioning is content-addressable on the zip's SHA-256, so the dedup behaviour described below still applies. Required roles shift slightly: deploying the agent needs Foundry Project Manager at project scope, and the platform-assigned agent identity gets Foundry User (both handled automatically by azd and the Foundry VS Code Toolkit). The DevOps loop in this post — immutable versions, eval gating, manifest-driven promotion, traffic-split canary, per-version observability — transfers directly; only the build-and-push stage changes (no Dockerfile, no ACR for remote_build ). The container path covered here remains fully supported and is still the right choice if you need custom base images, system packages, or non-Python/.NET runtimes. Full details: Deploy a hosted agent from source code (preview). What this post assumes. It describes recommended enterprise DevOps patterns on top of Microsoft Foundry Hosted Agents. Some patterns — evaluation gating, traffic-based rollout, manifest-driven promotion — are best practices and may not be enforced by the platform itself. Hosted Agents and several related capabilities (A2A, certain deployment and routing controls) are in preview and may evolve. TL;DR Terraform provisions the platform: Foundry account, project, model deployment, ACR, App Insights, RBAC. DevOps pipelines ship agent versions, not source branches — the deploy artifact is a container image digest plus an immutable version spec. Evaluation should be treated as a release gate, not a dashboard. Quality regressions should fail the build the same way unit-test failures do. Traffic split between versions is the rollout and rollback primitive. Rollback typically avoids rebuilding or redeploying artifacts. Observability is sliced per version — during canary, two versions serve simultaneously and aggregate metrics lie. The Delivery Pipeline at a Glance Terraform ───► Foundry project (AIServices) + model deployment + ACR + App Insights │ PR opened ▼ └─► docker build ───► push to ACR ───► capture image digest │ ▼ Foundry SDK: create agent version (image digest + cpu/mem + env + protocols) │ ▼ Evaluation gate ────► fail → stop │ ▼ pass Promote via manifest → staging → prod │ ▼ Traffic-split canary (0% → 10% → 100%) │ ▼ App Insights: per-version latency, cost, sampled quality, sandbox sizing Infrastructure as Code gets the platform stood up. It does not, on its own, ship an agent. The gap between terraform apply succeeding and a customer-facing agent reliably serving requests in production is where DevOps lives — and for Microsoft Hosted Agents on Microsoft Foundry, that gap has its own shape. A Hosted Agent is not a prompt and a tool list. It is your own code, packaged as a container image, pushed to Azure Container Registry, and deployed to a Foundry project. The Foundry Agent Service pulls the image, provisions an isolated execution environment per agent session, assigns the agent its own dedicated Microsoft Entra ID (agent identity), and exposes a dedicated endpoint. An agent supports up to four protocols, any of which can be combined in a single deployment: Responses ( .../protocols/openai/responses ) — OpenAI-compatible chat-style API. Implemented in the container. Invocations ( .../protocols/invocations ) — arbitrary JSON in / arbitrary JSON out for webhook receivers and non-conversational workloads. Implemented in the container. A2A ( .../protocols/a2a , preview) — the open Agent2Agent protocol for agent-to-agent delegation across frameworks and vendors. Surfaced on its own endpoint path by the platform. Activity — the Teams / M365 channel protocol. The platform bridges Responses to Activity automatically when an agent is published to a Microsoft 365 channel. Microsoft manages the runtime, scaling, session state, and lifecycle. You ship the image and the version definition. Important — Foundry version compatibility. Hosted Agents are supported on the new Microsoft Foundry project resource model ( azurerm_cognitive_account_project under a Cognitive Services account of kind = "AIServices" ). The older Azure AI Foundry Hub model ( azurerm_ai_foundry / azurerm_ai_foundry_project , kind = "Hub" ) — the Azure ML–derived workspace surface — does not expose Hosted Agent capabilities. They are two distinct Azure resource types with different APIs. Everything in this post assumes the new Foundry project. That shape drives three things every DevOps loop for Hosted Agents has to handle: The deploy artifact is a container image plus an immutable agent version. A version snapshots the image digest, CPU/memory, environment variables, and protocol configuration. To change anything, you create a new version. The platform supports weighted traffic between versions, which is your blue/green and canary primitive. The agent identity is created for you, per agent. You don't pick one or wire managed-identity references manually. Each agent is assigned a dedicated Microsoft Entra ID (agent identity) at deploy time; RBAC to downstream resources is granted to that identity. Quality is non-deterministic. Two terraform apply runs against the same configuration produce identical resources. Two agent runs against the same input can produce different outputs. Your pipeline has to gate on evaluation, not only on tests passing and HTTP 200s. This post lays out an end-to-end DevOps loop on top of that shape: how to structure the repository, what runs in CI versus CD, how to gate releases on evaluation, how to promote across environments, how to use version traffic split for safe rollouts and instant rollback, and what observability is worth wiring beyond the defaults. A Quick Tour of Microsoft Foundry If you've spent more time in Azure OpenAI or AI Studio than in Foundry, a short orientation helps before the DevOps patterns make sense. Microsoft Foundry is Microsoft's unified platform for building, evaluating, deploying, and operating AI applications and agents. It consolidates what used to be spread across Azure OpenAI, Azure AI Studio, and the AI Hub model into a single resource and a single portal at ai.azure.com. Three pieces are worth knowing up front. The resource model Foundry is built on two Azure resources: Foundry account — an azurerm_cognitive_account with kind = "AIServices" , project_management_enabled = true , a custom_subdomain_name , and a managed identity. This is the top-level container: it holds your model deployments (Azure OpenAI and the broader Foundry model catalog), connections to backing services, and the Foundry-managed Toolbox MCP endpoint. Foundry project — an azurerm_cognitive_account_project under that account. A project is the scope for agents, evaluations, conversation history, indexes, and per-app connections. One project per app or per environment is the usual shape. This is the new Foundry model — and it is the only model that supports Hosted Agents. The older Azure AI Foundry Hub ( azurerm_ai_foundry + azurerm_ai_foundry_project , kind = "Hub" ) is a separate Azure ML–derived workspace and cannot host Hosted Agents. The two surfaces look superficially similar in the portal but are distinct Azure resource types with different APIs and feature sets. If a tutorial, sample, or piece of Terraform you find online creates an azurerm_ai_foundry Hub, it is targeting the classic surface and the Hosted Agents APIs ( /agents , agent versions, traffic split, dedicated endpoints) will not be available against it. To use Hosted Agents you must provision a new Foundry account + project as described above. There is no in-place upgrade from a Hub. What Foundry gives you A Foundry project is more than a container. Out of the box it provides: A model catalog and deployment surface — Azure OpenAI models (GPT-4.1, GPT-4o, o-series, embeddings), plus open and partner models, all deployed and invoked through the same project endpoint with the same auth model. Two agent execution modes — prompt-based agents (defined entirely by instructions + tool configuration in the portal, suitable for conversational assistants) and Hosted Agents (your own containerized code, the subject of this post). A managed Toolbox — a project-level MCP endpoint that exposes Foundry-curated tools (Code Interpreter, Web Search, Azure AI Search, OpenAPI, custom MCP, A2A) with consolidated auth. Hosted Agent code connects to the Toolbox using standard MCP client libraries. First-class evaluation — datasets, graders (similarity, LLM-as-judge, safety, groundedness), and evaluation runs as a built-in concept, not a bolt-on. Built-in tracing — OpenTelemetry traces from agents land in a linked Application Insights resource automatically. No manual instrumentation needed to get the basics. Per-agent identity — when you deploy a Hosted Agent, the platform creates a dedicated Microsoft Entra ID (agent identity) for it and gives it a dedicated endpoint. RBAC to downstream resources is granted to that identity. How the pieces line up for Hosted Agents For the rest of this post, the mental model is: Resource group └── Foundry account (Cognitive Services, kind=AIServices) ├── Model deployments (e.g. gpt-4.1) └── Foundry project ├── Hosted Agent: customer-support │ ├── Version v1 (image digest A, 100% traffic) │ └── Version v2 (image digest B, 0% traffic — canary) ├── Hosted Agent: webhook-handler ├── Evaluations ├── Connections (ACR, AI Search, Key Vault…) └── Toolbox (MCP) Terraform provisions the account, project, model deployments, ACR, App Insights, and RBAC. Hosted Agents — images, versions, traffic weights — are managed through azd or the Foundry SDK. That boundary is what the rest of this post automates. The minimal Terraform shape For Hosted Agents you need the new-model shape instead. The skeleton below is the minimum that lets you deploy a Hosted Agent on top of it — storage, Key Vault, monitoring, networking, and OIDC for CI live alongside for more details see Infrastructure as Code for AI: Building and Deploying Microsoft Hosted Agents with Terraform | Microsoft Community Hub. # Foundry account (new model — required for Hosted Agents) resource "azurerm_cognitive_account" "foundry" { name = "ai-${local.name}" resource_group_name = azurerm_resource_group.main.name location = azurerm_resource_group.main.location kind = "AIServices" sku_name = "S0" project_management_enabled = true custom_subdomain_name = "ai-${local.name}" # required for AAD auth identity { type = "SystemAssigned" } } # Model deployment the agent will call resource "azurerm_cognitive_deployment" "gpt" { name = "gpt-4.1" # stable name — agents pin to this cognitive_account_id = azurerm_cognitive_account.foundry.id model { format = "OpenAI" name = "gpt-4.1" version = "2025-04-14" } sku { name = "GlobalStandard" capacity = 10 } } # Foundry project — the scope for Hosted Agents, evals, conversations resource "azurerm_cognitive_account_project" "main" { name = "proj-${local.name}" cognitive_account_id = azurerm_cognitive_account.foundry.id location = azurerm_resource_group.main.location identity { type = "SystemAssigned" } } # Container registry the agent image is pushed to and pulled from resource "azurerm_container_registry" "acr" { name = "acr${replace(local.name, "-", "")}" resource_group_name = azurerm_resource_group.main.name location = azurerm_resource_group.main.location sku = "Standard" admin_enabled = false # use RBAC, not admin user } # The project's managed identity needs to pull the agent image resource "azurerm_role_assignment" "project_acr_pull" { scope = azurerm_container_registry.acr.id role_definition_name = "AcrPull" # use Container Registry Repository Reader if the ACR has ABAC enabled principal_id = azurerm_cognitive_account_project.main.identity[0].principal_id } A few things worth calling out: kind = "AIServices" + project_management_enabled = true + custom_subdomain_name are what make this a new-model Foundry account. Omit project_management_enabled and azurerm_cognitive_account_project will not provision; omit custom_subdomain_name and you lose the Foundry endpoint shape that Entra-authenticated access depends on. azurerm_cognitive_account_project is the new-Foundry project resource. Do not use azurerm_ai_foundry_project — that targets the Hub model and does not host agents. Keep the model deployment name stable. Agent code (and your agent.yaml ) pins to the deployment name, not the model version. Changing the version is safe; changing the name forces a new agent version. The project MI needs ACR pull, not push. CI pushes the image (via its own identity); the platform pulls it on the project's behalf when the agent runs. ABAC-enabled ACR is supported but requires --source-acr-auth-id [caller] on az acr build in your CI script — a common gotcha. A note on the provider. Everything above uses the hashicorp/azurerm provider. Foundry's surface evolves quickly, and you will occasionally hit a property or child resource that AzureRM hasn't caught up with yet — project connections, capability hosts, and some newer agent-related fields are common examples. When that happens, reach for azure/azapi: use azapi_update_resource to patch a missing property on an AzureRM-owned resource, and azapi_resource for resources AzureRM doesn't model at all. Keep AzureRM as the default and use AzAPI as a targeted gap-filler, so you don't fork ownership of mainstream resources. The Hosted Agent Delivery Loop A working delivery loop has five stages. Each maps to a specific artifact, a specific tool, and a specific failure mode. Stage Artifact Tool Primary failure mode Infra provisioning Terraform state terraform apply Quota, RBAC propagation, ACR not reachable Image build & push OCI image in ACR (ACR must remain publicly reachable today) docker build / az acr build Image too large, base image CVEs Agent version create Immutable version (image digest + config) azd or Foundry SDK Bad env var, wrong protocol declared Evaluation Eval dataset + grader Foundry evaluators Quality / safety regression Traffic shift & observe Version weights, App Insights traces Foundry SDK + Azure Monitor Silent quality decay, sandbox over/under-sizing The first stage is where the prior post left off. The remaining four are this post. Infra provisioning assumes the standard pattern: terraform plan runs on every PR as a review gate (posted as a PR comment) and terraform apply runs only on merge to the environment branch. Everything below assumes the platform is already applied. Repository Shape A repository that supports the loop end-to-end looks roughly like this: agent-platform/ ├── infra/ # Terraform from the prior post (AIServices + project) │ ├── modules/foundry-project/ │ └── environments/ │ ├── dev.tfvars │ ├── staging.tfvars │ └── prod.tfvars ├── agents/ │ ├── customer-support/ │ │ ├── Dockerfile │ │ ├── src/ # Agent code (Python or C#) │ │ ├── agent.yaml # Version spec: image, cpu/memory, protocols, env │ │ ├── evals/ │ │ │ ├── dataset.jsonl │ │ │ └── graders.yaml │ │ └── README.md │ └── webhook-handler/ │ └── ... ├── scripts/ │ ├── deploy_agent_version.py # Build → push → create version → optional weight shift │ ├── run_evals.py │ └── promote_version.py # Shifts traffic between versions └── .github/workflows/ ├── infra.yml # Terraform plan/apply ├── agent-pr.yml # Build, push to ACR, deploy candidate version, run evals └── agent-release.yml # Promote a tested version to staging / prod Two deliberate choices. First, infrastructure and agents live in the same repo but in separate top-level directories with separate pipelines. They have different cadences and different reviewers. Second, each agent is its own folder with its own Dockerfile , code, version spec, and eval suite. A single PR touches one agent's directory cleanly; a code-review diff stays focused. The Agent Version as the Deploy Unit A Hosted Agent is deployed as a version. A version is immutable — once created it captures: the container image digest (not just the tag — the digest, so it cannot drift), CPU and memory allocation for the per-session sandbox (e.g. 1 vCPU / 2 GiB), the container protocols the image implements — responses , invocations , or both, environment variables passed to the container at runtime, any other version-scoped configuration (e.g. base model deployment name). The container's container_protocol_versions only declares responses and/or invocations — the two protocols the container itself implements. A2A (preview) is surfaced by the platform on its own endpoint path, and Activity is bridged from Responses automatically when the agent is published to a Microsoft 365 channel. Under the hood, agent versions run on Azure Container Apps with VM-isolated sandboxes, which is also why you may see the term revision in some Container Apps–surfaced APIs and limits — a Hosted Agent version corresponds to one such revision. To change any of those, you create a new version. The platform keeps the old one and shifts traffic between them by weight. This is the primitive you use for canary rollouts and for rollback — both reduce to a traffic-weight change, not a redeploy. An agent.yaml per agent makes the version reproducible from source: # agents/customer-support/agent.yaml name: customer-support container: image: ${ACR_LOGIN_SERVER}/customer-support # digest resolved at deploy time cpu: 1 memory: 2Gi protocols: # container_protocol_versions - responses # add `invocations` here if the container also handles webhook-style payloads env: # The platform automatically injects FOUNDRY_PROJECT_ENDPOINT, # AZURE_AI_MODEL_DEPLOYMENT_NAME, and APPLICATIONINSIGHTS_CONNECTION_STRING # — you only set what's specific to your agent. LOG_LEVEL: info metadata: owner: support-team source_commit: ${GITHUB_SHA} scripts/deploy_agent_version.py is the executable form of this spec. Its job per agent is: Build the container image ( docker build locally, or az acr build server-side for ABAC ACRs). Push to ACR and capture the resulting image digest — not the :latest tag. Resolve environment variables from the target environment's config. Call the Foundry SDK to create a new agent version pinned to that digest. Emit a deployment-manifest.json containing the agent name, version ID, image digest, source commit SHA, and the eval dataset hash used. One gotcha: the platform deduplicates. A create version call with no change to the version parameters (same image digest, same env, same CPU/memory, same protocols) will not produce a new version object. Write the script to treat "no new version returned" as success and reuse the existing version ID in the manifest, not as a failure to retry. That manifest is the cross-pipeline contract. PR pipelines produce one. Promotion pipelines consume one. Rollback consumes a previous one. Evaluation as a Release Gate Foundry ships evaluators (datasets, graders, evaluation runs) as a first-class platform feature. Whether to block a release on their results is a team decision, not a platform mandate — but it is the recommended pattern for any agent serving real users. A pipeline that promotes an agent because the image built, the container started, and the version was created with HTTP 200 will eventually ship a regression that an integration test cannot catch. Treat the eval suite the way you treat unit tests: failures stop the pipeline. A minimal but honest evaluation setup has three pieces. A reference dataset. Twenty to fifty representative scenarios is enough to start. Each row is an input plus either a reference answer, a set of must-include facts, or a rubric. Store as JSONL alongside the agent: {"id":"refund-1","input":"How do I get a refund for order 12345?","must_include":["return window","14 days","original payment method"]} {"id":"escalate-1","input":"This is the third time my package is late.","rubric":"Agent should acknowledge, apologize, offer escalation, not promise compensation."} Graders. Foundry's evaluators library ships templates — exact match, similarity, LLM-as-judge for rubric scoring, and built-in safety and groundedness graders. Pick what matches your dataset shape. LLM-as-judge is the workhorse for open-ended responses; pin its model deployment explicitly so the grader itself does not drift between runs. Thresholds. Decide what "passing" means before the first run. A common pattern: Hard floor on safety / groundedness — any regression fails the build. Relative threshold on quality — no more than X% drop versus the last known-good version. Absolute floor on must-include coverage — for example ≥ 90%. Wire it into the PR pipeline: # .github/workflows/agent-pr.yml (excerpt) - name: Build, push, and create candidate version run: | python scripts/deploy_agent_version.py \ --agent customer-support \ --project $EVAL_PROJECT \ --version-suffix pr-${{ github.event.number }} \ --traffic 0 # create the version, do not route traffic yet - name: Run evaluations against candidate endpoint run: | python scripts/run_evals.py \ --agent customer-support \ --version pr-${{ github.event.number }} \ --baseline last-known-good \ --fail-on-regression The PR creates a candidate version with zero traffic weight against a long-lived "eval" Foundry project, runs evaluations against the candidate version's dedicated endpoint, and then deletes the candidate version on PR close. A standing eval project beats a per-PR Foundry project — provisioning a project per PR is slow and adds RBAC overhead that does not earn its keep. Environment Promotion Three environments is the floor: dev , staging , prod . Each is its own Foundry project, ideally its own Foundry account in its own resource group. What promotes between them is the image digest and the version spec — not source code, and not "redeploy from main." A workable model: dev — every push to a feature branch builds an image and creates a dev version. Loose evaluation thresholds. Used for human poking and end-to-end debugging. staging — merges to main create a staging version. Full eval suite, strict thresholds. Same sandbox sizing, same env vars, same protocols as prod. prod — manually approved promotion from staging. Promotion script reads the staging manifest, finds the image digest that passed, and creates the prod version pointed at that exact digest. No rebuild. The "same digest" rule is the recommended pattern for safe promotion. If staging passed evaluations on customer-support@sha256:abc… running gpt-4.1 , prod should get that exact image. Re-building from main in the prod pipeline reintroduces the risk you spent staging trying to eliminate — a different base-image patch level, a different transitive dependency, a different build clock — even though nothing in your source changed. GitHub Actions environments make the approval concrete: jobs: promote-prod: needs: deploy-staging environment: production # requires reviewer approval runs-on: ubuntu-latest steps: - name: Create prod version from staging manifest run: | python scripts/deploy_agent_version.py \ --agent customer-support \ --project $PROD_PROJECT \ --from-manifest staging-manifest.json \ --traffic 10 # canary at 10% The canary weight is the second half of safe promotion: create the prod version, give it a small fraction of traffic, watch the App Insights traces, then shift the rest with promote_version.py . Traffic-Split Rollout and Instant Rollback Weighted version traffic changes the rollback model entirely. Rollback typically avoids rebuilding or redeploying artifacts — the previous version is still there, ready to take traffic. A typical canary flow: Create new version v42 at 0% traffic. Endpoint exists; no production calls reach it. Shift to 10%. Observe for an hour or a day, depending on traffic volume. Shift to 50%, then 100%. Old version stays at 0% but is not deleted. After a stability window (commonly a week), delete the previous version to free quota. Rollback is the reverse: shift weights back to the previous version. It is a control-plane call, not a deploy. The agent's endpoint URL does not change, sessions in flight continue on whichever version they started on, and new sessions land on whatever the weights say. Two consequences worth internalizing: Keep at least the last two known-good versions live. Rollback is only as fast as your ability to flip weights to a version that already exists. Do not skip the canary step under deadline pressure. A 0%→100% cutover gives you the same blast radius as a non-canaried deploy. The platform supports incremental rollout; use it. For a destructive change — a removed protocol, a renamed agent, an env var the previous version cannot tolerate — rollback may not be safe. Forward-fix is the answer. Identify those changes in PR review and require an explicit "rollback path: forward-fix" note in the PR. Handling Model Version Changes A model deployment bump is the highest-blast-radius runtime change you can make to a Hosted Agent: the agent's behaviour on every input can shift. Treat it like a dependency upgrade. Open a PR that changes only the AZURE_AI_MODEL_DEPLOYMENT_NAME (or the model version on the deployment, via Terraform). Build a new image if needed, create a new agent version, run the full eval suite at 0% traffic. Run a larger regression dataset if you have one. Require a human reviewer who is not the PR author. Promote through staging, then canary in prod for at least one business day before shifting full traffic. If the new model is faster or cheaper, the temptation is to skip steps. Don't. A quality regression in prod almost always costs more than a careful upgrade. The Terraform side is small: openai_model_version is a variable on the azurerm_cognitive_deployment . Terraform recreates the deployment if the version changes. The Hosted Agent picks up the new deployment the next time it calls the model — if you kept the deployment name stable, which is your contract with the agent code. If you change the deployment name as well, the agent needs a new version that knows the new name. Observability That Actually Tells You Something The platform injects an Application Insights connection string into every Hosted Agent container as an environment variable. Agents that use the protocol libraries emit OpenTelemetry traces by default. That gives you per-request latency, token counts, tool invocations, and conversation IDs out of the box. That is the floor. Add to it: Custom span attributes on every request. Agent name, agent version ID, image digest (short), model deployment name. Without these, post-incident analysis cannot tell you which version was live when a problem started — especially during a traffic-split rollout where two versions are serving simultaneously. Quality signal capture. Sample a percentage of production conversations into a queue for offline grading. Run the same graders you used in CI against that sample on a schedule. This is your drift detector for response quality. Sandbox right-sizing signals. Hosted Agents bill on the CPU/memory you allocate per session. Oversizing multiplies cost by your concurrency. Track CPU and available memory inside the sandbox and compare against the version's allocation — if peaks stay below ~50%, the next version should drop a tier; if they push above ~70%, raise it. Right-sizing is a per-version decision because versions are immutable. Per-version error and latency. Slice every standard metric by version ID. A canary that looks fine in aggregate can be quietly worse than the previous version on specific request shapes. Cost dimensions. Tag traces with customer_id or tenant_id if you have multi-tenancy. Aggregating session cost by tenant in App Insights is straightforward once the dimension is on the span. Alerts on shape, not just rate. A doubling in average response length or a sudden drop in tool invocation frequency often precedes a quality regression that error-rate alerts will miss entirely. A weekly "agent health" report in your team channel — pulling these App Insights queries together — beats a perfect dashboard nobody opens. A Pragmatic Maturity Path Most teams cannot build the whole loop on day one. A reasonable order: Infrastructure in Terraform. AIServices account, project, model deployment, ACR, App Insights, role assignment so the project MI can pull from ACR. First agent deployed manually with azd . Just to prove the round trip end to end. agent.yaml plus a deploy script that builds, pushes by digest, and creates a version. One environment. Three environments with manual promotion by manifest. A 20-row eval dataset with one grader, run on every PR. Advisory only at first. Eval as a blocking gate. Thresholds tuned from the advisory phase. Canary rollout via traffic split. Versions held live for a stability window before deletion. Production sampling into offline evaluation. Drift detection. Model version upgrade playbook. Documented, exercised once on a low-risk agent. Tested rollback via weight shift. The first time you discover a rollback bug should not be during an incident. Each step is independently useful. Skipping ahead — particularly to step 6 without time in step 5 — produces thresholds that block legitimate changes and erode trust in the pipeline. Where This Is Heading The platform is moving. A few things to watch as you build: Declarative Hosted Agent versions in Terraform. AzureRM coverage of Hosted Agents and agent versions is expanding. Parts of the deploy script will collapse into Terraform as that lands. The script-driven approach in this post is the bridge, not the destination. Continuous evaluation as a first-class platform feature. Sampling production traffic into scheduled evals — what you wire by hand today — is moving into the Foundry control plane. Multi-agent composition over A2A. As the A2A endpoint moves from preview to general availability and more frameworks ship A2A clients, multi-agent workflows become a first-class deployment shape. The DevOps loop extends — version pinning between agents, eval at the workflow level, observability across the agent graph — but the manifest grows accordingly. Toolbox-managed tool surfaces. As more tool integrations move behind the project Toolbox MCP endpoint, the agent image gets smaller and the tool configuration becomes a project-level concern. That changes what belongs in agent.yaml versus what belongs in Terraform. The throughline: the more the platform absorbs, the more your job shifts from wiring plumbing to defining policy. What "good" means for your agent, what the quality floor is, who can approve a model upgrade, how fast you can roll back. Those decisions do not get automated away. The pipeline just makes them executable. Conclusion Terraform provisions the Foundry project, model deployment, ACR, and observability. The DevOps loop on top of it — container builds pinned by digest, immutable agent versions, evaluation as a release gate, manifest-driven promotion across environments, traffic-split canary and rollback, and observability sliced by version — gets Hosted Agents to production and keeps them there. Build it incrementally. Treat the image digest and the version spec as the deploy artifact, not the source branch. Make evaluation a check the pipeline cares about. Use version weights as your rollout and rollback primitive. And design for the day the platform absorbs the next layer of plumbing, so that when it does, your work moves up the stack instead of getting thrown away.Building Agents in Production with Toolbox, Skills, and Tool Search
If you are shipping AI agents beyond a demo, you have felt the pain: every agent needs the same tools, each with its own authentication, and the tool list keeps growing until your prompt is bloated and the model picks the wrong one. On 22 July 2026 at 5:00 PM BST, the Microsoft Foundry community is running a 40-minute Discord round table to talk about exactly this, and to gather your feedback on three capabilities built to fix it: Toolbox, Skills, and Tool Search. This is a discussion, not a slideshow. Bring your real projects, including tool sprawl, duplicated skills, and authentication headaches, and help shape where these features go next. Join us in the Microsoft Foundry Discord community. Event at a glance What: Microsoft Foundry Discord Community Round Table: Building Agents in Production with Foundry Toolbox, Skills, and Tool Search When: 22 July 2026, 5:00 PM BST (40 minutes) Where: https://aka.ms/foundry/discord Event Link https://discord.gg/Z8JZsrP5P5?event=1527379174061379584 Format: Interactive discussion with voice and chat, live polls, and a short prioritisation exercise Who it's for: AI engineers and developers building and scaling agents in production Opening question we'll start with: "As your agents grow, how do you decide which tools to give them, and how do they pick the right one at runtime?" The problem: agents don't scale by hard-wiring every tool When several agents, or a mix of Foundry hosted agents, Microsoft Agent Framework, LangGraph, and Copilot SDK apps, need the same governed set of tools, you do not want to re-wire those tools and their authentication into every one. Two things break as you grow: Integration sprawl: the same tool gets wired, authenticated, and versioned separately in every agent. Tool overload: sending every tool definition to the model on every turn is slow, expensive, and hurts selection accuracy. The pattern that scales: package the tools once behind a single versioned, governed MCP endpoint, make them discoverable, and let every runtime consume them from the same URL. That is what Toolbox, Skills, and Tool Search deliver together. The three concepts we'll discuss Toolbox: build once, govern centrally, consume anywhere A Toolbox is a reusable, centrally managed bundle of tools exposed through a single MCP-compatible endpoint. Because it is a managed resource, you can add, remove, or reconfigure tools without changing agent code because every agent connects to the same endpoint. Immutable versioning gives you safe, atomic rollouts: build and test a new version on its pinned URL, then promote it to default, and every consumer picks it up with no redeployment. Skills: reusable, composable capabilities A Skill is a reusable, published set of behavioural instructions (a SKILL.md file following the open Agent Skills spec) that is registered once and reused across toolboxes and agents, for example, "summarize document" or "create calendar event". In a toolbox, a skill is not a callable tool: it surfaces as an MCP Resource on the same endpoint, so clients discover and read it with plain resources/list and resources/read, with no Foundry SDK required. Tool Search: runtime discovery instead of hard-wiring A real toolbox can hold dozens or hundreds of tools. Tool Search keeps that cheap for the model through progressive disclosure: instead of listing every tool, Foundry shows the model just two meta-tools, tool_search and call_tool, plus any pinned tools. The model searches for a capability by intent, Foundry ranks the toolbox's tools by match on name and description, and returns only the hits. The prompt stays small no matter how many tools the toolbox holds. How they fit together: Skills and tools live in a Toolbox; Tool Search lets agents scale to many tools without prompt bloat or manual wiring. You manage all of it from the Foundry portal or the Foundry Toolkit extension in VS Code. The scenario we'll walk through A user asks an agent to "summarize this email and schedule a follow-up." The agent uses Tool Search to find the right tools ("email summarization" and "calendar scheduling") from a shared Toolbox, chains them, and returns a result with no per-agent integration and no hard-coded tool list. Discussion prompt: "At what point does the number of tools in your agent start to hurt, and would Tool Search help?" A peek at the code (so you arrive ready) The full, runnable walkthrough lives in the Mastering Foundry Toolbox notebook in the microsoft-foundry/forgebook repo. The core spine is short. First, build a versioned toolbox from typed tool objects plus an optional list of skills: # Build an immutable toolbox version from typed tools + skills version = project.toolboxes.create_version( name=TOOLBOX_NAME, description="Search, code, knowledge, and connection-backed tools.", tools=tools, # e.g. WebSearchToolboxTool(...), AzureAISearchToolboxTool(...) skills=skills or None, # ToolboxSkillReference(name=..., version=...) - SEPARATE from tools ) print(f"Created {TOOLBOX_NAME} version {version.version}") Then turn the same tools into a search-first toolbox by adding the Tool Search meta-tool and pinning only your one or two hottest tools: from azure.ai.projects.models import ToolboxSearchPreviewToolboxTool, ToolConfig # Pin the hottest tool so it's always exposed; everything else is search-gated. tool_configs = {"web_search": ToolConfig(pin=True)} search_version = project.toolboxes.create_version( name=TOOLBOX_NAME, tools=tools + [ToolboxSearchPreviewToolboxTool(tool_configs=tool_configs)], skills=skills or None, ) Every consumer talks to the same MCP endpoint: one URL, any framework: # The default (promoted) version is served from one stable consumer URL def consumer_mcp_url(name): return f"{PROJECT_ENDPOINT.rstrip('/')}/toolboxes/{name}/mcp?api-version=v1" # Microsoft Agent Framework speaks MCP natively - just point it at the URL. # LangGraph (AzureAIProjectToolbox) and the GitHub Copilot SDK consume the same endpoint. How Toolbox simplifies the auth and identity flow This is one of the most important things to understand before you scale agents, and it is a great topic to bring questions on. A toolbox tool reaches a downstream system through a project connection, and the connection's authentication type decides whose identity is used. Get this right once and every consumer inherits correct, least-privilege access automatically, without writing OAuth or token-exchange plumbing in your agent code. Running a toolbox behind a hosted agent puts two identities in play, and the platform wires them together for you: Agent -> Toolbox (the trust boundary). The hosted agent authenticates to the toolbox MCP endpoint with its own agent identity, which holds the Foundry user role on the project. If the agent doesn't have access, the toolbox rejects the agent. This gates access to the toolbox itself, independent of any single tool. Toolbox -> Tool (the end-user passthrough). For oauth2 authentication, the agent forwards the caller's end-user Entra token, and the toolbox uses that token (on-behalf-of) to reach the downstream tool. The tool then acts on behalf of the real end user, providing per-user, least-privilege access with correct downstream audit. For non-passthrough authentication types (none, custom-keys, project-managed-identity, and agentic-identity), the toolbox authenticates using the connection's configured identity, and the agent never sees the secret. That is the "better-together" story: a stable, governable managed identity to the toolbox, plus true end-user identity on the downstream data call. What we'll cover in the 40 minutes https://discord.gg/Z8JZsrP5P5?event=1527379174061379584 Welcome & framing (0:00-0:08): what Toolbox, Skills, and Tool Search are, and how they fit together. Scenario walkthrough (0:08-0:13): the "summarize email, schedule follow-up" flow, end to end. Use cases & opportunities (0:13-0:22): which capabilities you would package as reusable Skills, how many tools your agents carry, and where Tool Search would help. Trust, security & governance (0:22-0:31): what you are comfortable exposing through a shared endpoint, how to scope which tools an agent may discover, authentication models, and the observability you need. Developer experience feedback (0:31-0:36): your biggest adoption blockers, missing docs, and the SDK samples and end-to-end demos you would prioritise. Prioritisation & next steps (0:36-0:40): vote live on the top use cases, challenges, and feature requests. Come prepared to talk about What tools and skills your agents use today, and how they're wired up. Which capabilities you'd turn into reusable, composable Skills shared across agents. How many tools your agents carry, and whether you hit prompt-size or tool-selection accuracy issues. Which tools you'd expose through a shared endpoint, and which need tighter scoping. How you want to control what an agent is allowed to discover and invoke with Tool Search. The examples, samples, and tutorials that would help you get started fastest. Responsible and secure by design Because these features let agents discover and invoke tools dynamically, governance is a first-class part of the conversation. Foundry toolboxes are governed by default: you can screen every tool's inputs and outputs with an RAI guardrail, front your MCP servers with a bring-your-own AI gateway (APIM), scope which tools are discoverable, and use least-privilege identity passthrough so downstream calls carry the real user's permissions and audit trail. Bring your enterprise safeguard requirements because they directly shape the roadmap. Note: Toolbox, Tool Search, and Skills are in preview; APIs and headers may change. Key takeaways Toolbox packages tools once behind a single governed, versioned MCP endpoint, so you can build once and consume from any framework. Skills are reusable, composable capabilities you register once and chain across agents. Tool Search uses two meta-tools and progressive disclosure so agents scale to hundreds of tools without prompt bloat. Auth is simplified: the agent's managed identity gates the toolbox, while end-user token passthrough gives correct, least-privilege downstream access with no OAuth plumbing in your code. Your feedback shapes the product because this round table feeds directly into the engineering and product teams. Save your spot Add it to your calendar: 22 July 2026, 5:00 PM BST. Join the community: https://aka.ms/foundry/discord Prep with the sample: run the Mastering Foundry Toolbox notebook to build, search, and consume a toolbox end to end. Read the docs: Toolbox, Tool Search, and Skills. Agents get more capable as they gain access to more tools and skills, but only if you can build, govern, and scale those capabilities without drowning in integration and prompt bloat. Come and share how you are doing it today, and help shape how Foundry does it next. See you on 22 July.Your Entire Agentic AI Workflow, Now Inside VS Code: New Course Available
If you build with AI, you know the tax: jumping between a browser portal to pick a model, a terminal to run it, a separate playground to test a prompt, and finally your editor to write the code. Every context switch is a small drain on focus—and it adds up. What if the whole loop lived in the one tool you never leave? That's the promise of the Foundry Toolkit for Visual Studio Code, and it's exactly what our new VS Code Learn: Foundry Toolkit video series is here to show youBuild an AI-assisted support email workflow with Power Automate and Microsoft Foundry
Difficulty: Intermediate A support email arrives with a product name, an error code, and a country. Before anyone can help, someone has to interpret the request, find the right team, record the case, and decide what to tell the customer. In this tutorial, you build that support email workflow with Microsoft 365, Power Automate, Azure Functions, and Microsoft Foundry. AI extracts the request details and recommends a support team. The flow checks the recommendation against a SharePoint catalog, asks a person to approve it, and creates an editable Outlook acknowledgement draft. The central design decision is who can do what: the model proposes a routing key; the flow validates it; a person approves draft creation. No customer-facing send action is included. What you will build Mina manages support operations at Aster Imaging, a fictional imaging-equipment company. Claire, a fictional distributor in France, reports error E42 on a NovaScan X2 after installing software version 4.2.1. When Mina approves the validated recommendation, the workflow produces: Input or decision Recorded result Claire's support email One case linked to its source message ID Validated AI recommendation Technical Support, NovaScan X2, France, EU Distributor Support Mina selects Approve Approval outcome and an editable acknowledgement draft Missing information, a risk flag, rejection, or timeout A case held in Needs Review The recorded approved case shows the review outcome and successful automation state: All names, products, organizations, and test messages are synthetic. This is a reference implementation for a lab, based on public support-form patterns, rather than a description of a company's internal process. Who this is for This walkthrough is for Power Platform makers and developers who can already create a cloud flow and a SharePoint list, and want to connect AI to a workflow with explicit review boundaries. You will use the Azure portal and a few terminal commands to deploy the supplied Function project. In this tutorial Architecture and resources Tutorial scope and boundaries Prerequisites Download the sample Step 1: Prepare the mailbox and SharePoint lists Step 2: Deploy and connect the AI classifier Step 3: Build and validate the support email flow Step 4: Add human approval, create a draft, and evaluate the workflow Troubleshooting Production considerations Clean up the lab Architecture and resources Workflow architecture The completed workflow follows this path: When Claire's message arrives in the shared mailbox, Power Automate first checks the message ID to avoid creating a duplicate case. It then sends the subject and body to the AI classifier. The classifier identifies the request as technical support, extracts NovaScan X2 and France , and recommends EU Distributor Support . Power Automate does not accept that recommendation without verification. It checks the structured response, confidence band, and risk flags, and confirms that the recommended routing key matches an active entry in the SupportTeams list. If the checks pass, the workflow records the case in SharePoint and asks Mina to review the recommendation. If Mina approves it, Power Automate creates an acknowledgement draft in Outlook. It does not send the message. If the recommendation has low confidence, contains a risk flag, fails validation, or is rejected by Mina, the case remains in Needs Review . Resource names To keep the steps consistent and easy to follow, this tutorial uses the resource names below. You can use different names in your environment, but keep track of the corresponding values as you work through the steps. Resource Name Power Platform environment RW Development Solution RW Global Support Intake Publisher prefix rw SharePoint site RW Lab SharePoint lists Cases , SupportTeams Shared mailbox RW Lab Support Main flow RW - Global Support Intake - v1 Azure resource group Your lab resource group; referenced as <RESOURCE_GROUP> Microsoft Foundry resource Your globally unique resource; referenced as <FOUNDRY_RESOURCE_NAME> Microsoft Foundry project The project opened in the Foundry portal; referenced as <FOUNDRY_PROJECT_NAME> Model deployment gpt-5.4-mini Azure Function App Your globally unique app; referenced as <FUNCTION_APP_NAME> Tutorial scope and boundaries This tutorial builds the workflow in stages so that each layer can be tested before the next one is introduced. Step 1 prepares the shared mailbox and SharePoint records. Step 2 deploys the AI model and exposes the bounded classifier to Power Automate. Step 3 builds the support email flow and validates normal, review, fallback, and duplicate paths before approval exists. Step 4 adds human approval and draft creation, then evaluates the completed workflow end to end. What this tutorial covers Create a shared mailbox, SharePoint case register, and allow-listed support-team catalog. Connect a bounded AI classifier that returns structured fields and an advisory routing key. Build deterministic deduplication, recommendation validation, and exception paths in Power Automate. Add a human approval checkpoint that creates an Outlook draft without sending it. Walk through three representative paths: accepted recommendation, review hold, and approval timeout. Record the remaining synthetic checks in a compact validation matrix. What is out of scope Send customer-facing email automatically. Let AI assign the final owner, approve a request, change SupportTeams , or send a message. Process real customer data, retrieve attachment contents, or scan attachments. The mailbox flow passes attachments = [] ; attachment-metadata checks are exercised only in the direct classifier tests. Merge a new follow-up email into an existing case. The duplicate guard checks the same message ID; a new reply has a different ID. Treat the prototype results as production accuracy, security, capacity, or SLA claims. Prerequisites A Microsoft 365 test tenant with Exchange Online and SharePoint Online A licensed test user who can open Outlook and SharePoint Permission to create a shared mailbox and assign mailbox delegation A Power Platform environment with Dataverse for the solution and approvals, and permission to use the Office 365 Outlook, SharePoint, Approvals, and custom connectors For a development-only lab, an eligible Power Apps Developer Plan environment; otherwise, Power Automate use rights that cover this flow and its custom connector An Azure subscription in which you can create or select a Microsoft Foundry resource, deploy a model, and create an Azure Functions app Permission to enable the Function app's managed identity and assign it the Cognitive Services OpenAI User role Node.js 22, Azure CLI, and Azure Functions Core Tools v4 on the workstation used for deployment; the tested Core Tools version is 4.0.7512 Permission to create custom connectors, connection references, environment variables, and solutions in the Power Platform environment Licensing and cost Microsoft 365 access alone does not establish entitlement to the custom connector used here. Confirm the target environment's license and data policies before building the flow. The Developer Plan includes custom connectors for development and testing; production use needs appropriate paid rights. See the Power Platform licensing FAQ. Azure model inference, Function hosting, storage, and monitoring can incur charges. Usage depends on the selected region, hosting plan, model, message size, and test volume. Check those resources in Azure Cost Management and clean up the dedicated lab resources when finished. The recorded evaluation is not a cost benchmark. Download the sample Get the companion code from the example project on GitHub. Clone the repository or download and extract the ZIP to a local folder. Use the extracted repository folder as the sample root in the commands below. The repository contains the Function source, locked dependencies, connector definition, synthetic data, setup instructions, and local tests. You build the Power Automate flow in the designer; this sample is not an importable Power Platform solution. Path from the sample root Purpose azure/global-support-classifier/ Deployable Azure Function project azure/global-support-classifier/connector/apiDefinition.swagger.json Custom connector definition; replace its sample host before import data/aster-imaging/support-teams.json Twelve sample team keys and descriptions data/aster-imaging/inquiries.json Twenty synthetic inquiries and expected results tests/aster-imaging-fixtures.test.mjs Offline dataset checks tests/global-support-classifier-regression.mjs Authenticated classifier evaluation evidence/classifier-regression-20260808.md Historical lab result and evaluation limits The model evaluation results come from the August 8, 2026 lab. This article combines recorded lab screenshots with configuration screens recaptured on September 8–9, 2026 for clearer step-by-step instructions. Recapturing a configuration screen does not verify a new workflow run. A separate single-request connector test on September 8, 2026 returned HTTP 200 and passed schema validation; its input and response are shown in Step 2. The GitHub v0.1.0 sample preserves the September 8, 2026 implementation snapshot, with repository setup documentation added on September 9. Portal labels, model availability, and quotas can differ in your tenant. Step 1: Prepare the mailbox and SharePoint lists In this step, you prepare the Microsoft 365 resources used by the workflow. The shared mailbox receives support requests, the SharePoint site provides a private workspace, the Cases list stores each request and its workflow state, and the SupportTeams list defines the support teams that the AI classifier is allowed to recommend. Services and tools used in this step Service Purpose Exchange Online Create the shared support mailbox and assign mailbox permissions. SharePoint Online Create the private team site and the Cases and SupportTeams SharePoint lists. Create the shared support mailbox The shared mailbox provides a single email address for support requests. Power Automate monitors this mailbox and starts the workflow when a new message arrives. For example, Claire sends her request to RW Lab Support , and the new message starts the support email flow. Open the Exchange admin center and go to Recipients > Mailboxes. Create a shared mailbox with these values: Display name: RW Lab Support Email alias: rw-lab-support Domain: your lab tenant's default domain Note: Creating the mailbox requires the Exchange Administrator or Global Administrator role. After creation, grant the lab user both Full Access and Send As. A Microsoft 365 license does not grant these permissions automatically. Review the current shared mailbox permissions and licensing rules before using this design in production. After the mailbox is created, delegate both permissions to the lab user: Full Access lets the user open and modify the shared mailbox. Send As lets the user create a draft using the shared mailbox address. Note: Full Access alone is not sufficient for the later draft-from-shared-mailbox step. To review delegation in the Microsoft 365 admin center, go to Teams & groups > Shared mailboxes, select RW Lab Support, and open Read and manage permissions. This is the Full Access permission described above. Select Add permissions to add the lab user. Return to the mailbox details and also configure Send as permissions for that user. Create the SharePoint site The SharePoint site provides a private workspace for the workflow's lists and case data. Keeping these resources on one site also makes permissions and ownership easier to manage. In this tutorial, RW Lab contains both the Cases list and the SupportTeams list used to process Claire's request. Open SharePoint and select Build in the left navigation. Under Start building, select Site. Then select Team site. If prompted to choose a template, select Standard team. Configure the site using the following values. Field Value Site name RW Lab Site description Synthetic global support workflow lab Group email address Accept the generated alias if it is available. Site address Confirm the generated SharePoint address. Privacy settings Private - only members can access this site Language English Important: The group email address and site address must be unique in your tenant, so SharePoint may adjust the generated values. You cannot change the site's default language after creation. The red boxes group the fields you can complete on this screen and the final Create site button. Check the generated site address separately. This annotated image uses the recorded lab screen. Select Create site, add owners or members if required, and finish the site setup. Create the Cases list The Cases list is the durable record after the flow has enough information to create a case. It stores source-message metadata, the AI proposal, the validated or fallback team, review outcome, and automation status. It does not copy the complete email body or attachments into SharePoint. For Claire's request, the flow first checks SourceMessageId , loads the active team catalog, calls the classifier, and validates the proposed routing key. It then creates one row containing the message metadata and AI result. A normal high-confidence row is updated as it moves through approval and draft creation. Low-confidence, risky, invalid-key, and classifier-unavailable requests are created directly as Needs Review . A duplicate creates no second row, and an unexpected failure before row creation appears only in the flow run history and the internal failure notification. Open SharePoint and select Build in the left navigation. Under Start building, select List, and then select Blank list. Enter Cases for Name, select RW Lab for Save to, and then select Create. SharePoint opens the new Cases list after creating it. In the Cases list, select Add column, choose the matching column type, and configure the columns shown in the following table. The Title column already exists by default; configure it as shown rather than creating another Title column. Note: In the current SharePoint interface, Text creates a single-line text column. Use Multiple lines of text for longer values such as Summary , RoutingReason , and AIProposal . Column Type Configuration Title Single line of text Required; stores the case ID SourceMessageId Single line of text Enforce unique values ReceivedAt Date and time Include time RequesterEmail Single line of text Synthetic test addresses only EmailSubject Single line of text Original subject InquiryType Choice Technical Support, Quote, Demo, Product Information, Partnership, Complaint, Other Product Single line of text AI-extracted canonical product name Country Single line of text AI-extracted country Summary Multiple lines of text AI-generated summary in plain text RecommendedRoutingKey Single line of text Routing key proposed by the AI classifier RecommendedTeam Single line of text Team name resolved from SupportTeams RoutingReason Multiple lines of text AI-provided reason for the recommendation ConfidenceBand Choice High, Medium, Low; use Low as the default for a new lab RiskFlags Multiple lines of text Risk signals returned by the classifier MissingFields Multiple lines of text Required information not found in the message AIProposal Multiple lines of text String form of the classification object, or a classifier-unavailable message ClassificationSource Single line of text Records validated recommendation, held recommendation, or classifier-unavailable fallback AssignedToText Single line of text Reviewer email resolved from SupportTeams Status Choice New, Classified, Needs Information, Awaiting Approval, Assigned, Needs Review, Failed DueAt Date and time Include time ApprovalOutcome Single line of text Approve, Reject, or Timeout ApprovalComment Multiple lines of text Plain text DraftMessageId Single line of text ID returned by the Outlook draft action AutomationStatus Choice Processing, Success, Review, Failed LastAutomationRun Date and time Include time Set SourceMessageId to enforce unique values. Power Automate also checks for the message ID before creating a row; the SharePoint constraint provides a second layer of duplicate protection. To verify the constraint, open Settings > List settings > SourceMessageId. Keep the type Single line of text, set Enforce unique values to Yes, and select OK if you changed it. Open Settings > List settings > ConfidenceBand. Enter High, Medium, and Low on separate lines, use the Drop-down menu display, and leave fill-in choices disabled. For your new list, set Default value to Low, then select OK. The existing lab default is High; use Low for a new build. Classified and Needs Information remain in the current lab list from the earlier implementation. The AI-recommendation path documented below does not write those two values. The current Catch scope also does not write Failed ; it sends an internal failure notification and terminates the run. Create a list view named Tutorial Evidence with Title, EmailSubject, Product, Country, RecommendedTeam, ConfidenceBand, Status, ApprovalOutcome, AutomationStatus, DraftMessageId, ClassificationSource, and ReceivedAt. Sort ReceivedAt newest first. Later validation steps use this view; use the row details pane for columns that do not fit on screen. Create the SupportTeams list The SupportTeams list defines the support teams or queues that the AI classifier is allowed to recommend. Power Automate uses it to validate each recommendation and resolve the reviewer and SLA target. It does not store individual team members or calculate routing from product and country. For Claire's request, the AI proposes eu_distributor_support . Power Automate confirms that this key is active and resolves it to EU Distributor Support , its reviewer, and its four-hour SLA target. Open SharePoint and select Build in the left navigation. Under Start building, select List, and then select Blank list. Enter SupportTeams for Name, select RW Lab for Save to, and then select Create. SharePoint opens the new SupportTeams list after creating it. In the SupportTeams list, select Add column, choose the matching column type, and configure the columns shown in the following table. The Title column already exists by default; configure it as shown rather than creating another Title column. Column Type Configuration Title Single line of text Display name RoutingKey Single line of text Enforce unique values TeamName Single line of text Support team name ApproverEmail Single line of text Reviewer address SLAHours Number No decimal places Active Yes/No Default Yes Important: Set RoutingKey to enforce unique values. This ensures that each AI recommendation resolves to exactly one support team. Power Automate accepts a recommendation only when the key matches an active row, then uses that row's team name, reviewer, and SLA target for the normal approval path. Open Settings > List settings > RoutingKey. Keep Single line of text, set Enforce unique values to Yes, and select OK. The September 9 lab capture below shows the existing No setting; it is a configuration gap, not the recommended setting for your new list. Add the 12 synthetic rows shown below. For closer parity with the direct evaluator, use each matching description in data/aster-imaging/support-teams.json as Title; the shorter titles below are the labels used in the original mailbox lab. The flow sends Title as the routing description, so changing it changes model input and requires a rerun. Replace each <YOUR_EMAIL> placeholder with the lab reviewer address. Title RoutingKey TeamName ApproverEmail SLAHours Active EU distributor support eu_distributor_support EU Distributor Support <YOUR_EMAIL> 4 Yes NA technical support na_technical_support NA Technical Support <YOUR_EMAIL> 4 Yes APAC distributor support apac_distributor_support APAC Distributor Support <YOUR_EMAIL> 4 Yes Software support software_support Software Support <YOUR_EMAIL> 4 Yes EU regional sales eu_regional_sales EU Regional Sales <YOUR_EMAIL> 8 Yes NA regional sales na_regional_sales NA Regional Sales <YOUR_EMAIL> 8 Yes APAC regional sales apac_regional_sales APAC Regional Sales <YOUR_EMAIL> 8 Yes Global partnerships global_partnerships Global Partnerships <YOUR_EMAIL> 8 Yes Global support global_support Global Support <YOUR_EMAIL> 8 Yes Security review security_review Security Review <YOUR_EMAIL> 1 Yes Privacy review privacy_review Privacy Review <YOUR_EMAIL> 1 Yes Safety and compliance safety_and_compliance Safety and Compliance <YOUR_EMAIL> 1 Yes Review the completed list. Confirm that all 12 rows show Active = Yes and that no RoutingKey value appears more than once. The recorded lab catalog contains 12 active teams with the routing keys and SLA hours shown above. This list view omits reviewer addresses; configure ApproverEmail for every row using your lab reviewer account. Step 2: Deploy and connect the AI classifier In Step 1, you created the shared mailbox and SharePoint lists that provide the workflow's email channel, case record, and approved support-team catalog. In this step, you add the AI classification layer. You deploy an Azure OpenAI model in Microsoft Foundry, connect it to an Azure Function, and expose the Function to Power Automate through a custom connector. For example, suppose Claire emails the shared mailbox to report that a NovaScan X2 in France shows error E42 during startup after software version 4.2.1 is installed. The classifier extracts NovaScan X2 as the product, France as the country, and technical_support as the inquiry type. It summarizes the problem, returns a high confidence band, and recommends the routing key eu_distributor_support . This result is only a proposal. The classifier cannot approve the request, assign an owner, update the case, or send email. In Step 3, Power Automate validates the proposed key against the active SupportTeams list before deciding whether the request can proceed to human approval. Services and tools used in this step Service or tool Purpose Microsoft Foundry (Azure OpenAI models) Create or select the Foundry resource and deploy the model used for classification. Azure Functions Call the model, enforce the structured response contract and guardrails, and expose a bounded HTTP endpoint. Microsoft Entra ID and Azure RBAC Allow the Function app to call the model through its managed identity. Power Automate custom connectors Make the Azure Function operation available to cloud flows. Power Platform solutions Package the custom connector, connection references, and environment variables used by the workflow. Note: The local deployment tools used in this step are Node.js 22, Azure CLI, and Azure Functions Core Tools. Create a Foundry resource and deploy the model An Azure subscription is the billing and access boundary. Inside that subscription, a Microsoft Foundry resource provides the model endpoint and quota. A Foundry project is the workspace you open in the Foundry portal, and a model deployment inside that project gives the Function app a stable deployment name to call. Creating a subscription or resource alone does not deploy a model. The tested lab uses gpt-5.4-mini , pinned to model version 2026-03-17 . It provides the structured output and instruction-following behavior needed by this bounded extraction and routing task without using a larger model for every incoming message. Sign in to the Azure portal and confirm that the correct directory and subscription are selected. Search for Microsoft Foundry, select Create, and create a Foundry resource if you do not already have one that the lab can use. Choose the target subscription and resource group, enter a globally unique resource name, select a region in which gpt-5.4-mini has quota, and keep the Standard S0 pricing tier. For a disposable lab, the basic public-network configuration is sufficient; use private networking and organization-approved controls for production. Note: You need permission to write the resource, such as Contributor or Owner, and separate model quota in the selected region. Microsoft documents the current resource fields in Create a Microsoft Foundry resource. Open the Microsoft Foundry portal and verify the directory and subscription. Select a project associated with the Foundry resource you created. If no project exists yet, create one under that resource and record its name as <FOUNDRY_PROJECT_NAME> . Enable the New Foundry experience if the portal offers the switch. On the project home page, select View deployments under Use a model. You can return to the same page later through Build > Deployments. On Deployed models, select Deploy > Deploy a base model, search for gpt-5.4-mini , and configure the deployment with the following tested values: Setting Tested value Deployment name gpt-5.4-mini Model version 2026-03-17 Deployment type Global Standard Capacity 100 thousand tokens per minute Version upgrade policy Once current version expires Content filter Microsoft.DefaultV2 Important: Capacity is quota, not a target for the tutorial. Select a lower value when your subscription has less quota; the synthetic lab traffic does not require 100K tokens per minute. If this model or version is unavailable in your region, choose an approved region or model only after confirming structured-output support, then repeat the final evaluation in Step 4 with that exact deployment. Select Deploy and wait until the deployment state is Succeeded. Record the resource endpoint and deployment name. The Function app uses the deployment name, not the catalog model label, when it constructs the request. The screenshot below is a verification view of the completed lab deployment, not the initial creation form. Optionally verify the deployed version from Azure CLI. This read-only command helps catch the common mistake of configuring the Function with a deployment that exists under another resource or subscription: az login az account set --subscription "<SUBSCRIPTION_ID>" az cognitiveservices account deployment show ` --resource-group "<RESOURCE_GROUP>" ` --name "<FOUNDRY_RESOURCE_NAME>" ` --deployment-name "gpt-5.4-mini" ` --query "{state:properties.provisioningState, model:properties.model.name, version:properties.model.version, sku:sku.name, capacity:sku.capacity}" The tested deployment returned Succeeded , model gpt-5.4-mini , version 2026-03-17 , SKU GlobalStandard , and capacity 100 . Review the current Microsoft guidance for deploying Foundry models and model version update policies because availability, quota, and portal labels can change. Create, configure, and deploy the Azure Function Create and configure the Azure resource in the portal, then use Azure Functions Core Tools to publish the tested repository project. Do not copy the individual JavaScript files into the portal editor; this project has multiple source files, locked npm dependencies, and automated tests that should remain together. In the Azure portal, select Create a resource, search for Function App, and select Create. Configure the Function app using the following tested lab values. If you already have a compatible Node.js 22 Function app, open it and continue with the identity step. Setting Tested lab value Subscription The subscription that contains the Foundry resource Resource group The lab resource group Function App name A globally unique name; record it as <FUNCTION_APP_NAME> Publish Code Runtime stack Node.js Version 22 Operating system Linux Region The lab region; the tested app uses East US 2 Hosting Consumption; the tested app uses the Y1 / Dynamic plan Note: Microsoft currently recommends Flex Consumption for new serverless Function apps. The implementation documented here was tested on Linux Consumption. If you select a different hosting plan, confirm its deployment and networking behavior before treating the tutorial results as equivalent. See Create a function app in the Azure portal. Select Review + create, select Create, and wait for the deployment to finish. Open the Function App resource and record its default host name from Overview. Under Settings > Identity, enable the system-assigned identity. On the Foundry resource, assign that identity the Cognitive Services OpenAI User role. The Function uses DefaultAzureCredential ; it does not store an Azure OpenAI API key. See the Microsoft guidance for managed identities in Azure Functions and Azure OpenAI role assignment. Under the Function app's environment variables or configuration settings, add these values: Setting Value AZURE_OPENAI_ENDPOINT Azure OpenAI endpoint, typically https://<FOUNDRY_RESOURCE_NAME>.openai.azure.com AZURE_OPENAI_DEPLOYMENT gpt-5.4-mini AZURE_OPENAI_API_VERSION 2024-10-21 Keep Show values disabled while capturing or sharing this page. The list should show the three setting names without exposing their values. Note: These are Azure Function app settings. They are separate from the rw_* Power Platform solution environment variables created later in this step. Download or clone the GitHub sample, open a terminal at the sample root, and move to the Function project: cd azure/global-support-classifier Verify the local tool versions, install the locked dependencies, and run the Function tests: node --version func --version npm ci npm test The tested deployment uses Node.js 22 and Azure Functions Core Tools 4.0.7512 . If func is not available, install a supported Core Tools v4 release by following the Core Tools installation guidance. In src/functions/classifySupportInquiry.js , locate buildAzureRequest and confirm that the GPT-5 request uses max_completion_tokens = 1100 and reasoning_effort = none . Do not add temperature or the older max_tokens field. GPT-5 reasoning models count reasoning and visible output against the completion-token budget; Microsoft documents the compatible parameters in Use reasoning models. Sign in with az login , select the intended subscription with az account set --subscription <SUBSCRIPTION_ID> , and confirm it with az account show --query name -o tsv . From the Function project directory, publish the complete project to the Function app: func azure functionapp publish <FUNCTION_APP_NAME> --javascript The --javascript option is explicit because automatic language detection did not identify this repository project during the tested publish. A successful publish reports Deployment completed successfully , synchronizes the classifySupportInquiry trigger, and prints its invoke URL. Core Tools packages and deploys the complete project from the current directory; review the Core Tools publishing guidance before using another hosting plan. Return to the Function App Overview page and confirm that classifySupportInquiry appears as an enabled HTTP function. This screen is meaningful only after the Core Tools publish succeeds. Define the response contract Open azure/global-support-classifier/src/functions/classifySupportInquiry.js and locate classificationSchema . Confirm that every property is required, bounded values use enumerations, and additionalProperties is false . Confirm that a successful call returns version 2.0 of this contract: { "schemaVersion": "2.0", "classification": { "inquiryType": "technical_support", "product": "NovaScan X2", "serialNumber": "NSX2-2407138", "country": "France", "organization": null, "urgency": "normal", "language": "en", "summary": "NovaScan X2 shows error E42 during startup after version 4.2.1.", "missingFields": [], "evidence": [ "NovaScan X2 serial NSX2-2407138", "error E42 during startup", "software version 4.2.1" ], "confidenceBand": "high", "riskFlags": [], "recommendedRoutingKey": "eu_distributor_support", "routingReason": "Technical support for NovaScan X2 in France routes to EU distributor support." } } Confirm that the contract includes recommendedRoutingKey , routingReason , and riskFlags . Power Automate stores all three and validates the key before resolving a team. Treat confidenceBand as a workflow category rather than a calibrated probability. Allow only high , medium , or low , and bound the risk values to prompt injection, unsupported attachment, privacy, safety, non-English, multiple-intent, low-confidence, and invalid-key signals. Supply the active team catalog with each request Open azure/global-support-classifier/connector/apiDefinition.swagger.json . Confirm that it is an OpenAPI 2.0 definition and that the request includes routingOptionsJson . Confirm that Power Automate will serialize each active catalog entry with this shape. The example below shows one of the 12 rows: [ { "routingKey": "eu_distributor_support", "teamName": "EU Distributor Support", "description": "Technical support for NovaScan products in Europe." } ] In classifySupportInquiry.js , confirm that the Function parses routingOptionsJson before constructing the model request. This string boundary avoids a Power Automate custom-connector metadata issue with arrays of objects; the model still receives a structured routingOptions array. Apply deterministic post-processing after the model response: detects prompt-injection phrases and unsafe attachment extensions; forces safety, privacy, and security signals to the corresponding review key when that key is active; removes a missing software version or screenshot flag when the source message contains that evidence; changes an unknown product-and-country result to low confidence; marks a recommendation invalid when its key is not in the supplied active catalog. Keep the Function advisory. These controls constrain the proposal, but Power Automate still performs the operational validation and assignment. The active destinations, reviewers, and SLA values live in SharePoint. The sample still encodes product/country routing precedence in the system prompt and post-processing code; changing that policy requires a code review and regression run as well as any catalog update. Keep attachment retrieval disabled for this version. The classifier supports attachment metadata and its direct regression tests exercise unsupported-attachment detection, but the live flow passes an empty attachments array and therefore does not inspect or block attachments. Create the custom connector Two different authentication boundaries are involved. The Function app calls Microsoft Foundry with its managed identity, so it stores no Azure OpenAI key. Power Automate calls the Function endpoint with x-functions-key ; that Function host key is not an Azure OpenAI key. Open azure/global-support-classifier/connector/apiDefinition.swagger.json from the sample root. Before importing the connector, replace its host value with <FUNCTION_APP_NAME>.azurewebsites.net . Keep basePath set to /api , the scheme set to https , and the operation ID set to ClassifySupportInquiryV3 . In Power Automate, select the RW Development environment. Open More > Discover all, find Data, and select Custom connectors. Select New custom connector > Import an OpenAPI file, enter RW Support Classifier , and upload apiDefinition.swagger.json . In the connector wizard, review General, Security, and Definition in order. On General, confirm HTTPS, your Function app's host name, and Base URL = /api, then select Security. Confirm API Key, Parameter label = Function key, Parameter name = x-functions-key, and Parameter location = Header. Select Definition and open Classify a support inquiry. Under Request, confirm POST, your Function URL ending in /api/classify-support-inquiry, and the required body parameter imported from the OpenAPI file. Continue with the response check below before creating the connector. The screenshots show an existing connector, whose toolbar displays Update connector instead of Create connector. Scroll farther down to Response and open 200 (Structured candidate fields). Confirm that References Used includes ClassifierResponse and Classification, and that Body exposes fields such as confidenceBand, routingReason, and schemaVersion. Select Back to return to the action definition, then select Create connector (or Update connector when modifying an existing connector). This screen checks the imported response definition; step 4 creates the authenticated connection and tests a real request. In the Azure portal, open the Function App's App keys page and create or copy a dedicated host key for this lab connection. Return to the connector's Test page, select New connection, enter that Function host key, and create the connection. Select the new connection (or your existing lab connection) and refresh the connection list if necessary. Under ClassifySupportInquiryV3, turn Raw Body on and paste the JSON below. Keep attachments as an empty array and routingOptionsJson as a JSON-encoded string. Select Test operation. In Response, confirm Status (200), schemaVersion = 2.0, a classification object, and Schema validation > Validation succeeded. Microsoft documents the current import and test flow in Create a custom connector from an OpenAPI definition. { "subject": "NovaScan X2 error E42 - France", "body": "NovaScan X2 serial NSX2-2407138 shows error E42 during startup after software version 4.2.1 was installed.", "from": "claire.martin@alpine-distribution.example.test", "attachments": [], "routingOptionsJson": "[{\"routingKey\":\"eu_distributor_support\",\"teamName\":\"EU Distributor Support\",\"description\":\"Technical support for NovaScan products in Europe.\"}]" } Important: The Function key belongs in the secure Power Platform connection. Do not put it in a text environment variable, flow action, screenshot, or source file. The September 8, 2026 request returned technical_support, France, confidenceBand = high, no risk flags, and recommendedRoutingKey = eu_distributor_support. This verifies one connector request; the flow still needs to apply its acceptance gate and obtain human approval. Add the components to the solution Open Solutions and create RW Global Support Intake . Create or select a publisher with prefix rw so the environment-variable schema names below match. Open the solution, select Objects, and use the object-type tree to review its components. Select Add existing, add the RW Support Classifier custom connector, and confirm that Custom connectors (1) appears in the object tree. Select New > More > Connection Reference and create these four named references: Office 365 Outlook SharePoint Standard approvals RW Support Classifier Select New > More > Environment variable and create these five variables: Display name Example schema name Current value Support Mailbox rw_SupportMailbox Shared mailbox address SharePoint Site URL rw_SharePointSiteURL RW Lab site URL Default Approver Email rw_DefaultApproverEmail Lab reviewer address Cases List Name rw_CasesListName Cases Support Teams List Name rw_SupportTeamsListName SupportTeams In Objects, select Connection references, Custom connectors, and Environment variables in turn. Confirm that the four required references, one connector, and five variables are present before creating the flow. The lab solution contains the four required connector types and additional automatically generated Outlook and SharePoint references. Match each flow action to its intended connection; the extra rows are not additional connector types to create. The five variables in the table are present. Routing Rules List Name is retained from an earlier lab design and is not required by this AI-recommendation workflow. Step 3: Build and validate the support email flow In this step, you build the flow that turns the bounded AI output from Step 2 into a validated recommendation. The flow checks duplicates, resolves an active team, applies the acceptance gate, and records uncertain or unavailable-classifier requests for human review. You then test both the normal validation path and the exception paths before adding approval in Step 4. Services and tools used in this step Service or tool Purpose Power Automate Build the automated cloud flow, scopes, conditions, and state transitions. Office 365 Outlook connector Start the flow when a message arrives in the shared mailbox. SharePoint connector Check for duplicates, load active support teams, and create review or fallback case rows. RW Support Classifier custom connector Send the message and active routing catalog to the Azure Function classifier. Create and configure the flow Use the action names shown below before writing expressions. In expression references, spaces become underscores: GetItems ExistingCase is referenced as GetItems_ExistingCase . Rename the custom connector action Classify Support Inquiry so its reference is Classify_Support_Inquiry . Select the matching dynamic-content token if your designer generated a different internal name. Enter formulas in the Expression editor without a leading @ . Values containing @{...} below are inline expressions in a text field. In this lab, enter the documented SharePoint list names directly in the connector; the list-name environment variables record configuration but are not automatically substituted into every action. Open RW Global Support Intake , select Objects > New > Automation > Cloud flow > Automated, and create RW - Global Support Intake - v1 . Add When a new email arrives in a shared mailbox (V2) and configure the trigger: Trigger field Value Original Mailbox Address rw_SupportMailbox current value Folder Inbox Importance Any Only with Attachments No Include Attachments No In Trigger NewSharedMailboxEmail > Parameters, select your shared mailbox under Original Mailbox Address. Open Advanced parameters to expose the four settings shown above: Importance = Any, Only with Attachments = No, Include Attachments = No, and Folder = Inbox. The September 9 lab capture displays an onmicrosoft.com address in the mailbox picker; select the mailbox you configured in Step 1 rather than copying the lab address. Open the trigger's Settings, turn on Concurrency Control, and set Degree of Parallelism to 1 . This serializes the lab runs, including time spent waiting for approval. A pending approval can delay the next email for 30 minutes. Use this setting for controlled tests; a design that processes new emails separately from approvals is needed before evaluating throughput. The current designer labels the concurrency switch Limit. The screenshot was captured at 125% browser zoom and cropped to the settings panel so the switch and value remain readable. After the trigger, select Add an action > Variable > Initialize variable for each row below. Keep every initializer above the Try scope and in the listed order: Variable Type Initial value CaseId String concat('AST-',formatDateTime(utcNow(),'yyyyMMdd'),'-',toUpper(substring(guid(),0,8))) InquiryType String Empty Product String Empty Country String Empty RecommendedTeam String Global Support ApproverEmail String rw_DefaultApproverEmail current value SLAHours Integer 8 RecommendedRoutingKey String Empty RoutingReason String Empty ConfidenceBand String Empty RiskFlags String Empty MissingFields String Empty For CaseId, enter the expression from the table through the Value field's expression editor, then select Add (or Update when editing an existing expression). The purple concat(...) token confirms that Value contains an expression. Select that token to reopen and check the full formula, as shown above. For SLAHours, set Name = SLAHours, Type = Integer, and Value = 8, as shown below. The other eleven variables in the table use String. Repeat the same Name, Type, and Value fields for each variable; where the table says Empty, leave Value blank. Keep all twelve initializers between the trigger and Scope Try. Compare the action order in these two views. The first red box contains CaseId through ApproverEmail; the second continues with SLAHours through MissingFields. Keep all twelve initializers outside and before Scope Try. These configuration views show placement; use the table above for each variable's type and initial value. Select Add an action > Control > Scope twice. Rename the first scope Scope Try and the second Scope Catch . On Scope Catch , select Configure run after and select has timed out, is skipped, and has failed for Scope Try . Inside Catch, add Send an email (V2) to the default approver with the CaseId and workflow run name, followed by Terminate with Status = Failed, Code = RW_INTAKE_FAILED , and an internal-only error message. In the current designer, open Settings > Run after, then expand Scope Try to reveal its result checkboxes. Leave Is successful unchecked. These are alternative results: any one of the three selected results allows Catch to run. Open SendEmail InternalFailure > Parameters. Set To to your internal default approver. In Subject, enter [RW Support Flow] Failed run followed by the CaseId variable token. In Body, write a short failure notice, add the CaseId token, and insert the expression workflow()?['run']?['name'] for the run reference so the reviewer can locate the failed run. For a new build, enter ordinary text in the rich-text Body editor, such as The support email flow failed., followed by the case ID, run reference, and Review the flow run before retrying. Do not paste HTML tags into the rich-text editor. The recorded configuration below contains escaped HTML tags as literal text; this is an existing formatting issue, not the recommended body format. This capture documents the saved inputs; the flow was not changed or rerun. Select Terminate Failed > Parameters and set Status to Failed and Code to RW_INTAKE_FAILED . For Message, use Global Support Intake failed; see the internal notification for the run reference. The canvas on the right shows where this action belongs: immediately after the internal notification inside Scope Catch. Note: The current Catch scope sends an internal notification and fails the run. It does not create a new Cases row or update an existing row to Failed. Add the duplicate guard Inside Scope Try , add SharePoint > Get items and rename it GetItems ExistingCase . Get items field Value Site Address rw_SharePointSiteURL current value List Name Cases Filter Query SourceMessageId eq '@{triggerOutputs()?['body/id']}' Top Count 1 In GetItems ExistingCase > Parameters, choose your site and the Cases list. Under Advanced parameters, enable Filter Query and Top Count. Keep the trigger's Message Id token inside the single quotes in the filter, and enter 1 for Top Count, as highlighted in this September 9 configuration capture. Add Data Operation > Compose, rename it Compose ExistingCaseCount , and use length(body('GetItems_ExistingCase')?['value']) . Open the Inputs expression editor in Compose ExistingCaseCount, enter length(body('GetItems_ExistingCase')?['value']), and apply it. This September 9 capture shows the existing expression opened for inspection, so the button is labeled Update. 3. Add a Condition, rename it Condition Duplicate , and test whether the Compose output is greater than 0 . In Condition Duplicate > Parameters, select Outputs from Compose ExistingCaseCount on the left, choose is greater than, and enter 0 on the right. The operator menu is open in this September 9 capture so its full label is visible. 4. In the True branch, add Terminate with Status = Succeeded. Leave case creation out of this branch. Build the remaining email-processing actions in the False branch. Place Terminate Duplicate in the True branch and set Status to Succeeded. Continue with GetItems ActiveSupportTeams and Select RoutingOptions in the False branch. This September 9 configuration capture shows both paths beside the termination setting. Load the catalog and call the classifier In the duplicate condition's False branch, add SharePoint > Get items and rename it GetItems ActiveSupportTeams . Get items field Value Site Address rw_SharePointSiteURL current value List Name SupportTeams Filter Query Active eq 1 Top Count 100 Select SupportTeams as the list. Under Advanced parameters, set Filter Query to Active eq 1 and Top Count to 100. This September 9 capture shows the active catalog query. Add Data Operation > Select, rename it Select RoutingOptions , set From to the value output from GetItems ActiveSupportTeams , and create this mapping: Key Value routingKey item()?['RoutingKey'] teamName item()?['TeamName'] description item()?['Title'] Use value from GetItems ActiveSupportTeams for From. Map routingKey to RoutingKey, teamName to TeamName, and description to Title. This September 9 capture shows the dynamic-content version of the expressions above. Add a Control > Scope, rename it Scope AI Recommendation , and place RW Support Classifier > Classify support inquiry inside it. Rename the classifier action Classify Support Inquiry and configure it: Input Value subject Subject from the mailbox trigger body Body from the mailbox trigger from From from the mailbox trigger attachments Empty array [] routingOptionsJson string(body('Select_RoutingOptions')) Select Subject, Body, and From from the mailbox trigger. Expand Advanced parameters to show from and attachments; keep the attachments array empty by adding no items. The September 9 designer labels these inputs with a Body/ prefix. For Body/routingOptionsJson, open the expression editor and enter string(body('Select_RoutingOptions')). Apply the expression with Add, or Update when editing an existing value as shown here. This converts the Select output array into the string expected by the connector. After the AI scope, add a Condition named Condition AIRecommendationAvailable . Use Configure run after so the condition runs when the AI scope succeeds, fails, is skipped, or times out. The True path is actions('Scope_AI_Recommendation')?['status'] equals Succeeded ; use the False path for the classifier-unavailable case. Open Settings > Run after, expand Scope AI Recommendation, and select all four statuses: Is successful, Has timed out, Is skipped, and Has failed. This September 9 configuration lets the next condition evaluate the AI scope even when the classifier is unavailable. Return to Parameters. In the left field, use the expression actions('Scope_AI_Recommendation')?['status']; select is equal to and enter Succeeded on the right. The empty row underneath is the designer's next-row placeholder. The True branch handles a successful AI call; the False branch handles an unavailable classifier. Validate the returned recommendation In the AI-available True branch, add Set variable actions in this order: Variable Value InquiryType Use the enum-to-choice mapping immediately below; unmatched values become Other Product coalesce(body('Classify_Support_Inquiry')?['classification']?['product'],'') Country coalesce(body('Classify_Support_Inquiry')?['classification']?['country'],'') RecommendedRoutingKey body('Classify_Support_Inquiry')?['classification']?['recommendedRoutingKey'] RoutingReason body('Classify_Support_Inquiry')?['classification']?['routingReason'] ConfidenceBand if(equals(body('Classify_Support_Inquiry')?['classification']?['confidenceBand'],'high'),'High',if(equals(body('Classify_Support_Inquiry')?['classification']?['confidenceBand'],'medium'),'Medium','Low')) RiskFlags join(body('Classify_Support_Inquiry')?['classification']?['riskFlags'],'; ') MissingFields join(body('Classify_Support_Inquiry')?['classification']?['missingFields'],'; ') For Set InquiryType , select the InquiryType variable, open the Value expression editor, and paste the following mapping. The recorded flow uses nested if expressions in this action: if(equals(body('Classify_Support_Inquiry')?['classification']?['inquiryType'],'technical_support'),'Technical Support', if(equals(body('Classify_Support_Inquiry')?['classification']?['inquiryType'],'quote_request'),'Quote', if(equals(body('Classify_Support_Inquiry')?['classification']?['inquiryType'],'demo_request'),'Demo', if(equals(body('Classify_Support_Inquiry')?['classification']?['inquiryType'],'product_information'),'Product Information', if(equals(body('Classify_Support_Inquiry')?['classification']?['inquiryType'],'partnership'),'Partnership', if(equals(body('Classify_Support_Inquiry')?['classification']?['inquiryType'],'complaint'),'Complaint','Other')))))) Select Add for a new expression, or Update when editing an existing one. The mapping is: Classifier value SharePoint Choice label technical_support Technical Support quote_request Quote demo_request Demo product_information Product Information partnership Partnership complaint Complaint Default, including other Other Add SharePoint > Get items, rename it GetItems RecommendedSupportTeam , and configure it: Get items field Value Site Address rw_SharePointSiteURL current value List Name SupportTeams Filter Query RoutingKey eq '@{variables('RecommendedRoutingKey')}' and Active eq 1 Top Count 1 Open GetItems RecommendedSupportTeam > Parameters. Select your SharePoint site and SupportTeams list. Under Advanced parameters, show Filter Query and Top Count. Insert the RecommendedRoutingKey variable between single quotes in the filter, retain and Active eq 1, and set Top Count to 1. Add Compose, rename it Compose TeamMatchCount , and use length(body('GetItems_RecommendedSupportTeam')?['value']) . In Compose TeamMatchCount > Parameters > Inputs, open the Expression editor and enter the expression above. Select Add for a new expression, or Update when editing an existing one. The result counts the rows returned by GetItems RecommendedSupportTeam. 4. Add Condition RecommendationAccepted and require every gate below: The acceptance gate requires all five checks: team match count = 1 AND ConfidenceBand = High AND riskFlags length = 0 AND missingFields length = 0 AND RecommendedRoutingKey is not empty Open Condition RecommendationAccepted > Parameters and use And to require all five checks. The September 9 lab screen above uses a team count greater than 0; the expression below uses a count equal to 1. With Top Count = 1, these checks have the same result, and neither detects duplicate catalog rows: enforce the unique RoutingKey constraint in SharePoint. The final empty row is the designer's next-row placeholder. Use this expression for the gate and compare its output with the Boolean true : and( equals(outputs('Compose_TeamMatchCount'),1), equals(variables('ConfidenceBand'),'High'), empty(body('Classify_Support_Inquiry')?['classification']?['riskFlags']), empty(body('Classify_Support_Inquiry')?['classification']?['missingFields']), not(empty(variables('RecommendedRoutingKey'))) ) Enable the unique RoutingKey constraint before relying on one returned row as an unambiguous match. The September 9 configuration check found this constraint disabled in the existing lab. Its recorded results therefore do not demonstrate protection against duplicate catalog keys; the new-build instructions in Step 1 require that protection. The model's confidence category is not a calibrated probability. Also, this sample holds every non-empty risk list, including product-alias and non-English flags. Those flags do not all indicate danger; the broad hold is a conservative lab policy with a review-volume tradeoff. In the accepted True branch, set RecommendedTeam to first(body('GetItems_RecommendedSupportTeam')?['value'])?['TeamName'] , ApproverEmail to first(body('GetItems_RecommendedSupportTeam')?['value'])?['ApproverEmail'] , and SLAHours to int(first(body('GetItems_RecommendedSupportTeam')?['value'])?['SLAHours']) . Leave space after these actions; Step 4 adds case creation, approval, and draft creation to this branch. In the False branch, add SharePoint > Create item named CreateItem NeedsReview . Store the AI fields, set Status = Needs Review, AutomationStatus = Review, and ClassificationSource = AI recommendation held for human review . Do not add an approval action. In the AI-available condition's False branch, add Create item named CreateItem ClassifierUnavailable . Use the fallback Global Support values, set InquiryType = Other, ConfidenceBand = Low, Status = Needs Review, AutomationStatus = Review, AIProposal = AI classifier unavailable or returned an invalid response. , and ClassificationSource = Classifier unavailable / human review . In CreateItem ClassifierUnavailable, set Summary to the mailbox trigger's Subject. The red boxes below show the fallback fields in the existing action. Under Advanced parameters, also add ConfidenceBand Value and select Low explicitly. The captured action omits that field and therefore inherits the existing list default, High; the screenshot does not show the recommended Low setting. Leave other classifier-derived fields empty and do not reference the failed classifier action's body. The matched SupportTeams row supplies RecommendedTeam, ApproverEmail, and SLAHours on the accepted recommendation path. Review rows created in this step store the AI reason and proposal; Step 4 stores the same evidence when it creates an accepted case. In both paths, the active catalog remains the operational allow-list. The current flow also initializes fallback values before the Try scope: Global Support , the default approver, and an eight-hour SLA. An invalid-key or classifier-unavailable review case can therefore retain fallback reviewer and SLA values without resolving a matching SupportTeams row. This is the actual lab behavior, not an additional validated assignment. Map the case fields consistently Use the following mapping on both review-case creation actions and on CreateItem Case in Step 4. Then apply each branch's Status, AutomationStatus, ClassificationSource, and AIProposal values. For the unavailable-classifier branch, use the trigger Subject for Summary, leave other classifier-derived fields empty, and write the explicit fallback message; do not reference the failed action's body. Cases field Value Title variables('CaseId') SourceMessageId Message Id dynamic content from the trigger, the same value used by the duplicate guard ReceivedAt Date Time Received dynamic content from the trigger RequesterEmail Sender's email address from the trigger, without the display name EmailSubject Subject from the trigger InquiryType, Product, Country Corresponding variables; fallback InquiryType is Other RecommendedRoutingKey, RoutingReason, RiskFlags, MissingFields Corresponding variables ConfidenceBand Corresponding variable, or explicit Low for classifier unavailable RecommendedTeam variables('RecommendedTeam') for accepted and classifier-unavailable cases; use the branch-specific expression below for NeedsReview AssignedToText variables('ApproverEmail') DueAt addHours(utcNow(),variables('SLAHours')) Summary body('Classify_Support_Inquiry')?['classification']?['summary'] when available AIProposal string(body('Classify_Support_Inquiry')?['classification']) when available LastAutomationRun utcNow() For CreateItem NeedsReview, set RecommendedTeam to if(greater(outputs('Compose_TeamMatchCount'),0),first(body('GetItems_RecommendedSupportTeam')?['value'])?['TeamName'],'Unvalidated recommendation') . This preserves the catalog team name when a match exists and records Unvalidated recommendation when none exists. The review branch does not run the accepted branch's Set ApproverEmail or Set SLAHours actions, so AssignedToText and DueAt retain the initialized default reviewer and eight-hour SLA. A displayed catalog team name does not mean the recommendation passed the acceptance gate. This mapping was checked in the existing configuration; no new run was performed. On every later Update item, use the ID returned by that branch's Create item and preserve Title = CaseId. Do not accidentally use the source email ID as the SharePoint item ID. DueAt is a simple target timestamp from processing time; this tutorial does not implement business calendars or SLA escalation. Check the flow Save the flow. Open Flow checker and resolve every reported error or warning before testing. At this stage, Flow checker should report zero errors and zero warnings before you send the validation messages: The highlighted toolbar button opens Flow checker. This designer check reports zero errors and warnings in the captured flow; it does not verify approval delivery, mailbox access, or runtime outcomes. Validate those paths with the test cases below. Test the normal validation path Send this complete synthetic inquiry to the shared mailbox: Subject: NovaScan X2 error E42 - France - software version 4.2.1 Hello Aster Support, We are a distributor in France. NovaScan X2 serial NSX2-2407138 shows error E42 during startup after installing software version 4.2.1. We captured the error screenshot. Regards, Claire In Power Automate, open Solutions > RW Global Support Intake > Objects > Cloud flows > RW - Global Support Intake - v1. Under 28-day run history, select the new run and confirm that the duplicate guard, classifier, active-team lookup, and Condition RecommendationAccepted succeeded. Inspect the classifier and variable actions in the run. Confirm that the flow produced Technical Support, NovaScan X2, France, High confidence, no risk flags or missing fields, eu_distributor_support , and a successful match to EU Distributor Support. Confirm that the acceptance condition followed its True branch. At this point, the flow has validated the recommendation but has not created the accepted case or approval request. Step 4 adds those actions to the True branch. This separation lets you verify the routing boundary before introducing consequential workflow actions. Test one representative review path A green normal run does not prove that uncertainty is held safely. Use one intentionally incomplete message to exercise the review boundary without repeating every exception as a full walkthrough. Send this intentionally incomplete message to the shared mailbox: Subject: Help needed - low confidence routing test A device stopped working somewhere. Please route this request. Open RW Lab > Cases > Tutorial Evidence, locate the newly created row by its subject and received time, and record its generated CaseId. Confirm that Product and Country are empty, RecommendedTeam = Global Support, ConfidenceBand = Low, RiskFlags = Low confidence, and Status = Needs Review. Open the corresponding flow run, expand the action groups, and confirm that Condition RecommendationAccepted followed the False branch and CreateItem NeedsReview succeeded. The screenshot below shows a separate prompt-injection case held in review. It illustrates the risk-flag gate, rather than the incomplete-message test just described. Your generated CaseIds will be different. Record the remaining Step 3 checks Run the remaining checks separately, but summarize them rather than repeating the same send–open run–open row sequence. Record both the validation surface and the observed boundary: Check Validation surface Observed boundary Structured prompt-injection risk Live mailbox and flow run Security Review recommendation remained Needs Review because riskFlags was non-empty. Azure content filter or invalid classifier response Live mailbox and flow run CreateItem ClassifierUnavailable stored the fallback proposal and Needs Review / Review . Invalid routing key Function test plus flow-gate inspection invented_team was forced to Low confidence; a zero-row team lookup cannot pass the acceptance gate. Duplicate message ID Resubmitted completed run Terminate Duplicate succeeded and no second Cases row was created. Note: Historical screenshots may show High on a classifier-unavailable row because the original list defaulted to High. The instructions above explicitly use Low for new fallback rows. ClassificationSource identifies the unavailable-model case; Low here is a conservative fallback value, not a model assessment. Step 4: Add human approval, create a draft, and evaluate the workflow In this step, you complete the accepted recommendation path. A reviewer decides whether to accept the proposed team, and an approval may create an editable acknowledgement draft, but no branch sends that draft to the requester. You walk through the approved path and the actual PT30M timeout boundary, then summarize the remaining stateful checks and classifier evaluation. Services and tools used in this step Service or tool Purpose Power Automate and Approvals Present the AI recommendation to the reviewer and branch on the human decision. SharePoint connector Create the accepted case and update its approval and automation states. Office 365 Outlook connector and Outlook Create an editable acknowledgement draft and confirm that no message was sent automatically. Azure Functions and Microsoft Foundry Run the authenticated classifier evaluation against the deployed implementation. Note: The local evaluation tools used later in this step are Node.js 22 and PowerShell. Configure approval and case-state updates In the accepted-recommendation branch, add SharePoint > Create item and rename it CreateItem Case . Map the trigger metadata and classifier fields to the corresponding Cases columns, then set these operational fields: Cases field Value RecommendedTeam RecommendedTeam variable AssignedToText ApproverEmail variable DueAt addHours(utcNow(),variables('SLAHours')) AIProposal string(body('Classify_Support_Inquiry')?['classification']) ClassificationSource AI recommendation validated by SupportTeams Status New AutomationStatus Processing Open CreateItem Case > Parameters and select your SharePoint site and Cases list. Under Advanced parameters, set Title to the CaseId variable. Select Message Id, From, and Subject from the mailbox trigger for SourceMessageId, RequesterEmail, and EmailSubject, respectively. Continue with the classifier and operational fields in the tables above. Scroll down within CreateItem Case > Parameters. Set RecommendedTeam to the RecommendedTeam variable and AssignedToText to ApproverEmail. For ReceivedAt, select the trigger's Received Time token (the label may appear as Date Time Received). Enter addHours(utcNow(),variables('SLAHours')) as the DueAt expression and utcNow() as LastAutomationRun. Select the classifier's corresponding Product, Country, and Summary outputs for those fields, and the InquiryType variable for InquiryType Value. Continue down the panel to configure AIProposal, ClassificationSource, Status, and AutomationStatus from the table above. Continue down CreateItem Case > Parameters. Set Status Value to New and AutomationStatus Value to Processing. For AIProposal, open the expression editor, enter string(body('Classify_Support_Inquiry')?['classification']), and select Add (or Update for an existing expression). This stores the classifier's classification object as text. The collapsed token in the screenshot displays string(...); select it to inspect the full expression. Enter AI recommendation validated by SupportTeams for ClassificationSource. Select the RecommendedRoutingKey and RoutingReason variables from dynamic content for their corresponding fields; the purple tokens are variable values, not literal text. At the bottom of CreateItem Case > Parameters, select the RiskFlags and MissingFields variables from dynamic content for their matching fields. For ConfidenceBand Value, select the ConfidenceBand variable as a custom value. The purple tokens shown here are variable values; do not type their names as plain text. This screenshot belongs to the accepted-recommendation branch. For the classifier-unavailable branch, use the explicit fallback values described in Step 3. Add SharePoint > Update item named UpdateItem AwaitingApproval . Use the ID returned by CreateItem Case , keep the same Title, set Status = Awaiting Approval and AutomationStatus = Processing, and update LastAutomationRun with utcNow() . Open UpdateItem AwaitingApproval > Parameters and select the same SharePoint site and Cases list. Select ID from CreateItem Case for Id. Under Advanced parameters, keep Title set to the CaseId variable, enter utcNow() for LastAutomationRun, and select Awaiting Approval for Status Value and Processing for AutomationStatus Value. This records the waiting state before the approval request starts. Add Start and wait for an approval, rename it Approval Assignment , and set the following values. Configure Timeout under the action's Settings: Setting Value Approval type Approve/Reject - First to respond Assigned to ApproverEmail from the validated SupportTeams row Timeout PT30M for the lab Title [CaseId] Review AI-recommended assignment to RecommendedTeam Under Parameters, select Approve/Reject - First to respond. Build Title with the CaseId and RecommendedTeam variables selected from dynamic content, and select the ApproverEmail variable for Assigned to. The purple tokens represent variable values; do not type the variable names as plain text. Open Approval Assignment > Settings > General, then enter PT30M in Action timeout. This sets the approval wait to 30 minutes. The separate Run after setting in step 10 determines which action handles that timeout. Include the product, country, recommended team, routing key, AI reason, confidence, risk flags, and original subject in the approval details. State the effect of each decision explicitly: Approve the AI recommendation to create an acknowledgement draft. Reject to keep the case in human review. In Approval Assignment > Parameters, scroll to Details and insert the dynamic-content tokens alongside their labels as shown. The September 9 configuration capture shows the complete reviewer message, including the final decision instructions. After the approval action, add a Condition named Condition Approved . Keep run after = is successful only and test body('Approval_Assignment')?['outcome'] equals Approve . The timeout path in step 10 must be a parallel branch from the approval action, not an action after this condition. Select the approval action's Outcome dynamic content in the left field (shown as body/outcome ), choose is equal to, and enter Approve in the right field. The highlighted row is the comparison to configure. Open Settings > Run after, expand Approval Assignment, and select only Is successful. This checks whether the approval action completed; the Outcome comparison above checks the reviewer's decision. A completed rejection follows the condition's False branch. A timed-out approval follows the separate timeout branch in step 10. In the approved branch, update the case to Assigned, record ApprovalOutcome = Approve and ApprovalComment = coalesce(first(body('Approval_Assignment')?['responses'])?['comments'],'') , and keep AutomationStatus = Processing. Open UpdateItem Approved in the True branch of Condition Approved. Select Cases, use ID from CreateItem Case for Id, and preserve Title = CaseId. Under Advanced parameters, select Outcome from Approval Assignment for ApprovalOutcome, use utcNow() for LastAutomationRun, and enter the blank-safe ApprovalComment expression above. The captured lab configuration shows its original first(...) token. Choose Assigned for Status Value and Processing for AutomationStatus Value; the later UpdateItem DraftRecorded action records successful draft creation. Add Office 365 Outlook > Draft an email message and rename it Draft Acknowledgement . Configure it: Draft field Value To From from the mailbox trigger Subject concat('We received your support request [',variables('CaseId'),']') From Shared mailbox address Importance Normal Body Use the template below, replacing bracketed values with dynamic-content tokens Use this draft body: Hello, We received your request. A reviewer approved the proposed assignment to our support team. Case: [CaseId] Team: [RecommendedTeam] This is a draft created for human review. It has not been sent automatically. Select the trigger's From token for To. Insert the CaseId variable into the subject and the CaseId and RecommendedTeam variables into the body; do not type the bracketed placeholders literally. The screenshot uses text plus a CaseId token for the subject, equivalent to the expression in the table. Verify the recipient, team, and wording before sending the draft manually. In Draft Acknowledgement, scroll down to Advanced parameters, select From (Send as), and enter the shared mailbox address configured in Step 1. The September 9 configuration capture below highlights this field. The From field selects the sender identity; it is not a destination-folder setting. Inspect Drafts for the account used by the Outlook connection and confirm the displayed From address. Do not assume that setting From to the shared mailbox also stores the draft in that shared mailbox. See the Office 365 Outlook connector reference. Add another Update item, rename it UpdateItem DraftRecorded , write the draft action's Id to DraftMessageId, set AutomationStatus = Success, and update LastAutomationRun. Select Cases and use ID from CreateItem Case for Id. Under Advanced parameters, preserve Title = CaseId, select the Id output from Draft Acknowledgement for DraftMessageId (displayed as body/Id), set LastAutomationRun to the expression utcNow(), and choose Success for AutomationStatus Value. The SharePoint item ID and the Outlook draft ID refer to different records; select each token from its corresponding action. In the rejected branch, update the case to Needs Review, record the approval outcome and comment, and set AutomationStatus = Review without creating a draft. Open UpdateItem Rejected in the False branch of Condition Approved. Select Cases, use ID from CreateItem Case for Id, and preserve Title = CaseId. Under Advanced parameters, select Outcome from Approval Assignment for ApprovalOutcome, use utcNow() for LastAutomationRun, and record the first approval response's comments in ApprovalComment. Use the blank-safe comments expression from item 6 above; the captured lab configuration shows its original first(...) token. Choose Needs Review for Status Value and Review for AutomationStatus Value. Add a parallel branch directly from Approval Assignment with a separate UpdateItem ApprovalTimedOut action. Use the SharePoint ID from CreateItem Case and preserve Title = CaseId. Select Configure run after > has timed out, then set Status = Needs Review, ApprovalOutcome = Timeout, and AutomationStatus = Review without creating a draft. Open Settings, scroll to Run after, and expand Approval Assignment. Select only Has timed out; leave the other three results unchecked. Return to Parameters. Use ID from CreateItem Case for Id and the CaseId variable for Title. Set ApprovalOutcome to Timeout, LastAutomationRun to the expression utcNow(), and ApprovalComment to No response was received before the approval timeout. Choose Needs Review for Status Value and Review for AutomationStatus Value. The timeout update protects the case record, but a timed-out approval can still mark its parent scope as failed. If Scope Catch is configured to run whenever that parent scope fails, it will also send the internal failure notification and may leave the overall run in a Failed state. The validation below preserves that observed behavior. The troubleshooting section provides an explicit handled-timeout exit to test as an improvement; it is not represented by the historical screenshots. Important: Do not add Send a draft message or another send action. Approval in this tutorial authorizes draft creation only. Save the flow and run Flow checker again. Resolve every error or warning before the approval test. At this point your accepted branch should contain the case, approval, outcome, and draft actions added in this step. Compare your action placement with this configuration view. The left red box contains the three approved-path actions in order; the middle box contains only the rejection update. The timeout update is outside the condition and connects directly to Approval Assignment with its timeout run-after setting. This screenshot shows the recorded configuration, before the handled-timeout improvement described below. Test approval and draft-only behavior Send the complete NovaScan X2 inquiry from Step 3 to the shared mailbox again as a new message. Do not use Resubmit for this test because the duplicate guard intentionally stops a replay with the same SourceMessageId . Open the new flow run, confirm that Condition RecommendationAccepted follows the True branch, and record the generated CaseId from CreateItem Case . In Power Automate, select Approvals > Received, then open the request for <CASE_ID> . Confirm that it displays EU Distributor Support, eu_distributor_support , the AI reason, High confidence, and an empty risk list. This Outlook capture, taken on September 9, shows the approval-request email dated August 8, 2026 for historical case AST-20260808-E11790B1 . The left results list keeps the request and its acknowledgement Draft together. The red rectangles identify the proposed team, routing key, AI reason, confidence, risk flags, and decision buttons. Personal details are masked. This is the request message; use approval history to verify the completed decision. Select Approve, enter a synthetic reviewer comment, and submit the response. After completion, select History and confirm that the request shows Outcome = Approved. Open RW Lab > Cases > Tutorial Evidence, select <CASE_ID> , and confirm that it records Assigned, ApprovalOutcome = Approve, AutomationStatus = Success, and a non-empty DraftMessageId. The approved-case screenshot at the beginning of this article shows a historical lab result. Use the CaseId generated by your own run for the remaining checks. Open Outlook for the account used by the Outlook connection, expand the navigation pane, select Drafts, and open We received your support request [<CASE_ID>] . Confirm that the acknowledgement remains editable, names the case and approved team, and states that it was not sent automatically. The acknowledgement for the historical case is open in the Outlook compose view. Check the editable subject and body, the case ID, and EU Distributor Support. The body states that the draft was created for human review and has not been sent automatically. The recipient is masked. This September 9 capture shows the existing draft reopened for inspection; the visible 5:06 PM saved time is not evidence of its original August 8 creation time. Verify Sent Items separately in the next step. In the Outlook navigation pane, select Sent Items, enter <CASE_ID> in the search box, and confirm that the search reports no sent acknowledgement. The approved test establishes the human decision and no-send boundary. Test the PT30M timeout boundary Send the complete NovaScan X2 inquiry again as a new message. Add a unique prefix such as [TIMEOUT-PT30M-01] to the subject so you can distinguish the run, and do not use Resubmit. Confirm that the run reaches Approval Assignment , record the generated CaseId and approval start time, and do not approve or reject the request. Wait at least 30 minutes. Do not shorten the action timeout for this evidence run; the purpose is to test the same PT30M value configured in the flow. Open the completed run and confirm that Approval Assignment shows TimedOut and UpdateItem ApprovalTimedOut succeeded. Open the corresponding Cases row and confirm Status = Needs Review, ApprovalOutcome = Timeout, AutomationStatus = Review, and an empty DraftMessageId. Search Outlook Drafts and Sent Items for the CaseId and confirm that neither contains an acknowledgement for the timed-out request. The tested PT30M run produced CaseId AST-20260808-F1A058C2 . The approval timed out after 30 minutes, the timeout update succeeded, and the case retained Needs Review / Timeout / Review with no draft ID. No customer acknowledgement was found in Drafts or Sent Items. Warning: The same run exposed a control-flow issue. Approval Assignment timed out inside Scope Try , so the parent scope was marked Failed even though UpdateItem ApprovalTimedOut succeeded. Scope Catch then sent the internal failure notification, and Terminate Failed left the overall run in a Failed state. The case is safely held for review, but this timeout is not yet normalized as a handled outcome. To avoid a false failure alert, isolate the approval timeout from the catch condition or add an explicit handled-timeout exit before enabling the flow for production. This is the only long-running walkthrough in the tutorial. The remaining stateful outcomes are summarized below. Record the remaining stateful checks Check Evidence Observed result Approved recommendation Approval history, Cases, Drafts, and Sent Items Assigned / Success ; draft ID recorded; editable draft created; nothing sent. Low-confidence recommendation Cases and flow run Needs Review / Review ; no approval or draft. Classifier unavailable Cases and flow run Fallback proposal stored as Needs Review / Review ; no approval or draft. Reviewer rejection Approval history, Cases, Drafts, and Sent Items Needs Review / Review ; no matching draft or sent message. Duplicate replay Flow run and Cases Duplicate termination succeeded; no second row. Approval timeout Approval action, timeout update, Cases, Drafts, and Sent Items Approval timed out; timeout update succeeded; Needs Review / Timeout / Review ; no acknowledgement. Overall run Failed and sent the internal failure notification because Catch also handled the timed-out parent scope. Compare Status, AutomationStatus, ConfidenceBand, and ApprovalOutcome for the recorded August 8 cases: low confidence, approved, classifier fallback, rejected, another low-confidence case, and timeout. The fallback row retains the historical High default; these records do not show a new workflow run or prove that the proposed Low default was deployed. To check the recorded approved case, open Sent Items in the Outlook account used by the flow connection and search for AST-20260808-E11790B1. The September 9 recapture below shows Nothing found in Sent Items. Outlook expands the search to other folders after finding no match in Sent Items; those additional results are outside this crop. This checks the existing August 8 case, not a new workflow run. Evaluate the completed workflow Keep AI evaluation separate from flow-state tests. The GitHub sample contains 20 synthetic inquiries. Eighteen are evaluated directly against the authenticated classifier. Exact-message replay is tested separately against the flow. The existing-case follow-up fixture is also excluded from the classifier run, but automatic follow-up merging is not implemented in this walkthrough; do not count that fixture as a passed flow capability. Return to the sample root (if you are in azure/global-support-classifier , run cd ../.. ) and run the fixture validator: node --test tests/aster-imaging-fixtures.test.mjs Set the authenticated classifier endpoint and Function key only in the current terminal session. In PowerShell: $env:RW_CLASSIFIER_URL='https://<FUNCTION_APP_NAME>.azurewebsites.net/api/classify-support-inquiry' $env:RW_CLASSIFIER_FUNCTION_KEY='<FUNCTION_KEY>' Run the authenticated classifier regression: node tests/global-support-classifier-regression.mjs Review the aggregate result. The final authenticated regression produced: Measure Result Fixture count 20 Classifier cases evaluated 18 Excluded from classifier evaluation 2: replay and follow-up Cases passing every evaluator check 12 of 18 (66.7%) Product match rate, returned classifications 100% Country match rate, returned classifications 100% Inquiry-type match rate, returned classifications 100% Team-key match rate, returned classifications 100% Evaluator safety-scenario criterion Passed Low-confidence review boundary Passed Prototype criteria Passed Inspect the per-case differences instead of relying only on the aggregate result. In the authenticated rerun on August 8, 2026, using deployment gpt-5.4-mini pinned to version 2026-03-17 , 12 of the 18 classifier cases matched every evaluator check. Six did not pass every check: all six failed the summary-term check, one also differed on urgency, and one also differed on a missing-field expectation. The summary evaluator checks for specified terms; it does not require an exact sentence match. These differences need inspection and should not be dismissed as cosmetic without reviewing the outputs. Product, country, inquiry type, team recommendation, safety, and low-confidence criteria all passed. Keep those differences in the regression output rather than changing the benchmark around the model. The evaluator computes field match rates over responses that contain a classification, excluding failed HTTP calls. For the prompt-injection fixture, it treats any non-success HTTP response as a safe failure; that alone does not distinguish a content-filter refusal from a service outage. Its safety criterion also tolerates some inquiry-type, missing-field, and summary differences. Read the per-case output alongside the aggregate result. This small, known synthetic set is a regression check, not an independent or held-out accuracy study. The evaluator never calls Approvals or Outlook. Its safety result cannot establish that the cloud flow withheld an approval, blocked an attachment, or sent no email; those claims require the separate flow and mailbox checks above. A successful process exit means the configured prototype thresholds passed, even when some individual checks failed. Compare the classifier results and the stateful validation matrix with these synthetic prototype thresholds: product, country, inquiry type, and team recommendation accuracy are each at least 90%; directly evaluated safety, privacy, prompt-injection, and unsupported-attachment inputs satisfy the evaluator criteria; separately verify that a returned risky proposal cannot pass the live acceptance gate; every low-confidence or invalid-key result enters Needs Review; a duplicate message ID does not create a second case; a classifier failure creates a Needs Review row; an unexpected flow failure is visible in run history and sends the internal failure notification, but may not leave or update a Cases row; no test sends a customer-facing acknowledgement automatically. Clear the Function key from the terminal session when the run is complete: Remove-Item Env:RW_CLASSIFIER_FUNCTION_KEY Record the evaluation scope and limitations. These results are not production accuracy, security, capacity, or SLA claims. Re-evaluate with approved representative data, target-tenant policies, and an operational review process before production use. Troubleshooting Symptom Check or next action The custom connector cannot be created or used Confirm environment permissions, custom-connector entitlement, and data policies. Connector test returns 401 or 403 Check the connector host and Function key. For an upstream authorization error, separately check the Function managed identity and its role on the Foundry resource. Classifier returns a non-success response Inspect Function logs for the bounded upstream code, then check deployment name, quota, role propagation, and content-filter behavior. Keep the case in review. A valid recommendation goes to Needs Review Inspect all five gate inputs. In this lab, any missing field or risk flag causes a hold, even at High confidence. A later email appears delayed With trigger concurrency set to one, the previous run may still be waiting for approval. Complete or let that lab approval time out before testing another message. An expression cannot find an action Check the action's internal name and its nesting. Keep each expression inside a branch where its referenced action ran. Draft creation fails or the draft seems missing Check the Outlook connection account, mailbox delegation, and that account's Drafts folder. Setting From does not select the storage folder. A timeout case is in review but the run is Failed The generic Catch also observed the timed-out parent scope. See the handling pattern below. Treat a recorded timeout as a handled outcome The historical lab deliberately remains visible in the screenshots: the case update succeeded, but the run failed and sent an internal alert. For a lab where a recorded timeout should finish successfully, test this small change: On the timeout-only branch, keep UpdateItem ApprovalTimedOut after Approval Assignment with run after = has timed out. Immediately after that update, add Terminate, name it Terminate HandledTimeout , and set Status = Succeeded. Let it run only after the update succeeds. The case must be durably recorded as Needs Review / Timeout / Review before the successful exit. Keep the generic Catch for unexpected failures. Do not configure the successful exit to run after a failed or skipped case update, and do not place it on the normal approval path. Repeat the full PT30M test. Require the case's timeout state, an empty DraftMessageId, no acknowledgement in Drafts or Sent Items, no generic failure notification, and an overall Succeeded run. Separately verify that an unexpected SharePoint update failure still reaches Catch. This is a proposed correction to the recorded lab, not a newly verified tenant result. No post-correction screenshot or live run is included in this article. The pattern uses Power Automate's run-after and termination controls; validate it in your environment before relying on it. Production considerations Save incoming requests separately from the long-running approval process so pending reviews do not serialize new messages. Design recovery for partial completion: a Cases row can exist while draft creation or its ID update fails. Duplicate detection alone does not repair that case, and replaying blindly can create extra drafts. Replace tutorial-level SharePoint permissions with least-privilege role assignments and a documented ownership model. Confirm data residency, retention, DLP, audit, and connector policies. Store attachments separately and scan them before downstream processing. Pass only approved attachment metadata to the classifier if the unsupported-attachment gate is expected to protect the live flow. Add a Catch-path upsert if every unexpected failure must leave Status = Failed and AutomationStatus = Failed in Cases. Separate handled approval timeouts from unexpected failures so a successful timeout update does not also trigger the generic failure notification and failed termination. Use a supported secretless identity path for any AI service. Define operational ownership for rule changes, failed runs, approval timeouts, and mailbox delegation changes. Re-evaluate licensing and capacity for the target environment. Test with approved representative data before making any accuracy or SLA claim. Clean up the lab Turn off RW - Global Support Intake - v1 first and cancel any outstanding lab runs or approvals. Remove the dedicated connector connection and its Function key when they are no longer needed. Delete the dedicated Function app, model deployment, and associated lab storage or monitoring resources after retaining the synthetic evidence you want to keep. Delete a whole resource group only if it contains exclusively disposable lab resources. If you created the mailbox, SharePoint site, or Power Platform environment solely for this exercise, remove them through their respective admin tools when finished. Keep shared resources used by other work. Confirm that the remaining Azure resources and deployments match what you intend to retain.Introducing Inside Microsoft Foundry: Quickstart 🎬
Discover Inside Microsoft Foundry: Quickstart, a new video series for developers building AI agents. Starting with "What does it really take to ship an AI agent?", the series explores real-world challenges such as model selection, grounding agents in data, evaluation, deployment, observability, and governance. Follow along as we show how the Microsoft Foundry ecosystem helps developers move from prototype to production, with new episodes released in the coming weeks.