mcp
70 TopicsUnleashing the Power of Model Context Protocol (MCP): A Game-Changer in AI Integration
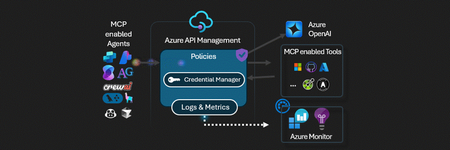
Artificial Intelligence is evolving rapidly, and one of the most pressing challenges is enabling AI models to interact effectively with external tools, data sources, and APIs. The Model Context Protocol (MCP) solves this problem by acting as a bridge between AI models and external services, creating a standardized communication framework that enhances tool integration, accessibility, and AI reasoning capabilities. What is Model Context Protocol (MCP)? MCP is a protocol designed to enable AI models, such as Azure OpenAI models, to interact seamlessly with external tools and services. Think of MCP as a universal USB-C connector for AI, allowing language models to fetch information, interact with APIs, and execute tasks beyond their built-in knowledge. Key Features of MCP Standardized Communication – MCP provides a structured way for AI models to interact with various tools. Tool Access & Expansion – AI assistants can now utilize external tools for real-time insights. Secure & Scalable – Enables safe and scalable integration with enterprise applications. Multi-Modal Integration – Supports STDIO, SSE (Server-Sent Events), and WebSocket communication methods. MCP Architecture & How It Works MCP follows a client-server architecture that allows AI models to interact with external tools efficiently. Here’s how it works: Components of MCP MCP Host – The AI model (e.g., Azure OpenAI GPT) requesting data or actions. MCP Client – An intermediary service that forwards the AI model's requests to MCP servers. MCP Server – Lightweight applications that expose specific capabilities (APIs, databases, files, etc.). Data Sources – Various backend systems, including local storage, cloud databases, and external APIs. Data Flow in MCP The AI model sends a request (e.g., "fetch user profile data"). The MCP client forwards the request to the appropriate MCP server. The MCP server retrieves the required data from a database or API. The response is sent back to the AI model via the MCP client. Integrating MCP with Azure OpenAI Services Microsoft has integrated MCP with Azure OpenAI Services, allowing GPT models to interact with external services and fetch live data. This means AI models are no longer limited to static knowledge but can access real-time information. Benefits of Azure OpenAI Services + MCP Integration ✔ Real-time Data Fetching – AI assistants can retrieve fresh information from APIs, databases, and internal systems. ✔ Contextual AI Responses – Enhances AI responses by providing accurate, up-to-date information. ✔ Enterprise-Ready – Secure and scalable for business applications, including finance, healthcare, and retail. Hands-On Tools for MCP Implementation To implement MCP effectively, Microsoft provides two powerful tools: Semantic Workbench and AI Gateway. Microsoft Semantic Workbench A development environment for prototyping AI-powered assistants and integrating MCP-based functionalities. Features: Build and test multi-agent AI assistants. Configure settings and interactions between AI models and external tools. Supports GitHub Codespaces for cloud-based development. Explore Semantic Workbench Workbench interface examples Microsoft AI Gateway A plug-and-play interface that allows developers to experiment with MCP using Azure API Management. Features: Credential Manager – Securely handle API credentials. Live Experimentation – Test AI model interactions with external tools. Pre-built Labs – Hands-on learning for developers. Explore AI Gateway Setting Up MCP with Azure OpenAI Services Step 1: Create a Virtual Environment First, create a virtual environment using Python: python -m venv .venv Activate the environment: # Windows venv\Scripts\activate # MacOS/Linux source .venv/bin/activate Step 2: Install Required Libraries Create a requirements.txt file and add the following dependencies: langchain-mcp-adapters langgraph langchain-openai Then, install the required libraries: pip install -r requirements.txt Step 3: Set Up OpenAI API Key Ensure you have your OpenAI API key set up: # Windows setx OPENAI_API_KEY "<your_api_key> # MacOS/Linux export OPENAI_API_KEY=<your_api_key> Building an MCP Server This server performs basic mathematical operations like addition and multiplication. Create the Server File First, create a new Python file: touch math_server.py Then, implement the server: from mcp.server.fastmcp import FastMCP # Initialize the server mcp = FastMCP("Math") MCP.tool() def add(a: int, b: int) -> int: return a + b MCP.tool() def multiply(a: int, b: int) -> int: return a * b if __name__ == "__main__": mcp.run(transport="stdio") Your MCP server is now ready to run. Building an MCP Client This client connects to the MCP server and interacts with it. Create the Client File First, create a new file: touch client.py Then, implement the client: import asyncio from mcp import ClientSession, StdioServerParameters from langchain_openai import ChatOpenAI from mcp.client.stdio import stdio_client # Define server parameters server_params = StdioServerParameters( command="python", args=["math_server.py"], ) # Define the model model = ChatOpenAI(model="gpt-4o") async def run_agent(): async with stdio_client(server_params) as (read, write): async with ClientSession(read, write) as session: await session.initialize() tools = await load_mcp_tools(session) agent = create_react_agent(model, tools) agent_response = await agent.ainvoke({"messages": "what's (4 + 6) x 14?"}) return agent_response["messages"][3].content if __name__ == "__main__": result = asyncio.run(run_agent()) print(result) Your client is now set up and ready to interact with the MCP server. Running the MCP Server and Client Step 1: Start the MCP Server Open a terminal and run: python math_server.py This starts the MCP server, making it available for client connections. Step 2: Run the MCP Client In another terminal, run: python client.py Expected Output 140 This means the AI agent correctly computed (4 + 6) x 14 using both the MCP server and GPT-4o. Conclusion Integrating MCP with Azure OpenAI Services enables AI applications to securely interact with external tools, enhancing functionality beyond text-based responses. With standardized communication and improved AI capabilities, developers can build smarter and more interactive AI-powered solutions. By following this guide, you can set up an MCP server and client, unlocking the full potential of AI with structured external interactions. Next Steps: Explore more MCP tools and integrations. Extend your MCP setup to work with additional APIs. Deploy your solution in a cloud environment for broader accessibility. For further details, visit the GitHub repository for MCP integration examples and best practices. MCP GitHub Repository MCP Documentation Semantic Workbench AI Gateway MCP Video Walkthrough MCP Blog MCP Github End to End Demo64KViews11likes6CommentsLevel up your Python + AI skills with our complete series
We've just wrapped up our live series on Python + AI, a comprehensive nine-part journey diving deep into how to use generative AI models from Python. The series introduced multiple types of models, including LLMs, embedding models, and vision models. We dug into popular techniques like RAG, tool calling, and structured outputs. We assessed AI quality and safety using automated evaluations and red-teaming. Finally, we developed AI agents using popular Python agents frameworks and explored the new Model Context Protocol (MCP). To help you apply what you've learned, all of our code examples work with GitHub Models, a service that provides free models to every GitHub account holder for experimentation and education. Even if you missed the live series, you can still access all the material using the links below! If you're an instructor, feel free to use the slides and code examples in your own classes. If you're a Spanish speaker, check out the Spanish version of the series. Python + AI: Large Language Models 📺 Watch recording In this session, we explore Large Language Models (LLMs), the models that power ChatGPT and GitHub Copilot. We use Python to interact with LLMs using popular packages like the OpenAI SDK and LangChain. We experiment with prompt engineering and few-shot examples to improve outputs. We also demonstrate how to build a full-stack app powered by LLMs and explain the importance of concurrency and streaming for user-facing AI apps. Slides for this session Code repository with examples: python-openai-demos Python + AI: Vector embeddings 📺 Watch recording In our second session, we dive into a different type of model: the vector embedding model. A vector embedding is a way to encode text or images as an array of floating-point numbers. Vector embeddings enable similarity search across many types of content. In this session, we explore different vector embedding models, such as the OpenAI text-embedding-3 series, through both visualizations and Python code. We compare distance metrics, use quantization to reduce vector size, and experiment with multimodal embedding models. Slides for this session Code repository with examples: vector-embedding-demos Python + AI: Retrieval Augmented Generation 📺 Watch recording In our third session, we explore one of the most popular techniques used with LLMs: Retrieval Augmented Generation. RAG is an approach that provides context to the LLM, enabling it to deliver well-grounded answers for a particular domain. The RAG approach works with many types of data sources, including CSVs, webpages, documents, and databases. In this session, we walk through RAG flows in Python, starting with a simple flow and culminating in a full-stack RAG application based on Azure AI Search. Slides for this session Code repository with examples: python-openai-demos Python + AI: Vision models 📺 Watch recording Our fourth session is all about vision models! Vision models are LLMs that can accept both text and images, such as GPT-4o and GPT-4o mini. You can use these models for image captioning, data extraction, question answering, classification, and more! We use Python to send images to vision models, build a basic chat-with-images app, and create a multimodal search engine. Slides for this session Code repository with examples: openai-chat-vision-quickstart Python + AI: Structured outputs 📺 Watch recording In our fifth session, we discover how to get LLMs to output structured responses that adhere to a schema. In Python, all you need to do is define a Pydantic BaseModel to get validated output that perfectly meets your needs. We focus on the structured outputs mode available in OpenAI models, but you can use similar techniques with other model providers. Our examples demonstrate the many ways you can use structured responses, such as entity extraction, classification, and agentic workflows. Slides for this session Code repository with examples: python-openai-demos Python + AI: Quality and safety 📺 Watch recording This session covers a crucial topic: how to use AI safely and how to evaluate the quality of AI outputs. There are multiple mitigation layers when working with LLMs: the model itself, a safety system on top, the prompting and context, and the application user experience. We focus on Azure tools that make it easier to deploy safe AI systems into production. We demonstrate how to configure the Azure AI Content Safety system when working with Azure AI models and how to handle errors in Python code. Then we use the Azure AI Evaluation SDK to evaluate the safety and quality of output from your LLM. Slides for this session Code repository with examples: ai-quality-safety-demos Python + AI: Tool calling 📺 Watch recording In the final part of the series, we focus on the technologies needed to build AI agents, starting with the foundation: tool calling (also known as function calling). We define tool call specifications using both JSON schema and Python function definitions, then send these definitions to the LLM. We demonstrate how to properly handle tool call responses from LLMs, enable parallel tool calling, and iterate over multiple tool calls. Understanding tool calling is absolutely essential before diving into agents, so don't skip over this foundational session. Slides for this session Code repository with examples: python-openai-demos Python + AI: Agents 📺 Watch recording In the penultimate session, we build AI agents! We use Python AI agent frameworks such as the new agent-framework from Microsoft and the popular LangGraph framework. Our agents start simple and then increase in complexity, demonstrating different architectures such as multiple tools, supervisor patterns, graphs, and human-in-the-loop workflows. Slides for this session Code repository with examples: python-ai-agent-frameworks-demos Python + AI: Model Context Protocol 📺 Watch recording In the final session, we dive into the hottest technology of 2025: MCP (Model Context Protocol). This open protocol makes it easy to extend AI agents and chatbots with custom functionality, making them more powerful and flexible. We demonstrate how to use the Python FastMCP SDK to build an MCP server running locally and consume that server from chatbots like GitHub Copilot. Then we build our own MCP client to consume the server. Finally, we discover how easy it is to connect AI agent frameworks like LangGraph and Microsoft agent-framework to MCP servers. With great power comes great responsibility, so we briefly discuss the security risks that come with MCP, both as a user and as a developer. Slides for this session Code repository with examples: python-mcp-demo12KViews6likes0CommentsKickstart Your AI Development with the Model Context Protocol (MCP) Course
Model Context Protocol is an open standard that acts as a universal connector between AI models and the outside world. Think of MCP as “the USB-C of the AI world,” allowing AI systems to plug into APIs, databases, files, and other tools seamlessly. By adopting MCP, developers can create smarter, more useful AI applications that access up-to-date information and perform actions like a human developer would. To help developers learn this game-changing technology, Microsoft has created the “MCP for Beginners” course a free, open-source curriculum that guides you from the basics of MCP to building real-world AI integrations. Below, we’ll explore what MCP is, who this course is for, and how it empowers both beginners and intermediate developers to get started with MCP. What is MCP and Why Should Developers Care? Model Context Protocol (MCP) is a innovative framework designed to standardize interactions between AI models and client applications. In simpler terms, MCP is a communication bridge that lets your AI agent fetch live context from external sources (like APIs, documents, databases, or web services) and even take actions using tools. This means your AI apps are no longer limited to pre-trained knowledge they can dynamically retrieve data or execute commands, enabling far more powerful and context-aware behavior. Some key reasons MCP matters for developers: Seamless Integration of Tools & Data: MCP provides a unified way to connect AI to various data sources and tools, eliminating the need for ad-hoc, fragile integrations. Your AI agent can, for example, query a database or call a web API during a conversation all through a standardized protocol. Stay Up-to-Date: Because AI models can use MCP to access external information, they overcome the training data cutoff problem. They can fetch the latest facts, figures, or documents on demand, ensuring more accurate and timely responses. Industry Momentum: MCP is quickly gaining traction. Originally introduced by Microsoft and Anthropic in late 2024, it has since been adopted by major AI platforms (Replit, Sourcegraph, Hugging Face, and more) and spawned thousands of open-source connectors by early 2025. It’s an emerging standard – learning it now puts developers at the forefront of AI innovation. In short, MCP is transformative for AI development, and being proficient in it will help you build smarter AI solutions that can interact with the real world. The MCP for Beginners course is designed to make mastering this protocol accessible, with a structured learning path and hands-on examples. Introducing the MCP for Beginners Course “Model Context Protocol for Beginners” is an open-source, self-paced curriculum created by Microsoft to teach the concepts and fundamentals of MCP. Whether you’re completely new to MCP or have some experience, this course offers a comprehensive guide from the ground up. Key Features and Highlights: Structured Learning Path: The curriculum is organized as a multi-part guide (9 modules in total) that gradually builds your knowledge. It starts with the basics of MCP – What is MCP? Why does standardization matter? What are the use cases? – and then moves through core concepts, security considerations, getting started with coding, all the way to advanced topics and real-world case studies. This progression ensures you understand the “why” and “how” of MCP before tackling complex scenarios. Hands-On Coding Examples: This isn’t just theory – practical coding examples are a cornerstone of the course. You’ll find live code samples and mini-projects in multiple languages (C#, Java, JavaScript/TypeScript, and Python) for each concept. For instance, you’ll build a simple MCP-powered Calculator application as a project, exploring how to implement MCP clients and servers in your preferred language. By coding along, you cement your understanding and see MCP in action. Real-World Use Cases: The curriculum illustrates how MCP applies to real scenarios. It discusses practical use cases of MCP in AI pipelines (e.g. an AI agent pulling in documentation or database info on the fly) and includes case studies of early adopters. These examples help you connect what you learn to actual applications and solutions you might develop in your job. Broad Language Support: A unique aspect of this course is its multi-language approach – both in terms of programming and human languages. The content provides code implementations in several popular programming languages (so you can learn MCP in the context of C#, Java, Python, JavaScript, or TypeScript, as you prefer). In addition, the learning materials themselves are available in multiple human languages (English, plus translations like French, Spanish, German, Chinese, Japanese, Korean, Polish, etc.) to support learners worldwide. This inclusivity ensures that more developers can comfortably engage with the material. Up-to-Date and Open-Source: Being hosted on GitHub under MIT License, the curriculum is completely free to use and open for contributions. It’s maintained with the latest updates for example, automated workflows keep translations in sync so all language versions stay current. As MCP evolves, the course content can evolve with it. You can even join the community to suggest improvements or add content, making this a living learning resource. Official Resources & Community Support: The course links to official MCP documentation and specs for deeper reference, and it encourages learners to join thehttps;//aka.ms/ai/discord to discuss and get help. You won’t be learning alone; you can network with experts and peers, ask questions, and share progress. Microsoft’s open-source approach means you’re part of a community of practitioners from day one. Course Outline: (Modules at a Glance) Introduction to MCP: Overview of MCP, why standardization matters in AI, and the key benefits and use cases of using MCP. (Start here to understand the big picture.) Core Concepts: Deep dive into MCP’s architecture – understanding the client-server model, how requests and responses work, and the message schema. Learn the fundamental components that make up the protocol. Security in MCP: Identify potential security threats when building MCP-based systems and learn best practices to secure your AI integrations. Important for anyone planning to deploy MCP in production environments. Getting Started (Hands-On): Set up your environment and create your first MCP server and client. This module walks through basic implementation steps and shows how to integrate MCP with existing applications, so you get a service up and running that an AI agent can communicate with. MCP Calculator Project: A guided project where you build a simple MCP-powered application (a calculator) in the language of your choice. This hands-on exercise reinforces the concepts by implementing a real tool – you’ll see how an AI agent can use MCP to perform calculations via an external tool. Practical Implementation: Tips and techniques for using MCP SDKs across different languages. Covers debugging, testing, validation of MCP integrations, and how to design effective prompt workflows that leverage MCP’s capabilities. Advanced Topics: Going beyond the basics – explore multi-modal AI workflows (using MCP to handle not just text but other data types), scalability and performance tuning for MCP servers, and how MCP fits into larger enterprise architectures. This is where intermediate users can really deepen their expertise. Community Contributions: Learn how to contribute to the MCP ecosystem and the curriculum itself. This section shows you how to collaborate via GitHub, follow the project’s guidelines, and even extend the protocol with your own ideas. It underlines that MCP is a growing, community-driven standard. Insights from Early Adoption: Hear lessons learned from real-world MCP implementations. What challenges did early adopters face? What patterns and solutions worked best? Understanding these will prepare you to avoid pitfalls in your own projects. Best Practices and Case Studies: A roundup of do’s and don’ts when using MCP. This includes performance optimization techniques, designing fault-tolerant systems, and testing strategies. Plus, detailed case studies that walk through actual MCP solution architectures with diagrams and integration tips bringing everything you learned together in concrete examples. Who Should Take This Course? The MCP for Beginners course is geared towards developers if you build or work on AI-driven applications, this course is for you. The content specifically welcomes: Beginners in AI Integration: You might be a developer who's comfortable with languages like Python, C#, or Java but new to AI/LLMs or to MCP itself. This course will take you from zero knowledge of MCP to a level where you can build and deploy your own MCP-enabled services. You do not need prior experience with MCP or machine learning pipelines the introduction module will bring you up to speed on key concepts. (Basic programming skills and understanding of client-server or API concepts are the only prerequisites.) Intermediate Developers & AI Practitioners: If you have some experience building bots or AI features and want to enhance them with real-time data access, you’ll benefit greatly. The course’s later modules on advanced topics, security, and best practices are especially valuable for those looking to integrate MCP into existing projects or optimize their approach. Even if you've dabbled in MCP or a similar concept before, this curriculum will fill gaps in knowledge and provide structured insights that are hard to get from scattered documentation. AI Enthusiasts & Architects: Perhaps you’re an AI architect or tech lead exploring new frameworks for intelligent agents. This course serves as a comprehensive resource to evaluate MCP for your architecture. By walking through it, you’ll understand how MCP can fit into enterprise systems, what benefits it brings, and how to implement it in a maintainable way. It’s perfect for getting a broad yet detailed view of MCP’s capabilities before adopting it within a team. In essence, anyone interested in making AI applications more connected and powerful will find value here. From a solo hackathon coder to a professional solution architect, the material scales to your need. The course starts with fundamentals in an easy-to-grasp manner and then deepens into complex topics appealing to a wide range of skill levels. Prerequisites: The official prerequisites for the course are minimal: you should have basic knowledge of at least one programming language (C#, Java, or Python is recommended) and a general understanding of how client-server applications or APIs work. Familiarity with machine learning concepts is optional but can help. In short, if you can write simple programs and understand making API calls, you have everything you need to start learning MCP. Conclusion: Empower Your AI Projects with MCP The Model Context Protocol for Beginners course is more than just a tutorial – it’s a comprehensive journey that empowers you to build the next generation of AI applications. By demystifying MCP and equipping you with hands-on experience, this curriculum turns a seemingly complex concept into practical skills you can apply immediately. With MCP, you unlock capabilities like giving your AI agents real-time information access and the ability to use tools autonomously. That means as a developer, you can create solutions that are significantly more intelligent and useful. A chatbot that can search documents, a coding assistant that can consult APIs or run code, an AI service that seamlessly integrates with your database – all these become achievable when you know MCP. And thanks to this beginners-friendly course, you’ll be able to implement such features with confidence. Whether you are starting out in the AI development world or looking to sharpen your cutting-edge skills, the MCP for Beginners course has something for you. It condenses best practices, real-world lessons, and robust techniques into an accessible format. Learning MCP now will put you ahead of the curve, as this protocol rapidly becomes a cornerstone of AI integrations across the industry. So, are you ready to level up your AI development skills? Dive into the https://aka.ms/mcp-for-beginnerscourse and start building AI agents that can truly interact with the world around them. With the knowledge and experience gained, you’ll be prepared to create smarter, context-aware applications and be a part of the community driving AI innovation forward.11KViews4likes1CommentEnterprise Deployment Architecture for Agentic AI: ChatGPT-Style UI on IIS over Agents & MCP Servers
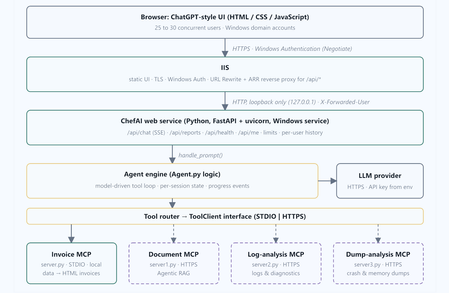
Research Disclaimer: This article is a technical research paper intended solely for educational, research, and illustrative purposes. It reflects the author’s personal technical perspectives. All concepts, architectural designs, diagrams, and implementation approaches are provided “AS IS” for technical exploration and review, not as production-ready development guidance. Organizations considering implementing these approaches should consult their internal software development standards, enterprise architecture teams, corporate security policies, and governance requirements. Any production implementation must undergo appropriate end-to-end architectural, security, privacy, compliance, and responsible AI or ethics reviews, along with necessary testing and organizational approvals before deployment. Abstract. Large language model agents that call tools through the Model Context Protocol (MCP) are usually shown from a console or a developer IDE. Enterprise users expect something different. They want a familiar chat interface, single sign-on and steady behavior when many people use the system at once. This paper gives architectural guidance for a ChatGPT-style web interface, hosted in Microsoft Internet Information Services (IIS) with Windows Authentication, that fronts an MCP-based agent for 25 to 30 concurrent users. The work is broken into nine steps: the engine boundary, state isolation, a streaming API, the chat UI, a Windows service host, IIS reverse-proxy configuration, security, testing and deployment. The paper explains why a long-running Python service behind IIS beats launching Python for every request, and why no Kerberos delegation (the double hop) is needed. It also describes a small transport-neutral tool-client layer, so the same agent can call a local STDIO MCP server and several remote MCP servers over HTTPS without any change to the user interface. The reference scenario is ChefAI, a fictitious restaurant-operations assistant that needs real-time answers, invoice generation, and log and crash-dump analysis for technical troubleshooting. Its STDIO server generates invoices. Three HTTP servers handle document retrieval through an Agentic RAG system, log analysis and dump analysis. The agent logic itself is treated as a black box. The paper closes with a threat model, a capacity argument and an evaluation methodology. Keywords: Model Context Protocol, agent user interface, IIS, Windows Authentication, reverse proxy, Server-Sent Events, agentic RAG, concurrency control, tool routing 1. Introduction Tool-using language model agents have become practical because protocols such as the Model Context Protocol (MCP) standardize how an agent discovers and calls external capabilities [1]. A typical agent loop sends a user request and the list of available tools to a model, receives a tool choice, runs the tool, and feeds the result back until the model can answer. The loop is easy to demonstrate in a terminal. Putting it in front of a team is harder, because the interface, identity, concurrency, streaming and deployment all become real concerns. This paper addresses that gap for a common enterprise setting: Windows infrastructure, an intranet, Active Directory identities and IIS as the standard web host. It is written as a reference architecture. It describes the components, what each one is responsible for, the trust boundaries between them and the order in which to build them. A fictitious reference application, ChefAI (Section 1.2), keeps the discussion concrete. End users reach the application through a browser chat window with their Windows identity, while the agent behind the scenes talks to one local MCP server over STDIO and to several remote MCP servers over HTTPS. 1.1 Contributions A nine-step design for a ChatGPT-style web interface that fronts an MCP agent and is hosted on IIS with Windows Authentication (Sections 4 and 5). A concurrency design sized for 25 to 30 simultaneous users, with explicit queues, per-user limits, timeouts and cleanup (Sections 5.2, 5.5 and 10). A transport-neutral tool-client layer made of an interface, a server registry and a router, which keeps the UI independent of how tools are reached (Section 6). A reference fleet of four MCP servers with different capabilities and data sensitivities, including an Agentic RAG document server, used to reason about routing and security (Section 7). An analysis of identity flow showing that no Kerberos delegation is needed, a threat model and an evaluation methodology (Sections 8 to 10). 1.2 The ChefAI reference application What ChefAI is. ChefAI is a fictitious restaurant-operations application used throughout this paper as the reference scenario. It is an AI assistant for a restaurant business. Staff need real-time answers during service, invoices generated from purchasing data, and help with technical troubleshooting when systems such as point-of-sale terminals, kitchen displays or online-ordering services misbehave. Staff describe what they need in plain language in a browser. The assistant decides which capability to use and answers with figures, documents, diagnostics or a generated report. How it is structured. The application is split into an agent and four MCP servers. Agent.py is the agent. It receives a request, consults a language model and calls tools exposed by MCP servers. The first server, server.py , is a local STDIO server and acts as the invoice generator. It reads purchasing data and produces HTML invoices and reports. The other three servers are remote HTTP(S) servers ( server1.py , server2.py and server3.py ), not STDIO, and the agent calls them to get information and to support technical issues. They are a document processor that answers questions by retrieving data and documents from an Agentic RAG system, a log analyzer and a dump analyzer. Table 0 summarizes the scenario. Capability Example request from staff Served by Transport Real-time spend answers “What did we spend on tomatoes last year?” Invoice server ( server.py ) STDIO, local Invoice generation “Generate the year-to-date invoice.” Invoice server ( server.py ) STDIO, local Knowledge and documents “What is our return policy for dairy deliveries?” “How do we descale the combi oven?” Document processor with Agentic RAG ( server1.py ) HTTPS, remote Log analysis “Why did the point-of-sale terminals time out on Friday evening?” Log analyzer ( server2.py ) HTTPS, remote Dump analysis “The kitchen display crashed. What does this dump show?” Dump analyzer ( server3.py ) HTTPS, remote Table 0. The ChefAI reference scenario: capabilities, the server that provides each, and its transport. The scenario deliberately mixes a business need (spend, invoices, policies) with an operational need (logs, dumps and runbooks). One interface therefore has to route between servers with very different data and risk profiles. The restaurant details, hostnames and example questions are illustrative and do not describe a real business. 1.3 Scope The focus is the user-interface tier and its hosting. The agent internals are out of scope except for the configuration the UI depends on, namely how the agent is invoked and how it reaches tools. The tool names, capacity figures and timeouts in this paper are illustrative design values. They show how to reason about a deployment and should be checked against the real workload (Section 10). 2. Background 2.1 The Model Context Protocol and its transports MCP defines how a client discovers a server’s tools, resources and prompts and calls them using JSON- RPC messages [1]. Two standard transports matter here. STDIO launches the server as a child process and exchanges messages over standard input and output. It is simple and local and needs no network port, but it ties the server’s lifetime to the client process. Streamable HTTP exposes the server at a URL. That allows servers on other machines, shared by several clients and protected by TLS and HTTP authentication. The official SDKs let the same tool code be exposed over either transport, so a server can move from one to the other without rewriting its tools. 2.2 Server-Sent Events for progress Agent requests can last tens of seconds because they chain model calls and tool calls. Server-Sent Events (SSE) let the server push a one-way stream of text events over an ordinary HTTP response [2]. This suits a chat interface that wants to show “queued”, “analyzing logs” and “building invoice” before the final answer. SSE also passes through reverse proxies more easily than WebSockets, as long as buffering is turned off. 2.3 IIS, ARR and Windows Authentication IIS can authenticate users with the Negotiate provider, which uses Kerberos where available and falls back to NTLM [3]. With the URL Rewrite and Application Request Routing (ARR) extensions, IIS can act as a reverse proxy. It forwards selected paths to a back-end service and can copy server variables such as LOGON_USER into request headers [4]. 2.4 The double-hop problem A “double hop” happens when a server has to use the caller’s Windows identity to reach a second server on the caller’s behalf. That requires Kerberos delegation. Section 8 shows why this design avoids it. 3. Requirements and Constraints Category Requirement Interface ChatGPT-style chat in a browser, real-time progress, a stop button, report cards with preview, and no CDN so it works offline on an intranet. Identity Windows Authentication in IIS. The application knows the user’s name and never handles user passwords. Concurrency 25 to 30 simultaneous users without cross-user data leakage, orphaned processes or unbounded resource use. Tools A local STDIO MCP server and several remote HTTPS MCP servers. The UI must not change when servers are added or moved. Security LLM keys never in files, logs or the browser. Loopback-only back end, output escaping, restrictive report serving and allow-listed remote servers. Operations Runs as a Windows service with restart on failure, structured logs and idempotent deployment scripts. Constraints System Python without virtual environments, standard-library HTTP for model calls, IIS as the only public listener and no Kerberos delegation. 4. System Architecture Figure 1 shows the end-to-end architecture. Users reach IIS over HTTPS and authenticate with Windows credentials. IIS serves the static single-page interface and reverse-proxies /api/* over loopback to a Python web service. The service owns the agent engine, which plans with a language model and calls tools through a router. The router reaches the local invoice server over STDIO and the remote servers over HTTPS. Figure 1. End-to-end architecture. Solid boxes and arrows are local components and the local STDIO server. Dashed boxes and arrows are remote MCP servers reached over HTTPS. Adding a server only touches the service and the tool layer. The browser and IIS tiers stay the same. 4.1 Request lifecycle Figure 2 follows a single prompt. The browser posts to /api/chat . IIS authenticates the user, overwrites the identity header and proxies the call. The service queues and admits the request, then streams status events while the engine consults the model and calls tools. The loop repeats, up to a fixed number of tool calls, until the model reports completion or, for report requests, an HTML file exists. The final answer and report links go out as the last events. Figure 2. Request lifecycle for one prompt. Messages 3 and 12 are Server-Sent Events returned through IIS on the original HTTP response. The browser never talks to the engine, the model or any MCP server directly. 4.2 Why a web service sits between the browser and the agent, and why the browser cannot call MCP servers directly The browser cannot call the agent directly, for reasons of feasibility and of fitness. On feasibility, clientside JavaScript can only issue HTTP requests and cannot start or import a Python program. IIS, as a static-file and ASP.NET host, has no in-process Python runtime. An agent is also a script and not a network endpoint, so something has to listen for requests and invoke it. On fitness, an agent request is long-lived, stateful and costly. It chains model and tool calls for tens of seconds, spawns MCP child processes that must be cleaned up on timeout or disconnect, keeps per-conversation state and has to stream progress. It therefore needs a persistent process that can enforce admission control (per-user gates, a bounded queue, semaphores and timeouts), isolate sessions, emit Server-Sent Events and hold the model key and service credentials in a service account, not in the client or the IIS application pool. Launching Python for every request would add seconds of start-up cost and make streaming, cancellation and cleanup fragile. Letting IIS supervise the process, for example through FastCGI or HttpPlatformHandler, changes who restarts it but not the need for it. The browser also cannot call the MCP servers directly. A STDIO server has no network listener at all. A Streamable HTTP server does carry MCP’s JSON-RPC over HTTP, so transport is not the real obstacle. The real obstacle is that an MCP server exposes typed tools and does not understand natural language, so some component must decide which tool to call with which arguments and iterate on the results. That component is the modeldriven agent loop, and it needs the LLM key. Direct access would also place server tokens or client certificates in every browser and expose the sensitive log and dump servers to every desktop. It would bypass central rate limiting, audit, allow-listing and redaction, remove the agent’s defence against prompt injection in tool results, and force the interface to carry discovery, routing and namespacing logic for every server, so adding a server would change the UI. Putting the service in between reduces the browser’s contract to a single HTTP endpoint, /api/chat , and keeps MCP, model credentials and trust decisions on the server side. 5. User-Interface-Centered Design in Nine Steps The design is organized as nine steps (Figure 3). Steps 1 and 2 define the boundary to the agent, Steps 3 and 4 deliver the API and the interface, Steps 5 and 6 host it, Step 7 secures it, Step 8 tests it and Step 9 documents and deploys it. Figure 3. The nine-step roadmap. Amber is the agent boundary, green is the API and interface, grey is hosting, red is security, and purple is verification and delivery. 5.1 Step 1: Define an engine boundary the UI can call An agent is often first written as a console program that mixes the planning loop with prompts and printing. The first step separates them. The agent exposes one asynchronous function, handle_prompt(prompt, history, progress_callback) , that returns {answer, html_files, tool_trace, error} and reports progress through a callback instead of printing. It never reads from or writes to a console. A single prompt box replaces any menu of modes, and the model decides from the live tool list whether the request needs a generated file or only an answer. Recent conversation turns, six by default, are passed as context so that follow-ups such as “now compare it to 2026” work. Only aggregates and provenance go back to the model, and raw rows stay on the server. This boundary is the only contract between the interface tier and the agent. 5.2 Step 2: Remove shared mutable state Agents and tool servers often keep module-level state, such as loaded data and cached query results. With 25 to 30 concurrent users, that state becomes a correctness and privacy hazard. The design therefore does three things. It loads and parses reference data once into an immutable shared dataset, reloaded only when the source file’s size or modification time changes and guarded by a lock. It keeps query results in a per-session store, so each query identifier belongs to exactly one session. And it gives each request an isolated tool connection, or a bounded pool of server processes with per-request session identifiers. Shared outputs are written atomically (a temporary file, then a rename) so a reader never sees a half-written file. 5.3 Step 3: Provide a streaming API The service exposes four endpoints (Table 1). The chat endpoint returns a Server-Sent Event stream. Conversation history is kept per user and conversation with a time-to-live and a cap, and no other user can read it. Endpoint Behavior POST /api/chat Body {prompt, conversation id} . The prompt is validated and capped at 2000 characters. Streams status , tool , result , done and error events (Appendix A). GET /api/reports/{name} Serves generated HTML from one folder only. Filenames are allow-listed and the resolved path must stay inside the folder. Sends a restrictive Content-Security-Policy and nosniff . Reports are scoped per user, plus shared built-in reports. GET /api/health Status, provider, model, data-loaded flag, queue depth and running count. Never keys or paths outside the project. GET /api/me Authenticated display name taken from the trusted header. Table 1. API surface of the web service. 5.4 Step 4: Build the ChatGPT-style interface The interface is plain HTML, CSS and vanilla JavaScript. There is no framework and no CDN, so it works on an isolated intranet and adds no supply-chain exposure. Figure 4 shows the layout. The sidebar lists this browser’s recent conversations from localStorage . The main pane shows user and assistant bubbles, a live status line fed by the event stream, and report cards that open in a new tab or preview in a sandboxed iframe with scripts disabled. The composer grows with its content, sends on Enter, inserts a newline on Shift+Enter, shows a character counter and is disabled while that user has a request running. A Stop button aborts the stream, which in turn cancels the server-side run. Example prompts fill an empty chat. Figure 4. Wireframe of the chat interface. (1) Conversation sidebar, (2) message bubbles, (3) live status line from the event stream, (4) report card with Open and Preview, (5) composer with Send and Stop, (6) data-egress notice. All model and server text is inserted as escaped text. Minimal formatting (line breaks, bold, simple tables) is added by the interface itself and never by interpreting model output as HTML. Errors are visible and actionable. Network loss, 401 and 403, 409 (a request is already running), 429 (system busy, with a retry hint) and timeouts each show a message and a Retry button. Figure 5. Typical event sequence for an invoice request. The browser adds each event to the status line as it arrives and renders the final answer and report cards when the closing done event comes in. 5.5 Step 5: Host the service The Python application runs under a Windows service wrapper (for example NSSM or WinSW), bound to 127.0.0.1 on a fixed port, with automatic restart and a dedicated low-privilege account. It reads the provider name, the model override, the data path and the limits from environment variables, and it reads the LLM key from the service environment only. The account gets read access to the project and data, and write access only to the report output and log folders. Capacity is protected by explicit limits (Figure 6). There is a per-user gate (one running request and a rate limit), a bounded queue that reports “queued, position N” through the stream and returns HTTP 429 when full, a semaphore on concurrent agent runs (default 8) and a separate semaphore on concurrent model calls (default 6). Every request has a wall-clock timeout (default 120 s). On timeout, cancellation or browser disconnect, the request’s child processes are terminated and its slots released, so no orphaned processes remain. Blocking work such as file and network I/O runs off the event loop, so one slow call cannot stall other users. Figure 6. Admission control and cleanup. A request has to pass the per-user gate and the queue before it gets an agent slot, and model calls are throttled separately. 5.6 Step 6: Configure IIS IIS is configured as a thin front end. The site’s application pool uses “No Managed Code” because IIS only serves static files and proxies. URL Rewrite forwards /api/* to the loopback service and, in the same rule, sets an X-Forwarded-User header from the authenticated LOGON_USER value, overwriting anything the client sent. The ARR proxy is enabled with a timeout longer than the engine’s request timeout, and response buffering and dynamic compression are turned off so the event stream is delivered live. Request size is capped, risky file extensions ( .py , .csv , .env , .log , .md ) are denied and an HTTPS binding is required. Windows Authentication is enabled and Anonymous is disabled. Those sections are locked at server level by default, so they are set through appcmd at the application-host scope. Appendix C lists the key settings. 5.7 Step 7: Secure the system Section 8 covers the security controls in detail. In short, identity comes only from IIS and the service accepts connections from loopback only. The model key is read from the service environment and scrubbed from every error and log. All text is escaped in the browser. Reports are served with a restrictive policy from one folder. Tools are read-only against the data and write only to report folders. Users are told that aggregated figures are sent to the external model provider. 5.8 Step 8: Test Tests use a mocked model, so no paid calls are made and results are repeatable (Section 10.1). They cover the API contract, path traversal, cross-user isolation, malformed model output and missing keys. They also run a simulated 30-user mixed workload, check cleanup on timeout and disconnect, scan responses and logs to confirm the key never appears, and exercise the tool router with fake clients. 5.9 Step 9: Document and deploy Two idempotent PowerShell scripts install the service and configure IIS. The README documents installation, service commands, key rotation and troubleshooting. Idempotence matters because configuration drift is a frequent cause of failure in reverse-proxy deployments, and a script that can be safely rerun repairs drift instead of adding to it. 6. The Agent Boundary and a Transport-Neutral Tool Layer The agent is treated as a black box that takes a prompt and history and returns an answer, files and a trace. Only one part of its configuration matters to the interface design, and that is how it reaches tools. A deployment may reach a tool server as a local STDIO child process or as a remote HTTPS endpoint, and may move a server from one to the other. Neither choice should change the browser, IIS or the API contract. Three small abstractions achieve this (Figure 7). ToolClient interface. Three asynchronous operations: list_tools() , which returns name, description and input schema, call_tool(name, arguments) , which returns a result object, and close() . An STDIO client, an in-process fallback and a Streamable HTTP client all implement it. Server registry. A list of entries, each with a name, transport, command or URL, the name of the environment variable holding its credential, a timeout and an enabled flag. A deployment can start with a single entry, such as the local invoice server over STDIO, and grow by loading more entries from a configuration file. Tool router. It combines the tools of every enabled client into one live list for the model and sends each call to the client that owns the tool. Once more than one server is registered, it namespaces tool names ( server__tool ) so collisions cannot happen. A slow or unreachable server is skipped with a status event and does not fail the whole request. Application-specific behavior, such as the data summary sent to the model, query identifiers and the rule that report requests must produce an HTML file, lives in an adapter and not in the generic loop. That way, servers that know nothing about invoices can still be used. Figure 7. The transport-neutral tool layer. A remote server is added with a registry entry. One HTTP client implementation serves all remote servers, and no code above the router changes. 6.1 Registry example The following shows the shape of the registry for the four ChefAI servers. Credentials are referenced by environment-variable name, and the secrets themselves never appear in the file. Here docs , logs and dumps correspond to server1.py , server2.py and server3.py . With several servers registered, the model sees namespaced tools such as invoices__generate_invoice or logs__search_logs . Each extra server makes the tool list sent with every model call longer, so a practical deployment should filter or pre-route the list by request intent. Section 11 returns to this. 7. The ChefAI MCP Server Fleet The ChefAI scenario (Section 1.2) uses four servers with deliberately different capabilities (Table 2). Tool names are illustrative, and an implementation may name and group tools differently. Server Transport Capability and example tools Data sensitivity Operational notes Invoice generator server.py STDIO, local Queries purchasing data by period, item and vendor, and generates HTML invoices and reports with totals computed in code. Tools: query expenses ,generate invoice ,generate report , chef summary . Business- confidential totals and vendor names. One child process per request. Read- only on data, writes only to report folders. Document processor (Agentic RAG) server1.py HTTPS, remote Answers questions by retrieving data and documents (supplier contracts, return policies, menus, allergen sheets, equipment manuals, runbooks) from an Agentic RAG system and returning an answer with citations. Tools: search documents , get document, answer with citations . Mixed. Some documents are confidential (contracts, pricing), so it needs document-level access control. Read-only. Always returns source references. Has a retrieval budget and timeout, and shows index freshness. Log analyzer server2.py HTTPS, remote Searches and summarizes application and device logs from point-of-sale, kitchen-display and ordering systems: error counts by time bucket, top messages, correlation by request id. Tools: search logs ,summarize errors ,time histogram . May contain user identifiers, IP addresses or secrets, so it needs redaction. Read-only. Limits result size and redacts on the server side. Dump analyzer server3.py HTTPS, remote Triages crash or memory dumps from restaurant systems:exception summary, faulting module, thread stacks. Tools: list dumps , analyze dump , stack summary. Dumps can contain memory contents,including credentials. The most sensitive server. Long-running, so it needs a larger timeout. Strict access control. Returns summaries only, never raw dumps, to the model. Table 2. The four MCP servers in the ChefAI scenario. 7.1 Agentic RAG in the document processor Retrieval-augmented generation (RAG) grounds a model’s answer in retrieved documents instead of the model’s own memory. An agentic RAG system goes further. It plans the retrieval, may rewrite the query, searches several collections, reads the most promising documents, checks whether the evidence is enough and iterates before answering. In ChefAI this behavior lives inside the document server, behind a small tool surface. The main agent sees one tool, such as answer_with_citations , and does not need to know how the retrieval works. This has three consequences for the design. The document server must return citations so the interface can show sources. Its latency is usually higher than a simple lookup and is bounded by its own timeout and retrieval budget. And retrieved text is untrusted input that can carry injected instructions (threat T2 in Section 8). 7.2 Cross-server tasks The value of a multi-server fleet is that the servers can work together. Take a request such as “The kitchen display froze during Friday dinner service. What happened and what should we do?” It could need the log analyzer for an error histogram around the incident, the dump analyzer for the crash cause and the document processor for the vendor’s runbook and escalation policy. A request such as “Generate the year-to-date invoice and check our dairy return policy” combines the invoice generator with the document processor. The router makes these tools look like one catalogue. Per-server timeouts and failure isolation mean that if the dump server is down, the other tools still answer. Combining servers also raises a data-flow question, because results from one server become inputs to another through the model. Every result passes through the engine, so the engine is the right place to apply size limits, redaction rules and per-server allow-lists. 8. Windows Authentication, Trust Boundaries and Threats 8.1 Identity flow and the absence of a double hop The browser authenticates to IIS using Negotiate (Kerberos or NTLM). IIS knows the user’s account, copies it into X-Forwarded-User and forwards the request over loopback. From that point the application uses only the name, for scoping history, report access, rate limits and logs. The user’s Windows token is never impersonated or forwarded. Resources are reached with service-level credentials: the data file with the service account, the model with an API key, and remote MCP servers with a bearer token or client certificate (Figure 8). No downstream system needs to act as the user, so Kerberos constrained delegation is unnecessary. Figure 8. Identity and credential flow. The user identity is used only for scoping, and every downstream resource is reached with a service-level credential. When delegation would be needed. Delegation, or token forwarding, becomes necessary only if a downstream system must authorize the end user itself. Examples are a per-user permissioned file share, a SQL Server using Windows authentication as the user, or a remote MCP server (such as the document processor) that must apply the caller’s own document entitlements. Those cases would need Kerberos constrained delegation or an OAuthstyle token exchange, and they are outside this design. 8.2 Trust boundaries Figure 9 marks four zones and the threats that cross them. The key rule is that the Python service trusts the identity header only because it listens on loopback and IIS overwrites the header on every proxied request. Figure 9. Trust zones and threat markers T1 to T6 (Table 3). Arrows show the direction of requests. ID Threat Mitigation in this design T1 Spoofed identity header or direct access to the service port IIS overwrites the header on every proxied request. The service binds to 127.0.0.1 and rejects non-loopback callers, and the port is not opened in the firewall. T2 Prompt injection through tool results, retrieved documents or logs (for example text that says “ignore your instructions”) Tool results and retrieved text are treated as untrusted data. Tools are read- only. Tool calls are allow-listed and capped, arguments are validated against schemas, and results are size-limited and redacted before they reach the model. T3 Pointing the agent at arbitrary URLs (server-side request forgery) Remote servers come only from the registry. HTTPS is required, hosts are allow-listed and the model cannot supply URLs. T4 Sensitive data leaving the network through the model provider Only aggregates, provenance and short cited excerpts are sent, never raw rows. Log and dump summaries are redacted. The UI shows a notice and the provider is chosen by policy. T5 Cross-user leakage (history, query results, reports, documents) Per-session stores keyed by user and conversation. Query identifiers are owned by one session, reports are scoped, and the retrieval system applies document-level access control. Tests try cross-access on purpose. T6 Path traversal or exposure of secrets in files served by IIS or the service Report filenames are allow-listed and the resolved path is checked. IIS denies .py , .csv , .env , .log and .md . Keys live only in the service environment and are scrubbed from errors and logs. Table 3. Threat model. The model key is stored in the service’s environment, which administrators can read from the registry. Sites that need stronger protection should use a machine-level secret store read at start-up. 9. IIS Hosting and Deployment Figure 10 shows the physical deployment. Only port 443 is exposed to clients. The Python service listens on loopback and needs no inbound firewall rule. Outbound traffic is limited to the model provider and the approved remote MCP hosts. Figure 10. Deployment topology and firewall posture. 9.1 Provisioning sequence Install IIS with static content, request filtering and Windows Authentication. Install URL Rewrite and ARR. Enable the ARR proxy, set its timeout above the engine timeout, set the response buffer limit to zero and allow the HTTP_X_FORWARDED_USER server variable. Create the application pool (No Managed Code) and the site pointing at the UI folder, then add the HTTPS binding with an internal CA or test certificate. Disable Anonymous and enable Windows Authentication at the application-host scope. Add the rewrite rule, request limits, security headers and file-type deny list to the site configuration. Create the service account, grant the narrowest file permissions, install the service wrapper, set the environment variables and start the service. Verify the result: the service is running, the health endpoint answers on loopback, sign-in from a client is silent, a streamed answer arrives, a report card appears, access to data and source files is blocked, and two simultaneous users get independent results. 9.2 Common failure modes Symptom Typical cause 502.3 on /api Service stopped, wrong port, or ARR proxy not enabled. 500.50 from URL Rewrite The identity server variable is not in the allowed list. Repeated sign-in prompts Authentication sections not set at application-host scope, browser zone settings, or a missing service principal name for the site name. Progress arrives only at the end Response buffering or dynamic compression on the proxied route. Timeouts near two minutes Proxy timeout shorter than the engine timeout. Leftover Python processes Cleanup path not triggered on timeout or disconnect. 10. Evaluation Methodology and Capacity Reasoning 10.1 Evaluation plan An implementation of this architecture should be evaluated against the criteria in Table 4 before it is released to users. A mocked model keeps functional tests repeatable and free of provider cost. Latency and quality are then measured with the real provider. Question Method Metric or pass criterion Correctness of the API Mocked model, test client and deterministic scenarios. All contract and error-path tests pass, and totals equal direct data queries. Isolation 30 simulated users with mixed queries and reports, plus deliberate cross-access attempts. Zero cross-user data, zero unhandled exceptions and zero orphaned processes. Concurrency limits Ramp from 1 to 30 users, saturate agent slots and fill the queue. Running agents never exceed the configured cap, overflow returns 429, and the system recovers after the burst. Real-time responsiveness Mocked model with a fixed delay, then the real provider, with a browser trace through IIS. Median and 95th-percentile end-to-end time, time to first event, first event before the first tool completes, and no buffering. Cleanup Timeout and abrupt disconnect tests. Child processes terminated, slots released and no handle growth after repeated runs. Secret hygiene Automated scan of responses, logs and error text. The key never appears. Router Two to four fake clients, one slow and one failing. Correct routing and namespacing, and the request still succeeds when one client fails. Retrieval quality (document server) A question set with known source documents. Share of answers with correct citations, and refusal when evidence is missing. Table 4. Recommended evaluation plan. 10.2 A capacity argument Little’s law relates the average number of requests in service N to the arrival rate λ and the average time in the system W: N = λ × W [7]. Suppose, as an assumption, that each of 30 users submits one request per minute on average (λ = 0.5 requests per second). If the mean service time is 15 s, then on average N = 7.5 requests are in service at once. That fits the default of eight agent slots with little queueing. If the mean time is 30 s, then N = 15, the slots saturate and queueing delay grows, so either the cap or the speed of each run has to change. The model call is the biggest part of a run, and an Agentic RAG lookup adds its own multi-step latency. Provider latency and the number of tool calls per request therefore set the capacity you need. These figures illustrate the method, and each deployment should substitute its own measured arrival rate and service time. Memory per STDIO child process also grows with N, so it must be measured before choosing between one child per request and a pool. 11. Limitations and Future Work Reference architecture. ChefAI is a fictitious scenario and the figures in this paper are design values, not benchmark results. Capacity, latency and memory must be measured for each real deployment. Single-process assumption. Per-user limits, history and the shared data cache live in memory. Scaling to several worker processes needs a shared store, such as a database or cache, or sticky routing. Tool-list growth. More servers mean larger prompts and more mistakes in tool selection. Pre- routing by intent, per-user tool entitlements and lazy tool loading are natural extensions. Per-user authorization downstream. The design uses service credentials. If remote servers, notably the document processor, must enforce each user’s own rights, token exchange or delegation will be required. Model-provider dependence. Answers depend on an external provider’s availability, cost and data policy. An on-premises model would change the data-egress analysis. Human factors. The paper does not prescribe a usability study. Candidate measures include task completion, perceived trust in numbers and citations, and how clear the status line is. Secret storage. A service environment variable is fine for a pilot. A managed secret store is better for production. 12. Conclusion Putting an MCP agent behind a familiar chat interface is mostly an engineering problem at the edges. The questions are how the request enters, who the user is, how long-running work is streamed, how concurrent users are kept apart and how new tool servers are added without disturbing the rest. The architecture in this paper keeps IIS thin, with static content, TLS, Windows Authentication and a reverse proxy. It puts the agent behind a loopback Python service with explicit admission control, and it separates the interface from the way tools are reached by using a small transport-neutral tool layer. User identity is used only for scoping and every downstream resource is reached with a service credential, so no Kerberos delegation is needed. For the fictitious ChefAI restaurant, this gives staff real-time answers, invoices, document-grounded guidance and log and dump diagnostics from one chat window. The recommended path is to build the nine steps in order, validate the result with the evaluation plan, and add remote MCP servers one at a time through registry entries. References Model Context Protocol. “Model Context Protocol specification.” modelcontextprotocol.io (accessed October 2026). WHATWG. “HTML Living Standard: Server-sent events.” html.spec.whatwg.org (accessed October 2026). Jaganathan, K., Zhu, L., and Brezak, J. “SPNEGO-based Kerberos and NTLM HTTP Authentication in Microsoft Windows,” RFC 4559, IETF, June 2006. Microsoft. “URL Rewrite” and “Application Request Routing” documentation for IIS, learn.microsoft.com and iis.net (accessed October 2026). Fielding, R., Nottingham, M., and Reschke, J. “HTTP Semantics,” RFC 9110, IETF, 2022. OWASP Foundation. “OWASP Top 10 for Large Language Model Applications.” owasp.org (accessed October 2026). Little, J. D. C. “A Proof for the Queuing Formula: L = λW.” Operations Research 9(3), 1961. Appendix A. Event stream schema Each SSE message has an event name and a JSON data field. The schema is the only contract between the browser and the engine. Appendix B. Environment variables Variable Purpose LLM_PROVIDER, LLM_MODEL Model provider and optional model override. LLM_API_KEY Provider key. Service environment only, never logged or returned. CHEFAI_CSV_PATH Location of the purchasing data file used by the invoice server. CHEFAI_REQUIRE_USER 1 rejects requests without the identity header (production). 0 uses a single anonymous user (development). CHEFAI_MAX_AGENTS Concurrent agent runs (default 8). CHEFAI_REQUEST_TIMEOUT Per-request wall-clock limit in seconds (default 120). MCP_*_TOKEN Per-server credentials for remote MCP servers, referenced by name in the registry. Appendix C. Key IIS settings These settings are indicative. Module versions and server policies vary, so validate them in a non-production environment before rolling out.695Views3likes0Comments
MCP Server Authorization with Azure API Management: From Simple to Advanced
Why put API Management in front of your MCP servers The Model Context Protocol (MCP) has quickly become the standard way for AI agents, such as GitHub Copilot in VS Code, to reach external tools and data. As soon as an MCP server does anything meaningful, the same questions that govern any API resurface: who is allowed to call it, what are they allowed to do, and how do you enforce that consistently across many servers without rewriting each one. Azure API Management (APIM) answers those questions for MCP. It sits between the MCP client and the tool backend and applies the controls you already trust for REST APIs: identity validation, OAuth, rate limiting, IP filtering, and observability. Crucially, APIM speaks the MCP authorization specification, which is built on OAuth 2.1 and Protected Resource Metadata (PRM, RFC 9728). That means APIM can do more than block bad requests. It can actively drive an interactive sign-in from the IDE, so the user logs in with their own identity and the agent acts on their behalf. This article walks through a progression of authorization scenarios, each one building on the last: The simple case: validate a token and block everything else. Triggering an interactive sign-in from VS Code for an MCP server that APIM hosts from your own APIs. Going beyond "is this a tenant user" to "does this user have the right attribute" with Entra app roles. Fronting an existing external MCP server and letting it drive its own OAuth flow (GitHub as the example). Governing which tools of an existing MCP server an agent is actually allowed to invoke. APIM MCP capabilities and the basic authorization options API Management exposes MCP servers in two distinct ways, and the authorization story differs slightly for each. Expose a REST API as an MCP server. APIM takes an API it already manages and projects selected operations as MCP tools. You own the operations, so you choose exactly which ones become tools at configuration time. This is the right mode when the capability you want to expose is an API you control. Expose an existing MCP server (passthrough). APIM fronts a remote MCP-compatible server (LangChain, an Azure Function, GitHub's remote MCP server, your own container) and relays the MCP protocol to it. APIM governs access, but the upstream server still owns its tool catalog. On top of either mode, you have a spectrum of authorization options: Subscription keys for simple, machine-to-machine access where a shared secret in a header is acceptable. Token validation with Microsoft Entra ID, where APIM acts as the protected resource and verifies a bearer token on every call. Interactive OAuth 2.1 sign-in, where APIM advertises Protected Resource Metadata so an MCP client can discover the authorization server, log the user in, and retry with a user token. Authorization passthrough, where an external MCP server presents its own authorization challenge and APIM relays it faithfully so the client authenticates directly against the upstream's identity provider. The rest of the article works through these options in increasing order of capability. The example setup The walkthroughs in the first three scenarios all use the same backend so you can reproduce them without standing up anything of your own: the publicly available Star Wars API at Star Wars API. It is a simple, read-friendly REST API (characters, films, planets, starships, and so on) imported into API Management as a normal API and then projected as an MCP server. The reason this single API is enough to illustrate the whole progression is that, in API Management, one underlying API can back several independent MCP servers, each exposing a different slice of its operations. For example, you can create: A read-only MCP server that exposes only the GET operations, for agents that should be able to query data but never change it. A write-capable MCP server that exposes the POST, PUT, or DELETE operations, for trusted automation that is allowed to mutate state. Same backend API, two MCP servers, two different tool surfaces. Each of these servers is an independent resource in APIM, so each one can carry its own authorization. Both can require an authenticated user (Scenarios 1 and 2), and you can go further by protecting only the sensitive one: gate the write-capable server behind an Entra app role so that, even among authenticated users, only those who carry a specific claim can reach the mutating tools. That app-role mechanism is the subject of Scenario 3, and it composes naturally with the multi-server split described here. Registering the MCP API in Microsoft Entra ID Before any of the policies below can validate a token, you need an application registration in Microsoft Entra ID that represents the MCP API. This registration is what defines the audience and scope that tokens are issued for, and it is the source of the mcp-audience, mcp-scope, and (indirectly) mcp-client-id values that the policies reference. Create it once and reuse it across all the MCP servers in this article. In the Azure portal, open Microsoft Entra ID, then App registrations, then New registration. Name it (for example, star-wars-mcp-api), choose single-tenant, and register. Record the Application (client) ID and the Directory (tenant) ID. Open Expose an API and add an Application ID URI. Accept the default api://<app-id>. This URI is your token audience. Still under Expose an API, add a delegated scope named MCP.Access, set its consent display name and description, set the state to Enabled, and save. Authorize the client that will request the scope. Under Expose an API, select Add a client application and enter the client ID of the MCP client. For VS Code, this is the built-in Microsoft authentication client aebc6443-996d-45c2-90f0-388ff96faa56. Check the MCP.Access scope and save. These steps produce the four constants the validation policy needs: Named value Comes from Example entra-tenant-id The Directory (tenant) ID from step 1 11111111-1111-1111-1111-111111111111 mcp-audience The Application ID URI from step 2 api://22222222-2222-2222-2222-222222222222 mcp-scope The scope name from step 3 MCP.Access mcp-client-id The client ID of the calling app from step 4 aebc6443-996d-45c2-90f0-388ff96faa56 [!NOTE] mcp-client-id is the identity of the application calling the MCP server, not the MCP API itself. For VS Code it is the built-in Microsoft authentication client, and its value lands in the token's appid claim, which is why the validation policy lists it under client-application-ids. If your tenant blocks the first-party VS Code client, register your own public client application and use its client ID instead. [!TIP] For the privileged-access feature in Scenario 3, you will also declare an app role on this same registration. You do not need it yet, but it is convenient to know that all identity configuration for these servers lives on this one app registration. With that backend and structure in mind, the scenarios below build up the authorization model one capability at a time. Scenario 1: The simple case, validate the token and block unauthorized access The most basic protection is to require a valid Entra ID token on every MCP request and reject anything that fails validation. No interactive flow, no roles, just a gate. APIM does this with the validate-azure-ad-token policy. The policy checks the issuing tenant, the audience (your MCP API), the calling client application, and the required scope. Anything that does not satisfy all four is rejected with a 401. <policies> <inbound> <base /> <validate-azure-ad-token tenant-id="{{entra-tenant-id}}" header-name="Authorization" failed-validation-httpcode="401" failed-validation-error-message="Unauthorized. Access token is missing or invalid."> <client-application-ids> <application-id>{{mcp-client-id}}</application-id> </client-application-ids> <audiences> <audience>{{mcp-audience}}</audience> </audiences> <required-claims> <claim name="scp" match="any"> <value>{{mcp-scope}}</value> </claim> </required-claims> </validate-azure-ad-token> </inbound> <backend> <base /> </backend> <outbound> <base /> </outbound> <on-error> <base /> </on-error> </policies> The values in double braces are APIM named values: centralized constants, defined once and shared by every MCP server. They map directly to the four values produced by the Entra app registration in the example setup (entra-tenant-id, mcp-audience, mcp-scope, and mcp-client-id). Storing them as named values keeps the policy free of hardcoded identifiers and lets every server reuse the same configuration. This gets you a server that nobody can call without a properly minted token. What it does not do is help a fresh client obtain that token in the first place. That is the next scenario. Scenario 2: Driving an interactive sign-in from VS Code for an APIM-hosted MCP server When you expose one of your own APIs as an MCP server, you usually want a developer to open VS Code, connect to the server, and be prompted to sign in with their Microsoft account. No pre-shared key, no manual token handling. APIM achieves this by behaving as a well-mannered OAuth 2.1 protected resource. Using the Star Wars MCP server from the example setup, each selected operation becomes a tool the agent can call, so an agent can answer "which films featured the character named Leia" by calling the underlying API through APIM. How the sign-in flow works The protocol choreography is what turns a plain 401 into an interactive login: Two ingredients make this work: a 401 challenge that points to a metadata document, and the metadata document itself. The challenge: a 401 that points the client to its metadata Instead of a bare 401, APIM returns a WWW-Authenticate header carrying the URL of the server's Protected Resource Metadata. This is what tells the client "you need a token, and here is where to learn how to get one." Keeping this logic in a shared policy fragment means every MCP server reuses it. Notice the mcpResourceMetadataUrl reference in the fragment below. It is not hardcoded; it is a context variable that each MCP server sets in its own server-level policy before including this fragment (you will see that wiring in the per-server policy later in this scenario). The fragment simply reads whatever value the calling server provided. This indirection is what keeps the fragment pluggable: the same shared challenge-and-validate logic serves every MCP server, while each server supplies its own PRM URL. In most deployments the PRM endpoint is a single, dynamic one (built in the next section) that derives the resource from the request path, so the variable just carries that server's path. But because the URL is configurable per server rather than baked into the fragment, you retain flexibility for the cases that need it. <fragment> <!-- No token: challenge with the per-server PRM URL set by the caller --> <choose> <when condition="@(!context.Request.Headers.ContainsKey("Authorization"))"> <return-response> <set-status code="401" reason="Unauthorized" /> <set-header name="WWW-Authenticate" exists-action="override"> <value>@("Bearer resource_metadata=\"" + (string)context.Variables.GetValueOrDefault("mcpResourceMetadataUrl", "") + "\"")</value> </set-header> </return-response> </when> </choose> <!-- Token present: validate against shared named values --> <validate-azure-ad-token tenant-id="{{entra-tenant-id}}" header-name="Authorization" failed-validation-httpcode="401" failed-validation-error-message="Unauthorized. Access token is missing or invalid."> <client-application-ids> <application-id>{{mcp-client-id}}</application-id> </client-application-ids> <audiences> <audience>{{mcp-audience}}</audience> </audiences> <required-claims> <claim name="scp" match="any"> <value>{{mcp-scope}}</value> </claim> </required-claims> </validate-azure-ad-token> </fragment> Creating the /.well-known PRM endpoint in APIM with a policy This is the part that often surprises people: APIM itself serves the metadata document. There is no separate identity service to stand up. You publish one small anonymous API at the service root that answers GET /.well-known/oauth-protected-resource/*, derives the resource value from the requested path, and returns a JSON document pointing at Microsoft Entra ID as the authorization server. Create a blank HTTP API named well-known with an empty API URL suffix so it resolves at the service root, add a GET operation with the template /.well-known/oauth-protected-resource/*, clear the subscription requirement so it is reachable anonymously, and apply this policy: <policies> <inbound> <base /> <!-- Build the resource URL from the requested PRM sub-path --> <set-variable name="resourceUrl" value="@{ var prefix = "/.well-known/oauth-protected-resource"; var path = context.Request.OriginalUrl.Path; var resourcePath = path.Length > prefix.Length ? path.Substring(prefix.Length) : ""; return "https://" + context.Request.OriginalUrl.Host + resourcePath; }" /> <return-response> <set-status code="200" reason="OK" /> <set-header name="Content-Type" exists-action="override"> <value>application/json</value> </set-header> <set-body>@{ return new JObject( new JProperty("resource", (string)context.Variables["resourceUrl"]), new JProperty("authorization_servers", new JArray( "https://login.microsoftonline.com/{{entra-tenant-id}}/v2.0")), new JProperty("scopes_supported", new JArray("{{mcp-prm-scope}}")), new JProperty("bearer_methods_supported", new JArray("header")) ).ToString(); }</set-body> </return-response> </inbound> <backend> <base /> </backend> <outbound> <base /> </outbound> <on-error> <base /> </on-error> </policies> The {{mcp-prm-scope}} named value populates the scopes_supported array of the metadata document. It tells the client which delegated scope to request when it goes to the authorization server, so it must be the fully qualified scope value: the token audience (the Application ID URI from the app registration) followed by the scope name. With the example values that is api://22222222-2222-2222-2222-222222222222/MCP.Access. In other words, it is the combination of the mcp-audience and mcp-scope values defined in the example setup. Named value Value to set Example mcp-prm-scope <mcp-audience>/<mcp-scope> api://22222222-2222-2222-2222-222222222222/MCP.Access [!NOTE] Keep mcp-prm-scope in sync with the scope the validation fragment requires. The PRM document advertises this scope so the client requests it, and validate-azure-ad-token then checks for it in the scp claim. A mismatch means the client obtains a token without the scope APIM expects, and validation fails. Because the policy builds the resource value from the request path, this single endpoint serves metadata for every MCP server you ever add. The Star Wars server, a future inventory server, and anything else all share it. Wiring it onto the MCP server Each MCP server only needs to declare its own metadata URL and include the shared fragment: <policies> <inbound> <base /> <set-variable name="mcpResourceMetadataUrl" value="https://apim-contoso-mcp.azure-api.net/.well-known/oauth-protected-resource/star-wars-mcp/mcp" /> <include-fragment fragment-id="mcp-entra-auth" /> </inbound> <backend> <base /> </backend> <outbound> <base /> </outbound> <on-error> <base /> <include-fragment fragment-id="mcp-auth-challenge-onerror" /> </on-error> </policies> On the VS Code side, the configuration is deliberately plain. With no subscription-key header present, the client falls straight into the OAuth flow: { "servers": { "star-wars-mcp": { "url": "https://apim-contoso-mcp.azure-api.net/star-wars-mcp/mcp", "type": "http" } } } Restart the server in VS Code, and it detects the 401, reads the metadata, opens a browser sign-in, requests consent on first use, and then loads the tools using the user's token. [!CAUTION] Do not read the response body with context.Response.Body inside MCP server policies. It forces response buffering and breaks the MCP streaming transport. If global diagnostic logging is enabled, set the Frontend Response payload bytes to log to 0 at the All APIs scope. Scenario 3: Beyond tenant membership, authorize on a user attribute with app roles Validating a token confirms the caller is a signed-in user in your tenant with the right scope. That is often not enough. Some MCP servers expose sensitive tools that only a subset of users should reach. You want to express "this user is not only part of the tenant, but has a specific attribute that permits this server." Microsoft Entra app roles are the optimal mechanism for this. You declare a role on the MCP API app registration, assign it to specific users or to a security group, and Entra ID emits a roles claim in the access token whenever your API is the audience. APIM then authorizes on that claim. App roles beat the groups claim here because they avoid the group overage problem, they are scoped to the application, and they travel with the app. Declaring and assigning the role On the MCP API app registration, under App roles, create a role: Setting Value Display name Privileged Access Allowed member types Users/Groups Value Privileged.Access Description Access to privileged MCP servers Then, on the matching enterprise application, under Users and groups, assign the users (or, better, a security group) to the Privileged Access role. The Value field is the exact string that lands in the token roles claim, so it cannot contain spaces. [!TIP] Keep User assignment required set to No on the enterprise application. Unassigned users still obtain a valid token with the MCP.Access scope and keep access to the non-privileged servers. They simply do not carry the roles claim, so the privileged servers reject them. Enforcing the claim in the per-server policy The shared mcp-entra-auth fragment is used by every server, so the role requirement must not live there. Place the check in the privileged server's own policy, right after the fragment include. The token is already validated at that point, so this step is pure authorization. Because the caller is authenticated but not authorized, return 403, not 401, and do not emit a challenge: re-authenticating will not grant a role the user does not have. <policies> <inbound> <base /> <set-variable name="mcpResourceMetadataUrl" value="https://apim-contoso-mcp.azure-api.net/.well-known/oauth-protected-resource/star-wars-mcp/mcp" /> <include-fragment fragment-id="mcp-entra-auth" /> <!-- Privileged guardrail: require the Privileged.Access app role --> <choose> <when condition="@(!context.Request.Headers.GetValueOrDefault("Authorization","").Replace("Bearer ","").AsJwt().Claims.GetValueOrDefault("roles", new string[0]).Contains("Privileged.Access"))"> <return-response> <set-status code="403" reason="Forbidden" /> <set-header name="Content-Type" exists-action="override"> <value>application/json</value> </set-header> <set-body>{"error":"forbidden","message":"You lack the Privileged.Access role required for this MCP server."}</set-body> </return-response> </when> </choose> </inbound> <backend> <base /> </backend> <outbound> <base /> </outbound> <on-error> <base /> <include-fragment fragment-id="mcp-auth-challenge-onerror" /> </on-error> </policies> One operational detail worth calling out: app-role assignments only appear in newly issued tokens. A user who is granted the role after they signed in must obtain a fresh token. In VS Code, run MCP: Reset Cached Tokens (or sign out of the Microsoft account from the Accounts menu), then restart the server and sign in again. You can confirm the result by pasting the access token into https://jwt.ms and checking for "roles": ["Privileged.Access"]. Scenario 4: Fronting an existing external MCP server that drives its own sign-in So far APIM has been the authorization resource. But many valuable MCP servers already exist and run their own identity. GitHub publishes a remote MCP server with dozens of tools, and it authenticates users against GitHub's own OAuth authorization server. You do not want to re-implement that. You want APIM to govern access (rate limits, IP rules, logging, a single managed endpoint) while letting the upstream own the login. This is the "expose an existing MCP server" passthrough mode. When you register GitHub's remote MCP server behind APIM, the gateway relays the upstream's own authorization challenge. The client never authenticates against Entra here. It authenticates directly against GitHub. The flow, confirmed by probing the gateway: A call to the APIM endpoint with no token returns GitHub's own 401 with a WWW-Authenticate header, relayed through APIM. The Protected Resource Metadata that GitHub serves advertises authorization_servers: ["https://github.com/login/oauth"], so the client knows to log in at GitHub. The PRM resource reflects the APIM host, because GitHub builds it from the forwarded Host header. The client trusts the APIM endpoint while still logging in at GitHub. VS Code completes the GitHub sign-in and the full tool catalog loads. In the proof of concept this surfaced all 47 GitHub tools through the single APIM endpoint. The client configuration is again just a URL pointing at APIM: { "servers": { "github-via-apim": { "url": "https://apim-contoso-mcp.azure-api.net/github-mcp/mcp", "type": "http" } } } The key insight is that APIM transparently relays the backend's authentication challenge. GitHub remains the authorization server, GitHub tolerates being fronted by APIM, and you get a governed, centrally managed entry point without owning the identity flow. [!NOTE] Passthrough only relays what the upstream advertises. If the backend's PRM resource value and the actual MCP transport endpoint differ by a path segment, some clients fall back to deriving the metadata location from the server URL and can miss it. When you onboard a custom self-authenticating server, verify that the resource it advertises matches the exact URL the client connects to. Scenario 5: Restricting which tools of an existing MCP server an agent may call Passthrough raises a governance question that token validation alone cannot answer. A developer may legitimately have permission to merge a pull request through GitHub, but you may not want their AI agent to perform that action autonomously. You want to allow the read and discovery tools while blocking the destructive write tools, at the gateway, regardless of what the client tries. What is and is not possible for an external server It is important to be precise here, because the capability differs from the REST-as-MCP mode: For a REST-API-exposed-as-MCP server, you pick which operations become tools at creation time. That is native tool selection and the cleanest possible filter. For an existing/external MCP server, APIM does not enumerate the upstream's tools. The portal Tools blade explicitly states that tools are not visible for external MCP servers, and there is no allow-list property for them. APIM also cannot safely rewrite the tools/list response, because reading the response body breaks the streaming transport and the list may arrive as text/event-stream. What APIM can do reliably, and server-agnostically, is block the invocation. Every tool call arrives as a JSON-RPC tools/call request in the request body, which APIM can inspect safely. The deny-listed tools remain visible in the catalog, but any attempt to invoke one is intercepted at the gateway and returned a JSON-RPC error before it ever reaches the upstream. The reusable deny-list fragment The block is driven by a per-server named value (a comma-separated list of tool names), so the same fragment governs every external server. Only the named value changes. <!-- Fragment: mcp-tool-filter (include after the auth fragment) --> <fragment> <choose> <when condition="@(context.Request.Body != null)"> <set-variable name="mcpMethod" value="@{ try { var body = context.Request.Body.As<JObject>(preserveContent: true); return (string)body?["method"] ?? string.Empty; } catch { return string.Empty; } }" /> <choose> <when condition="@(((string)context.Variables["mcpMethod"]).Equals("tools/call", StringComparison.OrdinalIgnoreCase))"> <set-variable name="mcpToolName" value="@{ var body = context.Request.Body.As<JObject>(preserveContent: true); return (string)body?["params"]?["name"] ?? string.Empty; }" /> <!-- mcpBlockedTools is a comma-separated deny-list set by the per-server policy before this include --> <set-variable name="mcpBlocked" value="@{ var tool = ((string)context.Variables["mcpToolName"]).Trim().ToLowerInvariant(); var deny = ((string)context.Variables.GetValueOrDefault("mcpBlockedTools", "")).ToLowerInvariant().Split(',').Select(t => t.Trim()); return deny.Contains(tool); }" /> <choose> <when condition="@((bool)context.Variables["mcpBlocked"])"> <return-response> <set-status code="200" reason="OK" /> <set-header name="Content-Type" exists-action="override"> <value>application/json</value> </set-header> <set-body>@{ var id = "null"; try { var body = context.Request.Body.As<JObject>(preserveContent: true); id = body?["id"]?.ToString(Newtonsoft.Json.Formatting.None) ?? "null"; } catch {} return "{\"jsonrpc\":\"2.0\",\"id\":" + id + ",\"error\":{\"code\":-32602,\"message\":\"Unknown tool: " + ((string)context.Variables["mcpToolName"]) + "\"}}"; }</set-body> </return-response> </when> </choose> </when> </choose> </when> </choose> </fragment> The deny-list itself lives in a named value, one per server: APIM named value. Comma-separated, case-insensitive. mcp-blocked-tools-github = merge_pull_request,create_repository,delete_repository,push_files,create_or_update_file,issue_write,label_write # <policies> <inbound> <base /> <set-variable name="mcpResourceMetadataUrl" value="https://apim-contoso-mcp.azure-api.net/.well-known/oauth-protected-resource/github-mcp/mcp" /> <include-fragment fragment-id="mcp-entra-auth" /> <set-variable name="mcpBlockedTools" value="{{mcp-blocked-tools-github}}" /> <include-fragment fragment-id="mcp-tool-filter" /> </inbound> <backend> <base /> </backend> <outbound> <base /> </outbound> <on-error> <base /> <include-fragment fragment-id="mcp-auth-challenge-onerror" /> </on-error> </policies> Generic per-server pattern: mcp-blocked-tools-<server> = <comma,separated,tool,names> Wiring it onto the GitHub passthrough server <policies> <inbound> <base /> <set-variable name="mcpResourceMetadataUrl" value="https://apim-contoso-mcp.azure-api.net/.well-known/oauth-protected-resource/github-mcp/mcp" /> <include-fragment fragment-id="mcp-entra-auth" /> <set-variable name="mcpBlockedTools" value="{{mcp-blocked-tools-github}}" /> <include-fragment fragment-id="mcp-tool-filter" /> </inbound> <backend> <base /> </backend> <outbound> <base /> </outbound> <on-error> <base /> <include-fragment fragment-id="mcp-auth-challenge-onerror" /> </on-error> </policies> Now when the agent tries to merge a pull request, the gateway returns a clean -32602 Unknown tool error and the upstream is never touched. Read and discovery tools continue to work. The tool still appears in the client's catalog. Adding governance for another external server is just one more named value plus the same fragment include. No new policy logic. Key takeaways API Management turns MCP servers into governed resources, applying the same identity, traffic, and observability controls you already use for APIs. Start simple with validate-azure-ad-token to gate access, then graduate to a full interactive sign-in by serving Protected Resource Metadata from a single APIM policy. You can publish multiple MCP servers from one underlying API, for example a read-only server and a read-write server, by selecting different operations. App roles let you authorize on a user attribute, not just tenant membership, and the check belongs in the per-server policy so shared logic stays clean. For existing external servers, APIM relays the upstream's own OAuth flow, so a server like GitHub keeps owning its identity while you keep central governance. When an external server's full tool surface is too broad, APIM can block specific tool invocations at the gateway with a reusable, named-value-driven policy, so a user's agent cannot perform actions the user could perform manually. References About MCP servers in Azure API Management Secure access to MCP servers in API Management Expose REST API in API Management as an MCP server Expose and govern an existing MCP server validate-azure-ad-token policy reference Policy fragments in API Management RFC 9728: OAuth 2.0 Protected Resource Metadata MCP authorization specification Star Wars API (example backend) MCP for Beginners1.9KViews3likes2CommentsAgents League: Meet the Winners
Agents League brought together developers from around the world to build AI agents using Microsoft's developer tools. With 100+ submissions across three tracks, choosing winners was genuinely difficult. Today, we're proud to announce the category champions. 🎨 Creative Apps Winner: CodeSonify View project CodeSonify turns source code into music. As a genuinely thoughtful system, its functions become ascending melodies, loops create rhythmic patterns, conditionals trigger chord changes, and bugs produce dissonant sounds. It supports 7 programming languages and 5 musical styles, with each language mapped to its own key signature and code complexity directly driving the tempo. What makes CodeSonify stand out is the depth of execution. CodeSonify team delivered three integrated experiences: a web app with real-time visualization and one-click MIDI export, an MCP server exposing 5 tools inside GitHub Copilot in VS Code Agent Mode, and a diff sonification engine that lets you hear a code review. A clean refactor sounds harmonious. A messy one sounds chaotic. The team even built the MIDI generator from scratch in pure TypeScript with zero external dependencies. Built entirely with GitHub Copilot assistance, this is one of those projects that makes you think about code differently. 🧠 Reasoning Agents Winner: CertPrep Multi-Agent System View project CertPrep Multi-Agent System team built a production-grade 8-agent system for personalized Microsoft certification exam preparation, supporting 9 exam families including AI-102, AZ-204, AZ-305, and more. Each agent has a distinct responsibility: profiling the learner, generating a week-by-week study schedule, curating learning paths, tracking readiness, running mock assessments, and issuing a GO / CONDITIONAL GO / NOT YET booking recommendation. The engineering behind the scene here is impressive. A 3-tier LLM fallback chain ensures the system runs reliably even without Azure credentials, with the full pipeline completing in under 1 second in mock mode. A 17-rule guardrail pipeline validates every agent boundary. Study time allocation uses the Largest Remainder algorithm to guarantee no domain is silently zeroed out. 342 automated tests back it all up. This is what thoughtful multi-agent architecture looks like in practice. 💼 Enterprise Agents Winner: Whatever AI Assistant (WAIA) View project WAIA is a production-ready multi-agent system for Microsoft 365 Copilot Chat and Microsoft Teams. A workflow agent routes queries to specialized HR, IT, or Fallback agents, transparently to the user, handling both RAG-pattern Q&A and action automation — including IT ticket submission via a SharePoint list. Technically, it's a showcase of what serious enterprise agent development looks like: a custom MCP server secured with OAuth Identity Passthrough, streaming responses via the OpenAI Responses API, Adaptive Cards for human-in-the-loop approval flows, a debug mode accessible directly from Teams or Copilot, and full OpenTelemetry integration visible in the Foundry portal. Franck also shipped end-to-end automated Bicep deployment so the solution can land in any Azure environment. It's polished, thoroughly documented, and built to be replicated. Thank you To every developer who submitted and shipped projects during Agents League: thank you 💜 Your creativity and innovation brought Agents League to life! 👉 Browse all submissions on GitHubBuilding a Smart Building HVAC Digital Twin with AI Copilot Using Foundry Local
Introduction Building operations teams face a constant challenge: optimizing HVAC systems for energy efficiency while maintaining occupant comfort and air quality. Traditional building management systems display raw sensor data, temperatures, pressures, CO₂ levels—but translating this into actionable insights requires deep HVAC expertise. What if operators could simply ask "Why is the third floor so warm?" and get an intelligent answer grounded in real building state? This article demonstrates building a sample smart building digital twin with an AI-powered operations copilot, implemented using DigitalTwin, React, Three.js, and Microsoft Foundry Local. You'll learn how to architect physics-based simulators that model thermal dynamics, implement 3D visualizations of building systems, integrate natural language AI control, and design fault injection systems for testing and training. Whether you're building IoT platforms for commercial real estate, designing energy management systems, or implementing predictive maintenance for building automation, this sample provides proven patterns for intelligent facility operations. Why Digital Twins Matter for Building Operations Physical buildings generate enormous operational data but lack intelligent interpretation layers. A 50,000 square foot office building might have 500+ sensors streaming metrics every minute, zone temperatures, humidity levels, equipment runtimes, energy consumption. Traditional BMS (Building Management Systems) visualize this data as charts and gauges, but operators must manually correlate patterns, diagnose issues, and predict failures. Digital twins solve this through physics-based simulation coupled with AI interpretation. Instead of just displaying current temperature readings, a digital twin models thermal dynamics, heat transfer rates, HVAC response characteristics, occupancy impacts. When conditions deviate from expectations, the twin compares observed versus predicted states, identifying root causes. Layer AI on top, and operators get natural language explanations: "The conference room is 3 degrees too warm because the VAV damper is stuck at 40% open, reducing airflow by 60%." This application focuses on HVAC, the largest building energy consumer, typically 40-50% of total usage. Optimizing HVAC by just 10% through better controls can save thousands of dollars monthly while improving occupant satisfaction. The digital twin enables "what-if" scenarios before making changes: "What happens to energy consumption and comfort if we raise the cooling setpoint by 2 degrees during peak demand response events?" Architecture: Three-Tier Digital Twin System The application implements a clean three-tier architecture separating visualization, simulation, and state management: The frontend uses React with Three.js for 3D visualization. Users see an interactive 3D model of the three-floor building with color-coded zones indicating temperature and CO₂ levels. Click any equipment, AHUs, VAVs, chillers, to see detailed telemetry. The control panel enables adjusting setpoints, running simulation steps, and activating demand response scenarios. Real-time charts display KPIs: energy consumption, comfort compliance, air quality levels. The backend Node.js/Express server orchestrates simulation and state management. It maintains the digital twin state as JSON, the single source of truth for all equipment, zones, and telemetry. REST API endpoints handle control requests, simulation steps, and AI copilot queries. WebSocket connections push real-time updates to the frontend for live monitoring. The HVAC simulator implements physics-based models: 1R1C thermal models for zones, affinity laws for fan power, chiller COP calculations, CO₂ mass balance equations. Foundry Local provides AI copilot capabilities. The backend uses foundry-local-sdk to query locally running models. Natural language queries ("How's the lobby temperature?") get answered with building state context. The copilot can explain anomalies, suggest optimizations, and even execute commands when explicitly requested. Implementing Physics-Based HVAC Simulation Accurate simulation requires modeling actual HVAC physics. The simulator implements several established building energy models: // backend/src/simulator/thermal-model.js class ZoneThermalModel { // 1R1C (one resistance, one capacitance) thermal model static calculateTemperatureChange(zone, delta_t_seconds) { const C_thermal = zone.volume * 1.2 * 1000; // Heat capacity (J/K) const R_thermal = zone.r_value * zone.envelope_area; // Thermal resistance // Internal heat gains (occupancy, equipment, lighting) const Q_internal = zone.occupancy * 100 + // 100W per person zone.equipment_load + zone.lighting_load; // Cooling/heating from HVAC const airflow_kg_s = zone.vav.airflow_cfm * 0.0004719; // CFM to kg/s const c_p_air = 1006; // Specific heat of air (J/kg·K) const Q_hvac = airflow_kg_s * c_p_air * (zone.vav.supply_temp - zone.temperature); // Envelope losses const Q_envelope = (zone.outdoor_temp - zone.temperature) / R_thermal; // Net energy balance const Q_net = Q_internal + Q_hvac + Q_envelope; // Temperature change: Q = C * dT/dt const dT = (Q_net / C_thermal) * delta_t_seconds; return zone.temperature + dT; } } This model captures essential thermal dynamics while remaining computationally fast enough for real-time simulation. It accounts for internal heat generation from occupants and equipment, HVAC cooling/heating contributions, and heat loss through the building envelope. The CO₂ model uses mass balance equations: class AirQualityModel { static calculateCO2Change(zone, delta_t_seconds) { // CO₂ generation from occupants const G_co2 = zone.occupancy * 0.0052; // L/s per person at rest // Outdoor air ventilation rate const V_oa = zone.vav.outdoor_air_cfm * 0.000471947; // CFM to m³/s // CO₂ concentration difference (indoor - outdoor) const delta_CO2 = zone.co2_ppm - 400; // Outdoor ~400ppm // Mass balance: dC/dt = (G - V*ΔC) / Volume const dCO2_dt = (G_co2 - V_oa * delta_CO2) / zone.volume; return zone.co2_ppm + (dCO2_dt * delta_t_seconds); } } These models execute every simulation step, updating the entire building state: async function simulateStep(twin, timestep_minutes) { const delta_t = timestep_minutes * 60; // Convert to seconds // Update each zone for (const zone of twin.zones) { zone.temperature = ZoneThermalModel.calculateTemperatureChange(zone, delta_t); zone.co2_ppm = AirQualityModel.calculateCO2Change(zone, delta_t); } // Update equipment based on zone demands for (const vav of twin.vavs) { updateVAVOperation(vav, twin.zones); } for (const ahu of twin.ahus) { updateAHUOperation(ahu, twin.vavs); } updateChillerOperation(twin.chiller, twin.ahus); updateBoilerOperation(twin.boiler, twin.ahus); // Calculate system KPIs twin.kpis = calculateSystemKPIs(twin); // Detect alerts twin.alerts = detectAnomalies(twin); // Persist updated state await saveTwinState(twin); return twin; } 3D Visualization with React and Three.js The frontend renders an interactive 3D building view that updates in real-time as conditions change. Using React Three Fiber simplifies Three.js integration with React's component model: // frontend/src/components/BuildingView3D.jsx import { Canvas } from '@react-three/fiber'; import { OrbitControls } from '@react-three/drei'; export function BuildingView3D({ twinState }) { return ( {/* Render building floors */} {twinState.zones.map(zone => ( selectZone(zone.id)} /> ))} {/* Render equipment */} {twinState.ahus.map(ahu => ( ))} ); } function ZoneMesh({ zone, onClick }) { const color = getTemperatureColor(zone.temperature, zone.setpoint); return ( ); } function getTemperatureColor(current, setpoint) { const deviation = current - setpoint; if (Math.abs(deviation) < 1) return '#00ff00'; // Green: comfortable if (Math.abs(deviation) < 3) return '#ffff00'; // Yellow: acceptable return '#ff0000'; // Red: uncomfortable } This visualization immediately shows building state at a glance, operators see "hot spots" in red, comfortable zones in green, and can click any area for detailed metrics. Integrating AI Copilot for Natural Language Control The AI copilot transforms building data into conversational insights. Instead of navigating multiple screens, operators simply ask questions: // backend/src/routes/copilot.js import { FoundryLocalClient } from 'foundry-local-sdk'; const foundry = new FoundryLocalClient({ endpoint: process.env.FOUNDRY_LOCAL_ENDPOINT }); router.post('/api/copilot/chat', async (req, res) => { const { message } = req.body; // Load current building state const twin = await loadTwinState(); // Build context for AI const context = buildBuildingContext(twin); const completion = await foundry.chat.completions.create({ model: 'phi-4', messages: [ { role: 'system', content: `You are an HVAC operations assistant for a 3-floor office building. Current Building State: ${context} Answer questions about equipment status, comfort conditions, and energy usage. Provide specific, actionable information based on the current data. Do not speculate beyond provided information.` }, { role: 'user', content: message } ], temperature: 0.3, max_tokens: 300 }); res.json({ response: completion.choices[0].message.content, model: 'phi-4', timestamp: new Date().toISOString() }); }); function buildBuildingContext(twin) { const alerts = twin.alerts.filter(a => a.active); const zoneStatus = twin.zones.map(z => `${z.name}: ${z.temperature.toFixed(1)}°F (setpoint: ${z.setpoint}°F), CO₂: ${z.co2_ppm}ppm, ${z.occupancy} people` ); return ` Zones: ${zoneStatus.join('\n')} Active Alerts: ${alerts.length} ${alerts.map(a => `- ${a.severity}: ${a.message}`).join('\n')} Energy: ${twin.kpis.total_power_kw.toFixed(1)} kW Chiller: ${twin.chiller.percent_load}% load, ${twin.chiller.cop.toFixed(2)} COP `.trim(); } Example interactions: User: "Why is the third floor conference room warm?" AI: "The Executive Suite on Floor 3 is currently 75.2°F, 3 degrees above the 72°F setpoint. This is due to high occupancy (8 people) and VAV-F3-EXEC operating at reduced airflow (285 CFM vs 450 CFM capacity). AHU-2 is supplying adequate cool air at 55°F. Recommend checking VAV damper position—it may be partially stuck." User: "What's our current energy usage?" AI: "Total building power consumption is 47.3 kW. Breakdown: Chiller (24.1 kW, 51%), AHU fans (12.8 kW, 27%), Pumps (7.2 kW, 15%), Other (3.2 kW, 7%). Chiller is operating at 62% load with a COP of 4.8, which is efficient for current conditions." User: "Activate demand response level 2" AI: "I cannot directly control building systems for safety reasons. To activate DR Level 2, use the Control Panel and click 'Demand Response' → 'Level 2'. This will raise cooling setpoints by 3°F and reduce auxiliary loads, targeting 15% energy reduction." The AI provides grounded, specific answers citing actual equipment IDs and metrics. It refuses to directly execute control commands, instead guiding operators to explicit control interfaces, a critical safety pattern for building systems. Fault Injection for Testing and Training Real building operations experience equipment failures, stuck dampers, sensor drift, communication losses. The digital twin includes comprehensive fault injection capabilities to train operators and test control logic: // backend/src/simulator/fault-injector.js const FAULT_CATALOG = { chillerFailure: { description: 'Chiller compressor failure', apply: (twin) => { twin.chiller.status = 'FAULT'; twin.chiller.cooling_output = 0; twin.alerts.push({ id: 'chiller-fault', severity: 'CRITICAL', message: 'Chiller compressor failure - no cooling available', equipment: 'CHILLER-01' }); } }, stuckVAVDamper: { description: 'VAV damper stuck at current position', apply: (twin, vavId) => { const vav = twin.vavs.find(v => v.id === vavId); vav.damper_stuck = true; vav.damper_position_fixed = vav.damper_position; twin.alerts.push({ id: `vav-stuck-${vavId}`, severity: 'HIGH', message: `VAV ${vavId} damper stuck at ${vav.damper_position}%`, equipment: vavId }); } }, sensorDrift: { description: 'Temperature sensor reading 5°F high', apply: (twin, zoneId) => { const zone = twin.zones.find(z => z.id === zoneId); zone.sensor_drift = 5.0; zone.temperature_measured = zone.temperature_actual + 5.0; } }, communicationLoss: { description: 'Equipment communication timeout', apply: (twin, equipmentId) => { const equipment = findEquipmentById(twin, equipmentId); equipment.comm_status = 'OFFLINE'; equipment.stale_data = true; twin.alerts.push({ id: `comm-loss-${equipmentId}`, severity: 'MEDIUM', message: `Lost communication with ${equipmentId}`, equipment: equipmentId }); } } }; router.post('/api/twin/fault', async (req, res) => { const { faultType, targetEquipment } = req.body; const twin = await loadTwinState(); const fault = FAULT_CATALOG[faultType]; if (!fault) { return res.status(400).json({ error: 'Unknown fault type' }); } fault.apply(twin, targetEquipment); await saveTwinState(twin); res.json({ message: `Applied fault: ${fault.description}`, affectedEquipment: targetEquipment, timestamp: new Date().toISOString() }); }); Operators can inject faults to practice diagnosis and response. Training scenarios might include: "The chiller just failed during a heat wave, how do you maintain comfort?" or "Multiple VAV dampers are stuck, which zones need immediate attention?" Key Takeaways and Production Deployment Building a physics-based digital twin with AI capabilities requires balancing simulation accuracy with computational performance, providing intuitive visualization while maintaining technical depth, and enabling AI assistance without compromising safety. Key architectural lessons: Physics models enable prediction: Comparing predicted vs observed behavior identifies anomalies that simple thresholds miss 3D visualization improves spatial understanding: Operators immediately see which floors or zones need attention AI copilots accelerate diagnosis: Natural language queries get answers in seconds vs. minutes of manual data examination Fault injection validates readiness: Testing failure scenarios prepares operators for real incidents JSON state enables integration: Simple file-based state makes connecting to real BMS systems straightforward For production deployment, connect the twin to actual building systems via BACnet, Modbus, or MQTT integrations. Replace simulated telemetry with real sensor streams. Calibrate model parameters against historical building performance. Implement continuous learning where the twin's predictions improve as it observes actual building behavior. The complete implementation with simulation engine, 3D visualization, AI copilot, and fault injection system is available at github.com/leestott/DigitalTwin. Clone the repository and run the startup scripts to explore the digital twin, no building hardware required. Resources and Further Reading Smart Building HVAC Digital Twin Repository - Complete source code and simulation engine Setup and Quick Start Guide - Installation instructions and usage examples Microsoft Foundry Local Documentation - AI integration reference HVAC Simulation Documentation - Physics model details and calibration Three.js Documentation - 3D visualization framework ASHRAE Standards - Building energy modeling standardsLearn how to build MCP servers with Python and Azure
We just concluded Python + MCP, a three-part livestream series where we: Built MCP servers in Python using FastMCP Deployed them into production on Azure (Container Apps and Functions) Added authentication, including Microsoft Entra as the OAuth provider All of the materials from our series are available for you to keep learning from, and linked below: Video recordings of each stream Powerpoint slides Open-source code samples complete with Azure infrastructure and 1-command deployment If you're an instructor, feel free to use the slides and code examples in your own classes. Spanish speaker? We've got you covered- check out the Spanish version of the series. 🙋🏽♂️Have follow up questions? Join our weekly office hours on Foundry Discord: Tuesdays @ 11AM PT → Python + AI Thursdays @ 8:30 AM PT → All things MCP Building MCP servers with FastMCP 📺 Watch YouTube recording In the intro session of our Python + MCP series, we dive into the hottest technology of 2025: MCP (Model Context Protocol). This open protocol makes it easy to extend AI agents and chatbots with custom functionality, making them more powerful and flexible. We demonstrate how to use the Python FastMCP SDK to build an MCP server running locally. Then we consume that server from chatbots like GitHub Copilot in VS Code, using it's tools, resources, and prompts. Finally, we discover how easy it is to connect AI agent frameworks like Langchain and Microsoft agent-framework to the MCP server. Slides for this session Code repository with examples: python-mcp-demos Deploying MCP servers to the cloud 📺 Watch YouTube recording In our second session of the Python + MCP series, we deploy MCP servers to the cloud! We walk through the process of containerizing a FastMCP server with Docker and deploying to Azure Container Apps. Then we instrument the MCP server with OpenTelemetry and observe the tool calls using Azure Application Insights and Logfire. Finally, we explore private networking options for MCP servers, using virtual networks that restrict external access to internal MCP tools and agents. Slides for this session Code repository with examples: python-mcp-demos Authentication for MCP servers 📺 Watch YouTube recording In our third session of the Python + MCP series, we explore the best ways to build authentication layers on top of your MCP servers. We start off simple, with an API key to gate access, and demonstrate a key-restricted FastMCP server deployed to Azure Functions. Then we move on to OAuth-based authentication for MCP servers that provide user-specific data. We dive deep into MCP authentication, which is built on top of OAuth2 but with additional requirements like PRM and DCR/CIMD, which can make it difficult to implement fully. We demonstrate the full MCP auth flow in the open-souce identity provider KeyCloak, and show how to use an OAuth proxy pattern to implement MCP auth on top of Microsoft Entra. Slides for this session Code repository with Container Apps examples: python-mcp-demos Code repository with Functions examples: python-mcp-demosUnlocking AI-Driven Data Access: Azure Database for MySQL Support via the Azure MCP Server
Step into a new era of data-driven intelligence with the fusion of Azure MCP Server and Azure Database for MySQL, where your MySQL data is no longer just stored, but instantly conversational, intelligent and action-ready. By harnessing the open-standard Model Context Protocol (MCP), your AI agents can now query, analyze and automate in natural language, accessing tables, surfacing insights and acting on your MySQL-driven business logic as easily as chatting with a colleague. It’s like giving your data a voice and your applications a brain, all within Azure’s trusted cloud platform. We are excited to announce that we have added support for Azure Database for MySQL in Azure MCP Server. The Azure MCP Server leverages the Model Context Protocol (MCP) to allow AI agents to seamlessly interact with various Azure services to perform context-aware operations such as querying databases and managing cloud resources. Building on this foundation, the Azure MCP Server now offers a set of tools that AI agents and apps can invoke to interact with Azure Database for MySQL - enabling them to list and query databases, retrieve schema details of tables, and access server configurations and parameters. These capabilities are delivered through the same standardized interface used for other Azure services, making it easier to the adopt the MCP standard for leveraging AI to work with your business data and operations across the Azure ecosystem. Before we delve into these new tools and explore how to get started with them, let’s take a moment to refresh our understanding of MCP and the Azure MCP Server - what they are, how they work, and why they matter. MCP architecture and key components The Model Context Protocol (MCP) is an emerging open protocol designed to integrate AI models with external data sources and services in a scalable, standardized, and secure manner. MCP dictates a client-server architecture with four key components: MCP Host, MCP Client, MCP Server and external data sources, services and APIs that provide the data context required to enhance AI models. To explain briefly, an MCP Host (AI apps and agents) includes an MCP client component that connects to one or more MCP Servers. These servers are lightweight programs that securely interface with external data sources, services and APIs and exposes them to MCP clients in the form of standardized capabilities called tools, resources and prompts. Learn more: MCP Documentation What is Azure MCP Server? Azure offers a multitude of cloud services that help developers build robust applications and AI solutions to address business needs. The Azure MCP Server aims to expose these powerful services for agentic usage, allowing AI systems to perform operations that are context-aware of your Azure resources and your business data within them, while ensuring adherence to the Model Context Protocol. It supports a wide range of Azure services and tools including Azure AI Search, Azure Cosmos DB, Azure Storage, Azure Monitor, Azure CLI and Developer CLI extensions. This means that you can empower AI agents, apps and tools to: Explore your Azure resources, such as listing and retrieving details on your Azure subscriptions, resource groups, services, databases, and tables. Search, query and analyze your data and logs. Execute CLI and Azure Developer CLI commands directly, and more! Learn more: Azure MCP Server GitHub Repository Introducing new Azure MCP Server tools to interact with Azure Database for MySQL The Azure MCP Server now includes the following tools that allow AI agents to interact with Azure Database for MySQL and your valuable business data residing in these servers, in accordance with the MCP standard: Tool Description Example Prompts azmcp_mysql_server_list List all MySQL servers in a subscription & resource group "List MySQL servers in resource group 'prod-rg'." "Show MySQL servers in region 'eastus'." azmcp_mysql_server_config_get Retrieve the configuration of a MySQL server "What is the backup retention period for server 'my-mysql-server'?" "Show storage allocation for server 'my-mysql-server'." azmcp_mysql_server_param_get Retrieve a specific parameter of a MySQL server "Is slow_query_log enabled on server my-mysql-server?" "Get innodb_buffer_pool_size for server my-mysql-server." azmcp_mysql_server_param_set Set a specific parameter of a MySQL server to a specific value "Set max_connections to 500 on server my-mysql-server." "Set wait_timeout to 300 on server my-mysql-server." azmcp_mysql_table_list List all tables in a MySQL database "List tables starting with 'tmp_' in database 'appdb'." "How many tables are in database 'analytics'?" azmcp_mysql_table_schema_get Get the schema of a specific table in a MySQL database "Show indexes for table 'transactions' in database 'billing'." "What is the primary key for table 'users' in database 'auth'?" azmcp_mysql_database_query Executes a SELECT query on a MySQL Database. The query must start with SELECT and cannot contain any destructive SQL operations for security reasons. “How many orders were placed in the last 30 days in the salesdb.orders table?” “Show the number of new users signed up in the last week in appdb.users grouped by day.” These interactions are secured using Microsoft Entra authentication, which enables seamless, identity-based access to Azure Database for MySQL - eliminating the need for password storage and enhancing overall security. How are these new tools in the Azure MCP Server different from the standalone MCP Server for Azure Database for MySQL? We have integrated the key capabilities of the Azure Database for MySQL MCP server into the Azure MCP Server, making it easier to connect your agentic apps not only to Azure Database for MySQL but also to other Azure services through one unified and secure interface! How to get started Installing and running the Azure MCP Server is quick and easy! Use GitHub Copilot in Visual Studio Code to gain meaningful insights from your business data in Azure Database for MySQL. Pre-requisites Install Visual Studio Code. Install GitHub Copilot and GitHub Copilot Chat extensions. An Azure Database for MySQL with Microsoft Entra authentication enabled. Ensure that the MCP Server is installed on a system with network connectivity and credentials to connect to Azure Database for MySQL. Installation and Testing Please use this guide for installation: Azure MCP Server Installation Guide Try the following prompts with your Azure Database for MySQL: Azure Database for MySQL tools for Azure MCP Server Try it out and share your feedback! Start using Azure MCP Server with the MySQL tools today and let our cloud services become your AI agent’s most powerful ally. We’re counting on your feedback - every comment, suggestion, or bug-report helps us build better tools together. Stay tuned: more features and capabilities are on the horizon! Feel free to comment below or write to us with your feedback and queries at AskAzureDBforMySQL@service.microsoft.com.607Views3likes0Comments