mcp
70 TopicsSkills over MCP are now available in VS Code
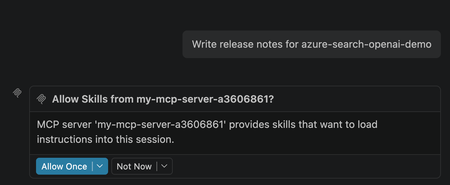
VS Code 1.147+ can now load agent skills straight from an MCP server! If your team runs an MCP server, you can ship skills from the same server as your tools, so every agent reads the same copy and gets updates the moment you deploy. Those skills can help models use your tools optimally and equip agents for the most common workflows. Once agent skills are bundled inside the MCP server itself, the skills can be served with the same auth, access control, and trust model as the tools. One sign-in covers both, and each skill is versioned right alongside the tools it describes. Skills-over-MCP: How it works The MCP standard added support for skills in SEP-2640. Many thanks to the Skills Over MCP Working Group for getting it there! A server advertises that it can serve skills by declaring the extension in its capabilities: { "capabilities": { "resources": {}, "extensions": { "io.modelcontextprotocol/skills": {} } } } A client can then call skills/list to get each skill's name and description, along with a list of the skill's files: { "uri": "skill://pdf-processing/SKILL.md", "frontmatter": { "name": "pdf-processing", "description": "Extract, fill, and assemble PDF documents" }, "resources": [ { "uri": "skill://pdf-processing/SKILL.md", "digest": "sha256:d5e6...", "size": 5120 }, { "uri": "skill://pdf-processing/references/FORMS.md", "digest": "sha256:e6f7...", "size": 18433 } ] } The files themselves are ordinary skill:// resources that the client loads with resources/read as it needs them. So you get the same progressive disclosure you'd get from skills on disk, where the agent only pays for a skill when it uses one. Adding skills to a FastMCP server Adding skills to an existing MCP server is easy, especially if you are using the FastMCP framework for building your MCP servers. In the example code below, we define a new Skill inline, with name, description, instructions, and files, and add that via the SkillCatalogProvider to the MCP server: from fastmcp import FastMCP, Skill from fastmcp.skills.provider import SkillCatalogProvider release_notes = Skill( name="release-notes", description="Write release notes from merged pull requests.", instructions="# Release notes\n\nGroup changes by theme. Follow template.md.\n", files={"template.md": "## Highlights\n\n## Fixes\n"}, ) mcp = FastMCP("Team Skills") mcp.add_provider(SkillCatalogProvider([release_notes])) Learn more ways to add skills to FastMCP servers from their Skills over MCP documentation guide. Using them in VS Code Support for skills-over-MCP varies across MCP clients, as you can see from MCPJam's caniuse.dev compatibility matrix. VS Code is one of the first clients to add support, which makes it great for testing you MCP servers which bundle skills. Verify that your VS Code is version 1.147 or higher, and has chat.agentHost.mcpSkills.enabled: Run your server over HTTP: fastmcp run server.py --transport http --port 8000 Add your server to ~/.copilot/mcp-config.json: { "mcpServers": { "team-skills": { "type": "http", "url": "http://localhost:8000/mcp" "tools": ["*"] } } } Start a new chat and type /. Your server's skills show up as slash commands, right next to the built-in ones. Pick one and VS Code asks before it loads skills from that server. Then the agent follows the skill like any skill on disk, and pulls in template.md when the instructions point to it. Of course, you don't need to explicitly invoke the skill. You can also write a prompt to the Copilot agent that causes it to invoke the bundled skill: VS Code will prompt to ensure you want to allow the MCP server to load the skill instructions into the context, and you can decide whether to allow once or allow always. That prompt gives users more control over the instructions injected into their context windows. Hosting MCP servers A local MCP server works great if it's just for your personal workflows, but if you're like many developers, you're building MCP servers to share inside an organization or even externally for customers. We have great ways for you to host MCP servers on Azure, like Azure Container Apps, Functions, App Service, or Kubernetes. Check our guide on choosing an Azure service for MCP servers. The FastMCP team also makes it easy to deploy servers with their FastMCP Gateway, the quickest way to deploy a FastMCP server from a GitHub repo. For clients that aren't as far along as VS Code, the FastMCP Gateway can also offer your skills as plain tools, so the same URL works there too. They also offer FastMCP Skills Drop, a free page that turns your skills into an MCP server. Start experimenting with skills in your MCP servers today! Give feedback to the VS Code team if you find any issues with invoking the skills, and share your experience in the MCP community on how MCP can better support skills.Enterprise Deployment Architecture for Agentic AI: ChatGPT-Style UI on IIS over Agents & MCP Servers
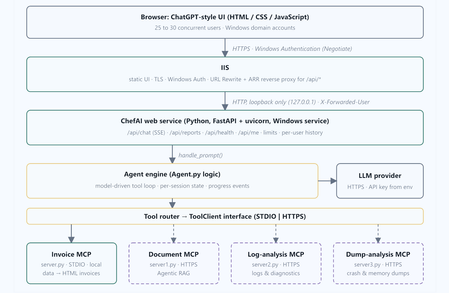
Research Disclaimer: This article is a technical research paper intended solely for educational, research, and illustrative purposes. It reflects the author’s personal technical perspectives. All concepts, architectural designs, diagrams, and implementation approaches are provided “AS IS” for technical exploration and review, not as production-ready development guidance. Organizations considering implementing these approaches should consult their internal software development standards, enterprise architecture teams, corporate security policies, and governance requirements. Any production implementation must undergo appropriate end-to-end architectural, security, privacy, compliance, and responsible AI or ethics reviews, along with necessary testing and organizational approvals before deployment. Abstract. Large language model agents that call tools through the Model Context Protocol (MCP) are usually shown from a console or a developer IDE. Enterprise users expect something different. They want a familiar chat interface, single sign-on and steady behavior when many people use the system at once. This paper gives architectural guidance for a ChatGPT-style web interface, hosted in Microsoft Internet Information Services (IIS) with Windows Authentication, that fronts an MCP-based agent for 25 to 30 concurrent users. The work is broken into nine steps: the engine boundary, state isolation, a streaming API, the chat UI, a Windows service host, IIS reverse-proxy configuration, security, testing and deployment. The paper explains why a long-running Python service behind IIS beats launching Python for every request, and why no Kerberos delegation (the double hop) is needed. It also describes a small transport-neutral tool-client layer, so the same agent can call a local STDIO MCP server and several remote MCP servers over HTTPS without any change to the user interface. The reference scenario is ChefAI, a fictitious restaurant-operations assistant that needs real-time answers, invoice generation, and log and crash-dump analysis for technical troubleshooting. Its STDIO server generates invoices. Three HTTP servers handle document retrieval through an Agentic RAG system, log analysis and dump analysis. The agent logic itself is treated as a black box. The paper closes with a threat model, a capacity argument and an evaluation methodology. Keywords: Model Context Protocol, agent user interface, IIS, Windows Authentication, reverse proxy, Server-Sent Events, agentic RAG, concurrency control, tool routing 1. Introduction Tool-using language model agents have become practical because protocols such as the Model Context Protocol (MCP) standardize how an agent discovers and calls external capabilities [1]. A typical agent loop sends a user request and the list of available tools to a model, receives a tool choice, runs the tool, and feeds the result back until the model can answer. The loop is easy to demonstrate in a terminal. Putting it in front of a team is harder, because the interface, identity, concurrency, streaming and deployment all become real concerns. This paper addresses that gap for a common enterprise setting: Windows infrastructure, an intranet, Active Directory identities and IIS as the standard web host. It is written as a reference architecture. It describes the components, what each one is responsible for, the trust boundaries between them and the order in which to build them. A fictitious reference application, ChefAI (Section 1.2), keeps the discussion concrete. End users reach the application through a browser chat window with their Windows identity, while the agent behind the scenes talks to one local MCP server over STDIO and to several remote MCP servers over HTTPS. 1.1 Contributions A nine-step design for a ChatGPT-style web interface that fronts an MCP agent and is hosted on IIS with Windows Authentication (Sections 4 and 5). A concurrency design sized for 25 to 30 simultaneous users, with explicit queues, per-user limits, timeouts and cleanup (Sections 5.2, 5.5 and 10). A transport-neutral tool-client layer made of an interface, a server registry and a router, which keeps the UI independent of how tools are reached (Section 6). A reference fleet of four MCP servers with different capabilities and data sensitivities, including an Agentic RAG document server, used to reason about routing and security (Section 7). An analysis of identity flow showing that no Kerberos delegation is needed, a threat model and an evaluation methodology (Sections 8 to 10). 1.2 The ChefAI reference application What ChefAI is. ChefAI is a fictitious restaurant-operations application used throughout this paper as the reference scenario. It is an AI assistant for a restaurant business. Staff need real-time answers during service, invoices generated from purchasing data, and help with technical troubleshooting when systems such as point-of-sale terminals, kitchen displays or online-ordering services misbehave. Staff describe what they need in plain language in a browser. The assistant decides which capability to use and answers with figures, documents, diagnostics or a generated report. How it is structured. The application is split into an agent and four MCP servers. Agent.py is the agent. It receives a request, consults a language model and calls tools exposed by MCP servers. The first server, server.py , is a local STDIO server and acts as the invoice generator. It reads purchasing data and produces HTML invoices and reports. The other three servers are remote HTTP(S) servers ( server1.py , server2.py and server3.py ), not STDIO, and the agent calls them to get information and to support technical issues. They are a document processor that answers questions by retrieving data and documents from an Agentic RAG system, a log analyzer and a dump analyzer. Table 0 summarizes the scenario. Capability Example request from staff Served by Transport Real-time spend answers “What did we spend on tomatoes last year?” Invoice server ( server.py ) STDIO, local Invoice generation “Generate the year-to-date invoice.” Invoice server ( server.py ) STDIO, local Knowledge and documents “What is our return policy for dairy deliveries?” “How do we descale the combi oven?” Document processor with Agentic RAG ( server1.py ) HTTPS, remote Log analysis “Why did the point-of-sale terminals time out on Friday evening?” Log analyzer ( server2.py ) HTTPS, remote Dump analysis “The kitchen display crashed. What does this dump show?” Dump analyzer ( server3.py ) HTTPS, remote Table 0. The ChefAI reference scenario: capabilities, the server that provides each, and its transport. The scenario deliberately mixes a business need (spend, invoices, policies) with an operational need (logs, dumps and runbooks). One interface therefore has to route between servers with very different data and risk profiles. The restaurant details, hostnames and example questions are illustrative and do not describe a real business. 1.3 Scope The focus is the user-interface tier and its hosting. The agent internals are out of scope except for the configuration the UI depends on, namely how the agent is invoked and how it reaches tools. The tool names, capacity figures and timeouts in this paper are illustrative design values. They show how to reason about a deployment and should be checked against the real workload (Section 10). 2. Background 2.1 The Model Context Protocol and its transports MCP defines how a client discovers a server’s tools, resources and prompts and calls them using JSON- RPC messages [1]. Two standard transports matter here. STDIO launches the server as a child process and exchanges messages over standard input and output. It is simple and local and needs no network port, but it ties the server’s lifetime to the client process. Streamable HTTP exposes the server at a URL. That allows servers on other machines, shared by several clients and protected by TLS and HTTP authentication. The official SDKs let the same tool code be exposed over either transport, so a server can move from one to the other without rewriting its tools. 2.2 Server-Sent Events for progress Agent requests can last tens of seconds because they chain model calls and tool calls. Server-Sent Events (SSE) let the server push a one-way stream of text events over an ordinary HTTP response [2]. This suits a chat interface that wants to show “queued”, “analyzing logs” and “building invoice” before the final answer. SSE also passes through reverse proxies more easily than WebSockets, as long as buffering is turned off. 2.3 IIS, ARR and Windows Authentication IIS can authenticate users with the Negotiate provider, which uses Kerberos where available and falls back to NTLM [3]. With the URL Rewrite and Application Request Routing (ARR) extensions, IIS can act as a reverse proxy. It forwards selected paths to a back-end service and can copy server variables such as LOGON_USER into request headers [4]. 2.4 The double-hop problem A “double hop” happens when a server has to use the caller’s Windows identity to reach a second server on the caller’s behalf. That requires Kerberos delegation. Section 8 shows why this design avoids it. 3. Requirements and Constraints Category Requirement Interface ChatGPT-style chat in a browser, real-time progress, a stop button, report cards with preview, and no CDN so it works offline on an intranet. Identity Windows Authentication in IIS. The application knows the user’s name and never handles user passwords. Concurrency 25 to 30 simultaneous users without cross-user data leakage, orphaned processes or unbounded resource use. Tools A local STDIO MCP server and several remote HTTPS MCP servers. The UI must not change when servers are added or moved. Security LLM keys never in files, logs or the browser. Loopback-only back end, output escaping, restrictive report serving and allow-listed remote servers. Operations Runs as a Windows service with restart on failure, structured logs and idempotent deployment scripts. Constraints System Python without virtual environments, standard-library HTTP for model calls, IIS as the only public listener and no Kerberos delegation. 4. System Architecture Figure 1 shows the end-to-end architecture. Users reach IIS over HTTPS and authenticate with Windows credentials. IIS serves the static single-page interface and reverse-proxies /api/* over loopback to a Python web service. The service owns the agent engine, which plans with a language model and calls tools through a router. The router reaches the local invoice server over STDIO and the remote servers over HTTPS. Figure 1. End-to-end architecture. Solid boxes and arrows are local components and the local STDIO server. Dashed boxes and arrows are remote MCP servers reached over HTTPS. Adding a server only touches the service and the tool layer. The browser and IIS tiers stay the same. 4.1 Request lifecycle Figure 2 follows a single prompt. The browser posts to /api/chat . IIS authenticates the user, overwrites the identity header and proxies the call. The service queues and admits the request, then streams status events while the engine consults the model and calls tools. The loop repeats, up to a fixed number of tool calls, until the model reports completion or, for report requests, an HTML file exists. The final answer and report links go out as the last events. Figure 2. Request lifecycle for one prompt. Messages 3 and 12 are Server-Sent Events returned through IIS on the original HTTP response. The browser never talks to the engine, the model or any MCP server directly. 4.2 Why a web service sits between the browser and the agent, and why the browser cannot call MCP servers directly The browser cannot call the agent directly, for reasons of feasibility and of fitness. On feasibility, clientside JavaScript can only issue HTTP requests and cannot start or import a Python program. IIS, as a static-file and ASP.NET host, has no in-process Python runtime. An agent is also a script and not a network endpoint, so something has to listen for requests and invoke it. On fitness, an agent request is long-lived, stateful and costly. It chains model and tool calls for tens of seconds, spawns MCP child processes that must be cleaned up on timeout or disconnect, keeps per-conversation state and has to stream progress. It therefore needs a persistent process that can enforce admission control (per-user gates, a bounded queue, semaphores and timeouts), isolate sessions, emit Server-Sent Events and hold the model key and service credentials in a service account, not in the client or the IIS application pool. Launching Python for every request would add seconds of start-up cost and make streaming, cancellation and cleanup fragile. Letting IIS supervise the process, for example through FastCGI or HttpPlatformHandler, changes who restarts it but not the need for it. The browser also cannot call the MCP servers directly. A STDIO server has no network listener at all. A Streamable HTTP server does carry MCP’s JSON-RPC over HTTP, so transport is not the real obstacle. The real obstacle is that an MCP server exposes typed tools and does not understand natural language, so some component must decide which tool to call with which arguments and iterate on the results. That component is the modeldriven agent loop, and it needs the LLM key. Direct access would also place server tokens or client certificates in every browser and expose the sensitive log and dump servers to every desktop. It would bypass central rate limiting, audit, allow-listing and redaction, remove the agent’s defence against prompt injection in tool results, and force the interface to carry discovery, routing and namespacing logic for every server, so adding a server would change the UI. Putting the service in between reduces the browser’s contract to a single HTTP endpoint, /api/chat , and keeps MCP, model credentials and trust decisions on the server side. 5. User-Interface-Centered Design in Nine Steps The design is organized as nine steps (Figure 3). Steps 1 and 2 define the boundary to the agent, Steps 3 and 4 deliver the API and the interface, Steps 5 and 6 host it, Step 7 secures it, Step 8 tests it and Step 9 documents and deploys it. Figure 3. The nine-step roadmap. Amber is the agent boundary, green is the API and interface, grey is hosting, red is security, and purple is verification and delivery. 5.1 Step 1: Define an engine boundary the UI can call An agent is often first written as a console program that mixes the planning loop with prompts and printing. The first step separates them. The agent exposes one asynchronous function, handle_prompt(prompt, history, progress_callback) , that returns {answer, html_files, tool_trace, error} and reports progress through a callback instead of printing. It never reads from or writes to a console. A single prompt box replaces any menu of modes, and the model decides from the live tool list whether the request needs a generated file or only an answer. Recent conversation turns, six by default, are passed as context so that follow-ups such as “now compare it to 2026” work. Only aggregates and provenance go back to the model, and raw rows stay on the server. This boundary is the only contract between the interface tier and the agent. 5.2 Step 2: Remove shared mutable state Agents and tool servers often keep module-level state, such as loaded data and cached query results. With 25 to 30 concurrent users, that state becomes a correctness and privacy hazard. The design therefore does three things. It loads and parses reference data once into an immutable shared dataset, reloaded only when the source file’s size or modification time changes and guarded by a lock. It keeps query results in a per-session store, so each query identifier belongs to exactly one session. And it gives each request an isolated tool connection, or a bounded pool of server processes with per-request session identifiers. Shared outputs are written atomically (a temporary file, then a rename) so a reader never sees a half-written file. 5.3 Step 3: Provide a streaming API The service exposes four endpoints (Table 1). The chat endpoint returns a Server-Sent Event stream. Conversation history is kept per user and conversation with a time-to-live and a cap, and no other user can read it. Endpoint Behavior POST /api/chat Body {prompt, conversation id} . The prompt is validated and capped at 2000 characters. Streams status , tool , result , done and error events (Appendix A). GET /api/reports/{name} Serves generated HTML from one folder only. Filenames are allow-listed and the resolved path must stay inside the folder. Sends a restrictive Content-Security-Policy and nosniff . Reports are scoped per user, plus shared built-in reports. GET /api/health Status, provider, model, data-loaded flag, queue depth and running count. Never keys or paths outside the project. GET /api/me Authenticated display name taken from the trusted header. Table 1. API surface of the web service. 5.4 Step 4: Build the ChatGPT-style interface The interface is plain HTML, CSS and vanilla JavaScript. There is no framework and no CDN, so it works on an isolated intranet and adds no supply-chain exposure. Figure 4 shows the layout. The sidebar lists this browser’s recent conversations from localStorage . The main pane shows user and assistant bubbles, a live status line fed by the event stream, and report cards that open in a new tab or preview in a sandboxed iframe with scripts disabled. The composer grows with its content, sends on Enter, inserts a newline on Shift+Enter, shows a character counter and is disabled while that user has a request running. A Stop button aborts the stream, which in turn cancels the server-side run. Example prompts fill an empty chat. Figure 4. Wireframe of the chat interface. (1) Conversation sidebar, (2) message bubbles, (3) live status line from the event stream, (4) report card with Open and Preview, (5) composer with Send and Stop, (6) data-egress notice. All model and server text is inserted as escaped text. Minimal formatting (line breaks, bold, simple tables) is added by the interface itself and never by interpreting model output as HTML. Errors are visible and actionable. Network loss, 401 and 403, 409 (a request is already running), 429 (system busy, with a retry hint) and timeouts each show a message and a Retry button. Figure 5. Typical event sequence for an invoice request. The browser adds each event to the status line as it arrives and renders the final answer and report cards when the closing done event comes in. 5.5 Step 5: Host the service The Python application runs under a Windows service wrapper (for example NSSM or WinSW), bound to 127.0.0.1 on a fixed port, with automatic restart and a dedicated low-privilege account. It reads the provider name, the model override, the data path and the limits from environment variables, and it reads the LLM key from the service environment only. The account gets read access to the project and data, and write access only to the report output and log folders. Capacity is protected by explicit limits (Figure 6). There is a per-user gate (one running request and a rate limit), a bounded queue that reports “queued, position N” through the stream and returns HTTP 429 when full, a semaphore on concurrent agent runs (default 8) and a separate semaphore on concurrent model calls (default 6). Every request has a wall-clock timeout (default 120 s). On timeout, cancellation or browser disconnect, the request’s child processes are terminated and its slots released, so no orphaned processes remain. Blocking work such as file and network I/O runs off the event loop, so one slow call cannot stall other users. Figure 6. Admission control and cleanup. A request has to pass the per-user gate and the queue before it gets an agent slot, and model calls are throttled separately. 5.6 Step 6: Configure IIS IIS is configured as a thin front end. The site’s application pool uses “No Managed Code” because IIS only serves static files and proxies. URL Rewrite forwards /api/* to the loopback service and, in the same rule, sets an X-Forwarded-User header from the authenticated LOGON_USER value, overwriting anything the client sent. The ARR proxy is enabled with a timeout longer than the engine’s request timeout, and response buffering and dynamic compression are turned off so the event stream is delivered live. Request size is capped, risky file extensions ( .py , .csv , .env , .log , .md ) are denied and an HTTPS binding is required. Windows Authentication is enabled and Anonymous is disabled. Those sections are locked at server level by default, so they are set through appcmd at the application-host scope. Appendix C lists the key settings. 5.7 Step 7: Secure the system Section 8 covers the security controls in detail. In short, identity comes only from IIS and the service accepts connections from loopback only. The model key is read from the service environment and scrubbed from every error and log. All text is escaped in the browser. Reports are served with a restrictive policy from one folder. Tools are read-only against the data and write only to report folders. Users are told that aggregated figures are sent to the external model provider. 5.8 Step 8: Test Tests use a mocked model, so no paid calls are made and results are repeatable (Section 10.1). They cover the API contract, path traversal, cross-user isolation, malformed model output and missing keys. They also run a simulated 30-user mixed workload, check cleanup on timeout and disconnect, scan responses and logs to confirm the key never appears, and exercise the tool router with fake clients. 5.9 Step 9: Document and deploy Two idempotent PowerShell scripts install the service and configure IIS. The README documents installation, service commands, key rotation and troubleshooting. Idempotence matters because configuration drift is a frequent cause of failure in reverse-proxy deployments, and a script that can be safely rerun repairs drift instead of adding to it. 6. The Agent Boundary and a Transport-Neutral Tool Layer The agent is treated as a black box that takes a prompt and history and returns an answer, files and a trace. Only one part of its configuration matters to the interface design, and that is how it reaches tools. A deployment may reach a tool server as a local STDIO child process or as a remote HTTPS endpoint, and may move a server from one to the other. Neither choice should change the browser, IIS or the API contract. Three small abstractions achieve this (Figure 7). ToolClient interface. Three asynchronous operations: list_tools() , which returns name, description and input schema, call_tool(name, arguments) , which returns a result object, and close() . An STDIO client, an in-process fallback and a Streamable HTTP client all implement it. Server registry. A list of entries, each with a name, transport, command or URL, the name of the environment variable holding its credential, a timeout and an enabled flag. A deployment can start with a single entry, such as the local invoice server over STDIO, and grow by loading more entries from a configuration file. Tool router. It combines the tools of every enabled client into one live list for the model and sends each call to the client that owns the tool. Once more than one server is registered, it namespaces tool names ( server__tool ) so collisions cannot happen. A slow or unreachable server is skipped with a status event and does not fail the whole request. Application-specific behavior, such as the data summary sent to the model, query identifiers and the rule that report requests must produce an HTML file, lives in an adapter and not in the generic loop. That way, servers that know nothing about invoices can still be used. Figure 7. The transport-neutral tool layer. A remote server is added with a registry entry. One HTTP client implementation serves all remote servers, and no code above the router changes. 6.1 Registry example The following shows the shape of the registry for the four ChefAI servers. Credentials are referenced by environment-variable name, and the secrets themselves never appear in the file. Here docs , logs and dumps correspond to server1.py , server2.py and server3.py . With several servers registered, the model sees namespaced tools such as invoices__generate_invoice or logs__search_logs . Each extra server makes the tool list sent with every model call longer, so a practical deployment should filter or pre-route the list by request intent. Section 11 returns to this. 7. The ChefAI MCP Server Fleet The ChefAI scenario (Section 1.2) uses four servers with deliberately different capabilities (Table 2). Tool names are illustrative, and an implementation may name and group tools differently. Server Transport Capability and example tools Data sensitivity Operational notes Invoice generator server.py STDIO, local Queries purchasing data by period, item and vendor, and generates HTML invoices and reports with totals computed in code. Tools: query expenses ,generate invoice ,generate report , chef summary . Business- confidential totals and vendor names. One child process per request. Read- only on data, writes only to report folders. Document processor (Agentic RAG) server1.py HTTPS, remote Answers questions by retrieving data and documents (supplier contracts, return policies, menus, allergen sheets, equipment manuals, runbooks) from an Agentic RAG system and returning an answer with citations. Tools: search documents , get document, answer with citations . Mixed. Some documents are confidential (contracts, pricing), so it needs document-level access control. Read-only. Always returns source references. Has a retrieval budget and timeout, and shows index freshness. Log analyzer server2.py HTTPS, remote Searches and summarizes application and device logs from point-of-sale, kitchen-display and ordering systems: error counts by time bucket, top messages, correlation by request id. Tools: search logs ,summarize errors ,time histogram . May contain user identifiers, IP addresses or secrets, so it needs redaction. Read-only. Limits result size and redacts on the server side. Dump analyzer server3.py HTTPS, remote Triages crash or memory dumps from restaurant systems:exception summary, faulting module, thread stacks. Tools: list dumps , analyze dump , stack summary. Dumps can contain memory contents,including credentials. The most sensitive server. Long-running, so it needs a larger timeout. Strict access control. Returns summaries only, never raw dumps, to the model. Table 2. The four MCP servers in the ChefAI scenario. 7.1 Agentic RAG in the document processor Retrieval-augmented generation (RAG) grounds a model’s answer in retrieved documents instead of the model’s own memory. An agentic RAG system goes further. It plans the retrieval, may rewrite the query, searches several collections, reads the most promising documents, checks whether the evidence is enough and iterates before answering. In ChefAI this behavior lives inside the document server, behind a small tool surface. The main agent sees one tool, such as answer_with_citations , and does not need to know how the retrieval works. This has three consequences for the design. The document server must return citations so the interface can show sources. Its latency is usually higher than a simple lookup and is bounded by its own timeout and retrieval budget. And retrieved text is untrusted input that can carry injected instructions (threat T2 in Section 8). 7.2 Cross-server tasks The value of a multi-server fleet is that the servers can work together. Take a request such as “The kitchen display froze during Friday dinner service. What happened and what should we do?” It could need the log analyzer for an error histogram around the incident, the dump analyzer for the crash cause and the document processor for the vendor’s runbook and escalation policy. A request such as “Generate the year-to-date invoice and check our dairy return policy” combines the invoice generator with the document processor. The router makes these tools look like one catalogue. Per-server timeouts and failure isolation mean that if the dump server is down, the other tools still answer. Combining servers also raises a data-flow question, because results from one server become inputs to another through the model. Every result passes through the engine, so the engine is the right place to apply size limits, redaction rules and per-server allow-lists. 8. Windows Authentication, Trust Boundaries and Threats 8.1 Identity flow and the absence of a double hop The browser authenticates to IIS using Negotiate (Kerberos or NTLM). IIS knows the user’s account, copies it into X-Forwarded-User and forwards the request over loopback. From that point the application uses only the name, for scoping history, report access, rate limits and logs. The user’s Windows token is never impersonated or forwarded. Resources are reached with service-level credentials: the data file with the service account, the model with an API key, and remote MCP servers with a bearer token or client certificate (Figure 8). No downstream system needs to act as the user, so Kerberos constrained delegation is unnecessary. Figure 8. Identity and credential flow. The user identity is used only for scoping, and every downstream resource is reached with a service-level credential. When delegation would be needed. Delegation, or token forwarding, becomes necessary only if a downstream system must authorize the end user itself. Examples are a per-user permissioned file share, a SQL Server using Windows authentication as the user, or a remote MCP server (such as the document processor) that must apply the caller’s own document entitlements. Those cases would need Kerberos constrained delegation or an OAuthstyle token exchange, and they are outside this design. 8.2 Trust boundaries Figure 9 marks four zones and the threats that cross them. The key rule is that the Python service trusts the identity header only because it listens on loopback and IIS overwrites the header on every proxied request. Figure 9. Trust zones and threat markers T1 to T6 (Table 3). Arrows show the direction of requests. ID Threat Mitigation in this design T1 Spoofed identity header or direct access to the service port IIS overwrites the header on every proxied request. The service binds to 127.0.0.1 and rejects non-loopback callers, and the port is not opened in the firewall. T2 Prompt injection through tool results, retrieved documents or logs (for example text that says “ignore your instructions”) Tool results and retrieved text are treated as untrusted data. Tools are read- only. Tool calls are allow-listed and capped, arguments are validated against schemas, and results are size-limited and redacted before they reach the model. T3 Pointing the agent at arbitrary URLs (server-side request forgery) Remote servers come only from the registry. HTTPS is required, hosts are allow-listed and the model cannot supply URLs. T4 Sensitive data leaving the network through the model provider Only aggregates, provenance and short cited excerpts are sent, never raw rows. Log and dump summaries are redacted. The UI shows a notice and the provider is chosen by policy. T5 Cross-user leakage (history, query results, reports, documents) Per-session stores keyed by user and conversation. Query identifiers are owned by one session, reports are scoped, and the retrieval system applies document-level access control. Tests try cross-access on purpose. T6 Path traversal or exposure of secrets in files served by IIS or the service Report filenames are allow-listed and the resolved path is checked. IIS denies .py , .csv , .env , .log and .md . Keys live only in the service environment and are scrubbed from errors and logs. Table 3. Threat model. The model key is stored in the service’s environment, which administrators can read from the registry. Sites that need stronger protection should use a machine-level secret store read at start-up. 9. IIS Hosting and Deployment Figure 10 shows the physical deployment. Only port 443 is exposed to clients. The Python service listens on loopback and needs no inbound firewall rule. Outbound traffic is limited to the model provider and the approved remote MCP hosts. Figure 10. Deployment topology and firewall posture. 9.1 Provisioning sequence Install IIS with static content, request filtering and Windows Authentication. Install URL Rewrite and ARR. Enable the ARR proxy, set its timeout above the engine timeout, set the response buffer limit to zero and allow the HTTP_X_FORWARDED_USER server variable. Create the application pool (No Managed Code) and the site pointing at the UI folder, then add the HTTPS binding with an internal CA or test certificate. Disable Anonymous and enable Windows Authentication at the application-host scope. Add the rewrite rule, request limits, security headers and file-type deny list to the site configuration. Create the service account, grant the narrowest file permissions, install the service wrapper, set the environment variables and start the service. Verify the result: the service is running, the health endpoint answers on loopback, sign-in from a client is silent, a streamed answer arrives, a report card appears, access to data and source files is blocked, and two simultaneous users get independent results. 9.2 Common failure modes Symptom Typical cause 502.3 on /api Service stopped, wrong port, or ARR proxy not enabled. 500.50 from URL Rewrite The identity server variable is not in the allowed list. Repeated sign-in prompts Authentication sections not set at application-host scope, browser zone settings, or a missing service principal name for the site name. Progress arrives only at the end Response buffering or dynamic compression on the proxied route. Timeouts near two minutes Proxy timeout shorter than the engine timeout. Leftover Python processes Cleanup path not triggered on timeout or disconnect. 10. Evaluation Methodology and Capacity Reasoning 10.1 Evaluation plan An implementation of this architecture should be evaluated against the criteria in Table 4 before it is released to users. A mocked model keeps functional tests repeatable and free of provider cost. Latency and quality are then measured with the real provider. Question Method Metric or pass criterion Correctness of the API Mocked model, test client and deterministic scenarios. All contract and error-path tests pass, and totals equal direct data queries. Isolation 30 simulated users with mixed queries and reports, plus deliberate cross-access attempts. Zero cross-user data, zero unhandled exceptions and zero orphaned processes. Concurrency limits Ramp from 1 to 30 users, saturate agent slots and fill the queue. Running agents never exceed the configured cap, overflow returns 429, and the system recovers after the burst. Real-time responsiveness Mocked model with a fixed delay, then the real provider, with a browser trace through IIS. Median and 95th-percentile end-to-end time, time to first event, first event before the first tool completes, and no buffering. Cleanup Timeout and abrupt disconnect tests. Child processes terminated, slots released and no handle growth after repeated runs. Secret hygiene Automated scan of responses, logs and error text. The key never appears. Router Two to four fake clients, one slow and one failing. Correct routing and namespacing, and the request still succeeds when one client fails. Retrieval quality (document server) A question set with known source documents. Share of answers with correct citations, and refusal when evidence is missing. Table 4. Recommended evaluation plan. 10.2 A capacity argument Little’s law relates the average number of requests in service N to the arrival rate λ and the average time in the system W: N = λ × W [7]. Suppose, as an assumption, that each of 30 users submits one request per minute on average (λ = 0.5 requests per second). If the mean service time is 15 s, then on average N = 7.5 requests are in service at once. That fits the default of eight agent slots with little queueing. If the mean time is 30 s, then N = 15, the slots saturate and queueing delay grows, so either the cap or the speed of each run has to change. The model call is the biggest part of a run, and an Agentic RAG lookup adds its own multi-step latency. Provider latency and the number of tool calls per request therefore set the capacity you need. These figures illustrate the method, and each deployment should substitute its own measured arrival rate and service time. Memory per STDIO child process also grows with N, so it must be measured before choosing between one child per request and a pool. 11. Limitations and Future Work Reference architecture. ChefAI is a fictitious scenario and the figures in this paper are design values, not benchmark results. Capacity, latency and memory must be measured for each real deployment. Single-process assumption. Per-user limits, history and the shared data cache live in memory. Scaling to several worker processes needs a shared store, such as a database or cache, or sticky routing. Tool-list growth. More servers mean larger prompts and more mistakes in tool selection. Pre- routing by intent, per-user tool entitlements and lazy tool loading are natural extensions. Per-user authorization downstream. The design uses service credentials. If remote servers, notably the document processor, must enforce each user’s own rights, token exchange or delegation will be required. Model-provider dependence. Answers depend on an external provider’s availability, cost and data policy. An on-premises model would change the data-egress analysis. Human factors. The paper does not prescribe a usability study. Candidate measures include task completion, perceived trust in numbers and citations, and how clear the status line is. Secret storage. A service environment variable is fine for a pilot. A managed secret store is better for production. 12. Conclusion Putting an MCP agent behind a familiar chat interface is mostly an engineering problem at the edges. The questions are how the request enters, who the user is, how long-running work is streamed, how concurrent users are kept apart and how new tool servers are added without disturbing the rest. The architecture in this paper keeps IIS thin, with static content, TLS, Windows Authentication and a reverse proxy. It puts the agent behind a loopback Python service with explicit admission control, and it separates the interface from the way tools are reached by using a small transport-neutral tool layer. User identity is used only for scoping and every downstream resource is reached with a service credential, so no Kerberos delegation is needed. For the fictitious ChefAI restaurant, this gives staff real-time answers, invoices, document-grounded guidance and log and dump diagnostics from one chat window. The recommended path is to build the nine steps in order, validate the result with the evaluation plan, and add remote MCP servers one at a time through registry entries. References Model Context Protocol. “Model Context Protocol specification.” modelcontextprotocol.io (accessed October 2026). WHATWG. “HTML Living Standard: Server-sent events.” html.spec.whatwg.org (accessed October 2026). Jaganathan, K., Zhu, L., and Brezak, J. “SPNEGO-based Kerberos and NTLM HTTP Authentication in Microsoft Windows,” RFC 4559, IETF, June 2006. Microsoft. “URL Rewrite” and “Application Request Routing” documentation for IIS, learn.microsoft.com and iis.net (accessed October 2026). Fielding, R., Nottingham, M., and Reschke, J. “HTTP Semantics,” RFC 9110, IETF, 2022. OWASP Foundation. “OWASP Top 10 for Large Language Model Applications.” owasp.org (accessed October 2026). Little, J. D. C. “A Proof for the Queuing Formula: L = λW.” Operations Research 9(3), 1961. Appendix A. Event stream schema Each SSE message has an event name and a JSON data field. The schema is the only contract between the browser and the engine. Appendix B. Environment variables Variable Purpose LLM_PROVIDER, LLM_MODEL Model provider and optional model override. LLM_API_KEY Provider key. Service environment only, never logged or returned. CHEFAI_CSV_PATH Location of the purchasing data file used by the invoice server. CHEFAI_REQUIRE_USER 1 rejects requests without the identity header (production). 0 uses a single anonymous user (development). CHEFAI_MAX_AGENTS Concurrent agent runs (default 8). CHEFAI_REQUEST_TIMEOUT Per-request wall-clock limit in seconds (default 120). MCP_*_TOKEN Per-server credentials for remote MCP servers, referenced by name in the registry. Appendix C. Key IIS settings These settings are indicative. Module versions and server policies vary, so validate them in a non-production environment before rolling out.695Views3likes0Comments
Web IQ: Web Search and Grounding APIs for AI Agents
Web IQ gives AI agents current, citable evidence from across the web. We explain what it is, how its four layers (Bing's web substrate, Harrier embeddings, DiskANN, and structured evidence) work together, and how it pairs with Microsoft IQ to ground agents in web and enterprise context.When AI Starts Taking Action: Building Execution Boundaries with OpenSandbox and AKS
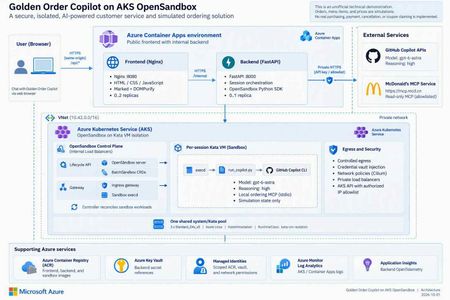
1. An agent needs more than a smarter model Imagine you are building a food-ordering assistant. In its first version, it says, “You might enjoy a burger and fries.” That is primarily a content-generation problem. In the next version, it queries coupons, reads a menu, calculates prices, creates files, and calls a local program to create an order. The engineering problem has changed. You are no longer asking a model to speak. You are allowing software to act on someone's behalf. This is a distinction I emphasize in technical talks: model capability determines what the agent can propose; the execution platform determines where, with which permissions, and for how long those proposals can become actions. Running every agent's tool processes inside the business API container creates awkward coupling. Leftover files, stuck processes, dependency changes, or excessive resource consumption from one session can affect another. Even if customers cannot invoke an arbitrary shell, CLI processes, tool dependencies, and temporary state still need boundaries. A sandbox is therefore not an instruction that says “please be safe.” It is a working environment with a lifecycle, a resource budget, and an access policy. Figure 1. A tool protocol, a working environment, and runtime isolation solve different problems. 2. Separate three concepts that often get conflated MCP describes tool interaction; it does not put tools inside a VM The Model Context Protocol gives model-facing applications a consistent way to discover and invoke tools. But “called through MCP” does not automatically mean “executed within a security boundary.” An MCP server can run on a developer's laptop, in a business-service container, remotely, or in a dedicated sandbox. Whether a tool can write data, who may invoke it, and how its side effects can be reversed are separate design questions. OpenSandbox makes the working environment an application resource OpenSandbox is an open-source platform for agent execution environments. It exposes sandbox lifecycle, command execution, file operations, and network-access capabilities. Applications use SDKs and APIs to create environments, run work, retrieve results, and clean up. Docker supports a local starting point; Kubernetes provides a cluster deployment path.1 Think of it as a workspace management system: it allocates a room, delivers materials, exposes ways to work, and reclaims the room at the end of its lease. The strength of the walls depends on the runtime and deployment underneath. OpenSandbox is not a language model, not a replacement for Kubernetes, and not synonymous with Kata. The upstream project also provides pools, multiple runtime paths, and snapshot-related capabilities. Availability, state semantics, and infrastructure requirements must be checked against the selected version and runtime. A project-wide feature list is not a promise that every backend behaves identically.1, 5 Kata adds a separate guest kernel to the sandbox pod Conventional containers generally share the host kernel. Kata Containers runs workloads in lightweight virtual machines, adding a VM boundary. With AKS Pod Sandboxing, the isolation unit is the pod using the Kata runtime, with its own guest kernel.2, 3 That does not mean every container in the same pod gets its own VM. Nor does a VM replace application authentication, outbound restrictions, or business approvals. The useful summary is: MCP defines the tool interface. OpenSandbox manages the working environment. Kata provides runtime isolation. The application still owns authorization and business rules. 3. What does “per-session Kata VM” actually isolate? In this project, a session is identified by session_id. The backend creates an OpenSandbox sandbox for a new session, and its pod selects the Kata RuntimeClass. Later requests in the same session reuse that environment. Several distinctions matter: It is not a new VM for every message. Related turns can reuse files and temporary state produced by the tools. It is not an Azure VM purchased for every user. Kata pod VMs run on AKS nodes; multiple sandboxes can share a node's underlying compute resources. It is not one sandbox per node. Capacity depends on resource settings, VM overhead, system components, and concurrent work. A session ID is not authorization. It identifies routing and resource mappings; production services must validate session ownership. My favorite analogy is a campus: AKS is the campus, nodes are buildings, Kata sandboxes are workrooms, and OpenSandbox is the workspace management system. A session repeatedly uses the same room; a lifecycle policy eventually clears it. That final step matters. Files surviving between turns does not mean they survive sandbox deletion. Orders, code artifacts, or audit records that must outlive the environment need explicit, governed persistence. Figure 2. This project hosts its frontend and backend in regular ACA, and OpenSandbox/Kata on AKS. Model inference is called through an external API, not hosted on the AKS nodes. 4. OpenSandbox on AKS: installation is not the finish line Kubernetes supplies scheduling and declarative resource management. OpenSandbox turns that infrastructure into sandbox operations that an application can consume. The execution path in this project is: The FastAPI backend requests a sandbox through the OpenSandbox SDK. The lifecycle service creates a BatchSandbox resource. The controller reconciles that declaration into a sandbox pod. The pod starts with the Kata runtime. The SDK accesses execd through the gateway for command and file operations. Deletion or expiration reclaims the sandbox. The upstream Kubernetes operator also supports pool allocation. However, warming an image in this sample is not the same as maintaining a ready-to-allocate pool of sandbox instances. Cached image layers and ready idle sandboxes are different latency optimizations.5 4.1 Declare the runtime, then verify the running boundary The important part of the project's BatchSandbox pod template is: spec: runtimeClassName: kata-vm-isolation nodeSelector: kubernetes.azure.com/kata-vm-isolation: "true" securityContext: seccompProfile: type: RuntimeDefault This is a fragment of the pod template, not a complete manifest that works independently of cluster prerequisites. The deployed example uses one shared system/Kata pool: three Standard_D4s_v5 Azure Linux nodes with KataVmIsolation, created through AKS API 2026-07-01. The model is gpt-6-astra accessed through GitHub Copilot APIs; this is not a GPU model-serving deployment. To avoid confusing “Kata appears in the configuration” with “the boundary is working,” deployment checks inspect the actual pool properties, three Ready nodes, the RuntimeClass, and the guest kernel inside a temporary Kata pod. The kernel check is a deployment acceptance signal, not a formal proof of the entire system's security. 4.2 More platform control also means more platform ownership OpenSandbox on AKS gives a team control over its runtime, images, network layout, and application integration. It also leaves the team responsible for node capacity, image provenance, control-plane upgrades, resource budgets, observability, recovery, and removal of temporary installation privileges. For simplicity, this demonstration uses a shared system/Kata pool. Three nodes are not presented as a high-availability guarantee. A production design should reconsider dedicated system and workload pools, zones, quotas, and tenant separation rather than copy the demonstration's footprint. 4.3 Credentials should be usable without being casually readable Credential Vault is especially interesting here. The trusted backend supplies credentials and bindings to OpenSandbox's egress sidecar. The Copilot workload process receives placeholders; the proxy injects authentication into matching outbound HTTPS requests.4 Precision matters: this reduces the workload's direct access to long-lived credentials; it does not make credentials disappear from the system. The backend and egress sidecar remain in the trusted computing base. It would be inaccurate to claim that real credentials can never exist anywhere within the pod VM. Preventing a model from reading a token also does not prevent misuse of operations authorized by that token. This project still restricts remote tools to read-only operations and uses exact hostname bindings for credential injection. Production systems should further scope operations, paths, tenants, and data. The upstream guide also explains that Kubernetes pause/resume can recreate the sidecar, requiring a trusted client to repopulate its in-memory vault.4 That distinction is valuable: restoring compute state, restoring identity context, and restoring business permissions are different operations. 5. Before comparing ACA Sandbox, stop treating it as another name for Dynamic Sessions Azure Container Apps includes several compute models: Model Primary concern Regular Container Apps Web apps, APIs, continuous services, and replica scaling Jobs Tasks that start, run, and complete Dynamic Sessions Isolated execution through a session pool and identifier Sandboxes Explicit lifecycle, state, and policy control over individual environments The current official overview describes ACA Sandboxes as a distinct resource model. A Microsoft.App/SandboxGroups resource is the management boundary for sandboxes, disk images, snapshots, volumes, and related resources. Documented capabilities include suspend/resume, memory and disk state, ports, egress policies, and Azure Blob/Data Disk volumes.6 Integration has its own control-plane contract: ARM manages sandbox groups, while the Sandboxes data plane manages individual instances, files, and related resources. The documentation requires a Microsoft Entra ID identity and the Container Apps SandboxGroup Data Owner role for sandbox management, assigned at an appropriate scope rather than granting broad access by default. These platform access requirements still do not replace your application's end-user authentication and authorization.6 Dynamic Sessions centers on Session Pool + identifier. A pool allocates a session, routes related requests to it, and reclaims it according to lifecycle and cooldown settings. Context can survive while that session exists; calling it “completely stateless per request” would be misleading. But it is not the same abstraction as a workspace with explicit snapshot and volume management.7, 8 There is also a release-status caveat. At the time of review, Microsoft Learn described these Sandboxes capabilities, while Microsoft's earlier repository documentation still carried an Early Access label and warned that early resources might need recreation.9 This article does not infer universal GA or regional access, nor does it treat the older “SDK coming soon” wording as current. Verify access, SDKs, RBAC, networking options, and service terms before adoption. Figure 3. This is an ownership comparison, not a security rating or performance ranking. 5.1 A comparison that helps make a decision Dimension OpenSandbox on AKS: this project's path ACA Sandboxes ACA Dynamic Sessions Main object OpenSandbox sandbox and Kubernetes workload Sandbox group and individual sandbox Session pool and identifier Platform operations Team operates OpenSandbox and configures AKS workloads/nodes; Azure still manages the AKS control plane Azure manages underlying infrastructure; the app explicitly manages sandbox lifecycle Azure manages pool allocation and session lifecycle Isolation This project explicitly selects Kata pod VMs Documented independent security boundary; this article does not infer a particular open-source runtime Officially documented Hyper-V isolation State Temporary per-session state here; upstream persistence/snapshot paths need separate configuration and validation Explicit suspend, resume, snapshots, and volumes Context while a session exists; treat state as ephemeral after reclamation Images and tools Custom images, CLI, MCP, and runtime policy OCI images converted to root filesystems; validate workload compatibility Built-in interpreters or custom container pools Network and credentials Team combines private networking, egress policy, Vault, and app authorization Service identity/network/policy capabilities; do not assume equivalence to OpenSandbox Vault Pool access and network controls; app owns identity and tool authorization Startup experience Depends on cache, scheduling, runtime, and initialization; no instant-start guarantee in this sample Documentation describes prewarmed subsecond startup/restore; measure your own workload Documentation describes low-latency prewarmed allocation; distinguish spare pool capacity from cold starts Team fit Kubernetes expertise and a need for deeper runtime control Managed infrastructure with explicit workspace state control Managed execution sessions without managing every environment's full lifecycle The ACA entries describe documented capabilities, not measurements from this project.6, 7, 8 A shared OCI image format does not make SDKs and APIs interchangeable. The existing backend depends on OpenSandbox creation, command-log, health, credential-proxy, and deletion semantics. Moving it to ACA Sandboxes requires mapping and testing those contracts, not changing an endpoint URL. Cost is also more than a price per hour. A useful measure is total cost per successfully completed task: execution resources, warm capacity, state storage, images, networking, logs, model usage, and operational effort. ACA documentation says stopped sandboxes incur no CPU/memory fees; that does not zero the bill for the application, storage, or dependencies. Deleting an AKS sandbox does not eliminate fixed node costs either.6 6. How I would choose for different scenarios Scenario A: upload a CSV and ask AI to run a short analysis If work is brief, the built-in runtime is sufficient, and state can be discarded afterward, I would evaluate Dynamic Sessions first to reduce platform work. Generated code remains untrusted input, and downloadable outputs still need content and authorization checks. Scenario B: a coding agent that works across turns and time This agent may need dependencies, a source tree, and process state. A user leaves, the environment pauses, and work continues later. ACA Sandboxes' explicit lifecycle is a compelling capability to validate. The design must still decide what may enter a snapshot, how credentials are reauthorized after restore, and how deletion policies meet business obligations. Scenario C: an enterprise with an established AKS platform If a team needs existing Kubernetes governance, runtime control, custom toolchains, or a platform built around a unified sandbox API, OpenSandbox on AKS is attractive. Its benefit is control and composability, not the assumption that open source removes operating costs. Scenario D: the agent only calls a governed business API If there is no generated-code execution, local tool process, or temporary filesystem requirement, a sandbox per user may be unnecessary. A regular ACA API with authentication, server-side permissions, and a well-defined tool gateway can be simpler. Not every agent needs a sandbox platform. These choices are not mutually exclusive. Our project uses regular ACA for the lightweight web/API layer and AKS for the execution plane. Different task classes could eventually use different execution backends, provided identity, lifecycle, results, and error contracts are explicit. 7. The concrete example: an ordering assistant that does not place real orders Project: kinfey/aks_opensbx_ghc_demo. This is an unofficial McDonald's-themed technical demonstration, not an official service or a real transaction system. Its value is not that AI can recommend a burger. It places several boundaries in an understandable business story: Application boundary: a public Nginx frontend and an internal FastAPI backend. Execution boundary: per-session OpenSandbox/Kata running Copilot CLI and local MCP. Operation boundary: selected read-only remote queries; order creation exists only in local simulation tools. Credential boundary: placeholders in the CLI workload, with authentication injected for allowed requests by a trusted egress proxy. Presentation boundary: original Markdown preserved in transit and sanitized before browser rendering. Figure 4. Querying external information and writing a simulated order are different paths, even when they appear in the same conversation. 7.1 What should a reasonable interaction look like? The following is an illustrative workflow, not an invented transcript of a live customer: A user asks, “Check current offers, then calculate a simulated meal.” The backend creates or reuses the session sandbox. Copilot invokes a read-only remote MCP tool for official offers rather than inventing them. Local get_menu and calculate_order tools price the simulation, clearly distinguished from official quotes. The assistant displays items and the total and asks for confirmation. Only after confirmation does it call local create_order, producing an explicitly simulated order. Session completion or the idle policy triggers sandbox cleanup; the order file is not retained as a durable business record. The tool rejects confirmed=false. Its limit should also be clear in any technical presentation: an agent-supplied boolean is not an independently authenticated, auditable purchase-approval system. Real commerce would require server-verifiable authorization bound to a user and the exact order contents. The current backend keeps session mappings in memory, runs at most one replica, and does not provide public user login or authenticated session ownership. These are demonstration constraints, not a production multitenancy template.10 7.2 Three lessons from making it work First: startup latency is not one number. An initial pull of the roughly 2.8 GB sandbox image took almost six minutes. That delay was not slow model inference, and it could not simply be attributed to feature approval. We moved image warmup outside the user request path and waited for actual execd health. End-to-end latency = queue/scheduling + image pull + guest startup + certificate/proxy setup + CLI startup + model/tool execution + result transport and rendering This is why a documented subsecond allocation from warm capacity should not be compared directly with one cold image pull in this project. A meaningful evaluation controls the image, cache state, concurrency, region, and measurement boundary, then tracks percentiles, failure rates, and cost per successful task. Second: a working isolation boundary does not guarantee a working data contract. We encountered a deceptively simple issue: the web renderer supported Markdown, but real replies still had no proper tables. CSS was not the problem: Copilot's default terminal output had already converted Markdown tables into character borders. Execd's line-oriented logging removed the terminators from nonempty lines. The fix extracted original assistant content from CLI JSONL, encoded it in a single-line JSON envelope across command logs, and decoded it back into Markdown in the backend. Marked and DOMPurify then preserved tables, headings, and code without inserting arbitrary model-generated HTML directly into the page. Third: acceptance must cover the real path. A browser test with a fixed reply proves that the renderer works, not that model output survives the CLI, logs, and API. The project added a live-model test that checks raw Markdown, actual DOM tables, mobile layout, and confirmed sandbox deletion.11 Similarly, successful remote tool use should be established from tool-execution events, not merely from the model saying “I checked.” The broader engineering rule is the same: prove completion with structured results and actual side effects, not a success-shaped sentence. 8. What I would add before calling this production I would not start by adding more tools. I would answer five questions: Question Required design Who owns the session? Authentication, tenant binding, server-side session ownership, and resource authorization Which state deserves to survive? Separate temporary workspace files, durable artifacts, business orders, and audit records Who may cause side effects? User approval bound to contents, idempotency, and auditable authorization beyond model instructions Where can the system fail? Stage-level startup metrics, admission control, budgets, timeouts, retries, and resource reclamation Can the execution backend change? Contract tests for create, execute, files, credentials, state restoration, and deletion For the last question, ACA Sandboxes is a worthwhile alternative backend to evaluate. But it should be a measured migration experiment with a deliberate identity design, not an untested promise of a seamless swap. Closing thought: an agent platform puts capability inside boundaries OpenSandbox gives applications an abstraction for working environments. AKS and Kata let a team implement that abstraction on observable, configurable infrastructure. ACA Sandboxes and Dynamic Sessions offer managed alternatives with different levels of operational ownership. I prefer to rewrite the selection question as three questions: What do we need to control? What are we willing to operate? How will we prove that execution completed as intended? Those questions are more useful than a simple “self-hosted versus serverless” debate. A reliable AI application needs both a capable model and a workspace with clear boundaries, a reclaimable lifecycle, and an auditable record of what happened. Further reading and scope Full deployment instructions: English README. Runnable source: project repository. The four diagram sets are original technical illustrations. imgs/ contains Chinese and English PNGs, scalable SVGs, and matching editable .excalidraw files. They are not benchmarks or product certifications. Resource descriptions are generic. Supply your own AZURE_RESOURCE_GROUP, AKS_NAME, and other configuration when reproducing the deployment. Sources OpenSandbox: scope, SDKs, runtimes, and examples Kata Containers: lightweight VM isolation OpenSandbox Credential Vault: broker and restore semantics, pinned revision OpenSandbox Kubernetes operator: BatchSandbox, Pool, snapshots, pinned revision Azure Container Apps Sandboxes overview Azure Container Apps Dynamic Sessions overview Official comparison of Dynamic Sessions and Sandboxes Microsoft's earlier ACA Sandboxes Early Access documentation This project: session management and runtime boundaries This project: real-reply end-to-end browser test565Views0likes0Comments
MCP Integration for OneDrive/SharePoint
Hi OneDrive Team, I'm reaching out to explore Model Context Protocol (MCP) server integration for OneDrive and SharePoint. I am looking to integrate OneDrive/SharePoint data access into ThoughtSpot application using MCP solution. Are there existing MCP server implementations (official or community-driven) for OneDrive/SharePoint? If available, what are the connection endpoints and authentication details needed to set up the MCP server? If no MCP server currently exists, are there any upcoming plan on this and is there any alternate recommended approach present. Also could you please provide a SPOC from your team who can support further discussions and technical guidance on this integration? I'd like to schedule a follow-up conversation to explore the best path forward and discuss the use case. Thanks in advance for your help.288Views0likes0CommentsEngineering Agentic Recall Controls with MCP and Microsoft Foundry
AI agents become operationally interesting when they can reach real systems. They also become operationally dangerous at exactly the same moment. Caldova Recall Control Tower is a developer demonstration built around that tension. It uses a fictional pharmaceutical recall to show how an agent can gather evidence and prepare a decision while deterministic application code retains authority over approval and inventory mutation. The implementation combines the Model Context Protocol (MCP), Microsoft Agent Framework, a Microsoft Foundry Hosted Agent, FastAPI, Microsoft Entra authentication, managed identity, and optimistic concurrency in Azure Blob Storage. Central design rule: Let the model interpret and recommend. Make ordinary code authenticate, authorize, mutate, and prove what happened. Caldova is fictional, all operational data is synthetic, and this sample is not a production recall system or a source of clinical advice. The scenario: useful reasoning, consequential action The demo starts with a temperature excursion affecting batch B-2408-AX7 of Caldova Relief 20 mg tablets. The synthetic inventory contains 2,196 units across two distribution centers and two retail stores. A useful system must establish the notice, locate every affected position, check supplier status, explain uncertainty, and recommend an action. That analysis is a good fit for specialized agents. Quarantining inventory is not. Quarantine changes operational state. It therefore needs an authenticated human, explicit authorization, a batch-scoped approval, concurrency control, idempotency, and an audit record. None of those guarantees should depend on a prompt being followed. The authenticated hosted application at the start of the fictional recall. Architecture: separate reasoning from authority The solution has two related but deliberately separate paths. Caldova separates model reasoning from application authority. Official Microsoft service icons identify Foundry Agent Service, App Service, Managed Identity, and Blob Storage. The reasoning path invokes a Hosted Agent through the Responses protocol. Four agents run in a fixed sequence: triage, inventory impact, supplier/compliance, and supervisor. The first three have narrow read-only tools. The supervisor has no tools and synthesizes the accumulated context into a decision brief. The authority path remains in the web application. It validates the EasyAuth identity claims, checks an approver allowlist, binds approval to the caller, batch, action, and current demo generation, and only then calls deterministic domain code. State is stored per actor in Blob Storage and updated with ETag match conditions so concurrent writes fail instead of silently overwriting each other. There is also a deterministic localhost demo. It reuses synthetic domain fixtures and demonstrates MCP contracts, approval, quarantine, and replay without a model or cloud account. It is useful for development, but its typed approver name and in-memory state are not production identity or durable compliance evidence. Building a narrow MCP surface MCP standardizes how an AI application discovers and calls external tools. It does not remove the need to design those tools carefully. Caldova exposes small, typed operations such as get_recall_notice , locate_inventory , and get_supplier_status . Inputs are constrained with Pydantic, and tool annotations tell clients that these operations are read-only and closed-world: @mcp.tool( title="Locate affected inventory", annotations=ToolAnnotations( read_only_hint=True, open_world_hint=False, ), ) def locate_inventory(batch_id: BatchId) -> dict[str, Any]: return STORE.locate_inventory(batch_id) The mutation tool is separately marked destructive and requires a batch-scoped approval token. Those annotations improve discovery and planning, but they are metadata, not an authorization boundary. The real check occurs inside quarantine_batch , below the model and below the tool description. The Hosted Agent does not receive the mutation tools at all. Its specialists call only three read operations through an isolated MCP stdio subprocess. This is stronger than asking an all-powerful agent to "please remain read-only": capability is constrained by construction. The subprocess boundary also keeps MCP v2 dependencies isolated from the Foundry hosting environment. Each call has a timeout, bounded concurrency, structured JSON handling, and a generic failure response that does not leak subprocess details. Fixed workflows beat vague autonomy for this case Multi-agent does not have to mean dynamic routing. Caldova uses an explicit sequence because the business dependency is explicit: validate the notice before locating inventory, locate inventory before checking supplier implications, and synthesize only after all three specialist outputs exist. return ( WorkflowBuilder(start_executor=triage, output_from=[supervisor]) .add_edge(triage, inventory) .add_edge(inventory, compliance) .add_edge(compliance, supervisor) .build() .as_agent() ) This topology is easier to test and reason about than an unconstrained planner. Each specialist has one job and one tool allowlist. Full context is passed where synthesis requires it, while the supervisor remains tool-free. Request isolation matters too. A hosted process can serve concurrent users, so workflow state must not leak between requests. The sample creates a fresh workflow agent for each request context rather than reusing mutable agent state globally. What the live hosted run showed The hosted application completed a read-only assessment for the synthetic batch. The resulting brief reported: 2,196 affected units across four locations. A high-risk inbound temperature excursion. Supplier acknowledgement, a 36-hour replacement estimate, and a drafted credit note. Unknown transit temperature details, excursion duration, stability impact, final supplier disposition, and potentially issued stock. A recommendation to hold or quarantine stock, explicitly stating that no quarantine had occurred. A required human approval before any inventory restriction. The live Hosted Agent decision brief. Transient response and correlation identifiers are masked; the operations rail is excluded because it contains actor-scoped audit data. The screenshot also shows an important truthfulness choice: the UI says Hosted workflow trace unavailable. The application does not invent stage completion or tool-call evidence when the hosted endpoint does not return trustworthy trace data. The answer can be displayed, but it must not be presented as proof of an internal execution path. Approval is a protocol, not a button The hosted web path uses App Service authentication with Microsoft Entra. The application accepts the injected principal only on the configured App Service host, validates tenant and object identifiers, applies a user allowlist, and performs an additional approver check for mutation requests. State-changing calls also require the expected origin and an application request header. Approval is then bound to five facts: The authenticated actor. The current demo generation. The affected batch. The quarantine action. A ten-minute validity window until first use. Resetting the demo creates a new generation, invalidating old handles. Consuming an approval does not make replay unsafe: the same bound handle can repeat the same quarantine operation, but domain code changes only positions that are not already quarantined. A second call reports an idempotent replay with zero additional positions changed. This is the difference between a human-in-the-loop interface and a human-authorized system. A modal dialog provides user experience; identity binding and deterministic policy provide control. Durable state needs concurrency semantics The hosted application stores each actor's synthetic session in a separate Blob object. A load returns both JSON state and its ETag. A save uses IfNotModified semantics; if another request updated the same state first, Azure Storage rejects the stale write and the API returns a conflict. conditions = ( {"etag": etag, "match_condition": MatchConditions.IfNotModified} if etag else {} ) await blob.upload_blob( json.dumps(state), overwrite=etag is not None, **conditions, ) Without that condition, two browser requests could both read the same approval state and overwrite one another using last-writer-wins behavior. Agent systems do not get a concurrency exemption: ordinary distributed-systems rules still apply. Fail closed, and make the failure legible The analysis adapter accepts only HTTPS Foundry endpoints with the expected path, uses a managed-identity token for https://ai.azure.com/.default , disables redirects, and enforces bounded connect and overall timeouts. It accepts only a completed assistant response with non-empty output text. If the endpoint times out, returns partial output, returns malformed data, or becomes unavailable, the application clears the analysis lease and reports that no inventory changed. It does not substitute a local answer and label it as hosted. Approval remains locked until a new hosted analysis succeeds. This can feel strict during a demo, but it protects provenance. A degraded fallback is useful only when the UI and audit model can identify it accurately. What is proven, and what is not The sample provides useful evidence for several engineering claims: Typed MCP tools reject malformed input. Hosted specialists receive read-only capabilities only. Approval is checked below the model and bound to identity and session state. Quarantine is idempotent in the synthetic domain. Blob ETags prevent stale session writes. Empty, partial, failed, and timed-out hosted responses fail closed. Local tests cover domain, MCP, workflow, API, and repository-hygiene behavior. It does not prove that the sample is a production recall platform. The scenario is synthetic. The local audit log is not tamper-evident. The hosted UI currently lacks trustworthy per-stage and per-tool trace rendering. Deployment-specific RBAC, EasyAuth configuration, telemetry access, model behavior, load characteristics, costs, and recovery procedures require validation in each environment. Evaluation evidence also expires. Golden cases and evaluator configuration are useful assets, but historical results are not a current release certificate. Re-run evaluations against the deployed agent version and inspect failures before making quality claims. Try the pattern Start with the deterministic path before provisioning cloud resources: Set-Location (git rev-parse --show-toplevel) py -3.13 -m venv caldova-recall-control/.venv ./caldova-recall-control/.venv/Scripts/python.exe -m pip install ` -r caldova-recall-control/requirements-ui.txt ./caldova-recall-control/.venv/Scripts/python.exe -m uvicorn ` control_tower_api:app ` --app-dir caldova-recall-control/src ` --host 127.0.0.1 ` --port 8091 Then inspect the MCP server over stdio: ./caldova-recall-control/.venv/Scripts/python.exe ` caldova-recall-control/scripts/inspect_mcp.py The inspector discovers the real tool schemas, reads the synthetic inventory, rejects malformed input and an unapproved mutation, and confirms the stock remains unchanged. Only after that local contract is understood should you configure a Foundry project, deployment identity, model deployment, and Hosted Agent. Engineering takeaways The most reusable lesson in Caldova is not the number of agents. It is the placement of authority. Give each model the smallest useful toolset. Prefer explicit workflow topology when the business process is known. Treat tool annotations as descriptive metadata, not access control. Bind consequential approval to authenticated identity, resource, action, and session generation. Put mutation and idempotency in deterministic domain code. Use optimistic concurrency for durable web state. Preserve provenance by failing closed instead of silently changing execution paths. Show only evidence the system actually captured. Agents are excellent at turning fragmented evidence into an actionable brief. Reliable systems make sure the brief and the action remain two different things. References Caldova source repository Model Context Protocol introduction Microsoft Agent Framework workflow capabilities Deploy a Hosted Agent in Microsoft Foundry Configure Microsoft Entra authentication for Azure App Service Manage concurrency in Azure Blob StorageMicrosoft Foundry Hosted Agents and MCP in Practice: Building Fibey Field Ops
An agent can produce a convincing answer while the system around it is still difficult to deploy, authorize, debug, and recover. For AI engineers and developers, that is often the real gap between a promising prototype and an application people can depend on. Fibey Field Ops makes that gap concrete. It is a synthetic fiber-operations assistant built with Microsoft Foundry Hosted Agents, Model Context Protocol (MCP), and Azure Container Apps. This walkthrough follows one field-service task through the implementation, then examines the deployment and operational decisions behind it. Introduction: the application is more than the model Imagine a technician preparing a fiber work order. Before leaving the depot, they need the job details, available parts, relevant procedures, and network status. Those facts belong to different systems. A useful assistant must retrieve them, combine them, and explain what is missing without inventing an answer. The challenge is not simply selecting a capable model. It is establishing reliable contracts between the model, its tools, the hosting platform, and the application. Fibey demonstrates those contracts with one hosted agent, five instruction skills, eleven operational tools, and five supporting Container Apps. There is an important qualification: Fibey is a protected, synthetic-data demonstration, not a production-ready field-service system. Its gateway mappings and work orders remain in memory, and it does not enforce per-user session ownership or approval of operational writes. Those limitations are useful teaching material rather than details to hide. The Fibey repository contains the implementation, infrastructure, documentation, and presentation deck. Repository access depends on its permissions. 1. Separate reasoning, instructions, and tool execution MCP is a standard interface for discovering and invoking tools. In Fibey, the agent connects to one Microsoft Foundry Toolbox MCP endpoint. The toolbox exposes capabilities backed by an inventory MCP server, a work-orders OpenAPI service, and a Search knowledge base. That common interface does not make the underlying systems identical. OpenAPI still describes an HTTP API, inventory still implements MCP, and knowledge retrieval still depends on indexed documents. The toolbox centralizes the agent-facing integration and connection configuration while preserving those implementation choices. Four terms describe different responsibilities: Concept Responsibility in Fibey Agent Classifies the request, loads instructions, selects tools, and constructs the response Skill An instruction document for a task such as inventory lookup or field briefing Tool An operation with an advertised input schema and a result Toolbox The curated MCP surface and references to downstream connections Fibey's five skills cover inventory lookup, work-order management, knowledge retrieval, work-order preparation, and field briefings. The last two coordinate several tools; they do not create additional agents. The configured toolbox exposes eleven operational tools directly: six inventory/status operations, four work-order operations, and one knowledge-retrieval operation. The agent uses their actual names and schemas. Discovery wrappers such as tool_search and call_tool are relevant only when a toolbox exposes them; they are not mandatory steps before every call. This distinction matters when debugging. A missing wrapper is not necessarily a broken integration. A skill mentioning a capability is also not proof that the runtime can invoke it. The current tool schema is the executable contract. 2. Follow the hosted Azure architecture Microsoft Foundry hosts the agent container and exposes its endpoint. Azure Container Apps (ACA) hosts the application services around it. The deployment source of truth is azure.yaml , which declares the GPT-5.4-mini model deployment and the hosted agent's Responses 2.0.0 protocol. The design keeps the browser-facing application separate from agent execution and backend integration. That makes it easier to inspect each boundary, but it does not make the whole deployment private or remove the need for application authorization. Treat GPT-5.4-mini as the sample's configured baseline, not a claim that it is optimal for every workload. When evaluating another model, measure tool-selection accuracy, schema compliance, grounded answers, latency, and cost per completed task rather than choosing from a fluent demo response alone. The engineering architecture expands this presentation view with resource ownership, identities, configuration, and telemetry paths. The application request path The browser signs in through Microsoft Entra ID at the UI's ACA authentication boundary. An explicit allowlist restricts access to the intended user. Nginx serves the React application and proxies chat requests to the internal FastAPI gateway. The gateway invokes the Foundry-hosted agent using its managed identity. Server-sent events (SSE), a streaming HTTP format, carry answer text, tool activity, citations, failures, and completion back to the UI. Gateway and dashboard ingress are internal to the ACA environment. Inventory and work orders have external ingress so the toolbox can reach them, but their operational endpoints require separate API keys. External accessibility is not anonymous access, and internal ingress is not a complete network-isolation strategy. The knowledge and status paths The knowledge pipeline starts with eight Markdown documents in the repository. A setup script uploads them to a private Blob Storage container, configures a Search data source and indexer, verifies ingestion, and creates the knowledge source and knowledge base used by Foundry IQ. This is not an embedding pipeline assembled implicitly by the chat application. The current configuration uses minimal reasoning and extractive retrieval, with defaults of three output documents and 6,000 output tokens. Its knowledge-base configuration and MCP endpoint use preview APIs, which need lifecycle and support review before production adoption. Network status takes a different path. Inventory's get_network_status tool reads the configured internal HTML dashboard. It is a narrow HTTP fetch, not browser automation, arbitrary website navigation, or a real operational clearance. Azure Container Registry supplies container images. ACA logs go to Log Analytics. Hosted code enables OpenTelemetry, the standard instrumentation framework for traces and metrics, but the repository does not provision Application Insights. The project's linked trace destination must be configured and verified separately. 3. Trace a work-order briefing through the implementation The most useful demonstration starts with one concrete request: prepare a technician for a job. The field-briefing skill provides the instructions for combining work-order data, inventory, procedures, and status without pretending that one backend contains everything. Use a request such as the following in a prepared synthetic environment. The exact wording and tool order may vary; the important evidence is which operations succeeded and which facts support the answer. Brief me on WO-007, including stock, relevant procedures, safety, and network status. The intended flow is: Load the field-briefing instructions and retrieve WO-007. Identify required parts and use a batch stock check when several parts need checking. Combine procedure and safety questions into one focused knowledge retrieval. Read the configured synthetic status dashboard through inventory MCP. Produce a briefing grounded in successful results, with source references and explicit gaps. Batching is a useful engineering choice, not a claim of a measured performance improvement. One batch stock call avoids unnecessary repeated requests. Combining related retrieval questions can also reduce duplicate context and tool traffic. This screenshot was captured from an authenticated deployment. The displayed briefing identifies an unavailable connector kit and available test equipment. It illustrates a specific synthetic response, not current stock or a benchmark. Use the supported hosted integration The relevant implementation is the hosted entrypoint. It uses FoundryToolbox from agent_framework_foundry_hosting , a FoundryChatClient , a skills provider, and ResponsesHostServer.run_async() . The hosting helper does more than attach a bearer token. It authenticates MCP requests and forwards the hosted runtime's per-request call ID. Replacing it with a generic transport can lose context that the platform expects. The entrypoint also closes credentials and clients when execution exits. Hosted skill discovery prefers published skills when available and retains bundled instructions as a fallback in auto mode. Explicit mcp mode fails if published skills cannot be loaded; file mode uses the bundled documents. This makes the fallback intentional rather than silently running without the task instructions. Distinguish history from compute affinity The gateway maintains two hosted mappings. previous_response_id links conversation history, while agent_session_id preserves affinity to the hosted compute session. Losing one is not equivalent to losing the other. Both mappings are held in gateway memory, which is why it remains at one replica. A UUID (universally unique identifier) is a conversation handle, not proof of ownership. Reset clears the local mappings but does not reset work orders or delete the old remote compute session. There is also a privacy distinction between storage and telemetry. Gateway requests use stored Responses history, while the agent's model-call options use store: false . Sensitive tracing being disabled does not mean all conversation persistence is disabled. 4. Run locally without confusing development and cloud boundaries Local development is useful for inspecting the gateway and agent without rebuilding the hosted image. It still calls a real Foundry project, model, and toolbox. It is not an offline simulation, and tool writes can affect the configured synthetic backend. Use Python 3.12+, uv, Node.js 24 LTS, and an authorized Azure developer identity. The commands below run from the repository root in PowerShell. Keep the existing dependency locks and copy .env.example only when creating a new local configuration. uv sync --frozen Copy-Item .env.example .env Set FOUNDRY_PROJECT_ENDPOINT , FOUNDRY_MODEL , and TOOLBOX_MCP_URL in the ignored .env . Use your environment's actual values. Backend API keys belong in Foundry connections, not in the browser or prompts. Start the gateway: az login uv run --frozen uvicorn fibey.gateway.api_server:app --host 127.0.0.1 --port 8080 In another terminal, start the UI: Set-Location ui npm ci npm run dev Open http://localhost:5173 . Vite forwards /api to the gateway on port 8080. These development servers do not reproduce the cloud Entra boundary, and a cloud toolbox cannot reach your workstation's localhost . Inspect the API progressively With the local gateway running, start with a health request in a separate PowerShell terminal: $base = "http://127.0.0.1:8080" Invoke-RestMethod "$base/api/health" Next, create a UUID conversation and submit one synthetic request: $session = [guid]::NewGuid().ToString() $body = @{ message = "Show me WO-007."; session_id = $session } | ConvertTo-Json -Compress $response = Invoke-WebRequest "$base/api/chat" -Method Post -ContentType "application/json" -Body $body $response.Headers["X-Session-Id"] $response.Content This prints the completed SSE body rather than animating the stream. Reuse the same session for a follow-up by extracting a small helper: function Invoke-FibeyTurn { param([string] $Message, [string] $SessionId) $payload = @{ message = $Message; session_id = $SessionId } | ConvertTo-Json -Compress $result = Invoke-WebRequest "$base/api/chat" -Method Post ` -ContentType "application/json" -Body $payload return $result.Content } Invoke-FibeyTurn -Message "What parts does that work order need?" -SessionId $session The helper uses $base and $session from the preceding examples. It makes continuity explicit without hiding the API contract. The browser remains the better place to watch incremental text and activity. See local development for reset behavior and supporting-service details. 5. Deploy artifacts and infrastructure together Fibey's initial deployment is intentionally staged. A container image, its target port, its health probes, its registry association, and its runtime permissions must agree. Successfully building an image does not establish that agreement. The first supporting-infrastructure pass creates placeholder apps on port 80. Once all five real images have been published, a second pass applies the images with their application ports and probes. Plain azd deploy of a supporting service is not the initial port-switch mechanism for this sample. The deployment guide gives the complete sequence and prerequisites: Select the intended environment and provision the Foundry layer. Configure project aliases, the Entra application, the allowed user, and separate API keys. Provision placeholder supporting apps and verify scoped access and registry identity associations. Publish all five supporting images and confirm every image setting is populated. Provision supporting infrastructure again to apply the matching images, ports, and probes. Run knowledge setup, then toolbox setup. Deploy fibey-agent and perform protected-path acceptance checks. For example, this publication step comes after placeholders and access checks, not at the start of an unconfigured environment: azd publish status-dashboard azd publish inventory-mcp azd publish work-orders-api azd publish gateway azd publish ui Only after all five SERVICE_*_IMAGE_NAME settings exist should the next azd provision infra apply them. Keep those settings: an empty value selects a placeholder again. This is where DevOps becomes tangible. Review source, Bicep, locks, schemas, skills, and configuration together; record accepted image references, model configuration, toolbox version, and hosted-agent version. GitOps adds controlled reconciliation of reviewed desired state. The repository supplies the ingredients, not an existing CI/CD pipeline or GitOps controller. Toolbox promotion deserves the same discipline. The unversioned consumer endpoint follows the published default version. A version-specific developer endpoint can test a candidate before promotion. Updating a shared connection or default can affect consumers without rebuilding their images, so Git history alone is not a rollback mechanism. 6. Treat governance, observability, and scale as separate concerns Role-based access control (RBAC) grants an identity permission at a resource scope. The control plane creates and configures Azure resources; the data plane performs application work such as invoking agents, querying Search, or reading blobs. The identities used across those operations are not interchangeable. In particular, a successful UI login is not automatic end-user identity passthrough to every tool, and resource provisioning permissions do not establish all runtime permissions. Boundary Identity or credential Browser to UI Entra user, application registration, and user allowlist Gateway to Foundry Gateway managed identity with project-scoped invocation access Hosted agent to model and toolbox Foundry-provided runtime agent identity Toolbox to inventory and work orders Separate API keys stored in project connections Toolbox to Search knowledge base Foundry project managed identity Search indexer to documents Search managed identity with Blob reader access Image delivery adds another boundary: each supporting app needs both AcrPull and a registry association selecting its identity. The Foundry project identity used for infrastructure operations is also distinct from the hosted agent's runtime identity. Approval must exist outside the prompt Fibey's synthetic work-order writes run without an enforced human approval round trip. That is appropriate to understand in a disposable demo and inappropriate to conceal when discussing production. The hosted toolbox documentation is explicit: approval metadata alone does not block tools/call . The runtime must pause, collect a decision, and resume or reject the exact proposed operation. A prompt saying "ask first" is not equivalent to that control. Real writes need server-side authorization, approval tied to the arguments, idempotency, and a durable audit record. If a write's response is uncertain, read its state before retrying. Treat tool results as untrusted data rather than instructions. Debug the boundary that failed The activity sidebar makes tool use visible, but it is not a durable audit log or access to the model's hidden reasoning. Combine it with timestamps, request/session identifiers, ACA logs, and configured hosted traces. Keep sensitive message tracing off unless a controlled investigation explicitly requires it. Verify that a synthetic trace reaches the intended sink; enabled instrumentation alone does not prove ingestion. Symptom First checks UI returns 502 Gateway revision, target port, fixed Nginx upstream, SNI, and certificate trust Agent or tool returns 401/403 Identity, token audience, role scope, and downstream connection credential Knowledge retrieval fails Indexer completion, project Search role, API version, and advertised input schema Briefing receives 429 Model quota, concurrency, retrieval budgets, and repeated tool calls Stream ends early Terminal response event, timeout, malformed SSE, and transport failure The gateway must surface failed or truncated streams rather than treating partial text as a completed action. A final stream terminator after an error is not application success. Scale only after identifying state and capacity limits Foundry manages hosted runtime capabilities, but it does not externalize Fibey's gateway mappings or in-memory work orders. Adding replicas before redesigning that state would undermine continuity and consistent updates. Model throughput, hosted compute, downstream API capacity, Search, and ACA are separate constraints. Measure latency, errors, tokens, tool counts, and recovery under concurrent load. Registry storage/builds, model inference, compute, Search, Blob Storage, and telemetry all have costs; using a managed platform does not remove the need for budgets. 7. Evaluate the result before adding more agents The practical result is an inspectable workflow that combines heterogeneous systems into a grounded response. We can demonstrate inventory lookup, a synthetic work order, cited knowledge, a fixed status fetch, and a combined briefing through one agent-facing toolbox. That is functional evidence, not a production certification or benchmark. This post does not establish latency percentiles, cost per successful task, throughput, or availability under load. Those measurements should be acceptance criteria for an adaptation, not numbers inferred from a screenshot. Multi-agent coordination is a possible next design, not deployed Fibey behavior. A coordinator could delegate read-only inventory and procedure tasks while a restricted specialist handles approved writes. Each handoff would need typed inputs/results, correlation IDs, deadlines, cancellation, and budgets. Sharing a toolbox alone does not implement that coordination. Specialists also introduce additional failure paths, identity decisions, and state. Start with them only when task complexity, ownership, or isolation requirements justify the cost. The current five skills already provide modular instructions without creating five independently operated agents. 8. Summary: reuse the engineering boundaries Fibey's reusable pattern is the separation of model reasoning, task instructions, tool contracts, hosted execution, and operational controls. MCP gives the agent a common tool interface; Foundry supplies managed hosting and integration capabilities. The application team remains responsible for the guarantees around its data and actions. Start with one workflow and verify each boundary. Then add durable state, per-user authorization, enforced approvals, secret rotation, appropriate networking, evaluation, and recovery before introducing real operational data or more autonomous behavior. For a practical starting point, use the repository, follow the deployment guide, and reproduce the session walkthrough with synthetic data. The presentation deck provides the same architecture and demo sequence for a team discussion. References The repository describes what this sample implements. Microsoft documentation describes the surrounding platform capabilities, responsibilities, and supported integration contracts. Read both before adapting the solution, especially where preview APIs, identity behavior, or approval enforcement affect your requirements. Fibey Field Ops repository Fibey engineering architecture Fibey deployment guide Fibey toolbox integration Microsoft Foundry hosted agents Use a toolbox with a hosted agent Official Python hosted-agent toolbox sampleExplore the latest in MCP: All recordings from MCP Live!
We recently hosted MCP Live!, a free half-day event featuring the people building the Model Context Protocol and putting it into practice. The Model Context Protocol (MCP) is the open standard for connecting AI models to tools and data. MCP servers let agents work with external data sources and capabilities across clients such as VS Code, GitHub Copilot, Claude, and other AI applications. Across the event, speakers explored: The state of MCP, the latest specification updates, and the protocol roadmap MCP server and client development at GitHub and in Visual Studio Code Enterprise-ready tools, authentication, governance, and security Interactive MCP Apps built with FastMCP Event-driven agents powered by MCP triggers and events Watch the complete MCP Live playlist, or browse the individual session recordings below along with links to related documentation, code, and resources. State of MCP 📺 Watch YouTube recording Join Caitie McCaffrey for a look at the state of the Model Context Protocol and the major changes introduced in the latest 2026-07-28 MCP specification release. Learn about the protocol's updated roadmap and emerging protocol priorities, including Agentic Messaging Primitives, and how they enable new patterns for agent-to-agent communication. Get a preview of where the protocol is headed and what these changes mean for developers building the next generation of AI agents. View the slides Follow Caitie on: LinkedIn | X MCP specification 2026-07-28 release MCP conformance tests MCP Server Cards working group A unified MCP layer with Toolboxes in Microsoft Foundry 📺 Watch YouTube recording Viswajeeet Balaji shows how Toolboxes in Microsoft Foundry make MCP enterprise-ready. It supports runtime tool search, MCP skill extensions, and the latest MCP 07-28 specification—while letting teams bring OpenAPI tools and A2A agents, expose them through MCP, and reuse the same unified configuration across agents. A centralized governance layer adds consistent authentication and guardrails without requiring every agent to rebuild its integrations. View the slides Follow Viswajeeet on: LinkedIn Documentation: Toolboxes in Microsoft Foundry Blog post: Building agents that act on your behalf with Toolboxes MCP: Server, Client & Protocol at GitHub 📺 Watch YouTube recording Sam Morrow is a co-creator of GitHub's MCP, an MCP Spec Maintainer, and Copilot client developer. Find out the latest MCP features his team is shipping on both the server and client side, as well as the parts of the spec that he's most excited about. Learn about some of the recent challenges, future plans, and insights from working across the MCP stack, and get a sneak peek at what's coming next. GitHub MCP Server Follow Sam on: LinkedIn | X Building MCP servers with VS Code — Level up your MCP 📺 Watch YouTube recording Harald Kirschner shows how MCP servers have evolved beyond local tool calls into richer, production-ready agent capabilities. Through a live VS Code demo, he builds an agentic achievement tracker that uses tools, elicitation, progress notifications, an interactive MCP App, stateless HTTP, and Agent Plugins—showing how to design, debug, and distribute modern MCP integrations. View the slides Follow Harald on: LinkedIn | X Documentation: MCP servers in VS Code Official MCP Registry MCP Registry repository Evolution of MCP auth 📺 Watch YouTube recording Den Delimarsky, Lead Maintainer of MCP and Member of Technical Staff at Anthropic, discusses how MCP authorization reached its current state: the original OAuth profile, protected resource metadata, the shift in client registration with servers, and enterprise-managed authorization. He also covers what the maintainers are working on next, including agent identity. View the slides Follow Den on: LinkedIn MCP auth: Stop registering, Start linking 📺 Watch YouTube recording Sam Bellen explains how Dynamic Client Registration made every MCP client mint a fresh client_id with every server it met, a per-server credential tax that quietly breaks down once clients start connecting to servers opportunistically. He shows how Client ID Metadata Documents flip the model: your client_id becomes a URL the server fetches on demand, giving you one durable identity that works everywhere, with a live demo of the flow end to end. View the slides Follow Sam on: LinkedIn DCR vs. CIMD demo with xmcp and Auth0 When chatbots grow buttons: Building MCP apps with FastMCP 📺 Watch YouTube recording Chat is great, but sometimes the answer is a button, a chart, or a form. MCP Apps let servers render interactive interfaces directly inside AI clients. Jeremiah Lowin, creator of FastMCP, shows how to build them in Python with FastMCP and Prefab, from simple components to dynamically generated interfaces. Follow Jeremiah on: LinkedIn FastMCP FastMCP authentication Event-driven agents, powered by MCP 📺 Watch YouTube recording Clare Liguori discusses the MCP Triggers & Events experimental extension, which lets agents poll MCP servers for events and get webhook triggers. She explores the new agent architectures the extension enables and presents a live demo. View the slides Follow Clare on: LinkedIn | X MCP Triggers & Events Working Group MCP events serverless earthquake agent demo