foundry
32 Topics
Azure AI Gateway is now generally available: Ship faster, stay in control
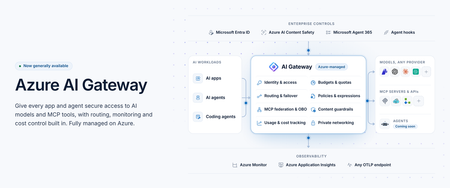
Today at Microsoft Ignite 2026, we're announcing the general availability of Azure AI Gateway, a fully managed Azure service that lets you set up a single, controlled path from your AI applications and agents to models and tools across providers. Developers build with the models and tools they choose, and platform teams manage access, enforce policies, control costs, and monitor usage from one place, without operating gateway infrastructure. Azure AI Gateway, previously in public preview as the AI Gateway tier of Azure API Management, is now a standalone product optimized for governing access to AI models and tools, with a roadmap focused entirely on AI. You can use it by itself with any app or agent, or together with Microsoft Foundry, where you build and run agents, and Microsoft Agent 365, where you manage them. Azure AI Gateway is available today in 17 Azure regions. To make it easy to get started, it offers a freemium, per-use pricing model with 10,000 free requests per gateway each month. Paid billing begins January 1, 2027. See the Regions and pricing section below for details. Why enterprise AI needs a unified governance layer Enterprise AI has moved beyond one app calling one model. Organizations use models from several providers, build agents that act through enterprise tools, and scale AI across teams. When each app manages its own credentials, routing, safety, and usage limits, governance becomes fragmented. Developers struggle to find approved models and tools, and platform teams can't see who is using what, what it costs, or which policies apply. Azure AI Gateway lets you move those controls out of individual apps and into one place, where they apply consistently to every app and agent you connect. How Azure AI Gateway works Apps and agents you connect call the gateway instead of calling each model or tool directly. On every request, the gateway authenticates the caller with Microsoft Entra ID or a gateway access key, enforces access rules and your policies, routes the request to the right model or tool, and records telemetry. Figure 1. Azure AI Gateway sits between callers and backends, governing every request that passes through it. What you can do with Azure AI Gateway Build with models and tools across providers Any model, one name: Use models from Microsoft Foundry, Azure OpenAI, OpenAI, Anthropic, Amazon Bedrock, Google Vertex AI, or any OpenAI-compatible endpoint. Apps call each model by an alias you define, so you can switch models without changing app code. Routing and failover: Route by priority, weight, or custom conditions, with configurable failover, or let Model Router (preview) choose by cost or quality. Consolidated tools: Federate MCP servers and turn OpenAPI specs, connectors, and API Management APIs into MCP tools. Multiple MCP spec versions are supported, including the latest (July 2026). The APIs you know: Call models through an OpenAI-compatible API or the Anthropic Messages API and connect agents to tools from any MCP client. Govern and observe AI interactions Access with Entra ID: Built-in roles control who can use models and tools. Provider keys and tool credentials never reach app code. Safety on every prompt: Screen prompts and responses with Azure AI Content Safety. Only approved tools: Curate and block tools at the gateway, or through Microsoft Agent 365 policies. Protection from poisoned tools (preview): Through the Microsoft Agent 365 integration, Microsoft Defender and Microsoft Purview inspect tool calls and results and block threats before an agent acts. Delegated identity: With on-behalf-of (OBO) authentication, tools act with the signed-in user’s own permissions. Every call on record: Record the caller, target, tokens, and outcome of each model and tool call, trace each call to its agent, and export the data over OpenTelemetry to Application Insights, Datadog, Splunk, Grafana Cloud, or any OTLP endpoint. Private by design: Private Link (preview) for inbound calls, VNet integration (preview) for private backends, IP filtering, and managed identity. Control AI spend as adoption scales See who spends what: Track tokens and estimated cost by user, team, app, agent, provider. Enforced budgets: Cost limits stop new requests once estimated spend reaches a budget. Fair sharing: Token and request limits keep one caller from crowding out the rest. Discover, build, and operate in your existing workflow Coding agent plugin: Developers find approved models and tools and connect their apps from their coding agent. Portal, CLI, Bicep, and REST API: Configure in the portal or with the CLI, then deploy the same setup as code from your CI/CD pipelines with Bicep or the REST API. See Azure AI Gateway in action From connecting models and MCP tools to securing access, controlling costs, and monitoring AI traffic, this demo shows how Azure AI Gateway helps you run AI applications with confidence. Extend AI governance across your Microsoft ecosystem Already using Microsoft Foundry, Microsoft Agent 365, or Azure API Management? Azure AI Gateway works with all three. Microsoft Foundry: Foundry has governance built in for its resources and projects. When AI spreads across teams, Foundry resources, subscriptions, and other providers, the gateway adds a shared layer on top. In a hub-and-spoke model, the gateway is the hub: a central platform team sets the rules once, and developers keep building in their Foundry projects, the spokes, using approved models and tools without managing credentials. Projects can share one deployment, including PTU, and fail over to another Foundry resource or provider. Foundry prompt agents can use gateway models through a model connection (preview), without code changes. Microsoft Agent 365: Agent 365 discovers the gateway’s MCP servers and lets you set tool policies. The gateway enforces those policies, alongside its own, on every tool call, with added threat protection (preview) from Defender and Purview. Regions and pricing Azure AI Gateway is available today in 17 Azure regions: East US, East US 2, East US 2 EUAP, West US, West US 2, Central US, North Central US, South Central US, Canada East, West Europe, North Europe, UK South, France Central, Sweden Central, Australia East, Japan East, and Southeast Asia. Azure AI Gateway offers a freemium, per-use pricing model with 10,000 free requests per gateway each month. Paid billing begins January 1, 2027. Monthly gateway requests Service fee Additional request charges Up to 10,000 Free None More than 10,000, up to 10 million $500 per month, per gateway, billed hourly None (includes 10 million requests) More than 10 million $500 per month, per gateway, billed hourly $20 per additional million requests, billed in increments of 10,000 requests Prices are in US dollars and may vary by region. Exact regional prices will be available when billing begins. Get started with Azure AI Gateway Create a gateway at ai.gateway.azure.com. It’s ready in about a minute and free to start. Then: Connect an existing model and give it an alias. Expose the MCP tools your agents need. Give your team access with an AI Gateway role. Set a cost limit. Point your app or agent at the gateway. Or start from your coding agent. Install the Azure AI Gateway plugin, and it finds approved models and tools and connects your app for you. Explore the documentation and quickstarts at ai.gateway.azure.com/docs.6.4KViews1like1CommentWhat’s new in Logic Apps Automation at Ignite 2026
Build like a startup. Ship like an enterprise. That's the idea behind Logic Apps Automation launched in Public Preview earlier this year. This Ignite preview refresh moves both halves forward. To build faster, you get templates, a refreshed designer, new built-in connectors for Azure automation, AI models that are ready to use with no deployment, and Decision actions that turn judgment calls into typed answers your workflow can act on. To ship with confidence, you get virtual network support, a re-platformed hosting environment that makes environments and apps faster to create, shareable templates that become your team's approved patterns, and availability in most Azure public region over the coming weeks. Here's what's new. New built-in connectors for Azure automation Automating Azure operations usually means connecting several systems: where your code lives, how it ships, how work is tracked, and how your Azure environment is behaving. This Ignite, Logic Apps adds a new set of built-in connectors for these systems: GitHub, Azure DevOps Pipelines, Azure DevOps Repos, Azure DevOps Boards, Azure Monitor Logs, Azure Resource Graph and Azure Advisor. Together they let a single workflow cover the full loop. It can respond to an event in your environment, look up the affected resources, check recommendations, open or update the right work item, kick off a pipeline and keep the code-review process moving. You can sign in with managed identity, OAuth or a personal access token, so you can pick what fits your security setup. Many of these connectors include triggers, so automation can start from an event instead of a schedule. Here are a few of the scenarios they make possible. Work tracking and planning with Azure DevOps Boards Route and assign new work items as they're created Monitor SLAs every time a work item is updated Code and delivery with agents with GitHub, Azure DevOps Repos and Azure DevOps Pipelines Triage new issues and suggest or open a fix as a pull request with an agent Review new pull requests automatically Kick off pipelines as part of the same workflow Azure operations and governance with Azure Monitor Logs, Azure Resource Graph and Azure Advisor Find affected resources and query logs when something needs attention Act on best-practice recommendations as they appear Together, these make Logic Apps Automation a central place to automate how you run, govern and improve your Azure estate. Because they run directly within the Logic Apps runtime, built-in connectors are generally faster and have fewer limits than managed connectors. More are coming soon, including Azure Events, Azure Key Vault, Microsoft Defender, Azure Policy, Azure Health and Azure Billing. Explore the template catalog and go from idea to workflow in minutes You don't need to start from scratch. Logic Apps Automation includes a growing catalog of ready-made templates that cover the full range of automation, from integration and business process workflows to agentic scenarios with AI agents and proven design patterns you can build on. For Azure automation, templates cover scenarios such as triaging new GitHub issues with an agent, reviewing incoming pull requests automatically, creating Azure DevOps work items from incoming events and tracking SLAs as work items change. Every template is a fully editable workflow, so you can start from a proven pattern and then add your own steps, approvals or AI agents as your needs grow. The catalog is now available in the Logic Apps Automation portal, where you can browse every template without signing in and explore what's possible before you commit to anything. When you find one you want to use, just choose your environment and app, and the workflow is created for you, ready to connect your accounts and run. Coming soon, you'll be able to maintain your own template library, giving your organization a single place to discover, publish and manage its approved templates. Turn any workflow run into a shareable template Templates aren't limited to the ones Microsoft ships. You can now generate a template directly from a run. When a workflow works well, one click turns it into a reusable template. From there you choose how far to share it. You can share it within your team or organization, where colleagues can import it and use it like any other template. Or you can check it into the public Logic Apps templates GitHub repository so it appears in the public gallery for the wider community. Teams can package proven automation patterns once and reuse them everywhere, and organizations can use templates to bring their development guidelines and best practices into every new workflow from the start. Coming soon, you'll be able to maintain your own template library, giving your organization a single place to discover, publish and manage its approved templates. Managed AI models: bring AI into your automation, with no setup Adding AI to a workflow used to mean provisioning a model resource, deploying a model and managing keys and quotas before you could build anything. With Managed AI Models, Logic Apps provides the large language models for you, so your agents can use them right away. There's nothing to provision, deploy or maintain. Pick a model and start building. Managed models work with both types of agents in Logic Apps. Workflow Agents are simple, declarative agents that you define directly in your workflow, which makes them a good fit for tasks like triaging GitHub issues or summarizing Azure Monitor findings. Managed Agents are for more advanced scenarios. They give you a pluggable harness and model choice, plus a sandbox for running code in isolation, so agents can safely analyze data, generate scripts or test fixes without touching your production environment. Decision actions Many automation steps come down to a judgment call: is this alert actionable, which team should own this issue, how severe is this incident? Decision actions, now in public preview, handle these questions with three native actions. Yes/No, Choice and Score each return a typed answer with a confidence value that your workflow can act on right away. The actions are powered by the built-in Microsoft-Decision-1 model, so there's no model to deploy and no output to parse. You'll find them under AI and agents in the designer. Read the full announcement here. Region availability Logic Apps Automation is already live in a set of initial regions, and starting at Ignite we're rolling it out to most Azure public regions. The rollout will take couple of weeks, so if it isn't in your region yet, check back over the coming days. Network isolation with virtual network support Automation that works across your Azure estate often needs to reach resources that aren't open to the internet. Logic Apps Automation now supports virtual network (VNet) integration. You can connect an environment to your virtual network, and all outbound calls from your workflows then go through it. That covers everything that runs in the environment, including all built-in connectors, agents and workflow actions, so your automation can run entirely inside your network. It can reach private databases, internal APIs and locked-down Azure resources while meeting your organization's network and compliance requirements. Setup is a single toggle. When you create an environment, choose your subscription, resource group and region, turn on Use a virtual network and pick a subnet from the list. That's it: the environment's traffic now goes through your VNet. Choose the subnet carefully, because it can't be attached, changed or removed after the environment is created. For more advanced configuration, you can also create the environment in the Azure portal. Private endpoint support for inbound traffic is next on the roadmap. Faster from the first click: a re-platformed foundation Logic Apps Automation moves to a new hosting platform built on Azure's lightweight, microVM-based compute with sub second cold start times. Before, each environment brought up its own dedicated infrastructure before you could build anything. Now environments and apps run on pre-provisioned regional capacity, so creating an environment and an app takes only a few seconds, down from a few minutes, and you go from sign-in to your first workflow almost immediately. The lighter-weight foundation also means each app uses fewer resources, and future platform improvements reach you without any changes on your side. Environments you've already created will keep running until they're migrated to the new platform. If you want the benefits sooner, you can recreate an environment to move it to the new platform right away. A refreshed designer Based on your feedback during the preview, we’ve redesigned the Logic Apps Automation designer to make workflows easier to understand, edit, test, and troubleshoot. Clearer canvas: a consistent visual style, labeled branches you can collapse, horizontal or vertical layouts, and canvas search. Agents in one view: each agent appears with its tools and selected model, and you can choose a Microsoft-managed model. Faster editing: copy, paste, or group several steps at once, and references update automatically when you rename a step. Easier configuration: individual Parse JSON properties show up as dynamic content, and inputs accept JavaScript expressions. Test before publishing: use test data and draft app settings to run supported drafts without touching your published workflow. Better monitoring: see the branch each run took, inspect loops one iteration at a time, and view retry history and analytics. Read the full walkthrough: From canvas to run: a better Logic Apps Automation experience Get started Logic Apps Automation is in preview today. Here's how to get started: Learn the basics. The documentation includes a three-minute overview video and a quickstart that walks you through creating your first environment and workflow. Start from a template. Browse the template gallery, pick a scenario that matches your needs and make it your own. Share your feedback. Try it on a real workflow and tell us what works and what's missing via Automation Feature Request. Your feedback shapes what we build next.503Views0likes0Comments
Issue enforcing Azure Policy on Azure OpenAI Model Deployments
Hi everyone, Due to strict data residency and compliance regulations within our organization, we need to enforce controls ensuring that global inference deployments (such as GlobalStandard or GlobalProvisioned) cannot be created within our Azure OpenAI environments. Our goal is to mandate the use of Data Zone or Regional deployments (e.g., DataZoneStandard). To achieve this, we created a custom Azure Policy using a whitelisting approach on the resource type Microsoft.CognitiveServices/accounts/deployments. We want to deny any model deployment whose SKU does not match our allowed deployment types. Here is the policy definition we are attempting to use: { "mode": "Indexed", "policyRule": { "if": { "allOf": [ { "field": "type", "equals": "Microsoft.CognitiveServices/accounts/deployments" }, { "field": "Microsoft.CognitiveServices/accounts/deployments/sku.name", "notIn": [ "Standard", "DataZoneStandard", "Provisioned", "DataZoneProvisioned" ] } ] }, "then": { "effect": "deny" } } } The Problem: Despite referencing the fully qualified alias Microsoft.CognitiveServices/accounts/deployments/sku.name (and attempting variation matches with like/notLike), the policy is still not working as expected when creating deployments via the Azure Portal or ARM/Bicep templates. We previously ran into an error stating that sku.name was not a valid field, but after changing it to the full alias, the definition saves—yet the rule fails to block non-compliant deployments during evaluation. Questions for the Community: Is Microsoft.CognitiveServices/accounts/deployments/sku.name the correct alias evaluated during ARM deployment calls for Azure OpenAI model deployments? Does Azure OpenAI store deployment types (GlobalStandard, DataZoneStandard, etc.) under a different property path or alias during validation? Has anyone successfully implemented a policy rule to block Global Token deployments or enforce Data Zone deployments only? Any insights, working policy samples, or alias pointers would be greatly appreciated! Thanks in advance for your help!80Views0likes1Comment
Microsoft Foundry External MCP Server Traffic Routing via Corporate Firewall
The customer would like to confirm whether traffic from an Azure AI Foundry agent to an external MCP server can be routed through a corporate firewall and whether this scenario is officially supported. To validate this scenario, I configured the following in my lab: Deployed an Azure AI Foundry resource using the Standard Agent Service with network injection. Created a dedicated subnet for the Foundry Agent Service and delegated it to Microsoft.App/environments. Associated a route table with the Foundry Agent subnet to route outbound traffic through Azure Firewall. Configured the required application and network rules on Azure Firewall. The Foundry agent is able to successfully retrieve data from the external MCP server. However, no corresponding traffic is visible in the Azure Firewall logs. Could you please confirm whether outbound traffic from the Foundry agent to an external MCP server can be routed through Azure Firewall or a corporate firewall? Also, is this routing scenario officially supported? Appreciate your support!434Views0likes2Comments🆕Orchestrate Foundry Prompt and Hosted Agents with Logic Apps Automation
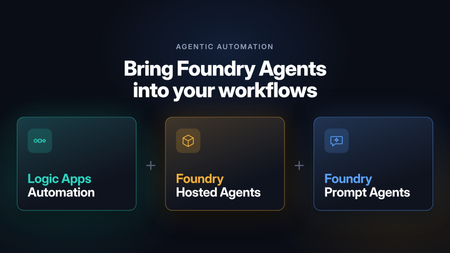
Microsoft Foundry is retiring workflows on December 1, 2026. After that date, the visual workflow designer and running workflows in the Foundry portal won’t be supported. For business process automation that combines deterministic steps with AI reasoning, the Foundry migration guide recommends Azure Logic Apps. Logic Apps is especially well suited to building these processes visually: Foundry agents become steps in a workflow, running alongside built-in actions, APIs, and MCP servers in the same run. Beyond the migration, there’s a broader question many teams face once an agent is working. Most agents start out as interactive, chat-based experiences: a person asks, and the agent responds. Putting that same agent to work in a business process means it has to run autonomously, started by an API call or an event instead of a person, running in the background and at scale. It also has to fit alongside the deterministic steps the process already depends on, such as gathering data before the agent runs and validating and acting on its output afterward. With support for Foundry Prompt Agents and Foundry Hosted Agents, Azure Logic Apps Automation gives you a direct way to do this. Any agent you’ve built in Foundry can become a step in a workflow. It can be started by an API call, a schedule, or an event from one of 1,400+ connectors, run in the background at scale, and sit between the deterministic steps that come before and after it. Before we get to the workflow side, here’s a quick look at the two agent types. If you want the full picture, the Foundry Agent Service overview compares them in detail. What are Foundry Prompt Agents A Prompt Agent is an agent you configure rather than code. You write instructions, pick a model, attach tools, and Foundry runs it. There’s nothing to deploy and no scaling to think about. It can use the Foundry model and tool catalogs, including knowledge sources like Azure AI Search and Foundry IQ. You pay for the tokens and tool calls it uses, with no separate platform charge. If you can write down what the agent should do and which tools it needs, a Prompt Agent will usually do the job, and it’s the quickest way to get something working. The prompt agent quickstart walks through building one. What are Foundry Hosted Agents A Hosted Agent is your own agent code, packaged as a container and run on Microsoft Foundry Agent Service. You can build it with Microsoft Agent Framework, LangGraph, the OpenAI Agents SDK, or your own code. Foundry handles the hosting and scaling. Since it’s your code, you decide how the agent loop works. Each session gets its own isolated sandbox with the CPU and memory you choose, and files and state persist between turns. Each Hosted Agent also gets its own Microsoft Entra agent identity, so you can see and audit what it does like any other identity in your tenant. Hosted Agents use the same models and tools as Prompt Agents. On top of tokens and tool calls, you pay for the compute they use (vCPU and memory hours). You can read more about how Hosted Agents work. A simple way to choose: start with a Prompt Agent. Move to a Hosted Agent when you need custom code or custom orchestration or want to bring your own code and framework. Orchestrate Foundry agents with Logic Apps workflows An agent in Foundry runs when someone or something calls it. Most business processes start somewhere else: an email comes in, a ticket is opened, a file lands in SharePoint, or a schedule fires. They usually end somewhere else too, with a record updated or someone getting a message. Logic Apps covers both ends and everything in between: a trigger to start the agent, deterministic steps around it, and branching, retries, timeouts, and parallel branches for the agent call. The next two sections show what that looks like. Every run shows up in run history, with the inputs, what the agent returned, and what happened next. When something goes wrong, you can see exactly where. The Learn article on automating Foundry agents with workflows covers the setup step by step. Run agents autonomously from any trigger The simplest setup is a trigger, an agent, and an action. Say a support email arrives in Outlook. The workflow sends it to a Prompt Agent that classifies it and drafts a reply, then creates a ticket with the result. This runs every time an email arrives, with no one starting it. Schedules work the same way. A recurrence trigger could call a Hosted Agent every Monday to go through last week’s data and post a summary in Teams. Mix agentic reasoning with deterministic steps Most processes are largely rule-based, with a step or two that needs adaptive reasoning or a decision. In Logic Apps you use an agent for those steps and keep everything else as deterministic steps. Before the agent runs, collect what it needs. Look up the customer in your CRM, pull the contract from SharePoint, or query a database, and pass all of it in. After it runs, check what came back. Validate it against a schema, apply your business rules, and send anything uncertain to a person for approval. Then write the result to the right system with a connector. Use both agent types in one workflow You don’t have to pick one type of agent per process. A workflow can call a Prompt Agent for a quick classification and send only the harder cases to a Hosted Agent for a longer analysis. The workflow passes output from one agent to the next, runs agents in parallel when they don’t depend on each other, and brings the results back together. Each agent stays small, and the end-to-end logic lives in the workflow, where you can see it and change it. How to use Foundry Agents from Workflows Hosted Agent You can create Foundry Hosted Agents directly from your Logic Apps Automation application. Pick your Foundry project and model deployment, and the app takes care of identity, permissions, and readiness checks for you. In a workflow, the Foundry Hosted agent action sends the agent its instructions, task, files, and any workflow actions you’ve added as tools. It returns the agent’s final response and generated files for the next steps to use. For details, see Foundry Hosted Agents for an overview and Create and use a Foundry Hosted Agent for step-by-step setup. https://youtu.be/foN9oPu5lRE Prompt Agent You can call an existing Foundry Prompt Agent from a workflow or create a new one right from the designer . Connect to your Foundry project, then either pick an agent from the list or select Create new agent and give it a name, a model, and instructions. The agent is created and hosted in Foundry. You can also give the agent tools from Logic Apps: actions from 1,400+ connectors, built-in actions, APIs, MCP servers, and other workflows. https://youtu.be/YkM7dHzHjdM Roadmap Today, workflows can invoke Hosted Agents that you create from your Logic Apps Automation app. We’re adding support for selecting an existing Hosted Agent from your Foundry project and invoking it from a workflow. Get Started Read to automate! Start building at auto.azure.com Automation QuickStart Automation Documentation - https://auto.azure.com/docs/791Views1like0CommentsMicrosoft Foundry Guardrails Getting in Your Way? Here’s How to Dial Them Down
How This All Started So here’s the story. I just got back from a trip and had a pile of footage sitting on my laptop. Being the lazy (sorry, efficient) person I am, I fired up OpenCode and asked GPT-6 Astra, running on Microsoft Foundry, to cut me a travelogue. Nothing fancy: under two minutes, nice lighting, clean transitions, no cringy effects, a quick QA before showing me, and the output in its own folder. Easy, right? Nope. This is what I got instead: “Image processing blocked due to content policy violation.” Seriously? It’s holiday footage! Nothing even remotely dodgy in there. This is a classic false positive from the default guardrails, and the good news is it’s totally fixable. Let me show you how. My Setup Quick context before we dive in: I’ve got two models deployed on Microsoft Foundry, gpt-6-astra and gpt-6-sol. Both were running on Microsoft’s out-of-the-box guardrail. Step 1: Find the Guardrails Page Head over to the Microsoft Foundry portal, click Build, then hit Guardrails in the left menu. You’ll see three guardrails that Microsoft gives you by default: Microsoft.Default, Microsoft.DefaultV2 and Microsoft.MAIDefault. Microsoft.DefaultV2 is the one every new deployment gets, which is why it’s sitting on both of my models. Here’s the catch: you can’t edit or delete these Microsoft-managed defaults. So instead of tweaking them, we’re going to build our own guardrail and swap it in. Step 2: Create Your Own Guardrail Smash that "Create" button and you’ll land on the Create guardrail page. This is where all the knobs and switches live: Every control has three bits: the risk type, the intervention point (does it check what you send in, what the model spits out, or both?) and the action. The magic trick for loosening things up is flipping the action from Block to Annotate. With Annotate, Foundry still scans the content and tags it in the API response, but it stops slamming the door on your request. So What Does Each Setting Actually Do? Before you go on a switching-off spree, it’s worth knowing what each of these does and what you’re giving up when you loosen it. Here’s the quick tour: Jailbreak: This one catches prompts trying to trick the model into ignoring its rules. On Block, those prompts get rejected outright. On Annotate, they go through with a flag. Turn it off completely and you’re trusting the model’s own training to keep it in line. Network (egress rules): Controls which outbound calls a hosted agent is allowed to make. As the portal points out, it only applies to hosted agents, so for plain model deployments like mine it doesn’t change a thing. Indirect prompt injections: Watches user input and tool responses (files, docs, web pages the model reads) for sneaky instructions someone has planted. Leave it on and your agents are protected when they read outside content; switch it off and a dodgy file could quietly hijack your model. For an agentic tool like OpenCode, which reads files and runs shell commands, I’d honestly keep this one on, even if it’s just on Annotate. Spotlighting (Preview): Tags external content inside the prompt so the model can tell your real instructions apart from random untrusted data. Think of it as an extra seatbelt against indirect attacks. Content harms (Hate, Sexual, Self-harm, Violence): Each of these has a severity slider that starts at Medium blocking, meaning anything rated medium or higher gets blocked. Slide it down to Lowest blocking and only the really nasty stuff gets stopped, which kills off most false positives like mine. The asterisk means these four are mandatory: you can turn the dial down, but you can’t switch them off. Blocklists: Want to ban specific words or phrases, like profanity or your competitor’s name? This is where you do it. It’s off by default. Protected material for code and text: Checks whether the model is about to spit out known copyrighted text (song lyrics, articles and so on) or code lifted from public repos. Block stops it; Annotate lets it through with a flag. Switch it off and you’re rolling the dice on your app reproducing someone else’s copyrighted work. Step 3: Pick Your Models Hit Next and Foundry asks which agents and models you want this guardrail on. Any model you’ve already deployed in your project shows up here. For me that’s gpt-6-astra and gpt-6-sol, so I ticked both. Step 4: Name It and Pick a Streaming Mode One more Next and you’re on the Review page. Give your guardrail a name (I went with NoGuardrails, because subtlety isn’t my thing) and pick a streaming mode. You’ve got two choices: Default: Foundry buffers the response and runs it through the guardrail before each chunk goes out. Nothing reaches the user until it’s been checked. Safest option, but you’ll feel a bit of lag when streaming. Asynchronous: Content streams back the moment it’s generated, with the filters running in the background. Much snappier, but flagged content might flash up briefly before the filter catches it, so your app has to clean up after the fact. Microsoft pitches this for low-latency stuff like internal dev tools, which is exactly my use case. Give the summary a quick once-over, then click Create. Done! Did It Work? Yep! With my shiny new guardrail in place, I fired off the exact same request, this time to GPT-6 Sol. And boom: no more content policy error. The model went straight to work scanning my footage and putting the video together. Wrapping Up Look, Microsoft’s default guardrails are a solid starting point, but they can be a bit trigger-happy when you’re doing perfectly legit stuff like video editing, creative work or internal tooling. Since you can’t touch the defaults, the trick is to roll your own: flip Block to Annotate where it makes sense, drag those content harm sliders down, pick the streaming mode that fits your app, and assign it to your deployments. That’s it! One friendly word of warning though: with great power comes great responsibility. Only loosen what you actually need, keep things like indirect prompt injection detection switched on for any agent that reads files or browses the web, and think twice before doing this on anything customer-facing. And if you want to go further than the portal lets you, like switching content filters off completely, you’ll need to apply to Microsoft for approval first. Happy building!655Views1like2CommentsAdding a Fallback Model to Hermes with Microsoft Foundry
So the plan was simple. Leave the Bedrock configuration untouched, then wire Microsoft Foundry in behind it as a fallback, so Hermes always has somewhere else to go when the primary provider is not responding. A few other reasons pushed me towards Foundry in particular: Redundancy that does not need me. If Bedrock is throttled or out of quota, I want Hermes to fail over on its own rather than waiting for me to notice. A catalogue I already pay for. Foundry puts the latest GPT models next to open-weight and partner models in one place, so I can pick a model that suits the task instead of settling for whatever a single provider happens to offer. Enterprise controls out of the box. Region pinning, private networking, content filters and per-deployment quota all sit in the same portal, which makes the setup far easier to defend to a security reviewer. Learning the mechanics before I need them. Working out how Hermes handles a provider chain is much nicer on a quiet Tuesday than during a live outage. Here is the short version, if you are deciding whether to read on. Time: about thirty minutes if nothing goes wrong. Cost: pay-as-you-go tokens only, and none at all while the fallback sits idle. Result: an assistant that keeps answering when your primary provider stops. Before you start, you will need three things: a machine with Hermes already installed and a working primary provider configured, an Azure subscription with access to Microsoft Foundry in a region you can actually deploy into, and enough quota in that region to create a deployment. One thing that made this easy to justify: Foundry deployments bill per token on the standard pay-as-you-go tier. A fallback provider that never gets invoked costs nothing beyond the requests it actually serves, so the insurance is close to free until the day you need it. Chat surface (CLI, messaging) → Hermes Gateway → Primary Amazon Bedrock → Fallback Microsoft Foundry Figure 1: Where the fallback sits. Every request goes through the Hermes gateway to the primary provider; only when that provider is unavailable does the chain continue to Microsoft Foundry. Part 1: Deploying a Model on Microsoft Foundry The first half of this job happens entirely inside the Microsoft Foundry portal and has nothing to do with Hermes yet. All you are really doing here is making sure your Azure subscription can serve a model, and that you hold an endpoint and key Hermes can authenticate with later. 1. Deploy model in Foundry → 2. Copy endpoint + key → 3. hermes fallback add → 4. Authenticate → 5. Select models, test Figure 2: The whole setup in five moves. The first two happen in the Microsoft Foundry portal (orange); the rest happen on the Hermes machine (blue). Go to Microsoft Foundry > Build > Models > Deploy > Deploy a base model. You can deploy a fine-tuned model instead if you already have one, which works just as well with Hermes. Check the region shown at the top of the portal before you commit, because both model availability and deployment quota differ from one region to the next. Then deploy the model you have selected: In this case I deployed gpt-5.6-sol, which is the model Hermes will fall back to. The choice was deliberate rather than exciting. My primary model on Bedrock is a general-purpose chat model, and a fallback is only useful if the answers it gives feel like a continuation of the same conversation rather than a different assistant wearing the same name. The gpt-5.6-sol deployment matches that behaviour closely, it was available in the region I wanted to pin, and the quota I was granted comfortably covers a day of normal use. If a fallback surprises you the first time it fires, it is the wrong fallback. Once the deployment finishes, open it and take note of two values: the target endpoint URI and the API key. Copy both somewhere safe now, because you will be pasting them into Hermes in the next part. If your organisation rotates keys on a schedule, use a key with the longest life you are allowed, since a fallback secured with a credential that expires quietly stops being a fallback. What to copy Where it lives in the portal Where Hermes asks for it Target endpoint URI Deployment > Endpoint > Target URI "Endpoint" prompt in hermes fallback add API key Deployment > Endpoint > Key "API key" prompt, or choose Entra ID instead Deployment name Deployment > Details > Name Shown in the model list Hermes returns Region Top of the portal, next to the resource Must match the region you deployed into Figure 3: Everything Hermes will ask for, and where to find each value before you leave the portal. Part 2: Adding Foundry to Hermes as a Fallback With the Foundry side sorted, everything from here happens in the Hermes CLI. One thing worth knowing before you start: this is the fallback command, not the primary model command, so your existing Bedrock configuration is left completely alone. Nothing in this section can break what is already working, which makes it a good one to try on a live setup. Run the Hermes fallback command: When Hermes asks which provider to add, choose Azure Foundry. The picker still carries the old name; it is the same service that the portal now calls Microsoft Foundry. Paste the target endpoint URI from your deployment, then authenticate with the API key you copied earlier. Hermes also offers Microsoft Entra ID at this prompt, which is the better option if your organisation would rather not have a static key sitting on the machine. If authentication fails here, check the endpoint before you start suspecting the key. In my experience the endpoint is wrong far more often than the credential is, usually because the deployment name at the end of the URI does not match the deployment you actually created. Once authentication succeeds, Hermes lists the deployments your Foundry resource exposes and asks which ones you want to use. You can select more than one, and the order is not cosmetic: Hermes walks down the chain from top to bottom whenever the provider above is unavailable. Treat that list as a priority order, not a shopping basket. What happens to the primary What Hermes does What you see in the chat Responds normally Routes every request to the primary and never touches the chain Nothing. The fallback stays idle Throttled or out of quota Retries the next provider down the chain on the same request A reply, served by the fallback model Endpoint unreachable Keeps failing over on each new request until the primary recovers Slightly different tone and latency, but a working assistant Every provider fails Returns the error rather than hanging An error worth chasing with hermes status Figure 4: The chain in practice. The fallback only earns its keep in the middle two rows, which is exactly why it is easy to forget you configured it. Part 3: Promoting Foundry to the Primary Model At this stage Foundry is sitting in the back seat as a backup. I wanted to reverse the arrangement and make Foundry the primary while Bedrock slides down into the fallback slot, partly because I preferred keeping day-to-day traffic inside my Azure subscription, and partly because I wanted proof the chain works in both directions. Before promotion After promotion Primary: Amazon Bedrock → Primary: Microsoft Foundry Fallback: Microsoft Foundry → Fallback: Amazon Bedrock Figure 5: The promotion, in effect. Nothing is added or removed; the two providers simply trade places in the chain. There is no dedicated "promote" command in Hermes, so the manual route is a short sequence of steps rather than a single instruction: Select the fallback provider/model as the new primary: hermes model Remove the now-duplicate model from the fallback chain: hermes fallback remove Optionally add the old primary model as a fallback: hermes fallback add Restart the messaging gateway: hermes gateway restart Verify the result: hermes status / hermes fallback list That sequence works, and it is good to know what is happening underneath. But since I already had a working provider configured, I would rather just ask Hermes to rearrange itself. This is the part I genuinely enjoy about the tool: the configuration is something you can talk to, not only something you type commands at. Prompt: Okay now please make the model I configured on Microsoft Foundry into the main model, and make the Bedrock one the fallback model! Hermes rewrites the provider chain on its own and confirms the swap once it is done, which is a great deal less error-prone than running the five commands by hand. Part 4: Testing the Switch Configuration you have not tested is just an assumption with extra steps, so the next thing is to confirm Hermes really is talking to Foundry. Type /model when running Hermes to bring up the model picker. You will be prompted to select a provider first. Pick the Microsoft Foundry entry, then choose the specific deployment from the list underneath it. The active model should switch straight away. Send it a plain "Hello" to check that the deployment actually responds, rather than just looking correct in the menu. Appearing in a dropdown and serving a request are two very different things. A second test is worth the thirty seconds it costs: run hermes status to confirm which provider is live, then hermes fallback list to confirm the chain is ordered the way you intended. The picker tells you what you selected; those two commands tell you what Hermes will actually do at three in the morning. Part 5: The Obstacle, and What It Actually Taught Me Every walkthrough has the part the author quietly leaves out. Here is mine: the wrinkle was not the model, it was capacity. My first attempt deployed into the region closest to me out of habit, and the portal turned it down because there was no capacity left for that model at the tier I asked for. The model was clearly listed in the catalogue; being listed and being deployable in your region, on your subscription, at your quota, are three separate questions. Redeploying in a different region fixed it in a couple of minutes, but it meant the endpoint URI changed, which in turn meant the value I had already pasted into Hermes was stale. Re-running hermes fallback add against the new endpoint sorted it out. The lesson is cheap enough to hand over for free: check quota and regional capacity for your specific subscription before you design a walkthrough, a demo or a production fallback around one deployment. In the Foundry portal, Management then Quota shows exactly what you have been granted per region and per model family, which is the only list that matters. Symptom Likely cause Fix Deployment rejected in the portal No capacity for that model at the tier you asked for, in that region Deploy in another region, or drop to a smaller tier Hermes rejects the credential Endpoint URI does not match the deployment you created Re-copy the target URI from the deployment, not the resource Provider authenticates but lists nothing Key belongs to a different Foundry resource Check you are in the right resource, then re-run hermes fallback add Fallback never fires Chain ordered the wrong way round hermes fallback list, then reorder Figure 6: The four things that went wrong, or nearly did, and what fixed each one. There is a silver lining worth stating plainly. Because the fallback chain was already in place, a deployment that refused to come up did not take the assistant down with it. That is precisely the scenario this whole exercise was meant to cover, and it turned up on day one without me having to simulate it. Command Cheat Sheet Everything used in this walkthrough, collected in one place: hermes fallback add: attach a provider to the fallback chain hermes fallback remove: drop a provider from the chain hermes fallback list: show the chain in priority order hermes model: set the primary model hermes gateway restart: restart the messaging gateway after a change hermes status: confirm which provider is currently live /model: switch models from inside a running session Conclusion Adding Microsoft Foundry as a fallback behind my existing Bedrock setup took an afternoon, and most of that was spent recovering from a regional capacity limit I should have checked first. The work itself is small: deploy a model, copy the endpoint and key, run hermes fallback add, authenticate, pick your deployments. The payoff is that Hermes no longer depends on one provider staying healthy. Three things are worth carrying away from this: Check quota, not just the catalogue. The Foundry catalogue shows what Microsoft offers. It does not show what your subscription and region can actually deploy today. Confirm that first, before you build anything on top of a specific deployment. Order your fallback chain deliberately. Hermes works down the list from top to bottom, so the sequence you choose during setup is the failover policy you are going to live with. Put the model you actually trust at the top. Treat the endpoint as part of the credential. Redeploying in a new region changes the endpoint URI, and a fallback pointed at an endpoint that no longer exists is not a fallback. Re-run the setup whenever the deployment moves. The switch from Bedrock primary to Foundry primary also proved the chain runs in both directions, which is the real point. Provider redundancy is only useful if you have watched it work. Next on my list is deliberately breaking the primary provider to confirm the failover triggers on its own, without me typing a single command. If you run this against a different model, region or provider pairing, I would genuinely like to know how it went, particularly if your quota experience was better than mine. Drop it in the comments.468Views0likes0CommentsMicrosoft Agent Framework Multi-Agent Workflow Architecture for Automated Kubernetes Assessments
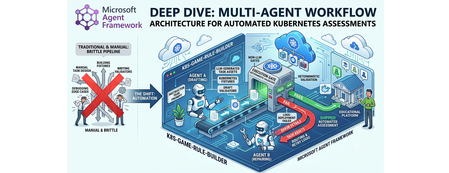
Why this system generates tests (design rationale) This project does not generate tests just to "check code." It generates tests because, in a Kubernetes learning game, the test suite is the grading contract. The design goals are: Scale content creation: instructors should not hand-author every task and checker. Keep grading objective: student success is measured against Kubernetes API state, not subjective review. Avoid fragile tasks: generated tasks must survive empty/wrong cluster states without crashing. Make failures repairable: when checks break, the system should patch and re-validate automatically. So the pipeline generates a full task package (setup, answer, check, cleanup) where tests define exactly what "correct" means. Lifecycle: from concept to production-ready grader Reader mental model: this is a content compiler with validation stages, not a single chat completion. Phase 1: Pedagogical intent -> structured concept The Idea Agent converts a topic into a constrained concept object (objective, progression, task IDs, difficulty variants). Memory rules block duplicates and previously failed concepts. Phase 2: Concept -> executable grading package The Generator Agent turns that concept into files: student instructions (instruction.md) learning material (concept.md) parameter source (session.json) setup and answer manifests (setup.template.yaml, answer.template.yaml) deterministic pytest flow (test_01 ... test_06) At this point, output is still untrusted draft content. Phase 3: Structural correctness gate Deterministic validation checks file presence, syntax, JSON/YAML shape, and template correctness. This catches basic integrity issues before cluster execution. Phase 4: Behavioral correctness gate (real cluster) Pytest executes against Kubernetes and verifies runtime behavior using real kubectl-derived state. This proves that generated checks actually evaluate cluster resources as intended. Phase 5: Anti-false-positive gate (skip-answer mode) The same suite runs with SKIP_ANSWER_TESTS=True to verify grader integrity: answer deployment is skipped test_05_check.py must fail If it still passes, the grader is invalid (it would accept wrong student submissions). Phase 6: Self-healing repair loop On any failure, deterministic error logs are fed into the Fixer Agent, which patches only broken files. The workflow then re-enters validation + test gates. Phase 7: Finalization If all gates pass -> task is kept as production-ready content. If retries are exhausted -> task is moved to unsuccessful/ with FAILURE_REPORT.txt for human triage. This lifecycle explains the core architecture decision: LLMs generate candidate graders, deterministic execution certifies them. Concrete generated sample (what the pipeline actually produces) Below is a representative generated task for topic: ConfigMap Environment Variable Injection. Generated directory layout tests/game01/050_configmap_env_injection/ ├── __init__.py ├── instruction.md ├── concept.md ├── session.json ├── setup.template.yaml ├── answer.template.yaml ├── test_01_setup.py ├── test_02_ready.py ├── test_03_answer.py ├── test_05_check.py └── test_06_cleanup.py session.json (runtime variables) { "namespace": "{{random_name()}}{{random_number(100,999)}}{{student_id()}}", "configmap_name": "{{random_name()}}", "deployment_name": "{{random_name()}}", "container_name": "app", "env_key": "APP_MODE", "env_value": "production" } Why this exists: task values are randomized per student/session, so tests verify behavior by variable contract instead of hardcoded names. setup.template.yaml (baseline state only) apiVersion: v1 kind: Namespace metadata: name: {{ namespace }} Why this exists: setup should create prerequisites only. It must not accidentally include the final answer. answer.template.yaml (expected correct solution) apiVersion: v1 kind: ConfigMap metadata: name: {{ configmap_name }} namespace: {{ namespace }} data: {{ env_key }}: "{{ env_value }}" --- apiVersion: apps/v1 kind: Deployment metadata: name: {{ deployment_name }} namespace: {{ namespace }} spec: replicas: 1 selector: matchLabels: app: env-demo template: metadata: labels: app: env-demo spec: containers: - name: {{ container_name }} image: nginx:latest env: - name: {{ env_key }} valueFrom: configMapKeyRef: name: {{ configmap_name }} key: {{ env_key }} Why this exists: defines canonical "correct cluster state" that graders must detect. test_02_ready.py (wait for setup resources) import json import time from tests.helper.kubectrl_helper import build_kube_config, run_kubectl_command class TestReady: def test_001_namespace_active(self, json_input): kube_config = build_kube_config( json_input["cert_file"], json_input["key_file"], json_input["host"] ) time.sleep(2) result = run_kubectl_command( kube_config, f"kubectl get namespace {json_input['namespace']} -o json", ) data = json.loads(result) assert data.get("status", {}).get("phase") == "Active" Why this matters: validates setup-stage readiness only. It should not check answer resources yet. test_05_check.py (student grading contract) import json from tests.helper.kubectrl_helper import build_kube_config, run_kubectl_command class TestCheck: def test_001_configmap_key_exists(self, json_input): kube_config = build_kube_config( json_input["cert_file"], json_input["key_file"], json_input["host"] ) result = run_kubectl_command( kube_config, f"kubectl get configmap {json_input['configmap_name']} -n {json_input['namespace']} -o json", ) data = json.loads(result) assert data["data"][json_input["env_key"]] == json_input["env_value"] def test_002_deployment_uses_configmap_env(self, json_input): kube_config = build_kube_config( json_input["cert_file"], json_input["key_file"], json_input["host"] ) result = run_kubectl_command( kube_config, f"kubectl get deployment {json_input['deployment_name']} -n {json_input['namespace']} -o json", ) data = json.loads(result) env = data["spec"]["template"]["spec"]["containers"][0].get("env", []) matched = [ e for e in env if e.get("name") == json_input["env_key"] and e.get("valueFrom", {}).get("configMapKeyRef", {}).get("name") == json_input["configmap_name"] and e.get("valueFrom", {}).get("configMapKeyRef", {}).get("key") == json_input["env_key"] ] assert matched, "Deployment container must consume env var from ConfigMap key" Why this matters: this is the real grading logic. If a student deploys wrong resource wiring, this test fails with explicit reason. Why skip-answer validation is essential for this sample When SKIP_ANSWER_TESTS=True, answer deployment is skipped. In this mode: test_03_answer.py should be skipped test_05_check.py must fail (ConfigMap/Deployment wiring is absent) If test_05_check.py still passes, the grader is broken (false positive), and the workflow routes to Fixer. Rule Builder Workflow Flowchart Multi-graph architecture views 1) Control-plane graph (orchestration DAG) 2) Runtime sequence (who calls what) 3) State machine (task lifecycle) 4) Prompt lifecycle graph (how prompts evolve) 5) MCP + Kubernetes execution boundary graph Core Agent Framework Primitives Used This repository is a practical example of Agent Framework as a graph orchestrator, not just an agent wrapper. WorkflowBuilder builds a typed DAG with explicit edges. @executor functions implement deterministic nodes (validation, pytest, decisions, routing prep). AgentExecutor wraps LLM agents so they behave as graph nodes. WorkflowContext shared state carries typed data and retry metadata between nodes. add_multi_selection_edge_group(...) + selector functions enforce conditional routing. MCPStdioTool connects filesystem MCP tools into agents for controlled file I/O. Production graph construction (from workflow/builder.py) looks like this: workflow = ( WorkflowBuilder(start_executor=initialize_retry) .add_edge(initialize_retry, generator_executor) .add_edge(generator_executor, parse_generated_task) .add_edge(parse_generated_task, run_validation) .add_edge(run_validation, run_pytest) .add_edge(run_pytest, make_decision) .add_multi_selection_edge_group( make_decision, [keep_task, remove_task], selection_func=select_action, ) .add_edge(keep_task, run_pytest_skip_answer) .add_multi_selection_edge_group( run_pytest_skip_answer, [check_loop, complete_workflow], selection_func=select_skip_answer_action, ) .add_multi_selection_edge_group( check_loop, [fix_task, complete_workflow], selection_func=select_loop_action, ) .add_edge(fix_task, fixer_executor) .add_edge(fixer_executor, parse_generated_task) .build() ) This is the architectural heart of the system: agents and deterministic executors are first-class nodes in the same graph. Detailed Node-by-Node Mechanics 1. Idea Agent (🧠): Concept Synthesis with Memory Constraints The Idea Agent (agents/k8s_task_idea_agent.py) generates a structured concept with three difficulty variations (BEGINNER/INTERMEDIATE/ADVANCED). It is memory-aware: task_ideas_memory.json tracks successful concepts. task_ideas_failure_memory.json tracks concepts that failed downstream. Memory constraints are injected using AgentMiddleware (system-level prompt injection) to avoid duplicate or previously failed concepts. For Responses-only models, the agent switches to a tool-call contract (save_k8s_task_concept) instead of structured response formatting. 2. Generator Agent (⚙️): MCP-Backed File Authoring The Generator Agent receives a strict prompt and writes task files through MCP filesystem tools. Key framework details: Built through chat_client.as_agent(...). MCP tool attached via tools=mcp_tool. Function-call execution observability added with LoggingFunctionMiddleware. Uses absolute-path-only policy in instructions to prevent path drift. 3. Deterministic Validation + Test (✅): Non-LLM Gates After generation, the graph moves through deterministic executors: run_validation calls pure Python checks (k8s_task_validator). run_pytest executes pytest --import-mode=importlib --rootdir=. .... Raw pytest output is persisted in workflow state for later fixing. This is critical: no LLM is asked whether code is correct. 4. Skip-Answer Test (🧪): Grader Correctness Gate Even if standard tests pass, the workflow enforces a second tier: SKIP_ANSWER_TESTS=True pytest --import-mode=importlib --rootdir=. Implementation detail: the executor writes JUnit XML, parses it, and asserts that: test_03_answer.py is skipped test_05_check.py fails as expected If test_05_check.py does not fail, the task is treated as invalid and sent back to retry/fix. 5. Fixer Agent + Retry Loop (🔧): Bounded Self-Healing On failure, fix_task builds a targeted prompt containing: failure reasons from deterministic nodes full captured pytest output explicit rule to patch only broken files in place The Fixer Agent runs through AgentExecutor, writes patches via MCP, and the graph loops back to parse_generated_task. Retries are stateful (retry_count, max_retries) and hard-bounded. On exhaustion, complete_workflow moves the task to unsuccessful/<game>/ and writes FAILURE_REPORT.txt. Agent Prompt Design (The Part That Makes It Work) If you want to understand why this pipeline works, you need to inspect prompts as operational contracts, not generic instructions. Real Idea Agent Prompt (from code) IDEA_AGENT_INSTRUCTIONS = ( "You are a Kubernetes task idea generator that creates detailed task concepts with three difficulty variations. " "Read official K8s documentation and propose comprehensive learning concepts for a Kubernetes game. " "\n\nYour task:\n" "1. Choose ONE Kubernetes concept not yet covered (check context for existing concepts)\n" "2. Generate exactly 3 variations: BEGINNER, INTERMEDIATE, and ADVANCED\n" "3. Use 3-digit task IDs (001-999) in format: XXX_concept_name_level (e.g., 041_secrets_basic)\n" "4. Each variation should build on the previous one with increasing complexity\n" "5. Include practical, hands-on scenarios covering: Workloads, Services, Storage, Configuration, Security, Scheduling, Policies\n" "\nProvide the concept, tags, description, and 3 variations with task_id, difficulty, title, objective, key_skills, and estimated_time." ) Responses-only models use a stricter tool-call version: IDEA_AGENT_INSTRUCTIONS_TOOL_CALL = ( IDEA_AGENT_INSTRUCTIONS + "\n\n" "**CRITICAL**: You MUST call the save_k8s_task_concept tool to save your generated concept.\n" "...\n" "Always call save_k8s_task_concept with your generated concept." ) Idea Agent Prompt Contract The Idea Agent prompt enforces: one concept per run exactly three difficulty variations strict task ID format (XXX_concept_name_level) practical skill progression Core pattern: You are a Kubernetes task idea generator... 1. Choose ONE Kubernetes concept not yet covered 2. Generate exactly 3 variations: BEGINNER, INTERMEDIATE, ADVANCED 3. Use 3-digit task IDs in format XXX_concept_name_level ... It is strengthened by runtime memory injection: previously generated concepts are blocked previously failed concepts are blocked For Responses-only models, the contract becomes tool-driven: CRITICAL: You MUST call the save_k8s_task_concept tool... This reduces ambiguity in output structure and makes downstream parsing deterministic. Real Generator Agent Prompt (from code) def _get_generator_instructions(): return ( "You are a Kubernetes task generator with filesystem tools.\n" f"The MCP filesystem is rooted at: {PATHS.tests_root.parent}\n" f"You MUST use ABSOLUTE paths for ALL file operations.\n" f"Task directory: {PATHS.game_root}/XXX_task_name/\n" "...\n" "CRITICAL: test_02_ready.py checks resources from setup.template.yaml, NOT answer.template.yaml.\n" "...\n" "MUST use polling loops (60s timeout, 15s interval)\n" "MUST use try/except and safe .get() JSON access\n" ) The generator prompt is long on purpose: it encodes path correctness, file schema, YAML/Jinja structure, and testing strategy in a single deterministic contract. Generator Agent Prompt Contract The Generator prompt is intentionally long and prescriptive because it defines filesystem safety and grading correctness requirements. Key constraints encoded in the prompt: Absolute path writes only (prevents writing to wrong workspace paths) No directory creation (directory is pre-created by executor) Required file set (instruction.md, concept.md, session.json, templates, tests) test-flow invariants: test_01_setup.py deploys setup test_02_ready.py checks setup resources only test_03_answer.py deploys answer test_05_check.py validates final solution robust test coding style: polling loops, try/except, .get()-based JSON parsing, explicit debug output Example contract fragment: CRITICAL PATH RULES: ✅ CORRECT: /abs/path/tests/gameXX/050_task/file.py ❌ WRONG: tests/gameXX/050_task/file.py (relative) CRITICAL: test_02_ready.py checks resources from setup.template.yaml, NOT answer.template.yaml. This is why generation quality is high before the Fixer loop even starts. Real Runtime Retry Prompt Builder (from code) def _build_retry_generation_prompt(combined: CombinedValidationResult) -> str: task_id = combined.test.task_id failure_reasons = _build_failure_reasons(combined) return ( f"Generate a complete Kubernetes learning task with ID '{task_id}' about '{combined.target_topic}'. " f"This is retry attempt {combined.retry_count + 1} of {combined.max_retries}. " f"\n\n⚠️ PREVIOUS ATTEMPT FAILED:" f"\n{chr(10).join([f' - {reason}' for reason in failure_reasons])}" f"\n\nIMPORTANT: You MUST use the exact task ID '{task_id}' - do not generate a new ID." f"\n\n✅ Directory already exists: {PATHS.game_root}/{task_id}/" f"\nWrite all files directly into this directory. Do NOT call create_directory." "..." ) This means retries are not generic retries; they are failure-conditioned retries with precise constraints. Fixer Agent Prompt Contract The Fixer prompt is a repair protocol, not a regeneration prompt. It includes: exact failure reasons from deterministic validators raw pytest output instruction to read current task files first strict directive to patch only broken files Core behavior constraints: DO NOT rewrite all files. Make TARGETED FIXES to ONLY the broken files. Use ABSOLUTE paths for all file operations. This keeps retries cheap, preserves working artifacts, and improves convergence speed. Real Runtime Fix Prompt Builder (from code) def _build_fix_prompt(combined: CombinedValidationResult, raw_test_output: str) -> str: task_id = combined.test.task_id failure_reasons = _build_failure_reasons(combined) prompt = ( f"Fix the failed Kubernetes task '{task_id}' located in '{PATHS.game_root}/{task_id}/'." f"\n\nThis is fix attempt {combined.retry_count + 1} of {combined.max_retries}." f"\n\n⚠️ TASK FAILED WITH THESE ERRORS:" f"\n{chr(10).join([f' - {reason}' for reason in failure_reasons])}" ) if raw_test_output: prompt += f"\n\n📋 FULL TEST OUTPUT:\n```\n{raw_test_output}\n```" prompt += ( f"\n\n🔍 YOUR TASK:" f"\n1. READ all files from '{PATHS.game_root}/{task_id}/'" f"\n6. Make TARGETED FIXES to ONLY the broken files" f"\n7. WRITE ONLY the fixed files back" f"\n\n⚠️ CRITICAL: DO NOT rewrite all files! Only fix the broken ones!" ) return prompt How Prompt Output Enters the Agent Framework Graph The prompt builders above are used by deterministic executors and sent to agent nodes through AgentExecutorRequest: await ctx.send_message( AgentExecutorRequest( messages=[Message(role="user", contents=[fix_prompt])], should_respond=True ) ) So prompt generation and graph routing are tightly coupled: each route transition emits a specific prompt payload into the next LLM node. Runtime-Constructed Prompts in Executors The most important prompts are built dynamically in workflow executors: _build_retry_generation_prompt(...) _build_fix_prompt(...) These functions inject live context: retry_count / max_retries concept + objective metadata validation/test failure reasons full captured test logs So each retry is context-rich and specific, not another blind generation attempt. Prompt + Middleware + Deterministic Gates = Reliability In this repository, reliability does not come from prompt text alone. It comes from three layers working together: Prompt contracts constrain agent behavior. Middleware injects memory and logs tool invocations. Deterministic executors enforce objective pass/fail gates. That combination is why the workflow remains auditable and predictable even when LLM outputs vary. Agent Framework Execution Model in This Repo Strongly-Typed Message Passing workflow/models.py defines transport models used between nodes: ValidationResult and TestResult (Pydantic) CombinedValidationResult (dataclass with should_keep and should_retry) InitialWorkflowState (seed payload for each run) This keeps node contracts explicit and simplifies selector logic. Fail-Fast Shared State Management Executors use ctx.get_state(...) with a sentinel (_MISSING) and raise explicit exceptions if required state is absent. This prevents hidden fallback behavior and catches graph/data wiring errors early. Conditional Routing with Selectors Selectors (workflow/selectors.py) encode graph decisions: select_action → keep vs remove select_skip_answer_action → complete vs loop select_loop_action → fix vs complete This separates decision policy from executor implementation. Streaming Workflow Runtime workflow.run(initial_state, stream=True) emits output events incrementally. The runner (workflow/runner.py) consumes these events to detect successful completions and update concept memory accordingly. Agent Construction and API Selection Strategy The repository uses Azure CLI auth (AzureCliCredential) and dynamically selects API mode by deployment name (agents/config.py): Chat Completions path: OpenAIChatCompletionClient Responses-only model path: OpenAIChatClient or custom ResponsesAgent Why this matters: some codex-class deployments are Responses-only, so the architecture supports both without changing workflow logic. How MCP Actually Controls Kubernetes (Important Distinction) In this repo, MCP is used for filesystem control; Kubernetes control is done through kubectl tools. 1) MCP server role: controlled file I/O The workflow starts MCP stdio servers (official filesystem server) and mounts them into agents: docs_mcp_tool = MCPStdioTool( name="filesystem_docs", command="npx", args=["-y", "@modelcontextprotocol/server-filesystem", str(PATHS.k8s_docs_root)], load_prompts=False, ) tests_mcp_tool = MCPStdioTool( name="filesystem_tests", command="npx", args=["-y", "@modelcontextprotocol/server-filesystem", str(PATHS.tests_root.parent)], load_prompts=False, ) Those MCP tools are passed into Generator/Fixer agents, which then call MCP file functions (read/write/list) inside allowed roots only. 2) Kubernetes cluster control role: kubectl execution tool Cluster actions are not performed by MCP filesystem server; they are performed by a dedicated function tool: def run_kubectl_command(command: str) -> str: kubeconfig_path = os.environ.get("KUBECONFIG", "/home/developer/.kube/config") cmd_list = ["kubectl"] + command.split() result = subprocess.run( cmd_list, capture_output=True, text=True, check=True, env={**os.environ, "KUBECONFIG": kubeconfig_path}, ) return result.stdout And the Kubernetes agent forces tool usage: agent = responses_client.as_agent( name="KubernetesAgent", instructions="...You MUST use the run_kubectl_command tool...", tools=[run_kubectl_command], default_options={"tool_choice": "required"}, ) So the control plane is: MCP filesystem → manipulate generated task files. kubectl tool → query/mutate real cluster state. deterministic pytest/validator executors → accept or reject results. 3) End-to-end command flow in practice When generated tests run, they execute real kubectl get ... -o json checks in test code, and the deterministic runner captures raw output: pytest_command = f"pytest --import-mode=importlib --rootdir=. {task_with_val.task_directory}/" result = run_pytest_command(pytest_command) ctx.set_state(f"raw_output_{task_with_val.task_id}", raw_output) This means Kubernetes state verification is always grounded in live command output, not model speculation. Should MCP run Kubernetes tests? Short answer: not in this design. Current architecture keeps test execution deterministic and local: pytest is run by run_pytest_command(...) (pure Python subprocess runner) test results are parsed and stored in workflow state retry/fix routing uses those deterministic outputs This is intentional. If test execution were delegated to an LLM-facing MCP command tool, you would lose strict control over execution semantics and error handling. Recommended pattern: Use MCP for file/document access and controlled editing. Use deterministic executors for pytest and validation. Use LLM agents only for generation and repair. If you still want MCP-driven test execution, add a separate locked-down command MCP server (only whitelisted pytest/kubectl commands), but keep pass/fail decision logic in deterministic executors. How tests are run in this workflow (with code) The workflow executes tests in deterministic executors, not inside LLM agents. 1) Workflow node calls pytest runner run_pytest executor builds the command and calls the pure Python runner: @executor(id="run_pytest") async def run_pytest(task_with_val: TaskWithValidation, ctx: WorkflowContext[TestResult]) -> None: from agents.pytest_runner import run_pytest_command pytest_command = f"pytest --import-mode=importlib --rootdir=. {task_with_val.task_directory}/" result = run_pytest_command(pytest_command) raw_output = result["details"][0] if result.get("details") else "" ctx.set_state(f"raw_output_{task_with_val.task_id}", raw_output) ... 2) Deterministic subprocess execution The runner normalizes command flags and executes pytest via subprocess: def run_pytest_command(command: str) -> dict[str, Any]: normalized_command = _normalize_pytest_command(command) # adds -s if needed cmd_list = shlex.split(normalized_command) result = subprocess.run( cmd_list, capture_output=True, text=True, check=False, cwd=str(PATHS.pytest_rootdir), ) combined_output = result.stdout + "\n" + result.stderr _save_test_output(normalized_command, combined_output, skip_answer) ... Exit codes are interpreted deterministically: 0 → pass 5 → no tests collected (fail) others → fail with exit code reason 3) Skip-answer validation tier After normal pass, the workflow runs pytest again with SKIP_ANSWER_TESTS=True and parses JUnit XML: os.environ["SKIP_ANSWER_TESTS"] = "True" pytest_command = f"pytest --import-mode=importlib --rootdir=. --junitxml={junit_path} {task_dir}/" result = run_pytest_command(pytest_command) test_05_failed, test_03_skipped = _parse_skip_answer_junit(junit_path) The parser checks per-testcase outcomes: if "test_05_check.py" in context and has_failure_or_error: test_05_failed = True if "test_03_answer.py" in context and has_skipped: test_03_skipped = True 4) How failures trigger fix loop If pytest fails (or skip-answer logic fails), failure reasons and raw output are pushed into state, then the Fixer Agent receives a generated fix prompt containing that output: ctx.set_state(f"failure_reasons_{task_id}", reasons) ctx.set_state(f"raw_output_{task_id}", raw_output) fix_prompt = _build_fix_prompt(combined, raw_test_output) await ctx.send_message( AgentExecutorRequest( messages=[Message(role="user", contents=[fix_prompt])], should_respond=True ) ) That is the key loop: deterministic test output drives LLM repair, then deterministic tests re-run. ResponsesAgent Internals (Advanced Agent Framework Pattern) The custom ResponsesAgent (agents/responses_agent.py) demonstrates a lower-level integration pattern: Connect MCP tool lazily. Call Responses API. Parse ResponseFunctionToolCall items. Execute tools (MCP + custom callables). Feed function_call_output back to model. Repeat until final text response. It also runs a middleware chain around tool invocations, preserving observability and consistency with standard agent paths. Why This Architecture Is Robust This design works because Agent Framework is used as a deterministic orchestration layer around probabilistic generation: LLM creativity is constrained by typed state and strict prompts. deterministic executors act as objective quality gates. retries are targeted, bounded, and auditable. failures produce durable forensic artifacts (FAILURE_REPORT.txt + test logs). For Kubernetes education pipelines, this yields high throughput without sacrificing grader reliability. GitHub Repo - https://github.com/wongcyrus/k8s-game-rule-builder About the Author Cyrus Wong is the senior lecturer of Hong Kong Institute of Information Technology (HKIIT) @ IVE(Lee Wai Lee).and he focuses on teaching public Cloud technologies. He is a passionate advocate for the adoption of cloud technology across various media and events. With his extensive knowledge and expertise, he has earned prestigious recognitions such as AWS AI Hero, Microsoft MVP- Microsoft Foundry, and Google Developer Expert - Cloud(AI).533Views0likes0Comments
Is there a way to connect 2 Ai foundry to the same cosmos containers?
I defined Azure AI Foundry Connection for Azure Cosmos DB and BYO Thread Storage in Azure AI Agent Service by using these instructions: Integration with Azure AI Agent Service - Azure Cosmos DB for NoSQL | Microsoft Learn I see that it created 3 containers under the cosmos I provided: <guid>-agent-entity-store v-system-thread-message-store <guid>-thread-message-store Now I created another AI foundry and added a connection for the same AI foundry, and it created 3 different containers under the same DB. Is there a way that they'll use the same exact containers? I want to use multiple AI foundries, and they will use the same Cosmos containers to manage the data.504Views0likes1Comment
Missing equivalent for Python MemorySearchTool and AgentMemorySettings in C# SDK
Hi Team, I am currently working with the Azure AI Foundry Agent Service (preview). I’ve been reviewing the documentation for managed long-term memory, specifically the "Automatic User Memory" features demonstrated in the Python SDK here: https://learn.microsoft.com/en-us/azure/ai-foundry/agents/how-to/memory-usage?view=foundry&tabs=python. In Python, it is very straightforward to attach a MemorySearchTool to an agent and use AgentMemorySettings(scope="user_123") during a run. This allows the service to automatically extract, consolidate, and retrieve memories without manual intervention. However, in the https://github.com/Azure/azure-sdk-for-net/tree/main/sdk/ai/Azure.AI.Projects#memory-store-operations, I only see the low-level MemoryStoreClient which appears to require manual CRUD operations on memory items. My Questions: Is there an equivalent high-level AgentMemorySearchTool or similar abstraction in the current C# NuGet package (Azure.AI.Projects) that handles automatic extraction and retrieval? If not currently available, is this feature on the immediate roadmap for the .NET SDK? Are there any samples showing how to achieve "automatic" memory (where the Agent extracts facts itself) using the C# SDK without having to build a custom orchestration layer or call REST APIs directly? Any guidance on the timeline for feature parity between the Python and .NET SDKs regarding Agent Memory would be greatly appreciated. SDK Version: Azure.AI.Projects 1.2.0-beta.5373Views0likes2Comments