cloud adoption framework
21 TopicsHow do AKS and AKS on Azure Stack HCI compare?
This blog is an update to the original blog published comparing AKS in Azure and on Azure Stack HCI, a year ago. Since then, we’ve released multiple features and fixes aimed at improving AKS consistency between Azure and on-premises that warranted a fresh blog 😊 Features in preview are marked by (*) Feature Set AKS on Azure Stack HCI & AKS on Windows Server AKS Kubernetes Management Cluster/AKS host AKS on Azure Stack HCI and Windows Server is a Cluster API based hosted Kubernetes offering. A management Kubernetes cluster is used to manage Kubernetes workload clusters. The management Kubernetes cluster runs in customer datacenters and is managed by the infrastructure administrator. AKS is a managed Kubernetes offering. AKS control plane is hosted and managed by Microsoft. AKS worker nodes are created in customer subscriptions. Kubernetes Target Cluster (lifecycle operations) Cloud Native Computing Foundation (CNCF) certification Yes Yes Who manages the cluster? Managed by you Managed by you Where is the cluster located? In your datacenter alongside your AKS hybrid management cluster. Azure Stack HCI 21H2 Windows Server 2019 Datacenter Windows Server 2022 Datacenter Windows 10/11 IoT Enterprise* Windows 10/11 Enterprise* Windows 10/11 Pro* Azure cloud K8s cluster lifecycle management tools (create, scale, update and delete clusters) PowerShell (PS) Windows Admin Center (WAC) Az CLI* Azure Portal* ARM templates* Az CLI Az PowerShell Azure Portal Bicep ARM templates Can you use kubectl and other open-source Kubernetes tools? Yes Yes Workload cluster updates K8s version upgrade through PowerShell or WAC. Initiated by you. Node OS image update initiated by you; Updates in a target cluster happen at the cluster level – control plane nodes + node pools updated. Azure CLI, Azure PS, Portal, ARM templates, GitHub Actions; OS image patch upgrade; Automatic upgrades; Planned maintenance windows; Kubernetes versions Continuous updates to supported Kubernetes versions. For latest version support, visit AKS hybrid releases on GitHub. Continuous updates to supported Kubernetes versions. For latest version support, run az aks get-versions. Can you start/stop K8s clusters to save costs? Yes, by stopping the underlying failover cluster Yes Azure Fleet Manager integration Not yet. Yes* Terraform support Not yet. Yes Node Pools Do you support running Linux and Windows node pools in the same cluster? Yes! Linux nodes: CBL-Mariner Windows nodes: Windows Server 2019 Datacenter, Windows Server 2022 Datacenter Yes. Linux nodes: Ubuntu 18.04, CBL-Mariner Windows nodes: Windows Server 2019 Datacenter Windows Server 2022 Datacenter What’s your container runtime? Linux nodes: containerd Windows nodes: containerd Linux nodes: containerd Windows nodes: containerd Can you scale node pools? Manually Cluster autoscaler Vertical pod autoscalar Manually Cluster autoscaler Vertical pod autoscalar Horizontal pod autoscalar Yes Yes What about virtual nodes? Azure container instance No Yes Can you upgrade a node pool? We do not support upgrading individual node pools. All upgrades happen at the K8s cluster level. You can perform node pool specific upgrades in an AKS cluster. GPU enabled node pools Yes* Yes Azure Container Registry Yes Yes KEDA support Not yet Yes* Networking Who creates and manages the networks? All networks (for both the management cluster and target K8s clusters) are created and managed by you By default, Azure creates the virtual network and subnet for you. You can also choose an existing virtual network to create your AKS clusters What type of network options are supported? DHCP networks with/without VLAN ID Static IP networks with/without VLAN ID SDN support for AKS on Azure Stack HCI Bring your own Azure virtual network for AKS clusters. Load balancers HAProxy (default) runs in a separate VM in the target K8s cluster kubeVIP – runs as a K8s service in the control plane K8s node Bring your own load balancer Load balancers are always given sIP addresses from a customer vip pool to ensure application and K8s cluster availability. You can create multiple instances of a LB (active-passive) for high availability Azure load balancer – Basic SKU or Standard SKU Can also use internal load balancer By default, load balancer IP address is tied to load balancer ARM resource. You can also assign a static public IP address directly to your Kubernetes service CNI/Network plugin Calico (default) Note: Network policies are covered in the Security and Authentication section. Azure CNI Calico Azure CNI Overlay Bring your own CNI Note: Network policies are covered in the Security and Authentication section. Ingress controllers No but you can use 3 rd party addons – Nginx. 3 rd party addons are not supported by Microsoft’s support policy. Support for Nginx with web app routing addon. Egress controls Egress is controlled by Network policies, by default all outbound traffic from pods is blocked. You can deploy additional egress controls and policies. You can use Azure Policy and NSGs to control network flow or use Calico policies. You can also use Azure FW and Azure Security Groups. Egress types Egress types and options depend on your network architecture. Azure load balancer, managed NAT gateway and user defined routes are the supported egress types. Customize CoreDNS Allowed Allowed Service Mesh Yes, Open Service Mesh (OSM) through Azure Arc enabled Kubernetes. 3 rd party addons – Istio, etc. 3 rd party addons are not supported by Microsoft’s support policy. Open Service Mesh Marketplace offering available for Istio Storage Where is the storage provisioned? On-premises Azure Storage. Azure Files and Azure Disk premium CSI drivers deployed by default. You can also deploy any custom storage class. What types of persistent volumes are supported? Read Write Once Read Write Many Read Write Once Read Write Many Do the storage drivers support Container Storage Interface (CSI)? Yes Yes Is dynamic provisioning supported? Yes Yes Is volume resizing supported? Yes Yes Are volume snapshots supported? No Yes Security and Authentication How do you access your Kubernetes cluster? Certificate based kubeconfig (default) AD based kubeconfig Azure AD and Kubernetes RBAC Azure AD and Azure RBAC* Certificate based kubeconfig (default) Azure AD and Kubernetes RBAC Azure AD and Azure RBAC Network Policies Yes, we support Calico network policies Yes, we support Calico and Azure CNI network policies Limit source networks that can access API server Yes, by using VIP pools. Yes, by using the “-api-server-authorized-ip-ranges” parameter and private clusters. Certificate rotation and secrets encryption Yes Yes Support for private cluster Not supported yet Yes! You can create private AKS clusters Secrets store CSI driver Yes Yes Support for disk encryption Yes, via bitlocker Disks are encrypted on the storage side with platform managed keys and with support for customer provided keys. Hosts and locally attached disks can also be encrypted with encryption at host. gMSA v2 support for Windows containers Yes Yes Azure Policy Yes, through Azure Arc enabled K8s Yes Azure Defender Yes, through Azure Arc enabled K8s* Yes Monitoring and Logging Collect logs Yes, through PS and WAC. All logs – management cluster, control plane nodes, target K8s clusters are collected. Yes, through Azure Portal, Az CLI, etc Support for Azure Monitor Yes, through Azure Arc enabled K8s. Yes 3 rd party addons for monitoring and logging AKS works with Azure managed Prometheus* and Azure managed Grafana* Subscribe to Azure Event Grid Events Yes, via Azure Arc enabled Kubernetes* Yes Develop and run applications Azure App service Yes, through Azure Arc enabled K8s* Yes Azure Functions Yes, through Azure Arc enabled K8s* Yes Azure Logic Apps Yes, through Azure Arc enabled K8s* You can directly create App Service, Functions, Logic Apps on Azure instead of creating on AKS Develop applications using Helm Yes Yes Develop applications using Dapr Yes, through Azure Arc enabled K8s* Yes DevOps Azure DevOps via Azure Arc enabled K8s. GitHub Actions via Azure Arc enabled K8s. GitOps Flux v2 via Azure Arc enabled K8s. 3 rd party addon: ArgoCD. 3 rd party addons are not supported by Microsoft’s support policy. GitOps Flux v2 through Azure Arc enabled Kubernetes is free for AKS-HCI customers. Azure DevOps GitHub Actions GitOps Flux v2 Product Pricing Product pricing If you have Azure Hybrid Benefit, you can use AKS-HCI at no additional cost. If you do not have Azure Hybrid Benefit pricing based on number of workload cluster vCPUs. Management cluster, control plane nodes, load balancers are free. Unlimited free clusters, pay for on-demand compute of the worker nodes. Paid tier available with uptime SLA, support for 5k nodes. Azure Support AKS-HCI is supported out of the Windows Server support organization aligned with Arc for Kubernetes and Azure Stack HCI. You can open support requests through the Azure portal and other support channels like Premier Support. AKS in Azure is supported through enterprise class support in the Azure team. You can open support requests in the Azure portal. SLA We do not offer SLAs since AKS-HCI runs in your environment. Paid uptime SLA clusters for production with fixed cost on the API + worker node compute, storage and networking costs.18KViews2likes3CommentsAnnouncing landing zone accelerator for Azure Arc-enabled Kubernetes
Following our release a few months back of the new landing zone accelerator for Azure Arc-enabled servers, today we’re launching the Azure Arc-enabled Kubernetes landing zone accelerator within the Azure Cloud Adoption Framework.14KViews3likes0CommentsModern Azure Resilience with Mark Russinovich
Resiliency in the cloud reflects different priorities from consistent performance, to withstanding failures, to predictable recovery. These map to reliability, resiliency, and recoverability, which together guide how workloads should be designed on Azure. This post extends foundational guidance with practical multi‑region design decisions, including when to use availability zones, paired regions, and non‑paired regions to meet business continuity goals. Reliability in Azure isn’t defined by a single recommendation, but by a set of architectural patterns designed to balance cost, complexity, recovery speed, and operational effort—because no single approach fits every workload. While disaster recovery is a common driver for multi‑region designs, long‑term scale planning also matters. Azure regions operate within defined physical and latency boundaries, and large-scale workloads may eventually approach the practical capacity limits of a single region. This post introduces four resilience patterns, outlining when and why to use each so you can assess options based on your non‑functional requirements. It also explains how availability zone–based designs can often provide an alternative to paired regions as a default choice. Here are a few common reliability and availability architecture patterns: In-region High Availability (HA) with Availability Zones (AZ): Maximize availability within a single Azure region by deploying across multiple availability zones. Regional Business Continuity and Disaster Recovery (BCDR): A primary/secondary region strategy implemented across separate Azure regions, selected based on geographic risk boundaries, regulatory requirements, and service availability. Recovery sequencing and failover behaviors are defined by workload dependencies and organizational requirements. Non-paired region BCDR: A primary/secondary region strategy where the secondary region is chosen based on requirements such as capacity, service availability, data residency, and network latency. This approach also supports long‑term scale planning, since Azure regions operate within physical datacenter footprints and latency boundaries and can reach practical capacity limits as workloads grow. See multi‑region solutions in non‑paired regions. Multi-region active/active: Deploy workloads across multiple regions simultaneously so that each region can serve production traffic. This approach can provide both high availability and disaster resilience while improving global performance, but it introduces additional architectural complexity and operational overhead. The rest of this post helps you understand the tradeoffs across these patterns, enabling you to select the right approach per workload while avoiding unnecessary cost and operational complexity. First post in this series: Achieve agility and scale in a dynamic cloud world Why did Azure launch with paired regions? Launched in 2010, but rebranded to Microsoft Azure in 2014, the regions were introduced in pairs (West US & East US, West Europe & North Europe, Southeast Asia & East Asia) to align with common enterprise business continuity practices at the time. Many organizations operated multiple datacenters within the same geographic boundary, separated by sufficient distance to reduce shared risk while maintaining regulatory and operational alignment. This design mirrored familiar enterprise BCDR practices at the time and offered: A familiar primary/secondary failover pattern consistent with enterprise BCDR strategies Support for regulatory or data residency requirements that required disaster recovery within a defined geographic boundary Turnkey replication capabilities for services such as Geo-Redundant Storage (GRS) Platform-level sequencing of updates to reduce the likelihood of simultaneous regional impact A defined regional recovery prioritization model for rare geography-wide incidents This model provided assurance that Azure could meet or exceed the resilience of legacy enterprise environments while simplifying early cloud adoption through predefined recovery patterns. However, Azure’s engineering strategy has evolved. Many services now support replication to a region of choice rather than being limited to predefined pairs. This provides architects with greater flexibility to select regions based on workload requirements, risk boundaries, compliance constraints, capacity considerations, and cost models. It’s important to recognize that regional parity is never guaranteed even between paired regions. Differences in service availability, supported SKUs, scale limits, capacity, cost and operational maturity must be explicitly accounted for in the workload design. How has cloud resilience evolved since launch? The introduction of Availability Zones in 2018 provides a significant advancement in Azure resilience. Availability Zones are physically isolated groups of data centers within a region; each zone has independent power, cooling and networking. Many Azure services (App Service, Storage, Azure SQL etc.) use zones to provide platform-managed resilience. In addition, customers can deploy zonal resources, such as virtual machines, into specific zones or distribute them across zones to design for higher availability. Where previously Azure regions were launched in pairs, since 2020, regions have been typically designed with multiple availability zones, without a paired region. This design enables: High availability within a single region Platform-managed resilience for most failure scenarios Reduced need for multi-region deployments for standard high-availability requirements How should customers design for resilience when using both paired and non-paired regions? To decide which resiliency model makes sense, customers should start by defining clear expectations including uptime targets, recovery time objectives (RTO), recovery point objectives (RPO), latency tolerance, and data residency. These non-functional requirements should directly influence architectural decisions. In practice, High Availability (HA) and Disaster Recovery (DR) are differentiated by recovery objectives rather than geography. HA architectures target near-zero downtime and minimal data loss, while DR solutions allow for defined recovery time and acceptable data loss. While HA is commonly established within a region using availability zones, it can also be achieved across regions through active-active designs. Similarly, DR is typically implemented across regions using replication and failover strategies. HA: Availability Zones When designing high availability within a region, Azure builds on AZs with 2 models: Zone-redundant resources are replicated across multiple availability zones to ensure data remains accessible even if one zone fails. Some services provide built-in zone redundancy, while others require manual configuration. Typically, Microsoft chooses the zones used for your resources, though some services allow you to select them. Zonal resources are deployed in a single availability zone and do not provide automatic resiliency against zone outages. While faults in other zones do not affect them, ensuring resiliency requires deploying separate resources across multiple zones. Microsoft does not handle this process; you are responsible for managing failover if an outage occurs. The decision to design a zone-resilient architecture is critical for balancing availability requirements with cost and regional capacity constraints. Designing workloads to be resilient across availability zones is generally the preferred approach for improving availability and protecting against zone-level failures. Deploying workloads across availability zones can enhance fault tolerance and reduce downtime when supported by the Azure service being used. However, architects should still consider workload characteristics, cost implications, and potential latency impacts, which may vary depending on the services and architecture patterns involved. Ultimately, zone resiliency is an architectural decision that should be strategically aligned with business priorities and risk tolerance, not simply treated as a checkbox to be ticked during deployment. DR: Paired and Non-Paired Regions Region pairs should be viewed as an architectural choice rather than a rule. Historically, paired regions played a key role in minimizing correlated failures and streamlining platform updates and recovery processes. However, as the Azure Safe Deployment Practices (SDP) have matured, the advantages of region pairs have become more nuanced. Over time, SDP has evolved to support safer and more flexible change management through longer and more adaptable bake times, richer operational signal integration, and an expanded understanding of regional deployment boundaries. These improvements enable Azure to release changes more safely across a growing and increasingly diverse regional footprint, while still balancing reliability with time‑to‑market. As a result, regional pairs are no longer the sole mechanism for managing correlated change risk, but one of several architectural tools customers can apply based on their resiliency and compliance needs. Using non-paired regions or a mix of paired and non-paired regions allows customers to design high availability and disaster recovery architectures that are driven by business, compliance, and application requirements rather than fixed regional relationships. This enables customers to optimize data residency, regulatory boundaries, latency to specific user populations, and provide differentiated recovery objectives across their workloads. This approach can also reduce exposure to rare but high-impact platform-level events by avoiding tightly coupled regional behaviors. While some Azure services natively simplify replication and recovery within paired regions, and others support replication across arbitrary regions (such as Azure SQL, Cosmos DB, and Azure Blob Storage with object replication), non-paired designs encourage explicit, workload-aware resiliency strategies such as application-level replication, asynchronous data sync, and failover orchestration. Although this introduces more architectural responsibility and may require compensating for paired region features, it delivers greater transparency, predictable recovery behavior, and alignment with business-driven RTO/RPO requirements rather than platform defaults. Regional failover is a customer‑orchestrated decision; customers should design, test, and operate their own failover and failback processes rather than assuming platform‑initiated regional failover. Designing for regional resilience requires distinguishing between workload mobility and data protection. Azure provides two complementary capabilities that address these needs differently: Azure Site Recovery (ASR) and Azure Backup. Azure Site Recovery (ASR) enables near‑continuous replication and orchestrated failover of virtual machine–based workloads to a region of choice, not limited to paired regions. ASR is the primary mechanism for customers who need low RPO, controlled failover, and workload restart in a secondary region. This is especially relevant for regions without a paired region or where the paired region does not meet capacity, service availability, or compliance needs. Azure Backup provides durable, policy‑based data protection, independent of compute availability. While Azure Backup is not a high‑availability or infrastructure failover solution, it plays a critical role when services do not support region‑of‑choice replication natively. In these scenarios, backup and restore become the recovery mechanism. These two services are often used together: ASR for VM‑level workload continuity, and Azure Backup for protecting and restoring data across regions, including to non‑paired regions. I am using paired regions today – does this mean I need to change my architecture? If your current architecture is built around paired regions for compliance, data residency, or strict disaster recovery objectives, that model stays valid and supported. Azure continues to support paired regions providing prioritized recovery sequencing, staggered platform updates, and geo-aligned data residency, all backed by Microsoft’s global infrastructure strategy. What has changed is that paired regions are no longer the only way to achieve enterprise-grade resilience. For many workloads that adopted a paired region (1+1) model primarily to protect against local datacenter failure, Availability Zones combined with geo-redundant services now provide equivalent or better protection with far less architectural complexity and cost. The shift to nonpaired regions is therefore not a forced migration, but an opportunity to simplify. Customers can continue using paired regions where business requirements demand it, while selectively modernizing other workloads to take advantage of platform-managed zone resilience. What’s coming up next for resilience in Azure? Resilience is evolving from static guidance to continuous, workload-aware execution. A multi-region strategy isn’t only about recovery; it’s also a practical hedge against regional capacity constraints (regions have physical limits within a latency boundary, so growth can eventually hit caps). Resiliency agent in Azure Copilot (preview) helps you spot missing resiliency coverage—such as zone alignment gaps or missing backup/DR—and provides automated guidance (including scripts) to remediate issues, configure Azure Backup and Azure Site Recovery, and define recovery drills. Resiliency in Azure brings zone resiliency, high availability, backup, DR, and ransomware protection together into a unified experience within Azure Copilot, enabling teams to set resiliency goals, receive proactive recommendations, and view service‑group insights via Azure portal. If you’re looking for service-specific BCDR and replication guidance, use these authoritative starting points: Cloud Adoption Framework (CAF) – Landing zone design area (BCDR): guidance to define platform DR requirements (RTO/RPO), data residency considerations, and operational readiness as part of landing zone design. Azure Well-Architected Framework (WAF) – Disaster recovery strategies: guidance for structuring, testing, and operating DR plans aligned to recovery targets, with links to companion DR planning resources. WAF design guide – Regions & Availability Zones: how to choose between zone- vs region-based approaches and understand reliability/cost/performance tradeoffs. Azure service reliability guides: service-by-service reliability/replication behavior and customer responsibilities. Non‑paired multi‑region configurations: examples of supported multi-region approaches when regions aren’t paired. Validate feasibility before you design: confirm service/SKU/zone availability in both regions. Next step: Explore Azure Essentials for guidance and tools to build secure, resilient, cost-efficient Azure projects. To see how shared responsibility and Azure Essentials come together in practice, read Resiliency in the cloud—empowered by shared responsibility and Azure Essentials and How to design reliable, resilient, and recoverable workloads on Azure on the Microsoft Azure Blog. For expert-led, outcome-based engagements to strengthen resiliency and operational readiness, Microsoft Unified provides end-to-end support across the Microsoft cloud. To move from guidance to execution, start your project with experts and investments through Azure Accelerate. Related Resources Architecture strategies for using Availability Zones and Region High Availability Architecture strategies for highly available multi-region design Disaster Recovery Architecture strategies for designing a Disaster Recovery strategy Multi-Region solutions in nonpaired Regions Develop a disaster recovery plan for multi-region deployments Azure Regions and Services Azure region pairs and nonpaired regions Reliability guides for Azure servicesAzure Best Practices delivered to machines anywhere with new Azure Arc and Automanage integration.
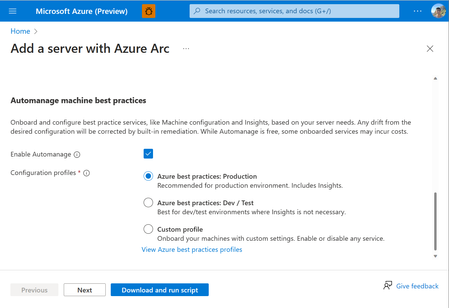
Tired of manually onboarding and configuring Azure services for your Arc-enabled servers? With Azure Automanage Machine Best Practices, you can point, click, set, and forget to extend Azure security, monitoring, and governance services to servers anywhere.6KViews6likes2CommentsAnnouncing Landing Zone Accelerator for Azure Arc-enabled SQL Managed Instance
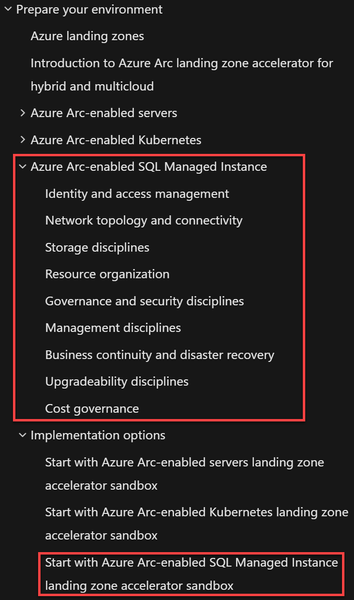
With both Azure Arc-enabled servers and Kubernetes Landing Zone Accelerators already generally available, today we're launching the Azure Arc-enabled SQL Managed Instance landing zone accelerator within the Azure Cloud Adoption Framework.5.8KViews0likes0Comments
Give us your thoughts on running Kubernetes anywhere for a chance to win a $300 USD gift card!
Do you work with Kubernetes? Are you interested in improving Kubernetes experience across hybrid and multicloud environments? Take the survey below for a chance to win a $300 USD virtual gift card! Must be 18 or older. Survey ends on May 10, 2023.3.6KViews0likes0CommentsChallenges of Containerized App Portability in Kubernetes
Introduction As organizations embrace containerization and Kubernetes for their applications, the need for seamless portability across the Kubernetes ecosystem coupled with cloud object storage and local persistence has become a pressing concern. In this blog post, we will dive into the core problem and dissect the complex challenges that customers face in achieving containerized app portability. Challenges Local Persistence and High Availability Local persistence is crucial, but ensuring highly available Kubernetes volumes that can tolerate hardware failures presents a challenge. Organizations need a robust solution to maintain continuous operation and data integrity. Coordinating Consistency Across Apps Coordinating data consistency across all edge applications sharing data is imperative. Ensuring that data changes are propagated uniformly and reliably is a significant challenge in a distributed and dynamic Kubernetes environment. Once cloud storage is involved in your data management strategy, consistency handling between edge data bound for cloud processing becomes even more challenging. Data Upload at the Edge A suite of containerized apps deployed at the edge needs to upload data to cloud storage, introducing challenges related to data transfer, synchronization, and efficient utilization of bandwidth. Avoiding Cloud Storage API Coding for Every App It is not feasible for every app in the suite to code directly to the Cloud Storage API. Organizations need solutions that abstract this complexity, providing a unified interface for different applications without compromising on functionality. Disconnect/Reconnect Logic The need for disconnect/reconnect logic to handle network disconnections introduces an additional layer of complexity. Applications must seamlessly adapt to network disruptions, ensuring uninterrupted operation and data flow. Shared Filesystem Capability Implementing shared filesystem capability on top of high availability volumes is essential. Achieving this requires careful orchestration to avoid data inconsistencies and conflicts in a distributed environment. Addressing the Challenges Robust High-Availability Strategies Implement robust strategies for local persistence and high availability within Kubernetes clusters, minimizing the impact of compute hardware failures and maintaining continuous operations. Unified Filesystem Abstraction Ensures consistency across applications without compromising on the benefits of distributed storage. Edge-Focused Data Solutions Explore solutions tailored for edge computing that efficiently manage data upload, synchronization, and bandwidth utilization, ensuring optimal performance in edge environments. Smart Network Handling Implement intelligent disconnect/reconnect logic that enables applications to handle network disruptions gracefully. This ensures uninterrupted operation and minimizes the impact of transient network issues. If you choose to cloud-enable your application, you must consider cloud unavailability. Infrastructure Capability Differences between Kubernetes Environments Application developers must be aware of the inherited advertised capabilities of differing cloud and edge environments which are often not homogenous. Taking an application from Dev/Test environment to a different Production environment typically requires additional deployment customization. Conclusion In the landscape of containerized applications across Kubernetes, achieving portability across the ecosystem while leveraging cloud object storage and local persistence is a multifaceted challenge. By understanding and addressing the specific challenges related to high availability, shared filesystems, data upload, and network handling, organizations can pave the way for a more efficient and resilient containerized app deployment. As the industry continues to evolve, staying up to date on emerging solutions and best practices is essential for navigating the complexities of Kubernetes and ensuring a portable and robust application ecosystem. Check back shortly for a follow-on blog post talking about how you can build deployments that address some of these challenges.3.4KViews2likes0CommentsBuild, deploy, and govern sovereign AI with Foundry Local on Azure Local
Not every AI workload can run in the cloud. For many of our customers, data needs to stay within defined boundaries, connectivity may be limited or absent, and latency, governance, and auditability are non-negotiable. With Foundry Local on Azure Local, you can use the same model catalog, developer workflows, and governance capabilities you know from Azure, while running AI entirely within your own environment where your data resides. Foundry Local provides the model catalog and developer experience. Azure Local provides the customer-managed infrastructure. Azure Arc provides unified policy, governance, and lifecycle management across cloud and local environments. This gives developers a consistent way to build, deploy, and operate AI. The same az commands, the same model catalog, the same Arc policies, all running on hardware you control. Expansion of Foundry Local on Azure Local We're expanding the Foundry Local model offering on Azure Local, with support for multi-node deployments and new agents and tools that run locally, in preview. Deploy and run AI models locally. Run models with Foundry Local in customer-managed environments on Azure Local, across sovereign, private, and edge scenarios, including fully disconnected operation. Choose from a flexible, high-performance model catalog. Access proprietary and community models through Foundry Local, now expanded with vLLM-optimized models alongside ONNX-based offerings. You explore and deploy through the same catalog API experience, then operate locally on Azure Local. Build for production realities. Bring governance, identity, and auditability into your applications while keeping execution inside your controlled boundary. See what’s new in Foundry Local on Azure Local in the Tech Community blog. From intelligence to action: agents and tools inside the enterprise boundary Most production AI use cases need two things: grounded answers and the ability to act on them, without sending data outside the environment. Here's how we're enabling that locally. Preview: Agentic retrieval with Foundry Local: Ground agents in enterprise data using retrieval-augmented generation across local Microsoft 365 services, including Exchange and SharePoint. Read the Tech Community blog to learn more. Preview: Agents and tools with Foundry Local: Build AI systems that reason, retrieve information, and take action within customer-controlled environments. Learn more. Preview: Developer acceleration templates: Jump-start local AI application development with new Foundry solution templates, including local chat experiences and video agents, powered by Azure AI Video Indexer. Read the Tech Community to learn more. GitHub Enterprise Local: Now available in public preview Sovereign AI is also about how systems are built and secured, not just where they run. With GitHub Enterprise Local on Azure Local, you can bring your full software development lifecycle on-premises: Source control and repositories CI/CD pipelines Security and DevSecOps workflows GitHub Enterprise Local deploys entirely within customer-owned infrastructure, so teams get the developer tools they expect without compromising on data residency or operational control. This extends modern DevSecOps practice into sovereign environments and pairs naturally with the AI development workflows above: build, secure, and ship your AI applications within the same boundary where they run. Read the tech community blog to learn more about GitHub Enterprise Local and how to join the preview. Accelerating High-performance AI at the Edge with NVIDIA We are expanding our collaboration with NVIDIA to deliver high-performance AI capabilities directly at the edge. At Build, we are bringing: Azure Local and Foundry Local on NVIDIA-powered GPUs, including NVIDIA RTX PRO 6000 Blackwell Server Edition, with expanded GPU support coming soon Integration with Nemotron models, optimized for enterprise performance A scalable foundation for data-intensive, low-latency workloads This partnership ensures that organizations can run advanced AI workloads where data is generated - without dependency on centralized cloud infrastructure. Hardware options: AI factory configurations are available now in the catalog Alongside our hardware partners, we’re bringing integrated solutions to customers building AI within sovereign environments. The Azure Local hardware catalog now includes AI factory configurations from our OEM partners, including NVIDIA-certified 8xH100 systems, with options from DataON, Dell, HPE, and Lenovo. These configurations are sized for the performance that model serving and agentic workloads require on customer-managed infrastructure. Together with Microsoft, we are advancing sovereign AI by bringing the open NVIDIA Nemotron model family to Microsoft Foundry Local on Azure Local. This collaboration gives organizations a production-ready AI platform that enables them to deploy AI where their data resides while maintaining the governance, control, and performance needed to scale AI across the enterprise.” Kari Briski, VP Generative AI Software Products, NVIDIA ”Sovereign AI is becoming increasingly important for governments, regulated industries, and enterprises that want to use AI while maintaining control of their data, location, and operations. Lenovo’s ThinkAgile MX Series delivers trusted, enterprise-grade infrastructure with global deployment expertise to help customers run AI wherever their data resides. Co-engineered with Foundry Local and Azure Local, this solution provides an optimized platform to deploy, run, and scale AI locally with greater simplicity, consistency, and control, while helping meet strict data residency, security, and compliance requirements." Scott Patti - VP Infrastructure Solutions Group (ISG), Lenovo From AI models to trusted, mission-critical systems: what this unlocks for developers and operators AI is evolving from systems that answer questions to systems that plan, reason, and take action across workloads. These capabilities move AI from a cloud-only assumption to something you can deploy where sensitive work actually happens, with governance and operational controls intact. For our customers, this means you can now: Keep data, identities, and audit trails inside your sovereign boundary. Run AI inference and agentic workloads in connected, intermittently connected, or fully disconnected modes. Apply consistent policy and governance across cloud and local environments through Azure Arc. Use the same Foundry catalog and developer experience you already know, on infrastructure you own. Build, secure, and ship your AI applications with GitHub Enterprise Local, keeping source control, CI/CD, and DevSecOps workflows inside the same sovereign boundary. Resources Join us at Build OD837 Shipping physical AI to the edge with Azure Local and Foundry Local https://github.com/microsoft/build26-OD837 OD839 Foundry Local: AI solutions for industrial and sovereign needs https://github.com/microsoft/build26-OD839 LTG425 Expanding horizons: Foundry Local for devices and on-prem https://build.microsoft.com/en-US/sessions/LTG425 Request to join the Foundry Local on Azure Local preview Hands-on walkthrough: Your first model deployment on Foundry Local on Azure Local: from catalog to inference in 10 minutes | Microsoft Community Hub Read our Tech Community blogs: Foundry Local announcing multi-node and vLLM support Agentic Retrival with Foundry Local blog: https://aka.ms/AgentsAndToolsBuildBlog2026 Code sample / model catalog blog: https://aka.ms/foundry-local-model-catalog-blog For more details on the expanded capabilities of Foundry Local for highly secure environments, contact your Microsoft account team Discover Microsoft Sovereign Cloud Explore product documentation at: Foundry Local models on Azure Local: https://aka.ms/FoundryLocalonAzureLocal_documentation Local Agentic retrieval with Foundry Local: https://aka.ms/edge-agentic-retrieval-docs2KViews0likes1CommentLaunching the Arc Jumpstart Newsletter: October 2024 Edition
We are excited to kick off this monthly newsletter, where you can get the latest updates on everything happening in the Arc Jumpstart realm. Whether you are new to the community or a regular Jumpstart contributor, this newsletter will keep you informed about new releases, key events, and opportunities to get involved in within the Azure Adaptive Cloud ecosystem. Check back each month for new ways to connect, share your experiences, and learn from others in the Adaptive Cloud community.1.9KViews3likes0Comments