best practices
1799 TopicsA Practical RCA Method for Azure SQL: Separating Evidence, Correlation and Root Cause
CPU hit 100%. You scaled the database. The problem went away. You still haven't proved that CPU was the root cause. We see RCAs written this way all the time, and it's easy to understand why. There's pressure to explain what happened, and a clear story feels better than an open question. But an RCA built on correlation can send a team in the wrong direction. You end up paying for capacity you don't need while the real cause waits for the next incident. Here's the method we use to keep evidence, correlation and conclusions apart. What an RCA should answer A useful RCA answers four questions: What happened? Symptoms and impact, with exact times. Why did it happen? The cause, backed by evidence. What stopped it? The mitigation. What are we still unsure about? The limits of the evidence. Most weak RCAs answer the first and third questions well and then treat the third as if it were the second. The framework Observation → Correlation → Hypothesis → Validation → Conclusion Step What it means Example Observation Something you measured directly "CPU reached 95% at 09:00 UTC" Correlation Two observations happened close together "Login failures started two minutes later" Hypothesis A possible explanation you can test "High CPU caused the failover" Validation Evidence that supports or rules out the hypothesis "Comparable CPU peaks last week caused no failover" Conclusion What the validated evidence allows you to say "CPU is not established as the cause" The step that gets skipped most often is validation, and it's the one that matters most. A worked example (synthetic) Here's an invented incident on a fictional database, SalesDB: 09:00 UTC CPU rises to 95% 09:02 UTC Login failures begin (error 40613) 09:04 UTC Database fails over to another replica 09:05 UTC Connections recover The first draft of the RCA practically writes itself: "High CPU caused the failover." Before you accept that, ask: Did CPU actually reach the limit? 95% is high, but it isn't exhaustion. Were worker or session limits reached? Check max_worker_percent and max_session_percent in sys.dm_db_resource_stats. Was memory under pressure? Was the failover triggered independently? For example, by planned maintenance. Check Resource Health and Service Health. What happened during earlier high-CPU periods? If CPU reached 95% three times last week with no failover, CPU alone doesn't explain this one. Did other databases on similar workloads see the same thing? Now classify every statement: Statement Classification CPU reached 95% Confirmed Login failures occurred Confirmed The events overlapped in time Confirmed CPU caused the failover Unconfirmed hypothesis The failover restored connectivity Confirmed The failover proves the old replica was faulty Not established That table is more honest than the first draft, and more useful too. It shows the reader exactly what's known and what still needs work. Habits that make RCAs better Use UTC everywhere. Mixed time zones are the most common reason two sets of logs "don't line up." Convert everything before you compare anything. Define the impact first. Who was affected, how badly, and for how long? "Some logins failed between 09:02 and 09:05" is far more useful than "the database was down." Keep observations and interpretation apart. "Error 40613 was returned" is an observation. "The database was unavailable because of load" is an interpretation. Write them in separate places. Consider more than one explanation. If you only have one hypothesis, you'll find evidence for it. Write down at least two, then look for evidence that would rule each one out. Compare against healthy periods. A metric only means something next to its baseline. High CPU during an incident matters less if CPU is just as high every Monday morning. Compare against unaffected resources. If two databases had the same load and only one failed, load probably isn't the whole story. Don't assume the fix explains the cause. Restarts, failovers and scale operations change many things at once: the compute node, connections, caches and sometimes the physical host. When the problem stops after one of them, you know something in that bundle mattered. You don't know which part. When "root cause unknown" is the right answer Sometimes the evidence doesn't support a definite cause. Saying so isn't failure. It's accuracy. A good RCA with an open cause still gives the reader something to act on: What was ruled out, and how. Which hypotheses remain, ranked by likelihood. What evidence would settle it next time, such as finer-grained monitoring, connection-level logging or a synthetic probe. What resilience work reduces the impact whatever the cause turns out to be, such as retry logic or alerting. A simple RCA template 1. Summary – One paragraph: what happened, the impact, the current status 2. Impact – Who/what was affected, start and end times in UTC 3. Timeline – Observations only, in UTC 4. Analysis – Hypotheses considered, evidence for and against each 5. Root cause – What the evidence supports (or "not established") 6. Mitigation – What restored service 7. Limitations – What the evidence could not show 8. Next actions – Prevention, detection, and evidence gaps to close Summary A good RCA tells you what the evidence shows, and also what it doesn't let you claim. "We restarted it and the problem went away" describes a mitigation, not automatically a root cause. Keep those two apart, and your RCAs become something people can trust and act on.Designing a Reliable AI Workflow on Azure: Production Lessons from Translation Automation
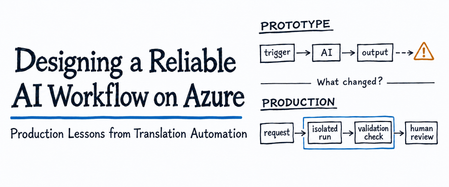
Many teams can build an AI prototype that works. A trigger arrives, the model produces a plausible response, and the demo ends with the expected file or message. But what happens when that prototype becomes a workflow that other people depend on? Imagine an AI-assisted process that prepares a recurring report. The notification arrives on time, but the report is blank. On another run, the research is useful but lands in the wrong template. A retry then replaces a version that someone had already reviewed. In each case, the model may have responded normally while the application still delivered the wrong operational result. I encountered versions of these failures while operating Localizeflow, an independent translation orchestration project built around Co-op Translator. A translation could appear to finish without producing a complete, reviewable document. A credential failure could look like a missing result. Overlapping requests could place too much work and state inside one long-running worker. Those experiences changed the question I ask after an AI prototype succeeds. The next question is not simply, “Can the model do the task?” It is, “Can the workflow record the request, survive failure, validate the final artifact, and return something another person can trust?” This article uses translation as one worked example, but the lessons apply to any long-running AI workflow that produces a report, document, batch, or repository change. We will follow three failure classes from prototype to production, then add one operating requirement that makes the workflow's progress visible. A working prototype proves only one thing The translation prototype was deliberately simple. A trigger started the process, the process downloaded the source, called the model, wrote the translated files, and uploaded the result. It proved that the model could translate a document. It did not prove that the workflow had used the intended input revision, preserved a partial result, rejected stale output, or left enough evidence to explain a failure. It also did not prove that the resulting document was ready for someone else to use. That distinction became visible in public repository work. MCP for Beginners pull request #926 shows an incomplete translation batch that stopped with two of 19 translation tasks complete and was closed without merge. The screen records the observable state, but it does not establish the root cause or prove that every generated file was blank. Figure 1. Public failure evidence from MCP for Beginners pull request #926. The Localizeflow progress record showed two of 19 translation tasks complete, and the pull request was closed without merge. This screen establishes the observable outcome, not the root cause or the contents of every generated file. By contrast, AI Agents for Beginners pull request #790 connects a completed translation update to a visible diff, review findings, follow-up fixes, and a repository decision. The Localizeflow bot opened the update, and the repository merged it on October 30, 2026. The merge proves that the repository accepted the change. It does not prove translation accuracy, time saved, or a separate deployment. We will return to this accepted result at the end. The two records illustrate the central distinction in this article: A model response, a completed process, a delivered artifact, and an accepted result are different outcomes. Translation exposed that distinction, but it is not unique to translation. A report generator can return text while omitting a required section. A post-processor can damage a valid response. An uploader can publish the wrong revision. A retry can replace work that a person had already approved. What the workflow had to add The production-oriented design starts by treating each request as durable work rather than a long-running model call. Figure 2 applies that pattern to an independent translation example. The sections that follow explain the responsibility at each handoff. Figure 2. Independent reference architecture for hosting Co-op Translator on Azure. A GitHub documentation change enters an orchestrator hosted in Azure Container Apps, which records the request and starts an Azure Container Apps Job. The job runs Co-op Translator and calls Azure OpenAI to produce a candidate translation. Deterministic checks gate the pull request, and a person decides whether to merge it. This is an independent reference design, not a description of an existing project's internal implementation. Note: Azure Container Apps is suited to service-style workloads such as HTTP APIs, while Container Apps Jobs runs tasks that start, perform a finite unit of work, and stop. In this design, the Container App hosts the request-facing API and orchestrator, while each accepted translation attempt runs as a separate Job. The container app receives the GitHub change, validates the scope, records the logical job, and decides when an attempt may start. The job runs Co-op Translator, calls the deployed Azure OpenAI model, writes an attempt-scoped artifact, reports its outcome, and exits. Azure OpenAI performs model inference, but it does not own workflow state, validation policy, or merge authority. First, accept the work. The application checks that the caller, input, scope, and policy are allowed. In this worked example, the accepted request connects a GitHub documentation change to the repository, source revision, file scope, and target language. In a report workflow, it may mean the data source, reporting period, template, and recipient. Next, record and orchestrate it. The orchestrator hosted in Azure Container Apps saves the logical job before starting execution. The record connects the request to the input revision, policy version, attempt history, and eventual decision. If the process stops, the work still has an identity and a state. In this design, the application layer detects work, records the logical job, and coordinates bounded executions. Then, execute a bounded attempt. The orchestrator remains the request-facing service boundary in Azure Container Apps while an Azure Container Apps Job runs Co-op Translator for the finite unit of work. The worker receives the recorded job ID, writes to an attempt-specific workspace, and reports its outcome. Finally, validate and decide. The job's output remains a candidate. Application checks establish whether the artifact is complete, current, and within the allowed scope. Only then does the application prepare a reviewable change. In this worked example, that change is a pull request, and a person decides whether to merge it. The model call remains important, but it is no longer asked to carry workflow state, validation policy, and delivery authority by itself. What changes after the prototype works? Starting with the prototype was the right decision. A first version should answer the smallest useful question: can the model perform the task on one known input? Building job records, isolated workers, recovery logic, validation rules, and monitoring before that question is answered can become overengineering. The mistake is not starting simple. It is treating the simple version as production-ready. Reliability features should be added when the workflow crosses a real boundary: more inputs, overlapping requests, external dependencies, consequential delivery, or users who need to understand and recover from failure. The original prototype connected a trigger directly to a model call and treated the returned output as success. That was enough to prove the basic capability. Most state lived inside the process, however, so a stopped run or incomplete artifact left little durable evidence. The production-oriented workflow keeps the model call but changes the boundaries around it. The trigger records a job, each execution becomes an attempt, generated files remain separate from accepted state, and a retry cannot silently erase the failed attempt. Start with the simplest workflow that can prove the task. Add complexity only when a real failure boundary justifies it. Figure 3. The model call remains. Production adds durable state, bounded execution, artifact checks, and human review. This change matters because real operation adds failure surfaces that a successful demo does not exercise. A trigger can arrive twice. A credential can be invalid. The source can change while work is running. A model can return only part of a document. Application code can damage a valid response. A validator can reject acceptable variation. An external system can complete an action while the workflow loses the response. While writing this article, I went back through every Co-op Translator release, from v0.2.1 to v0.23.3. Reading them in order felt a little like replaying the project from the first prototype to the workflow it became. I had forgotten how many of the harder problems appeared only after the model was already returning translations. Credentials failed, chunks were reassembled incorrectly, retries needed boundaries, and valid output could still be rejected. Looking back helped me choose the cases below. I wanted to share the problems that became visible only after the prototype worked, because they are the kinds of problems other teams may meet when a proof of concept becomes an automation people depend on. Three failures changed the design most. Lesson 1: A successful model call can still produce a failed artifact In early runs, a translation could appear to finish while omitting source lines or changing protected Markdown structure. The provider request had completed, but the document was not complete enough to review. Co-op Translator pull request #568 records a reproducible version of this behavior. Azure OpenAI returned HTTP 200 with finish_reason='stop' , but a response could still omit source lines or lose, duplicate, or reorder protected Markdown placeholders. The affected responses were below the provider token limit and did not report a length or content-filter stop. The recovery logic therefore stopped treating a normal provider completion as proof of a valid artifact. It validated each translated chunk, preserved the verified prefix, and retried only the missing or damaged portion when possible. I described how that review path evolved, including marker checks, bounded retries, preserved human edits, and recorded failures, in What production taught us about reviewing AI translations. The model is not the only place where an artifact can break. Issue #505 showed a translated Markdown table that rendered correctly for the first four rows and then collapsed into unformatted text. Figure 4. Cropped evidence from Co-op Translator issue #505. Application reassembly inserted an extra newline at the chunk boundary, so the final Markdown table broke after row 03 even though translated chunks were available. Pull request #508 documents the fix. This is not a model-quality failure. The one-line repair was conceptually simple: join the translated chunks without injecting a new newline. The lesson was larger. Valid model outputs can become an invalid document after the response, so validation must inspect the final assembled artifact. The earlier article Fixing Broken Markdown in AI Translation: Hardening a Production Pipeline examines the wider class of structural failures, including damaged code fences, links, lists, images, anchors, and CJK formatting. Guardrails can also be wrong. Pull request #581 documents a valid Italian translation that preserved the protected structure but moved ordinary prose naturally. The validator retried the valid result and eventually failed, so the fix narrowed the invariant to the structure that actually needed protection. These cases led to one operating rule: treat every generated response as a candidate. Keep the logical job, attempt, candidate, and accepted result separate. Pull request #493 applied the same principle by preserving the last usable translation when a replacement failed. Where policy permits, quarantine a rejected candidate with its validation report. Where the content cannot be retained, preserve safe structural diagnostics such as the file, attempt ID, failed check, and expected and actual counts. Do not copy sensitive source content into routine logs. The same rule applies to a report workflow. A report with a missing required section is not a completed report, even if the model returned a normal response. A template populated with damaged fields is not safe to deliver, even if the original content was correct. Try this before production: remove one required section or protected marker from an otherwise normal candidate. The attempt should fail without replacing the previous accepted result, and the failure record should explain which check rejected it. Lesson 2: A missing result may be a dependency failure Another failure occurred before translation quality could matter. A credential problem prevented the provider from producing a usable response. In the early workflow, the expected artifact simply did not appear, while the underlying authentication problem surfaced only as a generic process failure. A blind retry would repeat a request that could not succeed. The workflow needed to distinguish “the model produced a bad candidate” from “a required dependency was unavailable.” Co-op Translator pull request #211 added a lightweight connectivity check that exercises the real provider data path before translation begins. It checks the endpoint, API version, credential, and deployment. Authentication failures such as 401 or 403 stop the run with actionable feedback instead of appearing after a long batch. Figure 5. Authentication failure becomes failed with a stable reason and does not publish an empty artifact. After repair, the workflow starts a new attempt under the same logical job. A startup check is valuable, but it cannot guarantee that a token or credential will remain valid throughout a long execution. A 401 or 403 received during execution should enter the same stable failure category. The job can become failed with a reason such as provider_authentication , while an operator repairs the endpoint, permission, or credential and starts a new attempt without losing the earlier history. The same pattern applies to retrieval indexes, databases, document stores, and delivery APIs. Report the dependency failure instead of allowing it to masquerade as missing or low-quality AI output. For Azure resources that support Microsoft Entra authentication, managed identities reduce the secrets that an application must store and rotate. Any remaining credentials belong in the execution environment or a secret store, never in prompts, repository content, or job payloads. Try this before production: use an invalid endpoint or unavailable credential. The workflow should stop before expensive work, record a stable dependency reason, and publish no empty artifact. After repair, the new attempt should remain connected to the original request. Lesson 3: Long-running work needs a bounded execution The first hosting path ran translation work through the same long-lived Container App process that served the application. When requests overlapped, the process had to coordinate more than one workspace, more than one translation state, and more memory-intensive work at the same time. Cleanup and failure isolation became harder to reason about. This was not evidence that Azure Container Apps inherently leaks memory. Container Apps can scale continuously available services horizontally. The problem was the execution model: a translation batch has a beginning, an end, and an artifact, while the worker behaved like a continuously running service. Figure 6. Keep the continuously available API in Azure Container Apps and give each finite attempt its own Azure Container Apps Job execution. Retries, cleanup, and admission control still require application policy. Microsoft describes a container app as a continuously running service and a Container Apps Job as a task that starts, performs a finite unit of work, and stops. That made the split clearer. The API and dispatcher could remain in a container app; Figure 2 groups those continuously available application responsibilities as the orchestrator. Each accepted unit of work could start a separate job execution linked to the logical job and attempt IDs. The job definition supplies the container image, resource allocation, timeout, and retry policy. Each execution has its own finite process lifetime, execution identity, status, logs, and an attempt-scoped workspace when the application creates one. A finite process lifetime does not remove the need to control memory or clean temporary files, but it limits how far one failed attempt can spread. Data written to persistent storage still needs an explicit retention and cleanup policy. Bound cost and permissions the same way: cap model usage per attempt, and give the dispatcher, worker, validator, and publisher only the access each one needs. The dispatcher can admit independent requests up to an application-defined limit and deliberately serialize work that might conflict, such as simultaneous updates to the same repository. Container Apps Jobs parallelism controls replicas within one execution. It does not replace request-level admission control. The application should not rely on external side effects happening exactly once. A retry, restart, or lost response can still occur. Attempt ownership, idempotent state transitions, and reconciliation of an existing pull request or downstream record remain application responsibilities. Try this before production: submit two independent requests together. Each should retain its own execution ID, workspace, result, logs, and retry path. Then submit two requests that would update the same downstream resource and confirm that the dispatcher applies the intended serialization policy. Then test the handoffs that fail quietly: submit the same request twice, change the source while an attempt is running, and lose the response after the downstream record is created. The recorded job, input revision, and current attempt owner should lead the workflow to one logical job, no stale output, and no duplicated downstream record. Lesson 4: Make progress visible before the final artifact appears A long-running AI workflow should not force a developer to infer its health from whether a file eventually appears. Without searching raw console logs, a person should be able to answer four questions: Was my request accepted? Is the work still advancing? Where did it stop? What result is waiting for review? The workflow should expose the current attempt, how many units are running, complete, queued, or failed, when progress last changed, and whether a reviewable artifact is ready. Those answers come from a small set of job states. Status should describe evidence, not optimism, so each state names what must be on record before a job can enter it. The following is a reference state model for this design, not a description of Localizeflow's current internal state machine. Here, accepted means the orchestrator has durably recorded the request and accepted it for processing. It does not mean that execution has completed. State What it means Evidence on record accepted The request is stored for processing. Request ID, input revision, scope, policy running A current attempt owns the job. Attempt ID, ownership expiry validating An artifact exists and checks are running. Candidate artifact, checks run so far ready_for_review Validation passed and a reviewable change is available. Validation result, artifact diff failed The latest attempt ended without a valid artifact. Failing stage, stable reason, safe diagnostics superseded A newer request or input revision replaced this job. Link to the replacement approved A person accepted the reviewable change. Reviewer identity, downstream decision record rejected A person declined the reviewable change. Reviewer identity, recorded reason approved and rejected come from the downstream decision, not from the workflow finishing. For failed , name the stage, such as dependency, generation, assembly, validation, or delivery, so the workflow never retries blindly. The Localizeflow progress records in the public pull requests make that distinction concrete. The failed record in Figure 1 exposes partial completion and failed jobs instead of presenting an empty destination as the only symptom. The completed record shown at the end exposes a different state using the same vocabulary. A developer can see that the automation is advancing, stopped, or ready for the next decision without treating a model response as the only signal. Progress is not quality. 19 / 19 completed means that the execution units reported completion; it does not mean every translation is accurate. Operational visibility must connect to artifact validation, a reviewable diff, and the final human decision. The dashboard explains what the workflow is doing. The checks and reviewer decide whether its result is acceptable. Whether the workflow saves time or improves quality needs its own measurements: review time, retries, dependency failures, superseded results, human corrections, and the model, container, and storage resources each run consumes. Collect them before claiming improvement. Try this before production: start a multi-unit request, then fail one worker or make a dependency unavailable. The progress view should stop advancing, identify the failed or blocked unit, preserve the earlier attempt, and lead an operator to the relevant evidence. After a retry, the new attempt should be visible without erasing the old one. Build for the moment after the demo The prototype answered whether a model could perform one task. Production asked a harder question: could the surrounding application explain failure, preserve usable work, reject unsafe output, and return something a person could trust? Translation revealed three failure classes, but the design lesson is broader. A normal model response can still produce a failed artifact. A missing result can be a dependency problem. A finite unit of work becomes easier to isolate when its process lifetime is finite too. Most reliability concerns in an AI workflow are familiar automation concerns: state, retries, dependencies, concurrency, and delivery. What AI adds is a probabilistic boundary. Even when the model call succeeds, its response may be incomplete, structurally invalid, or simply unsuitable for the intended use. A reliable design must therefore validate the artifact, preserve rejected candidates safely, and keep consequential acceptance outside the model. An AI workflow must handle ordinary automation failures and also assume that a successful model call can produce an unacceptable result. A reliable AI workflow connects the accepted request, input version, execution attempt, candidate artifact, validation result, and human decision. When a run fails or the input changes, that chain should explain what happened and what should happen next. Figure 7. The public Localizeflow run record linked from AI Agents for Beginners pull request #790 shows the overall state, all 19 work units complete, no active work, no recovery attempts, and no terminal failures. These fields make execution observable. Review findings still led to follow-up changes before the repository merged the pull request on October 30, 2026. Neither completed progress nor the merge alone proves translation accuracy, time saved, or deployment. That is the purpose of the progress view: make the AI and automation workflow inspectable while it is running, then connect completion to validation and a visible repository decision. A green progress bar is useful evidence, but it becomes trustworthy only as part of that larger chain. Start with one input, one expected artifact, and one downstream decision: in the translation example, one document, one language, and one test repository. Prove that one valid run stops at ready_for_review and waits for a person, then widen the scope. Track the work, preserve the evidence, validate the result, and return something a person can inspect.
Speed dial in new Teams call history layout
Hello all, I have a query which I am hoping someone can help me out with. The new Teams desktop client layout has launched, but I am experiencing an issue with the layout of the call history section. Previously, speed dials that I add myself within the client would be ordered alphabetically, as well as being able to create my personal groups for the contacts in my speed dial. In the new layout, both of these features appear to be missing. Am I missing something here, or is anyone else noticing these two features are no longer available in the new layout?15KViews5likes13Comments
Teams co-organizers can’t access meeting engagement data: a gap for centrally managed meetings
Hi everyone, We’ve run into what seems to be a gap in the Microsoft Teams co-organizer model while working on moving our enterprise virtual learning delivery from a dedicated virtual-classroom platform to Teams. Our requirement is fairly straightforward: we run a large number of centrally administered learning sessions, with multiple facilitators who need to be able to step in and deliver a session when required. The model we’d ideally use is: A shared calendar/mailbox for central visibility and administration. The relevant facilitator group automatically added as co-organizers. Facilitators can run the session, manage participants, breakout rooms, recordings, etc. Co-organizers can access the standard attendance report after the session. This gets us almost everything we need. The gap is the richer meeting engagement data. Teams provides engagement information such as reactions, raised hands, camera usage and other engagement measures, but this appears to remain restricted to the meeting organizer, rather than being available to co-organizers. That creates an awkward problem for centrally administered meeting scenarios. A co-organizer can be trusted to run the meeting and access its attendance reporting, but not access all of the post-meeting engagement reporting. It becomes particularly problematic if a shared mailbox is the meeting organizer, because there may be no actual person able to retrieve that organizer-only data. What I’d love to see I’d like Microsoft to allow explicitly assigned co-organizers to access the same post-meeting engagement data as the organizer. I’ve submitted this as a feature request here, which I'd love for you to vote for at the link below please if you think it would help you too: https://feedbackportal.microsoft.com/feedback/idea/28182268-f7d9-f111-bda3-6045bd78a526 I’d be really interested to hear: Is anyone else running centrally managed Teams meetings at scale and hitting this same limitation? Have you found another supported way of retrieving this engagement data? If this would be useful for your organization too, would you consider voting/commenting on the feature request? It feels like a relatively small permissions gap in an otherwise very capable co-organizer model, but closing it would make a big difference for centrally managed training, events and similar enterprise scenarios. Thanks!164Views0likes1CommentMaking Azure Container Registry Activity Visible at Scale
Learn More Use Grafana dashboards in Azure Container Registry Monitor Azure Container Registry Azure Container Registry (ACR) now publishes two new metrics: Transactions and Data Transfer. For the first time, you can see which operations your registry serves, which region serves them, and how much data (egress) they move, for each registry and each of its geo-replicas. ACR often serves as a shared distribution point for containerized workloads. Build systems push container images and other artifacts, Kubernetes clusters pull images during deployments, and security and lifecycle tools scan artifacts throughout the day. As those environments grow, high-level signals such as a total pull count or storage used can tell you that activity changed, but not why. Transactions and Data Transfer fill that gap, so you can explain a traffic spike, catch a failing or throttled pipeline, and see where your data goes. A customer-facing metric is a stream of data points, attributed to one resource, that you can chart, split, and alert on in Azure Monitor. Building these metrics meant producing data points for very high-throughput signals, counting them accurately, attributing each one to the right registry in every region, and not exhausting the metrics system underneath. In this post, we'll cover what these metrics show you, what it took to deliver them at scale, and the sharded design that made it possible. What you couldn't see before Before this work, push and pull counts, alongside storage used, were the only registry traffic metrics we published. They showed that activity happened, but not what kind of operations drove it, whether each operation succeeded, or where it was served. Take a sudden jump in pulls: Before: total pull count is up, with no way to tell which geo-replication drove the traffic. Now: the extra requests are blob downloads in one geo-replication region, many of them Throttled, while Data Transfer from that geo-replication stays flat. Those gaps matter most when traffic changes. An increase may come from a deployment, a retry loop, metadata polling, a regional workload shift, or larger image layers, and each looks different underneath: a surge in manifest and blob reads, repeated errors or throttled responses, a steady stream of tag and listing calls, traffic moving between replicas, or more bytes per pull without more requests. To tell them apart, you need to know which operations are changing, how much artifact data is moving, where requests are being served, and whether the pattern matches the workload you intended to run. Push and pull counts summarize outcomes. Transactions and Data Transfer describe behavior, and describing behavior takes far more data. Why scale is the hard part These signals are high throughput by nature, because every counted request becomes its own data point: a single sampled registry's activity can exceed 100,000 transactions and hundreds of gigabytes of data transferred (egress) in one hour. All of those data points land in internal metrics accounts, and each account has a finite budget for how much data it can take in and process. Our previous emission strategy sent metrics to a single backing account. That worked for the metrics we already had but signals this large would eventually exhaust that account's quota. Scale wasn't an optimization we could add later. It was a prerequisite for launching these metrics at all. Sharding the metrics without splitting the view The answer to the capacity problem is to stop relying on one account. Instead, we shard our metrics across multiple internal metrics accounts. A shard is one slice of a larger system that holds part of the data and has its own capacity. Each shard has its own headroom, which we monitor and manage independently, so no single account caps growth. Geo-replication complicates this. A geo-replicated registry is served from many regions at once, and a single request can pass through more than one component: one answering API calls, another serving blob bytes, another delivering webhooks. However capacity is divided, every data point from every region and every component still has to be attributed to the registry it belongs to. Otherwise, you'd see your registry's activity in pieces and have to stitch it back together yourself. Activity from every geo-replication and component is attributed to its registry and counted once. Each registry's metrics land on one shard, different registries are spread across shards, and you still query one registry in the portal. When you open the Azure portal or query Azure Monitor, you query your registry. You never see or choose where that information is coming from. Counting each request once. Multi-hop requests raise the same question for accuracy. One blob pull can touch more than one component: the registry may answer with a redirect, and a different component serves the bytes. Each step is counted once, by the component that handled it: the redirect appears as its own Redirect transaction, the download as a Success transaction, and the bytes appear once in Data Transfer. Failed requests count as Transactions, so errors stay visible, but not as Data Transfer, because no bytes were delivered. Every emitting component uses the same ApiName and ResponseType vocabulary, and we verify that each counted request produces exactly one data point. Each step is counted once, by the component that handled it, and bytes count only when they're served. The result is one view of each registry, across every region and component, with each step of a request counted exactly once. What customers get Both metrics appear where you already look: Azure portal > your registry > Monitoring > Metrics, and through Azure Monitor for programmatic queries and alerts. Transactions counts registry API operations, with three dimensions: ApiName: the registry operation, such as manifest, tag, and blob operations, referrer and catalog listings, token requests, etc. ResponseType: Success, Redirect, ClientErrorUnauthorized, ClientErrorNotFound, Throttled, etc. Region: the geo-replication of the registry that served the request Data Transfer reports the total outbound data your registry transfers, in bytes, when it serves content such as blob and manifest downloads. You can split it by ApiName and Region. ApiName: the flow that moved the data, such as layer downloads, manifest downloads, image imports, replicating content to your geo-replicas, etc. Region: the geo-replication of the registry that served the request A typical investigation takes a few steps. Open Monitoring > Metrics, choose Transactions, and split by ResponseType to see successes, redirects, throttling, and errors at a glance. Switch the split to Region to see which geo-replication is serving the change. Then select New alert rule from the same chart. For example, filter to Throttled and alert when the total over 5 minutes exceeds a threshold you choose. To understand egress by region, chart Data Transfer over time and split it by Region to see how much data each geo-replication serves and whether that data transfer traffic is growing. Match the view to what you suspect: A deployment or metadata polling: split Transactions by ApiName to see whether blob and manifest reads or tag and listing calls are driving the change. A retry loop: filter ResponseType to Throttled, ClientErrorUnauthorized, or ServerErrorOther. A regional workload shift: split metric by Region. Larger image layers: compare the two metrics. Data Transfer rising while Transactions stays flat points to bigger artifacts, not more requests. Transactions split by ResponseType: successes, redirects, throttling, and errors at a glance. Built for the metrics that come next Transactions and Data Transfer run on the same sharded metrics path, and we built it so future metrics onboard onto that same path instead of competing for one account's capacity. The design scales with customer workloads and with the metrics we add next, without a redesign. Conclusion Transactions and Data Transfer give you a direct view of what your registry is doing: which operations it serves, whether they succeed, where they're served, and how much data moves. Sharding is how we delivered that view at scale without giving up accuracy, and it's the path future metrics will onboard onto. A few lessons generalize beyond metrics: Design for scale before you launch a high-throughput signal, not after. Attribute by resource, not by location. Activity spread across many regions still needs one source of truth per resource. Keep the complexity on the service side. Customers query a registry, not a shard, so how we manage capacity can evolve without changing what you query. Get started with Transactions and Data Transfer in Monitor Azure Container Registry and the supported metrics reference for Azure Container Registry.478Views4likes1Comment
News to Know – Volume 3, Edition 11, October 2026
October brings clearer program setup and broader support for organizational-data integration, along with new private-preview opportunities for reporting and Copilot experiences. This edition covers what is available now and gives you an early look at administration, exports, insights, and survey management capabilities planned for the months ahead. New on your Viva Glint platform This section highlights new capabilities now available on your Viva Glint platform this month. Program setup: Clearer required-field indicators. Required fields throughout program setup now have visual indicators, making it easy to tell which fields are optional and which are required. Missed or skipped required fields will also be clearly identified. There have not been any changes to which fields are required and which are optional. Viva Glint Questions setup | Microsoft Learn Viva Glint integration with Microsoft 365 Organizational Data Service is rolling out to General Availability (GA) and will be available to all customers by the end of October. With GA, we are expanding support to a broader range of customer environments, including organizations with multiple Glint instances, MTO/CTS policies, and Microsoft 365 Government Community Cloud Moderate (GCC Moderate).The GA release also introduces several new capabilities, including email notifications, multiple connectors to support phased data ingestion, and Microsoft Purview integration for audit events, making it easier for organizations to manage, monitor, and govern their employee data integration. Coming soon to Viva Glint The following section offers an early look at capabilities coming to Glint in upcoming releases. Multi-attribute report exports for more roles | Private preview in October. Managers, leaders, analysts, and HR business partners in the private preview can export filtered, grouped, cross-dimensional report data for analysis outside Viva Glint. The update expands access beyond administrators and supports more flexible analysis while keeping permissions under administrative control. Viva Glint Multi-Attribute Export – Private Preview Sign-Up form Copilot Results Summarization | Private preview in early November. Results Summarization makes it easier for your managers and leaders to understand, explore, root cause and act on their Viva Glint results and comments. The Microsoft 365 Copilot Chat experience within Viva Glint brings together scores, benchmarks, changes, response rates, drivers, and comment themes for demographic breakdowns and segmented populations in one grounded conversation, so they can ask questions, spot patterns, make comparisons and dig deeper into your results. Join the private preview and help shape the experience through feedback sessions. Sign up here Continuous Engagement self-service administration | Private preview in November. Following additional engineering work, the administration update previously targeted for October is now planned for November. Existing private-preview customers will be able to map eligible workplace metrics to survey questions through a guided setup flow, reducing manual coordination and giving administrators more control over the context managers see with survey results. Comments export with attributes | Private preview planned for November. Private-preview participants will be able to export comments to Excel with selected respondent attributes, preserving the report’s filters and groupings. This will enable deeper analysis of comment themes across employee groups outside Viva Glint, while respecting users’ reporting permissions and applicable confidentiality safeguards. Copilot Highlights with workplace-metric context | Preview in December. Following updated development sequencing, this capability is now targeting December. When Continuous Engagement preview is enabled, Copilot Highlights will add selective workplace-metric callouts when an eligible behavioral signal provides useful context for a survey strength or opportunity, helping leaders identify where deeper investigation may be useful. Survey administration: Bulk removal of participants | Generally available in December. Building on the existing ability to remove participants in groups of 25, administrators will be able to remove closed surveys with no limit using a file upload When users are removed, their survey response will be permanently deleted. Removal events will also be recorded in audit logs, helping teams correct survey populations without relying on support. See our public roadmap for more feature updates. New Thought Leadership The Next Generation of Employee Listening Research Report | Available October 28. Organizations have more ways than ever to hear from employees, but more channels don't automatically lead to better decisions. Our latest research showed that 74% of enterprise listening leaders reported expanding their listening channels, yet only 1 in 3 rated their systems as strong at influencing business decisions and connecting listening data to meaningful outcomes. The report explores how listening teams can move from managing listening activity to building a right-fit system around what the organization needs to understand. The report will be the first release on Glint Labs, a new home for research, frameworks, and resources from the Microsoft People Science team. Look for the launch announcement on Viva Community on October 28. EECC session details In this recent EECC session, we previewed Results Summarization in Viva Glint Copilot Chat, an updated experience that brings survey scores and comment analysis together in a conversational interface. Customers saw how managers and leaders can ask plain-language questions about response rates, strengths, opportunities, trends, benchmarks, demographic differences, and comments, without first building reports or configuring filters. The session included a live product demonstration, an overview of the people-science research and evaluation shaping the experience, and details about the private preview. Participants discussed organizational guidance for AI-supported interpretation and action taking, administrative controls, licensing, confidentiality, presentation templates, language support, and practical preview limitations. Key takeaways from the discussion included: Results Summarization is the first milestone in a broader roadmap that moves from understanding survey findings to drafting, managing, and following up on manager action plans. The preview combines quantitative scores with comment summarization and can dynamically apply filters to answer questions about trends, benchmarks, demographics, and differences between employee groups. People-science guidance is built into the experience to promote accurate, relevant, clear, and calibrated interpretations, including appropriate context for group size, score changes, benchmarks, and correlation versus causation. Existing Viva Glint permissions, confidentiality thresholds, and suppression rules continue to apply; Copilot receives only aggregated results that have passed those protections. Customers emphasized the need for organization-specific guidance, approved action resources, company templates, and more granular administrative controls. These needs are being explored as part of the manager action-taking roadmap. The private preview is planned for participating customers beginning in November, with a recommended small-group rollout and a 30-minute feedback session for selected organizations. General availability is targeted for early next year. The capability supports the languages available in Viva Glint and currently works with the last two closed surveys for ad hoc and recurring programs. During preview, users should work from the Executive Summary report, select benchmarks in the report, use explicit prompts, and begin a new chat when context becomes too complex. If you are not yet a member of the Employee Experience Customer Connection (EECC) but would like to participate in upcoming sessions and gain access to other engaging and valuable Glint and Pulse customer activities, please sign up using the EECC opt-in form.511Views0likes0CommentsWhy Did Our Azure Bill Change? Investigating Cloud Spend with Azure SRE Agent
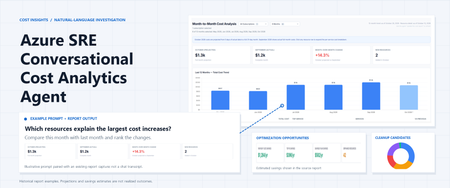
The question after the cost chart The monthly cost review usually starts with a straightforward observation: Azure spending changed. Then come the questions that take the time. Which subscription accounts for the increase? Is it an existing workload getting more expensive, or something that only started generating charges this month? Did a reduction somewhere else hide part of the increase? And which optimization recommendations are worth taking to a workload owner? Azure already has the underlying information. Cost Management provides spending data. Azure Advisor provides optimization recommendations. Resource inventory provides context about what those resources are. The work is connecting those sources into an explanation that someone can check and act on. Conversational Cost Analytics Agent: a solution built around Azure SRE Agent that lets operations and FinOps leads start with a question, investigate cost drivers, identify optimization opportunities, and generate reusable reports. The solution can also generate proactive alerts and scheduled reports. Scope of this post: The repository contains a prototype, an importable dashboard template, reusable skills, and example report screenshots. These demonstrate the reporting approach; they are not evidence of measured customer savings, verified production readiness, or a completed deployment in your environment. The prompts below are examples to try, not a transcript of a measured production investigation. What we built This is a custom cost-investigation workflow on Azure SRE Agent, not a separate billing system or a claim that every feature is available out of the box. The solution brings together three pieces: An analytical skill that describes how to compare spending, calculate resource contributions, identify newly billed resources, and handle incomplete periods. A query-reference skill that records the Cost Management query patterns, response shapes, aggregation rules, and SRE Agent tool mappings used by the dashboard workflow. An HTML Live Report template that presents subscription selection, summary metrics, six-month trends, and expandable resource-level comparisons. The distinction matters. A template determines how findings appear. A skill determines how the agent should investigate. Neither replaces access to the underlying data. The agent still needs scoped permissions, supported tools, and a successful data refresh before the report can represent your subscriptions.' How the investigation works The workflow starts by discovering the subscriptions the agent can access. It then queries Cost Management for historical totals and current- and previous-month resource-level details, aggregates the results, and populates the report template. Source or component Role in the investigation Azure Cost Management Billing-based cost data and historical comparisons Azure Resource Graph Resource inventory and metadata enrichment, not cost data Azure Advisor Optimization recommendations to review alongside spending Reusable agent skills Investigation rules, query patterns, and interpretation guardrails Live Report template Interactive presentation of the refreshed data snapshot How cost data is collected: The agent sends a request to Azure Cost Management to retrieve spending data. The request uses HTTP POST, so the kit runs it through RunAzCliWriteCommands, even though it only reads data. Reading costs does not change resources: This query does not resize, delete, or modify resources. Still, configure permissions and tools carefully to limit what the agent can do. The report shows the most recently refreshed data: Opening the report displays the data collected during its most recent refresh. It does not automatically request updated billing data. Fetching data directly from the report requires a connector: A supported connector gives the report access to a cost-query tool. The report cannot directly use the agent’s built-in CLI tools. You can start without a connector: Use the report with periodically refreshed data, and add a connector later if you need to fetch updates directly from the report. Four questions to explore in the report 1. Where is spending heading? Start with the broad view: The overview brings subscription selection, summary KPIs, previous-month actuals, and an adjustable cost trend into one view. Select the number of months you want to compare, up to 12, and expand any month to explore the services behind the spending changes. Figure 1. Historical prototype snapshot, not current pricing or a verified financial result. The current-month KPI is a projection; the screenshot does not establish that the partial-month trend bar uses the same basis. Reconcile those values and use consistent labels before relying on the comparison. This is also where an apparently simple comparison can become misleading. Ten days of current-month spend and a full previous month are not comparable periods. For an in-progress month, ask for matched month-to-date periods when investigating change. If the report displays a full-month run-rate projection, keep it labeled as a projection. Do not describe it as a Cost Management forecast unless that forecast was actually retrieved. The useful outcome is not just a larger or smaller bar. It is an explicit statement of the period, cost basis, currency, and freshness behind that bar. 2. Which resources explain the change? Once the subscription-level movement is clear, move to the contributors: "Rank the resources driving increases and decreases. Separate newly billed resources from existing resources whose costs changed." The resource view compares spending at the resource level, highlights resources appearing in the current period’s billing data, and supports expandable service breakdowns. Figure 2. Historical prototype comparison. The screenshot's "New Resources" label means newly observed in billing, not confirmed creation. In this example workflow, current-month "Full" values are projections, not completed-month actuals. The agent can help break down cost changes that might otherwise require multiple spreadsheets and time-consuming manual comparisons: New charges do not always mean new resources: An existing resource may start generating charges after a period of inactivity. Costs may also rise because of autoscaling, longer VM running hours, increased storage usage, more read/write operations, or billable data transfers. These changes can be difficult to spot in summary reports. Newly created resources can add to spending: The agent can highlight resources appearing in the current period’s billing data. Resource inventory or deployment history is needed to confirm whether they were newly created or simply started generating charges. One resource can have several cost entries: A resource may appear in multiple billing records for different services or meters. Adding the relevant entries together helps show its total cost and contribution to the change. The net change can hide larger movements: For example, if one resource’s cost increases by $800 while another decreases by $300 over comparable periods, the net increase is $500. Showing both changes reveals the increase and the offsetting reduction. These figures are illustrative. Finding the cost driver is not the same as finding the cause: Identifying which resource contributed to an increase is the first step. Explaining why it happened may require additional evidence about usage, configuration changes, pricing, or other factors. 3. Which optimization opportunities deserve attention? The next question is usually practical: "Show Azure Advisor cost optimization recommendations for the subscriptions in scope. Separate estimated savings from confirmed spending reductions." The repository includes an example Advisor optimization view for reviewing rightsizing and commitment-related opportunities alongside the cost investigation. Figure 3. Historical prototype optimization view. Displayed savings are estimates, not realized savings; low CPU alone does not establish that shutdown is appropriate. A displayed zero for reservations requires a successful, authorized query before it can be interpreted as no reservations. The useful next step is to review the findings with the workload owner, not to make an automatic purchase or resize a resource. Rightsizing can change the baseline for a reservation or savings plan decision. Recommendations can also overlap, so adding every displayed savings figure may overstate the opportunity. Billing and commitment visibility depend on the identity's actual access; subscription resource access does not automatically expose every reservation or savings plan dataset. An unavailable dataset should be reported as unavailable. It should never silently become "no recommendations" or "no commitments." 4. What might we be paying for without using? Finally, investigate cleanup candidates: "Identify potentially orphaned resources and show the evidence that makes each one a candidate for owner review." The example orphaned-resource view covers candidates such as unattached disks, stale snapshots, unassociated public IP addresses and network interfaces, and empty App Service plans. Figure 4. Example cleanup-candidate inventory. An apparent orphan is an investigation finding, not deletion approval. An unattached disk may be retained for recovery. A snapshot may be subject to a retention requirement. A network resource may be reserved for a planned deployment. The report should help the owner answer those questions by identifying the resource, its state, and any observed charges. It should not turn "not currently attached" into "safe to delete." The intended configuration is read-only reporting and investigation. Validate the identity's effective permissions and enabled tools before use; the template alone does not enforce that boundary. Any cleanup requires separate validation and explicit approval. Have a meaningful cost conversation with the agent A cost dashboard remains useful. It shows the shape of spending and gives people a shared view. However, a conversational approach takes this further by helping users investigate what is driving spending, identify key contributors, distinguish new charges from changes in existing resources, and explore cost optimization opportunities. Start with a simple cost question, then use follow-up prompts to explore what changed, which resources contributed, and what needs further investigation. Example prompts include: “Which subscriptions and resources explain the largest cost increases compared with last month?” “Why did costs increase this month?” “Which resources contributed most to the increase?” “Is this newly billed spending or higher costs from existing resources?” “Compare the last three months and show the biggest changes.” “Create a report focused on this subscription and its top cost drivers.” “Show Azure Advisor savings opportunities and orphaned resources that require owner review.” “Refresh this report every Monday morning.” With the required data access and tools configured, the agent can help rerun analyses, narrow the scope, and generate reports focused on specific cost questions. Scheduled reports and cost alerts require supported capabilities, appropriate permissions, and separate configuration. Check findings against source data before making decisions or changing resources. Try it in your environment Start with one subscription whose costs you already understand. That makes it easier to reconcile the first report before expanding the scope. Review the kit. Start with the repository overview Add the three skills from the skills folder, and upload the cost analysis playbook as a knowledge source. Configure scoped access. The kit calls for Cost Management Reader and Reader on each target subscription for cost queries and inventory enrichment. Validate any additional billing or commitment access separately. Bootstrap the report. Submit the first-run prompt from the bootstrap prompts and provide the HTML report template. Validate the result. Reconcile a completed month's totals against Cost Management using the same scope, currency, and cost basis. Check resource aggregation, labels, and missing-data states. Configure refresh only after validation. The kit includes a suggested Monday 07:00 UTC refresh prompt. Confirm scheduling support, permissions, and failure handling in your environment before relying on it. Using this workflow may incur Azure SRE Agent charges and other applicable service charges. Review Azure SRE Agent pricing and billing and the pricing for the services you configure before running a pilot. This post does not describe a free service offering. Further reading Azure SRE Agent overview Azure Cost Management overview Azure Cost Management Query API Azure Advisor cost recommendations Azure Resource Graph overview596Views1like0Comments
How Microsoft Intune team upgraded a .NET service with GitHub Copilot modernization
Microsoft's Customer Zero blog series gives an insider view of how Microsoft builds and operates Microsoft using our trusted, enterprise-grade platform. Learn best practices from our engineering teams through real-world lessons, architectural patterns, and operational strategies for building, operating, and scaling AI-powered systems across the organization. A hosting platform transition gave our team an opportunity to modernize a Microsoft Intune enrollment service to .NET 8. I used GitHub Copilot modernization to assist with that work while retaining responsibility for design decisions and validation. Using GitHub Copilot modernization, I saved more than four weeks on the first library alone. The more durable outcome was the working method built around the agent: three working files that I kept alongside the code and owned myself, rather than leaving that state to the model, that let a months-long migration be paused, corrected and resumed without re-deriving the analysis every time. What follows is how that worked in practice, including where the agent stopped helping. The Challenge: retiring a hosting platform without carrying the framework forward My team owns a Platform as-a Service (PaaS) service that supports devices enrolling into Intune at the start of their enrollment journey. Microsoft Intune is a cloud-based endpoint management service that secures and manages an organization's devices and apps. It lets a company’s IT team manage and secure employees’ laptops, phones, tablets, apps, and company data from one central service. It supports Android, iOS/iPadOS, Linux, macOS, tvOS, visionOS, and Windows devices. This Service was running on .NET Framework 4.7.2, hosted on a non-AKS hosting platform. I moved it to Azure Kubernetes Service (AKS) hosting environment which is what started the work. The modernization combined two related but distinct changes: moving the workload to AKS and modernizing the application code to .NET. 8. The heaviest part was dependency mapping. A key part of the migration was mapping dependencies across shared libraries, namespaces, and APIs, including Intune owned and even team-owned libraries, some of which also needed modern .NET-compatible packages. The service had a substantial codebase with dependencies across multiple libraries, namespaces, and APIs. Some APIs were unchanged, some were renamed, and some had no direct replacement and required a design decision. These APIs were most often from internal Intune libraries. Without reusable mappings, those questions recur across projects and files. To maintain continuity across the migration as this was a long-term project, I kept an explicit record of decisions, completed work, and the next steps. The service spans several libraries and multiple endpoints that support about 20 plus different enrollment flows across Windows, Linux, Android, iOS, and macOS platforms. A single pull request covering the full migration was not possible, so I divided the work into increments small enough to review, test, and merge, or to isolate by enrollment flow, with a way to stop one day and pick up the next without paying the analysis cost twice. The Solution: a modernization agent with engineer-owned working content I started the side-by-side .NET framework service to .NET 8 service migration by hand, then brought in GitHub Copilot. In my early tests, I needed .NET migration-specific domain context beyond what I had established in my copilot session. The limitation was missing domain context, not an inability to generate code, and that is the gap a purpose-built tool closes. GitHub Copilot modernization is an agent built on GitHub Copilot, with Microsoft's language teams supplying domain knowledge. For .NET, its recommendations draw on current assembly and NuGet package analysis rather than relying only on patterns learned during model training. GitHub Copilot modernization is now available in Visual Studio, Visual Studio Code, GitHub Copilot CLI, GitHub Copilot app, and GitHub.com. When I did this migration, it was available only in Visual Studio and Visual Studio Code. For this migration, I chose GitHub Copilot modernization in Visual Studio through GitHub Copilot Chat in agent mode. I tested the modernization agent against work it could already check, running it over the same project and classes that I had migrated by hand and comparing the two. They were very close. That comparison, rather than anything in the tool's description, is what established enough confidence to point it at code nobody had migrated or analyzed manually yet. Once I started using the modernization agent, I realized that it was able to map .NET specific and global libraries as well as the API calls efficiently. The agent analyzed well but did not reliably retain migration state across sessions. Returning to the work could trigger a new assessment that overwrote prior artifacts. To avoid this, the more transferable part of my approach was the working context I built around the agent: a migration plan (migrationplan.md), a progress record (progress.md), and context notes. The agent generated a migrationPlan.md and progress.md at my request; I added the context from my notes from my previous sessions and manual migration and kept all three current in my local repository. The context preserved mappings I had already established by hand, so the agent could reuse settled decisions instead of researching them again. I kept them in my local repository rather than checking them in. The migrationplan.md broke the work into phases and day-sized tasks, and the progress.md file was updated after each increment. The next session could resume the recorded task instead of reassessing the codebase. When a migration increment surfaced a build issue, fixing it meant a side conversation, and the thread of the main work got lost in it. To avoid this, I started recording each failure under that day's task: what failed, what was tried, and what was ruled out. That gave the investigation somewhere to live without overwriting the main work. The current agents experience records task failures in progress-details.md. The Migrationplan.md is an editable markdown file, not opaque internal state, and I edited it when needed. Where a generated step was wrong for the service, or I wanted smaller increments of work per pull request, or to migrate a scenario before another, or to focus on one API path per pull request, or even to change the ordering, I updated the file with the correct information and the agent picked up the revision and carried on rather than reverting to its own plan. That made the editable plan especially useful when the migration approach changed. Plan granularity is also how I controlled pull request size. I used the plan to constrain each increment: for example, three model files and a view file, or one small end-to-end enrollment flow at a time, or one controller at a time, or sometimes not even a whole controller, just one API path, I made this judgement depending on the complexity of the scenario I wanted to migrate. Small increments stayed reviewable, and a broken build left a smaller surface to investigate. Supplying the build error and asking the agent to re-examine that increment produced a focused follow-up change. I began using the .NET modernize agent with an internal library, that supports Windows client calls made over Simple Object Access Protocol (SOAP). Before discovering the tool, I had already side-by-side migrated the .NET framework version of that library into another .NET8 successor library and had updated portions of the service’s windows enrollment flow. I used the mapping I had made between framework and .NET 8 libraries and APIs during this migration as a context for the tool, allowing each migration pass to reuse and add to the mappings established in previous one. The tool’s recommendations closely aligned with my manual migration approach on redo of the first library, which built my confidence in its output. I then used it for my next two internal library migrations, and the remaining Apple and Android enrollment flows in the service. The Impact: what the approach saved, and what it did not The internal library that handles Windows enrollment calls was estimated and took roughly six weeks of work but the tool completed it in one and a half weeks, a 75% schedule reduction, and on the second internal library dependency, also estimated at six weeks, I saved time again. I was able to reapply those savings to the remaining enrollment flows as I continued the service migration. The saving came from work that did not have to happen twice. Mappings settled in one phase were reused in the next rather than rediscovered. Project file conversion and NuGet package resolution, which is mechanical but voluminous, moved to the agent. What stayed with me was review, integration, the decisions, and the containerization and move to AKS itself. Without the agent, I would have needed to prioritize the migration more exclusively, which would have cut into the other project work I was delivering at the same time. Where the agent stopped helping In my experience, public libraries and Microsoft-wide libraries mapped well. Intune-internal libraries did not. In a subsequent internal prototype, I tested the agent on another service with different migration dependencies. For Intune-internal libraries, it could not identify which modern NuGet package or API replaced each dependency because those mappings were not available in its context. It still removed some of the mechanical work, but the mappings themselves stayed manual. During the prototype, I also built skills that work as a wrapper for the modernization agent that provides this internal migration context. I checked those skills into our internal repository so other Microsoft Intune engineering teams can use them internally through a plugin. What another team should take from this Validate it against work already done by hand to gain confidence. Running the agent over classes you have already migrated manually and comparing the output is cheap, and it gives you evidence for deciding whether to use the agent on code it has not yet migrated. Own the plan, not just the prompt. The agent writes its own plan and progress files to the repository. Read them and correct them, and it will follow your edits. For what it can't know, such as internal library mappings or your team's coding conventions, add a custom skill to the repository, and the agent will follow that too. Control pull request size through the plan rather than after the fact. Break pull requests into small increments. Scoping an increment to one controller, one API path, or a small end-to-end scenario keeps the change reviewable and testable, with a clear boundary for investigating migration issues. Reuse dependency mapping instead of rediscovering them. A large part of time savings come from carrying mappings established in previous phases into subsequent ones, even across libraries and services. Mechanical work like project conversion and NuGet package resolution can be handed off to the agent while you retained responsibility for integration, review and design decisions. Looking ahead The application-layer modernization is finished, while parity validation and the AKS traffic rollout continues. The reusable skills are checked into an internal repository and available to Intune engineering teams through an internal plugin, so another library or service can reuse established dependency-mapping work as well as Intune internal guidelines. I also shared the method and its measured time savings through Intune learning sessions, show and tell, Teams posts, and a newsletter. Learn more about GitHub Copilot modernization for .NET at https://dotnet.microsoft.com/platform/modernize and about Microsoft Intune at What is Microsoft Intune? - Microsoft Intune | Microsoft Learn.601Views0likes0CommentsCloud Security Billing, Simplified: Introducing the Defender Workload Unit
That's the thinking behind an upcoming improvement to Microsoft Defender for Cloud: the Defender Workload Unit, or DWU. It's a new billing model and product experience that translates workload-specific usage into a common billing unit, with one unit price and one place to estimate and track costs. Why we’re improving our billing model We heard two things consistently: cloud security pricing can be complex, and tracking cost can take real work. DWU simplifies this with one unit price. Workload usage still converts behind the scenes. What changes is that organizations see a single unit and have one place to estimate, track, and explain cloud security spend. How DWU helps: Simplify pricing. Bring multiple workload-specific measures under one common billing model. Simplify onboarding and expansion. Make it easier to enable and extend protection across cloud environments. Match how you evaluate cloud security. Understand protection across your entire cloud environment, rather than workload by workload. Reduce cost-tracking friction. Make costs easier to estimate, track, and explain. One thing we deliberately kept unchanged: billing stays tied to what is used. How it compares DWU translates workload-specific usage into a common billing unit with a consistent per-unit price. Each workload continues to convert into DWUs according to its applicable usage measure. Workloads still count behind the scenes, including servers, databases, storage, containers, posture management, APIs, AI services, app services, Key Vault, and Azure Resource Manager. What changes are what customers see: one unit and one price. Workload-specific usage is converted into DWUs and aggregated across your environment, based on a consistent global per-unit price calculated hourly and billed monthly. Estimation, reporting, and billing use the same DWU framework, making it easier to understand how usage translates into cost. What changes is how customers estimate, buy, manage, and track consumption. DWU brings together changes to the billing model, supporting tools, and management experience. Here is how the new experience compares with the existing model. Existing PAYG model With DWU Estimating cost Manual mapping, plan by plan Signed-in estimator, formula visible. Sizing environment Manual inventory Read-only discovery script; your data stays with you Tracking spend Multiple billing signals Defender portal dashboard, detail in Azure Cost Management Database plans Multiple instance/hour-based plans A single instance/hour-based plan Containers pricing vCore-based pricing Per-node pricing APIs pricing Multiple plans A single plan at a reduced price Plan Management Azure portal only Defender portal only (based on customer scope selection) The benefits of DWU DWU is designed to make Defender for Cloud consumption easier to estimate and track by translating supported workload usage into a common billing unit. Actual consumption and cost will depend on your workload mix, usage, pricing arrangement, and applicable discounts. We are committing to pricing that's easier to understand and manage. Clearer cost planning. As your estate grows, you can watch how costs scale. Transparency you can show your finance team. The new cost estimator requires you to sign in and shows the pricing formula and how your estimate is calculated. The same ways to buy. DWU is available through Enterprise Agreement, Microsoft Customer Agreement Enterprise, Cloud Solution Provider, and buy-online channels. Streamlined onboarding. Enable selected Defender for Cloud plans across subscriptions and management scopes through a unified experience. Easier expansion. Extend protection as your cloud environment grows without introducing a new customer-facing pricing construct for every workload. More holistic visibility. Understand protection and consumption across your cloud environment, rather than workload by workload. What's new to help you A cost estimator. Enter resource quantities to receive an immediate list-price estimate. A path from estimate to deployment. The experience follows a simple flow: estimate, deploy, and track. Move directly from your estimate to deployment, then monitor cost through the Defender portal. A dashboard that answers the next question. See total spend, which workloads drive it, and how it trends over time. New pricing models for some workloads. Containers move from vCore-based pricing to per-node. APIs consolidate multiple plans into one with a reduced plan. Database workload protection is consolidated from multiple instance-per-hour plans into one. What stays in your control Simpler doesn't mean less flexible. Choose which workload plans to enable and change them at any time. In the product, tenant-level enablement applies to Azure subscriptions and management groups connected to the Defender portal. You can also enable plans for an individual connected management group or subscription. When you opt into a subscription, its workloads move together. Where to start A 30-day platform trial. Eligible subscriptions that are new to Cloud Security can start a Defender for Cloud trial in the Defender portal. The trial is optional, is granted at the subscription level, and is limited to one trial per subscription. It covers the full platform, including all plans, rather than one capability at a time. After the trial ends, billing begins for the subscription, unless all cloud security plans are disabled before the trial expires. Two questions worth bringing to your next planning review: How clearly can we estimate and explain Defender for Cloud consumption across supported workloads? If we cannot do so clearly, that's the gap DWU can close. When did we last compare our intended protection scope with our current cloud-resource inventory? The read-only discovery script can tell you, with nothing leaving your environment. One common unit and a more consistent way to estimate and track consumption can make it easier to understand and explain what you’re protecting. Learn more and get started Calculate your DWU estimates with the new Cloud Security Cost Estimator. Learn more about DWU and start onboarding. FAQ Does DWU cover multicloud environments? Initial support is focused on Azure, with broader multicloud and hybrid support planned over time. Does DWU cover Security Copilot? No, DWU does not offer coverage for Security Copilot. Can I use the new container and API models through the existing PAYG experience in Azure? No, they are available only through the DWU experience in the Defender portal.Azure Verified Modules (AVM) is now owned by Azure engineering
Next community call: Monday 26th October 2026 @ 16:00 UK | 12:00 EDT | 09:00 PDT | 21:30 IST | 03:00 AEDT This call will be streamed to YouTube live so use the "Set reminder" / "Notify Me" options on YouTube and also put an entry in your calendar to remind you. This means it will automatically be recorded and published live once finished as well 👍 YouTube Live Link: aka.ms/AVM/CommunityCall ICS for your calendar: aka.ms/AVM/CommunityCall/ICS GitHub Issue Link: AVM Community Call - October 2026 · Issue #3079 · Azure/Azure-Verified-Modules - please add a comment for any topics or discussions you'd like covered Everyone is welcome whether you contribute to AVM or just use it. We want to welcome you for an insight into our roadmap over the next 6 months as well as an open discussion with you all. Azure Verified Modules (AVM) has moved into the Azure Deployments team, inside Microsoft’s Azure engineering organization. That is the headline, and it is a big one for us. AVM started as a community-led project inside Microsoft, built and maintained largely by people who cared about it alongside their day jobs in various roles and teams across Microsoft. It is now owned by an engineering team, with dedicated engineers working on it every day; as well as those who helped make AVM what it is today. I want to be clear about what that does and does not mean, because I know the questions this raises. AVM is still open source. The repositories, specifications, the contribution model and the way you consume modules from the public registries are all unchanged. What has changed is the level of investment behind it, and how sustainable we can make it. In short: Microsoft has increased its investment in AVM. It has moved from a community-led project into Azure engineering, with dedicated engineering resources behind it. It stays open-source. On the back of that, we are updating the support statement and introducing a three-tier module ownership model at the start of 2027 (more on these below). This blog post has a lot of content, please take the time to read it all but feel free to use the table of contents below to help you navigate it. If AVM is new to you AVM is the Microsoft standard for Infrastructure as Code (IaC) modules for Azure, in both Bicep and Terraform. Every module is built to the same published specification, passes the same continuous integration (CI) tests, and is published to the official public Bicep and Terraform registries. The idea is simple: you should not have to write the same Azure IaC code again, and you should be able to trust what you pick up. There is a lot more detail at aka.ms/AVM. And if you would rather watch than read, Jared Holgate and I covered AVM in our recent Azure Infra Summit session: watch the recording on YouTube. What the move lets us fix: our support statement Today, the AVM support statement includes day-based targets for responses and fixes. We have not met them consistently, and that does not give you clear or reliable expectations. We are removing those targets and aligning with the support model used by Azure CLI, Azure PowerShell, Bicep, AzAPI, and the AzureRM Terraform provider. The move into Azure engineering is the important part. Dedicated engineers will maintain modules directly and improve the tooling, automation, and framework used by all module owners. That is a stronger commitment than any fixed target we cannot reliably meet. It also lets us be clearer about who maintains each module. Right now, every AVM module is treated identically, and that is not sustainable. So, we are introducing module tiering. Introducing module tiering Right now, every AVM module is treated identically. That is not sustainable. A resource group module needs almost no attention. A storage account or virtual machine module needs constant work as the underlying service evolves. So, today we are introducing two tiers (and thinking about a third) based on who owns and maintains a module: Tier Owned by What it means Tier 1 (Core) The AVM engineering team Modules are owned directly by the AVM team inside Azure engineering. These are the ones we maintain as our day job alongside the AVM specifications and framework Tier 2 (Maintained) Any Microsoft employee (FTE) Modules are owned by any Microsoft full-time employee or team/s. It also includes other Azure engineering teams owning the modules for their own services. This is the model we have today, and it is not going away. Tier 3 (Open-Source) * being considered for future * Vetted external owners (future) An idea, not a commitment. It would let trusted external parties such as Microsoft MVPs and accredited partners own modules. We will not look at this until the 2nd half of calendar year 2027. One thing that will not change: the bar. Every module in every tier is built to the same AVM specification and passes the same CI checks. Tiering describes who is behind a module, not its quality. Ownership also stays aligned across languages if in Tier 1. If we own a module in Tier 1, we own it in both Bicep and Terraform. Why we are not publishing the module tiering list yet We want to know our real maintenance capacity before we commit. We are spending the rest of 2026 reducing toil and clearing the backlog. This work will show how many modules we can maintain. We would rather publish a list that we can sustain than change it soon after publication. Publishing a list will also focus attention on excluded modules. We want clear evidence before those discussions start. For context, our draft puts about 50 resource modules in Tier 1, across Bicep and Terraform. Current telemetry suggests these modules represent about 85 percent of AVM module deployments. Usage is one input. Critical services and other factors also matter. We will validate the draft before making a public commitment. Distributed ownership is still the point AVM has always run on decentralized ownership and moving into engineering does not change that. If anything, it should help. Being inside Azure engineering puts us much closer to the product teams who build the services, and getting more of those teams to own the modules for their own service has been a goal from day one. That is already happening. With the recent transition of Azure Landing Zones (ALZ), the Azure Migrate team now maintain the ALZ modules and the subscription vending modules in AVM. Those sit in Tier 2, but they are maintained by a dedicated engineering team. Tier 2 is not a lesser tier, it is a broader one. However, if they currently own a resource module that will be included in Tier 1, they are still welcome to be involved in its ownership alongside the AVM engineering team, but we would also encourage them to own a module outside of Tier 1 so we have an owner on as many modules as possible. But all of this will be dealt with when we implement the tiering structure in early 2027. Tier 2 ownership remains open to Microsoft employees and teams. The AVM engineering team will support those owners through improved tooling, automation, and the AVM framework. We will confirm ownership changes when we implement module tiering in early 2027. Come and meet the team (AVM Community Call) Rather than list names on a page, we would rather you meet the people. Join our next AVM community call, where the new engineering team looking after AVM will introduce themselves and take your questions. If you want to know who is behind AVM now, or discuss anything in this post, this will be the place to do it, and we can’t wait to see you all there! Next community call: Monday 26th October 2026 @ 16:00 UK | 12:00 EDT | 09:00 PDT | 21:30 IST | 03:00 AEDT This call will be streamed to YouTube live so use the "Set reminder" / "Notify Me" options on YouTube and also put an entry in your calendar to remind you. This means it will automatically be recorded and published live once finished as well 👍 YouTube Live Link: aka.ms/AVM/CommunityCall ICS for your calendar: aka.ms/AVM/CommunityCall/ICS GitHub Issue Link: AVM Community Call - October 2026 · Issue #3079 · Azure/Azure-Verified-Modules - please add a comment for any topics or discussions you'd like covered Everyone is welcome whether you contribute to AVM or just use it. We want to welcome you for an insight into our roadmap over the next 6 months as well as an open discussion with you all. What happens next We update the published module support statement and remove the day-based response targets. The team keeps burning down issues and pull requests and keeps reducing the manual toil in our CI. We validate our maintenance run rate through the end of calendar year 2026. We publish the initial tier classifications once we can stand behind them. We revisit Tier 3, including the legal and intellectual property questions, in 2027. AVM got here because customers, partners and contributors backed it and used it in anger. That has not changed, and neither has our need for your input. If you think we are getting this wrong, tell us in GitHub Discussions. Candidly, the feedback we get on this will shape how we land it. And finally, thank you to everyone who built this AVM exists because many people put real work into it, often alongside their day jobs. Matt White, Charlie Grabiaud, Mate Barabas, Pankaj Meshram, were some of AVM’s key founders and helped shape the project during its early days that are no longer involved in AVM day-to-day. Jared Holgate, Alexander Sehr, Erika Gressi, Kris Baranek, Sebastian Graf, Rene Hezser and Chris Sidebotham remain involved today helping develop and maintain the AVM framework and specifications with the engineering team. Some contributors have moved to other roles, teams, or companies. Many continue through issues, pull requests, community calls, and module ownership and contributions. Every contribution helped AVM reach this point and continue to drive it forward today. The move into Azure engineering adds dedicated investment. It does not replace the community that built and sustained AVM. To every past and present contributor and module owner: thank you for your time, commitment, and belief in AVM. Thanks, Jack and the AVM team.3.1KViews3likes0Comments