azure sre agent
63 TopicsContext Engineering Lessons from Building Azure SRE Agent
We started with 100+ tools and 50+ specialized agents. We ended with 5 core tools and a handful of generalists. The agent got more reliable, not less. Every context decision is a tradeoff: latency vs autonomy, evidence-building vs speed, oversight - and the cost of being wrong. This post is a practical map of those knobs and how we adjusted them for SRE Agent.15KViews22likes2CommentsAn AI led SDLC: Building an End-to-End Agentic Software Development Lifecycle with Azure and GitHub.
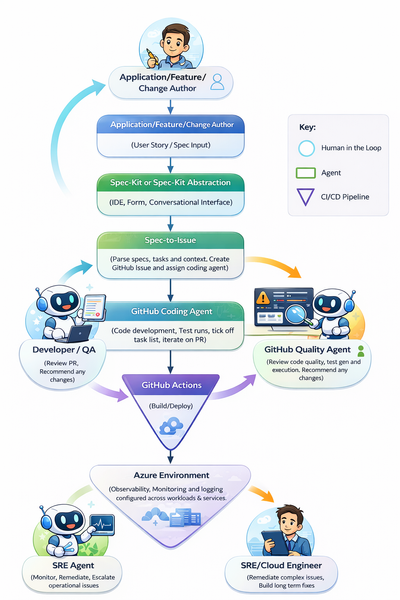
This is due to the inevitable move towards fully agentic, end-to-end SDLCs. We may not yet be at a point where software engineers are managing fleets of agents creating the billion-dollar AI abstraction layer, but (as I will evidence in this article) we are certainly on the precipice of such a world. Before we dive into the reality of agentic development today, let me examine two very different modules from university and their relevance in an AI-first development environment. Manual Requirements Translation. At university I dedicated two whole years to a unit called “Systems Design”. This was one of my favourite units, primarily focused on requirements translation. Often, I would receive a scenario between “The Proprietor” and “The Proprietor’s wife”, who seemed to be in a never-ending cycle of new product ideas. These tasks would be analysed, broken down, manually refined, and then mapped to some kind of early-stage application architecture (potentially some pseudo-code and a UML diagram or two). The big intellectual effort in this exercise was taking human intention and turning it into something tangible to build from (BA’s). Today, by the time I have opened Notepad and started to decipher requirements, an agent can already have created a comprehensive list, a service blueprint, and a code scaffold to start the process (*cough* spec-kit *cough*). Manual debugging. Need I say any more? Old-school debugging with print()’s and breakpoints is dead. I spent countless hours learning to debug in a classroom and then later with my own software, stepping through execution line by line, reading through logs, and understanding what to look for; where correlation did and didn’t mean causation. I think back to my year at IBM as a fresh-faced intern in a cloud engineering team, where around 50% of my time was debugging different issues until it was sufficiently “narrowed down”, and then reading countless Stack Overflow posts figuring out the actual change I would need to make to a PowerShell script or Jenkins pipeline. Already in Azure, with the emergence of SRE agents, that debug process looks entirely different. The debug process for software even more so… #terminallastcommand WHY IS THIS NOT RUNNING? #terminallastcommand Review these logs and surface errors relating to XYZ. As I said: breakpoints are dead, for now at least. Caveat – Is this a good thing? One more deviation from the main core of the article if you would be so kind (if you are not as kind skip to the implementation walkthrough below). Is this actually a good thing? Is a software engineering degree now worthless? What if I love printf()? I don’t know is my answer today, at the start of 2026. Two things worry me: one theoretical and one very real. To start with the theoretical: today AI takes a significant amount of the “donkey work” away from developers. How does this impact cognitive load at both ends of the spectrum? The list that “donkey work” encapsulates is certainly growing. As a result, on one end of the spectrum humans are left with the complicated parts yet to be within an agent’s remit. This could have quite an impact on our ability to perform tasks. If we are constantly dealing with the complex and advanced, when do we have time to re-root ourselves in the foundations? Will we see an increase in developer burnout? How do technical people perform without the mundane or routine tasks? I often hear people who have been in the industry for years discuss how simple infrastructure, computing, development, etc. were 20 years ago, almost with a longing to return to a world where today’s zero trust, globally replicated architectures are a twinkle in an architect’s eye. Is constantly working on only the most complex problems a good thing? At the other end of the spectrum, what if the performance of AI tooling and agents outperforms our wildest expectations? Suddenly, AI tools and agents are picking up more and more of today’s complicated and advanced tasks. Will developers, architects, and organisations lose some ability to innovate? Fundamentally, we are not talking about artificial general intelligence when we say AI; we are talking about incredibly complex predictive models that can augment the existing ideas they are built upon but are not, in themselves, innovators. Put simply, in the words of Scott Hanselman: “Spicy auto-complete”. Does increased reliance on these agents in more and more of our business processes remove the opportunity for innovative ideas? For example, if agents were football managers, would we ever have graduated from Neil Warnock and Mick McCarthy football to Pep? Would every agent just augment a ‘lump it long and hope’ approach? We hear about learning loops, but can these learning loops evolve into “innovation loops?” Past the theoretical and the game of 20 questions, the very real concern I have is off the back of some data shared recently on Stack Overflow traffic. We can see in the diagram below that Stack Overflow traffic has dipped significantly since the release of GitHub Copilot in October 2021, and as the product has matured that trend has only accelerated. Data from 12 months ago suggests that Stack Overflow has lost 77% of new questions compared to 2022… Stack Overflow democratises access to problem-solving (I have to be careful not to talk in past tense here), but I will admit I cannot remember the last time I was reviewing Stack Overflow or furiously searching through solutions that are vaguely similar to my own issue. This causes some concern over the data available in the future to train models. Today, models can be grounded in real, tested scenarios built by developers in anger. What happens with this question drop when API schemas change, when the technology built for today is old and deprecated, and the dataset is stale and never returning to its peak? How do we mitigate this impact? There is potential for some closed-loop type continuous improvement in the future, but do we think this is a scalable solution? I am unsure. So, back to the question: “Is this a good thing?”. It’s great today; the long-term impacts are yet to be seen. If we think that AGI may never be achieved, or is at least a very distant horizon, then understanding the foundations of your technical discipline is still incredibly important. Developers will not only be the managers of their fleet of agents, but also the janitors mopping up the mess when there is an accident (albeit likely mopping with AI-augmented tooling). An AI First SDLC Today – The Reality Enough reflection and nostalgia (I don’t think that’s why you clicked the article), let’s start building something. For the rest of this article I will be building an AI-led, agent-powered software development lifecycle. The example I will be building is an AI-generated weather dashboard. It’s a simple example, but if agents can generate, test, deploy, observe, and evolve this application, it proves that today, and into the future, the process can likely scale to more complex domains. Let’s start with the entry point. The problem statement that we will build from. “As a user I want to view real time weather data for my city so that I can plan my day.” We will use this as the single input for our AI led SDLC. This is what we will pass to promptkit and watch our app and subsequent features built in front of our eyes. The goal is that we will: - Spec-kit to get going and move from textual idea to requirements and scaffold. - Use a coding agent to implement our plan. - A Quality agent to assess the output and quality of the code. - GitHub Actions that not only host the agents (Abstracted) but also handle the build and deployment. - An SRE agent proactively monitoring and opening issues automatically. The end to end flow that we will review through this article is the following: Step 1: Spec-driven development - Spec First, Code Second A big piece of realising an AI-led SDLC today relies on spec-driven development (SDD). One of the best summaries for SDD that I have seen is: “Version control for your thinking”. Instead of huge specs that are stale and buried in a knowledge repository somewhere, SDD looks to make them a first-class citizen within the SDLC. Architectural decisions, business logic, and intent can be captured and versioned as a product evolves; an executable artefact that evolves with the project. In 2025, GitHub released the open-source Spec Kit: a tool that enables the goal of placing a specification at the centre of the engineering process. Specs drive the implementation, checklists, and task breakdowns, steering an agent towards the end goal. This article from GitHub does a great job explaining the basics, so if you’d like to learn more it’s a great place to start (https://github.blog/ai-and-ml/generative-ai/spec-driven-development-with-ai-get-started-with-a-new-open-source-toolkit/). In short, Spec Kit generates requirements, a plan, and tasks to guide a coding agent through an iterative, structured development process. Through the Spec Kit constitution, organisational standards and tech-stack preferences are adhered to throughout each change. I did notice one (likely intentional) gap in functionality that would cement Spec Kit’s role in an autonomous SDLC. That gap is that the implement stage is designed to run within an IDE or client coding agent. You can now, in the IDE, toggle between task implementation locally or with an agent in the cloud. That is great but again it still requires you to drive through the IDE. Thinking about this in the context of an AI-led SDLC (where we are pushing tasks from Spec Kit to a coding agent outside of my own desktop), it was clear that a bridge was needed. As a result, I used Spec Kit to create the Spec-to-issue tool. This allows us to take the tasks and plan generated by Spec Kit, parse the important parts, and automatically create a GitHub issue, with the option to auto-assign the coding agent. From the perspective of an autonomous AI-led SDLC, Speckit really is the entry point that triggers the flow. How Speckit is surfaced to users will vary depending on the organisation and the context of the users. For the rest of this demo I use Spec Kit to create a weather app calling out to the OpenWeather API, and then add additional features with new specs. With one simple prompt of “/promptkit.specify “Application feature/idea/change” I suddenly had a really clear breakdown of the tasks and plan required to get to my desired end state while respecting the context and preferences I had previously set in my Spec Kit constitution. I had mentioned a desire for test driven development, that I required certain coverage and that all solutions were to be Azure Native. The real benefit here compared to prompting directly into the coding agent is that the breakdown of one large task into individual measurable small components that are clear and methodical improves the coding agents ability to perform them by a considerable degree. We can see an example below of not just creating a whole application but another spec to iterate on an existing application and add a feature. We can see the result of the spec creation, the issue in our github repo and most importantly for the next step, our coding agent, GitHub CoPilot has been assigned automatically. Step 2: GitHub Coding Agent - Iterative, autonomous software creation Talking of coding agents, GitHub Copilot’s coding agent is an autonom ous agent in GitHub that can take a scoped development task and work on it in the background using the repository’s context. It can make code changes and produce concrete outputs like commits and pull requests for a developer to review. The developer stays in control by reviewing, requesting changes, or taking over at any point. This does the heavy lifting in our AI-led SDLC. We have already seen great success with customers who have adopted the coding agent when it comes to carrying out menial tasks to save developers time. These coding agents can work in parallel to human developers and with each other. In our example we see that the coding agent creates a new branch for its changes, and creates a PR which it starts working on as it ticks off the various tasks generated in our spec. One huge positive of the coding agent that sets it apart from other similar solutions is the transparency in decision-making and actions taken. The monitoring and observability built directly into the feature means that the agent’s “thinking” is easily visible: the iterations and steps being taken can be viewed in full sequence in the Agents tab. Furthermore, the action that the agent is running is also transparently available to view in the Actions tab, meaning problems can be assessed very quickly. Once the coding agent is finished, it has run the required tests and, even in the case of a UI change, goes as far as calling the Playwright MCP server and screenshotting the change to showcase in the PR. We are then asked to review the change. In this demo, I also created a GitHub Action that is triggered when a PR review is requested: it creates the required resources in Azure and surfaces the (in this case) Azure Container Apps revision URL, making it even smoother for the human in the loop to evaluate the changes. Just like any normal PR, if changes are required comments can be left; when they are, the coding agent can pick them up and action what is needed. It’s also worth noting that for any manual intervention here, use of GitHub Codespaces would work very well to make minor changes or perform testing on an agent’s branch. We can even see the unit tests that have been specified in our spec how been executed by our coding agent. The pattern used here (Spec Kit -> coding agent) overcomes one of the biggest challenges we see with the coding agent. Unlike an IDE-based coding agent, the GitHub.com coding agent is left to its own iterations and implementation without input until the PR review. This can lead to subpar performance, especially compared to IDE agents which have constant input and interruption. The concise and considered breakdown generated from Spec Kit provides the structure and foundation for the agent to execute on; very little is left to interpretation for the coding agent. Step 3: GitHub Code Quality Review (Human in the loop with agent assistance.) GitHub Code Quality is a feature (currently in preview) that proactively identifies code quality risks and opportunities for enhancement both in PRs and through repository scans. These are surfaced within a PR and also in repo-level scoreboards. This means that PRs can now extend existing static code analysis: Copilot can action CodeQL, PMD, and ESLint scanning on top of the new, in-context code quality findings and autofixes. Furthermore, we receive a summary of the actual changes made. This can be used to assist the human in the loop in understanding what changes have been made and whether enhancements or improvements are required. Thinking about this in the context of review coverage, one of the challenges sometimes in already-lean development teams is the time to give proper credence to PRs. Now, with AI-assisted quality scanning, we can be more confident in our overall evaluation and test coverage. I would expect that use of these tools alongside existing human review processes would increase repository code quality and reduce uncaught errors. The data points support this too. The Qodo 2025 AI Code Quality report showed that usage of AI code reviews increased quality improvements to 81% (from 55%). A similar study from Atlassian RovoDev 2026 study showed that 38.7% of comments left by AI agents in code reviews lead to additional code fixes. LLM’s in their current form are never going to achieve 100% accuracy however these are still considerable, significant gains in one of the most important (and often neglected) parts of the SDLC. With a significant number of software supply chain attacks recently it is also not a stretch to imagine that that many projects could benefit from "independently" (use this term loosely) reviewed and summarised PR's and commits. This in the future could potentially by a specialist/sub agent during a PR or merge to focus on identifying malicious code that may be hidden within otherwise normal contributions, case in point being the "near-miss" XZ Utils attack. Step 4: GitHub Actions for build and deploy - No agents here, just deterministic automation. This step will be our briefest, as the idea of CI/CD and automation needs no introduction. It is worth noting that while I am sure there are additional opportunities for using agents within a build and deploy pipeline, I have not investigated them. I often speak with customers about deterministic and non-deterministic business process automation, and the importance of distinguishing between the two. Some processes were created to be deterministic because that is all that was available at the time; the number of conditions required to deal with N possible flows just did not scale. However, now those processes can be non-deterministic. Good examples include IVR decision trees in customer service or hard-coded sales routines to retain a customer regardless of context; these would benefit from less determinism in their execution. However, some processes remain best as deterministic flows: financial transactions, policy engines, document ingestion. While all these flows may be part of an AI solution in the future (possibly as a tool an agent calls, or as part of a larger agent-based orchestration), the processes themselves are deterministic for a reason. Just because we could have dynamic decision-making doesn’t mean we should. Infrastructure deployment and CI/CD pipelines are one good example of this, in my opinion. We could have an agent decide what service best fits our codebase and which region we should deploy to, but do we really want to, and do the benefits outweigh the potential negatives? In this process flow we use a deterministic GitHub action to deploy our weather application into our “development” environment and then promote through the environments until we reach production and we want to now ensure that the application is running smoothly. We also use an action as mentioned above to deploy and surface our agents changes. In Azure Container Apps we can do this in a secure sandbox environment called a “Dynamic Session” to ensure strong isolation of what is essentially “untrusted code”. Often enterprises can view the building and development of AI applications as something that requires a completely new process to take to production, while certain additional processes are new, evaluation, model deployment etc many of our traditional SDLC principles are just as relevant as ever before, CI/CD pipelines being a great example of that. Checked in code that is predictably deployed alongside required services to run tests or promote through environments. Whether you are deploying a java calculator app or a multi agent customer service bot, CI/CD even in this new world is a non-negotiable. We can see that our geolocation feature is running on our Azure Container Apps revision and we can begin to evaluate if we agree with CoPilot that all the feature requirements have been met. In this case they have. If they hadn't we'd just jump into the PR and add a new comment with "@copilot" requesting our changes. Step 5: SRE Agent - Proactive agentic day two operations. The SRE agent service on Azure is an operations-focused agent that continuously watches a running service using telemetry such as logs, metrics, and traces. When it detects incidents or reliability risks, it can investigate signals, correlate likely causes, and propose or initiate response actions such as opening issues, creating runbook-guided fixes, or escalating to an on-call engineer. It effectively automates parts of day two operations while keeping humans in control of approval and remediation. It can be run in two different permission models: one with a reader role that can temporarily take user permissions for approved actions when identified. The other model is a privileged level that allows it to autonomously take approved actions on resources and resource types within the resource groups it is monitoring. In our example, our SRE agent could take actions to ensure our container app runs as intended: restarting pods, changing traffic allocations, and alerting for secret expiry. The SRE agent can also perform detailed debugging to save human SREs time, summarising the issue, fixes tried so far, and narrowing down potential root causes to reduce time to resolution, even across the most complex issues. My initial concern with these types of autonomous fixes (be it VPA on Kubernetes or an SRE agent across your infrastructure) is always that they can very quickly mask problems, or become an anti-pattern where you have drift between your IaC and what is actually running in Azure. One of my favourite features of SRE agents is sub-agents. Sub-agents can be created to handle very specific tasks that the primary SRE agent can leverage. Examples include alerting, report generation, and potentially other third-party integrations or tooling that require a more concise context. In my example, I created a GitHub sub-agent to be called by the primary agent after every issue that is resolved. When called, the GitHub sub-agent creates an issue summarising the origin, context, and resolution. This really brings us full circle. We can then potentially assign this to our coding agent to implement the fix before we proceed with the rest of the cycle; for example, a change where a port is incorrect in some Bicep, or min scale has been adjusted because of latency observed by the SRE agent. These are quick fixes that can be easily implemented by a coding agent, subsequently creating an autonomous feedback loop with human review. Conclusion: The journey through this AI-led SDLC demonstrates that it is possible, with today’s tooling, to improve any existing SDLC with AI assistance, evolving from simply using a chat interface in an IDE. By combining Speckit, spec-driven development, autonomous coding agents, AI-augmented quality checks, deterministic CI/CD pipelines, and proactive SRE agents, we see an emerging ecosystem where human creativity and oversight guide an increasingly capable fleet of collaborative agents. As with all AI solutions we design today, I remind myself that “this is as bad as it gets”. If the last two years are anything to go by, the rate of change in this space means this article may look very different in 12 months. I imagine Spec-to-issue will no longer be required as a bridge, as native solutions evolve to make this process even smoother. There are also some areas of an AI-led SDLC that are not included in this post, things like reviewing the inner-loop process or the use of existing enterprise patterns and blueprints. I also did not review use of third-party plugins or tools available through GitHub. These would make for an interesting expansion of the demo. We also did not look at the creation of custom coding agents, which could be hosted in Microsoft Foundry; this is especially pertinent with the recent announcement of Anthropic models now being available to deploy in Foundry. Does today’s tooling mean that developers, QAs, and engineers are no longer required? Absolutely not (and if I am honest, I can’t see that changing any time soon). However, it is evidently clear that in the next 12 months, enterprises who reshape their SDLC (and any other business process) to become one augmented by agents will innovate faster, learn faster, and deliver faster, leaving organisations who resist this shift struggling to keep up.59KViews9likes2CommentsThe Agent that investigates itself
Azure SRE Agent handles tens of thousands of incident investigations each week for internal Microsoft services and external teams running it for their own systems. Last month, one of those incidents was about the agent itself. Our KV cache hit rate alert started firing. Cached token percentage was dropping across the fleet. We didn't open dashboards. We simply asked the agent. It spawned parallel subagents, searched logs, read through its own source code, and produced the analysis. First finding: Claude Haiku at 0% cache hits. The agent checked the input distribution and found that the average call was ~180 tokens, well below Anthropic’s 4,096-token minimum for Haiku prompt caching. Structurally, these requests could never be cached. They were false positives. The real regression was in Claude Opus: cache hit rate fell from ~70% to ~48% over a week. The agent correlated the drop against the deployment history and traced it to a single PR that restructured prompt ordering, breaking the common prefix that caching relies on. It submitted two fixes: one to exclude all uncacheable requests from the alert, and the other to restore prefix stability in the prompt pipeline. That investigation is how we develop now. We rarely start with dashboards or manual log queries. We start by asking the agent. Three months earlier, it could not have done any of this. The breakthrough was not building better playbooks. It was harness engineering: enabling the agent to discover context as the investigation unfolded. This post is about the architecture decisions that made it possible. Where we started In our last post, Context Engineering for Reliable AI Agents: Lessons from Building Azure SRE Agent, we described how moving to a single generalist agent unlocked more complex investigations. The resolution rates were climbing, and for many internal teams, the agent could now autonomously investigate and mitigate roughly 50% of incidents. We were moving in the right direction. But the scores weren't uniform, and when we dug into why, the pattern was uncomfortable. The high-performing scenarios shared a trait: they'd been built with heavy human scaffolding. They relied on custom response plans for specific incident types, hand-built subagents for known failure modes, and pre-written log queries exposed as opaque tools. We weren’t measuring the agent’s reasoning – we were measuring how much engineering had gone into the scenario beforehand. On anything new, the agent had nowhere to start. We found these gaps through manual review. Every week, engineers read through lower-scored investigation threads and pushed fixes: tighten a prompt, fix a tool schema, add a guardrail. Each fix was real. But we could only review fifty threads a week. The agent was handling ten thousand. We were debugging at human speed. The gap between those two numbers was where our blind spots lived. We needed an agent powerful enough to take this toil off us. An agent which could investigate itself. Dogfooding wasn't a philosophy - it was the only way to scale. The Inversion: Three bets The problem we faced was structural - and the KV cache investigation shows it clearly. The cache rate drop was visible in telemetry, but the cause was not. The agent had to correlate telemetry with deployment history, inspect the relevant code, and reason over the diff that broke prefix stability. We kept hitting the same gap in different forms: logs pointing in multiple directions, failure modes in uninstrumented paths, regressions that only made sense at the commit level. Telemetry showed symptoms, but not what actually changed. We'd been building the agent to reason over telemetry. We needed it to reason over the system itself. The instinct when agents fail is to restrict them: pre-write the queries, pre-fetch the context, pre-curate the tools. It feels like control. In practice, it creates a ceiling. The agent can only handle what engineers anticipated in advance. The answer is an agent that can discover what it needs as the investigation unfolds. In the KV cache incident, each step, from metric anomaly to deployment history to a specific diff, followed from what the previous step revealed. It was not a pre-scripted path. Navigating towards the right context with progressive discovery is key to creating deep agents which can handle novel scenarios. Three architectural decisions made this possible – and each one compounded on the last. Bet 1: The Filesystem as the Agent's World Our first bet was to give the agent a filesystem as its workspace instead of a custom API layer. Everything it reasons over – source code, runbooks, query schemas, past investigation notes – is exposed as files. It interacts with that world using read_file, grep, find, and shell. No SearchCodebase API. No RetrieveMemory endpoint. This is an old Unix idea: reduce heterogeneous resources to a single interface. Coding agents already work this way. It turns out the same pattern works for an SRE agent. Frontier models are trained on developer workflows: navigating repositories, grepping logs, patching files, running commands. The filesystem is not an abstraction layered on top of that prior. It matches it. When we materialized the agent’s world as a repo-like workspace, our human "Intent Met" score - whether the agent's investigation addressed the actual root cause as judged by the on-call engineer - rose from 45% to 75% on novel incidents. But interface design is only half the story. The other half is what you put inside it. Code Repositories: the highest-leverage context Teams had prewritten log queries because they did not trust the agent to generate correct ones. That distrust was justified. Models hallucinate table names, guess column schemas, and write queries against the wrong cluster. But the answer was not tighter restriction. It was better grounding. The repo is the schema. Everything else is derived from it. When the agent reads the code that produces the logs, query construction stops being guesswork. It knows the exact exceptions thrown, and the conditions under which each path executes. Stack traces start making sense, and logs become legible. But beyond query grounding, code access unlocked three new capabilities that telemetry alone could not provide: Ground truth over documentation. Docs drift and dashboards show symptoms. The code is what the service actually does. In practice, most investigations only made sense when logs were read alongside implementation. Point-in-time investigation. The agent checks out the exact commit at incident time, not current HEAD, so it can correlate the failure against the actual diffs. That's what cracked the KV cache investigation: a PR broke prefix stability, and the diff was the only place this was visible. Without commit history, you can't distinguish a code regression from external factors. Reasoning even where telemetry is absent. Some code paths are not well instrumented. The agent can still trace logic through source and explain behavior even when logs do not exist. This is especially valuable in novel failure modes – the ones most likely to be missed precisely because no one thought to instrument them. Memory as a filesystem, not a vector store Our first memory system used RAG over past session learnings. It had a circular dependency: a limited agent learned from limited sessions and produced limited knowledge. Garbage in, garbage out. But the deeper problem was retrieval. In SRE Context, embedding similarity is a weak proxy for relevance. “KV cache regression” and “prompt prefix instability” may be distant in embedding space yet still describe the same causal chain. We tried re-ranking, query expansion, and hybrid search. None fixed the core mismatch between semantic similarity and diagnostic relevance. We replaced RAG with structured Markdown files that the agent reads and writes through its standard tool interface. The model names each file semantically: overview.md for a service summary, team.md for ownership and escalation paths, logs.md for cluster access and query patterns, debugging.md for failure modes and prior learnings. Each carry just enough context to orient the agent, with links to deeper files when needed. The key design choice was to let the model navigate memory, not retrieve it through query matching. The agent starts from a structured entry point and follows the evidence toward what matters. RAG assumes you know the right query before you know what you need. File traversal lets relevance emerge as context accumulates. This removed chunking, overlap tuning, and re-ranking entirely. It also proved more accurate, because frontier models are better at following context than embeddings are at guessing relevance. As a side benefit, memory state can be snapshotted periodically. One problem remains unsolved: staleness. When two sessions write conflicting patterns to debugging.md, the model must reconcile them. When a service changes behavior, old entries can become misleading. We rely on timestamps and explicit deprecation notes, but we do not have a systemic solution yet. This is an active area of work, and anyone building memory at scale will run into it. The sandbox as epistemic boundary The filesystem also defines what the agent can see. If something is not in the sandbox, the agent cannot reason about it. We treat that as a feature, not a limitation. Security boundaries and epistemic boundaries are enforced by the same mechanism. Inside that boundary, the agent has full execution: arbitrary bash, python, jq, and package installs through pip or apt. That scope unlocks capabilities we never would have built as custom tools. It opens PRs with gh cli, like the prompt-ordering fix from KV cache incident. It pushes Grafana dashboards, like a cache-hit-rate dashboard we now track by model. It installs domain-specific CLI tools mid-investigation when needed. No bespoke integration required, just a shell. The recurring lesson was simple: a generally capable agent in the right execution environment outperforms a specialized agent with bespoke tooling. Custom tools accumulate maintenance costs. Shell commands compose for free. Bet 2: Context Layering Code access tells the agent what a service does. It does not tell the agent what it can access, which resources its tools are scoped to, or where an investigation should begin. This gap surfaced immediately. Users would ask "which team do you handle incidents for?" and the agent had no answer. Tools alone are not enough. An integration also needs ambient context so the model knows what exists, how it is configured, and when to use it. We fixed this with context hooks: structured context injected at prompt construction time to orient the agent before it takes action. Connectors - what can I access? A manifest of wired systems such as Log Analytics, Outlook, and Grafana, along with their configuration. Repositories - what does this system do? Serialized repo trees, plus files like AGENTS.md, Copilot.md, and CLAUDE.md with team-specific instructions. Knowledge map - what have I learned before? A two-tier memory index with a top-level file linking to deeper scenario-specific files, so the model can drill down only when needed. Azure resource topology - where do things live? A serialized map of relationships across subscriptions, resource groups, and regions, so investigations start in the right scope. Together, these context hooks turn a cold start into an informed one. That matters because a bad early choice does not just waste tokens. It sends the investigation down the wrong trajectory. A capable agent still needs to know what exists, what matters, and where to start. Bet 3: Frugal Context Management Layered context creates a new problem: budget. Serialized repo trees, resource topology, connector manifests, and a memory index fill context fast. Once the agent starts reading source files and logs, complex incidents hit context limits. We needed our context usage to be deliberately frugal. Tool result compression via the filesystem Large tool outputs are expensive because they consume context before the agent has extracted any value from them. In many cases, only a small slice or a derived summary of that output is actually useful. Our framework exposes these results as files to the agent. The agent can then use tools like grep, jq, or python to process them outside the model interface, so that only the final result enters context. The filesystem isn't just a capability abstraction - it's also a budget management primitive. Context Pruning and Auto Compact Long investigations accumulate dead weight. As hypotheses narrow, earlier context becomes noise. We handle this with two compaction strategies. Context Pruning runs mid-session. When context usage crosses a threshold, we trim or drop stale tool calls and outputs - keeping the window focused on what still matters. Auto-Compact kicks in when a session approaches its context limit. The framework summarizes findings and working hypotheses, then resumes from that summary. From the user's perspective, there's no visible limit. Long investigations just work. Parallel subagents The KV cache investigation required reasoning along two independent hypotheses: whether the alert definition was sound, and whether cache behavior had actually regressed. The agent spawned parallel subagents for each task, each operating in its own context window. Once both finished, it merged their conclusions. This pattern generalizes to any task with independent components. It speeds up the search, keeps intermediate work from consuming the main context window, and prevents one hypothesis from biasing another. The Feedback loop These architectural bets have enabled us to close the original scaling gap. Instead of debugging the agent at human speed, we could finally start using it to fix itself. As an example, we were hitting various LLM errors: timeouts, 429s (too many requests), failures in the middle of response streaming, 400s from code bugs that produced malformed payloads. These paper cuts would cause investigations to stall midway and some conversations broke entirely. So, we set up a daily monitoring task for these failures. The agent searches for the last 24 hours of errors, clusters the top hitters, traces each to its root cause in the codebase, and submits a PR. We review it manually before merging. Over two weeks, the errors were reduced by more than 80%. Over the last month, we have successfully used our agent across a wide range of scenarios: Analyzed our user churn rate and built dashboards we now review weekly. Correlated which builds needed the most hotfixes, surfacing flaky areas of the codebase. Ran security analysis and found vulnerabilities in the read path. Helped fill out parts of its own Responsible AI review, with strict human review. Handles customer-reported issues and LiveSite alerts end to end. Whenever it gets stuck, we talk to it and teach it, ask it to update its memory, and it doesn't fail that class of problem again. The title of this post is literal. The agent investigating itself is not a metaphor. It is a real workflow, driven by scheduled tasks, incident triggers, and direct conversations with users. What We Learned We spent months building scaffolding to compensate for what the agent could not do. The breakthrough was removing it. Every prewritten query was a place we told the model not to think. Every curated tool was a decision made on its behalf. Every pre-fetched context was a guess about what would matter before we understood the problem. The inversion was simple but hard to accept: stop pre-computing the answer space. Give the model a structured starting point, a filesystem it knows how to navigate, context hooks that tell it what it can access, and budget management that keeps it sharp through long investigations. The agent that investigates itself is both the proof and the product of this approach. It finds its own bugs, traces them to root causes in its own code, and submits its own fixes. Not because we designed it to. Because we designed it to reason over systems, and it happens to be one. We are still learning. Staleness is unsolved, budget tuning remains largely empirical, and we regularly discover assumptions baked into context that quietly constrain the agent. But we have crossed a new threshold: from an agent that follows your playbook to one that writes the next one. Thanks to visagarwal for co-authoring this post.14KViews7likes0CommentsZero Ops: Agents Operate, Humans Govern
How to design, build, and grow an agentic operations practice — and what becomes possible once you do. A note on scope: the patterns in this guide apply to any agentic operations platform. The specifics — the pricing model, the built-in capabilities, the primitives named throughout — are Azure SRE Agent. Where something is a property of the product rather than a universal truth, it’s called out. Remember when? Remember the 3am page? The one where you sat on the edge of the bed with a laptop balanced on your knees, hunting through six dashboards to work out whether the thing that woke you was even real. Half the time it wasn’t. Remember the cost review? Somebody exports a month of billing to a spreadsheet, three engineers spend a fortnight arguing about which resources are actually orphaned, and by the time you’ve agreed on a plan the next month’s bill has already landed. Remember the zero-day? The all-hands marathon. Two days of people cancelling everything, tracing which services pulled the affected package, hand-patching in an order nobody had time to write down. And remember the CVE backlog — the one everyone knows about, the one that only ever grows, because triaging it properly would take a team you don’t have? None of that was a failure of effort. It was the operating model. For decades it looked like this: humans operated, software assisted. We built dashboards, alerts, runbooks, automation scripts, and eventually copilots — and through every one of those advances, the human was still the operator. That’s the part that’s changing. And it’s genuinely good news. Agents operate. Humans govern. That’s Zero Ops. And the best part is you don’t have to invent it — the path is already well-worn. The five things worth knowing before you start Everything below comes from building and running agentic operations at scale. If you read nothing else, read these. 1. Zero Ops is the destination — and it doesn’t mean zero humans. It means removing operations from humans. People don’t disappear; they move up the stack. They set the intent, govern the system, and validate outcomes. Nobody’s job becomes “watch the dashboard” ever again. 2. The model is not the moat. This was the biggest surprise. The model matters less every year. You can swap models. What you cannot swap is the context and governance wrapped around them. That’s the durable asset you’re building. 3. Context creates intelligence. Agents become genuinely useful the moment they’re grounded in reality — your source code, your live telemetry, your institutional knowledge, your incident history, and the skills and tools to act on all of it. Swap the model and the system still works. Swap the context and it stops being useful. 4. Governance creates trust. Enterprises don’t trust intelligence. Enterprises trust controls. Identity, audit, evals, rollback, evidence. Governance is what earns the right to automate — and it’s liberating rather than restricting, because it’s what lets you say yes. 5. Metrics create permission. Nobody should trust an agent because a demo looked impressive. Trust comes from numbers you can run yourself. If only the vendor can produce the number, it’s marketing. If you can query it, it’s a metric. The climb, and the one thing that changes at each rung Here’s the elegant part. As an agent matures, the thing that changes isn’t how clever it is. It’s what the human reviews. Rung What the agent does What the human reviews Crawl Suggests. A human still does the work. Their own work Walk Does the work one step at a time, asking before each action. Every step Run Completes whole tasks and hands back a change to approve. The diff Fly Fixes, deploys to test, validates the outcome itself, posts the evidence. The outcome And between Run and Fly sits the review wall. When an agent produces hundreds of changes a month, reviewing someone else’s diff is nearly as hard as writing it yourself. That’s where teams plateau — not because the agent isn’t capable, but because the humans became the bottleneck. Fly is how you get past it: you move the unit of human review from the diff to the outcome. Hold that thought — we’ll come back to it, because it’s the most exciting part of the whole journey. Getting there is a design problem before it’s a technology one. Agents that climb were built to climb. So let’s start where every one of them starts — how you scope it, what you teach it, and what you connect it to. Part One — Designing your agent Before you start: what you’ll want in place The good news is that this list is short, and you almost certainly have most of it already. There’s no platform to stand up first. Diagnostic logs turned on for the services you care about. An agent can only reason about what your system actually emits. Telemetry the agent can query. It doesn’t need to live in one place — most estates have it spread across several platforms, and that’s completely fine. What matters is that each of those places is reachable and queryable. This is what turns “something is wrong” into “here’s why.” Read access to the sources that hold the answers — your subscriptions, your repositories, your incident history, your ticketing system. An identity for the agent, with permissions scoped the way you’d scope a new team member’s on day one. A repository for agent artifacts. Skills, custom agents and tool definitions are production code. They deserve version control from the first one. That’s it. Nothing here is agent-specific — it’s the same hygiene that makes a system operable by humans. If your on-call engineer can answer a question at 3am, your agent can too. Step 1: Scope it — how many agents do you actually need? Good news first: fewer than you think. Teams often assume one agent per team, and that’s usually wrong. Five considerations decide it: 1. Fixed cost. Every Azure SRE Agent carries a small baseline charge just for existing — think of it as keeping the lights on so the agent is ready the instant something happens. That means consolidating where you can is genuinely good hygiene: fewer agents, each with a clear job, means every dollar goes toward outcomes rather than idle capacity. 2. Context. This is the big one. An agent is powerful because it holds a complete picture of a system. Split one application’s context across two agents and you’ve halved what each of them knows — usually the half that mattered. Don’t split an app’s context. 3. Data residency at rest. If data legally cannot leave a geography, that’s a boundary, and it’s a real one. Separate agent, separate region. 4. Team and organisational access boundaries. Genuinely different permission sets and genuinely different blast radius deserve genuinely different agents — each with its own identity, so least-privilege actually means something. 5. At least one dev agent. Always keep a non-production agent to test changes before they touch prod. Same reason you have a staging environment. That’s the whole list. Everything else, consolidate. Ideally, this is what it looks like. A single agent per application or product module — never splitting one across two. Explicit production and test agents. A regional agent wherever residency genuinely demands one. Every split maps to one of the five considerations above. The one thing to protect in every split decision is context. When two agents need to reason about the same problem, each one only has half the picture. If you absolutely must split context — say your org structure or access boundaries require it — plan for those agents to talk to each other so the full context is still reachable. Multiple patterns work. A dedicated infrastructure team that manages AKS clusters and only cares about the upkeep of that infrastructure? A single agent scoped to those resources makes perfect sense — they have a clear domain, a clear boundary, and a clear job. An application team whose service depends on a database? Give that application’s agent access to the database rather than standing up a second agent and splitting the problem’s context across two. There’s no single right layout — the principle is: keep the context of the problems you’re trying to solve together. Step 2: Teach it — context is king This is where the magic actually comes from, and it’s the step most worth over-investing in. Your agent needs five kinds of context: Source code — what the system actually does Production telemetry — what it’s doing right now Institutional knowledge — how your team really operates Previous incidents — what broke before, and why Skills and tools — how to act on any of it Connect the first two and you have a competent log reader. Add the middle two and it starts sounding like someone who’s worked on your team for a year. How you actually bring context in: Connect the real sources — subscriptions and their telemetry, your repositories, your incident history, your ticketing system. Knowledge as markdown in a repo. This is the pattern that works best. LLMs are exceptionally good with markdown files, and putting your knowledge in a connected repository means it’s version-controlled, reviewable, and — critically — updatable by the agent itself. Your scheduled tasks can automatically improve these files as the agent learns, closing the loop between insight and artifact. Connect external knowledge via MCP. If your team’s knowledge lives in Confluence, SharePoint, or another platform, connect it as an MCP server rather than migrating it. The agent queries it at runtime. Upload documents. Architecture diagrams, architecture decision records, design docs, onboarding guides. It reads all of it. Just talk to it. This is the underrated one. Tell it how your system works. Explain that “the blue cluster” means the EU stamp, that Tuesday deploys are riskier, that this alert is always noise before 8am. Ask it to summarise your architecture back to you — where it’s wrong, you’ve found a context gap, and you can fill it on the spot. One thing to be deliberate about: don’t dump everything. If you’ve accumulated years of documentation, runbooks, and tribal knowledge, resist the urge to pour all of it in on day one. Garbage in, garbage out. The agent will work with whatever you give it, and outdated or contradictory knowledge makes it worse, not better. Curate intentionally. Start with the knowledge that matters for the scenarios you’re tackling first, make sure it’s current, and grow from there. Teaching an agent feels remarkably like onboarding a sharp new hire. The difference is it reads everything you give it, overnight, and never forgets. And you don’t have to teach it everything at once. This is the part worth saying plainly, because the size of an estate can feel paralysing. You are not trying to pour your entire organisation into an agent before it becomes useful. You teach it the parts that matter, and you do it organically — one solution at a time. Start from your toil. Write down the things that actually wake your engineers up, the tasks your team does over and over, the investigation everyone dreads because it takes four hours and always ends the same way. Pick the top one. Coach the agent through that single scenario the way you’d coach a new engineer through their first on-call shift — the context it needs, the sources it should check, the judgement calls that aren’t written down anywhere. Then do the next one. Each scenario you teach is narrow, which means it’s cheap and fast to get right. And each one compounds: the context you gave it for scenario one is already there when you start scenario three. Six weeks in, you’ll notice it knows your system well enough to help with things you never explicitly taught it. Don’t boil the ocean. Boil the thing that’s burning you. Step 3: Create the artifacts — understand the primitives, then build Before you build anything, it helps to understand the three primitives you’re building with — because the difference between them is what gives you consistency. The meta agent is your agent out of the box. It has the LLM’s world knowledge plus all the context you’ve connected — your code, your telemetry, your documents, your memory. It’s versatile: it can investigate, reason, plan, and act. But it’s non-deterministic. Ask it the same question twice and it might take different steps, in a different order, and format its findings differently. That’s fine for exploration. It’s not fine for the 3am incident that needs to run the same way every time. Custom agents give you that consistency. A custom agent is a specialist with its own instructions, its own tools, and its own scope. Think of it as the what — the plan. The Zava learning lab’s learning-ops agent is a good example: it tells the agent exactly how to handle an incident — what to check, in what order, what to post, how to format the report. Every run follows that plan. Custom agents are scoped — they’re only invoked when you specifically ask for them (via /agent in chat, or via a response plan or scheduled task). That scoping is itself a governance lever, which we’ll come back to in Step 5. Skills are the how. They’re reusable procedures that teach the agent how to do a specific thing — query your Kusto cluster, restart a container app, read an IcM incident, run a particular diagnostic sequence. Skills are universal: both the meta agent and any custom agent can use them. A single skill written once is available everywhere. The key insight: the meta agent alone will get you far, but it won’t do the same ten steps next time, or in the same order, or produce the same kind of report. Custom agents and skills give you that repeatability — and repeatability is what you need for automation you trust. Now — how you actually create them. There are exactly two on-ramps, and which one you take depends on whether you already know the answer. Path A — you have a runbook (a known problem). Throw the runbook at the agent and ask it to build the artifacts: the skill, the custom agent, the tool definitions. Review what it produces, refine it, and have it cut a pull request into your repository. A procedure you’d have hand-written over a week arrives in an afternoon. Path B — you don’t (a complex or unknown problem). Work it interactively. Hand the agent the live problem and investigate together. Let it dig, watch it waver, correct its wrong turns, point it at the source it didn’t know about. When you finally crack it — that’s the moment. Ask it to turn what just happened into a custom agent, a skill, a tool. The next time that problem appears, it’s automatic. Path B is the one people don’t expect, and it’s the more valuable of the two. Your best artifacts aren’t written at a desk. They’re precipitated out of real investigations that worked. Every hard incident you solve together becomes an incident you never have to solve again. This isn’t unusual, either — teams everywhere now run skill-creating skills, agent-building skills, and MCP-server-building skills. Using the agent to build more of the agent is simply how this works now. Step 4: Test it — playground first, then non-prod Treat agent artifacts like code, because they are. Start in the playground — a safe space to exercise a skill against realistic inputs without touching anything. Then promote to a non-production system where the agent can act for real against resources that don’t matter. You won’t get everything right before production, and you don’t need to. Get the critical parts right — the core logic, the safety boundaries, the happy path — and then put it on real work. That’s where you find out what it’s actually like. From there, use evals to improve continuously. Every real run produces one, and reading them is how you find out whether the artifact holds up outside the playground. Part Two covers what to do with that signal — including how to wire it back into the artifacts automatically. And because these are production artifacts, they belong in source control from the beginning — with review, diffs, and rollback. Step 5: Govern it — earn the right to automate Remember principle four: governance creates trust. This is where you make it concrete. Before anything touches production, you decide who the agent is, what it’s allowed to do, what rules gate its actions, and what checks run in context. These controls layer on top of each other, and together they’re what lets you say yes to autonomy with confidence. Identity and access Your agent authenticates as a managed identity — system-assigned or user-assigned — and you scope it with normal Azure RBAC at the subscription, resource group, or management group level. Out of the box, Azure SRE Agent offers two access tiers: Reader — read-only access to your resources. This is all your agent needs for investigation, root-cause analysis, and reporting. It’s the right starting point. Privileged — adds resource-type-specific contributor roles (like Container App Contributor) based on what’s detected in your environment. This is what the agent needs for actions: restart, scale, rollback, configuration changes. Most teams start with Reader and add Privileged only on the resource groups where they want the agent to act. If neither tier fits — maybe you want the agent to restart App Services but never touch network rules — create a custom RBAC role with exactly the permissions you need and assign it to the agent’s managed identity. The agent’s identity is its security boundary; treat it the way you’d treat any other service principal. Run mode This is the single biggest lever. In Review mode, the agent proposes actions and waits for a human to approve each one. In Autonomous mode, it acts on its own within the bounds you’ve set. Most teams start every scenario in Review, watch it work for a few weeks, and then selectively move well-understood scenarios to Autonomous. That graduation is the Crawl-to-Run climb in practice. There’s a third thing worth understanding: what happens when the agent doesn’t have the privileges to act. If the agent’s managed identity lacks the RBAC permission for an action, it doesn’t fail silently — it asks. An Administrator can grant temporary elevation via on-behalf-of (OBO), which lets the action execute using the human’s credentials rather than the agent’s identity. This is the human-in-the-loop pattern at its most precise: the agent does the investigation, proposes the action, and a human with the right privileges authorises it in context. The agent never accumulates permissions it doesn’t need permanently, and the audit trail shows exactly who approved what. Tool controls Every tool the agent has access to can be set to one of three states: Allow — the tool executes without asking. Good for safe read operations you’re confident about. Ask — the tool pauses for human approval before running. Good for actions you trust but want to see before they happen. Off — the tool is completely disabled. The agent can’t use it at all. This is the first governance layer — simple, per-tool toggles. Need the agent to query your Kusto cluster but never write to it? Allow the read tool, turn the write tool off. Need it to restart an App Service but never delete one? Allow the restart, turn delete off. This is how you define the agent’s basic operational envelope. Some actions — like restarting a healthy service or scaling up a container app — may not need any gating at all. Others — like modifying a network security group or changing a database configuration — absolutely do. The right setting depends on how much autonomy you want the agent to have and how much you want a human involved. There’s no single right answer; there’s the answer that fits your comfort level today, and it can change tomorrow. Tool access policies Tool controls are per-tool on/off switches. Tool access policies go deeper: they let you write pattern-based rules that match tool names and even command arguments. Examples: - “Deny any command containing delete “ — bash(az * delete *) matches any az ... delete ... command regardless of which tool executes it. - “Allow all monitoring queries without approval” — so your read-only investigation flow runs uninterrupted. - “Ask before any deployment command” — so deploys always pause for a human. Policies apply at three scopes: Scope Who sets it What it can do Global Admin Allow, Ask, or Deny — across the entire agent Custom agent Admin or author Allow only — widen access within global boundaries for a specific custom agent Thread Any user Allow only — temporary override for one conversation The key principle: a global deny cannot be overridden by a lower scope. A custom agent or thread can widen access but never weaken a global deny. This means an admin can set a floor — “nobody, human or agent, can run a delete command” — and know it holds. Hooks Policies match patterns. Hooks evaluate context. This is the layer that handles the cases patterns can’t express. Four hook events: Event When it fires What you’d use it for Start A new thread begins Seed context, validate the trigger, tag the conversation PreToolUse The agent is about to call a tool Inspect the arguments, allow/deny/ask based on what you see PostToolUse A tool just returned Audit the result, flag sensitive output, trigger follow-up Stop The agent is about to finish Validate that the work is complete, reject and keep the loop running if it’s not Hooks can be prompt-based (an LLM judge evaluates the situation) or command-based (a bash or Python script runs deterministically). They sit at the highest priority in the decision chain — a hook allow overrides everything below it, and a hook deny blocks immediately. Here’s where it gets practical. Say the agent is investigating a performance issue and discovers a corrupt database index. It decides to drop and rebuild the index — exactly what a DBA would do. But you don’t want the agent to ever drop a table. How do you allow one and prevent the other? Three layers, working together: Tool access policy: a global deny on any command matching *DROP TABLE* . Pattern-based, unconditional, always enforced. Custom agent scoping: create a database-maintenance custom agent with instructions that explicitly say “you may drop and rebuild indexes; you may never drop tables.” The custom agent only has the database tools it needs — nothing else. The blast radius is contained by design. PreToolUse hook: a script that inspects the actual SQL command. It allows DROP INDEX , denies DROP TABLE , and can require approval for any DDL command above a risk threshold you define. The policy catches the obvious pattern. The custom agent constrains the scope. The hook handles the edge cases that patterns miss. This is the full stack working together. Scoping automations to a custom agent is one of the most powerful governance levers you have. Instead of giving the meta agent broad database access, you create a specialist with its own tools, its own instructions, its own tool access policies, and its own hooks. The meta agent can investigate and recommend. Actual database changes only happen through the custom agent, with guardrails purpose-built for that domain. Who can configure the agent RBAC extends to the agent itself. Four built-in roles govern who can do what: Role What they can do Administrator Full control — approve actions, manage connectors, configure hooks and policies, change run mode, deploy artifacts Author Create custom agents and tools, upload knowledge, author response plans and incident configurations, manage connectors Standard User Chat, run diagnostics, request actions, create scheduled tasks Reader View conversations and configuration — read-only Separation of duties applies here the same way it applies everywhere else: the person who builds a skill shouldn’t necessarily be the person who promotes it to Autonomous. Only Administrators can approve infrastructure actions — Standard Users and Authors cannot. And only Administrators can create hooks and tool access policies, because those controls govern what every other role can do. How it all fits together These controls layer: identity sets the boundary, run mode sets the default posture, tool controls set the envelope, policies set the rules, and hooks handle the judgement calls. They’re not restrictions — they’re what lets you say yes to progressively more autonomy, with evidence that each step is safe. A useful mental model: governance isn’t a gate you pass through once. It’s the dial you turn up gradually, scenario by scenario, as each one proves itself. The agent that’s fully autonomous for certificate renewals and fully gated for database changes isn’t half-governed — it’s precisely governed. Step 6: Promote to production — your agent configuration is code This is the step that turns your dev agent into a repeatable, auditable production system. Your dev agent is your workshop — the place where you experiment, teach, build artifacts, and iterate until things work. Once they do, the configuration you’ve built there becomes your golden state: the skills, custom agents, tool definitions, knowledge base, response plans, scheduled tasks, and memory that together define how this agent operates. All of it can be declared, versioned, and deployed programmatically: Infrastructure as Code — define agents and their configuration in Bicep or Terraform, same as any other Azure resource. Your agent’s entire shape lives in a template. CLI and REST API — create, update, and configure agents with az commands or direct API calls. Useful for CI/CD pipelines that promote artifacts from dev to prod as part of a normal release. Artifact repositories — skills, custom agents, and tool definitions are files in your repo. Push them to your production agent the same way you push code: through a pipeline, with review, with rollback. This means everything your dev agent learned can flow to production through your existing change process. A new skill gets built and tested in dev, reviewed in a PR, merged, and deployed to the production agent by the pipeline — no portal clicking, no manual replication, no drift. It also means consistency across a fleet. If you run multiple agents — per module, per region, per environment — they can all be powered from the same artifact repository. Update the skill once, deploy it everywhere. The agent-per-module pattern from Step 1 works precisely because IaC makes it cheap to keep them consistent. And when something goes wrong, you roll back the same way you roll back anything else: revert the commit, redeploy the template, and the agent is back to its last known-good state. Step 7: Wire it up — an artifact does nothing until something calls it A skill sitting in your repository doesn’t do anything until it’s bound to a trigger — something in your world that fires it without a human deciding to. It’s an easy step to skip, and worth not skipping. There are three you’ll use constantly: Incident response plans. Attach the artifact to an alert class, so that when that alert fires, that skill runs. This is the single highest-value wiring you can do. Scheduled tasks. For work that should happen on a rhythm rather than in response to a signal — the nightly sweep, the weekly review, the monthly audit. HTTP triggers. For everything else in your ecosystem that wants to start agent work: a pipeline stage, a webhook, a work item transitioning to Ready. Here’s why this matters more than it looks. Remember the climb — Crawl, Walk, Run, Fly. Teams often assume they’ll graduate by making the agent smarter. They won’t. A brilliantly capable agent that only ever runs when someone opens a chat window is still at Walk, permanently, because a human is still initiating every piece of work. Capability doesn’t promote you. Triggers do. Wiring is the actual line between Walk and Run. Cross it deliberately. Step 8: Mimic your production process Here’s the step that turns a clever assistant into an operations teammate: the agent should follow the process your humans already follow. Not a parallel workflow. The workflow. An incident arrives → the agent acknowledges it, so everyone can see it’s owned → it investigates, pulling telemetry, correlating recent deploys, checking dependencies → it posts its findings to the incident, where the on-call already lives → it proposes or applies the mitigation → it updates status → it documents the root cause → it resolves. That’s end-to-end incident investigation and remediation, in the same lifecycle, the same ticket, the same channel your team already watches. No new tool to learn. The on-call engineer just notices the work is already done. And this covers more ground than people expect. Most teams think of incidents in three flavours: outages, where something is down; performance issues, where something is slow or degrading; and manual errors — the config change somebody made by hand at the end of a long day, the setting that got flipped in the portal and never made it back into source control. That third category is the one teams under-count and the one agents are unusually good at, because catching it is mostly a matter of comparing what’s running against what was declared — patient, unglamorous work that nobody wants to do at 2am. A worked example. The Zava learning lab agent runs exactly this loop — incident-triggered investigation and remediation across a live estate. Looking at its real runs: a typical end-to-end run takes about 32 tool calls and lands in a 5-to-12-minute band, with a median around 8.6 minutes from signal to finished work. Roughly five minutes to a mitigation, ten to a full resolution. Compare that with what it replaces: a page, someone waking up, ten minutes to orient, a scramble across dashboards, a colleague pulled in for a second opinion. Ninety minutes and two engineers, on a good night. A second example, from the other end of the lifecycle. A large software vendor running a multi-region estate — dozens of subscriptions, tens of thousands of resources — wired their agents into delivery rather than just incidents. A work item moves to Ready, and that’s the trigger. A custom agent picks it up, writes the code, opens the pull request, deploys the change to a test environment, and runs the validation suite against it — synthetic checks and browser-driven tests, the same ones a human would have run. Then it posts the result on the original work item. The engineer’s first involvement is reading an outcome that already has evidence attached. Same five design considerations from Step 1 govern their fleet: one agent per product module, explicit prod and test agents, and one extra agent in-region purely for data residency. These two examples bookend the same idea. One agent closes incidents; the other closes work items. Both were built the same way — context first, artifacts second, triggers third. Beyond incidents — the agent as a proactive partner It’s easy to think of agents as incident responders, because that’s where the value is most visible. But the best teams use them just as heavily when nothing is broken. Understand your system better. Ask the agent to explain your architecture back to you. Ask it what depends on what. Ask it to map the blast radius of a change you haven’t made yet. Ask it to find every resource in your estate that hasn’t been touched in six months, or every configuration that drifts from what’s declared in code. These aren’t investigations — they’re conversations. And the answers come grounded in your actual telemetry and source code, not a wiki page that was last updated in 2023. Get recommendations you didn’t ask for. Set up a scheduled task that reviews your infrastructure weekly and surfaces opportunities: resources that could be right-sized, SKUs that could be downgraded, replicas that could be consolidated, regions where you’re paying for redundancy you’re not using. The same task can check for reliability gaps: services without health probes configured, storage accounts without soft-delete enabled, deployments running without a rollback path. The agent sees all of it because it already has the context — it just needs a reason to look. Run proactive reliability reviews. Ask the agent to evaluate your service against the Azure Well-Architected Framework, or against your own best practices checklist. Ask it to compare your production configuration against your staging configuration and tell you what’s different — and whether the difference is intentional. Ask it to trace a customer-facing flow end to end and identify the single points of failure. Shift from reactive to preventive. This is the compounding value of the platform. Every incident the agent resolves teaches it something about your system. Over time, the agent that started as an incident responder becomes the thing that prevents incidents — because it’s seen enough of your system to spot the preconditions before they become symptoms. The cost analysis that catches the runaway resource before finance does. The capacity check that raises the quota before the 429s start. The configuration audit that catches the drift before it becomes an outage. The agent that only responds to incidents is useful. The agent that also prevents them is transformative. Part Two — Running it well Two loops, not one queue Once agents are working real incidents, the question stops being can it and becomes which ones. Make that a routing decision rather than a judgement call. Run two loops: an agent loop and a human loop. Every incident class is registered to one of them, so where an incident lands is a property of the class, decided in advance — not something someone works out at 3am. Promotion between loops is deliberate. Moving a class into the agent loop is a reviewable change with a written gate, and a written demotion trigger for when it stops earning its place. The safety net belongs to the incident system, not the agent. Define the conditions your process cares about — not acknowledged within x minutes, not mitigated, not handed off — and let the incident system escalate to the human loop when they’re breached. An agent that has stalled can’t be relied on to report that it has stalled; something outside it has to notice. And escalation should carry the work with it, so the human arrives to evidence already gathered rather than a blank page. Cost: know what an outcome costs One of the quietly wonderful things about agentic operations is that you can finally price an outcome. Agents consume metered units, and every unit maps to work. So instead of “what does our on-call cost?” — a question nobody has ever answered honestly — you get: this incident, end to end, cost this much. For the loop above: an entire incident investigated, mitigated, documented and resolved, in minutes, for under $30. Now price the alternative. Two engineers, ninety minutes, out of hours, plus the context-switch tax on whatever they were doing, plus the meeting the next morning to explain what happened. You’re comparing tens of dollars against hundreds — and that’s before you count the ninety minutes of customer impact that didn’t happen because the fix landed in eight minutes instead of an hour and a half. Multiply by your monthly incident volume and it stops being a cost conversation and starts being a capacity one. The question isn’t “can we afford this?” — it’s “what do we do with the engineering time we just got back?” But be careful not to measure the return only in money and minutes, because the larger part of it never shows up on an invoice. It’s the engineer who slept through the night. It’s the on-call rotation people stop quietly dreading, and the weekend that stayed a weekend. It’s the postmortem that never had to be written — and with it, the whole uncomfortable ritual of working out whose change it was — because the problem was caught and fixed while it was still one degraded instance rather than a customer-visible outage. Teams feel that long before finance notices the bill. Morale has always been a reliability metric; it just never had a dashboard. A few practical habits: - Set a consumption budget deliberately, and know who can raise it and how fast before you need them. - Watch cost per resolved outcome, not total spend. Total spend rising while cost-per-outcome falls is exactly what success looks like. - Use the right trigger for the job. Incident response plans and HTTP triggers bring the work to the agent the instant it matters. Scheduled tasks handle the work that belongs on a rhythm — the nightly sweep, the weekly review. Both have a place; the key is matching each scenario to the trigger that fits it. Live Reports — the UI beyond chat Most people first encounter their agent in a chat window, and chat is genuinely good for investigation and conversation. But it’s not the only surface — and for a lot of operational work, it’s not the best one. Live Reports are interactive HTML applications built by the agent and hosted on the platform. They call the same tools the agent uses — Kusto queries, Azure CLI, incident APIs, connector tools — and render the results as charts, tables, grids, and interactive controls. They’re not screenshots of a past conversation. They’re live applications that re-fetch data every time you open them. Here’s the part worth understanding from a cost perspective: the agent spends tokens when it builds the report — the conversation where you describe what you want. After that, opening the report calls the tools directly. No LLM is involved, so there’s no ongoing token consumption. Build it once, open it a hundred times, share it with your team — the investment is in the creation, and it pays off every time someone opens it. Think of Live Reports as the place where your agent’s intelligence becomes a permanent, shareable surface rather than a conversation that scrolls away. Scenarios where Live Reports shine: Morning triage view. What happened overnight? Which incidents are open, which were resolved autonomously, which need human attention? A single page your on-call opens at the start of every shift — always current, no queries to run. Agent fleet health. Across all your agents: which are healthy, which have degraded tool reliability, which haven’t run in a week? Per-tool success rates, outcome counts, cost-per-resolution trending. The monitoring dashboard you’d otherwise build in Grafana, except it’s already wired to the data. Governance and compliance. NSG audit results, CVE exposure by service, resource compliance against your policy baseline. The report that used to take two engineers a day to compile — now it’s a page that’s always current. Cost analysis. Per-agent spend, per-outcome cost, consumption trending with visual charts. The data that makes the cost conversation in Part Two actually work. On-call handover. A shift handoff report: what happened during this rotation, what’s still pending, what to watch. Built once, regenerated for every handover. Stakeholder status pages. Service health for leadership or customers — uptime, incident summary, SLA adherence — without exposing the underlying tools or conversations. Interactive explorers. Not just viewing data but acting on it. A compliance report where you can drill into a finding and ask the agent to open a remediation PR, right from the report surface. The pattern is the same every time: you tell the agent what you want to see, it builds the report, and from that point forward the report is a zero-cost, always-current application that anyone on your team can open. It’s the agent’s intelligence crystallised into a surface that doesn’t need the agent to be running. Monitor the agent You’ll want a few different lenses, because each sees something the others can’t: Layer What it gives you Live reports Your measurement dashboard — autonomy by scenario, throughput, tool reliability — refreshed from your own connectors every time you open it Scheduled tasks The agent reporting on itself: a weekly health narrative, and the loops that keep artifacts current Your own observability platform Independent health and reliability monitoring outside the agent — the layer that still works when the agent doesn’t Foundry Control Plane Auto-discovers your SRE agents across the subscription: status, error rate, run counts, plus start/stop/block lifecycle control, governed by normal Azure RBAC Agent 365 Organisation-wide registry, governance and security posture across every agent platform you run. Agent 365 is generally available; SRE Agent integration into it is on the roadmap One field-tested tip: track tool failure rate per tool, not in aggregate. The overall success rate in large estates typically sits above 98%, which is reassuring — but it can mask a single connector that needs a configuration fix. Watching each tool individually lets you catch those early, and the fix is usually straightforward: a stale token, a permission gap, a connector that needs reconnecting. Knowledge, evals and learning — insist on these Context isn’t a one-time setup. It’s a living asset, and it’s the thing that compounds — but only if your platform is built to let it. This is the section where what you’re running starts to matter a great deal, so it’s worth being direct about what to demand. Insist on an agent that learns without being told to. The common failure mode of agentic tooling is that all the good material stays in the chat thread. Someone works a hard problem with the agent at midnight, finally cracks it, and the reasoning evaporates when the tab closes. What you want instead is derived learning: the agent distils what it just worked out — the query that got there, the dead end worth avoiding, the service that behaves nothing like its documentation — and files it as durable, structured knowledge on its own, without anyone remembering to write it down. Azure SRE Agent does this automatically. Every investigation deposits something. What still needs your attention is the round trip to the original source of truth. Derived learning lives with the agent. Your runbook, your architecture note, your alert definition lives in your repository — and that’s the copy your humans read. Wire the automation that pushes a learning back into the original artifact as a pull request, so the knowledge doesn’t quietly fork into two versions. This is the single most valuable piece of plumbing most teams haven’t built yet. Insist on evals that run forever, not once. Evals get widely misread as a pre-production gate: test the skill, it passes, it ships, done. That’s the smaller half of the value. The bigger half is relentless — continuously evaluating the agent’s real runs in production. Did it stay in scope? Did it reach the right conclusion? Did it stop and ask when it should have? Did that skill quietly start failing at step four last Tuesday? Real traffic finds things no test suite will, and it finds them on your actual estate rather than on a fixture. Then close the loop, so eval results become work rather than a report nobody opens. Azure SRE Agent ships this as a first-class loop: scheduled tasks that watch the eval signal, notice the degradation, and act on it. Self-improvement — where it gets fun Which is where something rather lovely happens: the agent starts improving itself. It notices a runbook is out of date and updates it. It sees a skill failing at the same step and rewrites that step. It spots a recurring investigation and proposes a new custom agent to own it. It watches its own eval scores and opens a pull request against the artifact that slipped. Teams run learning-loop agents alongside their fleets, and watchdog agents that review other agents’ work. Every completed task should make the next task easier. That’s the flywheel — and it only turns when all three pieces are present: knowledge that accumulates by itself, evals that keep scoring real work, and automation wired to act on both. Put them together and the system stops being something you maintain and starts being something that maintains itself. Part Three — The Zero Ops journey: the art of the possible Now the fun part. Here’s what each rung actually feels like, across the scenarios teams really run. Crawl — the agent suggests, you do the work You’ve connected context and you’re asking questions. It’s already useful: “Which of these 40 alerts overnight actually mattered?” — and it tells you, with reasoning. At this rung the governance sweep produces its first report: here are your idle resources, here are the network rules that don’t match policy, here are the CVEs you’re exposed to. Just a list — but it’s a list nobody had time to produce before, and it took four minutes. The certificate scan tells you what expires in the next 90 days. The cost analysis names your top ten spenders and why they moved. The change reviewer reads an incoming change request and tells you, in plain language, what it actually touches and what depends on it — the blast-radius analysis somebody used to do by hand in a change advisory board meeting. You still do all the work. But for the first time, you can see everything. Walk — the agent does the work, one step at a time Now it acts, asking before each step. This is where investigation and root-cause analysis come alive. An alert fires and the agent has already pulled the telemetry, correlated the recent deployment, checked the dependency, and posted a probable cause on the incident — before the on-call has finished reading the title. The question responder starts answering “is the EU region healthy?” in your team channel, with evidence. The governance sweep grows a spine: it doesn’t just list the orphaned resources, it recommends what to do about each. The CVE report becomes a prioritised remediation plan. The change reviewer stops describing the change and starts drafting it — the implementation plan, the validation steps, and the rollback procedure, written before anyone approves anything. You approve every step. It feels slow. It is also where you discover exactly what your agent is good at — and every gap you find becomes tomorrow’s artifact. Run — the agent completes whole tasks; you review the change Triggers are wired now — incidents, webhooks, schedules — and work starts without you. This is the rung where the 3am page stops arriving. The alert-class handler takes a whole class end to end: fires on arrival, investigates, applies the safe mitigation — restart, scale up, roll back the release — documents it, resolves it. You read about it in the morning. This is the rung where the word self-healing finally earns its place. It’s worth being precise about what it means, because it’s a phrase that gets stretched: self-healing is when the agent detects a known failure class, decides on the response, and acts on it within bounds you pre-approved. Not “the agent does whatever it thinks best.” The class is chosen by you. The safe actions are enumerated by you. The agent’s contribution is that it does the work at 3am, correctly, without waking anyone — and tells you exactly what it did. And notice that this is granted per alert class, never per service. It’s completely normal for one fleet to run some classes at near-total autonomy while other classes sit at a deliberate zero, because nobody’s ready yet. That’s not inconsistency. That’s the control working. The capacity agent sees the quota curve heading for a wall and raises it before anything breaks. The certificate agent opens the renewal PR on schedule. The maintenance agent handles the planned work that used to eat somebody’s weekend — the scheduled patching round, the index rebuild, the node pool rotation — running it in the window, verifying it landed, and reporting on it. The change agent executes the approved change in non-production, validates it, and raises the pull request and the change record together. The governance sweep stops recommending and starts acting — opening pull requests against your infrastructure-as-code to close the findings it used to just report. The CVE backlog that only ever grew? It starts going down, because something is working it every single day. And the work-item loop appears: a backlog item goes in, a custom agent writes the code and opens a pull request. You review the diff. Which is exactly when you meet the review wall. Fly — the agent proves the outcome, and improves the system Fly is not “the agent can execute.” It’s two much better things. Fly, part one: the agent can prove the outcome is correct. It builds the fix. It deploys it to a test environment. It runs the validation itself — synthetic checks, browser tests, the full suite. Then it posts the evidence. You stop reviewing the diff and start reviewing the outcome. That’s how the wall comes down. Now the work-item loop closes completely: backlog item → code → deploy → tested → evidence posted. The release-safety agent doesn’t just roll back after an incident, it gates the deploy beforehand — validating in test and blocking the bad one. The governance sweep pushes its own fix to production, having proven in test that it works. And your standard changes — the well-understood, pre-approved, thousand-times-executed ones — get carried out in production end to end, validated, and the change record closed with the evidence attached. The change advisory board stops reviewing procedure and starts reviewing outcomes, which is what it always wanted to be doing. Fly, part two: the agent improves the system. It learns from every incident. It improves knowledge, artifacts, runbooks, skills — and its own custom agents. The alert-quality loop turns inward: it notices which of your alerts are chronic false positives and opens PRs to fix the alert rules themselves. Your monitoring gets better while you sleep. The system gets better without a human editing it. And back to where we started That 3am page? A whole class of them doesn’t reach a person anymore. The fortnight-long cost review? A standing job that finds the waste and opens the PR. The zero-day marathon? The agent maps exposure across every service in minutes, patches in test, proves it works, and hands you evidence. The CVE backlog that only grew? Something works it every day, and it shrinks. That’s Zero Ops. Not zero humans — zero operations for humans. Your people set intent, govern the system, and validate outcomes. Everything below that line takes care of itself. The proof We run Microsoft this way. Every number here is queryable — these aren’t product metrics, they’re trust metrics. Today: - 2,500+ Microsoft engineering teams - 5,400+ agents running in production - Median time from alert to mitigation: 4 minutes To date: - 1.47M incidents processed - 221K mitigated autonomously - 1.25M enriched for the on-call engineer - ~1M developer hours saved* In the last month alone: - 480K incidents handled - 91K mitigated autonomously - 32M agent actions executed - 60K deploy-and-validate runs - 97.9% of agent work ran autonomously That last number is the one worth sitting with. Ninety-eight percent of the work happens with no human in the conversation — and the two percent that does reach a person is the two percent that genuinely needs judgement. In closing It isn’t about building a better agent. It’s about building a system that deserves autonomy. Context makes it intelligent. Governance makes it trustworthy. Metrics make it provable. When those three come together — agents operate, and humans govern. And the best news: you don’t have to build this from the ground up. Azure SRE Agent already carries these learnings — the context, the governance, the evidence, and the metrics — so your team can start today. Pick one scenario. Give it context. Teach it your system. Work a real problem with it, and turn what you learn into something that persists. Then do it again next week. Start your Zero Ops journey: aka.ms/sreagent · Resources and community: aka.ms/sreagent/links *AI-calculated estimate, based on a conservative earlier baseline.1.7KViews6likes0CommentsHow we build and use Azure SRE Agent with agentic workflows
The Challenge: Ops is critical but takes time from innovation Microsoft operates always-on, mission-critical production systems at extraordinary scale. Thousands of services, millions of deployments, and constant change are the reality of modern cloud engineering. These are titan systems that power organizations around the globe—including our own—with extremely low risk tolerance for downtime. While operations work like incident investigation, response and recovery, and remediation is essential, it’s also disruptive to innovation. For engineers, operational toil often means being pulled away from feature work to diagnose alerts, sift through logs, correlate metrics across systems, or respond to incidents at any hour. On-call rotations and manual investigations slow teams down and introduce burnout. What's more, in the era of AI, demand for operational excellence has spiked to new heights. It became clear that traditional human-only processes couldn't meet the scale and complexity needs for system maintenance especially in the AI world where code shipping velocity has increased exponentially. At the same time, we needed to integrate with the AI landscape which continues to evolve at a breakneck pace. New models, new tooling, and new best practices released constantly, fragmenting ecosystems between different platforms for observability, DevOps, incident management, and security. Beyond simply automating tasks, we needed to build an adaptable approach that could integrate with existing systems and improve over time. Microsoft needed a fundamentally different way to perform operations—one that reduced toil, accelerated response, and gave engineers the time to focus on building great products. The Solution: How we build Azure SRE Agent using agentic workflows To address these challenges, Microsoft built Azure SRE Agent, an AI-powered operations agent that serves as an always-on SRE partner for engineers. In practice, Azure SRE Agent continuously observes production environments to detect and investigate incidents. It reasons across signals like logs, metrics, code changes, and other deployment records to perform root cause analysis. It supports engineers from triage to resolution and it’s used in a variety of autonomy levels from assistive investigation to automating remediation proposals. Everything occurs within governance guardrails and human approval checks grounded in role‑based access controls and clear escalation paths. What’s more, Azure SRE Agent learns from past incidents, outcomes, and human feedback to improve over time. But just as important as what was built is how it was built. Azure SRE Agent was created using the agentic workflow approach—building agents with agents. Rather than treating AI as a bolt-on tool, Microsoft embedded specialized agents across the entire software development lifecycle (SDLC) to collaborate with developers, from planning through operations. The diagram above outlines the agents used at each stage of development. They come together to form a full lifecycle: Plan & Code: Agents support spec‑driven development to unlock faster inner loop cycles for developers and even product managers. With AI, we can not only draft spec documentation that defines feature requirements for UX and software development agents but also create prototypes and check in code to staging which now enables PMs/UX/Engineering to rapidly iterate, generate and improve code even for early-stage merges. Verify, Test & Deploy: Agents for code quality review, security, evaluation, and deployment agents work together to shift left on quality and security issues. They also continuously assess reliability, ensure performance, and enforce consistent release best practices. Operate & Optimize: Azure SRE Agent handles ongoing operational work from investigating alerts, to assisting with remediation, and even resolving some issues autonomously. Moreover, it learns continuously over time and we provide Azure SRE Agent with its own specialized instance of Azure SRE Agent to maintain itself and catalyze feedback loops. While agents surface insights, propose actions, mitigate issues and suggest long term code or IaC fixes autonomously, humans remain in the loop for oversight, approval, and decision-making when required. This combination of autonomy and governance proved critical for safe operations at scale. We also designed Azure SRE agent to integrate across existing systems. Our team uses custom agents, Model Context Protocol (MCP) and Python tools, telemetry connections, incident management platforms, code repositories, knowledge sources, business process and operational tools to add intelligence on top of established workflows rather than replacing them. Built this way, Azure SRE Agent was not just a new tool but a new operational system. And at Microsoft’s scale, transformative systems lead to transformative outcomes. The Impact: Reducing toil at enterprise scale The impact of Azure SRE Agent is felt most clearly in day-to-day operations. By automating investigations and assisting with remediation, the agent reduces burden for on-call engineers and accelerates time to resolution. Internally at Microsoft in the last nine months, we've seen: 35,000+ incidents have been handled autonomously by Azure SRE Agent. 50,000+ developer hours have been saved by reducing manual investigation and response work. Teams experienced a reduced on-call burden and faster time-to-mitigation during incidents. To share a couple of specific cases, the Azure Container Apps and Azure App Service product group teams have had tremendous success with Azure SRE Agent. Engineers for Azure Container Apps had overwhelmingly positive (89%) responses to the root cause analysis (RCA) results from Azure SRE agent, covering over 90% of incidents. Meanwhile, Azure App Service has brought their time-to-mitigation for live-site incidents (LSIs) down to 3 minutes, a drastic improvement from the 40.5-hour average with human-only activity. And this impact is felt within the developer experience. When asked developers about how the agent has changed ops work, one of our engineers had this to say: “[It’s] been a massive help in dealing with quota requests which were being done manually at first. I can also say with high confidence that there have been quite a few CRIs that the agent was spot on/ gave the right RCA / provided useful clues that helped navigate my initial investigation in the right direction RATHER than me having to spend time exploring all different possibilities before arriving at the correct one. Since the Agent/AI has already explored all different combinations and narrowed it down to the right one, I can pick the investigation up from there and save me countless hours of logs checking.” - Software Engineer II, Microsoft Engineering Beyond the impact of the agent itself, the agentic workflow process has also completely redefined how we build. Key learnings: Agentic workflow process and impact It's very easy to think of agents as another form of advanced automation, but it's important to understand that Azure SRE agent is also a collaborative tool. Engineers can prompt the agent in their investigations to surface relevant context (logs, metrics, and related code changes) to propose actions far faster and easier than traditional troubleshooting. What’s more, they can also extend it for data analysis and dashboarding. Now engineers can focus on the agent’s findings to approve actions or intervene when necessary. The result is a human-AI partnership that scales operations expertise without sacrificing control. While the process took time and experimentation to refine, the payoff has been extraordinary; our team is building high-quality features faster than ever since we introduced specialized agents for each stage of the SDLC. While these results were achieved inside Microsoft, the underlying patterns are broadly applicable. First, building agents with agents is essential to scaling, as manual development quickly became a bottleneck; agents dramatically accelerated inner loop iteration through code generation, review, debugging, security fixes, etc. In practice, we found that a generic agent—guided by rich context and powered by memory and learning—can continuously adapt, becoming faster and more effective over time as it builds experience. This allows the agent to apply prior knowledge, avoid relearning, and reduce the effort required to resolve similar problems repeatedly. In parallel, specialized agents help bring consistency and repeatability to well‑defined categories of incidents, encoding proven patterns, workflows, and safeguards. Together, these approaches enable systems that both adapt to new situations and respond reliably at scale. Microsoft also learned to integrate deeply with existing systems, embedding agents into established telemetry, workflows, and platforms rather than attempting to replace them. Throughout this process, maintaining tight human‑in‑the‑loop governance proved critical. Autonomy had to be balanced with clear approval boundaries, role‑based access, and safety checks to build trust. Finally, teams learned to invest in continuous feedback and evaluation, using ongoing measurement to improve agents over time and understand where automation added value versus where human judgment should remain central. Want to learn more? Azure SRE Agent is one example of how agentic workflows can transform both product development and operations at scale. Teams at Microsoft are on a mission of leading the industry by example, not just sharing results. We invite you to take the practical learnings from this blog and apply the same principles in your own environments. Discover more about Azure SRE Agent Learn about agents in DevOps tools and processes Read best practices on agent management with Azure10KViews4likes1CommentA Paradigm Shift in Cloud Operations with Azure SRE Agent
Cloud operations are entering a new era. As systems grow in scale and complexity, the traditional model of reactive incident response, where engineers manually piece together signals across dozens of tools and portals, juggling all that context alone, is no longer sustainable. The operational toil required to keep systems running shipping new capabilities. The question is straightforward: what if engineers could spend most of their time building instead of maintaining? To help organizations make that shift, today we’re sharing how Zafin, Provation Medical, and InEight are rethinking cloud operations with Azure SRE Agent. The SRE Agent product team has been working side by side with these customers, embedding with their engineering teams to agentify their cloud operations. What follows is the story of that collaboration and the results it produced. From hours to minutes across industries We worked closely with Zafin starting October last year. As the onboarding progressed, and Zafin’s scenarios became more sophisticated, Zafin’s security team needed confidence that the agent would respect their access boundaries at scale. We worked closely to configure granular RBAC, and scoping needed for multi-user rollout. “Azure SRE Agent transformed how we approach incident response. We’ve moved from fragmented signals and manual triage to an intelligence-driven model where agents collect evidence, classify issues, and recommend actions before our engineers even engage. We’ve taken incident triage from hours down to minutes, and we’re now expanding this automation across observability, health monitoring, and incident management. As an AI platform company serving tier 1 banks globally, that speed, accuracy, and enterprise-grade governance is exactly what we need.” — George K Mathew, SVP Cloud & Business Operations, Zafin We partnered with Provation on initial onboarding, connecting Azure DevOps as an incident source so the agent could begin triaging production support tickets. From there, they expanded into proactive health checks on their own. “When software runs reliably, care teams can focus on their patients instead of technology. At Provation, a leading provider of clinical productivity software, we’re continuing to advance our AI-powered software development lifecycle with Azure SRE Agent, Microsoft’s AI-powered reliability service. When a support ticket comes in, Azure SRE Agent pulls together the context an engineer needs to understand what the system was doing, what code recently changed, likely contributing factors, and recommended next steps. That analysis drops directly into our team’s normal workflow. In its first month, Azure SRE Agent provided analysis for all of our production-related tickets. Instead of checking multiple locations, engineers can start with more context already in front of them, helping work move forward more consistently and efficiently. Azure SRE Agent also supports our development environments, helping engineers review emerging patterns earlier in the process and create follow-up work with measurable first-month results, contributing to more than a quarter of related investigation tickets during that period. That’s what AI-assisted software development looks like day to day at Provation: intelligent tools integrated into the systems our teams already use, so healthcare providers get a smoother experience from start to finish.” — Paul Snider, CTO, Provation Medical With InEight, our engagement started with an on-site workshop where the agent diagnosed a live production bug their team had been unable to reproduce. That result drove rapid expansion, and we collaborated closely as InEight scaled from one product to multiple products and teams in three months. “SRE Agent is helping InEight transform how engineering operates. By embedding AI into software delivery, reliability engineering, quality assurance, security, and operational workflows, we are reducing manual effort, accelerating delivery, improving stability, and creating a scalable foundation for future growth. Incident investigation is down 80 percent, build failure triage down 80 percent, and bug investigation down 67 percent. Azure SRE Agent is the only tool we have found that reasons across source code, live telemetry, and Azure infrastructure simultaneously, in a single conversation. For a company operating a large suite of integrated products on Azure, that capability is not incremental. It is transformational.” — Jim Ellerbeck, Vice President of Technology, InEight Built on governance and memory Faster resolution is the most visible outcome, but not the full story. The reason these customers trust the agent with production operations comes down to two things: governance and memory. Governance is what makes this level of autonomy possible. The agent explains what it intends to do and why before acting, and every interaction produces a full audit trail. Routine operations run autonomously; actions designated high-impact pause for in-workflow sign-off. VNet integration routes traffic through your own network - NSG rules, private DNS, and firewalls all apply - while least-privilege access and granular tool-level policies keep the agent operating under your rules. Memory is what makes the system compound. Every investigation captures root causes, resolution steps, team preferences, and operational patterns. That knowledge persists across conversations. New team members ramp faster. On-call quality stays consistent regardless of who is paged. The collective expertise of the team grows automatically and never leaves when people do. From maintaining to building The pattern emerging from these customers points to a fundamental shift in what it means to run services. Traditional operations are giving way to an agent-driven model where the cognitive burden of monitoring, diagnosing, and resolving issues is lifted. When the agent handles the investigative toil, captures institutional knowledge, and gets smarter with every interaction, engineering teams can redirect their energy toward building the next generation of products and services. The teams adopting this model are not just operating faster. They are innovating faster, because their best people are no longer trapped in reactive maintenance cycles. Azure SRE Agent is generally available. Visit https://sre.azure.com to create your first agent in minutes.1.8KViews3likes2Comments
From Vibe Coding to Working App: How SRE Agent Completes the Developer Loop
The Most Common Challenge in Modern Cloud Apps There's a category of bugs that drive engineers crazy: multi-layer infrastructure issues. Your app deploys successfully. Every Azure resource shows "Succeeded." But the app fails at runtime with a vague error like Login failed for user ''. Where do you even start? You're checking the Web App, the SQL Server, the VNet, the private endpoint, the DNS zone, the identity configuration... and each one looks fine in isolation. The problem is how they connect and that's invisible in the portal. Networking issues are especially brutal. The error says "Login failed" but the actual causes could be DNS, firewall, identity, or all three. The symptom and the root causes are in completely different resources. Without deep Azure networking knowledge, you're just clicking around hoping something jumps out. Now imagine you vibe coded the infrastructure. You used AI to generate the Bicep, deployed it, and moved on. When it breaks, you're debugging code you didn't write, configuring resources you don't fully understand. This is where I wanted AI to help not just to build, but to debug. Enter SRE Agent + Coding Agent Here's what I used: Layer Tool Purpose Build VS Code Copilot Agent Mode + Claude Opus Generate code, Bicep, deploy Debug Azure SRE Agent Diagnose infrastructure issues and create developer issue with suggested fixes in source code (app code and IaC) Fix GitHub Coding Agent Create PRs with code and IaC fix from Github issue created by SRE Agent Copilot builds. SRE Agent debugs. Coding Agent fixes. What I Built I used VS Code Copilot in Agent Mode with Claude Opus to create a .NET 8 Web App connected to Azure SQL via private endpoint: Private networking (no public exposure) Entra-only authentication Managed identity (no secrets) Deployed with azd up. All green. Then I tested the health endpoint: $ curl https://app-tsdvdfdwo77hc.azurewebsites.net/health/sql {"status":"unhealthy","error":"Login failed for user ''.","errorType":"SqlException"} Deployment succeeded. App failed. One error. How I Fixed It: Step by Step Step 1: Create SRE Agent with Azure Access I created an SRE Agent with read access to my Azure subscription. You can scope it to specific resource groups. The agent builds a knowledge graph of your resources and their dependencies visible in the Resource Mapping view below. Step 2: Connect GitHub to SRE Agent using GitHub MCP server I connected the GitHub MCP server so the agent could read my repository and create issues. Step 3: Create Sub Agent to analyze source code I created a sub-agent for analyzing source code using GitHub mcp tools. this lets SRE Agent understand not just Azure resources, but also the Bicep and source code files that created them. "you are expert in analyzing source code (bicep and app code) from github repos" Step 4: Invoke Sub-Agent to Analyze the Error In the SRE Agent chat, I invoked the sub-agent to diagnose the error I received from my app end point. It correlated the runtime error with the infrastructure configuration Step 5: Watch the SRE Agent Think and Reason SRE Agent analyzed the error by tracing code in Program.cs, Bicep configurations, and Azure resource relationships Web App, SQL Server, VNet, private endpoint, DNS zone, and managed identity. Its reasoning process worked through each layer, eliminating possibilities one by one until it identified the root causes. Step 6: Agent Creates GitHub Issue Based on its analysis, SRE Agent summarized the root causes and suggested fixes in a GitHub issue: Root Causes: Private DNS Zone missing VNet link Managed identity not created as SQL user Suggested Fixes: Add virtualNetworkLinks resource to Bicep Add SQL setup script to create user with db_datareader and db_datawriter roles Step 7: Merge the PR from Coding Agent Assign the Github issue to Coding Agent which then creates a PR with the fixes. I just reviewed the fix. It made sense and I merged it. Redeployed with azd up, ran the SQL script: curl -s https://app-tsdvdfdwo77hc.azurewebsites.net/health/sql | jq . { "status": "healthy", "database": "tododb", "server": "tcp:sql-tsdvdfdwo77hc.database.windows.net,1433", "message": "Successfully connected to SQL Server" } 🎉 From error to fix in minutes without manually debugging a single Azure resource. Why This Matters If you're a developer building and deploying apps to Azure, SRE Agent changes how you work: You don't need to be a networking expert. SRE Agent understands the relationships between Azure resources private endpoints, DNS zones, VNet links, managed identities. It connects dots you didn't know existed. You don't need to guess. Instead of clicking through the portal hoping something looks wrong, the agent systematically eliminates possibilities like a senior engineer would. You don't break your workflow. SRE Agent suggests fixes in your Bicep and source code not portal changes. Everything stays version controlled. Deployed through pipelines. No hot fixes at 2 AM. You close the loop. AI helps you build fast. Now AI helps you debug fast too. Try It Yourself Do you vibe code your app, your infrastructure, or both? How do you debug when things break? Here's a challenge: Vibe code a todo app with a Web App, VNet, private endpoint, and SQL database. "Forget" to link the DNS zone to the VNet. Deploy it. Watch it fail. Then point SRE Agent at it and see how it identifies the root cause, creates a GitHub issue with the fix, and hands it off to Coding Agent for a PR. Share your experience. I'd love to hear how it goes. Learn More Azure SRE Agent documentation Azure SRE Agent blogs Azure SRE Agent community Azure SRE Agent home page Azure SRE Agent pricing1.2KViews3likes0CommentsAzure SRE Agent: Expanding Observability and Multi-Cloud Resilience
The Azure SRE Agent continues to evolve as a cornerstone for operational excellence and incident management. Over the past few months, we have made significant strides in enabling integrations with leading observability platforms—Dynatrace, New Relic, and Datadog—through Model Context Protocol (MCP) Servers. These partnerships serve joint customers, enabling automated remediation across diverse environments. Deepening Integrations with MCP Servers Our collaboration with these partners is more than technical—it’s about delivering value at scale. Datadog, New Relic, and Dynatrace are all Azure Native ISV Service partners. With these integrations Azure Native customers can also choose to add these MCP servers directly from the Azure Native partners’ resource: Datadog: At Ignite, Azure SRE Agent was presented with the Datadog MCP Server, to demonstrate how our customers can streamline complex workflows. Customers can now bring their Datadog MCP Server into Azure SRE Agent, extending knowledge capabilities and centralizing logs and metrics. Find Datadog Azure Native offerings on Marketplace. New Relic: When an alert fires in New Relic, the Azure SRE Agent calls the New Relic MCP Server to provide Intelligent Observability insights. This agentic integration with the New Relic MCP Server offers over 35 specialized tools across, entity and account management, alerts and monitoring, data analysis and queries, performance analysis, and much more. The advanced remediation skills of the Azure SRE Agent + New Relic AI help our joint customers diagnose and resolve production issues faster. Find New Relic’s Azure Native offering on Marketplace Dynatrace: The Dynatrace integration bridges Microsoft Azure's cloud-native infrastructure management with Dynatrace's AI-powered observability platform, leveraging the Davis AI engine and remote MCP server capabilities for incident detection, root cause analysis, and remediation across hybrid cloud environments. Check out Dynatrace’s Azure Native offering on Marketplace. These integrations are made possible by Azure SRE Agent’s MCP connectors. The MCP connectors in Azure SRE Agent act as the bridge between the agent and MCP servers, enabling dynamic discovery and execution of specialized tools for observability and incident management across diverse environments. This feature allows customers to build their own custom sub-agents to leverage tools from MCP Servers from integrated platforms like Dynatrace, Datadog, and New Relic to complement the agent’s diagnostic and remediation capabilities. By connecting Azure SRE Agent to external MCP servers scenarios such as cross-platform telemetry analysis are unlocked. Looking Ahead: Multi-Agent Collaboration Azure SRE Agent isn’t stopping with MCP integrations We’re actively working with PagerDuty and NeuBird to support dynamic use cases via agent-to-agent collaboration: PagerDuty: PagerDuty’s PD Advance SRE Agent is an AI-powered assistant that triages incidents by analyzing logs, diagnostics, past incident history, and runbooks to surface relevant context and recommended remediations. At Ignite, PagerDuty and Microsoft demonstrated how Azure SRE Agent can ingest PagerDuty incidents and collaborate with PagerDuty’s SRE Agent to complement triage using historical patterns, runbook intelligence and Azure diagnostics. NeuBird: NeuBird’s Agentic AI SRE, Hawkeye, autonomously investigates and resolves incidents across hybrid, and multi-cloud environments. By connecting to telemetry sources like Azure Monitor, Prometheus, and GitHub, Hawkeye delivers real-time diagnosis and targeted fixes. Building on the work presented at SRE Day this partnership underscores our commitment to agentic ecosystems where specialized agents collaborate for complex scenarios. Sign up for the private preview to try the integration, here. Additionally, please check out NeuBird on Marketplace. These efforts reflect a broader vision: Azure SRE Agent as a hub for cross-platform reliability, enabling customers to manage incidents across Azure, on-premises, and other clouds with confidence. Why This Matters As organizations embrace distributed architectures, the need for integrated, intelligent, and multi-cloud-ready SRE solutions has never been greater. By partnering with industry leaders and pioneering agent-to-agent workflows, Azure SRE Agent is setting the stage for a future where resilience is not just reactive—it’s proactive and collaborative.1.5KViews3likes0CommentsFrom Coding Agents to Cloud Automation: AI-Assisted Customer Related Incidents in Azure Functions
On the Azure Functions team, we have been exploring how AI can help with investigating customer-reported incidents, root-cause analysis, and incident mitigation. This post shares our journey from early RCA agents to coding-agent-assisted investigations and cloud-hosted automation, and the lessons we learned along the way. Microsoft Engineering teams like Azure Functions work on production live site issues alongside customer reported issues, and these are one of the most important and rewarding parts of the job. On the Azure Functions team, complex customer incidents often require deep investigation. Engineers review Azure Data Explorer (Kusto) query results, source code, GitHub issues, previous incidents, public documentation, internal troubleshooting guides, and service-specific operational knowledge. The goal is always to mitigate customer impact quickly, identify the root cause, and feed what we learn back into the platform, and log improvement work items where needed. This work is valuable, but it is also time-consuming. As AI capabilities improved, we started asking a practical question: could AI help us reduce the operational burden of incident investigation while preserving the learning and engineering judgment that make those investigations useful? This is the story of how our approach evolved—from early RCA agents, to coding-agent-based workflows, and finally to cloud-hosted automation. Starting with AI-Assisted RCA Around May 2024, we began experimenting with an internal RCA agent together with a colleague from Microsoft Research. The first version was an informal approach towards the development of a formal service. It was a personal tool to help with our own investigations. The early experiments were very useful. We could give the agent an incident, let it run for several minutes, and then review the analysis. It did not always produce a perfect root cause, but it could run multiple queries, explore different hypotheses, and narrow the solution space enough to save time. Later, Azure SRE Agent emerged as a formal internal service. We contributed to it based on what We had learned from our earlier experiments. At that point, using AI to help resolve customer-reported incidents became a major focus for our team. What We Learned from Agentic Workflows The first generation of AI-assisted incident workflows were highly structured. The early experiments with the available models required careful design—especially for generating complex Kusto—we often needed to expose fixed Kusto queries as tools and let the model call them through well-defined parameters. Fig. 1 kusto query tool This made execution more predictable and reproducible, but it also revealed limitations. Detailed agentic workflows could work well when the incident matched the predefined path. Outside those paths, they were less flexible. Engineers also found it expensive to define and maintain those workflows, especially when the output felt only modestly better than a dashboard. Fig2. Agentic Workflow That experience taught us an important lesson: for complex operational investigations, flexibility matters as much as structure. The Shift to Coding Agents Near the end of 2025, we started using an internal tool using GitHub Copilot and skills, which made it possible to define and share VS Code workspaces. A workspace could include agent definitions, instructions, prompts, skills, MCP configuration, and repositories. Fig 3. GitHub Copilot internal tool The quality difference was significant. Combined with newer models, coding agents could investigate incidents much more flexibly. They could run Kusto queries, inspect code, use CLI and MCP tools, and iterate quickly by trying different paths. The team quickly adopted this model. With earlier workflow-based systems, engineers were reluctant to onboard because defining detailed workflows took effort, and the payoff was limited. With this internal tool, engineers started contributing agent definitions and skills because the system was easy to extend. Over time, the Azure Functions team accumulated a growing set of AI-ready materials which consisted of agent definitions, skills, MCP tools, instructions and repositories A number of lessons stood out. Lessons from Building AI-Ready Materials Prefer guidance over over-specification Modern coding agents are capable enough that they do not need every step spelled out. In fact, too many instructions can make the system brittle or stale. We found it better to provide concise guidance and point the agent to maintained sources of truth rather than embedding large amounts of detail directly into prompts. Manage context deliberately Instructions, tool definitions, conversation history, and tool outputs all compete for model context. Irrelevant or contradictory information can reduce quality. Tool design matters too: if a tool returns a large payload directly to the model, it can consume many tokens and confuse the agent. For large outputs, writing results to files and returning concise pointers often works better. Use files as durable memory Long-running investigations benefit from a simple pattern: create a plan and checklist file, update it as work progresses, and let the agent re-read it when needed. This helps the agent recover from context compaction and gives the investigation a durable state inside the workspace. Prefer references over inline knowledge Agent Definition and skills includes domain knowledge. Internal troubleshooting guides, product behavior, operational history, and expert judgment. Instead of placing all that information directly in prompts, we found it more effective to provide references to where the knowledge lives and guidance on when to use it. Make the right repositories visible Coding agents are strong at reading code. For our scenarios, multi-repository workspaces were especially powerful. When the agent could see related repositories together, it could trace behavior across components, understand dependencies, and produce better analysis. Domain knowledge matters most The best agent assets were often created by engineers with deep product and operational experience, not necessarily by AI specialists. The key skill was turning expert knowledge into instructions, references, and repository layouts that an agent could use. Facilitate and streamline domain knowledge updates Every incident not fully handled by an agent is a learning opportunity. Feed the context engineering flywheel: investigate, find gaps, update agent guidance, then re-test. It's important to keep this cycle quick and easy. Why We Moved Toward Cloud Automation Coding agents were extremely helpful, but they were still interactive tools. An engineer had to start the investigation and often guide it. For incident response, we wanted to go further. If an incident entered a specific feature area, the system should be able to start the investigation automatically, run the relevant analysis, and post useful results back to the incident. Even if the analysis was not perfect, narrowing the problem space early could reduce mitigation time. Some scenarios could eventually support automatic mitigation or automatic transfer to the right team. A local coding-agent workflow has advantages, especially because it can authenticate as the user. But as a foundation for reliable automation, it also had important limitations. First, it still depended on human involvement. AI dramatically improved individual productivity, but in incident response the bottleneck is often human attention and time. Even when starting an agent is simple, requiring an engineer to initiate the run introduces a context switch and consumes a scarce resource. Second, it depended on user credentials. Coding agents run with the user’s permissions, which can be overly broad for automation, and they inherit human-oriented flows such as browser-based reauthentication. For durable automation, we wanted an identity model better suited to unattended execution, such as managed identity. Third, there were execution-environment and security concerns. A local environment is powerful, but it does not naturally provide the sandboxing we wanted for safe automation. Because it runs with user access, it may also reach a much wider set of files and resources than is desirable for an automated incident workflow. Local and dev-box environments also have operational drawbacks. They can require restarts, contend with other workloads, and are not ideal for durable execution, failure recovery, or failover. For automation, we wanted a dedicated execution environment rather than something tied to an engineer’s machine. Finally, token management became an operational concern. User-linked token consumption can create instability when limits are reached, and automation can skew usage patterns so that one user appears to consume a disproportionate share of AI capacity. That adds noise to operational analysis and makes governance harder. For all of these reasons, cloud execution looked like the right direction. We wanted managed identity, a secure sandbox, durable execution, and a system that would not depend on someone’s local machine. Requirements for Cloud Automation Many of us had become strong supporters of coding agents and wanted to keep using them. Just as importantly, we had already accumulated assets that had been proven to work well: agent definitions, instructions, prompts, skills, MCP configuration, and repository layouts that the team had gradually built up and refined. That meant our move toward cloud automation was not about replacing coding agents with something entirely different. We wanted to preserve and reuse the assets that had made coding agents successful, while moving to an execution model that was better suited to automation. At the same time, coding agents had set a high quality bar. Because they worked so well in practice, we were not willing to assume that a cloud service would automatically deliver the same level of quality. So we defined two concrete goals for the cloud path. Achieve the same level of quality we were seeing from our existing coding-agent workflows when run in a focused, one-shot investigation. Ensure the assets we had already built could continue to be used and improved. In other words, we were not looking for just another cloud AI system. We were looking for a cloud automation path that could inherit the strengths of coding agents while providing the operational properties automation required. Comparing Headless coding-agent execution service and Azure SRE Agent To evaluate which approach could meet those requirements, we ran a side-by-side comparison. One path was a prototype headless coding agent execution service. It reused the same the internal tool’s workspace definitions that engineers used locally, but ran them without a human in the loop. When an incident entered a target loop, the system created an agent workspace, prepared repositories, started GitHub Copilot CLI with an initial prompt, collected the analysis, and posted the result back to the incident. It also preserved session artifacts so that an engineer could later review or resume the investigation. Fig 4. Agent Helped Trend – It shows people use Coding Agent, the introduction of headless coding agent execution service and SRE Agent increases the percentage of usefulness. The other path used Azure SRE Agent, which had improved with preview customer feedback and was nearing general availability, since our earlier experiments. It now supported newer models, stronger custom-agent behavior, MCP and built-in tools, repository access, and incident-triggered execution. We’ve performed a one-time migration from the Coding Agent asset to the Azure SRE Agent asset. This was achieved in one day using GitHub Copilot CLI and our existing coding agents. The comparison was deliberately practical. We already knew that our internal coding-agent environment produced results engineers trusted and liked. That became our quality bar. If Azure SRE Agent could meet or exceed that bar while also satisfying the operational requirements of cloud automation, it would be the stronger long-term path. Results and Feedback Loop The first Headless coding-agent execution service results were very encouraging. In its first set of incidents, the RCA matched the SME conclusion in cases where the agent could safely process the incident. That showed that the assets we had built for local coding agents could transfer effectively into a headless scenario. Azure SRE Agent also performed strongly from the beginning. Headless coding-agent execution service initially had slightly better analysis in some areas, but Azure SRE Agent was already good enough to be operationally useful. We then built an evaluation framework that compared: Each agent’s RCA, confidence score, and mitigation steps The RCA and mitigation reason later provided by a human Auto-mitigation recommendations Path to auto-mitigation Auto-transfer recommendations Session-level execution issues This evaluation became a feedback loop. Engineers reviewed interesting incidents, identified weaknesses, improved agent definitions and skills, and submitted pull requests. We also used agent assistance to generate improvement PRs from comparison reports. Fig 5. LLM as Judge side-by-side eval for headless coding-agent execution service (blue) vs Azure SRE Agent (green) Within a few weeks, Azure SRE Agent’s quality consistently exceeded the headless coding-agent execution service baseline. At that point, we stopped posting headless results back to incidents and focused on improving the Azure SRE Agent path instead. We also automated synchronization from the internal coding-agent assets so improvements could continue to flow through pull requests. That shift was important. It meant Azure SRE Agent was no longer just an interesting alternative—it had become the cloud path that could inherit what worked in coding agents while providing a better foundation for automation. Why Cloud AI Started to Work Better A common reaction to coding agents is that they feel much improved than the previous cloud AI experiences. Our experience suggests two main reasons: stronger models and improved access to the right context. A coding agent sees a workspace. It can use instructions, skills, tools, repositories, and files. Traditional cloud AI systems often did not have access to the same set of resources. Once Azure SRE Agent could see similar assets - the right repositories, the right tools, and the right domain-specific knowledge - it could reach comparable or better quality. The details of context compaction, tool execution, and orchestration matter. But the core principle is simpler: the agent needs to reach the right knowledge at the right time without carrying unnecessary context all the time. That means the most important work is not only choosing a model or building a tool. It creates high-quality AI-ready assets: concise instructions, useful skills, accurate references, well-structured repository access, and domain knowledge that was previously locked in people’s heads. The cloud hosted automation path instantly provided an exciting benefit, which is that the issue analysis is stored in the cloud and not only on the developer's machine. This means that the conclusions and investigations are stored for perusal and human interaction is possible via the chat interface. Fig 6. An Example of the Chat Interface for Azure SRE Agent Conclusion Our journey started with a personal RCA assistant, moved through structured agentic workflows, accelerated with coding agents, and eventually led us back to a cloud-hosted automation path. The lesson is not that coding agents or cloud agents are universally better. The lesson is that agent quality depends heavily on what the agent can see, how much irrelevant context it avoids, and whether domain experts have translated their knowledge into usable assets. For us, the key was not abandoning coding agents. It was carrying their strengths forward into Azure SRE Agent and a cloud execution model that was better suited to automation. Modern agents are now capable enough to make that work worthwhile. For incident response, that opens the door to faster investigation, safer automation, and ultimately lower incident mitigation time for customers. The Azure Functions team hope this experience is useful to other teams exploring how to apply AI to complex engineering operations. In the next post, we plan to go deeper into the evaluation framework and how we automated the feedback loop behind these improvements.2.9KViews2likes1CommentManaging Multi‑Tenant Azure Resource with SRE Agent and Lighthouse
Azure SRE Agent is an AI‑powered reliability assistant that helps teams diagnose and resolve production issues faster while reducing operational toil. It analyzes logs, metrics, alerts, and deployment data to perform root cause analysis and recommend or execute mitigations with human approval. It’s capable of integrating with azure services across subscriptions and resource groups that you need to monitor and manage. Today’s enterprise customers live in a multi-tenant world, and there are multiple reasons to that due to acquisitions, complex corporate structures, managed service providers, or IT partners. Azure Lighthouse enables enterprise IT teams and managed service providers to manage resources across multiple azure tenants from a single control plane. In this demo I will walk you through how to set up Azure SRE agent to manage and monitor multi-tenant resources delegated through Azure Lighthouse. Navigate to the Azure SRE agent and select Create agent. Fill in the required details along with the deployment region and deploy the SRE agent. Once the deployment is complete, hit Set up your agent. Select the Azure resources you would like your agent to analyze like resource groups or subscriptions. This will land you to the popup window that allows you to select the subscriptions and resource groups that you would like SRE agent to monitor and manage. You can then select the subscriptions and resource groups under the same tenant that you want SRE agent to manage; Great, So far so good 👍 As a Managed Service Provider (MSP) you have multiple tenants that you are managing via Azure Lighthouse, and you need to have SRE agent access to those. So, to demo this will need to set up Azure Lighthouse with correct set of roles and configuration to delegate access to management subscription where the Centralized SRE agent is running. From Azure portal search Lighthouse. Navigate to the Lighthouse home page and select Manage your customers. On My customers Overview select Create ARM Template Provide a Name and Description. Select subscriptions on a Delegated scope. Select + Add authorization which will take you to Add authorization window. Select Principal type, I am selecting User for demo purposes. The pop-up window will allow Select users from the list. Select the checkbox next to the desired user who you want to delegate the subscription and hit Select Then select the Role that you would like to assign the user from the managing tenant to the delegated tenant and select add. You can add multiple roles by adding additional authorization to the selected user. This step is important to make sure the delegated tenant is assigned with the right role in order for SRE Agents to add it as Azure source. Azure SRE agent requires an Owner or User Administrator RBAC role to assign the subscription to the list of managed resources. If an appropriate role is not assigned, you will see an error when selecting the delegated subscriptions in SRE agent Managed resources. As per Lighthouse role support Owner role isn’t supported and User access Administrator role is supported, but only for limited purpose. Refer Azure Lighthouse documentation for additional information. If role is not defined correctly, you might see an error stating: 🛑Failed to add Role assignment “The 'delegatedRoleDefinitionIds' property is required when using certain roleDefinitionIds for authorization. To allow a principalId to assign roles to a managed identity in the customer tenant, set its roleDefinitionId to User Access Administrator. Download the ARM template and add specific Azure built-in roles that you want to grant in the delegatedRoleDefinitionIds property. You can include any supported Azure built-in role except for User Access Administrator or Owner. This example shows a principalId with User Access Administrator role that can assign two built in roles to managed identities in the customer tenant: Contributor and Log Analytics Contributor. { "principalId": "00000000-0000-0000-0000-000000000000", "principalIdDisplayName": "Policy Automation Account", "roleDefinitionId": "18d7d88d-d35e-4fb5-a5c3-7773c20a72d9", "delegatedRoleDefinitionIds": [ "b24988ac-6180-42a0-ab88-20f7382dd24c", "92aaf0da-9dab-42b6-94a3-d43ce8d16293" ] } In addition SRE agent would require certain roles at the managed identity level in order to access and operate on those services. Locate SRE agent User assigned managed identity and add roles to the service principal. For the demo purpose I am assigning Reader, Monitoring Reader, and Log Analytics Reader role. Here is the sample ARM template used for this demo. { "$schema": "https://schema.management.azure.com/schemas/2019-08-01/subscriptionDeploymentTemplate.json#", "contentVersion": "1.0.0.0", "parameters": { "mspOfferName": { "type": "string", "metadata": { "description": "Specify a unique name for your offer" }, "defaultValue": "lighthouse-sre-demo" }, "mspOfferDescription": { "type": "string", "metadata": { "description": "Name of the Managed Service Provider offering" }, "defaultValue": "lighthouse-sre-demo" } }, "variables": { "mspRegistrationName": "[guid(parameters('mspOfferName'))]", "mspAssignmentName": "[guid(parameters('mspOfferName'))]", "managedByTenantId": "6e03bca1-4300-400d-9e80-000000000000", "authorizations": [ { "principalId": "504adfc5-da83-47d4-8709-000000000000", "roleDefinitionId": "e40ec5ca-96e0-45a2-b4ff-59039f2c2b59", "principalIdDisplayName": "Pranab Mandal" }, { "principalId": "504adfc5-da83-47d4-8709-000000000000", "roleDefinitionId": "18d7d88d-d35e-4fb5-a5c3-7773c20a72d9", "delegatedRoleDefinitionIds": [ "b24988ac-6180-42a0-ab88-20f7382dd24c", "92aaf0da-9dab-42b6-94a3-d43ce8d16293" ], "principalIdDisplayName": "Pranab Mandal" }, { "principalId": "504adfc5-da83-47d4-8709-000000000000", "roleDefinitionId": "b24988ac-6180-42a0-ab88-20f7382dd24c", "principalIdDisplayName": "Pranab Mandal" }, { "principalId": "0374ff5c-5272-49fa-878a-000000000000", "roleDefinitionId": "acdd72a7-3385-48ef-bd42-f606fba81ae7", "principalIdDisplayName": "sre-agent-ext-sub1-4n4y4v5jjdtuu" }, { "principalId": "0374ff5c-5272-49fa-878a-000000000000", "roleDefinitionId": "43d0d8ad-25c7-4714-9337-8ba259a9fe05", "principalIdDisplayName": "sre-agent-ext-sub1-4n4y4v5jjdtuu" }, { "principalId": "0374ff5c-5272-49fa-878a-000000000000", "roleDefinitionId": "73c42c96-874c-492b-b04d-ab87d138a893", "principalIdDisplayName": "sre-agent-ext-sub1-4n4y4v5jjdtuu" } ] }, "resources": [ { "type": "Microsoft.ManagedServices/registrationDefinitions", "apiVersion": "2022-10-01", "name": "[variables('mspRegistrationName')]", "properties": { "registrationDefinitionName": "[parameters('mspOfferName')]", "description": "[parameters('mspOfferDescription')]", "managedByTenantId": "[variables('managedByTenantId')]", "authorizations": "[variables('authorizations')]" } }, { "type": "Microsoft.ManagedServices/registrationAssignments", "apiVersion": "2022-10-01", "name": "[variables('mspAssignmentName')]", "dependsOn": [ "[resourceId('Microsoft.ManagedServices/registrationDefinitions/', variables('mspRegistrationName'))]" ], "properties": { "registrationDefinitionId": "[resourceId('Microsoft.ManagedServices/registrationDefinitions/', variables('mspRegistrationName'))]" } } ], "outputs": { "mspOfferName": { "type": "string", "value": "[concat('Managed by', ' ', parameters('mspOfferName'))]" }, "authorizations": { "type": "array", "value": "[variables('authorizations')]" } } } Login to the customers tenant and navigate to the service provides from the Azure Portal. From the Service Providers overview screen, select Service provider offers from the left navigation pane. From the top menu, select the Add offer drop down and select Add via template. In the Upload Offer Template window drag and drop or upload the template file that was created in the earlier step and hit Upload. Once the file is uploaded, select Review + Create. This will take a few minutes to deploy the template, and a successful deployment page should be displayed. Navigate to Delegations from Lighthouse overview and validate if you see the delegated subscription and the assigned role. Once the Lighthouse delegation is set up sign in to the managing tenant and navigate to the deployed SRE agent. Navigate to Azure resources from top menu or via Settings > Managed resources. Navigate to Add subscriptions to select customers subscriptions that you need SRE agent to manage. Adding subscription will automatically add required permission for the agent. Once the appropriate roles are added, the subscriptions are ready for the agent to manage and monitor resources within them. Summary - Benefits This blog post demonstrates how Azure SRE Agent can be used to centrally monitor and manage Azure resources across multiple tenants by integrating it with Azure Lighthouse, a common requirement for enterprises and managed service providers operating in complex, multi-tenant environments. It walks through: Centralized SRE operations across multiple Azure tenants Secure, role-based access using delegated resource management Reduced operational overhead for MSPs and enterprise IT teams Unified visibility into resource health and reliability across customer environments1.1KViews2likes1Comment