azure openai
98 TopicsAMA on Camera - AI Revolution: Azure OpenAI's Game-Changing Enhancements
Discover the latest enhancements to Azure OpenAI Service offering and deployments. Join our engineering experts to learn about Azure OpenAI Data Zones for flexible, multi-regional data processing and compliance. Explore simplified deployment flows, industry-leading performance guarantees, and cost-efficiency at scale. Perfect for anyone looking to leverage adaptable, reliable, and scalable AI solutions for enterprise applications. Please check out this blog post for more information: Accelerate scale with Azure OpenAI Service Provisioned offering | Microsoft Azure Blog Azure OpenAI Global Batch offering is designed to handle large-scale and high-volume processing tasks efficiently. Process asynchronous groups of requests with separate quota, a 24-hour turnaround time, at 50% less cost than global standard. Learn more There will be presentations on Batch, Data Zone Standard and Data Zone Provisioned and we will be taking questions throughout. Please share any questions that you would like our experts to address in the comments below. Questions can be posted anytime in the comments below beforehand, if it fits your schedule or time zone better, though questions will not be answered until the live hour. Questions will be answered both in the live broadcast on video and in text below. This will be a live stream video directly on this event page. NOTE: Please be aware the link sent via the private message to folks will not work due to some platform changes. We are working on redirecting it, but just in case, the new event link (the page you are on) is here: AMA on Camera - AI Revolution: Azure OpenAI's Game-Changing Enhancements | Microsoft Community Hub )5.1KViews13likes11CommentsAzure Data Explorer for Vector Similarity Search
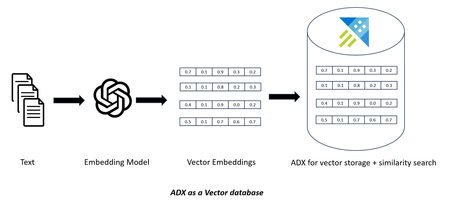
https://learn.microsoft.com/en-us/azure/data-explorer/kusto/query/series-cosine-similarity-function In the world of AI & data analytics, vector databases are emerging as a powerful tool for managing complex and high-dimensional data. In this article, we will explore the concept of vector databases, the need for vector databases in data analytics, and how Azure Data Explorer (ADX) aka Kusto can be used as a vector database.33KViews13likes5CommentsStop Drawing Architecture Diagrams Manually: Meet the Open-Source AI Architecture Review Agents
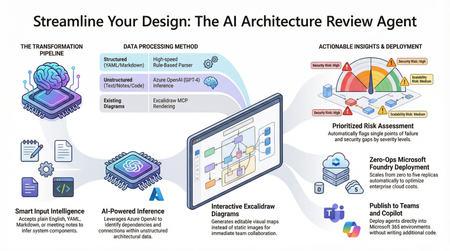
Designing and documenting software architecture is often a battle against static diagrams that become outdated the moment they are drawn. The Architecture Review Agent changes that by turning your design process into a dynamic, AI-powered workflow. In this post, we explore how to leverage Microsoft Foundry Hosted Agents, Azure OpenAI, and Excalidraw to build an open-source tool that instantly converts messy text descriptions, YAML, or README files into editable architecture diagrams. Beyond just drawing boxes, the agent acts as a technical co-pilot, delivering prioritized risk assessments, highlighting single points of failure, and mapping component dependencies. Discover how to eliminate manual diagramming, catch security flaws early, and deploy your own enterprise-grade agent with zero infrastructure overhead.18KViews7likes5CommentsBuilding a Scalable Web Crawling and Indexing Pipeline with Azure storage and AI Search
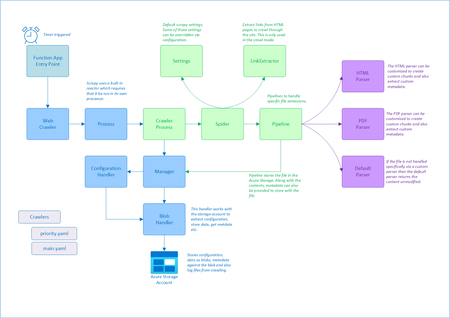
In the ever-evolving world of data management, keeping search indexes up-to-date with dynamic data can be challenging. Traditional approaches, such as manual or scheduled indexing, are resource-intensive, delay-prone, and difficult to scale. Azure Blob Trigger combined with an AI Search Indexer offers a cutting-edge solution to overcome these challenges, enabling real-time, scalable, and enriched data indexing. This blog explores how Blob Trigger, integrated with Azure Cognitive Search, transforms the indexing process by automating workflows and enriching data with AI capabilities. It highlights the step-by-step process of configuring Blob Storage, creating Azure Functions for triggers, and seamlessly connecting with an AI-powered search index. The approach leverages Azure's event-driven architecture, ensuring efficient and cost-effective data management.4.4KViews7likes10Comments
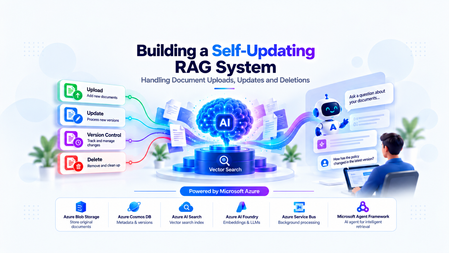
Building a Self-Updating RAG System: Handling Document Uploads, Updates and Deletions
The Hidden Challenge of Production RAG Imagine your organization has deployed an AI assistant to answer questions about employee policies. An employee asks, “How many days of annual leave am I entitled to?” The assistant responds confidently: “15 days.” There is just one problem. The company updated its policy last week. Employees are now entitled to 20 days. The updated PDF was uploaded successfully. The storage service is healthy. The search index is responding. The language model is generating answers without errors. Yet the answer is wrong. This is a different kind of production failure. Nothing appears to be broken at the infrastructure level. The failure lies in the relationship between the source document and the information the AI retrieves. Retrieval-Augmented Generation (RAG) systems depend on external knowledge to ground their responses. But that knowledge is not static. Policies change, contracts get revised, product documentation evolves, and outdated documents are removed. When the underlying documents change, the associated chunks, embeddings, metadata, and search-index entries must be managed accordingly. Otherwise, the system can continue generating plausible answers from information that is no longer valid. Building a RAG pipeline is a retrieval problem. Keeping it correct as data changes is a data lifecycle engineering problem. In this article, we will design a self-updating RAG system that handles document creation, updates, and deletion while addressing asynchronous processing, version consistency, failed jobs, and stale retrieval results. The goal is not simply to index documents automatically. It is to make sure that the right version of the right document is available to the right user when a query is executed. Understand the Problem Before Designing the Architecture A basic RAG pipeline is relatively straightforward: Load a document. Extract its text. Split the text into smaller chunks. Generate an embedding for each chunk. Store the chunks and embeddings in a searchable index. Retrieve relevant chunks when a user asks a question. Pass the retrieved context to a language model to generate an answer. This works well when the document collection is relatively static. The difficulty begins when the source data changes after indexing. Consider three common scenarios. Scenario A: A document is uploaded A new policy is added to the knowledge base. The system must process it and make its content searchable. Until indexing finishes, the document may not be available to the chatbot. Scenario B: A document is updated The original policy allows 15 days of annual leave. A revised policy allows 20 days. If the new version is indexed without correctly deactivating the old version, both versions may appear in search results. The language model may then select the wrong passage or combine conflicting information. Scenario C: A document is deleted An administrator removes a document from the application. However, deleting the original PDF from storage does not automatically delete the corresponding records from Azure AI Search. The content may remain searchable until its indexed chunks are removed. Azure AI Search document deletion itself can also take time to be reflected in index statistics. Microsoft Learn: Delete documents in Azure AI Search These scenarios reveal an important design principle: The source document, its metadata, the background processing jobs, and the search index must be treated as parts of one logical lifecycle—even though they are separate systems. We need a design that can handle failures between these systems without exposing outdated or unauthorized content. Design the System Around Clear Responsibilities Rather than making the upload API responsible for every operation, we can separate the system into a document management path, an asynchronous processing path, and a query path. The Proposed Architecture The design uses the following components: Component Responsibility Azure Blob Storage Stores the original document files Azure Cosmos DB Maintains document metadata, versions, and lifecycle state Azure Service Bus Queues ingestion and deletion jobs Background worker Extracts text, creates chunks, generates embeddings, and updates the index Microsoft Foundry Provides the models used for embedding generation and response generation Azure AI Search Stores searchable document chunks, metadata, and vectors FastAPI Exposes document management and chat APIs Microsoft Agent Framework Supports agentic query workflows when multi-step reasoning or tool use is required The background worker can be implemented as a separate Python service or another suitable compute component. It does not have to be part of the FastAPI process. Why separate these responsibilities? Suppose a user uploads a 100-page contract. The application may need to extract text, split thousands of characters into chunks, generate embeddings, and send multiple indexing requests. Performing all of that synchronously inside the upload request increases latency and makes the API vulnerable to timeouts. Instead, FastAPI accepts the request, persists the document and its metadata, and arranges for the work to be processed asynchronously. The worker performs the expensive operations independently. This allows ingestion to scale separately from query traffic and makes retries easier to manage. The query path remains separate: it retrieves eligible, relevant chunks and uses them to ground the model's response. Establish a source of truth Azure Cosmos DB should hold the authoritative lifecycle metadata in this design. Azure AI Search is the retrieval index, not the authority on whether a document is currently active. For example, a document record might look like this: { "id": "policy-123", "documentId": "policy-123", "currentVersion": 2, "indexedVersion": 1, "status": "PROCESSING", "blobPath": "policies/leave-policy.pdf" } Here, version 2 is the desired version, but version 1 is still the last successfully indexed version. The application must not assume that the latest upload has already become searchable simply because the metadata record has been updated. This distinction between the desired version and the indexed version is central to reliable lifecycle management. Implementing Document Uploads A reliable upload operation involves more than storing a file and sending a message to a queue. It must establish a durable record of the document, identify the version being processed, and ensure that background processing can be retried safely. Step 1: Accept and persist the document When a client uploads a document, FastAPI validates the request, checks the user's permissions, and stores the original file in Azure Blob Storage. The application then creates or updates the document metadata in Cosmos DB. At this stage, the document can be marked as PROCESSING until the ingestion pipeline completes. Step 2: Schedule background processing The system creates an ingestion job containing enough information for the worker to locate the source and determine exactly which version to process. For example: { "operationId": "op-789", "operation": "INGEST", "documentId": "policy-123", "documentVersion": 2, "blobPath": "policies/leave-policy-v2.pdf" } The worker should process the specified version rather than blindly reading whatever file happens to exist at a mutable storage path. For systems that overwrite the same blob path, use blob versioning, an immutable version-specific path, or another mechanism that ensures the worker reads the intended content. Step 3: Extract, chunk, and embed The worker downloads the appropriate document and extracts its text. The extracted text is divided into chunks. Each chunk should carry identifiers that connect it to its parent document and version. For example: { "id": "policy-123-v2-chunk-001", "documentId": "policy-123", "documentVersion": 2, "chunkNumber": 1, "content": "Employees are entitled to 20 days of annual leave." } The worker generates an embedding for each chunk and writes the chunk, its metadata, and its vector to Azure AI Search. The exact index schema depends on the retrieval strategy, embedding dimensions, filtering requirements, and whether hybrid search is used. Step 4: Mark the version as indexed After the worker confirms that all required indexing operations succeeded, it updates the document metadata to record the indexed version and processing status. For example: { "id": "policy-123", "currentVersion": 2, "indexedVersion": 2, "status": "ACTIVE" } This update must be conditional on the document still being at version 2. If a newer version has already been uploaded, the older job must not mark itself as the current version. Why idempotency matters Distributed systems can deliver the same job more than once. A worker may finish indexing but fail before acknowledging the queue message. The message can then be delivered again. If every attempt creates new chunk IDs, duplicate content may accumulate in the index. A practical solution is to derive chunk IDs deterministically from the document ID, version, and chunk identifier. Reprocessing the same version then targets the same index records instead of creating a new set each time. This does not eliminate every failure mode, but it makes repeated indexing much safer. Azure Service Bus supports duplicate detection for eligible tiers, but queue-level duplicate detection is not a substitute for idempotent worker logic. Microsoft Learn: Duplicate detection Updating Documents Without Serving Stale Content Document updates are the most interesting part of the lifecycle because they introduce a consistency problem. Imagine the current leave policy is version 1, allowing 15 days. An administrator uploads version 2, allowing 20 days. The worker starts processing version 2, but embedding generation takes time. Meanwhile, users continue querying the application. What should those users see? There are two common strategies. The right choice depends on whether the system prioritizes availability or strict freshness. Strategy A: Make the new version active after indexing succeeds In this approach, the existing active version remains available while the new version is processed. The workflow is: Create version 2 and mark it as processing. Extract text and generate embeddings for version 2. Index all required version 2 chunks. Verify indexing success. Atomically update the authoritative metadata to make version 2 active. Clean up version 1's indexed chunks asynchronously. This minimizes the time during which the document is unavailable. However, it means that version 1 can remain available while version 2 is being processed. That may be acceptable for some knowledge bases but inappropriate for policies that must become effective immediately. Strategy B: Disable the old version as soon as an update is accepted For high-sensitivity documents, the application can immediately mark the old version as ineligible for retrieval. It then processes the new version and activates it only after successful indexing. The trade-off is that the document may temporarily have no eligible version. The application should return a clear message or use an approved fallback rather than silently serving obsolete information. Prevent old jobs from overwriting new versions Consider this sequence: Version 2 starts processing. Version 3 is uploaded before version 2 finishes. Version 3 finishes indexing first. Version 2 finishes later and attempts to update the metadata. Without version checks, the late version 2 job could incorrectly reactivate stale content. The worker must therefore use conditional updates or optimistic concurrency checks against the authoritative document version. A job may complete its indexing work, but it must not activate its version unless it is still eligible to do so. Handle the lack of a cross-service transaction Cosmos DB and Azure AI Search do not participate in a single distributed transaction in this architecture. A metadata update can succeed while an indexing request fails. An indexing request can succeed while the subsequent metadata update fails. The system should account for these partial failures using: Explicit lifecycle states. Conditional version updates. Retryable and idempotent operations. Periodic reconciliation between metadata and indexed records. The important engineering principle is to make incomplete operations detectable and recoverable, rather than assuming every multi-step workflow succeeds atomically. Deleting Documents Safely Deletion requires special treatment because removing a document from the source does not automatically remove its indexed content. More importantly, waiting for physical index cleanup before preventing retrieval creates a window in which content that should no longer be available may still be returned. Step 1: Make the document ineligible for retrieval When an authorized deletion request arrives, the application updates the authoritative metadata to indicate that the document is being deleted or has been logically deleted. The retrieval path must check that status before using retrieved content. For sensitive documents, this check must happen before the content is added to the LLM context. Merely hiding a document in the user interface is insufficient. Step 2: Schedule physical cleanup The application enqueues a deletion job that identifies the document and all indexed records associated with it. The worker queries or otherwise identifies the corresponding chunk keys and deletes those records from Azure AI Search. The deletion operation should be idempotent. Retrying a deletion for an already-removed chunk should not cause the workflow to fail unnecessarily. Step 3: Verify cleanup The worker checks whether the targeted records have been removed and records the cleanup result. If an operation fails, the job should be retried according to a defined policy. Jobs that continue failing should be sent to a dead-letter queue for investigation and controlled recovery. Azure AI Search supports deleting indexed documents by their document keys. Its documentation also describes how to verify deletion and why index statistics may not update immediately. Microsoft Learn: Delete documents A simplified FastAPI deletion endpoint The following example illustrates the API boundary. The helper functions represent application-specific implementations. from fastapi import FastAPI, HTTPException app = FastAPI() @app.delete("/documents/{document_id}") async def delete_document(document_id: str): document = await get_document_metadata(document_id) if document is None: raise HTTPException( status_code=404, detail="Document not found" ) # Must enforce authorization and use a # concurrency-safe lifecycle transition. await mark_document_deleting(document_id) # The job must be published reliably. await enqueue_deletion_job( document_id=document_id, document_version=document["currentVersion"] ) return { "documentId": document_id, "status": "DELETING" } This is an illustrative example, not a complete production implementation. In particular, the metadata transition and message publication must be coordinated reliably. One approach is the transactional outbox pattern: write the lifecycle change and an outbox event in the same Cosmos DB transactional batch when the data model and partitioning allow it, then publish the event asynchronously. The publisher can retry without losing the intent to schedule cleanup. Deletion must also account for in-flight queries Suppose a query retrieves a document's chunks just before the deletion request is processed. The query might still hold those chunks in memory even after the document is marked deleted. For stricter deletion guarantees, the application needs a defined policy for in-flight requests, cache invalidation, and authorization checks immediately before content is sent to the model. If the requirement is that no response may contain content after a deletion takes effect, that guarantee must explicitly cover requests already in progress. Physical cleanup and retrieval eligibility are separate responsibilities. Both matter. Coordinate Lifecycle Changes Reliably Once ingestion and deletion run asynchronously, the queue becomes part of the system's correctness model. A production worker should not assume that each message is delivered exactly once or that messages for a particular document always finish in order. Design for at-least-once processing A practical worker lifecycle is: Receive a message using a lock-based delivery mode. Validate the document ID, version, and operation. Check whether the operation is still eligible to run. Perform idempotent indexing or deletion. Update lifecycle metadata conditionally. Acknowledge the message only after successful processing. If the worker fails before acknowledging the message, the message may be delivered again. That is expected behavior and should be handled by the design. Add retry and dead-letter policies Not all failures should be treated equally. Transient network errors or throttling may succeed after a delay. Invalid documents, unsupported file formats, and persistent schema mismatches may require manual investigation. The system should use bounded retries with appropriate backoff, record meaningful failure details, and route repeatedly failing messages to a dead-letter queue. Use reconciliation as a safety net Even with retries, the system needs a way to detect inconsistencies that escaped the normal workflow. A reconciliation job can compare authoritative metadata against indexed document versions and lifecycle states. It can identify cases such as: A document marked active whose current version is not fully indexed. Chunks belonging to an obsolete version. Search records for a logically deleted document. An operation that remained in a processing state beyond its expected duration. Reconciliation should repair only states it can safely determine. It should not reactivate a version simply because its chunks exist in the index. For applications using Azure Cosmos DB change feed, document metadata changes can also drive incremental background processing. The change feed captures inserts and updates in its standard latest-version mode; capturing deletions requires selecting and configuring an appropriate supported mode or using explicit lifecycle events. Microsoft Learn: Cosmos DB change feed Where Microsoft Agent Framework Fits A common mistake is to assume that every part of an agentic RAG application should be implemented as an AI agent. Document uploads, version transitions, embedding generation, and index deletion are predictable operations with explicit success and failure conditions. These are generally best implemented with conventional application logic and background workers. Microsoft Agent Framework becomes useful when the query itself requires multi-step reasoning, tool selection, or orchestration. For example, a user might ask: “Compare the current leave policy with the previous version and explain the changes that affect employees.” An agent could use approved tools to retrieve the current policy and the permitted historical version, compare the relevant passages, and generate an evidence-based explanation. The application must still control which documents and versions are eligible for retrieval. The agent should not independently decide whether a deleted document is authorized for use. This distinction is important: deterministic workflows protect data integrity; agentic workflows help solve tasks that benefit from reasoning and tool use. Microsoft Agent Framework provides both agent and workflow capabilities, allowing developers to choose an appropriate orchestration model for the task. Microsoft Agent Framework documentation Production Readiness: What Should We Measure? A pipeline that successfully indexes a document once is not necessarily production-ready. The system needs observable lifecycle states and measurable recovery behavior. Area What to validate Ingestion Can a failed upload or indexing job be retried safely? Idempotency Does processing the same document version twice create duplicate records? Version consistency Can a delayed job reactivate an older version? Deletion Can logically deleted content enter the LLM context? Authorization Are tenant and document-level permissions enforced during retrieval? Recovery Can reconciliation detect and repair partial failures? Observability Can operators identify stuck jobs, indexing failures, and cleanup delays? Performance How long does it take for an accepted update to become searchable? Useful operational metrics include ingestion success rate, queue age, indexing latency, retry counts, dead-letter queue depth, time spent in each lifecycle state, and deletion cleanup latency. Also test race conditions deliberately. Upload a new version while an earlier job is still running. Delete a document while a query is in flight. Simulate an indexing failure after metadata has been updated. Restart a worker after it has indexed content but before it acknowledges the message. These tests expose the problems that a happy-path demonstration will not reveal. Bringing It All Together Keeping a RAG system accurate is not simply a matter of re-running embeddings whenever a file changes. It requires a deliberate lifecycle design that connects source documents, versioned metadata, asynchronous processing, search-index operations, and retrieval-time authorization. Azure Blob Storage can preserve the source documents, Cosmos DB can track authoritative lifecycle state, Service Bus can distribute background work, and Azure AI Search can provide retrieval. Microsoft Foundry supplies the models, while Microsoft Agent Framework can support the parts of the application that genuinely benefit from agentic orchestration. The architecture becomes reliable when it assumes that failures will happen: messages may be repeated, jobs may finish out of order, index operations may partially succeed, and cleanup may take time. Version checks, idempotent operations, explicit lifecycle states, reliable event publication, and reconciliation turn those failure modes into manageable engineering problems. The objective is not merely to keep the index populated. It is to ensure that every answer is grounded in information that is current, eligible, and authorized for the user who asked the question. Further Reading Azure AI Search: Delete documents Azure Cosmos DB: Change feed Azure Service Bus: Duplicate detection Microsoft Agent Framework I'd be interested to hear from engineers building production RAG systems: how do you coordinate document updates and deletions across your source of truth and search index?525Views4likes2Comments
Three tiers of Agentic AI - and when to use none of them
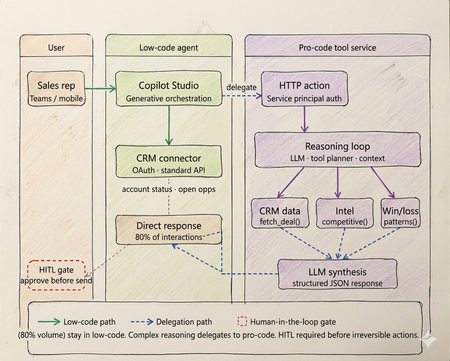
Every enterprise has an AI agent. Almost none of them work in production. Walk into any enterprise technology review right now and you will find the same thing. Pilots running. Demos recorded. Steering committees impressed. And somewhere in the background, a quiet acknowledgment that the thing does not actually work at scale yet. OutSystems surveyed nearly 1,900 global IT leaders and found that 96% of organizations are already running AI agents in some capacity. Yet only one in nine has those agents operating in production at scale. The experiments are everywhere. The production systems are not. That gap is not a capability problem. The infrastructure has matured. Tool calling is standard across all major models. Frameworks like LangGraph, CrewAI, and Microsoft Agent Framework abstract orchestration logic. Model Context Protocol standardizes how agents access external tools and data sources. Google's Agent-to-Agent protocol now under Linux Foundation governance with over 50 enterprise technology partners including Salesforce, SAP, ServiceNow, and Workday standardizes how agents coordinate with each other. The protocols are in place. The frameworks are production ready. The gap is a selection and governance problem. Teams are building agents on problems that do not need them. Choosing the wrong tier for the ones that do. And treating governance as a compliance checkbox to add after launch, rather than an architectural input to design in from the start. The same OutSystems research found that 94% of organizations are concerned that AI sprawl is increasing complexity, technical debt, and security risk and only 12% have a centralized approach to managing it. Teams are deploying agents the way shadow IT spread through enterprises a decade ago: fast, fragmented, and without a shared definition of what production-ready actually means. I've built agentic systems across enterprise clients in logistics, retail, and B2B services. The failures I keep seeing are not technology failures. They are architecture and judgment failures problems that existed before the first line of code was written, in the conversation where nobody asked the prior question. This article is the framework I use before any platform conversation starts. What has genuinely shifted in the agentic landscape Three changes are shaping how enterprise agent architecture should be designed today and they are not incremental improvements on what existed before. The first is the move from single agents to multi-agent systems. Databricks' State of AI Agents report drawing on data from over 20,000 organizations, including more than 60% of the Fortune 500 found that multi-agent workflows on their platform grew 327% in just four months. This is not experimentation. It is production architecture shifting. A single agent handling everything routing, retrieval, reasoning, execution is being replaced by specialized agents coordinating through defined interfaces. A financial organization, for example, might run separate agents for intent classification, document retrieval, and compliance checking each narrow in scope, each connected to the next through a standardized protocol rather than tightly coupled code. The second is protocol standardization. MCP handles vertical connectivity how agents access tools, data sources, and APIs through a typed manifest and standardized invocation pattern. A2A handles horizontal connectivity how agents discover peer agents, delegate subtasks, and coordinate workflows. Production systems today use both. The practical consequence is that multi-agent architectures can be composed and governed as a platform rather than managed as a collection of one-off integrations. The third is governance as the differentiating factor between teams that ship and teams that stall. Databricks found that companies using AI governance tools get over 12 times more AI projects into production compared to those without. The teams running production agents are not running more sophisticated models. They built evaluation pipelines, audit trails, and human oversight gates before scaling not after the first incident. Tier 1 - Low-code agents: fast delivery with a defined ceiling The low-code tier is more capable than it was eighteen months ago. Copilot Studio, Salesforce Agentforce, and equivalent platforms now support richer connector libraries, better generative orchestration, and more flexible topic models. The ceiling is higher than it was. It is still a ceiling. The core pattern remains: a visual topic model drives a platform-managed LLM that classifies intent and routes to named execution branches. Connectors abstract credential management and API surface. A business team — analyst, citizen developer, IT operations — can build, deploy, and iterate without engineering involvement on every change. For bounded conversational problems, this is the fastest path from requirement to production. The production reality is documented clearly. Gartner data found that only 5% of Copilot Studio pilots moved to larger-scale deployment. A European telecom with dedicated IT resources and a full Microsoft enterprise agreement spent six months and did not deliver a single production agent. The visual builder works. The path from prototype to production, production-grade integrations, error handling, compliance logging, exception routing is where most enterprises get stuck, because it requires Power Platform expertise that most business teams do not have. The platform ceiling shows up predictably at four points. Async processing anything beyond a synchronous connector call, including approval chains, document pipelines, or batch operations cannot be handled natively. Full payload audit logs platform logs give conversation transcripts and connector summaries, not structured records of every API call and its parameters. Production volume concurrency limits and message throughput budgets bind faster than planning assumptions suggest. Root cause analysis in production you cannot inspect the LLM's confidence score or the alternatives it considered, which makes diagnosing misbehavior significantly harder than it should be. The correct diagnostic: can this use case be owned end-to-end by a business team, covered by standard connectors, with no latency SLA below three seconds and no payload-level compliance requirement? Yes, low code is the correct tier. Not a compromise. If no on any point, continue. If low-code is the right call for your use case: Copilot Studio quickstart Tier 2 - Pro-code agents: the architecture the current landscape demands The defining pattern in production pro-code architecture today is multi-agent. Specialized agents per domain, coordinating through MCP for tool access and A2A for peer-to-peer delegation, with a governance layer spanning the entire system. What this looks like in practice: a financial organization handling incoming compliance queries runs separate agents for intent classification, document retrieval, and the compliance check itself. None of these agents tries to do all three jobs. Each has a narrow responsibility, a defined input/output contract typed against a JSON Schema, and a clear handoff boundary. The 327% growth in multi-agent workflows reflects production teams discovering that the failure modes of monolithic agents topic collision, context overflow, degraded classification as scope expands are solved by specialization, not by making a single agent more capable. The discipline that makes multi-agent systems reliable is identical to what makes single-agent systems reliable, just enforced across more boundaries: the LLM layer reasons and coordinates; deterministic tool functions enforce. In a compliance pipeline, no LLM decides whether a document satisfies a regulatory requirement. That evaluation runs in a deterministic tool with a versioned rule set, testable outputs, and an immutable audit log. The LLM orchestrates the sequence. The tool produces the compliance record. Mixing these letting an LLM evaluate whether a rule pass collapses the audit trail and introduces probabilistic outputs on questions that have regulatory answers. MCP is the tool interface standard today. An MCP server exposes a typed manifest any compliant agent runtime can discover at startup. Tools are versioned, independently deployable, and reusable across agents without bespoke integration code. A2A extends this horizontally: agents advertise capability cards, discover peers, and delegate subtasks through a standardised protocol. The practical consequence is that multi-agent systems built on both protocols can be composed and governed as a platform rather than managed as a collection of one-off integrations. Observability is the architectural element that separates teams shipping production agents from teams perpetually in pilot. Build evaluation pipelines, distributed traces across all agent boundaries, and human review gates before scaling. The teams that add these after the first production incident spend months retrofitting what should have been designed in. If pro-code is the right call for your use case: Foundry Agent Service The hybrid pattern: still where production deployments land The shift to multi-agent architecture does not change the hybrid pattern it deepens it. Low-code at the conversational surface, pro-code multi-agent systems behind it, with a governance layer spanning both. On a logistics client engagement, the brief was a sales assistant for account managers shipment status, account health, and competitive context inside Teams. The business team wanted everything in Copilot Studio. Engineering wanted a custom agent runtime. Both were wrong. What we built: Copilot Studio handled all high-frequency, low-complexity queries shipment tracking, account status, open cases through Power Platform connectors. Zero custom code. That covered roughly 78% of actual interaction volume. Requests requiring multi-source reasoning competitive positioning on a specific lane, churn risk across an account portfolio, contract renewal analysis delegated via authenticated HTTP action to a pro-code multi-agent service on Azure. A retrieval agent pulled deal history and market intelligence through MCP-exposed tools. A synthesis agent composed the recommendation with confidence scoring. Structured JSON back to the low-code layer, rendered as an adaptive card in Teams. The HITL gate was non-negotiable and designed before deployment, not added after the first incident. No output reached a customer without a manager approval step. The agent drafts. A human sends. This boundary low-code for conversational volume, pro-code for reasoning depth maps directly to what the research shows separates teams that ship from teams that stall. The organizations running agents in production drew the line correctly between what the platform can own and what engineering needs to own. Then they built governance into both sides before scaling. The four gates - the prior question that still gets skipped Run every candidate use case through these four checks before the platform conversation begins. None of the recent infrastructure improvements change what they are checking, because none of them change the fundamental cost structure of agentic reasoning. Gate 1 - is the logic fully deterministic? If every valid output for every valid input can be enumerated in unit tests, the problem does not need an LLM. A rules engine executes in microseconds at zero inference cost and cannot produce a plausible-but-wrong answer. NeuBird AI's production ops agents which have resolved over a million alerts and saved enterprises over $2 million in engineering hours work because alert triage logic that can be expressed as rules runs in deterministic code, and the LLM only handles cases where pattern-matching is insufficient. That boundary is not incidental to the system's reliability. It is the reason for it. Gate 2 - is zero hallucination tolerance required? With over 80% of databases now being built by AI agents per Databricks' State of AI Agents report the surface area for hallucination-induced data errors has grown significantly. In domains where a wrong answer is a compliance event financial calculation, medical logic, regulatory determinations irreducible LLM output uncertainty is disqualifying regardless of model version or prompt engineering effort. Exit to deterministic code or classical ML with bounded output spaces. Gate 3 - is a sub-100ms latency SLA required? LLM inference is faster than it was eighteen months ago. It is not fast enough for payment transaction processing, real-time fraud scoring, or live inventory management. A three-agent system with MCP tool calls has a P50 latency measured in seconds. These problems need purpose-built transactional architecture. Gate 4 - is regulatory explainability required? A2A enables complex agent coordination and delegation. It does not make LLM reasoning reproducible in a regulatory sense. Temperature above zero means the same input produces different outputs across invocations. Regulators in financial services, healthcare, and consumer credit require deterministic, auditable decision rationale. Exit to deterministic workflow with structured audit logging at every Five production failure modes - one of them new The four original anti-patterns are still showing up in production. A fifth has been added by scale. Routing data retrieval through a reasoning loop. A direct API call returns account status in under 10ms. Routing the same request through an LLM reasoning step adds hundreds of milliseconds, consumes tokens on every call, and introduces output parsing on data that is already structured. The agent calls a structured tool. The tool calls the API. The agent never acts as the integration layer. Encoding business rules in prompts. Rules expressed in prompt text drift as models update. They produce probabilistic output across invocations and fail in ways that are difficult to reproduce and diagnose. A rule that must evaluate correctly every time belongs in a deterministic tool function unit-tested, version-controlled, independently deployable via MCP. No approval gate on CRUD operations. CRUD operations without a human approval step will eventually misfire on the input that testing did not cover. The gate needs to be designed before deployment, not added after the first incident involving a financial posting, a customer-facing communication, or a data deletion. Monolithic agent for all domains. A single agent accumulating every domain leads predictably to topic collision, context overflow, and maintenance that becomes impossible as scope expands. Specialized agents per domain, coordinating through A2A, is the architecture that scales. Ungoverned agent sprawl. This is the new one and currently the most prevalent. OutSystems found 94% of organizations concerned about it, with only 12% having a centralized response. Teams building agents independently across fragmented stacks, without shared governance, evaluation standards, or audit infrastructure, produce exactly the same organizational debt that shadow IT created but with higher stakes, because these systems make autonomous decisions rather than just storing and retrieving data. The fix is treating governance as an architectural input before deployment, not a compliance requirement after something breaks. The infrastructure is ready. The judgment is not. The tier decision sequence has not changed. Does the problem need natural language understanding or dynamic generation? No — deterministic system, stop. Can a business team own it through standard connectors with no sub-3-second latency SLA and no payload-level compliance requirement? Yes — low-code. Does it need custom orchestration, multi-agent coordination, or audit-grade observability? Yes — pro-code with MCP and A2A. Does it need both a conversational surface and deep backend reasoning? Hybrid, with a governance layer spanning both. What has changed is that governance is no longer optional infrastructure to add when you have time. The data is unambiguous. Companies with governance tools get over 12 times more AI projects into production than those without. Evaluation pipelines, distributed tracing across agent boundaries, human oversight gates, and centralised agent lifecycle management are not overhead. They are what converts experiments into production systems. The teams still stuck in pilot are not stuck because the technology failed them. They are stuck because they skipped this layer. The protocols are standardised. The frameworks are mature. The infrastructure exists. None of that is what is holding most enterprise agent programmes back. What is holding them back is a selection problem disguised as a technology problem — teams building agents before asking whether agents are warranted, choosing platforms before running the four gates, and treating governance as a checkpoint rather than an architectural input. I have built agents that should have been workflow engines. Not because the technology was wrong, but because nobody stopped early enough to ask whether it was necessary. The four gates in this article exist because I learned those lessons at clients' expense, not mine. The most useful thing I can offer any team starting an agentic AI project is not a framework selection guide. It is permission to say no — and a clear basis for saying it. Take the four gates framework to your next architecture review. If you have already shipped agents to production, I would like to hear what worked and what did not - comment below What to do next Three concrete steps depending on where you are right now. If you have pilots that have not reached production: Run them through the four gates in this article before the next sprint. Gate 1 alone will eliminate a meaningful percentage of them. The ones that survive all four are your real candidates for production investment. Download the attached file for gated checklist and take it into your next architecture review. If you are starting a new agent project: Do not open a platform before you have answered the gate questions. Once you have confirmed an agent is warranted and identified the tier, start here: Copilot Studio guided setup for low-code scenarios, or Foundry Agent Service for pro-code patterns with MCP and multi-agent coordination built in. Build governance infrastructure - evaluation pipeline, distributed tracing, HITL gates - before you scale, not after. If you have already shipped agents to production: Share what worked and what did not in the Azure AI Tech Community — tag posts with #AgentArchitecture. The most useful signal for teams still in pilot is hearing from practitioners who have been through production, not vendors describing what production should look like. References OutSystems — State of AI Development Report - https://www.outsystems.com/1/state-ai-development-report Databricks — State of AI Agents Report - https://www.databricks.com/resources/ebook/state-of-ai-agents Gartner — 2025 Microsoft 365 and Copilot Survey - https://www.gartner.com/en/documents/6548002 (Paywalled primary source — publicly reported via techpartner.news: https://www.techpartner.news/news/gartner-microsoft-copilot-hype-offset-by-roi-and-readiness-realities-618118) Anthropic — Model Context Protocol (MCP) - https://modelcontextprotocol.io Google Cloud — Agent-to-Agent Protocol (A2A) . https://developers.googleblog.com/en/a2a-a-new-era-of-agent-interoperability NeuBird AI — Production Operations Deployment Announcement NeuBird AI Closes $19.3M Funding Round to Scale Agentic AI Across Enterprise Production Operations ReAct: Synergizing Reasoning and Acting in Language Models — Yao et al. https://arxiv.org/abs/2210.03629 Enterprise Integration Patterns — Gregor Hohpe & Bobby Woolf, Addison-Wesley https://www.enterpriseintegrationpatterns.com6.1KViews4likes1CommentGPT Capability in Understanding Coordinates: How GPT-5.4 Transforms Spatial Precision
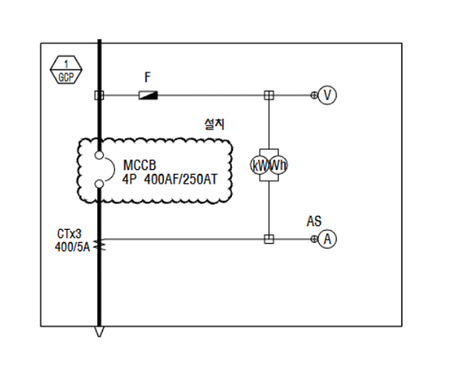
Why I Ran This Experiment This work started not as a benchmarking exercise, but as a practical problem: I needed to automatically extract panel regions from PDF-format electrical Single-Line Diagram (SLD) drawings using OpenAI models . All experiments were conducted using OpenAI models in Microsoft Foundry- Microsoft's unified platform for building generative AI applications. The downstream goal was a pipeline that combines GPT model with Azure Document Intelligence to generate Bills of Materials (BOMs) — a project I wrote about separately in Extracting BOMs from Electrical Drawings with AI: Azure OpenAI GPT-5 + Azure Document Intelligence Pipeline. Before building that pipeline, I needed a clear-eyed answer to a deceptively simple question: how well can GPT actually understand and return pixel-level coordinates from an image? If the model can't reliably locate a panel bounding box, the rest of the pipeline doesn't matter. When I first ran these tests against GPT-5.2, the results were mixed — good enough to be promising, but inconsistent enough to leave clear room for improvement. I tried many workarounds: feeding image dimensions explicitly, overlaying coordinate grids, enabling extended reasoning, and building iterative self-correction loops. Each helped, but required deliberate engineering effort. Then GPT-5.4 was released. Re-running the same benchmark revealed that most of those workarounds were no longer necessary. Context: All experiments use a fixed CAD-style test image (847 × 783 px) with a known ground-truth bounding box at [135, 165, 687, 619] . Accuracy is measured by Intersection over Union (IoU) — a score of 1.0 is a perfect match. Every test was run 5 times and averaged. for all coordinate experiments. The Experiment Design I designed experiments across two axes: prompt strategy (how spatial information is presented to the model) and reasoning mode (standard vs. extended reasoning). Each combination was tested across both GPT-5.2 and GPT-5.4, producing 4 conditions per test. GPT-5.2 and GPT-5.4 were each tested under two reasoning modes (None vs. High), resulting in four conditions in total. Single-Shot Strategies (Tests 1–5) These tests have no iterative validation loop — the model gets one prompt and returns its answer. Each test was run 5 times and the results averaged, so the scores reflect consistency, not a single lucky attempt. The differences between tests lie in how spatial information is framed in the prompt. Test 1 is a simple sanity check: can the model understand percentage-based coordinates at all? The model receives the clean image (no overlay) and is asked: "return the pixel coordinate at 30% width, 50% height." The expected answer is (254, 392). GPT-5.2 gets the X coordinate roughly right (~254–260), but the Y coordinate scatters wildly — predictions range from 260 to 322, consistently 100+ pixels above the correct position. GPT-5.4 returns (254, 392) on every single run, essentially pixel-perfect. Even on this simple sanity check, the gap is stark: GPT-5.4 is pixel-perfect from the start, while GPT-5.2 shows a clear Y-axis bias. But a single-point test doesn't tell us how well the models handle real spatial tasks. The next question: can they detect a full bounding box? Tests 2–5: Bounding Box Detection with Increasing Prompt Richness Tests 2–5 move to the real task: detecting a bounding box drawn on the image. Each test sends a different version of the same base image, with progressively richer spatial context in the prompt: Feedback Loop Strategies (Tests 6A–7B) These tests add an iterative validation loop: the model's predicted bounding box is overlaid on the image and sent back for self-correction — up to 5 iterations (early stop at IoU ≥ 0.99). All feedback tests share the same two-phase structure: an init step (first prediction) and a validation loop (iterative correction). All feedback tests use the same two images (init + validation overlay), but differ in prompt strategy and color assignment. Image-wise, they fall into two groups: Group A — Orange GT (Tests 6A, 6C, 7A) Group B — Color Bias / Blue GT (Tests 6B, 6D, 7B) Figure 4b — Feedback loop input images. Group B (bottom): colors swapped to test color-role priors. What differs between tests in the same group: The images are identical, but the prompt changes. 6A/6B use holistic comparison ("compare and correct"). 6C/6D additionally send the full history of past predictions as multi-image input. 7A/7B ask for per-edge directional judgments ("move left/right/up/down/none" for each edge independently). Results 1. Model version is the single biggest factor Across every test, GPT-5.4 dramatically outperforms GPT-5.2. The gap is not incremental — it's the difference between a bounding box that roughly overlaps the target and one that is essentially pixel-perfect. GPT-5.4 achieved an IoU of 0.99 or above on its very first attempt on tests where GPT-5.2 had only scored between 0.76 and 0.88. GPT-5.4 (green bars) consistently hits ≥0.99 regardless of prompt strategy or reasoning mode. GPT-5.2 (blue bars) ranges from 0.76 to 0.92. 2. GPT-5.2 is inconsistent; GPT-5.4 locks in Raw averages only tell half the story. GPT-5.2 is unpredictable: on the exact same test with the exact same prompt and image, results fluctuate wildly between runs. The standard deviation on Test 2 is ±0.084 — meaning a single run could land anywhere from 0.66 to 0.88. GPT-5.4 stays within ±0.003. The scatter plots below make this viscerally clear. Each dot is one API call — notice how GPT-5.2 dots spray across the IoU range while GPT-5.4 dots stack on top of each other: Wide scatter on simpler prompts (Test 2: 0.66–0.88); reasoning mode (orange) provides a lift that shrinks with richer prompts (Δmean shown below each panel). Production implication: With GPT-5.2, you couldn't rely on a single inference call — building a reliable pipeline would require multiple calls and majority voting, multiplying latency and cost. With GPT-5.4, a single call is sufficient. 3. Reasoning mode reduced variance for GPT-5.2; GPT-5.4 didn't need it For GPT-5.2, enabling extended reasoning ( reasoning: high ) provided a meaningful boost — especially when the prompt was sparse. On Test 2 (bare image, no spatial context), reasoning added +0.076 IoU and visibly tightened the spread of results across runs. As prompts got richer, the benefit shrank: with a grid overlay (Test 4), reasoning added only +0.007. In other words, reasoning mode acted as a compensating mechanism — filling in the gaps when the prompt alone didn't provide enough spatial scaffolding. For GPT-5.4, reasoning mode offered no additional benefit on this class of task. The base model already achieves 0.99+ IoU, so there was simply no room for improvement. In a few cases the reasoning runs showed marginal regressions (−0.005 to −0.015), likely within noise. The takeaway isn't that reasoning mode is harmful in general, but rather that a spatial-coordinate task at this complexity level doesn't require it when the underlying model already has strong coordinate understanding. Figure 7 — Effect of reasoning mode: GPT-5.2 gains +0.04–0.08 from reasoning (blue bars), largest on sparse prompts. GPT-5.4 shows no meaningful gain (green bars near zero). 4. Richer prompts close the gap (but only for GPT-5.2) For GPT-5.2, providing more spatial context in the prompt made a big difference: from 0.765 (Test 2, no info) to 0.910 (Test 4, grid overlay) — a +0.145 IoU gain just from adding visual reference rulers to the image. Telling the model the image dimensions (Test 3) was a "free win" that cost nothing. For GPT-5.4, all prompt variants produce essentially the same result (0.989–0.997). The model already understands spatial coordinates well enough that extra scaffolding adds no value. ided. GPT-5.4 is flat at ≥0.99 regardless. If you're still on GPT-5.2: Always inject image dimensions into the prompt (free). Use grid overlays for the biggest single-shot gain (+0.145 IoU). With GPT-5.4, none of this is needed. 5. Validation loops: essential for GPT-5.2, Option for GPT-5.4 The feedback loop tests (6A–7B) showed that iterative self-correction genuinely helped GPT-5.2 improve from its initial prediction. For example, in Test 7A (directional feedback), GPT-5.2 improved from an init IoU of 0.926 to a best of 0.969 over 5 iterations. For GPT-5.4, every single run hit IoU ≥ 0.99 on iteration 1 and early-stopped immediately. There was nothing left to correct. The validation loop infrastructure — overlay rendering, multi-turn prompting, iteration logic — becomes dead code you can remove from your pipeline. GPT-5.4 (green) starts at ≥0.99 and early-stops at iteration 1. 6. Prompt instruction matters: holistic vs directional feedback Comparing 6A/6B (holistic: "compare the two boxes and correct") with 7A/7B (directional: "for each edge, decide which direction to move"), the directional approach consistently reached higher best IoU for GPT-5.2. The per-edge structured output forced the model to reason about each boundary independently rather than making a holistic guess. Separately, the color bias tests (6B, 7B — GT drawn in blue instead of orange) revealed that swapping GT/prediction colors drops the initial accuracy significantly. In 6A (orange GT) the init IoU was 0.937, but in 6B (blue GT) it dropped to 0.850. This suggests GPT models have learned color-role priors — orange is "expected" as the ground truth color. However, the validation loop largely recovers this gap: after 5 iterations, 6A and 6B converge to similar best IoU (~0.96). The directional variants (7A, 7B) show the same pattern but converge faster. Left: initial accuracy drops when GT is drawn in blue. Right: after the validation loop, the gap closes. Directional feedback (7A/7B) shows the same pattern. For GPT-5.4: Color bias has no measurable effect. All variants (6A/6B/7A/7B) hit 0.994–0.998 IoU on iteration 1 regardless of color assignment. Summary: What Changed from GPT-5.2 to GPT-5.4 The story of this benchmark is really about engineering workarounds that became unnecessary. Here's what we built for GPT-5.2 and whether you still need it: Grid overlays & image dimensions in prompt — Gave +0.05–0.15 IoU for GPT-5.2. Not needed for GPT-5.4 (already ≥0.99 without it). Extended reasoning mode — Gave +0.04–0.08 IoU for GPT-5.2. No benefit for GPT-5.4 on this task (already at ceiling without it). Validation loops (iterative self-correction) — Improved GPT-5.2 by +0.02–0.10 IoU over 5 iterations. Unnecessary for GPT-5.4 (early-stops at iteration 1). Multiple runs & voting — Required for GPT-5.2 due to ±0.08 variance. Not needed for GPT-5.4 (±0.003 variance, single call sufficient). Color convention management — GPT-5.2 showed color bias (−0.09 IoU when colors swapped). No effect on GPT-5.4. GPT-5.4 doesn't just perform better — it makes entire categories of pipeline engineering unnecessary. For clean, CAD-style images like the ones tested here, GPT-5.4 dramatically reduces prompt engineering overhead: grid overlays, image dimension injection, reasoning mode, and validation loops — all of which required deliberate effort with GPT-5.2 — are no longer necessary. This translates directly to simpler pipelines, lower latency, and lower cost. That said, for more complex scenarios — multiple overlapping panels, cluttered backgrounds, or ambiguous region boundaries — iterative validation loops could still prove valuable, and we plan to explore this in future work. This benchmark started as a sanity check and turned into a clear signal: GPT-5.4 represents a genuine leap in spatial coordinate understanding, not just a marginal iteration. The gap between 0.765 and 0.997 IoU on an identical task is the difference between a prototype experiment and a production-ready component. Try It Yourself Ready to explore GPT-5.4's spatial precision capabilities? Here are ways to get started: Sample notebooks for bounding box extraction test : github Read the companion post: Extracting BOMs from Electrical Drawings with AI: Azure OpenAI GPT-5 + Azure Document Intelligence — See how this benchmark informed a production pipeline888Views4likes0CommentsTeach ChatGPT to Answer Questions: Using Azure AI Search & Azure OpenAI (Semantic Kernel)
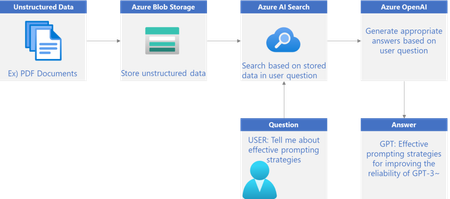
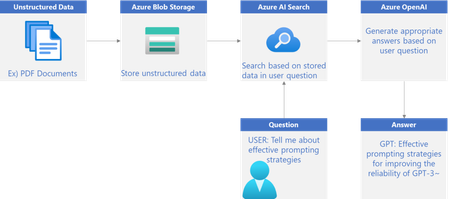
In this two-part series, we will explore how to build intelligent service using Azure. In Series 1, we'll use Azure AI Search to extract keywords from unstructured data stored in Azure Blob Storage. In Series 2, we'll Create a feature to answer questions based on PDF documents using Azure OpenAI26KViews4likes3CommentsTeach ChatGPT to Answer Questions: Using Azure AI Search & Azure OpenAI (Lang Chain)
In this two-part series, we will explore how to build intelligent service using Azure. In Series 1, we'll use Azure AI Search to extract keywords from unstructured data stored in Azure Blob Storage. In Series 2, we'll Create a feature to answer questions based on PDF documents using Azure OpenAI.44KViews4likes9CommentsAzure OpenAI GPT model to review Pull Requests for Azure DevOps
In recent months, the use of Generative Pre-trained Transformer (GPT) models for natural language processing (NLP) has gained significant traction. GPT models, which are based on the Transformer architecture, can generate text from arbitrary sources of input data and can be trained to identify errors and detect anomalies in text. As such, GPT models are increasingly being used for a variety of applications, ranging from natural language understanding to text summarization and question-answering. In the software development world, developers use pull requests to submit proposed changes to a codebase. However, reviews by other developers can sometimes take a long time and not accurate, and in some cases, these reviews can introduce new bugs and issues. In order to reduce this risk, During my research I found the integration of GPT models is possible and we can add Azure OpenAI service as pull request reviewers for Azure Pipelines service. The GPT models are trained on developer codebases and are able to detect potential coding issues such as typos, syntax errors, style inconsistencies and code smells. In addition, they can also assess code structure and suggest improvements to the overall code quality. Once the GPT models have been trained, they can be integrated into the Azure Pipelines service so that they can automatically review pull requests and provide feedback. This helps to reduce the time taken for code reviews, as well as reduce the likelihood of introducing bugs and issues.49KViews4likes13Comments