azure kubernetes service
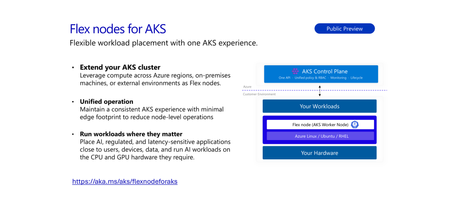
248 TopicsAnnouncing flex nodes for AKS (preview) in Azure portal
Explore how AKS flex nodes can address regional CPU and GPU capacity constraints, bring distributed compute under one control plane, and support on-premises workload placement for data residency, now with the Azure portal experience to simplify onboarding.73Views1like0CommentsScale Data Collection Endpoint private connectivity with IP Endpoint Compression - Preview
Scale Azure Monitor Private Link with data collection endpoint IP compression As organizations expand their Azure Monitor deployments, private networking needs to scale with them. For enterprises running large, distributed environments, that can create an increasingly important challenge: how do you grow private monitoring without consuming private IP address space at the same rate? Azure Monitor is introducing private IP endpoint compression for data collection endpoints (DCEs) connected through Azure Monitor Private Link Scope (AMPLS). This capability is designed to reduce the private IP footprint by ~90%-95% associated with DCEs while preserving the Azure Monitor Private Link architecture and the security controls customers already use. The challenge: private monitoring at enterprise scale Organizations often centralize Azure Monitor connectivity through carefully governed hub-and-spoke networks. As these environments grow, they can include monitored resources, data collection rules (DCRs), DCEs, and Log Analytics workspaces distributed across multiple regions. When private connectivity is required, DCEs are connected through AMPLS. The associated private endpoint uses addresses from a customer-managed subnet. As more DCEs are added, this can increase the private IP footprint required for Azure Monitor connectivity and create challenges such as: Increased subnet-capacity planning Additional network-governance reviews Delays when onboarding workloads or regions Provisioning challenges when available subnet capacity becomes constrained More operational complexity in centralized DNS and hub-and-spoke environments As customers onboard more Azure resources to send telemetry over private networks, they need a scalable way to preserve valuable private IP address space without increasing the operational complexity of their network-isolated monitoring environment. Introducing DCE private IP endpoint compression DCE private IP endpoint compression changes how DCE service endpoints are represented behind an AMPLS private endpoint. Instead of having the private IP footprint scale directly with every DCE, the compressed architecture groups compatible DCE service endpoints regionally and allows them to use a smaller, bounded set of private IP configurations. Requests continue to be routed to the intended DCE based on the requested endpoint and the existing Azure Monitor authorization context. The result is a more scalable private-network architecture without introducing a new data collection model. What does this mean for customers? Large enterprises have limited, tightly managed, often fragmented private IPv4 spaces. Private endpoints require IP addresses from customers' private IPv4 subnets. With private IP endpoint compression, all DCEs in a region share 3 regional private IPs. For example, 20 DCEs drop from 60 private IPs to 3, which is 95% fewer. Private IP address use stops growing with every DCE you add. There are no changes to how DCEs, DCRs, AMPLS, Azure Monitor Agent or Log Analytics work. Use private address space more efficiently A smaller, bounded private IP footprint can preserve valuable subnet capacity for additional workloads and Azure services. This can be particularly useful for enterprises operating with constrained private IP address space or centralized network-allocation processes. Make network planning more predictable Instead of treating each additional DCE as a proportional increase in private IP requirements, network teams can plan capacity around the regional architecture. This approach makes the network planning more predictable for enterprise customers. Scale monitoring across more workloads and regions Reducing pressure on private IP address space can make it easier to expand monitoring across applications, subscriptions, and regions without repeatedly redesigning private endpoint subnets. Reduce operational friction A more compact endpoint representation can reduce the networking work associated with subnet capacity reviews, expansion planning, and Private Link onboarding. What stays the same? One of the goals of this design is to improve network scalability while preserving the Azure Monitor model customers already use. DCE private IP endpoint compression doesn't change: The role of AMPLS as the private Azure Monitor network boundary The role of the private endpoint connecting a virtual network to AMPLS AMPLS Open and Private Only access modes DCR collection, transformation, and routing logic Azure Monitor Agent configuration semantics Log Analytics tables, retention, or KQL query behavior The amount of telemetry ingested into Azure Monitor Application Insights data collection, which doesn't use DCEs Azure Monitor ingestion charges Azure Private Link data-processing charges based on data volume Customers should continue following their existing DNS, routing, network security, public network access, and AMPLS configuration requirements. Preparing for the controlled preview DCE private IP endpoint compression is currently intended for subscriptions participating in a controlled preview. For customers participating in the preview, we recommend starting with a nonproduction or limited deployment. Before expanding the deployment: Map your topology. Understand the virtual networks, peering, AMPLS resources, private endpoints, DCEs, DCRs, workspaces, DNS zones, and supporting subnets involved. Review DNS ownership. Pay particular attention to networks sharing Azure Monitor private DNS zones and use a deliberate AMPLS topology. Establish a baseline. Record your existing private endpoint IP configurations and DCE DNS responses. Confirm regional alignment. Review the relationship between monitored resources, DCE configuration access, ingestion endpoints, and destination workspaces. Review access modes. Confirm the appropriate use of AMPLS Open or Private Only access modes for your security requirements. Validate end to end. Verify DNS resolution, Azure Monitor Agent configuration access, DCR health, ingestion, transformation, and query behavior before expanding the deployment. Looking ahead Bottom line: DCE private IP endpoint compression is designed to make private Azure Monitor deployments easier to scale by reducing the relationship between DCE growth and private IP consumption, while preserving the Azure Monitor and AMPLS architecture customers use today. Customers interested in participating in the controlled preview can contact the author via email with their subscription need to be allowlisted for the preview. This preview is available only to allowlisted subscriptions. To request access, submit your Azure subscription ID through the DCE IP Endpoint Compression preview onboarding form. Wait for Microsoft to confirm that your subscription is preview-enabled before you create the test DCEs. IP compression applies automatically to newly created DCEs in preview-enabled subscriptions. There's no additional setting to enable when you create a DCE or associate it with AMPLS. We look forward to helping customers scale private Azure Monitor deployments while making more efficient use of their network address space. Resources Learn more about designing and configuring private connectivity for Azure Monitor: Scale Data Collection Endpoint (DCE) private connectivity with IP Endpoint Compression (Preview) - Azure Monitor | Microsoft Learn Use Azure Private Link to connect networks to Azure Monitor Learn how Azure Monitor Private Link Scope (AMPLS), private endpoints, and Azure Monitor resources work together to provide private connectivity. Design your Azure Monitor Private Link configuration Review network topology, DNS, AMPLS limits, hub-and-spoke architectures, and other considerations when planning Azure Monitor Private Link. Configure Azure Monitor Private Link Follow the configuration guidance for creating an AMPLS, connecting Azure Monitor resources such as Data Collection Endpoints (DCEs), and connecting the AMPLS to a private endpoint. Prevent IPv4 Exhaustion in Azure - Azure Architecture Center | Microsoft Learn201Views0likes0CommentsPlan Your Java Upgrade Ahead of Microsoft’s 2027 Support Milestones
In April 2021, we announced the Microsoft Build of OpenJDK. We were starting with a preview of our Java 11 builds for Windows, Linux, and macOS. Today, if you’re planning a Java upgrade on Azure, you have several generations of that work to build on: 11, 17, 21, and now 25. Java 8 has been part of that work too, with help from the fine folks at the Eclipse Foundation’s Eclipse Adoptium project. Microsoft has supported Java 8 on Azure using their Eclipse Temurin builds of OpenJDK 8, rather than producing a Microsoft Build of OpenJDK 8. That collaboration goes back to the launch: our first Java 11 builds also used Adoptium’s build scripts and quality assurance suite. Supporting those releases has meant years of updates. Now it’s time to plan the next move. The Microsoft Build of OpenJDK support roadmap lists September 2027 as the earliest end-of-support date for Java 11 and 17. That’s a distribution-wide milestone: if you use those Microsoft builds on a VM, in a container, on Kubernetes, on Azure platform services, or evem outside Azure, it belongs in your upgrade planning. These dates are initial targets, and Microsoft may extend them. However, consider taking action now. Azure services also have their own deadlines. Azure App Service and Azure Functions support for Java 8, 11, and 17 ends on September 1, 2027. Existing applications will continue to run, but the affected Java versions will no longer receive security updates, improvements, or related customer support. If that’s your application, the practical question is how to get to Java 21 or 25 while keeping it working. GitHub Copilot modernization gives you a tool: the Modernize CLI, which can assess your code, help plan the upgrade, and actually perform and apply changes for you to review. Continue reading on the Java at Microsoft blog...232Views0likes0CommentsAnyscale on Azure is now Generally Available
Anyscale on Azure is now Generally Available. Enterprises can run the Ray distributed runtime as a managed service on Azure Kubernetes Service (AKS), with workloads running in the customer’s own Azure subscription, network, and identity boundary. With General Availability, Anyscale on Azure is ready for production workloads and comes with the commitments enterprises need. It is backed by a service level agreement and production support from both Microsoft and Anyscale. Customer workloads, datasets, and model artifacts run in their Azure subscription, while Anyscale operates the control plane in its own Azure tenant. Customers can use their Azure identity and governance controls for the resources in their subscription. Xoople is already using Anyscale on Azure to turn planetary-scale satellite imagery into decision-ready intelligence. AI systems need more than a good model Model quality is only part of the challenge. Enterprises must also connect, secure, and operate the stages around the model. A typical stack assembles one tool for data preparation, another for distributed training, a third for evaluation, and a fourth for serving. Each tool solves part of the problem. Connecting them can require custom integration code, separately provisioned compute, and security controls that teams must maintain across systems. The resulting challenges fall into four areas: Utilization: GPUs provisioned per stage can sit idle while another stage waits for capacity. Reserved capacity that is idle is still billed. Security and governance: Teams must manage who can access data and models, where they are processed, and how security controls are configured across each system and handoff. Engineering time: Integration code requires ongoing maintenance, monitoring, and troubleshooting alongside the tools themselves. Development cycle time: Handoffs between stages can slow the path from experimentation to production. Anyscale on Azure addresses this fragmentation by bringing data preparation, training, evaluation, and inference into a common runtime and operational model. Shared infrastructure can reduce idle compute capacity, while managed Ray cluster lifecycles reduce the infrastructure work teams perform themselves. Workloads, datasets, and model artifacts remain in the customer’s Azure subscription, where teams configure access and networking controls. Using a common runtime across stages can also reduce the need to maintain separate compute stacks. The goal is to support an AI learning loop, not just inference: production feedback informs data curation, training or post-training, and evaluation before updated models return to serving. Anyscale provides the common compute platform; teams remain responsible for their models, evaluation criteria, application workflows, and security configuration. How Anyscale on Azure works Anyscale on Azure is an Azure Native Integration with an Anyscale-operated control plane and a customer data plane that keeps core resources in the customer’s Azure tenant, helping teams maintain their security and data-residency requirements. Anyscale hosts and operates the control plane in Azure. You reach it from the Azure Portal, the Anyscale console, or the Anyscale CLI and SDK. The data plane runs entirely inside your own Azure subscription: Anyscale deploys an operator into your AKS cluster, which manages Ray cluster lifecycles on your behalf. This keeps Ray workloads, datasets, and model artifacts in your Azure subscription, while the Anyscale-hosted control plane processes operational metadata. Workloads run on AKS within your virtual network and use your existing Microsoft Entra ID, Azure RBAC, and private networking controls. The Anyscale operator and Ray clusters initiate outbound connections to the Anyscale control plane, so Anyscale does not require inbound firewall access to AKS nodes for those connections. Anyscale on Azure integrates with Azure Managed Identities for authentication, Azure Blob Storage and ADLS for data, Azure Key Vault for secrets, and Azure Container Registry for images. Use familiar Azure identity and resource controls Anyscale on Azure is backed by Azure Resource Manager, allowing platform teams to apply Azure Policy and discover Anyscale resources through Azure Resource Graph, just as they do with other Azure resources. Control How it works on Anyscale on Azure Provisioning A guided Azure Portal flow provisions storage, managed identity, container registry, and service account, then installs the Anyscale operator. ARM templates and Terraform are supported. Identity Sign-in runs through Microsoft Entra SSO. Conditional Access policies that govern Azure portal sign-in govern Anyscale sign-in too. Authorization Azure RBAC against your existing role assignments, with three built-in Anyscale roles as a starting point. Policy Platform teams can apply Azure Policy to supported Azure resource types. Validate policy coverage for the Anyscale resource and its underlying infrastructure. Private connectivity Connect the Anyscale operator and Ray clusters on AKS to Anyscale control plane through a private endpoint in the customer’s virtual network. Outbound traffic travels over the Microsoft backbone rather than the public internet. Cost visibility Usage appears in Microsoft Cost Management and on the same Azure invoice, drawing down against MACC. Data boundary Ray workloads run on AKS, with datasets and model artifacts in your subscription; operational metadata is managed separately. For regulated industries such as financial services, healthcare, and public sector, Anyscale on Azure makes in-tenant AI attainable. In production: Xoople Xoople is building what it calls Earth's system of record, a continuously updated and AI-ready picture of how the planet's surface is changing. The workload is a useful illustration of why a unified runtime matters. Turning raw spectral data from satellite constellations into decision-ready measurements is not primarily a model problem. It is continuous, large-scale, heterogeneous computation: ingest and reprojection, calibration, feature extraction, model training, and inference, each at a different shape and each needing different hardware. With Anyscale on Azure, Xoople can reliably run massively distributed AI workloads over planetary-scale satellite imagery, transforming complex spectral data into decision-ready intelligence. Anyscale lets our teams focus on models and outcomes rather than infrastructure, dramatically accelerating the path from experimentation to deployment. — Milos Colic, VP of Engineering, Xoople Workloads teams run on Anyscale on Azure Workload What it's used for Why it fits a unified runtime Multimodal data preparation Curating and preparing image, video, text, and sensor datasets for training CPU decoding and GPU model-based processing run in one pipeline, with no handoff between systems Distributed training and fine-tuning Scaling distributed training across available GPU capacity Checkpointing and, when using Ray Data for data loading, mid-epoch resume can reduce repeated work after interruptions Composite AI serving Deploying and orchestrating multi-model AI applications in production Ray Serve runs multiple models and steps as a single service Embedding generation Producing embeddings at scale for search and retrieval CPU preprocessing and GPU inference share one cluster and one scheduler Reinforcement learning for LLMs Coordinating parallel reinforcement-learning post-training workloads Rollouts, reward scoring, and training are coordinated in one Ray program Physical AI simulation Running thousands of concurrent simulation environments Ray schedules large numbers of parallel simulations alongside training One runtime for the entire AI lifecycle One Ray runtime supports data preparation, training and fine-tuning, batch and online inference, and long-running agentic workloads. When each stage has its own compute, capacity reserved for one can sit idle while another waits. A shared scheduler reallocates compute as demand shifts, which can reduce idle capacity and lower infrastructure costs. Model choice also matters. Fine-tuned, task-specific models can cut serving costs when they meet quality requirements, so weigh total cost, not inference alone. The Anyscale Runtime supports Ray APIs, so existing Ray code needs fewer changes to move over. Customers should validate dependencies, data access, networking, and deployment configuration. Get started Anyscale on Azure is provisioned from the Azure Portal onto an AKS cluster in your own subscription. You manage and monitor deployments from Portal, and use the Anyscale console, CLI, and SDK for cluster-level work. Review the Anyscale on Azure overview on Microsoft Learn for architecture and prerequisites. Check regional availability against where your data resides. Create an Anyscale cloud on an existing AKS cluster from the Azure Portal, then configure managed identities for access to Blob Storage, Key Vault, and Container Registry. Move an existing Ray workload using compatible Ray APIs, after validating dependencies and deployment configuration, or start from the Anyscale on Azure quickstart. Check current Azure pricing and offer eligibility before assuming free-account credits apply to Anyscale on Azure usage. Resources Anyscale on Azure architecture and overview Anyscale on Azure pricing Anyscale on Azure solution page Anyscale on AKS Terraform reference deployment Anyscale on Azure public preview announcement Anyscale on Azure press release, June 2, 2026 Announcing Anyscale Runtime Ray on AKS overview932Views0likes0CommentsVirtual nodes on Azure Container Instances: a new compute layer for AKS
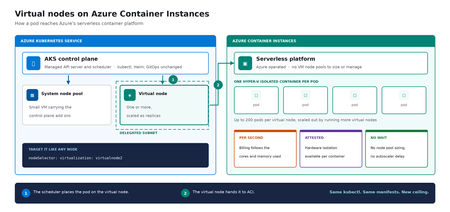
Meet virtual nodes on ACI Azure Kubernetes Service (AKS) gives you managed Kubernetes: the full Kubernetes API without operating the control plane yourself. Virtual nodes on Azure Container Instances go a step further, letting your pods run directly on Azure's serverless container platform, with the elasticity and with no capacity planning and no waiting for machines. Whether you already run AKS or want a managed Kubernetes that bursts without node management, this is for you. In short: virtual nodes on ACI attach Azure's serverless container platform to your cluster as Kubernetes nodes. Pods run as Hyper-V isolated containers, sized per pod rather than packed onto a fixed VM, up to 200 pods per virtual node. Run multiple virtual nodes, scaled as replicas, for more. They behave like any other pod: same kubectl, Helm, and GitOps. Kubernetes has always assumed a fixed set of machines underneath it. That assumption shapes everything above it: you size a node pool for a specific VM type in a specific region, you plan for peak rather than for average, and every workload on a node shares the same kernel and the same security boundary. Virtual nodes on ACI relaxs that assumption, which is what makes both elastic capacity and per container isolation possible without a different Kubernetes. If you've used the original AKS virtual nodes add-on (Virtual Kubelet based), this is not a rebrand. It is a new implementation that integrates far more deeply with Kubernetes, lifts most prior limitations (init containers, persistent volumes, managed identity, richer networking), and adds confidential containers as a first-class capability. The migration guide can be found here. Two capabilities carry the rest of this post: effortless burst capacity, and confidential containers. How virtual nodes on ACI work ACI runs every container as a Hyper-V isolated container, which means each one gets its own lightweight virtual machine boundary rather than sharing a kernel with its neighbors. Azure operates that platform. A virtual node connects it to your cluster. The cluster's control plane, the component that decides where each container runs, sees two kinds of destination: a small pool of virtual machines carrying cluster services, and one or more virtual nodes. From the application manifest's perspective, nothing changes. The pod lands on a virtual node; the virtual node hands it off to ACI. See Microsoft Learn: virtual nodes on ACI for the official capability and current limits. Virtual nodes on ACI in practice The rest of this post is hands on. You do not need to be a Kubernetes expert to follow it. kubectl is the command line tool for talking to a cluster, Helm installs packaged software into one, and a manifest is a text file describing what you want to run. If you have a cluster, everything below runs against it as written. The manifests behind the examples live in a companion demo repo. Setup is documented officially, and you can reproduce this end to end from the ACI virtual nodes documentation and the microsoft/virtualnodesOnAzureContainerInstances Helm repo. One requirement before you start: deploy into a delegated ACI subnet, meaning a subnet in your virtual network set aside for the ACI platform to place containers in. Size it for peak pod count plus headroom, since every pod consumes an address from it for its lifetime. Demo manifest files can be found in this repo, a personal sample repo provided as is and not a supported Microsoft artifact. Enable virtual nodes on ACI The virtual node is deployed via Helm. The Microsoft GitHub repo is itself a Helm repository, so a single helm install is all you strictly need. Cloning first, shown here, just makes it easier to customize values. Running kubectl get nodes afterward confirms the node registered. git clone https://github.com/microsoft/virtualnodesOnAzureContainerInstances.git helm install <yourReleaseName> ./virtualnodesOnAzureContainerInstances/Helm/virtualnode kubectl get nodes The virtual node appears alongside any existing capacity, ready to accept work. A virtual node is a Kubernetes node You target it the same way you would target any node. These few lines in a manifest say "run this on the virtual node": nodeSelector: virtualization: virtualnode2 kubernetes.io/os: linux tolerations: - key: virtual-kubelet.io/provider operator: Exists effect: NoSchedule That is the entire integration surface. No new API to learn, no separate deployment pipeline, no application changes. kubectl describe, kubectl logs, and kubectl exec, the standard commands for inspecting and troubleshooting, all work as they would anywhere else, including opening a shell inside a container running in a Hyper-V isolated boundary. Scaling stays trivial. kubectl scale deployment demo-deployment --replicas=10 lands every replica on the same virtual node, with no VMSS scale event, no provisioning latency, no climbing node-count chart. The same flow scales just as cleanly to hundreds. Cost follows the same shape. Each pod is billed per second against the cores and memory it requests, at ACI rates, and billing stops when the pod stops. Logs and metrics flow through the same path you already use, so existing dashboards and alerts keep working. One annotation makes a pod confidential Turning a regular container into a confidential one takes a single addition to its manifest: a policy that pins exactly which images, commands, environment variables, mounts, and capabilities are permitted inside the Trusted Execution Environment. The format is a base64 encoded Rego document, called a CCE (Container Confidential Enforcement) policy. You do not write that policy by hand. A tool generates it from the manifest you already have: az extension add -n confcom az confcom acipolicygen --virtual-node-yaml ./hello-world-deployment.yaml The tool pulls each image, hashes its layers, builds the allow-list, and injects the annotation back into the manifest. kubectl apply, and you're done. (acipolicygen has prerequisites of its own, including a working Docker installation; see the confcom documentation.) Here is why this is a genuinely new isolation primitive rather than a stronger version of an existing one. Most container security policy is enforced by software in the cluster, which means an attacker who compromises the host can potentially bypass it. This policy is enforced by the guest operating system inside the TEE instead. The underlying hardware, AMD SEV-SNP, also produces an attestation report, retrievable from inside the container, which is a cryptographic proof that the workload running is the workload you specified and nothing tampered with it. That is the guarantee regulated industries have been asking for, and increasingly the one AI workloads running untrusted code need too. The same per pod boundary is also what makes multi-tenancy on a single cluster realistic, though multi-tenancy in production still depends on your network and identity boundaries, which sit outside what the isolation layer itself provides. Background: Microsoft Learn: confidential containers on ACI. Wrapping up Virtual nodes on ACI give containers on Azure two things that were previously hard to deliver cleanly on Kubernetes: Effortless burst capacity on Azure's serverless container platform, billed per second for the cores and memory used, with no capacity planning and no waiting for machines. Confidential containers with hardware attested, per container isolation inside a Trusted Execution Environment. Virtual nodes are additive, not a replacement. Traditional node pools remain the right home for steady state, DaemonSet, and persistent volume workloads, and AKS features such as Node Auto Provisioning and Virtual Machine Node Pools already make that baseline more flexible. Virtual nodes on ACI absorb the spikes, the short-lived jobs, and the specialized isolation work on top. Where to start New to containers on Azure? Start with a small AKS cluster and add a virtual node from day one. You get a managed Kubernetes environment without having to guess your peak capacity in advance, and the elastic layer is there the first time you need it. Already running AKS? Add a virtual node to an existing cluster and move one bursty or short lived workload to it. Nothing else changes, and the comparison is immediate. Evaluating platforms? The capability that is hard to find elsewhere is the confidential containers path: hardware attested isolation per container, reachable through a standard Kubernetes manifest. The result: virtual nodes on ACI expand what AKS can run, with more capacity and stronger isolation, without changing the Kubernetes operating model you already use. Same kubectl, same manifests, same GitOps. New ceiling. For the high-level overview, official documentation, and Helm details, the Microsoft Learn is the source of truth. The companion repo holds the demo manifests used in this post. Acknowledgements I'd like to thank Gurpreet Virdi, Partner Group Engineering Manager, whose guidance shaped this post from the first outline through to publication. Her product leadership ensured this post reflects both the technical depth and the customer value of virtual nodes on ACI. Thanks to Gabriel Fuhrman, Senior Software Engineer, for his detailed technical review. His feedback refined the technical content and significantly improved the accuracy and depth of this post. Christopher Little, Principal CSA, shaped the enterprise adoption perspective, and Adam Sharif, CSA, reviewed the post from the earliest draft. Thanks also to Kirthi Maguluri, Senior Product Manager, and Varun Shandilya, Principal Product Manager, for their review of the blog.786Views1like0Comments
Action required: PromQL regex matching in Azure Monitor Workspace is becoming spec-compliant
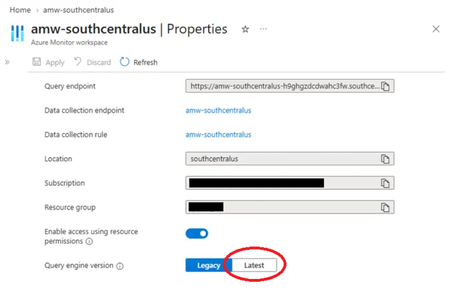
TL;DR: Bare regex matchers like pod=~"foo" will soon return only exact matches, not substring matches. If you rely on =~ for "starts with" or "contains" semantics, update your queries to add .* before the change lands. What is changing AMW's Prometheus Query Service is moving to fully-anchored regex matching, aligning with the upstream Prometheus specification. After the change, every =~ and !~ matcher is wrapped with ^…$ before evaluation. This matches the behavior of self-hosted Prometheus, Grafana Cloud Metrics, and Amazon Managed Prometheus. "Regex matches are fully anchored. A match of env=~"foo" is treated as env=~"^foo$"." Reference: Prometheus querying basics — Instant vector selectors Behavior delta Given these timeseries: kube_pod_container_status_ready{pod="grafana-otel-collector-97b6c55f4-abc12"} kube_pod_container_status_ready{pod="grafana-otel-collector-97b6c55f4-def34"} kube_pod_container_status_ready{pod="grafana-otel-collector-97b6c55f4"} Query: kube_pod_container_status_ready{pod=~"grafana-otel-collector-97b6c55f4"} Environment Effective regex Series returned AMW PQS — current grafana-otel-collector-97b6c55f4 (unanchored) 3 (all matching pods) AMW PQS — after change ^grafana-otel-collector-97b6c55f4$ 1 (exact name only) Self-hosted Prometheus, Grafana Cloud, AMP ^grafana-otel-collector-97b6c55f4$ 1 (exact name only) If your query depends on the first row, it will return fewer — often zero — series after the change. What to do Audit any query, alert rule, recording rule, or dashboard variable that uses =~ or !~. Map each to the table below. Intent Update to Exact match No change necessary; both label="value" and label=~"value" should return exact matches after updating query engine version for fully anchored regex support. Starts with label=~"value.*" Ends with label=~".*value" Contains label=~".*value.*" Set of prefixes label=~"(a\|b\|c).*" Recommendation: Where the intent is exact match, switch from =~ to = It is clearer to readers and skips per-series regex evaluation. When ready, update AMW configuration to use the latest Query engine version. This can be done via the Azure Portal UI, Azure CLI, or PowerShell. Configuring AMW to use the latest Prometheus query engine version Azure Portal In the Azure portal, open your Azure Monitor workspace. Under Settings, select Properties. Select the Latest segment of the Query engine version for the AMW. Azure CLI Run the following command to update to the latest (2.0) metrics query engine version for the AMW: Az monitor account metrics-container update --subscription <subscriptionId> -g <resourcegroupName> -w <azmonWorkspaceName> -n default --version 2.0 Azure PowerShell Run the following command to use the latest Query engine version for the AMW: $resourceId = “/subscriptions/<subscriptionId>/resourceGroups/<resourcegroupName>/providers/Microsoft.Monitor/accounts/<azureMonitorWorkspaceName>/metricsContainers/default” Az resource update --ids $resourceId --api-version 2025-10-03 --set properties.version=2.0 --force-string To confirm: Az resource show --ids $resourceId --api-version 2025-10-03 --query properties.version --output tsv Expected output: 2.0 Common pitfalls Alternation anchors the whole expression. pod=~"foo|bar" becomes ^(?:foo|bar)$, not ^foo|bar$. Add .* and parentheses for prefix sets. . matches any character, including -. pod=~"my-pod.*" will match my-pod-xyz, my-podxyz, and my-pod9xyz. Use character classes like [-] for tighter matches. Empty-label matching is unchanged. label=~"" still matches series without that label. Timeline Public Preview rollout: September 2026 In Public Preview, newly created AMWs will default to the latest metrics query version (“2.0”) which features fully anchored regex matching. AMWs created prior to September 2026 will continue using version (“1.0”) unless users take action to update. This provides users with the opportunity to verify their query intent and update accordingly prior to cutover to the latest AMW metrics query engine version. General Availability: March 2027 In General Availability, all AMWs regardless of creation date will be updated to version “2.0” for cross-workspace compatibility. Action window: Audit and update queries before the General Availability date.363Views0likes0CommentsAzure Copilot announces general availability of the Troubleshooting Agent
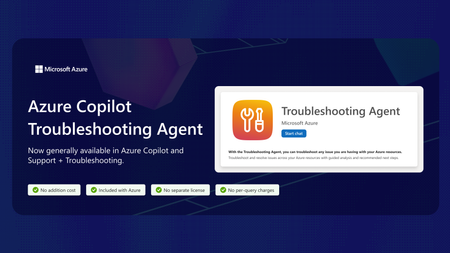
Cloud operations are most effective when teams can turn insights into understanding and understanding into action. Whether you’re deploying new services, troubleshooting an issue, assessing resource health, or managing change, you need operational intelligence that helps you make faster, more informed decisions and continuously improve your environment. This is the promise of agentic cloud operations, a new operating model that uses AI powered agents equipped with deep contextual understanding and built in governance to help you run your cloud environments with speed and confidence. Azure Copilot brings AI-powered operations directly into Azure, helping you understand your environment, identify issues, determine likely causes and take informed action using the context already available in your Azure resources and services. Today, Azure Copilot is announcing the general availability of Troubleshooting Agent, a unified, built-in Azure Copilot capability that helps customers investigate and resolve operational issues faster. Available through both Azure Copilot and Support + Troubleshooting in the Azure portal, Troubleshooting Agent enables you to move from issue detection to resolution faster by bringing together troubleshooting insights, operational context, and recommended actions in a single experience. Deep expertise across Azure services Azure services support a wide variety of architectures, operational patterns, and workload requirements. While Azure Copilot provides consistent agentic troubleshooting across Azure, deeper service integrations enable specialized expertise and investigative capabilities for specific services. At general availability, Azure Compute and Azure Kubernetes Service (AKS) are the first services to offer these enhanced troubleshooting experiences. Azure Compute: You can investigate issues such as unexpected virtual machine restarts, connectivity and boot failures, high resource utilization, deployment and allocation failures, and unhealthy scale set instances. AKS: You can investigate issues such as pod restarts, stalled deployments, scheduling constraints, cluster networking, scaling behavior, upgrade regressions, and degraded performance. “This [Troubleshooting Agent] is really helpful for the person who is debugging, and they can come to a conclusion. Instead of going through the entire documentation, it is giving us the exact information on what it needs and what to look on.” – Senior Software Engineer, Lavelle Networks As the agentic troubleshooting capabilities of Azure Copilot continue to evolve, additional service specific skills and capabilities will be added to support a broader range of operational scenarios across Azure services through the same conversational experience. Grounded in Azure context, with customers in control Azure Copilot Troubleshooting Agent uses the resource information and supported diagnostics available for the affected resource while respecting your identity and Azure role based access control (RBAC). The agent explains the information behind its findings and recommends actions for review, allowing you to remain in control of remediation actions. Diagnostic depth varies by service, resource type, and scenario, but the goal remains consistent: helping you investigate, diagnose, and resolve operational issues more effectively using the context already available within your Azure environment. When additional assistance is needed, Azure Support remains available, but you can begin those engagements with a richer understanding of the issue, its likely causes, and potential remediation options. Available at no additional cost Troubleshooting Agent in Azure Copilot is available at no additional cost. There is no separate license or per-query charge, and existing Azure Support plans remain unchanged. Standard charges for the Azure resources continue to apply. Get started Open Azure Copilot and select Troubleshooting Agent in the Azure portal or go to Support + Troubleshooting, then describe the issue you are experiencing. Include the affected resource or subscription if it is not already clear from your current context. To get started, here are some prompt suggestions: "Why did my virtual machine restart unexpectedly?", "Investigate why my AKS deployment is failing.", "Why can't I connect to this resource?", "What recent platform issues have affected this resource?", "Check whether this resource has active errors or configuration issues." Troubleshooting Agent will use the supported resource diagnostics available for the investigation, explain what it finds, and recommend next steps. Looking ahead Connected cloud environments need a more intelligent approach to operations. As part of our broader vision for agentic cloud operations, Azure Copilot is your starting point when you need to understand, troubleshoot, and take action across your Azure environment. Troubleshooting Agent is an important step in that journey. Based on available context and diagnostics, we help you move from symptoms to informed next steps faster.5KViews3likes1CommentHow Azure uses AI to turn feedback into improved customer experience
Authors: eshaanbhattad, jenniferjhan, lakshminarasimha, bharadwajr The Challenge: Synthesizing fragmented feedback signals, to improve Azure's experience quality at scale Customers experience products and services end to end, but product experiences are often structured around individual service. One team may only know its top issues, while another may see only its own slice of experience. That structure makes it difficult to identify cross-cutting friction across the broader product experience. The feedback signals themselves are also fragmented. Customers share feedback through in-product surveys, support cases, field conversations, and social channels. Most product teams can see only part of that picture, making it hard to distinguish isolated comments from meaningful trends, understand which issues were having the greatest impact, and avoid missing critical feedback. For the Azure team, the challenges of fragmentation were amplified by scale. The team processed roughly 10,000 to 15,000 customer feedback reports each month, and synthesizing that feedback required 80 to 100 hours of expert analysis. Additional effort was needed to translate findings into consistent engineering work items. As feedback volume grew, manual analysis became increasingly unsustainable creating delays in identifying and addressing customer priorities. Compounding the challenge was the absence of an effective feedback loop to measure the impact of quality improvements. Teams struggled to justify investments in quality over new features because the return on those investments was difficult to quantify. The absence of a closed-loop measurement system made it difficult to consistently assess the customer impact of quality improvements. The team needed a system that could operate across organizational boundaries and across the product development lifecycle: Identify the most critical customer issues across fragmented feedback channels and product areas. Convert those insights into actionable engineering work, help teams address issues effectively, and measure outcomes to close the loop. The solution needed to preserve team-specific context, maintain auditability, continuously improve through feedback, and keep human experts in control of decisions that require judgment. To address these challenges, Microsoft launched the Great Experiences Matter (GEM) initiative. GEM is designed to analyze feedback signals in aggregate, with access controls and privacy safeguards designed to limit exposure of customer-identifiable information while helping teams identify patterns across channels. The Solution: an agentic feedback-to-fix loop with humans in control GEM created an AI-enabled feedback-to-fix workflow that connects customer listening, engineering action, and impact measurement across the product development lifecycle. The workflow uses Microsoft Foundry, Azure Data Explorer, Microsoft Fabric, Azure DevOps, and a set of custom agents to transform large volumes of qualitative feedback into prioritized insights and actionable engineering work. Fig 1. GEM AI-enabled automation workflow The system closes the loop through two connected motions. Find. Agentic workflows remove noise and duplicate reports, assess relevance and actionability, classify feedback against known issues from UX research, cluster related issues, and surface likely root causes. GEM builds on years of deep end-to-end UX research that has identified systemic friction across customer journeys and product boundaries. By continuously triangulating GEM signals with ongoing research, we combine broad, scalable listening with deep human insight to inform a more cohesive Azure experience. The results are surfaced through global scorecards for cross-cutting Azure issues and vertical scorecards tailored to individual product teams. Fig 2. GEM Global scorecard of top issues with Azure, data has been fictionalized to protect intellectual property Fix. The workflow creates Azure DevOps work items with the customer context, likely reproduction steps, recommended next actions, and an auditable trace of the supporting analysis. To date, 42% of the identified issues have been addressed through engineering action. The team is also extending an AI-assisted engineering workflow, using GitHub Copilot cloud agent, that can generate proposed fixes for straightforward issues. Engineers remain responsible for reviewing, refining, approving, and shipping any changes. The architecture is designed for inspection rather than blind automation. The recommendations include an auditable evidence trail allowing reviewers to inspect the source feedback, classifications, supporting references, confidence indicators, and recommendation actions. Human expertise enters the system at several points. Researchers shape the issue taxonomies and qualitative grounding. Product teams define ownership boundaries, business priorities, domain-specific vocabulary, and trusted sources that guide agent analysis. Engineers review and act on resulting work items, while leaders use scorecards to inform investment decisions. This context is captured in configuration files that evolve alongside the products they support. Teams can add new issue categories, refine keywords, clarify ownership boundaries, or identify trusted research sources. The next analysis cycle automatically incorporates the updated context without requiring changes to the underlying agents. That design creates a "feedback loop for the feedback loop". Teams review the root-cause analyses and work-item quality, identify gaps, and refine their configurations. This enables teams to continuously embed domain expertise into the workflow, improving how feedback is interpreted and prioritized without requiring changes to the underlying infrastructure. Their input improves subsequent runs, helping the system become more precise while preserving local product knowledge. The agent also maintains access to reports from previous runs and uses tools such as Web IQ and MCP servers to assess whether previously identified issues are improving, still require attention, or can be confidently closed. Fig 3. Example of the vertical feedback agent reasoning through customer feedback to find new work items One demonstrated example surfaced customer reports that a networking tool lacked IPv6 validation and support. The workflow generated an engineering work item describing the issue, customer impact, likely reproduction path, and recommended actions. The networking team reproduced the issue, validated the finding, and added it to its backlog. The goal is not to remove people from the process. Agents assume much of the cognitive load associated with sorting, clustering, tracing, and drafting, allowing experts to focus on judgment, prioritization, and implementation. Teams remain accountable for what is fixed, what is funded, and what is allowed to ship. The Impact: measurable experience gains at Microsoft production scale GEM began with manual interventions and is now scaling through AI-enabled workflows. The combined approach has produced measurable results across the Azure Portal and individual product experiences: The workflow aggregates and analyzes approximately 10,000 to 15,000 feedback reports each month across in-product, support, and social channels. Automated analysis reduced manual synthesis time by over 95 percent, turning a process that required 110 to 160 hours each month into a workflow that runs in under 60 minutes. Between October 2025 and April 2026, Azure Portal feedback rates declined by 30%. During that same period, GEM helped teams identify and prioritize experience improvements, creating a clearer link between customer feedback, engineering action, and outcome measurement. Service-level outcomes also demonstrate how better signals can drive business impact. For example, improvements to VM Connect experiences reduced overall Core Compute support volume by 1-2% per month, resulting in proportionate cost savings. The Azure Growth team increased subscription conversion by 9.1 percent after prioritizing issues highlighted through GEM. The value goes beyond speed. Leaders gain a more consistent basis for prioritization, and engineering teams receive work that is already connected to customer evidence and impact signals. Most importantly, every completed cycle creates new learning. Teams can measure changes in customer feedback and support volumes following improvements, incorporate partner input into future analyses, and continuously refine both the system and the products it helps improve. Key learnings and transferable practices The GEM experience offers several lessons for teams building agentic systems around complex, qualitative business processes: Start with real problems, not AI - Value comes from understanding the genuine business needs and applying AI where it is demonstrably better than existing approaches. Applying AI without a clearly defined problem often adds complexity without delivering meaningful value. Design for the end-to-end workflow - Value comes from connecting insights to the broader business process, including grounding in prior knowledge, prioritization, engineering action, post-fix measurement and reporting. Standalone AI output creates limited value, while an integrated workflow drives outcomes. Design for human judgment and accountability - Agents can reduce toil and cognitive load, but researchers, product managers, engineers, and leaders remain responsible for validating insights and determining appropriate actions. Ground agents in the knowledge of the teams they serve - Shared models require local context. Editable configuration files allow teams to define ownership, business priorities, releases, examples, and trusted sources without modifying underlying agents. Build observability and feedback mechanisms into the agentic system itself - Making analysis inspectable through reasoning traces, source context, and recommendations enables experts to identify gaps, improve outputs, and build trust over time. Build feedback mechanisms directly into the flow of work, making it effortless for users to provide input on the system. Tailor outputs to the people making decisions - Executives need trends and investment signals. Researchers need evidence and themes. Engineers need reproducible, actionable work. Effective systems deliver the right information to the right audience. Start small and iterate quickly - The AI landscape continues to evolve rapidly. Begin with a well-defined problem, measure outcomes, learn from feedback, and iterate as capabilities mature. Looking forward GEM continues to scale across the Azure Portal ecosystem. In addition to the global scorecard, vertical scorecards are now live with seven teams, expanding to the top 20 portal extensions representing more than 80% of portal traffic and feedback, with longer-term plans to extend coverage across the entire ecosystem. The roadmap includes expanded feedback ingestion, streamlined work-item tracking, AI-assisted remediation workflows, stronger evaluation, and a self-improving architecture. Proposed fixes would remain subject to engineer review, approval, and standard release controls before deployment. GEM is also developing AI-assisted pre-release governance workflows for production code that help identify potential quality issues during development. We will share more about these pre-release workflows in a future post. New tools and models will continue to evolve, but the enduring principle remains the same: combine enterprise-scale automation with clear ownership, trusted grounding, and human control. For Microsoft, Customer Zero means deploying these systems in real production environments, learning from the complexities, and sharing those lessons broadly. GEM shows what becomes possible when AI does more than summarize feedback. It helps an organization listen, act, measure outcomes, and continuously learn at customer scale. Microsoft's Customer Zero blog series gives an insider view of how Microsoft builds and operates Microsoft using our trusted, enterprise-grade agentic platform. Learn best practices from our engineering teams through real-world lessons, architectural patterns, and operational strategies for building, operating, and scaling AI-powered systems across the organization.1.2KViews2likes0Comments