azure kubernetes service
273 TopicsWhat’s new in Azure SRE Agent at Microsoft Ignite 2026
At Microsoft Ignite 2026, Azure SRE Agent joins Microsoft Teams as a member of your team, with its own Microsoft Entra agent identity. It also now collaborates with other teams’ agents, investigates across AWS and Google Cloud, and starts work from the Azure Container Apps portal, Azure CLI, Grafana, and connector triggers.376Views0likes0CommentsWhat's new in Azure Monitor at Ignite 2026
Agents now sit at the center of modern applications, calling models, tools and other agents across a stack of APIs, data and infrastructure, so when a customer says the agent is slow, the cause can sit anywhere. At Microsoft Ignite 2026, Azure Monitor gives developers, SREs and IT operations teams one platform for end-to-end visibility across agents, applications, data and infrastructure. This year's announcements span four areas: full-stack agent observability, AI-assisted operations, business impact with Microsoft Fabric, and cost efficiency at scale. Why this matters Agentic applications are changing what it means to keep a service healthy. An agent might call several models and tools, hand work off to other agents, and rely on APIs, databases, Kubernetes clusters and virtual machines behind the scenes, so when a customer says the agent is slow, the cause can sit anywhere in that stack. At the same time, technical health needs business context to be meaningful, and both model consumption and telemetry add cost at scale. At Microsoft Ignite 2026, Azure Monitor is responding with one platform that gives developers, SREs and IT operations teams end-to-end visibility across agents, applications, data and infrastructure. This year's announcements fall into four areas: full-stack agent observability, AI-assisted operations, business impact with Microsoft Fabric, and cost efficiency at scale. Full-stack agent observability Agent observability follows the same loop your teams use to improve agents: observe what happened, evaluate quality, then optimize. Azure Monitor and Microsoft Foundry share one platform and the Microsoft OpenTelemetry Distro, so builders and operators work from the same telemetry. Observe and monitor: see what happened Agent details in Application Insights show per-agent metrics, errors, tool calls, models and tokens, correlated with application and infrastructure signals so you can pinpoint where failures begin. You can also link and observe agents built outside Foundry (generally available), compare health and usage across all your agents in a new fleet view (public preview), and track token usage and cost per agent (private preview). Learn more: aka.ms/AzMon_AgentObs | Unified agent observability with end-to-end tracing in Azure Monitor Trace Analytics builds on Application Insights distributed tracing to accelerate root cause analysis at-scale. It stitches spans across resources into key transactions, drives metrics for SLIs, alerts and dashboards, and lets you compare healthy and failing transactions at scale, including GenAI interactions. Learn more: aka.ms/AzMonTracesPreview Evaluate: measure quality A new evaluations view brings Foundry evaluations into Azure Monitor so you can track agent quality at scale. In Foundry, annotations add human feedback to agent runs, and a safety evaluator scores responses against safety rubrics. Learn more: Monitor AI agents in Application Insights and Run evaluations in Foundry. Microsoft Foundry turns those signals into action, with skill optimization from evaluation results, suggested fixes for failing runs and cost optimization to reduce token and model. Suggested code changes for agents are coming soon. Learn more: [Link to Foundry agent optimization blog] A secure, private, multimodal platform Protected tables (public preview) give GenAI content such as prompts and responses its own RBAC, and PII redaction (public preview) detects and masks values such as emails and SSNs in Log Analytics. Cross-agent debugging (public preview) brings in telemetry from Copilot Studio agents, GitHub Copilot and Azure Copilot, with Fabric Data Agent, Microsoft 365 Agent Builder, Microsoft 365 Copilot, Cowork and OTLP agents coming soon. You can also inspect images, PDFs and audio in agent interactions (private preview), and a lower-cost SKU for agent telemetry with a starter kit and free tier is coming soon. Learn more: aka.ms/ProtectGenAIContent | aka.ms/ProtectGenAIPii Find and close monitoring gaps across the stack OpenTelemetry onboarding is now generally available for apps on Azure VMs, scale sets and AKS, and AKS control plane metrics are generally available. Monitoring Coverage gives you one place to see coverage for VMs, AKS and Arc-enabled Kubernetes and apply recommendations in batches of up to 100 resources. New platform telemetry coverage (preview) extends this to resources such as storage accounts and key vaults, with data flow validation that flags problems before they cause data loss. Learn more: aka.ms/AzMonOTLPIgnite2026 | Monitoring coverage in Azure Monitor - Azure Monitor | Microsoft Learn AI-assisted operations Bring Azure Monitor into the coding agents your teams already use, and track workload health with flexible health models and SLOs. Azure Observability skills plugin in coding agents (public preview) The new skills plugin brings Azure Monitor capabilities into coding agents such as GitHub Copilot in VS Code, so you can detect, investigate, remediate and validate issues end-to-end. The skills draw on Prometheus and the Log Analytics, Application Insights, traces and Foundry MCP servers, packaging best practices so tasks use fewer tokens. A minimal fix is proposed for human approval, then evaluations confirm recovery before anything reaches production. Learn more: aka.ms/DashboardWithGrafanaMCP | aka.ms/AzObsSkillsPlugin Azure Monitor health models (generally available) Health models turn monitoring signals and dependencies into a clear view of workload health that both teams and agents can use. Start with SLIs and SLOs for a Service Group or any set of resources, then nest component models into a workload view that shows dependency impact and blast radius. Health is also available in Resiliency Hub and through a Health API and MCP server. Learn More: http://aka.ms/ahmgablog Business impact with Fabric Azure Monitor logs mirroring to Fabric (public preview contd.) Mirroring Azure Monitor logs to Microsoft Fabric lets you correlate errors and latency with transaction and customer data to assess revenue at risk and prioritize incidents by business impact. Service health and business KPIs then come together in Power BI as a shared view for IT and business stakeholders. Cost efficiency at scale More data means more cost, so Azure Monitor gives you two levers: match storage to how data is used and reduce telemetry before it is ingested. Match log storage and retention to your needs Analytics Logs serve real-time monitoring and alerting, while Basic and Auxiliary Logs offer pay-per-query pricing for troubleshooting and high-volume audit data. Long-term retention keeps data for up to 12 years, and commitment tiers optimize pricing Azure Monitor pipeline (public preview additions) The pipeline adds Azure Monitor's first managed OpenTelemetry collection for logs, metrics and traces at terabyte scale, plus Linux VM and server hosting so you can run it without Kubernetes. It filters and compresses data with KQL before ingestion and routes to Azure Monitor or any OpenTelemetry destination, with generally available health signals that flag potential data. Learn more: aka.ms/AzMonVMSupport Shape data at ingestion Enhanced data transformations (public preview) give you more control over what lands in your workspace. Schemaless ingestion keeps undeclared properties in a dynamic column, so evolving logs no longer need a schema update for every field, and a new data collection rules overview helps you spot duplicate collection that adds cost. Learn more: aka.ms/SchemalessIngestion Get started Customers are already seeing what that full-stack visibility makes possible. As Chris Waugh, Manager of Platform Architecture at Radiology Partners, puts it: “Azure Monitor is the cornerstone of Radiology Partners’ cloud operations strategy, giving us centralized visibility across critical Azure services, including virtual machines, AKS, Application Gateways, and more. With Log Analytics, Application Insights, and real-time alerting, our teams have the insights they need to prevent outages and quickly diagnose issues when they occur. This has helped us prevent downtime and, when issues do arise, gives us a jumpstart understanding of what the issue may be. Tailored alerts through Microsoft Teams bring the right context to the right teams, helping us resolve issues faster and keep our cloud environment reliable and resilient.” – Chris Waugh, Manager of Platform Architecture, Radiology Partners Whether you are building your first agent or running hundreds of services in production, Azure Monitor gives you one place to observe the full stack, investigate with AI and human oversight, connect reliability to business outcomes, and keep costs under control. Try the new capabilities in the Azure portal and tell us what you think.170Views1like0CommentsAzure Catalyst: one connected, agent-led modernization experience across apps, data, and infra
Azure Catalyst brings together Azure and GitHub Copilot in one experience to modernize applications, data, and infrastructure. It connects discovery, planning, and execution to help customers modernize faster, reduce complexity, and accelerate AI transformation.1.1KViews0likes0CommentsRun models and agents on your own Kubernetes clusters: AKS at Microsoft Ignite 2026
At Microsoft Ignite 2026 this week, we're introducing AKS AI Manager for Foundry, which lets you deploy open-weight models and Foundry hosted agents from Microsoft Foundry onto Azure Kubernetes Service (AKS) clusters you already run. Developers stay in the Foundry workflow they know, and platform teams keep their own networking, identity, policy, and GPU capacity. Alongside it, AKS is shipping updates for agent sandboxing, GPU operations, confidential computing, node lifecycle, and multi-cluster management. Here's what's new and where to start. For the wider set of Azure AI infrastructure news, including Agent Grid and Azure Cobalt 200 VMs, read the Azure AI infrastructure announcement from Ignite. Foundry models and agents on AKS clusters you govern Many organizations want the Foundry developer experience but need AI workloads to run on infrastructure their platform team already secures and pays for. AKS AI Manager for Foundry brings the two together, bringing intelligent optimization to AI workloads, GPU and VM performance, topology, and real-time capacity allocation to decide where workloads land and how the infrastructure is configured. Deploy open-weight models from Foundry to AKS (limited preview) You pick an open-weight model in Foundry and deploy it to your own AKS cluster with the security policies and governance already in place. Your team chooses GPUs and regions based on cost, latency, and data residency while Foundry handles the setup, so developers keep one workflow from first test through production. At Ignite, BRK420 walks through the whole path, from selecting a model and a runtime tuning profile to serving it on GPU node pools with workload identity, policy, and built-in observability. Run Foundry hosted agents on your own AKS clusters (limited preview) With this deployment option, Foundry runs the agent runtime on your AKS cluster, and developers keep building, deploying, and calling agents through Foundry with the same APIs, Azure Developer CLI (azd) flow, and endpoint they use today. Each session runs in its own pod inside a lightweight VM through AKS pod sandboxing, which keeps sessions isolated from one another. Foundry manages the agent lifecycle and its integration components, while your team operates the cluster, node pools, networking, container registry, and storage. This option fits teams that already run AKS as a platform, or that need agent workloads to stay inside an infrastructure, network, or compliance boundary they manage. Sign up for the hosted agents on AKS preview, and read what's new for hosted agents in Foundry Agent Service for the rest of this week's agent updates, including network egress controls and memory snapshots. Isolated sandboxes for agent-generated code Agents that execute model-generated code need an isolated environment for each session, but starting a fresh runtime every time leaves users waiting, and three previews work on both sides of that problem. The Agent Sandbox extension for AKS, built on the open-source Kubernetes Agent Sandbox project, handles sandbox creation, lifecycle, and pre-warmed pools, with two runtime options: Kata microVM isolation on your cluster's own nodes or a serverless runtime enabled by Azure Container Instances (ACI). The Pod Snapshot cluster extension saves a supported pod's memory and process state to Azure Blob Storage and restores it on demand, so a sandbox picks up where it left off instead of initializing again. Outside of agent workloads, pod sandboxing also gets a new kata isolation runtime class (preview) that starts pods from a pre-initialized VM template with lower per-pod memory overhead, so any sandboxed workload gets VM-level isolation with faster starts. Less GPU setup and better GPU utilization Managed GPU node pools are now generally available (GA). On each enabled node pool, AKS manages the GPU driver, Kubernetes device plugin, and metrics exporter, and GPU metrics flow into Azure Monitor. Support for NVIDIA GB200 and GB300 VM sizes is in preview on Ubuntu and Azure Linux node pools, with AKS managing the GPU software stack for Grace CPUs and Blackwell-family GPUs. If your GPUs are sitting underused, the mixed multi-instance GPU (MIG) strategy (preview) splits each supported GPU into differently sized instances, so workloads with different requirements share one GPU. Confidential computing and hardened nodes Confidential VM (CVM) node pools with Azure Container Linux are now GA on Intel Trust Domain Extensions (TDX) and AMD Secure Encrypted Virtualization-Secure Nested Paging (SEV-SNP) VM sizes, pairing hardware-based protection for data in use with an immutable, container-optimized host operating system. Sensitive workloads move over without refactoring, and the Center for Internet Security (CIS) Level 1 Benchmark for Azure Container Linux, also GA, gives security teams a published baseline to assess nodes against. In preview, Ubuntu 26.04 CVM node pools add Intel TDX support and encrypt the operating system (OS) disk by default from first boot, with no configuration changes. Node Hardening (preview) reserves resources for the kubelet, container runtime, and host services and adds soft eviction thresholds, so busy nodes stay responsive and pods shut down gracefully under memory or disk pressure. Nodes that scale out and recover with less intervention Node auto-provisioning (NAP) creates right-sized nodes in response to pending pods, and this release brings it to more workloads. Trusted Launch, Capacity Reservation Groups, instance-level public IP addresses, OS disk type selection, and AKS Machine API integration are now GA, while Windows Server nodes and node image pinning are in preview. NAP also adds Capacity Buffers, which keep a declared amount of spare capacity ready for bursty or latency-sensitive workloads in place of placeholder pods. On the recovery side, pod eviction on freeze is GA: before a scheduled VM freeze, AKS cordons the node and evicts only the pods you've labeled, respecting Pod Disruption Budgets. In preview, node autorepair can bring up a replacement node before removing an unhealthy one, and Container Network Interface (CNI) autorepair detects supported pod startup failures and starts recovery on its own. To confirm your applications hold up through events like these, Azure Chaos Studio workspaces and scenarios are GA, with pod-level faults for AKS clusters and a report for every run. Zone-redundant egress and simpler fleet operations New clusters using the managed network address translation (NAT) gateway outbound type now get a managed StandardV2 NAT gateway (GA) where StandardV2 is available, adding zone redundancy, up to 100 Gbps of throughput, IPv4 and IPv6 addresses, and flow logs. Existing clusters keep the NAT gateway they have, so moving to StandardV2 stays your call. For teams running many clusters, Azure Kubernetes Fleet Manager brings several capabilities to GA. Cross-cluster networking provides a managed Cilium multi-cluster network with global service discovery, now including member clusters on overlay networks. The security patch auto-upgrade channel applies weekly Linux node security updates, and scheduled start gates and label-based update groups decide when an update stage begins and which clusters it reaches. Multi-cluster identity binding management, in preview, lets you define an identity binding once and distribute it across member clusters. AKS desktop and AI-assisted troubleshooting AKS desktop picks up three previews: support for AKS on bare metal clusters without opening an inbound firewall port, an AI Assistant that detects GitHub Copilot and brings in AKS Skills and AKS MCP (Model Context Protocol) for cluster-aware troubleshooting, and Headlamp plugins with a Plugin Catalog for GitOps, security, and autoscaling workflows. For air-gapped environments, AKS Investigator (preview) runs read-only, AI-assisted incident investigations locally on AKS on Azure Local disconnected operations. Catch up on KubeCon North America If you missed KubeCon + CloudNativeCon North America 2026 last week, Brendan Burns covered the upstream and AKS updates that sit alongside these launches, including managed dynamic resource allocation (DRA) for GPUs and GA placement controls in Fleet Manager. Read What's new in Kubernetes, open source, and AKS for the full rundown. Watch the AKS sessions on demand These breakout sessions are recorded and will be available on demand after they air. BRK420: Deploy and run Microsoft Foundry models and agents on AKS. Take a model or agent from Foundry to a governed deployment on your own cluster. BRK422: Run open-weight models, post-training, and agents on AKS. GPU capacity, model serving, and distributed post-training with Ray, with Harvey on stage. BRK421: Operate a global AKS fleet across regions, edge, and sovereign clouds. Keep distributed clusters consistent with Fleet Manager, with JetBlue on stage. Where to start If you want Foundry models or agents on infrastructure your team already governs, sign up for the hosted agents on AKS preview and watch BRK420 (live streamed and recorded). If you're running GPU workloads today, try managed GPU node pools on a test cluster first, and if you're building agents that execute code, start with the Agent Sandbox extension for AKS. We'd like to hear what you're trying and what's still getting in your way, so leave a comment below.228Views0likes0CommentsWhat's new in Azure Functions durable task scheduler: Durable agents, disaster recovery, and more
There's been a lot happening with the Azure Functions durable task scheduler lately. Here's a quick look at what's new: Durable agents: The Durable Extension for Microsoft Agent Framework is generally available, durable execution with DTS for LangGraph is in preview, and Pydantic AI now includes Azure Durable Task as a built-in durability option. Native disaster recovery and task queues: Both are now in public preview. Private endpoints and customer-managed keys: Both are now generally available. Durable Task Go SDK: Now available in preview. Whether you're running business workflows, processing event-driven pipelines, or coordinating AI agents, here's what these updates mean for your apps and how to get started. What is the Durable Task Scheduler? If you're new to the Durable Task Scheduler, it's a fully managed durable execution backend for workflows and agents on Azure. It saves progress as work runs, so applications can recover from interruptions without starting over. Completed steps whose results have been saved can be reused, and workflows can wait for human input or external events without keeping a worker active just to wait. DTS handles task scheduling, state persistence, and recovery. Its built-in dashboard lets you inspect execution history and manage running orchestrations. The DTS dashboard shows the execution timeline of a travel-planning workflow, including agent calls and a wait for approval. DTS runs separately from your application. Use it with Durable Functions, the Durable Task SDKs, or supported agent framework integrations, including the Durable Extension for Microsoft Agent Framework. Your application code can run anywhere in Azure, including Azure Functions, Azure Container Apps, and Azure Kubernetes Service. Already using DTS? Here's what's new. Durable execution in agent SDKs Agents and workflows need more than conversation history to recover from interruptions. They might call several tools, start a long-running job, or wait for someone's approval. If a worker restarts halfway through, the application needs to know which steps completed and what should happen next. Durable execution saves that progress, so agents and workflows can run for minutes, days, or weeks and resume from recorded progress after worker or container restarts, scaling events, or infrastructure failures. Retry policies help handle transient errors such as rate limits and timeouts. Completed model calls, tool calls, and activities whose results have been saved can be reused during recovery, reducing repeated work and token costs. Conversation context remains available, and workflows can wait for approvals or external events for hours or days without keeping a worker active just to wait. You can bring these durable execution capabilities to agents and workflows built with Microsoft Agent Framework, LangGraph, or Pydantic AI. Here's how to get started with each: Microsoft Agent Framework: The Durable Extension is generally available for .NET and Python. Keep your core agent logic and coordinate durable agents and multi-agent workflows with Durable Task orchestrations or Agent Framework graphs. See the GA blog post and samples. LangGraph: In public preview. Add DTS to existing Python graphs, ReAct agents, and Deep Agents on Azure without rewriting your graph logic. Pydantic AI: Azure Durable Task is now available as a durability capability in Pydantic AI Harness. Use it with Durable Task orchestration and worker setup to persist model and tool results and recover agent execution without building your own checkpointing or recovery system. Native disaster recovery is now in public preview Native disaster recovery for Azure Functions durable task scheduler is now in public preview. For business-critical workflows and applications with cross-region recovery requirements, it provides a way to resume work in another region from replicated state rather than starting workflows over. Pair your primary scheduler with a secondary in another Azure region, and DTS replicates orchestration and entity state to the secondary. When you need to fail over, you can promote the secondary and resume work from that replicated state. Learn more: Disaster recovery documentation. Task queues are now in public preview Task queues for Azure Functions durable task scheduler are now in public preview. Group orchestration and activity work into named queues within a task hub and control how quickly DTS delivers that work to workers. This helps teams pace batch processing and give different workloads their own dispatch-rate budgets without creating separate task hubs. For workloads that call downstream services, it provides a way to manage how quickly work is dispatched. Create a queue, configure its work-item delivery rate, and select it using the DTS_TaskQueue tag when scheduling work. For a closer look at how task queues work and an example of how to use them, see Task queues in Durable Task Scheduler. Learn more: Task queues documentation and SDK examples. Private endpoints are now generally available Private endpoints for Azure Functions durable task scheduler are now generally available for both Consumption and Dedicated SKU schedulers. Connect your applications to DTS through a private IP address in your virtual network using Azure Private Link. Traffic stays on the Microsoft backbone instead of traversing the public internet. You can also disable public network access so your scheduler accepts connections only through private endpoints. Applications continue to use the same scheduler endpoint and Microsoft Entra authentication. Learn more: Configure private endpoints for DTS. Customer-managed keys are now generally available Customer-managed keys for Azure Functions durable task scheduler are now generally available for Dedicated SKU schedulers. Organizations that need to manage their own encryption keys can now use customer-managed keys to protect their workflow data, supporting separation of duties, centralized auditing of key access, and customer-defined key rotation policies. Use a key you own in Azure Key Vault or Azure Managed HSM to protect scheduler data at rest. Configuration is available through the ARM REST API, Azure CLI using az rest, or Bicep. Learn more: Configure customer-managed keys for DTS. The Durable Task Go SDK is now available in preview Writing your application in Go? You can now build durable workflows with the Durable Task Go SDK, available in preview. Write your orchestrations and activities in Go, and let DTS take care of durable state and dispatching work. You can chain activities, run work in parallel, wait for external events, and use durable timers. Retry policies help you handle failures, and orchestration management APIs let you manage execution. Start locally with the DTS emulator, then connect your application to a scheduler in Azure when you're ready. You'll need Go 1.25 or later, and DTS is currently the SDK's only supported runtime. Get started: Go SDK documentation, DTS quickstart sample, and Go sample catalog. Get started with the Durable Task Scheduler If you're new to DTS, start with the documentation and samples. You can develop locally with the emulator, then choose the Consumption or Dedicated SKU based on your workload's pricing and capacity requirements. We'd love to hear your feedback, especially as you try the new previews. Share questions and feedback through the Durable Task Scheduler GitHub repository.106Views0likes0CommentsTroubleshoot with OpenTelemetry in Azure Monitor – Now Generally Available
OpenTelemetry is fast becoming the industry standard for modern telemetry pipelines. Now Azure Monitor speaks it natively. With OpenTelemetry Protocol (OTLP) support generally available, you can ship logs, metrics, and traces from wherever your workloads run to analyze and act on it in one place. Direct OTLP ingestion into Azure Monitor has been generally available since May 2026. Now, we are expanding the scope to include automated onboarding for Azure Kubernetes Service (AKS) and using the Azure Monitor Agent (AMA) to receive and forward OTLP. OTLP Support in Azure Monitor Ingest OTLP signals directly into Azure Monitor logs, metrics, and traces. Automatically onboard AKS workloads. Receive and forward OTLP with (AMA) on Linux Azure VMs and VM Scale sets. Use Application Insights on OTLP for distributed tracing, performance and troubleshooting experiences. Visualize signals in Grafana with Azure-supported and community dashboards. Store and query OTLP metrics using PromQL Use OTLP semantic conventions for logs and traces, so your data lands in a familiar standards-based schema. Choose your OTLP path VMs/VM Scale Sets (and Azure Arc-enabled compute): Use the Azure Monitor Agent to receive OTLP from your apps and export it to Azure Monitor. Get started AKS: Auto-instrument Java, Node.js, Python and .NET workloads using the Azure Monitor OpenTelemetry distro, or auto-configure any OpenTelemetry SDK-instrumented workload to export OTLP to Azure Monitor. Get started Any environment: Use the OpenTelemetry Collector to receive OTLP signals and export directly to Azure Monitor cloud ingestion endpoints. Get started Where your telemetry lands Metrics: Stored in an Azure Monitor Workspace, a Prometheus metrics store. Logs + traces: Stored in a Log Analytics workspace using an OpenTelemetry semantic conventions–based schema. Troubleshooting: Application Insights lights up distributed tracing and end-to-end performance investigations, backed by Azure Monitor. OTLP traces: Also, now available in Azure Monitor traces with Trace Analytics Why it matters Standardize once: Instrument with OpenTelemetry and keep your telemetry portable and reusable. Reduce overhead: Fewer vendor-specific components and pipelines to maintain. Debug faster: Correlate metrics, logs, and traces using consistent labels to get from notifications to root cause faster. Observe with confidence: Use pre-built dashboards and tracing views and enable agent-assisted workflows through Azure Monitor MCPs and APIs. Next step: Onboard using direct ingestion, AKS or AMA, then validate end-to-end signal flow with Application Insights and Grafana dashboards. Learn More137Views0likes0Comments
Public preview: Auto scaling of ingestion limits in Azure Monitor workspace
If you run Azure Monitor Workspace at scale, you've probably had to request a higher ingestion limit at some point. A new service rolls out, a cluster scales out, or cardinality creeps up, and suddenly usage is close to your limit. Until now, the fix was a manual request, and you were at risk of throttling until the new limit was applied. Today we're announcing the public preview of Auto-scale for ingestion limits in Azure Monitor workspace (AMW). When you turn on Auto-scale, Azure Monitor adjusts your workspace's ingestion limits automatically based on your actual usage. Limits go up as your metrics volume grows and come back down when usage stays low for a sustained period of time. Why Auto-scale? Static ingestion limits create problems in both directions: Throttling risk: When usage grows faster than your limit, metrics can be dropped. You lose visibility right when your environment is changing. Manual work: Raising a limit means opening a support request and waiting for it to be applied. Over-provisioning: To avoid repeat requests, teams often ask for far more headroom than they need. Auto-scale removes this balancing act. Your limits track your real usage, so you can spend less time managing quotas and more time using your observability data. Key capabilities Turn on Auto-scale for your workspace During public preview, Auto-scale is an opt-in setting for each workspace. When it's on, the system keeps your ingestion limit at a healthy level compared with your usage: Scale up: When ingestion approaches the upper utilization threshold, your limit is raised to help prevent throttling. Scale down: When utilization stays low for a sustained period, unused capacity is reclaimed. Ingestion isn't affected. You can turn on Auto-scale in the with an ARM API update or in the Azure portal. Azure CLI: $resourceId = "/subscriptions/<subscriptionId>/resourceGroups/<resourceGroupName>/providers/Microsoft.Monitor/accounts/<azureMonitorWorkspaceName>/metricsContainers/default" az resource update --ids $resourceId --api-version 2026-09-03-preview --set properties.limits.enableAutoScale=true --force-string To turn Auto-scale off, set enableAutoScale=false. Your limits then stay fixed and you manage them manually, the same as today. [Coming soon] Azure portal: In the Azure portal, navigate to the Azure Monitor Workspace -> Limits and Usage to enable Auto-scale. Note: Azure portal support for this feature is being deployed in phases and is expected to be available in all regions in the coming weeks. See every scale change in the Activity Log When Auto-scale is enabled, any change in the ingestion limits is recorded in the workspace's Activity Log. You get a clear history of when your limits changed and in which direction. Set up alerts on limits, usage and scale events You can create Azure Monitor alerts on: Ingestion usage compared with your current limits, such as events per minute ingested and active time series. See set up recommended alerts for Azure Monitor Workspace to learn more. Dropped events or time series. See Monitor ingestion health to learn more. Any scale event triggered by Auto-scale. See Create an activity log alert rule to learn more. Once you set up these alerts, you will be notified whenever limits change, or when usage trends need a closer look. What about billing? Auto-scale doesn't change what you pay. It only adjusts your ingestion limit (the quota ceiling). Billing is still based on what you actually ingest. When should you use Auto-scale? Turn on Auto-scale if Keep Auto-scale off if Your metrics volume grows over time or varies with deployments You need a hard, fixed ingestion cap to control volume You want to avoid throttling without filing limit requests You prefer to manage limits manually through existing processes You want limits that match your real usage instead of padded headroom If you don't turn on Auto-scale, nothing changes. Your workspace behaves exactly as it does today. Get started Open your Azure Monitor workspace in the Azure portal or use the ARM command above. Turn on Auto-scale for ingestion limits. Check the Activity Log for scale events and set up alerts on usage and scale changes. Set up recommended alerts for your Azure Monitor Workspace to monitor your ingestion limits and utilization. Learn more. We want your feedback This is a public preview, and your input will shape general availability. Tell us how Auto-scale works for your workloads at AMW Auto-scale feedback form.148Views0likes0CommentsAzure NetApp Files: The Data Backbone for NVIDIA AI Model Training, Inference, and Microsoft Foundry
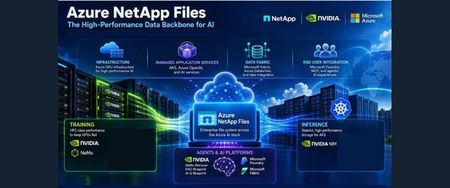
Azure NetApp Files provides a unified data foundation for enterprise AI, connecting data mobility, model training, inference, and agentic workflows. This article explores how caching, replication, high-throughput storage, low-latency checkpointing, and rapid dataset cloning help bring data closer to GPU compute and support efficient experimentation. It also examines persistent storage for containerized inference on Azure Kubernetes Service and integration with NVIDIA’s AI stack, Microsoft Foundry, and Microsoft Fabric. Two reference use cases illustrate its role in supporting domain-specific model training and modernizing AI inference while reducing infrastructure complexity.323Views0likes0CommentsAnnouncing flex nodes for AKS (preview) in Azure portal
Explore how AKS flex nodes can address regional CPU and GPU capacity constraints, bring distributed compute under one control plane, and support on-premises workload placement for data residency, now with the Azure portal experience to simplify onboarding.443Views1like0CommentsScale Data Collection Endpoint private connectivity with IP Endpoint Compression - Preview
Scale Azure Monitor Private Link with data collection endpoint IP compression As organizations expand their Azure Monitor deployments, private networking needs to scale with them. For enterprises running large, distributed environments, that can create an increasingly important challenge: how do you grow private monitoring without consuming private IP address space at the same rate? Azure Monitor is introducing private IP endpoint compression for data collection endpoints (DCEs) connected through Azure Monitor Private Link Scope (AMPLS). This capability is designed to reduce the private IP footprint by ~90%-95% associated with DCEs while preserving the Azure Monitor Private Link architecture and the security controls customers already use. The challenge: private monitoring at enterprise scale Organizations often centralize Azure Monitor connectivity through carefully governed hub-and-spoke networks. As these environments grow, they can include monitored resources, data collection rules (DCRs), DCEs, and Log Analytics workspaces distributed across multiple regions. When private connectivity is required, DCEs are connected through AMPLS. The associated private endpoint uses addresses from a customer-managed subnet. As more DCEs are added, this can increase the private IP footprint required for Azure Monitor connectivity and create challenges such as: Increased subnet-capacity planning Additional network-governance reviews Delays when onboarding workloads or regions Provisioning challenges when available subnet capacity becomes constrained More operational complexity in centralized DNS and hub-and-spoke environments As customers onboard more Azure resources to send telemetry over private networks, they need a scalable way to preserve valuable private IP address space without increasing the operational complexity of their network-isolated monitoring environment. Introducing DCE private IP endpoint compression DCE private IP endpoint compression changes how DCE service endpoints are represented behind an AMPLS private endpoint. Instead of having the private IP footprint scale directly with every DCE, the compressed architecture groups compatible DCE service endpoints regionally and allows them to use a smaller, bounded set of private IP configurations. Requests continue to be routed to the intended DCE based on the requested endpoint and the existing Azure Monitor authorization context. The result is a more scalable private-network architecture without introducing a new data collection model. What does this mean for customers? Large enterprises have limited, tightly managed, often fragmented private IPv4 spaces. Private endpoints require IP addresses from customers' private IPv4 subnets. With private IP endpoint compression, all DCEs in a region share 3 regional private IPs. For example, 20 DCEs drop from 60 private IPs to 3, which is 95% fewer. Private IP address use stops growing with every DCE you add. There are no changes to how DCEs, DCRs, AMPLS, Azure Monitor Agent or Log Analytics work. Use private address space more efficiently A smaller, bounded private IP footprint can preserve valuable subnet capacity for additional workloads and Azure services. This can be particularly useful for enterprises operating with constrained private IP address space or centralized network-allocation processes. Make network planning more predictable Instead of treating each additional DCE as a proportional increase in private IP requirements, network teams can plan capacity around the regional architecture. This approach makes the network planning more predictable for enterprise customers. Scale monitoring across more workloads and regions Reducing pressure on private IP address space can make it easier to expand monitoring across applications, subscriptions, and regions without repeatedly redesigning private endpoint subnets. Reduce operational friction A more compact endpoint representation can reduce the networking work associated with subnet capacity reviews, expansion planning, and Private Link onboarding. What stays the same? One of the goals of this design is to improve network scalability while preserving the Azure Monitor model customers already use. DCE private IP endpoint compression doesn't change: The role of AMPLS as the private Azure Monitor network boundary The role of the private endpoint connecting a virtual network to AMPLS AMPLS Open and Private Only access modes DCR collection, transformation, and routing logic Azure Monitor Agent configuration semantics Log Analytics tables, retention, or KQL query behavior The amount of telemetry ingested into Azure Monitor Application Insights data collection, which doesn't use DCEs Azure Monitor ingestion charges Azure Private Link data-processing charges based on data volume Customers should continue following their existing DNS, routing, network security, public network access, and AMPLS configuration requirements. Preparing for the controlled preview DCE private IP endpoint compression is currently intended for subscriptions participating in a controlled preview. For customers participating in the preview, we recommend starting with a nonproduction or limited deployment. Before expanding the deployment: Map your topology. Understand the virtual networks, peering, AMPLS resources, private endpoints, DCEs, DCRs, workspaces, DNS zones, and supporting subnets involved. Review DNS ownership. Pay particular attention to networks sharing Azure Monitor private DNS zones and use a deliberate AMPLS topology. Establish a baseline. Record your existing private endpoint IP configurations and DCE DNS responses. Confirm regional alignment. Review the relationship between monitored resources, DCE configuration access, ingestion endpoints, and destination workspaces. Review access modes. Confirm the appropriate use of AMPLS Open or Private Only access modes for your security requirements. Validate end to end. Verify DNS resolution, Azure Monitor Agent configuration access, DCR health, ingestion, transformation, and query behavior before expanding the deployment. Looking ahead Bottom line: DCE private IP endpoint compression is designed to make private Azure Monitor deployments easier to scale by reducing the relationship between DCE growth and private IP consumption, while preserving the Azure Monitor and AMPLS architecture customers use today. Customers interested in participating in the controlled preview can contact the author via email with their subscription need to be allowlisted for the preview. This preview is available only to allowlisted subscriptions. To request access, submit your Azure subscription ID through the DCE IP Endpoint Compression preview onboarding form. Wait for Microsoft to confirm that your subscription is preview-enabled before you create the test DCEs. IP compression applies automatically to newly created DCEs in preview-enabled subscriptions. There's no additional setting to enable when you create a DCE or associate it with AMPLS. We look forward to helping customers scale private Azure Monitor deployments while making more efficient use of their network address space. Resources Learn more about designing and configuring private connectivity for Azure Monitor: Scale Data Collection Endpoint (DCE) private connectivity with IP Endpoint Compression (Preview) - Azure Monitor | Microsoft Learn Use Azure Private Link to connect networks to Azure Monitor Learn how Azure Monitor Private Link Scope (AMPLS), private endpoints, and Azure Monitor resources work together to provide private connectivity. Design your Azure Monitor Private Link configuration Review network topology, DNS, AMPLS limits, hub-and-spoke architectures, and other considerations when planning Azure Monitor Private Link. Configure Azure Monitor Private Link Follow the configuration guidance for creating an AMPLS, connecting Azure Monitor resources such as Data Collection Endpoints (DCEs), and connecting the AMPLS to a private endpoint. Prevent IPv4 Exhaustion in Azure - Azure Architecture Center | Microsoft Learn270Views0likes0Comments