azure kubernetes service
257 TopicsAzure Copilot announces general availability of the Troubleshooting Agent
Cloud operations are most effective when teams can turn insights into understanding and understanding into action. Whether you’re deploying new services, troubleshooting an issue, assessing resource health, or managing change, you need operational intelligence that helps you make faster, more informed decisions and continuously improve your environment. This is the promise of agentic cloud operations, a new operating model that uses AI powered agents equipped with deep contextual understanding and built in governance to help you run your cloud environments with speed and confidence. Azure Copilot brings AI-powered operations directly into Azure, helping you understand your environment, identify issues, determine likely causes and take informed action using the context already available in your Azure resources and services. Today, Azure Copilot is announcing the general availability of Troubleshooting Agent, a unified, built-in Azure Copilot capability that helps customers investigate and resolve operational issues faster. Available through both Azure Copilot and Support + Troubleshooting in the Azure portal, Troubleshooting Agent enables you to move from issue detection to resolution faster by bringing together troubleshooting insights, operational context, and recommended actions in a single experience. Deep expertise across Azure services Azure services support a wide variety of architectures, operational patterns, and workload requirements. While Azure Copilot provides consistent agentic troubleshooting across Azure, deeper service integrations enable specialized expertise and investigative capabilities for specific services. At general availability, Azure Compute and Azure Kubernetes Service (AKS) are the first services to offer these enhanced troubleshooting experiences. Azure Compute: You can investigate issues such as unexpected virtual machine restarts, connectivity and boot failures, high resource utilization, deployment and allocation failures, and unhealthy scale set instances. AKS: You can investigate issues such as pod restarts, stalled deployments, scheduling constraints, cluster networking, scaling behavior, upgrade regressions, and degraded performance. “This [Troubleshooting Agent] is really helpful for the person who is debugging, and they can come to a conclusion. Instead of going through the entire documentation, it is giving us the exact information on what it needs and what to look on.” – Senior Software Engineer, Lavelle Networks As the agentic troubleshooting capabilities of Azure Copilot continue to evolve, additional service specific skills and capabilities will be added to support a broader range of operational scenarios across Azure services through the same conversational experience. Grounded in Azure context, with customers in control Azure Copilot Troubleshooting Agent uses the resource information and supported diagnostics available for the affected resource while respecting your identity and Azure role based access control (RBAC). The agent explains the information behind its findings and recommends actions for review, allowing you to remain in control of remediation actions. Diagnostic depth varies by service, resource type, and scenario, but the goal remains consistent: helping you investigate, diagnose, and resolve operational issues more effectively using the context already available within your Azure environment. When additional assistance is needed, Azure Support remains available, but you can begin those engagements with a richer understanding of the issue, its likely causes, and potential remediation options. Available at no additional cost Troubleshooting Agent in Azure Copilot is available at no additional cost. There is no separate license or per-query charge, and existing Azure Support plans remain unchanged. Standard charges for the Azure resources continue to apply. Get started Open Azure Copilot and select Troubleshooting Agent in the Azure portal or go to Support + Troubleshooting, then describe the issue you are experiencing. Include the affected resource or subscription if it is not already clear from your current context. To get started, here are some prompt suggestions: "Why did my virtual machine restart unexpectedly?", "Investigate why my AKS deployment is failing.", "Why can't I connect to this resource?", "What recent platform issues have affected this resource?", "Check whether this resource has active errors or configuration issues." Troubleshooting Agent will use the supported resource diagnostics available for the investigation, explain what it finds, and recommend next steps. Looking ahead Connected cloud environments need a more intelligent approach to operations. As part of our broader vision for agentic cloud operations, Azure Copilot is your starting point when you need to understand, troubleshoot, and take action across your Azure environment. Troubleshooting Agent is an important step in that journey. Based on available context and diagnostics, we help you move from symptoms to informed next steps faster.3.2KViews2likes1CommentHow Azure uses AI to turn feedback into improved customer experience
Authors: eshaanbhattad, jenniferjhan, lakshminarasimha, bharadwajr The Challenge: Synthesizing fragmented feedback signals, to improve Azure's experience quality at scale Customers experience products and services end to end, but product experiences are often structured around individual service. One team may only know its top issues, while another may see only its own slice of experience. That structure makes it difficult to identify cross-cutting friction across the broader product experience. The feedback signals themselves are also fragmented. Customers share feedback through in-product surveys, support cases, field conversations, and social channels. Most product teams can see only part of that picture, making it hard to distinguish isolated comments from meaningful trends, understand which issues were having the greatest impact, and avoid missing critical feedback. For the Azure team, the challenges of fragmentation were amplified by scale. The team processed roughly 10,000 to 15,000 customer feedback reports each month, and synthesizing that feedback required 80 to 100 hours of expert analysis. Additional effort was needed to translate findings into consistent engineering work items. As feedback volume grew, manual analysis became increasingly unsustainable creating delays in identifying and addressing customer priorities. Compounding the challenge was the absence of an effective feedback loop to measure the impact of quality improvements. Teams struggled to justify investments in quality over new features because the return on those investments was difficult to quantify. The absence of a closed-loop measurement system made it difficult to consistently assess the customer impact of quality improvements. The team needed a system that could operate across organizational boundaries and across the product development lifecycle: Identify the most critical customer issues across fragmented feedback channels and product areas. Convert those insights into actionable engineering work, help teams address issues effectively, and measure outcomes to close the loop. The solution needed to preserve team-specific context, maintain auditability, continuously improve through feedback, and keep human experts in control of decisions that require judgment. To address these challenges, Microsoft launched the Great Experiences Matter (GEM) initiative. GEM is designed to analyze feedback signals in aggregate, with access controls and privacy safeguards designed to limit exposure of customer-identifiable information while helping teams identify patterns across channels. The Solution: an agentic feedback-to-fix loop with humans in control GEM created an AI-enabled feedback-to-fix workflow that connects customer listening, engineering action, and impact measurement across the product development lifecycle. The workflow uses Microsoft Foundry, Azure Data Explorer, Microsoft Fabric, Azure DevOps, and a set of custom agents to transform large volumes of qualitative feedback into prioritized insights and actionable engineering work. Fig 1. GEM AI-enabled automation workflow The system closes the loop through two connected motions. Find. Agentic workflows remove noise and duplicate reports, assess relevance and actionability, classify feedback against known issues from UX research, cluster related issues, and surface likely root causes. GEM builds on years of deep end-to-end UX research that has identified systemic friction across customer journeys and product boundaries. By continuously triangulating GEM signals with ongoing research, we combine broad, scalable listening with deep human insight to inform a more cohesive Azure experience. The results are surfaced through global scorecards for cross-cutting Azure issues and vertical scorecards tailored to individual product teams. Fig 2. GEM Global scorecard of top issues with Azure, data has been fictionalized to protect intellectual property Fix. The workflow creates Azure DevOps work items with the customer context, likely reproduction steps, recommended next actions, and an auditable trace of the supporting analysis. To date, 42% of the identified issues have been addressed through engineering action. The team is also extending an AI-assisted engineering workflow, using GitHub Copilot cloud agent, that can generate proposed fixes for straightforward issues. Engineers remain responsible for reviewing, refining, approving, and shipping any changes. The architecture is designed for inspection rather than blind automation. The recommendations include an auditable evidence trail allowing reviewers to inspect the source feedback, classifications, supporting references, confidence indicators, and recommendation actions. Human expertise enters the system at several points. Researchers shape the issue taxonomies and qualitative grounding. Product teams define ownership boundaries, business priorities, domain-specific vocabulary, and trusted sources that guide agent analysis. Engineers review and act on resulting work items, while leaders use scorecards to inform investment decisions. This context is captured in configuration files that evolve alongside the products they support. Teams can add new issue categories, refine keywords, clarify ownership boundaries, or identify trusted research sources. The next analysis cycle automatically incorporates the updated context without requiring changes to the underlying agents. That design creates a "feedback loop for the feedback loop". Teams review the root-cause analyses and work-item quality, identify gaps, and refine their configurations. This enables teams to continuously embed domain expertise into the workflow, improving how feedback is interpreted and prioritized without requiring changes to the underlying infrastructure. Their input improves subsequent runs, helping the system become more precise while preserving local product knowledge. The agent also maintains access to reports from previous runs and uses tools such as Web IQ and MCP servers to assess whether previously identified issues are improving, still require attention, or can be confidently closed. Fig 3. Example of the vertical feedback agent reasoning through customer feedback to find new work items One demonstrated example surfaced customer reports that a networking tool lacked IPv6 validation and support. The workflow generated an engineering work item describing the issue, customer impact, likely reproduction path, and recommended actions. The networking team reproduced the issue, validated the finding, and added it to its backlog. The goal is not to remove people from the process. Agents assume much of the cognitive load associated with sorting, clustering, tracing, and drafting, allowing experts to focus on judgment, prioritization, and implementation. Teams remain accountable for what is fixed, what is funded, and what is allowed to ship. The Impact: measurable experience gains at Microsoft production scale GEM began with manual interventions and is now scaling through AI-enabled workflows. The combined approach has produced measurable results across the Azure Portal and individual product experiences: The workflow aggregates and analyzes approximately 10,000 to 15,000 feedback reports each month across in-product, support, and social channels. Automated analysis reduced manual synthesis time by over 95 percent, turning a process that required 110 to 160 hours each month into a workflow that runs in under 60 minutes. Between October 2025 and April 2026, Azure Portal feedback rates declined by 30%. During that same period, GEM helped teams identify and prioritize experience improvements, creating a clearer link between customer feedback, engineering action, and outcome measurement. Service-level outcomes also demonstrate how better signals can drive business impact. For example, improvements to VM Connect experiences reduced overall Core Compute support volume by 1-2% per month, resulting in proportionate cost savings. The Azure Growth team increased subscription conversion by 9.1 percent after prioritizing issues highlighted through GEM. The value goes beyond speed. Leaders gain a more consistent basis for prioritization, and engineering teams receive work that is already connected to customer evidence and impact signals. Most importantly, every completed cycle creates new learning. Teams can measure changes in customer feedback and support volumes following improvements, incorporate partner input into future analyses, and continuously refine both the system and the products it helps improve. Key learnings and transferable practices The GEM experience offers several lessons for teams building agentic systems around complex, qualitative business processes: Start with real problems, not AI - Value comes from understanding the genuine business needs and applying AI where it is demonstrably better than existing approaches. Applying AI without a clearly defined problem often adds complexity without delivering meaningful value. Design for the end-to-end workflow - Value comes from connecting insights to the broader business process, including grounding in prior knowledge, prioritization, engineering action, post-fix measurement and reporting. Standalone AI output creates limited value, while an integrated workflow drives outcomes. Design for human judgment and accountability - Agents can reduce toil and cognitive load, but researchers, product managers, engineers, and leaders remain responsible for validating insights and determining appropriate actions. Ground agents in the knowledge of the teams they serve - Shared models require local context. Editable configuration files allow teams to define ownership, business priorities, releases, examples, and trusted sources without modifying underlying agents. Build observability and feedback mechanisms into the agentic system itself - Making analysis inspectable through reasoning traces, source context, and recommendations enables experts to identify gaps, improve outputs, and build trust over time. Build feedback mechanisms directly into the flow of work, making it effortless for users to provide input on the system. Tailor outputs to the people making decisions - Executives need trends and investment signals. Researchers need evidence and themes. Engineers need reproducible, actionable work. Effective systems deliver the right information to the right audience. Start small and iterate quickly - The AI landscape continues to evolve rapidly. Begin with a well-defined problem, measure outcomes, learn from feedback, and iterate as capabilities mature. Looking forward GEM continues to scale across the Azure Portal ecosystem. In addition to the global scorecard, vertical scorecards are now live with seven teams, expanding to the top 20 portal extensions representing more than 80% of portal traffic and feedback, with longer-term plans to extend coverage across the entire ecosystem. The roadmap includes expanded feedback ingestion, streamlined work-item tracking, AI-assisted remediation workflows, stronger evaluation, and a self-improving architecture. Proposed fixes would remain subject to engineer review, approval, and standard release controls before deployment. GEM is also developing AI-assisted pre-release governance workflows for production code that help identify potential quality issues during development. We will share more about these pre-release workflows in a future post. New tools and models will continue to evolve, but the enduring principle remains the same: combine enterprise-scale automation with clear ownership, trusted grounding, and human control. For Microsoft, Customer Zero means deploying these systems in real production environments, learning from the complexities, and sharing those lessons broadly. GEM shows what becomes possible when AI does more than summarize feedback. It helps an organization listen, act, measure outcomes, and continuously learn at customer scale. Microsoft's Customer Zero blog series gives an insider view of how Microsoft builds and operates Microsoft using our trusted, enterprise-grade agentic platform. Learn best practices from our engineering teams through real-world lessons, architectural patterns, and operational strategies for building, operating, and scaling AI-powered systems across the organization.471Views2likes0CommentsWiring Azure DevOps Pipeline Templates Without the Parameter Sprawl: The Manifest Facade Pattern
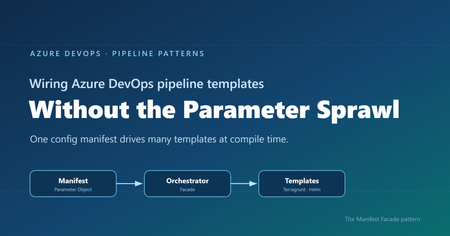
Where reusable pipelines start to hurt Who this is for: Platform and DevOps engineers who build shared Azure DevOps Pipeline Templates and want other teams to adopt them consistently. If you have ever built a set of shared Azure DevOps Pipeline Templates, you probably know how this goes. You write a whole library of clean, well-factored templates: provisioning infrastructure, deploying apps, scanning, promotion, and more. Each one is tidy on its own. Then the first team tries to actually use them together, and things get messy fast. That is exactly what happened to us on a customer engagement, while building a DevOps framework for their engineering teams. The templates themselves were fine. The trouble was wiring them together. Every consumer pipeline had to know how to call each template it used: the right order, which values one template fed another, and the full parameter list for every one of them. As the library grew, those consumer pipelines grew with it, long and repetitive. That friction turned into a real adoption problem. Getting started meant wading through pages of parameters, so teams put it off, copied whatever the team next door had, or quietly built their own thing instead. This post follows that story, from the tangle of parameters to the solution we landed on. Here is how it comes together. Where we started: Good templates, hard to adopt The DevOps framework we built had many templates. To keep this walkthrough concrete, we will follow just two of them: one that provisions infrastructure with Terragrunt (a wrapper around Terraform), and one that deploys an app to Kubernetes with Helm. Both are trimmed down to the essentials here so they are easy to follow. The infrastructure template, templates/infra/terragrunt-deploy.yml : parameters: - name: stack type: string - name: workingDir type: string steps: - script: | cd ${{ parameters.workingDir }} terragrunt plan -out=tfplan terragrunt apply -auto-approve tfplan displayName: "Deploy ${{ parameters.stack }}" The application template, templates/app/helm-deploy.yml : parameters: - name: releaseName type: string - name: chart type: string - name: namespace type: string - name: imageTag type: string steps: - script: | helm upgrade --install ${{ parameters.releaseName }} ${{ parameters.chart }} \ --namespace ${{ parameters.namespace }} \ --set image.tag=${{ parameters.imageTag }} displayName: "Deploy ${{ parameters.releaseName }}" There is nothing wrong with either file. The pain showed up in the pipeline that had to use them, where a team had to stitch the templates together by hand, remember the order, and repeat that boilerplate for every environment. Do that across a dozen services and you get long, copy-pasted pipelines that teams struggle to adopt. And because the wiring is done by hand, it leaves loopholes: a team can skip a step or override a parameter and slip past the guardrails you thought were in place. Challenge 1: Wiring the templates together The obvious move was to hide the wiring behind a single template that owned the order and the plumbing. We called it the orchestrator template: a consumer pipeline called that one template, and it wired up the rest. # templates/deployment-orchestrator.yml (the single orchestrator) parameters: - name: infraStack type: string - name: infraWorkingDir type: string - name: releaseName type: string - name: chart type: string - name: namespace type: string - name: imageTag type: string # ...and this list just kept growing stages: - stage: Infra jobs: - job: infra steps: - template: infra/terragrunt-deploy.yml parameters: stack: ${{ parameters.infraStack }} workingDir: ${{ parameters.infraWorkingDir }} - stage: App dependsOn: Infra jobs: - job: app steps: - template: app/helm-deploy.yml parameters: releaseName: ${{ parameters.releaseName }} chart: ${{ parameters.chart }} namespace: ${{ parameters.namespace }} imageTag: ${{ parameters.imageTag }} A team used it by calling that one template and passing a value for every parameter it exposed: # azure-pipelines.yml (a team's pipeline) parameters: - name: imageTag type: string extends: template: templates/deployment-orchestrator.yml parameters: infraStack: network infraWorkingDir: infra/network releaseName: orders-api chart: charts/orders-api namespace: orders imageTag: ${{ parameters.imageTag }} # ...and a value for every other parameter, too This solved the ordering and the copy-paste, but it handed us a new headache. This one template now had to expose every parameter of every template underneath it, and the list grew each time we added a capability. Worse, a real service usually needed more than one infrastructure stack and more than one Helm release. A flat list of parameters cannot express “two infrastructure stacks and three Helm releases” without silly names like infraStack1 , infraStack2 , and so on. Nobody could learn the thing. We had solved the wiring, only to trade it for a parameter problem. Challenge 2: The orchestrator’s parameter list explodes So how do you shrink that list? Step back and ask what you are really describing: a set of things to deploy. So the input should describe that set, not a long flat list of loose values. That is where the deployment manifest came in: one small config that lists the infrastructure to create and the apps to deploy. It reads about how you would expect: infrastructure: - stack: network workingDir: infra/network applications: - releaseName: orders-api chart: charts/orders-api namespace: orders Now the orchestrator can take that single manifest and loop over it, instead of exposing dozens of separate parameters. Its parameter list collapses to one, and a ${{ each }} loop turns each entry into a stage or job: # templates/deployment-orchestrator.yml (the orchestrator, now manifest-driven) parameters: - name: manifest type: object - name: imageTag type: string stages: - stage: Infra jobs: - ${{ each stack in parameters.manifest.infrastructure }}: - job: infra_${{ stack.stack }} steps: - template: infra/terragrunt-deploy.yml parameters: stack: ${{ stack.stack }} workingDir: ${{ stack.workingDir }} # ...an App stage loops over parameters.manifest.applications the same way And a consumer passes that manifest straight to the orchestrator: # azure-pipelines.yml (a team's pipeline) parameters: - name: imageTag type: string extends: template: templates/deployment-orchestrator.yml parameters: imageTag: ${{ parameters.imageTag }} manifest: infrastructure: - stack: network workingDir: infra/network applications: - releaseName: orders-api chart: charts/orders-api namespace: orders The parameter problem is solved. But hand-writing that whole manifest inside every pipeline is a lot to repeat, so the natural instinct is to pull it out into its own file. That is where things get tricky. Challenge 3: The manifest is read too late to shape the pipeline So we tried exactly that: we moved the manifest into a deployment-manifest.yml file and had the orchestrator read it back and expand it into stages and jobs. It sounded reasonable, but it did not work. To see why, you need to know how Azure DevOps builds a pipeline before it runs anything. An Azure DevOps pipeline actually happens in two phases, and they are further apart than people expect. First comes the build phase, before anything runs. Azure DevOps reads your YAML, pulls in every template, evaluates every ${{ }} expression, and unrolls every ${{ each }} loop. Out of this it produces one final, fully assembled pipeline. At this point no agent has started and no repo has been checked out. Only parameters and template expressions exist yet. Then comes the run phase. The assembled pipeline runs. An agent starts, checks out your code, and only now can a script open a file on disk. Here is the problem. Your deployment-manifest.yml does not exist as far as the pipeline is concerned until an agent checks out the repo, and that checkout happens during the run phase. So if the manifest is supposed to decide how many stages there are, or how many apps each get their own job, that decision has to be made earlier, while the pipeline is still being built. Important: The shape of the pipeline, its stages, jobs, and loops, is locked in while the pipeline is being built. A file you read during the run comes too late to change any of it. That was the wall we hit. The manifest was the right idea, but reading it from a file happened too late for the orchestrator to turn it into stages and jobs. So the manifest could not come from a file read during the run phase. It had to already exist, as an object, before the pipeline was assembled. The Manifest Facade pattern: Build the config while the pipeline is assembled The solution is to stop thinking of the manifest as a file to read, and start thinking of it as an object you build while the pipeline is being assembled. Parameters are available then. Template expressions can build a whole object then. So we added a small template, kept in the team’s own repo, with one job: take a couple of simple inputs, build the full manifest from them, and pass it to the shared orchestrator. We called it the builder, since assembling the manifest is its only job. It stays thin and lives next to the team’s pipeline, while the orchestrator stays in the shared platform repo. This is not a brand-new invention so much as a few familiar ideas working together, applied at pipeline build time. The manifest is a Parameter Object (Martin Fowler’s refactoring for collapsing a long parameter list into one structured value). The orchestrator is a Facade (the Gang of Four pattern for putting one simple, unified interface over a subsystem, here the underlying leaf templates). And the small template in the team’s repo is the piece that assembles that Parameter Object from a couple of inputs. What makes it an Azure DevOps pattern is the timing: the manifest is built as an object while the pipeline is assembled, so it can drive template expansion instead of sitting in a file that only gets read during the run. That is the twist we did not see written down anywhere, so we gave it a name: the Manifest Facade pattern. In practice it comes together in three small pieces: the consumer pipeline references the builder, the builder assembles the manifest and hands it to the shared orchestrator, and the orchestrator expands that manifest into stages and jobs. Here is how the files extend into one another: Here is each piece in turn. Step 1: The consumer references the builder The consumer pipeline extends the builder that lives in its own repo. It also declares the shared platform repo as a resource, so the orchestrator the builder calls is available while the pipeline is built. # azure-pipelines.yml (the team's pipeline) parameters: - name: imageTag displayName: Image tag type: string resources: repositories: - repository: platform type: git name: platform/pipeline-templates ref: refs/tags/v1.0.0 trigger: - main extends: template: config/deployment.yml@self parameters: environment: dev service: orders imageTag: ${{ parameters.imageTag }} Because the image tag is a runtime parameter, it is declared here in the consumer pipeline, which is what makes it appear in the Run pipeline panel for someone to fill in. Beyond that, the team passes only an environment and a service name, and the builder works out the rest. Step 2: The builder assembles the manifest The builder takes those inputs and assembles the whole manifest from them, then hands it to the orchestrator. Every structural value here is a parameter or a template expression, so all of it is ready while the pipeline is being assembled. # config/deployment.yml (builder, in the team's repo) parameters: - name: environment type: string - name: service type: string - name: imageTag type: string extends: template: deployment-orchestrator.yml@platform parameters: imageTag: ${{ parameters.imageTag }} manifest: schemaVersion: v1 infrastructure: - stack: network workingDir: infra/${{ parameters.environment }}/network applications: - releaseName: ${{ parameters.service }} chart: charts/${{ parameters.service }} namespace: ${{ parameters.service }} The builder assembles the manifest inline from the environment and service, then passes it straight to the orchestrator. The image tag is different: it is a runtime parameter the user supplies at queue time, so it is passed through to the orchestrator template and never becomes part of the manifest. The team gets a tiny interface, and the orchestrator still gets the full structure it needs. Step 3: The orchestrator turns the config into stages and jobs The orchestrator takes a single object and loops over it with ${{ each }} . Each stage and job gets generated while the pipeline is assembled. # deployment-orchestrator.yml (shared platform repo) parameters: - name: manifest type: object - name: imageTag type: string stages: # a ValidateManifest stage runs first (covered in the next section) - stage: Infra jobs: - ${{ each stack in parameters.manifest.infrastructure }}: - job: infra_${{ stack.stack }} steps: - template: infra/terragrunt-deploy.yml parameters: stack: ${{ stack.stack }} workingDir: ${{ stack.workingDir }} - stage: App dependsOn: Infra jobs: - ${{ each app in parameters.manifest.applications }}: - job: app_${{ app.releaseName }} steps: - template: app/helm-deploy.yml parameters: releaseName: ${{ app.releaseName }} chart: ${{ app.chart }} namespace: ${{ app.namespace }} imageTag: ${{ parameters.imageTag }} Because the manifest is a real object by the time the loops run, ${{ each }} unrolls it into actual jobs. List two stacks and you get two jobs. List two apps and you get two deploy jobs. And because the team only describes what to deploy, the sensitive wiring like service connections stays inside the platform templates, out of reach. The loophole is gone because the parameter is gone. Why the order of things matters The whole pattern comes down to who does what, and when. The builder turns a simple intent (“deploy orders to dev”) into a full manifest, while the pipeline is being assembled. The orchestrator turns that manifest into real stages and jobs, still while the pipeline is being assembled. Only the leaf templates do the real deployment work during the run: checkout, terragrunt apply , helm upgrade . Nothing about the shape of the pipeline waits for the run, so nothing about it depends on a file that only shows up after checkout. That is the whole trick. If you do have values you genuinely cannot know until the run, like a secret fetched from a vault or an artifact version an earlier stage writes to a variable, those still belong in runtime variables and variable groups. The manifest is for the structure and config you already know when you queue the build, which is almost always the part that was causing the pain. Validating the manifest against a schema Once the manifest became the one interface every team fills in, it needed a contract. We wrote that contract as a JSON Schema and kept it in the shared platform repo under schema/v1/ . The folder name is the version: backward-compatible additions go straight into v1 , and the day we need a breaking change we add a schema/v2/ alongside it, so existing consumers keep working while the schema evolves. Each manifest carries a schemaVersion so the orchestrator knows which contract to hold it to. On top of that, we validate in three layers, each catching a different class of mistake. Layer 1 is build time, for free. Because the orchestrator’s parameters are typed, with manifest declared as an object , Azure DevOps catches a range of structural problems while it expands the templates, before anything runs. For example, if a manifest left out infrastructure or misspelled it, the orchestrator’s ${{ each stack in parameters.manifest.infrastructure }} loop would have nothing valid to iterate over, and the failure would surface during template expansion rather than halfway through a deployment. Layer 2 is a version check that runs at build time. Both the ${{ if }} and parameters.manifest.schemaVersion are resolved while the pipeline is being assembled, so the orchestrator decides right then whether it understands the manifest’s version. If it does not, the only thing it generates is a single failing stage, and the real deployment stages are never built, so nothing runs against a contract the orchestrator does not know: # deployment-orchestrator.yml (shared platform repo) parameters: - name: manifest type: object stages: # Layer 2: reject schema versions this orchestrator does not understand - ${{ if not(containsValue(split('v1', ','), parameters.manifest.schemaVersion)) }}: - stage: UnsupportedSchemaVersion jobs: - job: fail steps: - script: | echo "##vso[task.logissue type=error]Unsupported manifest schemaVersion '${{ parameters.manifest.schemaVersion }}'" exit 1 # the ValidateManifest, Infra, and App stages below are generated only when the version is supported Layer 3 is a run-time check against the full schema. The first stage the orchestrator generates is ValidateManifest . Because the schema lives in the platform repo, the job checks that repo out first. Then it serializes the manifest object to JSON with the convertToJson expression, writes that JSON out to a file, and runs a JSON Schema checker to compare the file against the schema. If the manifest breaks the contract, the pipeline stops here, before any infrastructure or app stage runs: # Layer 3: validate the real manifest object against the JSON Schema - stage: ValidateManifest jobs: - job: validate steps: # the schema lives in the platform repo, so check it out first - checkout: platform - script: | echo '${{ convertToJson(parameters.manifest) }}' > manifest.json pip install check-jsonschema check-jsonschema --schemafile schema/${{ parameters.manifest.schemaVersion }}/deployment.schema.json manifest.json displayName: "Validate manifest against schema" Layer 1 is automatic, Layer 2 rejects an unknown contract at build time so the deployment stages are never generated, and Layer 3 confirms the actual values match the schema before any real work begins. Together they turn “the manifest looked right” into “the manifest is provably valid.” A few trade-offs to keep in mind No pattern comes without trade-offs. A few things worth weighing: The manifest has to be something template expressions can build. You can compose objects, loop, and branch with ${{ if }} , but there is no running arbitrary code while the pipeline is assembled. Anything fancier may need a prep step or a file generated upstream. Every team carries a small builder template. We think that is a fair trade, since it keeps their intent local and readable, but it is one more file per repo. Keep it thin and let the orchestrator hold the real logic. Treat the schema as living documentation. Because the manifest’s JSON Schema spells out every field and what it means, teams can read it to build their own manifest with confidence, instead of reverse-engineering the orchestrator. Pin the shared repo to a tag, like the v1.0.0 above, so a change to the orchestrator does not silently change everyone’s pipeline on the next run. Debugging takes a small shift in habit. When something looks off, use the pipeline’s preview to see the fully assembled YAML before it runs. It shows you exactly what the loops produced. Tip: Use the Azure DevOps pipeline preview to see the fully assembled YAML without running anything. It is the fastest way to confirm your manifest unrolled into the stages and jobs you expected. Wrapping up It is a journey a lot of platform teams will recognize. Clean templates, messy wiring, one orchestrator that fixes the order but drowns in parameters, a config file that brings back sanity, and then the surprise that reading it at the wrong moment means it can never shape the pipeline. The solution is small and it sticks. Put a thin builder template next to each team, let it assemble the manifest from a couple of simple inputs, and let a shared orchestrator turn that manifest into stages and jobs. Teams get an interface they can easily understand and adopt. The platform team keeps the wiring and the guardrails in one place. And the timing gap that trips up so many “just read the config file” attempts stops being a problem, because you are working with it instead of against it. Key takeaways Shared Pipeline Templates stall on adoption when every team has to wire them together by hand. A single orchestrator template fixes the ordering, but a flat parameter list does not scale to real adoption. A config file read during the pipeline run cannot shape the pipeline, because stages and jobs are decided earlier, while the pipeline is assembled. The Manifest Facade pattern builds the config as an object at assembly time, so one small input drives many templates, consistently and with the guardrails baked in. Give the manifest a versioned JSON Schema and validate it in layers, so a broken contract fails fast instead of halfway through a deployment. How are you handling template sprawl in your own pipelines? We would love to hear what has worked for your teams in the comments.277Views1like0Comments
How Microsoft 365 built a platform engineering layer on AKS to ship faster at global scale
This Customer Zero story explains how Microsoft 365 built COSMIC, a platform engineering layer on top of Azure Kubernetes Service (AKS), to standardize how cloud services are deployed and operated at global scale. The goal was to eliminate repetitive infrastructure work for service teams, embed security and compliance by default, and enable developers to focus on delivering customer value instead of managing platform complexity.4.6KViews4likes0Comments
Find anomalies in Prometheus and OpenTelemetry metrics with Dynamic Thresholds (Preview)
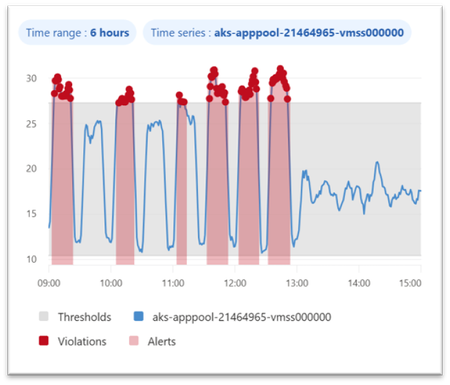
Dynamic thresholds are extended to query-based metric alerts in Azure Monitor, allowing to detect and alert on anomalies in Azure Monitor managed Prometheus metrics and OpenTelemetry metrics stored in an Azure Monitor Workspace. This follows the introduction of Dynamic Thresholds for Log search alerts — Azure Monitor now offers consistent Dynamic Thresholds support across logs and metrics — platform metrics, log search queries, and now query-based metric alerts. A consistent anomaly-detection approach, wherever your signals live. Dynamic thresholds are not a single static formula. They apply a range of machine-learning models and algorithms to historical query results, learn each series’ normal rhythm — including hourly, daily, and weekly seasonality — and automatically fit the most appropriate baseline separately to every time series. This way, a single alert rule can monitor many resources or dimensions while each one gets its own independent, self-refining baseline. Why Dynamic Thresholds Matter Simpler configuration: Reduce the need to define, maintain, and continuously tune static thresholds inside PromQL alert logic. Adaptive monitoring: Let alert thresholds adjust to changing workload behavior, recurring traffic peaks, and seasonal usage patterns. At-scale intelligence: Monitor multiple time series with a single alert rule, while Azure Monitor learns an independent baseline for each resource or dimension combination. Example 1 — Spot CPU anomalies in AKS workloads Scenario: Monitor container CPU utilization across pods or deployments in AKS with a query-based metric alert built on Prometheus metrics. Example query: sum by (microsoft_resource_id, namespace, deployment, container) (rate(container_cpu_usage_seconds_total[5m])) / sum by (microsoft_resource_id, namespace, deployment, container) (container_spec_cpu_quota / container_spec_cpu_period) Why dynamic thresholds help: CPU usage of a Kubernetes workload changes with workload mix, deployment timing, scaling activity, and traffic patterns. Static thresholds can be difficult to tune across namespaces, deployments, and containers. Dynamic thresholds learn a separate baseline for each monitored time series — in this example, for every pod, deployment, and container combination — so genuine CPU spikes stand out while expected variation from autoscaling and traffic mix stays quiet. Example 2 — Catch application latency regressions sooner Scenario: Detect abnormal latency patterns in an application by alerting on custom OpenTelemetry metrics stored in an Azure Monitor Workspace. Example query: histogram_quantile(0.95, sum by (le, service_name, http_route, http_method) (rate(http_server_duration_seconds_bucket[5m]))) Why dynamic thresholds help: Application latency naturally changes with traffic, user behavior, and release cadence. Fixed thresholds can be noisy during peak periods and too loose during quiet ones. Dynamic thresholds learn a separate baseline for each time series — here, for every service, route, and method — so real p95 latency regressions surface even as traffic and release cadence shift throughout the day. Best practices for better results To get the best results from dynamic thresholds for PromQL-based alerts, design your query so Azure Monitor can learn a clear, stable signal over time: Keep the expression numeric. Dynamic thresholds work best when the query returns a continuous numeric signal rather than a Boolean true/false result. For example, use an expression that calculates CPU usage, not a Boolean comparison like CPU > 0.8. Use meaningful dimensions. Split by dimensions such as namespace, deployment, service, or route when you want separate baselines for different workloads or endpoints. Prefer stable entities. Use longer-lived dimensions or aggregate across short-lived entities so the model has enough consistent history to learn from. In Kubernetes, for example, deployment is usually a better baseline dimension than individual pod ID. Choose the right threshold behavior. Decide whether the alert should trigger on values above the learned upper bound, below the lower bound, or both. Start with medium sensitivity. Use Medium as a balanced default, then tune up or down based on noise and missed anomalies. Allow enough historical data. Dynamic thresholds improve as more history is collected. Initial seasonal patterns use recent history, and weekly seasonality becomes more effective after several weeks of data. Get started Ready to try it? Create a query-based metric alert with dynamic thresholds on your metrics in Azure Monitor Workspace. You can create such rules in the Azure portal, where the built-in preview chart shows when your dynamic threshold alert would have fired based on historical baseline analysis. Use the preview chart to tune both the PromQL query and the dynamic threshold sensitivity before enabling the rule. You can also create query-based metric alert rules using programmatic interfaces or resource templates. Figure 1. Dynamic thresholds preview chart showing the learned baseline and the points where an alert would have fired. Dynamic thresholds cut alert noise where it starts — at detection. The alerts that do fire connect into Azure Monitor’s broader AIOps experience, where the Azure Copilot Observability Agent can help correlate signals into investigated issues with explainable reasoning — with humans in control. Next steps Related blog: Anomaly detection made easy with Dynamic thresholds for Log search alerts Dynamic thresholds in Azure Monitor Query-based metric alerts overview Create query-based metric alerts Prometheus metrics in Azure Monitor OpenTelemetry on Azure Monitor Stay connected Follow the Azure Observability Blog for more updates on Azure Monitor, Prometheus-based monitoring, alerting, and troubleshooting experiences. We’ll continue sharing product updates, practical guidance, and examples to help you improve observability across your Azure environments. Feedback We’d love to hear how dynamic thresholds for query-based metric alerts work for your scenarios. Share your feedback through your Microsoft account team, Azure support channels, or the feedback options in the Azure portal so we can continue improving the experience.212Views0likes0CommentsIPv6 Dual-Stack Endpoints for Azure Container Registry (Public Preview)
By Johnson Shi, Aviral Takkar, Bin Du Introduction Two of the most common networking questions we hear from teams running Azure Container Registry (ACR) are: "Can my registry serve clients on IPv6 networks?" — Teams operating IPv6-only or dual-stack networks need their container registry reachable over IPv6. "How do we start moving registry traffic toward IPv6 without breaking anything?" — Organizations guarding against IPv4 address exhaustion, or operating under IPv6 transition mandates, want a migration path that doesn't disrupt existing IPv4 clients. Today, we're announcing the public preview of IPv6 dual-stack endpoints for Azure Container Registry for public endpoints and firewall rules, with IPv6 over private endpoints planned for GA. Set your registry's endpoint protocol to IPv4AndIPv6 , and its endpoints become reachable over both IPv4 and IPv6 — so IPv4-only, dual-stack, and IPv6-capable clients all connect to the same registry, each over whichever protocol their network stack selects. Key Takeaways ACR registries now support an endpointProtocol setting with two values: IPv4 (default) and IPv4AndIPv6 (dual stack, preview). Dual stack is additive — your registry continues serving IPv4 clients exactly as before. There is no IPv6-only mode. Dual stack requires dedicated data endpoints to be enabled ( --data-endpoint-enabled true ), and dedicated data endpoints require the Premium SKU. The service enforces this requirement. You can enable it today with Azure CLI 2.87.0 via az acr update --endpoint-protocol IPv4AndIPv6 . FQDN-based client firewall rules keep working unchanged; IP-based allowlists need to account for IPv6 traffic. Limitation: This public preview covers IPv6 for the registry's public endpoints and firewall rules only. IPv6 over private endpoints is planned for a future release. Limitation: ACR Tasks isn't supported on a registry that has IPv6 dual-stack enabled. Tasks does not work when the endpoint protocol isIPv6 dual-stack, including quick builds (with az acr build) and quick task runs (with az acr run). Support is planned for a future release. How to enable it On an existing registry (Azure CLI 2.87.0 or later) Dual stack requires dedicated data endpoints, so enable both in a single update: az acr update --name <your-registry> --data-endpoint-enabled true --endpoint-protocol IPv4AndIPv6 If dedicated data endpoints are already enabled, set the endpoint protocol on its own: az acr update --name <your-registry> --endpoint-protocol IPv4AndIPv6 Verify the configuration: az acr show --name <your-registry> --query "{endpointProtocol:endpointProtocol, dataEndpointEnabled:dataEndpointEnabled}" { "dataEndpointEnabled": true, "endpointProtocol": "IPv4AndIPv6" } Note: If your clients sit behind a firewall and you're enabling dedicated data endpoints for the first time, add firewall rules for <your-registry>.<region>.data.azurecr.io before enabling — switching from *.blob.core.windows.net to dedicated data endpoints changes where layer blobs are downloaded from. See Dedicated data endpoints for details. Reverting to IPv4 Dual stack is reversible at any time: az acr update --name <your-registry> --endpoint-protocol IPv4 Reverting the endpoint protocol leaves dedicated data endpoints enabled; disable them separately if desired. Scope of this preview This public preview enables IPv6 for the registry's public endpoints — the login server, dedicated data endpoints, and regional endpoints (if enabled). IPv6 over private endpoints isn't part of this preview. Support is planned for a future release. Until then, registries reached through a private endpoint continue to use IPv4. Additionally, IPv6 dual-stack support for ACR Tasks, including support for `az acr build` and `az acr run`, are not supported in the public preview. Support is planned for a future release. Requirements and how features compose Requirement Why Premium SKU Dedicated data endpoints are a Premium feature. Dedicated data endpoints enabled IPv4AndIPv6 requires dataEndpointEnabled: true ; the service rejects the setting otherwise. Azure CLI 2.87.0+ Adds --endpoint-protocol to az acr update . For geo-replicated registries, the endpoint protocol is a registry-level setting, and dedicated data endpoints exist in every replica region. Firewall guidance: rules based on registry FQDNs — the login server, dedicated data endpoints, and regional endpoints (if enabled) — continue to work unchanged for dual-stack registries; only IP-address-based allowlists need updating for IPv6. To learn more, see IPv6 dual-stack endpoints in Azure Container Registry (preview) and the ACR endpoint reference. If you have further questions about IPv6 dual-stack endpoints or dedicated data endpoints, reach out to us on the Azure Container Registry GitHub repository or file feedback through the Azure portal.271Views1like0Comments
Azure Copilot Observability Agent is generally available, with autonomous operations in preview
Complex cloud environments have outpaced manual operations. Agentic cloud operations connect people, tools, and data to streamline investigation workflows and move teams from scattered signals to evidence-backed next steps. With unified observability, teams can investigate Azure-monitored applications, Azure Kubernetes Service (AKS) environments, VMs, Foundry telemetry, infrastructure, and platform signals with greater context and control. Powered by Azure Monitor, the Azure Copilot Observability Agent is now generally available. It helps engineering, SRE, DevOps, and operations teams move from telemetry and alert noise to investigated issues, explainable reasoning, and recommended next steps that can reduce Time-To-Mitigate (TTM). Autonomous operations are also available in public preview. They help prepare context and reduce triage work while people remain responsible for mitigation decisions and any changes to the environment. From alert noise to investigated issues The Observability Agent helps teams reduce the effort required to understand operational problems. Instead of starting every investigation from a dashboard, query editor, or alert payload, teams can work with an AI companion that reasons across telemetry, Azure resource context, discovered topology, and custom instructions to identify what changed, what is correlated, and what evidence supports the conclusion. Teams can start with natural-language exploration and continue into deeper investigations when an issue requires more evidence. That light-to-deep workflow helps responders move from broad questions to a structured investigation without losing the reasoning trail. Here's what this looks like in practice: after a deployment, several alerts might fire across an app, database dependency, and compute resource. The Observability Agent can group those signals around the affected service, identify when the regression started, compare related dependencies and infrastructure metrics, and capture the findings in an Azure Monitor issue. The responder can then validate the evidence, add team context, route work to the right owner, and decide whether a rollback, configuration change, or code fix is appropriate. Explainable investigations across Azure-monitored signals Operations teams need more than a chatbot that answers questions. The Observability Agent follows an investigation workflow: it frames hypotheses, gathers evidence, compares signals by time, scope, and type, rules out weak explanations, and shows the reasoning path behind its findings. The Observability Agent can help teams: Investigate incidents and alerts across Azure-monitored applications, Azure Kubernetes Service (AKS) environments, VMs, Foundry telemetry, infrastructure, and platform signals Correlate related signals to reduce noise and surface higher-signal issues with context Explore telemetry using natural language while preserving transparency into the supporting data Compare signals by time, scope, and type to separate likely causes from coincidental changes Provide a reasoning trail that shows what the agent found, what it ruled out, and why Recommend next steps that engineers can review before deciding how to act This same investigation model applies to specialized skills and issue types, including customer's application, Azure Kubernetes Service (AKS), Foundry, VMs, and GenAI issues. When the relevant telemetry is available, the Observability Agent can correlate logs, metrics, traces, alerts, dependencies, resource graph, resource health, activity logs, Foundry telemetry, and changes. This helps teams investigate customer-visible issues with evidence, including latency, token spikes, tool-call failures, agent errors, hallucinations, deployments, API failures, performance regressions, infrastructure dependencies, and platform incidents. This explainability is central to the product. In production operations, trust is earned through evidence. The Observability agent is built to support human judgment, not bypass it. . Azure expertise, with context from your environment Context matters in every investigation. The same symptom can mean different things depending on application architecture, recent deployments, dependencies, historical incidents, and team practices. The Observability Agent brings Microsoft and Azure operational knowledge into the investigation experience. It can use discovered topology, Azure resource context, logs, metrics, traces, and custom instructions to ground investigations in signals that are more relevant to your environment. Native to Azure Monitor, with humans in control Because the Observability Agent is built into Azure Monitor, teams can use it close to the telemetry, alerts, and workflows they already rely on. Investigations can also be captured as Azure Monitor issues, creating a shared case file for humans and agents to collaborate on evidence, reasoning, and next steps. The Observability Agent is designed for governed AI operations inside Azure Monitor. Interactive chat and investigations use the signed-in user's identity and Azure role-based access control (RBAC). Prompts and responses are not used to train foundation models, and the agent doesn't restart resources, change configuration, or resolve issues on its own. Autonomous operations in public preview Alongside general availability, autonomous operations for the Observability Agent are available in public preview. When enabled, the agent can analyze alerts in the background, correlate related alerts when they likely represent the same incident, create Azure Monitor issues automatically, and run deep investigations on agent-created issues. This automatic triage helps reduce alert noise by turning streams of individual alerts into higher-signal issues with context, findings, and recommended next steps. Teams can review the issue, continue the investigation, and decide what action to take. Autonomous operations are designed to prepare context and reduce triage work, not to remove human control. Engineers remain responsible for decisions, approvals, and any changes to the environment. Next steps Check out our latest announcements and related blogs: Azure Blog and OMB Blog. Learn how to use the Observability Agent in Azure Copilot Observability Agent. Explore how investigations work in Deep investigations in the Azure Copilot Observability Agent. Learn more on how to Chat with your observability data Learn how teams preserve context in Azure Monitor issues. Review preview details in Autonomous operations in the Azure Copilot Observability Agent. Stay connected Follow this blog for ongoing deep dives, updates on current capabilities, and a preview of what's coming next. Live webinar - a walkthrough of real Observability Agent scenarios, best practices, and what's available today - along with a look at what's coming next, and live Q&A with the product team. Register for the Observability Agent webinar. We'd love your feedback The Observability agent continues to evolve based on real-world usage and operator feedback. Share your thoughts directly through the Give Feedback option in the experience, or reach us at enauerman@microsoft.com.10KViews6likes0CommentsHow Many Copies of Each Layer Does Your Container Registry Actually Need?
Authors: Payal Mahesh and Vicky Lin Azure Container Registry team: Jeanine Burke and Johnson Shi Introduction It's Monday morning. You spin up a fresh 1,000-node AKS cluster for a big training run or a fleet-wide rollout. Every node reaches for the same large container image at the same instant. What actually happens in the next ten minutes - and whether your pods reach Ready in 9 minutes or 14 - turns out to depend on a single number you've probably never thought about: how many copies of each image layer exist behind your registry. At the surface, you see a single capacity number for your registry size - but behind that abstraction, Azure Container Registry maintains copies of your layer data to optimize pull performance. That number of copies directly determines the read throughput available per layer. Each copy can serve requests independently, so distributing the layer across storage allows it to be read in parallel. More copies mean more independent readers - and higher aggregate throughput when thousands of nodes pull at once. The intuitive answer is that more is better: add copies, get faster pulls. When we actually tested it at 1,000-node scale, the truth turned out to be more interesting: A few extra copies helped a little. A moderate number helped a lot, and eliminated storage throttling entirely. A large number helped no more than the moderate one. A huge number actually made pulls slower again. Think of it like opening checkout lanes at a grocery store. Opening a few more lanes when the store is slammed cuts the line dramatically. Past a certain point, though, extra lanes barely help, because by then it's the customers, not the cashiers, who are the bottleneck. And open too many? Now the staff is spread thin and tripping over each other, and the line moves worse than it did at the sweet spot. This post walks through what we measured, why the curve bends where it does, and what we're building next so finding that sweet spot isn't something anyone has to do by hand. Key Takeaways There's a sweet spot, not a slope. Adding copies per layer cut pod-startup P99 by 27% and raised P50 per-node egress throughput by 244%, but only up to a point. Past that, the returns vanish, and far past it, latency actually regresses. Storage throttling is the real enemy. The win comes from spreading load across enough storage backends that no single backend gets pinned at its egress ceiling. Once throttling is gone, more copies stop helping. Storage scale alone has a ceiling. Even at the sweet spot, the per-backend egress limit caps total throughput. The next jump in performance has to come from somewhere else, which is exactly what we're building (see What's Next). This isn't something customers should need to manage. We're building a proactive, on-demand storage scaling capability that automatically grows the footprint before throttling happens and shrinks it back when the burst is over. A quick bit of background Within a region, the layer data behind your container images is backed by Azure storage. The number of copies ACR maintains per layer determines how many independent storage backends a concurrent-pull workload can spread its reads across. That's what matters, because each backend has a finite egress ceiling. Once concurrent reads against one backend get close to that ceiling, requests start getting throttled, and your pulls slow down in proportion. The principle is simple: more copies per layer means more backends serving the same data, which means more total egress headroom and fewer throttled requests. What we wanted data on was how many, and where it stops helping. How we tested We ran a controlled series of large-scale pull tests against ACR Premium on a roughly 1,000-node cluster, with every node pulling the same large image cold at the same time (no local cache on any node). The only thing we changed between runs was the number of per-layer copies behind a single registry endpoint. Everything else, including rate limits, the image, node count, and concurrency, stayed constant. For each run we measured pod-startup latency (P50/P90/P99), end-to-end storage read latency, egress throughput distributions (P50-P99.9), and storage throttling events. Pod-startup latency is our headline metric, because it's the one number that reflects the actual customer experience no matter where the bottleneck happens to be. Per-node egress throughput matters too, though. It tells you directly how much pull bandwidth ACR delivers to your fleet, and it's usually what customers have in mind when they ask how much faster extra copies will make their pulls. We report egress as a distribution rather than a single average, since per-request and per-time-window views can tell very different stories about the same set of pulls. These are observations from a single controlled environment, not a service guarantee. Absolute numbers will move with image size, node count, layer composition, network topology, and concurrency. What we found We tested five configurations, sweeping from a low baseline number of per-layer copies up to a very high one. We name them by relative copy count rather than exact instance counts: Baseline: the lowest level, our reference point. Low: a modest step up from Baseline. Mid: a meaningful step up from Low. Higher: a further step up from Mid. Very high: the largest configuration we tested, well above Higher. Here are the numbers. All percent changes are relative to Baseline. Configuration Pod startup P50 Pod startup P90 Pod startup P99 Storage throttling events Peak per-backend egress Baseline (fewest copies) 9m 36s 11m 0s 14m 16s Many; all top backends above the egress ceiling Highest Low 9m 27s (−2%) 10m 14s (−7%) 12m 59s (−9%) Some; one backend still above the ceiling High Mid 9m 25s (−2%) 9m 45s (−11%) 10m 22s (−27%) Zero Below the ceiling Higher 9m 20s (−3%) 9m 37s (−13%) 10m 22s (−27%) Zero Well below the ceiling Very high 9m 28s (−1%) 10m 31s (−4%) 13m 48s (−3%) Zero Lowest Look at the P99 pod-startup column from top to bottom: 14m 16s, 12m 59s, 10m 22s, 10m 22s, 13m 48s. It improves, flattens out, then climbs back up. Three things explain that shape: 1. The win: Throttling falls off a cliff at the Mid configuration As we added copies per layer, per-backend egress fell and storage-side throttling decreased. At the Mid configuration, throttling errors hit zero, and they stayed at zero for every configuration above it. The upside isn't just that the errors went away, though. It's raw pull bandwidth. At the Mid sweet spot, the typical node saw its P50 egress throughput jump 244% over Baseline. With load spread across enough copies, each node pulled its layers off storage much faster, not just without stalling. For a workload owner, that's the difference between watching pods come up in a steady stream and watching them stall for tens of seconds at a time while throttling clears. Same image, same node count, same registry, very different experience. To put it in concrete terms: if your team runs a daily AI training kickoff that needs all 1,000 nodes pulling before the job can start, this is the difference between starting on time and starting four minutes late every day. Over a quarter of training runs, that adds up. 2. The surprise: more copies made pulls slower This is the finding that genuinely surprised us. Going from Higher to Very high, the largest configuration we tested, cost us 3 minutes and 26 seconds at P99: 10m 22s climbing back up to 13m 48s. That gave back almost the entire benefit we'd built up over the previous four configurations. Tail storage-read latency at Very high actually came out worse than Baseline. The Very high run is where the wheels came off, and the reason is the trade-off underneath. Once storage throttling is gone, more copies stop buying you anything, and the cost of fanning reads across that many backends starts to take over. The throughput distribution shows it clearly. P50 and P75 throughput had been climbing steadily and getting smoother through Mid and Higher, then dropped sharply at Very high while the peak P99/P99.9 spikes came back. Spread the same load across too many backends and it fragments into smaller, less consistent bursts. The takeaway is that "more is better" stops being true past the sweet spot, and the failure mode is quiet. You won't see throttling errors. You'll just see your pulls get slower. 3. What we didn't expect: at few copies, the hottest backend is what hurts you At the lowest copy counts, pull traffic wasn't spread evenly across the underlying storage footprint. Some backends absorbed far more traffic than others. As we added copies, that distribution evened out and the hottest backends cooled down. The implication is sharp. You can saturate the busiest backend, and trigger throttling, even when the total headroom across all your backends is large in aggregate. What matters is the load on the hottest backend, not the average. That's exactly the failure mode that demand-driven, proactive scaling (described below) is meant to head off before it happens. So how should you think about this? You don't size copies yourself; ACR manages the storage footprint behind your registry. Still, it helps to understand what moves the sweet spot, because the shape of your own workload is what decides where it lands. The bigger your worst-case concurrent burst (more nodes, larger images, higher concurrency), the more copies per layer it takes to keep pulls off the throttling ceiling, and the further out the sweet spot sits. Smaller workloads may already be sitting on the flat part of the curve. One thing is worth saying plainly. The storage footprint underneath is managed by ACR and shared across many registries, so there's no fixed, private storage budget that maps one-to-one to your workload. The sweet spot isn't a number you compute and provision; it's a behavior the platform has to land on for you, which is exactly why we're moving toward demand-driven scaling that handles it automatically. That's what brings us to what we're building next. What's next: proactive, on-demand storage scaling and a caching layer The fixed-copy tests above answer the question "how many should the ACR system provision?" but they assume a single, static answer. Real workloads aren't static. A 1,000-node burst happens at deploy time, not at 3 a.m. on a Tuesday. And no matter how many copies are provisioned, the per-backend storage ceiling still bounds peak deliverable throughput. So we're investing along two complementary directions. 1. Proactive, demand-driven storage scaling We're building a capability that adjusts the number of per-layer copies automatically based on real-time pull demand: Proactive, not reactive. The system scales the storage footprint before concurrent pull pressure pushes any single backend near the throttling threshold, so throttling is prevented before it forms rather than cleaned up after the fact. On-demand scale-out. The footprint expands automatically as sustained pull demand grows. Scale-in when demand subsides. The footprint contracts so you're not paying for steady-state capacity you only needed during a burst. Tiering for cold content. Long-tail, rarely-pulled content can sit on colder storage, so the redundant footprint of frequently-pulled content doesn't pay full hot-storage cost everywhere. The benefit to customers is straightforward: smoother pulls under burst, higher delivered throughput on average, no permanent over-provisioning, and no manual re-tuning as workloads grow. 2. A caching layer to absorb burst beyond the storage ceiling Even a perfectly scaled storage footprint runs into the per-backend egress ceiling at extreme scale. To push past it, we're investing in a caching layer in the registry service that absorbs burst traffic before it ever reaches storage. A pull surge that hits the same set of layers, which is the common case for fleet-wide deployments, can be served largely from cache. That takes a lot of load off any single storage backend and complements the storage scaling above. We'll share results from this work in follow-up posts. If you have questions about scaling ACR for your workload, or about how we measure storage performance, reach out on the Azure Container Registry GitHub repository. Note: All results in this post are based on controlled internal testing configurations and are intended to illustrate general scaling behavior rather than prescribe exact configurations.307Views0likes0CommentsAccelerating AKS troubleshooting with the Azure Copilot Observability Agent
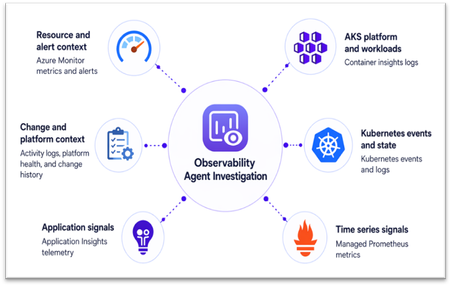
AKS incidents rarely stay within one Kubernetes object, signal, or tool. A latency spike might first appear in application telemetry, but the root cause may sit elsewhere: pod restarts, node pressure, scheduling failures, or a recent configuration change. The Azure Copilot Observability Agent in Azure Monitor helps connect these signals into an explainable investigation, so teams can move from symptoms to evidence-backed next steps. Why AKS troubleshooting is complex Troubleshooting Azure Kubernetes Service (AKS) is complex because failures can originate in workloads, platform components, infrastructure, or the application code running on the cluster. For example, pods stuck in Pending may indicate capacity or scheduling issues, while application latency may be caused by throttling, failed probes, pod restarts, or node pressure below the app. During an incident, simply having more telemetry is not enough. Teams need a way to test likely causes, rule out unrelated signals, and keep the investigation tied to the affected workload and time window. From signal to root cause: the investigation flow The Observability Agent follows a consistent investigation pipeline: Scope the problem by identifying the most likely infrastructure resources involved, plus connected dependencies. Collect data across metrics, logs, traces, change history, and related signals. Detect anomalies using learned baselines (for metrics) and log analysis. Correlate across resources spanning infrastructure and application layers. Run deep diagnostics by invoking resource-specific tools when needed to pinpoint root cause. Summarize findings in a structured format: what happened, why it happened, and what to do next. AKS investigation data sources The agent works with telemetry already available in your Azure Monitor environment. Investigation depth improves as more relevant signals are enabled, including Container insights logs, Kubernetes events and state, Azure managed service for Prometheus, container and pod logs, Application Insights telemetry for AKS-hosted workloads, Azure Activity Log changes, control plane logs routed through diagnostic settings, and resource metadata for the cluster, node pools, workloads, and related Azure resources. Figure 1. AKS investigation data sources You don’t need to enable every telemetry source to get started. The Observability Agent uses the data already available in Azure Monitor, and its findings become more complete as more AKS and application signals are collected. Example 1: AKS infrastructure — explaining why new pods never start Consider a workload rollout on AKS where replacement pods remain stuck in Pending state. What looks like a failed release may stem from the workload definition, cluster state, or underlying infrastructure. Investigation walkthrough Symptom: rollout is blocked Replacement pods remain in Pending during rollout, and Kubernetes events show repeated scheduling failures. This indicates that the rollout is blocked before new pods can start. Workload evidence: scheduling, not startup Pod state identifies the affected workload, while Kubernetes events show repeated placement failures. The issue is therefore tied to scheduling rather than application startup or container crash behavior. Cluster evidence: capacity pressure When enabled, Prometheus node metrics show CPU and memory utilization near capacity. Cluster-level trends show resource pressure increasing at the same time as pending pods and scheduling failures. Likely cause: insufficient schedulable capacity The scheduler cannot place new pods because the relevant node pool does not have enough available capacity. The failed rollout is best explained by capacity pressure in the target node pool rather than an application crash or image startup failure. Recommended action Scale out the affected node pool or adjust workload resource requests, then retry the rollout once schedulable capacity is restored. Figure 2. AKS investigation flow The Observability Agent connects pod state, scheduling events, and node pressure to explain why the rollout is blocked and which capacity action to consider next. Example 2: Joint app-AKS investigation — tracing application latency to pod restarts Now consider a customer-facing application where users see increased latency and intermittent HTTP 5xx errors after deployment. The first symptom appears in application telemetry, but the unhealthy requests are served by pods that are repeatedly restarting in AKS. Investigation walkthrough Symptom: customer-facing service degradation After deployment, application telemetry shows increased latency and HTTP 5xx errors. The first visible impact appears at the application layer. AKS evidence: unstable pods Affected pods enter CrashLoopBackOff, restart counts increase, and Kubernetes events show back-off restarts, probe failures, or image or command errors. Container logs point to startup exceptions, missing configuration, or crash details. Resource evidence: workload-specific pressure Container memory usage approaches configured limits before restarts, while node metrics show no broad node pressure. This suggests the issue is workload-specific rather than cluster-wide capacity related. Change evidence: deployment correlation Deployment history shows a new image or configuration change shortly before restarts began, with no matching platform health event. The timing points to the latest deployment or configuration change. Recommended action Review the latest image or configuration change, inspect container logs, adjust memory limits, or roll back if needed. Focus remediation on the workload change rather than node pool scaling. This pattern shows how an application symptom can map back to AKS workload behavior. Application telemetry establishes the user impact, while Kubernetes events, container logs, and resource metrics help explain why the affected pods keep failing. Operational impact For site reliability engineers, platform teams, and IT professionals, the Observability Agent reduces the time spent moving between application and AKS telemetry. It brings relevant signals into one investigation, surfaces supporting evidence, and applies Azure Monitor and AKS context so your team can review the findings, validate the recommended path, and decide which production changes to make. Figure 3. AKS investigation results Using the Observability Agent You can start using the Observability Agent from the Azure portal in two common AKS troubleshooting flows: Investigation mode: Start an investigation from an Azure Monitor alert on an AKS resource or from an Application Insights alert for an AKS-hosted workload. The agent uses the alert context to scope the incident, correlate application and cluster telemetry, and summarize the likely cause with recommended next steps. Chat-based exploration: Open the Monitor experience in AKS and select the Observability Agent button to chat with your telemetry. Use natural language to ask follow-up questions, explore logs and metrics, detect and inspect anomalies, and narrow down likely causes. Figure 4. Starting Observability Agent from AKS Monitor experience Next steps Azure Copilot Observability Agent overview Monitor Azure Kubernetes Service with Azure Monitor Stay connected Follow this blog for ongoing deep dives, updates on current capabilities, and a preview of what's coming next. Live webinar — A walkthrough of real Observability Agent scenarios, best practices, and what's available today, along with a look at what's coming next and live Q&A with the product team. Register for the Observability Agent webinar. We'd love your feedback The Observability Agent continues to evolve based on real-world usage and operator feedback. Share your thoughts directly through the Give Feedback option in the experience, or reach us at: azureobsagent@microsoft.com345Views0likes0CommentsVNet integration for Azure SRE Agent (preview)
For many production systems, the logs, databases, private endpoints, repositories, and runbooks an SRE Agent needs to do its job are behind network boundaries your security team already governs. VNet integration for Azure SRE Agent, now in preview, puts the agent's outbound traffic under those same controls - your virtual network, your NSG rules, your private DNS - so it reaches only what your network allows. The principle is one your security team already applies to every other workload: a component's network access shouldn't depend on the component behaving correctly. Identity governs what the agent can reach. Permissions and hooks shape what it does within reach. The network sits beneath both: it blocks any request to a destination you haven't allowed no matter what the agent decides. Why egress control matters Two reasons. First, the agent reads sensitive things by design. Inspecting logs, code, configuration, and internal systems is the whole point during an incident, which means you have to decide where that data can go. Open egress gives that data a path out of your network - a risk you wouldn't accept for any other production-adjacent workload. Second, it reasons over text it didn't write - logs, issue descriptions, tool output — which is how prompt injection gets in. Handling that is partly model safety, and Azure SRE Agent runs under Microsoft's Responsible AI standard with safety work from OpenAI and Anthropic. Network controls add another layer: an instruction that tries to reach a destination you haven't allowed can't run, because the network blocks it. For example, an agent investigating an outage might query Log Analytics, read deployment configuration, and call an internal runbook - all private resources. With VNet integration, those calls follow the routes, DNS, and firewall rules your workloads already use. A request to an external endpoint you haven't allowed fails at the network boundary. It doesn't depend on the model recognizing the risk and refusing; the network stops it either way. Choose an egress mode Azure SRE Agent has three egress modes, and you don't have to start at the strongest. Unrestricted - all outbound traffic allowed Limited - deny all outbound, allow an explicit list of hosts. Gives you host-level control without setting up a full VNet Azure VNet - outbound traffic goes through a delegated subnet in your network, with your NSG rules and private DNS applied. The recommended mode for production and regulated workloads. How Azure VNet mode works Outbound traffic takes one of two paths, and every call takes exactly one. Your VNet. Everything not placed on the managed path goes through a delegated subnet in your own network, where your NSG rules, private DNS, and firewall all apply. The agent is just another workload on that subnet, so it can reach what the subnet can reach: databases behind private endpoints, internal services, monitoring stores, and key vaults -the parts of production that aren't reachable from the public internet. The resources that matter most during an incident are usually the private ones. If your network connects to on-premises over ExpressRoute or VPN, the agent can reach those systems too, as long as your existing routes and rules allow it. The managed infra path. Some destinations go through Azure SRE Agent's managed infrastructure network instead - platform services the agent needs, plus optional categories you turn on: package registries, code repositories, and remote MCP servers. This path skips your VNet, so your NSG rules and Firewall Policies don't apply to it. Treat it as a deliberate exception, used only where you need it. Why public services start on the managed path Public services are hard to allow by IP address. GitHub, PyPI, npm, NuGet, apt, and the container registries run on large, changing IP ranges, and they don't map to a single Azure service tag. If your NSG filters by IP and port, keeping those lists up to date is constant work, and when a list falls behind, the agent can't pull a package or read a repository - and an investigation stalls on a networking problem that has nothing to do with the incident. Each category has a toggle: package registries (PyPI, npm, NuGet, apt), code repositories (GitHub, GitHub Enterprise, Azure DevOps), remote MCP servers, and a list of additional hostnames. Starting with these on the managed path keeps the agent working reliably without maintaining an IP allowlist. For build-time dependencies, that's usually fine. If you want this traffic inspected too, the next step is name-based (FQDN) egress filtering in your own network. Once your firewall can allow github.com and pypi.org by name, you can move these categories off the managed path and route them through your VNet instead Configure it Two decisions: the subnet, and what (if anything) uses the bypass. Navigate to Settings > Workspace Configuration > Network Choose Azure VNet as the egress mode. Select a subnet that is /27 or larger and delegated to `Microsoft.App/environments`. Decide which categories, if any, use the bypass. Restrict who can change the egress mode and bypass toggles. These settings widen or narrow the agent's reach, so govern them like any production network control. Test the outbound behavior before using the agent with production data. A reasonable setup for most enterprises during preview: use Azure VNet mode, keep package registries and code repositories on the bypass if you need reliable access to them, and route everything else through your VNet. Stricter environments can turn those categories off and rely on their own name-based firewall rules. What it doesn't cover yet VNet integration is in preview, with two limitations to know. It covers outbound traffic only - reaching the agent privately from inside your network isn't part of this preview. And connector traffic still routes over the public internet; the governance and credential isolation in Connectors V2 still apply. Use VNet integration for outbound control of the agent workspace, and combine it with identity, RBAC, tool permissions, hooks, and connector governance for a complete set of controls. Where it fits VNet integration doesn't replace identity, RBAC, tool permissions, or connector governance. It controls where traffic can go. The agent still needs the right identity and permissions to access a resource in the first place. Identity is the foundation: your RBAC assignments decide what the agent can reach. Permissions and hooks shape what it does within reach: allow/ask/deny rules control what runs, and hooks let you inspect or change a tool call before it runs. VNet integration sits underneath, controlling where traffic can go no matter what the agent tries to do. You want the agent to be capable. You also want a boundary that holds whether or not it is. Get started Create an SRE Agent - https://aka.ms/sreagent Documentation - https://aka.ms/sreagent/newdocs Recipes - https://aka.ms/sreagent/recipes Build 2026 Announcement - https://aka.ms/Build26/blog/SREAgent1.4KViews1like0Comments