azure horizondb
21 TopicsPostgres Trip Report from Postgres Summit US 2026
Photo gallery: Microsoft team at Postgres Summit US 2026 Postgres Summit US 2026 was a conference of connections: between database internals and the infrastructure underneath them, between AI ideas and production engineering, and between the people building PostgreSQL today and those who will carry it forward. For anyone who could not be in New York, this report captures the talks, technical questions, hallway conversations, and community moments that defined the week. The event also opened a new chapter. After years as PGConf NYC, the conference returned as Postgres Summit US, bringing more than 240 developers, DBAs, architects, contributors, technology leaders, and partners to Convene on Broadway from September 30 through October 2. The Microsoft team contributed six sessions across performance, replication, infrastructure, benchmarking, AI, developer tools, and community sustainability. Around those talks was a much larger program shaped by speakers and attendees from across the PostgreSQL ecosystem. 01 - Microsoft speaker highlights 02 - What the wider program was talking about 03 - Workshops and the hallway track 04 - The conversations continued after the slides 05 - What we brought home from New York 06 - Explore the Postgres Summit US 2026 program Gratitude for the organizers, speakers, sponsors, and attendees 01 - Microsoft speaker highlights Abe Omorogbe and Jared Meade: "Tour of Postgres on Azure with HorizonDB, Agentic workflows, & VS Code." Their end-to-end tour moved from HorizonDB's shared-storage architecture, rapid failover, and elastic read scale to SQL-declared chunking and embedding pipelines, durable incremental processing, intelligent product search, Copilot CLI Postgres skills, and an interactive VS Code query-plan visualizer. Although the demos used Microsoft technology, the engineering message applied broadly: production AI needs a dependable data layer, observable workflows, and tools that help developers understand what the database is doing. Microsoft Azure HorizonDB Documentation Landing Page | Microsoft Learn Claire Giordano delivered two talks that connected PostgreSQL's technical foundations with its future. In "A Secret Decoder Ring for Postgres Replication: A Beginner's Guide," Claire turned the alphabet soup of logical, physical, streaming, synchronous, and asynchronous replication into approachable mental models tied to high availability, disaster recovery, read scaling, migrations, WAL, and Patroni. Slides from Claire's talk: A Secret Decoder Ring for Postgres Replication: A Beginner's Guide In Claire Giordano's talk, "Building the next generation of Postgres contributors: what's working & what's getting in the way," she marked PostgreSQL's 30th anniversary by examining the project through three lenses: the soul of its people and culture, the machine of its workflows and governance, and the fuel of economics and funding. Together, the talks asked both how PostgreSQL keeps data moving and how the community keeps itself moving. Slides from Claire's talk: Building the next generation of Postgres contributors: what's working & what's getting in the way Divya Bhargov: "Same Postgres, Moving Ground: How Infrastructure Changes Shape Database Behavior." Divya explored a production reality that applies to every environment: PostgreSQL can remain stable while VM families, storage layers, operating systems, kernels, and networking stacks change underneath it. Drawing from large-scale operational experience, she showed why teams should correlate database symptoms with infrastructure transitions before assuming every behavioral change originated inside PostgreSQL. Gayathri Paderla: "PostgreSQL Performance Mysteries: When Low IOPS Still Means High Latency." Gayathri unpacked real production cases where latency increased even though familiar signals such as IOPS, query duration, CPU pressure, and indexing did not point to the cause. The trail instead led through memory behavior, cache eviction, PostgreSQL shared buffers, the operating system page cache, and storage interactions. The session showed how to correlate pg_buffercache, pg_stat_statements, wait events, storage behavior, and cache-warming techniques such as pg_prewarm. The practical lesson was memorable: low IOPS does not mean storage is uninvolved, and a normal query metric does not mean the application is experiencing normal latency. Slides from Gayathri's talk: PostgreSQL Performance Mysteries When low IOPS still means high latency - Speaker Deck Richard Yen: "Pushing PostgreSQL to the Limit: How to Benchmark Hardware with Postgres." Richard challenged the numbers used to sell hardware and cloud storage. Massive advertised IOPS or throughput does not tell a DBA whether the real limit will be storage, CPU bandwidth, PostgreSQL locks, checkpoints, archive_mode overhead, or autovacuum interference. His session focused on building an impartial PostgreSQL benchmarking harness, instrumenting both system and database metrics, and avoiding synthetic-test traps that can produce confident but misleading conclusions. Slides from Richard's talk: Pushing PostgreSQL to the Limit: How to Benchmark Hardware with Postgres 02 - What the wider program was talking about Beyond the Microsoft sessions, the schedule showed where PostgreSQL engineering is headed. The keynote "Lessons Learned from Developing Agentic AI Tooling for Postgres" set a practical tone for AI. Other sessions explored hybrid search, agent memory, AI-agent security, PostgreSQL 19, planner behavior, VACUUM, index prefetching, change data capture, driver maintenance, Kubernetes migrations, replication, and zero-downtime operations. The breadth of the program mattered. Healthcare, financial services, government, SaaS, analytics, and cloud-native teams have different workloads, but they share the same production requirements: reliability, security, predictable performance, recovery, regional availability, and a clear way to choose the right platform for each workload. The question is no longer simply whether PostgreSQL is enterprise ready. It is how each organization should use PostgreSQL without creating unnecessary operational complexity. 03 - Workshops and the hallway track The workshop track made the conference approachable for people at different stages of their PostgreSQL journey. Sessions such as "Getting Comfortable with Postgres," "Postgres DBA Basics Nobody Told You,"And "Locks, Monitoring & the Config That Matters" turned administration, configuration, troubleshooting, and performance concepts into hands-on practice. That mix of beginner-friendly learning and deep technical sessions is one of the best things about PostgreSQL conferences. Photo gallery: hands-on learning and community conversations 04 - The conversations continued after the slides The Day 1 reception gave everyone time to compare notes after the first full program, and many of the best exchanges continued at sponsor booths, over dinner, and between sessions. Engineers compared production lessons. Contributors heard directly from users. Teams discovered that problems they had considered unique were often shared by people at other companies. That hallway track is difficult to capture in an agenda, but it is a big reason people travel to PostgreSQL events. Postgres Summit US is organized by the United States PostgreSQL Association (PgUS) and supported by volunteer organizers, reviewers, speakers, and sponsors. The sponsor community included cloud providers, database companies, observability vendors, and open-source specialists. Microsoft was proud to participate, but the event's real strength came from the range of people willing to share what they had built, what had failed, and what they had learned. 05 - What we brought home from New York Microsoft brought home five key takeaways from Postgres Summit US 2026: Production AI is now a PostgreSQL architecture and operations discussion. The community is moving beyond AI prototypes toward dependable data foundations, secure agent access, observable pipelines, hybrid search, and production-ready developer tooling. Infrastructure changes can affect database behavior even when PostgreSQL itself has not changed. VM, storage, operating-system, kernel, and networking changes must be considered when diagnosing PostgreSQL performance and reliability. Observability and explainability are essential at scale. Effective diagnosis requires correlating PostgreSQL internals, query behavior, memory, caching, wait events, infrastructure metrics, and storage behavior rather than relying on one familiar metric. Organizations want to consolidate more workloads on PostgreSQL without increasing operational complexity. Customers expect simpler operations, predictable performance, stronger recovery, high availability, and clear guidance for selecting the right PostgreSQL platform. Community knowledge sharing remains one of PostgreSQL’s greatest strengths. Technical sessions, workshops, hallway conversations, and candid production lessons help practitioners, contributors, and new community members learn from one another. These takeaways reinforce Microsoft’s continued investment in PostgreSQL performance, developer experiences, AI integration, operational reliability, and open-source collaboration. The transition from PGConf NYC to Postgres Summit US felt appropriate. The event still had the technical depth, welcoming hallway conversations, and practical learning that people value, but the scope was broader. AI-enabled applications are moving into production, PostgreSQL 19 is opening new possibilities, and operators are asking sharper questions about reliability and performance. Microsoft will continue investing in PostgreSQL performance, developer experiences, AI integration, and open-source collaboration. We are already looking forward to the next gathering. Microsoft booth, reception, community dinner, and New York moments 06 - Explore the Postgres Summit US 2026 program Conference schedule :https://postgresql.us/events/postgressummitus2026/schedule/ Conference sessions and abstracts: https://postgresql.us/events/postgressummitus2026/sessions/ Gratitude for the organizers, speakers, sponsors, and attendees A conference like this only happens because many people contribute behind the scenes. Thank you to Postgres Summit US, the volunteer organizers, the program committee, the speakers who did the work behind every slide and demo, the sponsors who helped make the event possible, and the attendees who brought thoughtful questions and real production experience into every room. To everyone who shared a lesson, asked a difficult question, demonstrated a new idea, or welcomed someone new to the community: thank you. Hopefully these photos and highlights give you a feel for the energy in New York. See you at the next PostgreSQL gathering.221Views2likes0CommentsWhy Microsoft contributes to Postgres: What I tell people
Last week at PGConf.EU in Valencia, I gave a talk about the Postgres work being done at Microsoft (slides here). Getting ready for that talk, I kept noticing how much has changed in the Postgres team at Microsoft in the last 8 years. When I joined Microsoft through the Citus Data acquisition in early 2019, Microsoft contributed to Postgres in only one of the 9 ways it does today: our Azure Database for PostgreSQL managed service. We weren't sponsoring Postgres community conferences. We weren't sharing our expertise via blog posts and conference talks. We didn't have a Postgres open source contributors team. We didn't have a monthly podcast. And POSETTE: An Event for Postgres didn’t exist yet. It's heartwarming to see how far we've come. But sometimes, when I'm meeting people new to open source—especially those with a more proprietary software background—they will ask: “Why does Microsoft contribute to the Postgres open source project?” And when they learn my job is to lead our Postgres community efforts, they'll ask: “How do you know your open source work drives revenue?” Here's what I tell people about why Microsoft contributes to Postgres. Contributing upstream makes Postgres better for everyone, including Azure customers In my PGConf.EU 2026 talk, I used a slide like the one below to show how upstream and downstream fit together. Open source people use the “upstream” and “downstream” terms all the time, but they're not obvious to everyone. Quick definition: the upstream project is the Postgres open source project itself. Downstream services, like Azure Database for PostgreSQL and Azure HorizonDB, are built on top of it. Figure 1: Slide from my talk at PGConf.EU 2026, depicting the upstream Postgres open source project and our downstream managed services on Azure. If you run a Postgres managed service, you depend on Postgres—and we believe that means you have a responsibility to give back. So since 2019, we’ve been building a Postgres open source contributors team, to do our part to keep Postgres healthy for the long haul. And our upstream work benefits everyone who uses Postgres, including our downstream Azure customers. What might not be obvious: the things we learn running a Postgres service on Azure help the Postgres project too. When our engineers find a bug in Postgres while running it on Azure, they fix it upstream, which benefits Postgres users everywhere. Even open source developers need to eat Back in 2023 I wrote a meaty treatise of a blog post (complete with a hand-drawn infographic) about all the Postgres work happening at Microsoft. In that post, I included a section on why Microsoft has been building a team of Postgres contributors whose main focus is the upstream project. My answer to “why” hasn’t changed—I’ve included it in every edition of the annual what’s new blog post since, including the 2026 edition of What’s new with Postgres at Microsoft: In order to thrive, an open source ecosystem needs commercial support as well as volunteer efforts. Even open source developers need to eat! For the Postgres open source ecosystem to flourish, companies like Microsoft need to support the project by funding development in the Postgres core. Which we do. PostgreSQL is a complex piece of software that runs mission-critical workloads across the globe. To provide the best possible experience on Azure, it follows that we need to thoroughly understand how it works. By having PostgreSQL committers and contributors on our team, they can share knowledge internally across different orgs, or directly answer internal questions regarding incidents or extension development. Because today's cloud operates at a scale most on-prem solutions never encountered, unique cloud data center problems, often relating to performance, now require special attention. Our in-house team of deep Postgres experts are focused on tackling these cloud-scale issues upstream, in the Postgres core. Another benefit: our team's Postgres expertise gives Azure customers confidence in our cloud database services, too. Commercial funding of PostgreSQL developers has another benefit: it gives developers the long-term stability to pursue the big things, the groundbreaking changes that are super important to the future. In particular, the Postgres contributor team at Microsoft is focused on some big architectural changes (example: Asynchronous IO) that you wouldn’t be able to do without the funding for a full-time, multi-year effort. Example: one of those groundbreaking Postgres changes I mentioned landed last year: Asynchronous IO shipped in Postgres 18 and continues to evolve in Postgres 19 on forward. If I were writing those 2023 words above fresh today, I’d add one more reason: The Postgres project is about more than code. The project also runs on docs, the build farm, web infrastructure, packaging, translations, mentoring, conferences, trademark protection, the extension ecosystem, meetups, and more. That’s why our Postgres team contributes to the project in all sorts of ways beyond code. Nine ways Microsoft contributes to Postgres When explaining to people why we have a team dedicated to the upstream Postgres project, it helps to see how we contribute to the broader Postgres ecosystem—both our work on the Postgres code and community, and our managed services on Azure. So let’s walk through nine of the ways our team is contributing today. Figure 2: Infographic of 9 of the ways our team at Microsoft is contributing to the Postgres ecosystem. Clockwise, starting with our code contributions: Upstream Contributions to Postgres: Microsoft employs a dedicated team of Postgres committers and contributors working directly on upstream Postgres—plus a team working on open-source extensions such as Citus. While many of us believe commits are not a perfect measure of impact, they are a metric we have and they do give you a feel for scope. In the first release candidate of Postgres 19 (RC1), Microsoft’s team contributed 15% of the author commits (631 out of 4,098) and 17% of patch reviews (1,232 out of 7,240). The Microsoft team’s work spans performance, query planner, Async IO, security, and more. (Postgres 19 release notes) Supporting Postgres Events: Microsoft sponsors, and helps to organize, PostgreSQL community conferences and user groups worldwide. In the last year we sponsored 16 Postgres conferences, including PGConf.EU, PGConf.dev, PGConf India, and Postgres Summit US. Our team also shows up as speakers and program committee members. And several people on our team volunteer their time to co-organize conferences too: Daniel Gustafsson with Nordic PGDay; Melanie Plageman with PGConf.dev; Tomas Vondra with Prague PostgreSQL Developers Day (P2D2); and Cornelia Biacsics with PostgreSQL Conference Germany. Benefactor Sponsor of PGCA & the PostgreSQL project: Earlier this year, Microsoft made a benefactor donation to the PostgreSQL Community Association (PGCA), a non-profit chartered by the PostgreSQL core team in 2011 to protect and defend the Postgres trademarks. Full disclosure: I wear two hats here: I serve on the PGCA Board of Directors, and I work at Microsoft. With my PGCA hat on, I’m so appreciative of Microsoft’s support for the PGCA mission. (PGCA Sponsors) Visual Studio Code Extension for PostgreSQL: Lets you work with Postgres right inside VS Code. Over 785K installs, and it works with any Postgres database, not just Azure. (aka.ms/pgsql-vscode) POSETTE: An Event for Postgres: Free and virtual developer event with expert speakers from the Postgres ecosystem, now in its 6 th year. POSETTE 2027 will happen on 30 and 31 March 2027. (PosetteConf.com/2027) Azure Database for PostgreSQL: Our fully-managed database as a service, supporting the latest releases of Postgres open source. One thing I’m particularly happy to see: we supported Postgres 17 within 3 days of its release, and Postgres 18 on release day. With Postgres 19, we expect to support it on release day for both new servers and Major Version Upgrade. (aka.ms/azure-postgres-docs) Azure HorizonDB: Currently in preview, Azure HorizonDB is a new PostgreSQL-compatible database service built on a shared storage architecture, for applications that need to scale. (aka.ms/azure-horizondb-docs) Microsoft Blog for PostgreSQL: Our blog about Postgres, Azure, and our Postgres community initiatives. (aka.ms/microsoft-blog-postgres) Talking Postgres podcast: A monthly podcast about the people who work on Postgres and why they do what they do. I have the privilege of hosting it, and it’s so much fun. 44 episodes to date. (TalkingPostgres.com) And there’s more! Beyond the nine, our team keeps releasing new open-source tools for the Postgres community. Two recent ones: pghacker-mcp: This open-source MCP server lets you get answers to questions about Postgres’s design history and source code, with citations. Ask why a feature works the way it does, and an agent finds the relevant pgsql-hackers mailing list threads, commits, and code that answer it, and quotes them. (pghacker-mcp.dev) pg_durable: An open-source Postgres extension that lets you write long-running, fault-tolerant SQL functions, with retries and scheduling built in. It’s handy for things like ETL, database maintenance, and AI apps. Our team uses pg_durable in AI pipelines, Oracle to Postgres migrations, and pg_textsearch. (aka.ms/pg_durable) The revenue impact of upstream work is indirect—but it’s real Which brings me back to the question new hires ask me the most, especially if they come from a proprietary software background: Question: “How do we know our work on the upstream Postgres project moves the needle on Azure revenue?” My answer: The revenue impact of our open source work is indirect. And while it can't easily be measured, it's real. That's true of the patches our engineers write, and it's true of the podcast, POSETTE, and the conferences we sponsor. You can't trace most commits to a dollar of revenue, any more than you can trace a conference talk to one. Here's the thing: Azure Database for PostgreSQL and Azure HorizonDB are built on Postgres. As the Postgres project continues to thrive and grow, so do our Azure services. It all starts with people When we help make Postgres better, everyone who uses Postgres benefits, including our Azure customers. On the Talking Postgres podcast we sometimes talk about the toothbrush test: when you brush your teeth in the morning, are you looking forward to the work you'll be doing that day? My work leading our Postgres community efforts at Microsoft definitely passes the toothbrush test. 😊 And the biggest reason is the people. In my talk at PGConf.EU I said that Microsoft’s investment in the Postgres project starts with people. And the inspiration for my Postgres community work also starts with people: the people in the broader Postgres open source community, and my Postgres teammates at Microsoft. : Slide from my talk at PGConf.EU 2026 about Microsoft’s work with Postgres, with headshots of the people contributing to the upstream Postgres open source project—who inspire me every day. About Microsoft's Perspectives on PostgreSQL Perspectives on PostgreSQL is a monthly blog series featuring insights from Microsoft engineers, contributors, and builders working with PostgreSQL. Explore more articles on the Microsoft for PostgreSQL blog.1.9KViews3likes0CommentsUsing PostgreSQL to reflect on its own history and code: introducing pghacker-mcp.dev
By: Maxim Lukiyanov, PhD, Principal Software Engineer Every feature in PostgreSQL has a story. Before a line of code lands, it's proposed, debated, reviewed and often rewritten on the pgsql-hackers mailing list, sometimes over years. That conversation has been going on in public since 1997, and its 645,000 messages hold the reasons behind most of PostgreSQL's design decisions. It's one of the richest records of engineering knowledge I know of, and it's exactly the context AI agents need when they work on PostgreSQL or build on it. Agents can search the archive, but searching hundreds of thousands of messages takes them a long time, they can still miss the message that settled a question, and they have no map of how the facts connect: which thread led to which commit, which patch became which line of code, who argued for what, and what was finally decided. So I built pghacker-mcp. It's a free, public Model Context Protocol (MCP) server that gives any AI agent the PostgreSQL community's design history and PostgreSQL's source code, every commit on every branch, connected in one knowledge graph, and it answers with citations you can check. There's no sign-in, and the whole project is open source. Fittingly, it's powered by PostgreSQL itself, running on Azure HorizonDB: PostgreSQL, the database, reflecting on PostgreSQL, the project. With the PostgreSQL community gathering in Valencia for PGConf.EU 2026 this week, it felt like the right moment to share it. In this post, I'll show you what it can do, and then take you under the hood. Ask PostgreSQL why With pghacker-mcp connected, your agent can follow a feature from proposal to commit or revert, including the alternatives that were ruled out and why. It can also read, search and blame any version of PostgreSQL's code, back to the threads behind each line. Every answer comes with citations to the messages, commits and lines of code behind it. For example, ask whether retrying a failed fsync() can lose data. Your agent will explain that it can, because on Linux a retried fsync() can report success after the first failure lost the data, and that in 2018 PostgreSQL chose to PANIC instead. That's the real point of pghacker-mcp. Any agent can sound like it knows PostgreSQL's history. With pghacker-mcp, yours can show you where that history is written. How it works pghacker-mcp has three parts, built around one PostgreSQL database: The indexer, written in Rust, loads new mail and commits every hour and keeps the commit history and the graph up to date. Crawler agents, running on PilotSwarm, an open source durable runtime for agents from Microsoft, have read all 58,734 threads and recorded what each one decided: features, decisions and each author's positions, with verbatim quotes. Reading a 250-message debate and saying who argued what takes a language model, and it's what makes this project possible today. The MCP server, also in Rust, is public, stateless and read-only, with 17 tools: familiar ones like grep, read_file and blame, thread search, and a query tool for SQL and Cypher. PostgreSQL turned out to be a great code search engine Agents ask about code across time: how a function looked in 2015, who wrote a line, or whether a fix reached the back branches. That means pghacker-mcp needs every version of PostgreSQL's code, searchable fast. That's a bigger challenge than it sounds. PostgreSQL's history has 105,000 commits on 39 branches, and the tree at an average commit holds about 2.6 million lines. Checked out one by one, they would add up to more than 250 billion lines. On my laptop, git log -S fsync_fname , which finds the commits that changed uses of PostgreSQL's fsync helper, takes about 54 seconds to search the whole history, and running git grep on every commit would take about six hours. So the commit history stores each version of a line just once, with the range of commits that contain it. The idea is older than git. It's how SCCS stored every version of a file as one weave of interleaved deltas in the 1970s, and it's how temporal databases record the period in which a row is valid, here measured in commits, not time. The trick is in how commits are numbered. Every commit gets a 64-bit address: master's commits are spaced 2³² apart, and each branch numbers its commits in the gap right after the commit it forked from. PostgreSQL's history has no merge commits, so the descendants of any commit form one continuous range, much as in the nested set model for storing trees in SQL. "Is this line in commit X?" becomes a simple range test on the line's bounds: lo <= X AND X < hi AND (alive IS NULL OR alive @> X) The int8multirange column alive covers the one exception: lines deleted on one branch but kept on another. With this model, all 105,000 commits fit in 24 million line versions, 6.5 GB with indexes. What surprised me is that PostgreSQL already had every tool this design needs. The bounds are plain bigint columns, the same half-open interval an int8range describes, and int8multirange handles the exceptions. A B-tree on each line's file and bounds, (lineage, hi, lo) , narrows a search to the files and commit you asked about. And a GIN index with pg_trgm's gin_trgm_ops narrows a regular expression down to a few candidate lines, which PostgreSQL then checks exactly. That's the technique Russ Cox described in how Google Code Search worked, and pg_trgm has supported it since PostgreSQL 9.3, thanks to Alexander Korotkov. Together, these indexes search the whole history far faster than local grep can, because grep has to scan every version of the tree, while PostgreSQL's indexes go straight to the few lines that can match. pghacker-mcp finds every line that ever contained fsync_fname in every one of 105,000 commits, in 50 milliseconds. Trigrams carry most of the load. I studied how AI coding agents actually search code, and of 35,728 real grep calls from my own agent sessions, 91% could use a trigram index, including 98% of those that spanned a folder or a whole repository. Nearly all of the other 9% searched files the agent had already named, where PostgreSQL simply reads those few lines. Just as important, grep works exactly as agents expect. They can send pghacker-mcp the same grep commands they already write, flags, pipes and all. Replayed against GNU grep, 7,254 real grep commands from my agent sessions returned exactly the same output, every one. Agents don't need to learn a new search language: grep just works, on every version of PostgreSQL. Everything else this project needs runs in the same engine: BM25 ranking and vectors for the mail, and a graph for the links. One SQL query can join them all. I never needed a separate search engine, vector store or graph database. I chose PostgreSQL to store the code, and it turned out to be a great engine for searching it, too. A knowledge graph from the mailing list to the code Search finds text. But questions about design are about connections: which thread a commit came from, which patch first proposed a line, who argued for what, and what was decided. Relationships like these are natural to express as a graph, so pghacker-mcp keeps them in a knowledge graph, built with Apache AGE in the same database: about a million vertices, from authors and messages to files and commits, and four million edges between them. The most important design decision was who creates which links. Links that are facts are made by deterministic code. The Discussion: link that committers add to commit messages, or a message that mentions the commit, connects a commit to its thread; there are more than 40,000 such links. Patches posted to the list are matched to the lines and commits they became. Judgments, like what a thread decided and where each author stood, come from the crawler agents, and each one must quote its messages exactly, or it's rejected. Here's the fsync story again, this time starting from the code: One blame call takes a line of PostgreSQL 19 to its 2018 commit and to the patch where it first appeared. The commit's Discussion: link leads to the thread, and the thread to its decision. Three tool calls, from today's code to the debate behind it. Because these connections are stored rather than rediscovered on every question, your agent can also ask what no single thread can answer: which features a file implements, who argued for or against each of them, which commits changed the file, and which release each feature shipped in or targets. Search tells you where something was said. The graph tells you how it all connects: why the code is the way it is, and who shaped it. MCP is growing up fast In the last year and a half alone, MCP gained elicitation, structured output, tasks and extensions, and the 2026-07-28 revision made it stateless: no sessions, no handshake, and every request carries the client's capabilities. For a public server like pghacker-mcp, that's a big deal, because any server instance can answer any request. But what excites me most are two newer features that change what a server can offer, and pghacker-mcp uses both. Skills: a server that teaches agents Tools give an agent abilities; skills give it know-how. An Agent Skill is a SKILL.md file of instructions that teaches an agent a workflow. The new official skills extension for MCP lets a server publish skills next to its tools, so agents that connect can discover and load them. pghacker-mcp publishes one skill, review-as-author. Give your agent a patch and the name of a pgsql-hackers regular, and it reviews the patch the way that person likely would: each point backed by a quote of their own, marked as a prediction, and, given a date, based only on what they had written by then. Ask your agent to review the May 2022 patch set for logical replication of DDL as Tom Lane would have, and it predicts he'd push back on putting it into core, quoting his own 2012 warning that decompiling parse trees would be "a permanent drag on every type of SQL feature addition". Tom actually raised that objection on this patch in March 2023, 80 patch versions later. That's feedback worth having early. Clients that don't support the skills extension yet can load the same skill through a tool, load_skill_review_as_author. Elicitation: a server that can talk to the user Originally, an MCP server could only answer the model. Elicitation lets it ask the user a question directly, through a form the client shows, with the model taking no part. In the 2026-07-28 revision, it works as a multi-round-trip request: the server answers a tool call with input_required and a form, and the client retries the call with the user's answer. I use it for something every public service needs: feedback. Once in a while, pghacker-mcp asks "Was the last answer helpful?", with 👍, 👎 or Skip. It asks at most once in an hour of use, backs off for a day if you decline, and never asks if you connect with ?feedback=off. It sounds small, but it's a new interaction mode: a server that hears directly from the people it serves. I believe we'll see a lot more of this, from confirmations to choices to preferences. MCP is no longer just a way for agents to call tools. It's becoming a flexible protocol between servers, agents and the people who use them. Why I built it on Azure HorizonDB Everything I've described, from the mail and embeddings to the code history and the graph, lives in one Azure HorizonDB database: 29 GB on 32 vCores, running PostgreSQL 17 with pgvector, pg_trgm, pg_textsearch and Apache AGE. Even PilotSwarm keeps its agents' durable state there, and the indexer writes to it every hour while the public server reads. Full disclosure: I work on the team that builds HorizonDB, so I'm biased. But this project shows what HorizonDB was designed for. HorizonDB separates compute from storage and sends only WAL from compute to storage, so I never had to provision storage or IOPS as the archive and the history grew. If the public server needs more read capacity, read replicas share the same zone-resilient storage instead of copying it. And because HorizonDB is built on PostgreSQL, every extension this project needed is there, and nothing in the code is specific to HorizonDB. One command runs the same project on your laptop, with PostgreSQL 17. HorizonDB is in public preview and open to everyone. If you're building AI apps and agents on PostgreSQL, create a cluster and give it a try. In conclusion pghacker-mcp unlocks the PostgreSQL community's knowledge for every AI agent. With the commit history, your agent can search any version of PostgreSQL in milliseconds. With the knowledge graph, it can connect code to the debate behind it. And with skills and elicitation, a server can teach agents and hear from the people who use it. To try it, add the server to your agent. In GitHub Copilot CLI or Claude Code, it's one command: copilot mcp add --transport http pghacker https://pghacker-mcp.dev/mcp claude mcp add --transport http pghacker https://pghacker-mcp.dev/mcp pghacker-mcp.dev has the steps for the GitHub Copilot app, VS Code, Codex, Cursor and OpenCode. Then ask it something you've always wondered about PostgreSQL. The code is on GitHub: read it, file issues, contribute, and tell me how its answers work for you. For nearly three decades, the PostgreSQL community has explained in public why PostgreSQL is built the way it is. Now PostgreSQL itself can help every agent, and every developer, find those explanations.443Views3likes0Comments
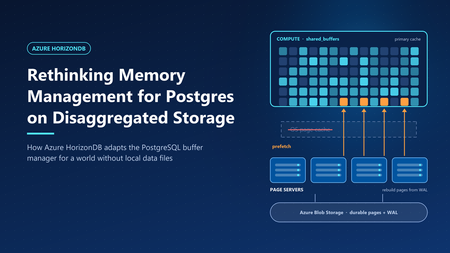
Rethinking Memory Management for Azure HorizonDB on Disaggregated Storage
In Smarter Storage for Azure HorizonDB, we described how HorizonDB moves durability, replication, checkpointing, and recovery out of PostgreSQL and into a purpose-built storage layer. The compute node writes only the write-ahead log (WAL). Data pages are rebuilt and stored by remote page servers. That design raises an obvious question: if PostgreSQL no longer reads and writes its own data files, what happens to its memory management? PostgreSQL's buffer manager was built around a specific partner: the operating system's page cache. Many of its defaults and heuristics only make sense because the kernel is quietly doing a lot of work underneath. HorizonDB removes that partner. This post explains which assumptions broke, and the changes we made to the PostgreSQL engine, so memory works well on disaggregated storage. What PostgreSQL assumes about the kernel PostgreSQL stores each table and index as ordinary files and accesses them with buffered I/O. Every page therefore can live in two places in memory: in PostgreSQL's own buffer pool (shared_buffers) and in the operating system's page cache. This "double buffering" is a deliberate part of the design, and it shapes several behaviors. A modest buffer pool. The PostgreSQL documentation suggests starting shared_buffers at about 25% of system memory. Much of the rest is expected to act as kernel file cache. A page evicted from shared_buffers is often still in the kernel cache, so reading it back costs a memory copy rather than a disk read. Prefetching is a hint to the kernel. When PostgreSQL knows it will need a page soon—during a bitmap heap scan, for example—it calls posix_fadvise with POSIX_FADV_WILLNEED. The kernel starts reading the page into its cache. A later read finds it there. PostgreSQL itself never allocates a buffer for the prefetched page. Sequential scans rely on kernel readahead. For sequential access, the kernel detects the pattern and reads ahead automatically, so PostgreSQL can issue fewer explicit hints. Ring buffers protect the cache. Large sequential scans, VACUUM, and bulk writes such as COPY use a small private ring of buffers—from a few hundred kilobytes to a few megabytes—instead of the whole buffer pool. A scan of a table much larger than memory therefore cannot push the working set out of shared_buffers. This is safe because a page that cycles through the ring is usually still in the kernel cache if it is needed again. Writes are cheap and deferred. When a dirty buffer is evicted, PostgreSQL writes it to the kernel cache, which flushes it to disk later. The background writer cleans buffers ahead of eviction so that queries rarely wait for a write. Checkpoints write all dirty pages and call fsync to make them durable. Each of these behaviors assumes that a miss in shared_buffers is usually cheap, and that writing a page means writing it to a local file. What changes in HorizonDB Figure 1. Compute memory layout: Community PostgreSQL vs. Azure HorizonDB. In HorizonDB, permanent tables and indexes do not exist as local files on the compute node. There is no kernel page cache holding database pages. A miss in shared_buffers must be served by the remote storage layer: Tier Where it lives Typical role Shared buffers Compute memory Working set; all pages are read and modified here SSD cache Compute local disk Extends shared buffers; holds cached copies of pages Page servers Remote storage fleet Page cache of the current version of every page Azure Blob Storage Remote, zone-redundant Durable backing store for pages and WAL A page that falls out of memory no longer drops into a free kernel cache. It may require a network round trip to a page server, which is much more expensive than a memory read. Writes change too. Because page servers rebuild pages from WAL, "writing" a dirty page on the compute node does not mean copying it anywhere. PostgreSQL only has to make sure the WAL describing the change is durable - a rule it already enforces before any page write. Taken together, this inverts the trade-offs behind PostgreSQL's defaults. Memory is no longer one of two caches. It is the primary cache. Design principle: shared buffers are the primary cache We organized the engine changes around one principle. shared_buffers is the primary cache, eliminating the memory overhead of double buffering and improving memory efficiency. Every page that is about to be needed should arrive in memory before the query asks for it. The following sections describe the engine changes that implement it. 1. Size shared buffers for the machine Without a kernel cache to share memory with, leaving 75% of RAM to the operating system would waste most of it. HorizonDB sizes shared_buffers automatically at 60–70% of the compute node's memory, depending on the size of the instance. The remaining memory is left for connections, query execution memory such as sorts and hashes, and the operating system. 2. Retire ring buffers Ring buffers exist so that a large scan can use a few megabytes of memory and rely on the kernel cache for anything it needs again. In HorizonDB, there is no such safety net. Recycling a small ring means that every page the scan touches is read, used once, and discarded—and a second scan of the same table must fetch everything again from storage. Ring buffers also exist to limit write traffic: a bulk operation that dirties pages in a small ring must write them out quickly. HorizonDB doesn't need to write dirty data pages back to disk at all, so that motivation disappears as well. HorizonDB therefore disables buffer ring strategies. Sequential scans, VACUUM, and bulk loads use the shared buffer pool like any other query. This is a trade-off, not a free win. A very large scan can now displace pages from shared_buffers that other queries were using. Two factors limit the cost. First, clock-sweep replacement tracks how often each buffer is used, so frequently accessed pages outlive pages a scan touched only once—and buffer replacement is an area we continue to improve. Second, pages that leave shared_buffers are not simply lost: HorizonDB can keep them close by in the local SSD cache. How it decides and what goes there is a story for a separate post. 3. Prefetch directly into shared buffers On a local disk, a prefetch miss costs a disk seek. On disaggregated storage, it costs a network round trip. Hiding that latency matters even more, so HorizonDB makes prefetching explicit, aggressive, and memory aware. Prefetch requests go to the page servers. When PostgreSQL issues a prefetch, HorizonDB sends a read request for the page to the page server that owns it, and does not wait for the answer. Each backend keeps a set of outstanding requests by default, so dozens of page reads overlap instead of running one after another. Sequential scans prefetch explicitly. PostgreSQL's read stream mechanism, which drives sequential scans and other block-range reads, normally avoids prefetching sequential blocks because it expects kernel readahead to cover them. HorizonDB turns that assumption off, so sequential reads are prefetched like any other access pattern. Responses land in their final buffer. In stock PostgreSQL, a prefetch only warms the kernel cache, so the later read still has to copy the page into shared_buffers. In HorizonDB, the page server's response goes straight into a shared buffer. When the query asks for the page, it is already in memory, with no extra copy and no second request to storage. These are only some of the prefetch optimizations we have built into the engine. Others use custom prefetch implementations and logic that tunes how far ahead each query reads. All of them share one goal: hiding storage latency so queries spend less time waiting on I/O and more time doing useful work. What this means for you As a fully managed service, our goal is to delight customers with a best-in-class PostgreSQL experience. You shouldn't have to think about kernel caches, buffer rings, or prefetch windows—that is our job. HorizonDB retains full PostgreSQL compatibility, so applications keep the familiar Postgres programming interface while the engine is tuned to deliver predictable performance on the storage underneath843Views5likes1Comment
AI features in Azure databases
A support engineer hits a fault. Somebody solved the same fault two years ago, wrote down what fixed it, and closed the ticket. The engineer searches, finds nothing, and works it out from scratch. The answer was in the database the whole time. The search could not reach it. The cost of that is not abstract. It is the same diagnosis paid for twice, a vessel or a production line down for longer than it needed to be, and an organisation that cannot tell whether a fault is new or its fifth recurrence. The knowledge was captured. The organisation still could not use it. That is a retrieval problem, not a model problem, and it is where this experiment starts. It also explains why a model alone does not fix it: the limiting factor is what the system can find, not how well it writes. Azure Database for PostgreSQL and Azure Cosmos DB have both added vector search, full text search, hybrid ranking, and the ability to call a model directly. These arrived as feature announcements. What they do under a real question, what they cost, and where each one stops being the right tool are not in the announcements. So the same 1000 records were loaded into both engines and into a graph, and every query was run live against Azure. Nothing here is a screenshot or a recorded result. Each claim is a query that executed, with its wall clock time and its request unit cost recorded. Three questions were being answered: Where does keyword search beat vector search, and where does it collapse? What changes when the database calls the model itself, rather than an application doing it? Does a graph add anything that SQL over the same table cannot already do? The third one produced the most uncomfortable answer. Background Both engines now ship the same broad capability set, at different stages of maturity. Capability PostgreSQL flexible server Cosmos DB for NoSQL Vector index DiskANN, via pg_diskann DiskANN Full text search tsvector with GIN built in, BM25 scoring Hybrid ranking written by hand RRF() as a single clause Embeddings from inside the database azure_ai extension, generally available public preview Generation from inside the database azure_ai.generate() not available Graph Apache AGE extension no The asymmetry is the interesting part. PostgreSQL gives the database its own identity and lets it call a model, which moves work out of the application entirely. Cosmos DB gives hybrid ranking as one function call and keeps latency low. Neither is a superset of the other. Method Dataset. 1000 synthetic support tickets across maritime, energy, payments and retail, generated from a fixed seed so the results reproduce exactly. Each ticket has a title, a free text description written the way a person would write it, a resolution, a fault code, an asset, a team and a severity. Two design choices decide whether the experiment says anything: The same fault is described as shuddering, juddering, trembling and knocking by different people. Without that variation there is nothing for vector search to beat keyword search at. The fault code is excluded from the embedded text. Include it and vector search half answers code lookups, which destroys the contrast being measured. Stores. Store Configuration PostgreSQL flexible server pgvector at 1536 dimensions, DiskANN, azure_ai, Apache AGE AGE graph, same server 1000 tickets, 18 assets, 12 teams, 12 codes, 3209 edges Cosmos DB for NoSQL 3072 dimension vectors, DiskANN, full text index, autoscale to 5000 RU/s Models. One Microsoft Foundry account. text-embedding-3-large for both stores, gpt-5.5 for the application, gpt-4.1-mini for generation inside PostgreSQL. Authentication. Entra ID everywhere. Password authentication disabled on PostgreSQL, local authentication disabled on Cosmos DB and Foundry. No key or connection string exists anywhere in the build. Measurement. A four page web application executes each query and reports wall clock time. A script runs every endpoint against every input and then clicks every control in a real browser. Numbers below come from that run. The setup. Note the difference in the two lines on the right: for PostgreSQL the database calls the model itself, for Cosmos DB the application does it. Results: PostgreSQL Query Time Plain English search, embedding generated in the database 1.3 s Semantic search feeding a GROUP BY 540 ms Hybrid fusion written by hand 580 ms Retrieval and generation in one statement 2.7 s The query contains no vector. azure_openai.create_embeddings() runs inside the SQL, authenticated by the server’s own managed identity. Because a similarity search returns an ordinary relation, ordinary SQL aggregates over it: which teams, how many tickets, average hours to repair. This is the operation a separate vector store cannot perform, because the join does not exist across two systems. With azure_ai.generate(), one statement embeds the question, searches, builds the prompt and calls the model. There is no application tier in the loop, so anything that can run SQL can do it: a scheduled job, a report, a trigger. The cost of that convenience is latency. Every one of these timings includes the database going out to Foundry and back on the caller’s behalf, which is why the plain English search takes over a second. The next section shows what the same questions cost when the application does that work instead. Results: the graph Apache AGE runs inside the same PostgreSQL server used above. No second database and no sync job. Three of its four edge types restate columns that already exist: which asset a ticket is on, which team fixed it, which code it carried. The fourth does not. SIMILAR_TO links each ticket to its two nearest neighbours by embedding, restricted to neighbours with a different fault code and a cosine distance under 0.40. That produced 209 edges over 1000 tickets. Same code neighbours are skipped because the existing CODED edge already connects those. Measured against a retail point of sale fault: Reached by Assets Fault code walk 5 retail stores and distribution centres SIMILAR_TO walk 4 vessels and 2 substations, none carrying that fault code The first walk is reproducible in SQL. SELECT DISTINCT asset FROM tickets WHERE error_code = ... returns the identical rows, verified one by one. The second is not, because no column connects a checkout terminal to a ship’s bridge display. Expanding from a retail point of sale fault. Grey links are the fault code, which SQL could also follow. Magenta links are the embedding-derived edge, and they reach four vessels and two substations that carry no ERR-6205 ticket at all. Note also that the graph stores no text and no vectors, so it cannot be searched by meaning, only traversed. Vector search selects the entry node and the graph decides how far to walk from there. Results: Cosmos DB The same 1000 tickets, in a document database rather than a relational one, with the application rather than the database calling the model. Query Result Time RU Keyword ERR-5012 13 tickets 130 ms 3.6 Keyword shaking 0 tickets 130 ms 3.6 Vector, paraphrased symptom the same 13 tickets, none sharing a word with the query 190 ms 7.1 Vector, given a fault code unrelated tickets, confidently ranked 420 ms 7.1 Filtered vector meaning plus metadata in one query 180 ms 8.7 Hybrid, ORDER BY RANK RRF(...) both rankings fused in the engine 380 ms 70.5 Two results stand out. The shaking query returns zero. The tickets describe that exact fault, using other words. Vector search then returns those tickets from a sentence that shares no vocabulary with them. Handed a fault code instead, vector search fails, because a code carries no meaning to embed. The two methods fail at opposite things. Hybrid search costs roughly ten times a plain vector query, 70.5 RU against 7.1. It is one clause and it works well, but it is not free and should not be the default on every request. The fusion itself is reciprocal rank fusion, which combines the two result lists by position rather than by score: score = sum over lists of 1 / (k + rank) This matters in practice, because it means the BM25 relevance score and the cosine distance never have to be made comparable. Only the ordering is used. It is also why the demo shows rank rather than the fused score: the score is an artefact of the constant k. With both sets of numbers on the table, the latency gap is the clearest difference between the two engines. Cosmos DB answers a vector query in 190 ms where PostgreSQL takes 1.3 s, roughly seven times faster, because the application has already produced the vector before the query is sent. That is the trade: PostgreSQL removes the application and pays for it in latency. Results: retrieval versus model The final test holds the model constant and varies only the retrieval. Same deployment, same prompt, same question. Each side receives whatever its search returned. Retrieval Tickets passed Answer Keyword search 0 “We have no record of this happening before.” Vector search 8 Names the causes and fixes, cites 8 ticket IDs, all verified Same deployment, same prompt, same 1000 tickets. Only the retrieval differed. The first answer is not a hallucination and not a weak model. It is accurate about what it was given, and wrong about reality, because the retrieval beneath it failed. A system that returns no results produces a confident denial rather than an error, which is why this failure mode reaches production. It is also the expensive one. A wrong answer gets challenged. “We have no record of this” gets believed, and the engineer starts again from nothing. No alert fires, no error appears in a log, and the only visible symptom is work being repeated somewhere else in the organisation months later. Constraints encountered Findings that were not documented in anything read beforehand. Cosmos DB autoscale has an irreversible floor. The maximum cannot later be set below one tenth of the highest value ever provisioned on that container. Raising throughput to 20000 briefly during a load permanently floored the container at 2000 RU/s. Data plane and control plane RBAC are independent. A subscription Owner still receives 403 when reading documents without a Cosmos data plane role. Throughput changes are control plane only. With local authentication disabled the data plane SDK cannot alter RU/s at all, regardless of identity. azure_ai.generate() sends temperature = 0.2 with no override. Newer reasoning models accept only the default and reject the request, so in database generation required a separate gpt-4.1-mini deployment. An embedding call inside ORDER BY is evaluated once per row. Over a cross join that is 1000 model calls per query. Moving it into its own CTE fixes it. The symptom presents as an unreliable network. pg_diskann is limited to 2000 dimensions. text-embedding-3-large produces 3072, so PostgreSQL indexes a 1536 dimension prefix of the same model. Apache AGE is preloaded on Azure. LOAD 'age', which most tutorials instruct, fails with a privilege error. shared_preload_libraries replaces rather than appends and changing it restarts the server. The Gremlin API does not support Entra ID on the data plane. It requires an account key and a separate account, which is incompatible with a keyless deployment. AGE inside PostgreSQL provided a graph without a second database. Role assignments take two to four minutes to propagate. During that window the error reads “Principal does not have access to API/Operation”, which is indistinguishable from a genuine misconfiguration. The /models inference endpoint requires Azure AI Developer. Cognitive Services OpenAI User grants OpenAI/* but not MaaS/*. A pooled connection survives a network change as a black hole. After the client machine changed address, the shared PostgreSQL connection remained open but unresponsive, and queries blocked indefinitely. connect_timeout, TCP keepalives and statement_timeout convert this into a recoverable error; measured recovery is 1.3 seconds. Cost Per day, in NOK, for the deployment described above: Component Cost PostgreSQL flexible server, running 83.80 Cosmos DB about 13 Storage about 1.30 The database dominates. Stopping the PostgreSQL server between sessions is the entire cost strategy. Model usage is consumption priced and negligible at this volume. Two things follow from that. The search and retrieval capability itself is nearly free, because it is a feature of a database that is already being paid for rather than a separate product with its own licence and its own operations budget. And the meter that matters is compute hours on a server that can be stopped, not tokens, which is a more predictable line item than most AI spending. Takeaways Money spent on a better model does not buy a better answer if the retrieval is weak. Both sides of the final test held the same 1000 tickets. Only the search differed, and that alone separated a correct answer from a confident denial. The search layer is where the return on an AI investment is decided, and it is usually the cheapest part of the stack to improve. The two search methods are complements, not competitors. Keyword search is exact and literal, and it is what a serial number, a part code or an invoice number needs. Vector search is approximate and semantic, and it is what a symptom described in someone’s own words needs. Each fails at what the other does well. Real questions contain both, which is the argument for hybrid rather than for choosing. Hybrid search is not free. Ten times the request units of a vector query on this dataset. That is a per-query cost multiplier at production volume, so it belongs on the queries that mix a code with a description, not on every request by default. PostgreSQL and Cosmos DB answer different questions, and the choice has consequences beyond performance. PostgreSQL keeps the semantic result inside SQL, where it can be joined, aggregated, and handed to a model without an application in between, which means a scheduled job or a report can use AI without anyone building a service first. Cosmos DB is the low latency path and gives hybrid fusion as a single clause. The first changes who in an organisation is able to deliver something. The second changes what the user waits for. Keeping operational data and vectors in one engine removes a moving part. There is no second store to provision, secure, synchronise or reconcile, and no window in which the two disagree. The experiment never had to answer the question “which copy is right”, because there was only one. A graph earns its place only through edges that are not columns. Traversing relationships that already exist as foreign keys is a GROUP BY in different syntax, and calling that a graph capability will not survive a competent question. An edge derived from embeddings is different: it reaches records that no WHERE clause can, and in this dataset it connected failures across four separate parts of the business that shared no code, no component and no domain. Keyless is achievable end to end. Entra ID across both databases and the model account, with the database calling the model as its own managed identity, removed every key, password and connection string from the system. Nothing can leak from a repository or a configuration file, because nothing is there. The cost is understanding that data plane roles are assigned separately from control plane roles. Silent failures dominate, and they are the ones that reach production. Every significant defect in this build produced no error: counts inflated by a cartesian product, unresolved tickets averaged as zero hour repairs, near duplicate generated text, a stale process serving old code, and a connection that had stopped responding. Nothing alerted. Assertions over the data and a scripted pass over every endpoint caught all of them, and both took under a day to write. On a system that answers questions rather than returning rows, that kind of check is not optional, because a wrong answer looks exactly like a right one. Where this goes next: Azure HorizonDB Nothing in this experiment used Azure HorizonDB, but it changes the shape of the argument, so it belongs here. The pattern behind the scaling question is familiar: teams want to stay on PostgreSQL and eventually hit a ceiling. HorizonDB is Microsoft’s own PostgreSQL, built for workloads past that point, and it is in public preview. It carries the same AI surface used above, pgvector, DiskANN indexing, hybrid search with reciprocal rank fusion, and the azure_ai extension, so the code in this experiment transfers rather than being rewritten. What it adds is AI pipelines. Chunking, embedding, extraction, generation and ranking are declared in SQL as a pipeline that runs inside the database, on top of durable execution. The definition is a row in a system catalog. Execution survives a crash, retries failed steps, checkpoints partial work, and re-embeds only rows that are new or changed. That closes the remaining gap. This experiment showed a database answering a question. A pipeline is the same idea applied to keeping the data ready to be asked: no orchestrator, no separate worker, no job that quietly stops running. Both are preview features and should be read as direction rather than as something to put in front of customers this quarter. Not tested Scope was limited to what the two databases do on their own. Three things were left out deliberately and would change the conclusions if included. Agentic retrieval. Query planning, sub queries, iterative retrieval and reflection over multiple knowledge sources, as offered by Azure AI Search and Foundry IQ. That is a retrieval strategy built above the database, and it would have made the single query comparison meaningless. Reranking. A semantic reranking model over the candidate set. PostgreSQL exposes azure_ai.rank() for this and it was verified as working, but nothing in the experiment used it. Scale. 1000 rows is enough to show behaviour and not enough to show performance. The query planner in particular behaves differently: at this size it correctly ignores the vector index, because a sequential scan over a thousand rows is cheaper than the index startup cost. Try it yourself Everything described here is published, including the Terraform for the Azure resources and the generator for the dataset. https://github.com/Hanifff/ai-features-in-azure-databases git clone https://github.com/Hanifff/ai-features-in-azure-databases.git cd ai-features-in-azure-databases az login ./scripts/setup.sh That reads your current Azure context, provisions the resources, loads all three stores, and starts the application. The dataset is generated from a fixed seed, so the counts quoted in this post reproduce exactly. The PostgreSQL server is the only meaningful cost. Stop it when you are not using it, and run terraform -chdir=infra/terraform destroy to remove everything.435Views1like0CommentsPostGIS and AI Retrieval in Azure HorizonDB
Fleet operators rarely search with a single kind of question. Sometimes they know exactly what they want: delayed shipments, within a certain radius of a location, arriving in a given window. Other times they only have intent, phrased in a sentence: "which delayed shipments need attention?" The first case is a deterministic filter. The second is a semantic search that a language model can shape into a query. Both need to run against the same operational data, return the same kind of exact rows, and stay inspectable enough that an operator can trust the result. The usual answer is to split that data: keep the transactional and, maybe, spatial rows in one system and copy embeddings into a separate vector store, with a search service in front. That works, but it duplicates the data, adds a synchronization problem, and hides the retrieval behind an API that no longer shows how a result was reached. The goal here is to keep both kinds of question against one database. I built a sample application, HorizonDB Fleet Intelligence, that answers them two ways: a criteria search form on the left, and a prompt-only assistant on the right. Its 24 global shipments are a deliberately small, hand-authored demo fixture, not a scale benchmark. Keeping the dataset small makes every returned row and planner choice easy to inspect. Both paths call the same repository, use PostGIS for location and pgvector for meaning, and expose the exact SQL and execution plan that produced their rows. This post walks through the goal, the two paths, and the queries and execution plans behind each. The interesting part is not that PostgreSQL can call an AI model. It is that the whole retrieval workflow, spatial filtering, vector ranking, and model reasoning, stays next to the data and remains readable. This sample demonstrates: One operational PostgreSQL database PostGIS for spatial filtering pgvector and DiskANN for semantic retrieval Agent Framework for prompt-driven search Full SQL and execution-plan visibility I ran this on Azure HorizonDB (preview), PostgreSQL 17.11, with postgis 3.6.1, vector 0.8.0, pg_diskann 0.7.3, and azure_ai 2.2.2 enabled. Both model aliases were registered with HorizonDB AI Model Management (AIMM). HorizonDB is a preview service, so region and subscription availability can change, and the plans and numbers below reflect what I ran rather than a support statement. The data model Each shipment is one row that carries relational fields, three PostGIS points, a JSON metadata blob, and a 1,536-dimensional embedding. The location columns are geometry(Point, 4326) , the standard WGS 84 longitude/latitude reference used by web maps. CREATE TABLE IF NOT EXISTS horizon_ship.shipments ( id uuid PRIMARY KEY DEFAULT pg_catalog.gen_random_uuid(), shipment_number text NOT NULL UNIQUE, title text NOT NULL, description text NOT NULL, origin_name text NOT NULL, origin_position public.geometry(Point, 4326) NOT NULL, destination_name text NOT NULL, destination_position public.geometry(Point, 4326) NOT NULL, current_location_name text NOT NULL, current_position public.geometry(Point, 4326) NOT NULL, status text NOT NULL CHECK ( status IN ('in_transit', 'delivered', 'delayed', 'exception', 'unknown') ), eta date, updated_at timestamptz NOT NULL DEFAULT now(), embedding vector(1536), metadata jsonb NOT NULL DEFAULT '{}'::jsonb ); The indexes give the planner several selective alternatives, which matters later because the two paths deliberately let the planner choose differently. There is a B-tree on status , a B-tree on eta , a GiST index on the geometry, and a second GiST index on the geography cast used by radius search: CREATE INDEX shipments_current_position_gix ON horizon_ship.shipments USING gist (current_position); CREATE INDEX shipments_current_position_geography_gix ON horizon_ship.shipments USING gist ((current_position::public.geography)); CREATE INDEX shipments_status_idx ON horizon_ship.shipments (status); CREATE INDEX shipments_eta_idx ON horizon_ship.shipments (eta); The vector index combines DiskANN with HorizonDB's spherical quantization (SQ) preview. DiskANN navigates a nearest-neighbor graph instead of scanning every vector. SQ compresses vector directions into low-bit representations, reducing the index footprint and memory traffic during graph traversal at the cost of an approximate comparison. Here each component uses four bits, shown as SQ4 in the interface, and sq_training_samples is configured at 25,000. Cosine distance matches the embedding model. CREATE INDEX shipments_embedding_diskann_idx ON horizon_ship.shipments USING diskann (embedding vector_cosine_ops) WITH ( spherical_quantized = true, sq_bits = 4, sq_training_samples = 25000 ); AI Model Management and azure_ai Both aliases are registered with HorizonDB AI Model Management (AIMM). The default-embedding alias resolves to text-embedding-3-small with 1,536 dimensions, and default-chat resolves to gpt-5.4 . Using aliases keeps the SQL and application code independent of the underlying model deployment details. The azure_ai extension provides the in-database model integration used by both paths: CREATE EXTENSION IF NOT EXISTS azure_ai CASCADE; Setup calls azure_openai.create_embeddings to create each row's embedding inside the database. The prompt-only agent later calls azure_ai.generate through its Agent Framework adapter. The embedding input uses format() with field labels, giving the model the business role of each value instead of an unlabeled sequence of words: UPDATE horizon_ship.shipments AS shipment SET embedding = azure_openai.create_embeddings( 'default-embedding', format( 'Title: %s. Description: %s. Origin: %s. Destination: %s. ' 'Current location: %s. Status: %s. Metadata: %s.', shipment.title, shipment.description, shipment.origin_name, shipment.destination_name, shipment.current_location_name, shipment.status, shipment.metadata::text ) )::vector(1536) WHERE ...; The application does not move embeddings between services, and no separate vector store is involved. Two paths, one repository The interface shown above has three panes: a criteria workbench on the left, a shared map in the center, and a prompt-only assistant on the right: Criteria workbench (left) Explicit status, ETA, and radius filters Calls POST /api/search This is a deterministic form, not a chat Agent assistant (right) Natural-language question only Calls POST /api/chat Agent Framework lets gpt-5.4 infer tool arguments The important design decision is that both paths call the same repository method, semantic_search . The criteria path fills in the filters from the form. The agent path fills them in from what the model inferred. Nothing from the left form leaks into the agent request, and the agent request contract enforces that: the /api/chat model forbids extra fields, so posting status or radius to it returns HTTP 422 before Agent Framework even runs. Here is the shared query, exactly as the repository builds it. The %s placeholders are bound with parameters. The criteria path supplies real values, while the agent path passes NULL for the filters it did not infer. -- 1. Embed the query text in the database, using the same model -- (default-embedding) that produced the row embeddings. WITH query_vector AS ( SELECT azure_openai.create_embeddings( %s, -- embedding model alias %s -- query text )::vector(1536) AS embedding ), -- 2. Retrieve candidates. MATERIALIZED forces this CTE to run once and -- be reused, so the vector distance is computed a single time. candidates AS MATERIALIZED ( SELECT s.shipment_number, s.title, -- ... projected columns, PostGIS points unpacked with ST_X / ST_Y ... -- 2a. Cosine distance between the row and the query embedding. s.embedding <=> query_vector.embedding AS vector_distance, -- 2b. Great-circle distance in km to the map center, only when a -- center was supplied (otherwise NULL). CASE WHEN %s::double precision IS NULL THEN NULL ELSE public.ST_Distance( s.current_position::public.geography, public.ST_SetSRID( public.ST_MakePoint(%s, %s), 4326 )::public.geography ) / 1000.0 END AS distance_km FROM horizon_ship.shipments AS s CROSS JOIN query_vector -- 2c. Optional filters. Each is "parameter IS NULL OR <condition>", -- so an unused filter drops out and the planner can ignore it -- (the application sets plan_cache_mode to force_custom_plan). WHERE (%s::text IS NULL OR s.status = %s) -- status AND ( -- ETA window %s::date IS NULL OR s.eta BETWEEN %s::date - (%s * INTERVAL '1 day') AND %s::date + (%s * INTERVAL '1 day') ) AND ( -- PostGIS radius %s::double precision IS NULL OR public.ST_DWithin( s.current_position::public.geography, public.ST_SetSRID( public.ST_MakePoint(%s, %s), 4326 )::public.geography, %s * 1000.0 ) ) -- 2d. Order by cosine distance and cap the list. This is the step -- DiskANN serves: nearest neighbors first, then LIMIT. ORDER BY s.embedding <=> query_vector.embedding LIMIT %s ) -- 3. Score and rank. Pure cosine similarity when there is no radius, -- otherwise a 72% semantic / 28% spatial blend. SELECT candidates.*, 1 - vector_distance AS similarity, CASE WHEN distance_km IS NULL THEN 1 - vector_distance ELSE 0.72 * (1 - vector_distance) + 0.28 * GREATEST(0, 1 - distance_km / %s) END AS hybrid_score FROM candidates ORDER BY hybrid_score DESC LIMIT %s; </condition> A few things are worth pointing out. The query embedding is created inside HorizonDB with azure_openai.create_embeddings , so the same model that embedded the rows also embeds the query, on the same connection. Each optional predicate is written as %s IS NULL OR , so an unused filter disappears from the effective query and the planner is free to ignore it. The inner ORDER BY ... <=> ... LIMIT keeps cosine distance as the candidate-retrieval step, which is what lets DiskANN serve it. The outer query then produces a hybrid score: pure cosine similarity when there is no radius, and a 72% semantic / 28% spatial blend when a radius is present. Why 72% semantic and 28% spatial The split is a tunable product choice, not a mathematical constant. Both terms are normalized from 0 to 1. Because ST_DWithin already removes rows outside the radius, semantic relevance leads among the eligible shipments and the 28% spatial term rewards proximity. Without a radius, the score is pure cosine similarity. Because the two paths share this query, the only thing that changes between them is which parameters are NULL . That is what makes the execution plans interesting: the same SQL shape produces two very different plans depending on how selective the filters are. Path one: criteria search For the first search I ask for cold-chain medicine for clinics, select the exception status, center the map near Dakar in West Africa, and choose a 3,000-kilometer radius. This is a highly selective request. In the sample data it returns exactly one row: SHIP-0007, Cold-Chain Vaccines. The cosine similarity is 0.56 and the hybrid score is 0.69. No model reasoning is needed to interpret those explicit filters. The application does not force an index. Every runtime SELECT is first run through EXPLAIN (ANALYZE, BUFFERS, WAL, FORMAT TEXT) , and the plan is retained alongside the literalized SQL. For this selective request, the planner does not touch the vector index at all. It combines the status B-tree and the PostGIS geography GiST index with a BitmapAnd , feeds one row into a Bitmap Heap Scan, and rechecks ST_DWithin there: -> Bitmap Heap Scan on shipments s (actual time=21.684..21.687 rows=1 loops=1) Recheck Cond: (status = 'exception'::text) Filter: st_dwithin((current_position)::geography, '...'::geography, '3000000'::double precision, true) Heap Blocks: exact=1 -> BitmapAnd (actual time=0.020..0.020 rows=0 loops=1) -> Bitmap Index Scan on shipments_status_idx (actual time=0.007..0.007 rows=2 loops=1) Index Cond: (status = 'exception'::text) -> Bitmap Index Scan on shipments_current_position_geography_gix (actual time=0.012..0.012 rows=3 loops=1) Index Cond: ((current_position)::geography && _st_expand('...'::geography, '3000000'::double precision)) This is the right call. The status B-tree returns two candidate rows, the geography GiST index returns three, and the BitmapAnd intersects them. The ST_DWithin recheck on the heap confirms the single match. Resolving that with relational and spatial selectivity is far cheaper than an approximate nearest-neighbor scan, and the whole query ran in about 22 ms. The vector distance is still computed in the outer query to produce the similarity and hybrid score, but it is not driving the access path. The SQL pane shows every literal, prompt, status, coordinates, and radius, so the operator can see exactly what was asked and how it was answered. Note that the GiST index scan uses the && bounding-box operator against _st_expand(...) , which is the index-friendly part of ST_DWithin . The exact distance test is then applied as the recheck, so the spatial predicate is both index-accelerated and exact. The application shows the same thing as a graph, with the literal SQL beside it. The BitmapAnd and its two bitmap index scans are visible as one flow, and the SQL pane highlights each user-supplied literal: Path two: the prompt-only agent For the second search I clear the left criteria and just ask the assistant: "Which delayed shipments need attention?" The request body contains only that question. Behind that, Microsoft Agent Framework runs a bounded two-turn loop while model inference stays inside HorizonDB. On the first turn, gpt-5.4 is asked, through azure_ai.generate , to return JSON arguments for a single registered tool, search_shipments . The model chooses delayed as the status and rewrites the intent to something like "shipments needing attention". Agent Framework validates those arguments and invokes the tool exactly once. That tool calls the same semantic_search method, with the model-chosen status and no spatial or ETA filter. On the second turn, the model receives only the serialized result rows and writes the grounded answer. The client caps the run at two model iterations and one function call, so the orchestration stays predictable. The tool is a plain typed function. The framework reads its schema from the annotations: @tool( name="search_shipments", description=( "Search live shipments by meaning and optional status. HorizonDB retrieves " "candidates with spherical-quantized DiskANN and returns ranked evidence." ), max_invocations=1, ) async def search_shipments(query_text: str, status_filter: StatusArgument = "all") -> str: ... This time the filter is not selective enough to win as a bitmap, so the planner takes the vector path. Before running a filtered vector query, the repository enables DiskANN's strict iterative search and filter hook in a transaction-local scope: SET LOCAL diskann.iterative_search TO 'strict_order'; SET LOCAL diskann.enable_filter_hook TO 'true'; SET LOCAL diskann.selectivity_min TO '0.0'; SET LOCAL diskann.selectivity_threshold TO '1.0'; SET LOCAL diskann.filtering_beta TO 0.85; SET LOCAL diskann.l_value_is TO 300; The plan is now a custom DiskANN scan. Strict iterative search applies the delayed filter and then vector ordering, collecting exactly the tuples that match: -> Custom Scan (DiskANNFilteredScan) (actual time=0.942..0.967 rows=3 loops=1) Strategy: Filter(SeqScan) -> Vector Rows Retrieved: 3 count TIDs Collected: 3 count The strategy line reads Filter(SeqScan) -> Vector : the delayed filter is applied first, then the vector index orders the survivors. It collected three tuple identifiers and retrieved three rows, and the whole statement ran in about 1.2 ms. Those three rows, Electric Vehicles, Apparel and Textiles, and Lithium Batteries, are the same rows that appear as cards in the answer, in the left-hand list, and on the map. The query pane exposes the model-selected semantic phrase and the cosine operator, so the vector path is as inspectable as the relational one. Filtered vector search is exactly what a separate vector store tends to hide. Here it stays in the plan. The plan graph makes the strategy explicit. The Query + plan button on the agent turn opens the exact SQL the model produced, "shipments needing attention" highlighted, next to the DiskANNFilteredScan node with its strategy and TID count: Both plans come from the identical query. The criteria request was selective, so the planner chose BitmapAnd over the status B-tree and geography GiST. The agent request was broad, so the planner chose DiskANNFilteredScan and let the vector index order the candidates. That is the payoff of keeping one query and one dataset: the planner adapts to the shape of each question instead of the application hard-coding an access path. The two plans do the same thing under the hood These two access paths look different in the plan, but they are solving the same problem the same way: reduce the table to the set of rows that satisfy the predicates, expressed as tuple identifiers (TIDs), the physical (block, offset) addresses of rows. In the criteria plan, each index produces a bitmap of TIDs. The status B-tree contributes the TIDs of exception rows, the geography GiST index contributes the TIDs whose bounding box intersects the radius, and BitmapAnd intersects the two bitmaps into the TIDs that satisfy both. The heap is then visited for exactly those TIDs and the exact ST_DWithin is rechecked. The predicates are resolved first, then the rows are fetched. The DiskANN filtered scan does the equivalent, but in the opposite order and against a graph. Rather than ordering by distance and hoping the top results happen to be delayed , strict iterative search evaluates the filter during graph navigation: as it walks the nearest-neighbor graph it keeps only the TIDs that pass the delayed predicate, and keeps walking until it has collected enough matches in nearest-first order. That is what Filter(SeqScan) -> Vector and TIDs Collected: 3 describe, the filter builds the set of eligible TIDs, and the vector index visits them in similarity order. So a bitmap index scan and a pre-filtered ANN search are two implementations of one idea: build the set of TIDs that match the predicates, then combine it, by bitmap intersection in one case, by filtering the candidates during navigation in the other. This is exactly the capability a separate vector store usually lacks. A pure HNSW index, for instance, orders by distance with no way to intersect a relational predicate into the walk, so it either over-fetches and filters afterward or misses matches. Keeping the vectors in the same table as the relational and spatial columns is what lets one predicate feed the other. A note on inspectability Every runtime SELECT in this sample is executed twice on purpose. The backend first runs it under EXPLAIN (ANALYZE, BUFFERS, WAL, FORMAT TEXT) to capture the real plan with buffer and WAL statistics, then runs the same statement to fetch rows. That is a demonstration choice, not something you would do in production, but it means every result carries the literal SQL and the plan that produced it. Each agent answer keeps its own plan snapshot too, so the Query + plan control still shows that turn's SQL and plan even after a later criteria search runs. Because EXPLAIN ANALYZE runs the statement, the model-backed statements run twice as well. Takeaways This started as a practical customer question: show PostGIS on HorizonDB, then combine location with AI in something that looks like a real development stack. The result is one operational database with two trustworthy ways to ask. When the operator knows the criteria, the left workflow keeps status, time, and geography deterministic, and the planner resolves it with B-tree and GiST bitmaps. When the intent is conversational, gpt-5.4 gets one controlled Agent Framework tool over the same repository, and the planner serves it from spherical-quantized DiskANN. In both cases the rows, scores, SQL literals, and planner decisions stay visible. Relational data, PostGIS geometry, pgvector embeddings, and AI model calls all live in the same HorizonDB instance, so there is no second store to synchronize and no retrieval hidden behind an opaque service. The pattern starts with shipment tracking but transfers directly to fleet, taxi, bus, and security dispatch, anywhere service intent and proximity matter together. If you want to try HorizonDB capabilities like these, the PostgreSQL Hub has sample applications and learning paths, and the PostgreSQL Developer Forum is the best place to share feedback and ask questions.285Views1like0Comments
Postgres Skills: Give Your AI Agent PostgreSQL Expertise
Modern application development increasingly relies on AI agents to generate code, configure services, and accelerate delivery. But generic agents often stop at plausible SQL or broad recommendations. They do not reliably inspect the live database, account for PostgreSQL versions and extensions, distinguish self-hosted from managed environments, apply production guardrails, or verify that a change actually works. That gap matters when database decisions affect security, performance, availability, and customer experience. A syntactically correct query can still create an isolation issue, use an incompatible feature, recommend an unsupported managed-service command, or leave an application with a design that does not scale. The solution: PostgreSQL Skills PostgreSQL Skills closes this gap by giving agents the PostgreSQL expertise, live context, execution tools, and validation workflow needed to turn a generic answer into a safe, production-ready outcome that solves the application’s business problem. Its 32 expert sub-skills support PostgreSQL running locally, self-hosted, or on any cloud; Azure Database for PostgreSQL and HorizonDB. The plugin includes postgres-mcp for live database access and Azure CLI integration for managed-service operations. One install works across GitHub Copilot CLI, VS Code, Claude Code, and Codex CLI. Domain What you can do PostgreSQL Anywhere Build vector search, partition tables, implement row-level security, index JSONB data, and analyze query regressions on local, self-hosted, or cloud deployments Azure Database for PostgreSQL & HorizonDB Provision and scale servers, configure HA/DR and PITR, use Entra ID authentication, plan major-version upgrades, and get HorizonDB (Preview) guidance You do not need to choose a sub-skill or tell the agent which rules apply. The plugin checks your environment and routes each request to the guidance that fits your deployment. Live database context and PostgreSQL expertise, together The included postgres-mcp server gives your agent structured access to the database you are using. It can inspect schemas, roles, extensions, and server capabilities, run queries, and apply changes you approve. This grounds the work in live database state instead of assumptions. The sub-skills guide how the agent uses that access. They define what to check, which rules apply to your deployment, when to ask for confirmation, and how to validate the outcome. Together, postgres-mcp and the sub-skills help the agent move from a generic answer to a change that fits your database and has been verified. Try it yourself Choose a host and follow the setup path for your operating system. Install your host Add the marketplace and install PostgreSQL Skills GitHub Copilot CLI copilot plugin marketplace add microsoft/postgres-skills copilot plugin install postgres-skills@postgres-skills copilot plugin list # confirm postgres-skills is active Claude Code /plugin marketplace add microsoft/postgres-skills /plugin install postgres-skills@postgres-skills /plugin # confirm the plugin appears as installed Codex CLI codex plugin marketplace add microsoft/postgres-skills codex plugin add postgres-skills codex plugin list # confirm postgres-skills is active See it work: three developer scenarios PostgreSQL anywhere: enforce tenant isolation Prompt: "Add row-level security so each tenant can only access its own data." A generic agent with SQL access can write a CREATE POLICY statement. But it may not inspect table ownership, BYPASSRLS roles, existing policies, or how your application establishes tenant context. The policy can look correct while still leaving an isolation gap. With PostgreSQL Skills, the agent inspects the live schema and role model, identifies the tenant key, accounts for owner bypass behavior, and proposes the policy against your actual tables. It asks before enabling RLS, then tests allowed and denied access with representative roles. You get a verified security boundary, not just policy syntax. PostgreSQL application development: build hybrid search Prompt: "Add semantic and keyword search to my product catalog." A generic agent can generate a pgvector query and a full-text search query. It still leaves you to reconcile two result sets, choose compatible indexes, and adapt the example to your schema and PostgreSQL version. With PostgreSQL Skills, the agent inspects your catalog schema and extension availability, designs the embedding and text-search columns, creates the appropriate indexes, and combines both signals with reciprocal rank fusion. It runs the search against your data and verifies the result before calling the implementation complete. Azure PostgreSQL: connect an application without passwords or public access Prompt: "Connect my application to Azure Database for PostgreSQL without passwords or public internet access." A generic agent with Azure CLI access may provide the right ingredients: Entra authentication, a managed identity, and a private endpoint. It may not check which server is targeted, whether private networking is already configured, how the application identity maps to PostgreSQL, or whether disabling an existing authentication path will break deployed applications. With PostgreSQL Skills, the agent confirms the Azure connection and discovers the server, subscription, resource group, networking mode, and current authentication configuration. It identifies the application identity, proposes a private and passwordless connection plan, and explains every Azure and PostgreSQL object that will change. It asks before modifying identity, authentication, or network access, validates token-based connectivity, and leaves existing access in place until you confirm it can be removed. Guardrails for safe execution Acting on a database is only useful if it is safe on any host. One rule is universal: Every destructive or non-reversible action is confirmed with you first. This applies without exception on self-hosted and Azure deployments. If you're connected to Azure, three more rules kick in automatically: Azure guidance uses `azure_pg_admin`, never `SUPERUSER`. It never assumes access that the managed service does not grant. No `ALTER SYSTEM` and no OS-level access on Flexible Server. Azure changes go through az ... parameter set, matching how the service actually works. Connection-aware gating. Azure-only guidance loads only after the live connection confirms isAzure: true. It never guesses your environment or applies Azure rules to a database that is not one. Get started Repo: github.com/microsoft/postgres-skills. Visit the PostgreSQL Skills repository for installation commands, usage examples, and contribution guidance. Explore the open-source collection of PostgreSQL skills for AI coding agents, including installation commands, usage examples, and contribution guidance. Contribute: Follow CONTRIBUTING.md to add a reference file, register its triggers in the routing table, run the validation checks, and submit a pull request. Feedback: open an issue on the repo with what you tried and what broke The takeaway: generic agents can produce plausible database code, but solving real application problems requires PostgreSQL expertise, live environment context, production guardrails, and validation. PostgreSQL Skills brings those capabilities together so your agent can move beyond suggesting an answer to delivering a safe, deployment-aware, and verified outcome.1.3KViews2likes0CommentsSmarter Storage for Azure HorizonDB
A key benefit of Azure HorizonDB comes from its smart storage layer, which works seamlessly with Postgres and takes over durability and high availability work typically done by Postgres itself. This frees Postgres to operate as a stateless compute engine focused on running queries and transactions leaving more CPU, disk, and network bandwidth available for your application’s business logic. For example, HorizonDB’s storage layer handles work such as replicating WAL to read replicas and archiving WAL to blob storage for point-in-time restore. PostgreSQL also no longer needs full-page writes or background dirty-page flushing, that work is handled by the storage layer. The rest of this post explains the storage architecture that enables this division of responsibility. HorizonDB Storage Overview HorizonDB’s storage design is similar to that of Socrates. The write‑ahead log (WAL) is the sole mechanism used to persist writes to storage (Orange in Figure 1). PostgreSQL compute nodes never write data pages to storage directly in HorizonDB (blue in Figure 1). Instead, pages and other on‑disk structures are treated as derived state and are reconstructed by the storage layer from WAL records. Each Postgres instance in a cluster shares the same copy of the data pages in storage (blue “Page Reads” arrow in Figure 1). A Postgres read replica doesn’t need to maintain its own copy of WAL and data pages as in a typical Postgres setup with a hot standby or readable secondary. Figure 1 - HorizonDB WAL and Page Storage HorizonDB uses separate storage services for WAL and data pages. This separation allows each to be specialized for the very different patterns of reads and writes for WAL versus pages. The WAL server is optimized for low latency writes to the tail of the log stream and reads often at or near the tail. The page server is optimized for elastic storage of potentially many terabytes of pages and it must support random reads and writes of pages. This specialization improves query performance as we have demonstrated in the past. Moving Work into Storage Figure 2) shows the work Postgres does in a typical configuration with high availability, backups and WAL archiving configured. The Postgres primary is doing the work to send WAL to the secondary, and archive WAL to blob storage. The primary and secondary nodes both maintain their own complete copies of the data. Figure 2 - Postgres without Smart Storage Figure 3) shows where the equivalent work is done by HorizonDB storage. The primary and secondaries share one copy of the data in storage in this design. Figure 3 – HorizonDB storage offloading work from Postgres Some example work HorizonDB storage is now doing in Figure 3. The work usually done by the Postgres walsender and archiver processes to send WAL to standbys\secondaries or to WAL archive (blob storage) is now done by HorizonDB’s WAL servers in Figure 3) instead of by Postgres as in Figure 2). In HorizonDB, Postgres secondaries don’t ever communicate directly the with primary. When Postgres starts up, it no longer needs to redo WAL to bring stale page content up to date speeding up startup times. HorizonDB’s page servers in Figure 3) take care of page recovery for Postgres and can send it any pages it needs on demand. The Postgres checkpointer and background writer no longer need to write dirty pages to disk. The page server handles this work. Both Postgres primary and any secondaries can retrieve the page versions they need from the page servers. HorizonDB page servers protect against torn pages making Postgres Full page writes unnecessary reducing the amount of WAL generated and improving write throughput. On read replicas, HorizonDB only requires redo of WAL onto pages that the read replica has stored in memory already saving the work to persist the WAL and redo it. HorizonDB read replicas don’t maintain their own private copy of the data, so redo is only used as a mechanism to keep their in-memory copy in sync with the primary. Tables 1) and 2) below summarize the Postgres processes whose work moved into HorizonDBs storage layer. Task Resource Savings Postgres Process Moved WAL sending to Postgres replicas Disk IO, Network IO walsender WAL archiving to blob storage Disk IO, Network IO archiver WAL filtering CPU, Network IO Shared Storage Specific (*) Dirty Page Writing Disk IO background writer Checkpointing Disk IO checkpointer PostgreSQL WAL recovery Disk IO, CPU startup recovering PostgreSQL read replica redo Disk IO, CPU startup recovering PostgreSQL read replica shared storage (read replicas share storage with primary Disk IO Background writer, checkpointer Backups Disk IO pg_dump, pg_basebackup, pg_backup_start, pg_backup_stop Full page writes Disk IO Backends doing WAL writing Hot standby feedback Vacuum accuracy walreceiver Task HorizonDB Storage Component Responsible WAL sending to Postgres replicas WAL Service WAL archiving to blob storage WAL Service WAL filtering WAL Filtering Service Dirty Page Writing Page Server Checkpointing Page Server PostgreSQL WAL recovery Page Server PostgreSQL read replica redo Page Server PostgreSQL read replica shared storage Page Server Backups WAL Service and Page Server Full page writes Page Server Hot standby feedback WAL Filtering Service (*) Table 1) and 2) refer to HorizonDB’s WAL filtering service. We haven’t talked about this service yet. It’s responsible for sharding the WAL stream across many page servers. To store 10s of TBs of data the page servers shard that data out across many machines. The WAL filtering service takes as input the full WAL stream and shards it into the parts that apply to each page server shard, sending only the WAL that applies to a given shard to that shard (reducing network amplification). Some other shared storage OLTP databases do this WAL filtering on the compute VM, within or alongside Postgres, incurring non-trivial CPU use and higher tail latencies on WAL writes. In summary, by moving durability, recovery, and replication into a purpose-built storage layer, HorizonDB simplifies Postgres while freeing up compute resources for query execution. The result is higher throughput, faster recovery, and lower cost, without compromising the familiar Postgres programming interface.882Views2likes0CommentsWhy PostgreSQL Still Inspires Builders
The PostgreSQL project turned 30 years old in July. As it enters middle-age, developers and builders rely on it more today than ever. In the crowded and competitive SQL database market, what is driving this popularity? PostgreSQL is a great fully featured database, but it’s not clearly better than the alternatives (SQL Server, MySQL, Oracle) on performance benchmarks or in feature-by-feature comparisons. Its popularity stems from other factors: the community’s focus on reliability and stability, and its open governance and lenient licensing. Together these qualities of PostgreSQL have spawned an ecosystem of extensions and forks built around its stable core. A stable open core My claim that PostgreSQL is more reliable than other databases is based on my experience and not on any hard data. I don’t know of any rigorous study on the count and severity of regressions in new releases of different database engines. Companies love to show off their TPC-C benchmark performance numbers, but we don’t have such an easily measurable metric for reliability. I’ve written code for a few different database engines in my engineering career (SQL Server, MemSQL/Singlestore in the MySQL ecosystem, and Azure HorizonDB in the PostgreSQL ecosystem). Of those, PostgreSQL is on the more conservative, careful and rigorous end of the engineering spectrum. The PostgreSQL committers may move a little more slowly when adding new features, but they move with great care. PostgreSQL’s open and independent governance model prevents a single company from dominating its evolution. That said, large companies such as Microsoft and Amazon employ teams of engineers whose job is writing open-source PostgreSQL engine code (not working on proprietary closed source forks for their respective companies). Application developers have learned to expect a steady stream of new features year after year as a result. PostgreSQL can run on a laptop, your own server running a variety of different operating systems, or on any of a dozen different PostgreSQL cloud services (see Table 1 below). It’s the database that gives builders the most choice and least single vendor lock-in. Built to extend and fork The PostgreSQL source code is also an important building block in many PostgreSQL derived databases and services. Folks building applications in the PostgreSQL ecosystem have a broad choice of vendors and systems. PostgreSQL’s permissive license makes it the most forked open-source database engine. There are forks that specialize in data warehousing, distributed SQL and cloud native OLTP. Its code base is a building block generating billions in revenues across the global economy for various companies. The table below shows some of the PostgreSQL compatible databases or services in production today. They include more specialized forks built to handle use cases that community Postgres is not as good at (i.e., data warehousing) as well as services that run mostly unmodified Postgres as a cloud service. The databases in bold are available on Azure. Category Product/Service Name Compatibility Cloud Native OLTP Azure HorizonDB, AWS Aurora PostgreSQL, Google AlloyDB, Neon, PolarDB PostgreSQL forks designed to run on top of specialized WAL and page storage services enabling lower latency writes, faster failovers, storage auto grow/shrink, efficient read scale out etc. Managed OLTP Services Azure Database for PostgreSQL AWS RDS PostgreSQL, Google CloudSQL PostgreSQL, Supabase, Crunchy Data Run mostly unmodified PostgreSQL as a service attached to off-the-shelf cloud storage (managed disks) and virtual machines Distributed SQL extensions or forks CitusDB (Azure PostgreSQL Elastic Clusters), YugabyteDB, Aurora DSQL, Aurora Limitless Shard data across a cluster of machines with a PostgreSQL compatible distributed query layer on top enabling read and write scale out. Distributed SQL with Postgres compatibility Google Spanner, CockroachDB These are not Postgres forks, but are sharded databases that aim for PostgreSQL query and wire compatibility Data warehousing extensions or forks Greenplum, ParAccel (powers AWS Redshift), Aster Data, TimescaleDB Postgres forks that add parallel query processing and column stores for data warehousing Document database forks or extensions Azure DocumentDB, FerretDB MongoDB compatibility layer on top of Postgres storage Table 1 – Postgres based databases or services; Not an exhaustive list. For more see PostgreSQL derived databases - PostgreSQL wiki No other open-source database has as many successful product offerings based on its source code or its query and wire protocols. MySQL would be a distant second place as far as number of derived databases or services. The databases listed above aren’t all fully compatible with community PostgreSQL, but many are highly compatible. Postgres on Azure At Azure, we’ve built three services around PostgreSQL shown in bold in Table 1 Azure Database for PostgreSQL runs Postgres on Azure virtual machines and Azure managed disks managing backups, high availability, and geo-replica’s as needed. It offers the Citus extension (via the Elastic Clusters configuration) to shard data across a cluster of Postgres worker machines to scale out writes and reads as needed. Azure HorizonDB extends the core PostgreSQL engine with a custom storage layer that has specialized WAL and page services improving performance, reliability and scalability. It frees up Postgres to run queries and transactions by pushing the work to make data durable and highly available into the storage layer (replication, checkpointing, WAL archival, etc.). Azure DocumentDB gives customers the option to build apps against a MongoDB compatible service on top of PostgreSQL’s solid foundation. So, thank you to the PostgreSQL developers (and community) for the hard work they’ve put in over three decades. The family of Postgres derivative or compatible databases wouldn’t exist with their foundational work. Choosing Postgres gives builders the confidence they’re building on a mature, reliable and flexible foundation. Who knows where a new fork or extension may take Postgres in the future. About PostgreSQL Perspectives PostgreSQL Perspectives is a monthly blog series featuring insights from Microsoft engineers, contributors, and builders working with PostgreSQL. Explore more articles on the Microsoft for PostgreSQL blog.575Views4likes0CommentsAI-assisted Oracle-to-PostgreSQL schema conversion in Visual Studio Code
By AI Omar Rajawat, Pranay Lohia, Gautam Juneja, Vikas Nimmagadda, Anil Dogra, Aditya Duvuri We’re seeing significant interest in migrating database workloads from Oracle to Azure Database for PostgreSQL. Historically, schema conversion has been one of the most technically challenging and expensive steps in that journey, demanding specialist knowledge of both engines and stretching migration timelines before a single row of data moves. Recent advances in AI-assisted schema conversion are changing that, turning what used to be a long, manual effort into a faster, more accessible, and lower-cost proposition. This post looks at what that shift means in practice for teams moving to Azure Database for PostgreSQL flexible server. Oracle schema conversion is where the complexity of translating schema and code objects to PostgreSQL becomes visible. Packages, procedures, triggers, custom types, and dependencies built up over years must be mapped to PostgreSQL-compatible definitions while preserving the relationships that make the schema work. Generally available since May 2026, the feature is built into the PostgreSQL extension for Visual Studio Code, published by Microsoft. It helps teams convert Oracle schema and code objects — tables, views, constraints, packages, procedures, functions, and triggers — into PostgreSQL-compatible definitions for Azure Database for PostgreSQL flexible server, with no separate conversion utility to install and no disconnected workflow to manage. It brings schema discovery, conversion, compile validation, and review into one project-based experience. Teams can connect to Oracle, select schemas, and configure a Microsoft Foundry connection in the same project. The extension then translates Oracle-specific constructs, compiles and syntax-checks converted DDL into scratch schemas on Azure Database for PostgreSQL flexible server and surfaces unresolved items as review tasks that teams can work through with GitHub Copilot agent mode. Why schema conversion deserves a better workflow Traditional conversion tools can produce a useful first pass, but the long tail of the process is rarely solved by generating replacement DDL alone. Teams still need clear answers to practical questions: What converted successfully? What needs attention? Which Oracle constructs require a PostgreSQL design decision? Which items should be reviewed first? We designed the schema conversion experience around those questions. The goal is not to hide complexity behind a single score. It is to help teams make steady progress while keeping the work visible and reviewable. What the schema conversion experience provides The experience guides teams through a schema conversion project rather than a collection of separate scripts. It discovers the selected Oracle schemas and converts both the relational model and the code that runs on it: tables, indexes, sequences, primary key, unique, check and foreign key constraints, views and materialized views, synonyms, and Oracle object types — along with the PL/SQL that is usually the hardest part of the migration. Packages and package bodies, package-level state, standalone procedures and functions, and triggers are translated into PostgreSQL functions, procedures, and trigger functions. Oracle-specific constructs are mapped to PostgreSQL equivalents rather than dropped or stubbed out. REF CURSOR and SYS_REFCURSOR become PostgreSQL refcursor; CLOB and BLOB columns become text and bytea ; and NUMBER and VARCHAR2 are mapped by precision and length to their closest PostgreSQL types. Oracle date functions such as ADD_MONTHS, LAST_DAY, MONTHS_BETWEEN, and TRUNC are resolved through the orafce extension, which the project detects and flags for you before deployment. Every converted definition is compiled against scratch schemas on Azure Database for PostgreSQL flexible server, so the deployment script you end up with is an organized, dependency-ordered set of PostgreSQL SQL artifacts that has already been proven to build. Objects that still require human judgment are surfaced as review tasks. Teams can inspect the source and converted definitions side by side, work through the remaining items, and use GitHub Copilot agent mode for guided assistance — keeping automation and human review in the same workflow. How it works: the system architecture Under the hood, the conversion engine follows one principle — the language model is a single, bounded stage; it never has the first or the last word. Deterministic steps decide what the model sees and what it is allowed to produce. Deterministic in. Rule-based extraction reads the Oracle DDL and metadata, then a dependency-graph decomposition splits the estate into bounded, dependency-ordered chunks — so every object is converted in the context that keeps it correct. Bounded conversion. A tiered model strategy through the Microsoft Foundry connection translates each chunk with structured, contract-wrapped input and output. Even very large PL/SQL packages are split and converted member by member, so nothing is trusted as a monolith. Deterministic out. Converted objects pass through review, then compile-and-verify against scratch schemas on Azure Database for PostgreSQL flexible server, and finally dependency-ordered deploy assembly. Unresolved items become review tasks, and every object carries a per-object audit trail. A continuous-improvement loop closes the system: the engineering team maintains a versioned regression suite of supported conversion patterns, and an executable benchmark tracks regressions as the pipeline evolves. Proven in production The approach has been exercised on real enterprise estate. Across representative production runs totaling more than 60,000 schema objects; conversion reached roughly 98% overall — with several schemas converting at a full 100%. The hardest tail, PL/SQL package members, now compiles at 96% across more than 20,000 members thanks to targeted coverage and a resilient compile stage. Conversion outcome and review status are separate measures. Objects that convert and compile cleanly are safe to deploy as they are; the rest are deliberately routed into a prioritized review queue rather than silently accepted. In a representative single-schema run, no object ended in a hard conversion failure, and a cleanly generated object can still involve a PostgreSQL design decision. That is the workflow operating as intended: automation absorbs the volume, and review tasks to keep the remaining judgment calls visible, ordered, and auditable. Measured, not asserted: the SchemaBench eval Quality is verified by running it. SchemaBench, the evaluation framework, deploys each converted schema to a live PostgreSQL database and probes real behavior — whether constraints still fire and whether objects still resolve — rather than comparing DDL text. It scores seven weighted dimensions: semantic fidelity, structure, constraints, completeness, performance, target idioms, and maintainability, behind hard gates. On the e-commerce benchmark, the strongest model scored 96.1 overall with 100% semantic fidelity and a ~98% behavioral-probe pass rate. Every failure a migration hits becomes a permanent regression test the next run has to pass. Learn more: Oracle to Azure Database for PostgreSQL schema conversion overview544Views5likes0Comments