azure hardware infrastructure
32 TopicsScaling distributed AI infrastructure with Azure’s ExpressRoute and AI Points of Presence (AI PoPs)
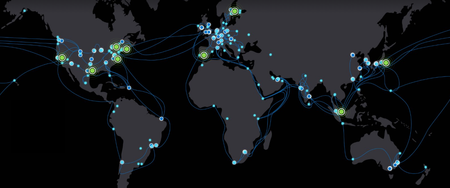
Rethinking connectivity for distributed AI infrastructure AI is changing more than the applications organizations build. It is reshaping where the infrastructure powering those applications is deployed. For years, cloud computing has been anchored by hyperscale regions that combine compute, storage, networking, security, and operations at massive scale. That model remains foundational to Microsoft Azure. At the same time, rapid AI growth is creating a more distributed infrastructure landscape. GPU capacity is increasingly being deployed across regions, providers, facilities, and operating environments wherever the right mix of power, space, cooling, and specialized infrastructure is available. That shift creates a practical challenge: how do organizations bring new GPU capacity online quickly while still giving AI workloads the Azure services, governance, security, and operational consistency they require? Microsoft’s approach: extending Azure to distributed AI infrastructure Microsoft is taking a platform approach to distributed AI infrastructure. For customers, Azure ExpressRoute offers the private connectivity experience for connecting remote sites and infrastructure to Azure. Behind that experience, AI PoPs provide Microsoft with a standardized infrastructure architecture for integrating distributed third-party GPU capacity into the Azure network and operating environment. Rather than building a unique network and operational integration for every external GPU deployment, Microsoft can use AI PoPs to onboard and aggregate GPU capacity wherever the GPUs may be, while customers continue to connect through familiar Azure networking products such as ExpressRoute. Azure ExpressRoute provides the private connectivity foundation for these customer-managed environments, enabling external GPU infrastructure to connect privately with Azure without traversing the public internet. Combined with the AI PoP architecture, this creates a repeatable model for integrating distributed GPU capacity with Azure, giving customers greater flexibility in where compute comes from while maintaining Azure as the platform connecting their AI environment. Based on current Microsoft deployment and provisioning data, Azure’s AI PoP operating model is already connecting and provisioning hundreds of thousands of GPUs across North America, Europe, and Asia Pacific, giving select preview customers a consistent Azure experience for using distributed AI infrastructure. The aim is simple: bring AI capacity to market faster, wherever it is located, while expanding the range of GPU providers and deployment locations. Customers receive a more consistent Azure experience regardless of where that capacity is located. Figure 1. Global deployment of Microsoft’s AI PoP infrastructure Microsoft is expanding AI PoPs to more than 10 planned sites across North America, Europe, and Asia over the next 12 months. Connecting distributed GPUs for faster connectivity and simpler operations for our customers AI workloads depend on more than chips. They need data, orchestration, identity, monitoring, security, and reliable high-bandwidth connectivity. ExpressRoute provides customers with private, high-bandwidth connectivity to Azure. Behind the scenes, AI PoP infrastructure helps Microsoft integrate and operate distributed third-party GPUs at scale. Together, this architecture can help customers: Connect privately to Azure: Use Azure ExpressRoute for private connectivity from remote sites and distributed infrastructure to Azure. Access distributed GPU capacity: Take advantage of GPU capacity across an expanding ecosystem of infrastructure providers without requiring customers to consume AI PoPs as a separate service. Use familiar Azure services: Connect workloads with Azure storage, orchestration, AI services, security, and operational tooling. Maintain a consistent Azure experience: Use established Azure networking and cloud services even as the physical GPU infrastructure becomes more distributed. For customers, this means less bespoke connectivity work and more focus on putting AI capacity to use. AI PoPs is part of the Microsoft infrastructure that enables Azure to integrate third-party GPU capacity into this experience, with ExpressRoute as a customer-facing service. For infrastructure providers, it creates a clearer path for integrating specialized GPU environments with the Microsoft Cloud. One Azure operating model, wherever AI capacity runs As GPU capacity becomes more distributed, customers should not have to adopt a new connectivity model for every provider or location. Azure ExpressRoute provides the customer connectivity experience, while AI PoPs give Microsoft a repeatable infrastructure architecture for integrating third-party GPU capacity into the Azure network and operating environment. That distinction matters as AI infrastructure spreads across regions and providers. Customers need flexibility in where capacity comes from, along with a reliable way to operate that capacity as part of a broader cloud environment. Microsoft is extending this model across regions to support Azure-connected AI capacity. The key principles behind the model are shown below (Figures 2–4). Figure 2. Example of aggregating capacity across multiple locations A single AI PoP can connect multiple GPU facilities and providers. Instead of treating each deployment as a unique project, new capacity can be onboarded through an established framework. This simplifies expansion, enables Microsoft to bring new capacity online faster, and makes it easier to scale as demand grows. Figure 3. Private connectivity to Azure services through Azure ExpressRoute and AI PoPs GPU capacity alone does not create an AI platform. Training and inference environments also depend on data, applications, orchestration, security, monitoring, and AI services. When GPU infrastructure sits outside Azure, the network becomes the critical bridge between compute and the Azure services it depends on. For customer-managed deployments, Azure ExpressRoute provides private connectivity between external infrastructure and Azure without sending traffic over the public internet. AI PoPs build on this connectivity model to provide a consistent approach for integrating distributed GPU environments with Azure services. Figure 4. AI PoPs deliver a consistent operating model Whether capacity is supplied by Microsoft, partners, or customers, AI PoPs are designed to provide a consistent connectivity and management experience. Standardization simplifies deployment, improves repeatability, and reduces the redesign required when introducing new providers or locations. Together, these design principles can reduce onboarding time, expand infrastructure choice, and provide a consistent Azure-connected experience. Looking ahead Demand for AI infrastructure continues to accelerate. Microsoft’s focus is not only on adding capacity, but also on making capacity available wherever it exists through a secure, reliable, and operationally consistent cloud platform. The next phase will focus on onboarding additional GPU providers, strengthening automation, and expanding Microsoft's ability to integrate distributed AI infrastructure with Azure. As AI PoP infrastructure scales behind Azure, customers can continue to use established Azure products such as ExpressRoute to privately connect remote sites and workloads, while gaining access to a broader ecosystem of distributed GPU capacity. As AI infrastructure becomes increasingly distributed, the ability to onboard capacity quickly, operate consistently across environments, and deliver a seamless Azure experience will become a meaningful differentiator. AI PoPs are one way Microsoft is helping shape that future.943Views1like0Comments
Catalyst: Frontier stories of AI Infrastructure innovation
In the Catalyst series, we explore the transformative power of AI by showcasing visionary companies driving scientific and industry breakthroughs powered by Azure and NVIDIA. This video series spotlights how innovation ignites action and how today’s visionaries are shaping tomorrow with the power of AI and cloud innovation. Building resilience against extreme weather Tomorrow.io turns space-based data into AI-driven forecasting powered by Azure and NVIDIA at a global scale. Its high-performance AI models deliver real-time weather intelligence that helps governments and enterprises anticipate disruption, optimize operations, and act faster in the face of severe events. Expanding access in preventative healthcare Powered by Microsoft Azure and NVIDIA, Helfie uses multimodal AI to transform smartphone selfies into intelligent health screening at scale. By combining advanced models with real-time inference, it delivers rapid biometric insights that help identify risks earlier and expand access to remote and underserved communities. How AI is mapping the tree of life Powered by Azure and NVIDIA to build the world’s largest biological databases, Basecamp Research is decoding the complexity of biology to accelerate scientific breakthroughs. Building the next frontier of data Powered by Microsoft Azure and NVIDIA, Global Objects is digitizing the real world by creating high-fidelity digital twins of over 5 million physical items. These photorealistic 3D models are transforming immersive content creation across Hollywood, gaming, robotics, and cultural preservation. Changing how doctors diagnose diseases with AI Powered by Microsoft Azure and NVIDIA, Pangaea Data is closing care gaps by identifying untreated and under-treated patients across rare and hard-to-diagnose diseases faster, earlier, and more accurately. Learn more The Catalyst series explores how organizations are using AI infrastructure to tackle some of their most complex technical and business challenges, from accelerating scientific discovery to advancing autonomous systems and transforming core industries. Learn more about Catalyst. Learn more about Azure AI infrastructure.214Views2likes0CommentsExpanding access to specialized GPU infrastructure through Dapple and Azure
Enterprise AI has entered a new phase. For much of the past decade, the challenge was building enough compute for machine learning. Today, organizations need platforms for foundation model training, fine-tuning, large-scale inference, agentic systems, and enterprise AI. As these workloads grow in scale and sophistication, the infrastructure supporting them is undergoing a fundamental transformation. The defining characteristic of modern AI infrastructure is no longer compute alone. It is topology. Training state-of-the-art AI models requires coordinated communication across hundreds or thousands of accelerators. Performance increasingly depends on how GPUs are interconnected, how data moves across the network fabric, and how efficiently distributed systems synchronize at scale—making network architecture as critical as compute performance. This shift is driving purpose-built AI infrastructure built around tightly coupled GPU fabrics, accelerated networking back-end interconnects, specialized storage architectures, and operational models that treat physical topology as a first-class concern. The challenge is turning this infrastructure into AI production without creating a separate operational domain or adding complexity for platform teams, application developers, and infrastructure operators. A new approach to scaling purpose-built AI infrastructure Microsoft is expanding access to purpose-built GPU capacity through infrastructure partners, including Dapple. Customers can use this specialized infrastructure within the Azure environment they already rely on to operate and govern their workloads. Through our collaboration, Dapple’s dedicated, topology-aware GPU infrastructure (Dapple Private AI Cloud | Microsoft Marketplace) is integrated into an Azure-native operating model that preserves Azure governance, security, and operational consistency. This model for purpose-built AI infrastructure can benefit any organization running compute-intensive AI workloads, including large-scale pre-training, fine-tuning, and distributed inference. Why purpose-built AI infrastructure matters AI workloads place demands on infrastructure that differ fundamentally from traditional enterprise applications. Conventional cloud architectures support a broad range of workloads across diverse infrastructure pools. Large-scale AI training environments, by contrast, depend on highly deterministic infrastructure characteristics, including GPU proximity, network topology, bandwidth consistency, and low-latency communication across thousands of accelerators. As model sizes continue to grow, the efficiency of the underlying GPU fabric becomes a critical determinant of training performance, infrastructure utilization, and overall time-to-results. For this reason, many AI deployments are increasingly built around purpose-designed GPU clusters featuring: Fixed infrastructure topology Dedicated InfiniBand fabrics High-bandwidth, low-latency communication paths Topology-optimized storage architectures Rack-scale and cluster-scale operational boundaries These systems are designed as integrated AI platforms rather than collections of independent compute nodes. Purpose-built GPU infrastructure is organized around validated cluster blocks: groups of compute, network, and related resources managed as a single topology, readiness, and maintenance boundary within InfiniBand fabric domains. Kubernetes nodes remain workload-scheduling objects, while cluster blocks represent the infrastructure unit on which distributed-job performance and availability depend. Figure 1 highlights an important distinction between traditional cloud infrastructure and modern AI systems. In conventional environments, compute resources are often treated as interchangeable units. Distributed AI workloads operate differently. GPU placement, rack boundaries, InfiniBand connectivity, and cluster block relationships can directly influence training throughput, communication efficiency, and overall job completion time. Physical topology therefore becomes a first-class operational consideration. The scheduler must account not only for resource availability, but also for how GPUs, racks, fabric domains, and cluster blocks relate to one another. Extending Azure beyond traditional cloud boundaries Addressing this challenge requires more than connecting specialized AI infrastructure to Azure. Purpose-built infrastructure must operate as a natural extension of the Azure environment, with the governance, security, and operational experience customers already use. This is where Azure and enterprise AI clouds such as Dapple are taking a different approach. Rather than treating large-scale GPU clusters as isolated infrastructure islands, the architecture extends the Azure operational model into dedicated AI environments. Customers can continue using familiar Azure governance frameworks, security models, and operational tools while leveraging infrastructure specifically optimized for large-scale AI workloads. The result is an architecture that combines two complementary capabilities: Purpose-built AI infrastructure optimized for topology-aware GPU workloads An Azure-native operational experience that preserves governance, security, and lifecycle consistency This model enables organizations to focus on AI innovation without creating a separate operational domain for their most demanding AI infrastructure. The role of Azure Kubernetes Service as the operational control plane As AI infrastructure evolves, the role of Kubernetes is evolving alongside it. Kubernetes has become the dominant platform for orchestrating cloud-native applications, AI services, and distributed workloads. Increasingly, it is also becoming the operational abstraction layer that enables organizations to manage heterogeneous infrastructure through a consistent interface. Azure Kubernetes Service (AKS) plays a critical role in this evolution. In the Azure and Dapple architecture, AKS serves as the primary operational control plane for AI workloads running on purpose-built GPU infrastructure. The physical infrastructure remains optimized around the realities of large-scale AI systems, including GPU topology, InfiniBand fabrics, hardware maintenance domains, and infrastructure lifecycle management. At the same time, platform teams continue to interact through familiar Kubernetes constructs for workload deployment, scheduling policies, governance, and lifecycle management. Organizations gain access to infrastructure designed specifically for modern AI workloads while preserving the operational consistency of a Kubernetes-based platform. In practice, enterprises rarely operate a single orchestrator. Kubernetes provides the common substrate, but the layers above it differ by team: batch schedulers for large training runs, workflow engines for data and fine-tuning pipelines, and internal control planes built around a specific operating model. Many organizations run several of these concurrently. For this reason, orchestration is best treated as a customer-owned concern. The infrastructure layer remains responsible for presenting consistent topology, readiness, and lifecycle semantics to whichever orchestrators an organization already operates. Extending Kubernetes into topology-aware infrastructure While Kubernetes excels at abstracting infrastructure, large-scale AI systems frequently require orchestration platforms that understand physical topology, maintenance boundaries, network fabrics, and hardware relationships. Simply exposing GPUs to a scheduler is no longer sufficient. Infrastructure operations must account for cluster blocks, fabric domains, rack boundaries, node recovery workflows, and physical lifecycle management activities that do not naturally exist within traditional Kubernetes environments. To bridge this challenge, Azure and Dapple are collaborating on an architecture that extends Kubernetes operations into topology-aware AI infrastructure while maintaining a clear separation between workload intent and infrastructure intent. Within this model, AKS remains the authoritative control plane for Kubernetes operations. Platform teams continue to leverage: Kubernetes APIs GitOps workflows Policy management Application lifecycle operations Multi-cluster governance AI workload orchestration At the infrastructure layer, Dapple maintains awareness of: Cluster-block composition GPU fabric topology Network-domain relationships Hardware lifecycle operations Infrastructure maintenance events Recovery and repave workflows The Dapple Operator serves as the integration layer between these domains. Rather than exposing infrastructure complexity directly to platform teams, the operator translates Azure-native operational intent into topology-aware infrastructure actions while synchronizing infrastructure state back into the Kubernetes environment. When hardware maintenance, node replacement, cluster recovery, or lifecycle events occur, the operator coordinates state transitions across both layers, helping ensure that infrastructure operations and workload operations remain aligned. FlexNode connects external workers to AKS, while the Dapple Operator synchronizes cluster block identity, topology, fabric health, maintenance intent, and rejoin evidence with the underlying Dapple infrastructure. This architecture reflects an important design principle: AKS remains responsible for workload intent, while Dapple remains responsible for infrastructure intent. The result is a unified operational model that preserves the architectural characteristics of purpose-built AI infrastructure while enabling Azure-native operations. Learn more Dapple Private AI Cloud | Microsoft Marketplace Dapple | The Enterprise OS Cloud743Views2likes0CommentsAnnouncing Microsoft Azure Network Adapter (MANA) support for Existing VM SKUs
As a leader in cloud infrastructure, Microsoft ensures that Azure’s IaaS customers always have access to the latest hardware. Our goal is to consistently deliver technology to support business critical workloads with world class efficiency, reliability, and security. Customers benefit from cutting-edge performance enhancements and features, helping them to future proof their workloads while maintaining business continuity. Azure will be a deploying new hardware generation to support capacity demands for existing VM Size Families. The hardware is optimized for these VM sizes, utilizing Intel’s Emerald Rapid CPU, native NVMe SSD support for higher storage bandwidth and lower latency, and Microsoft Azure Network Adapter (MANA). Deployment timelines will be communicated via Service Health Advisory updates. The intent is to provide the benefits of new server hardware to customers of existing VM SKUs as they work towards migrating to newer SKUs. The deployments will be based on capacity needs and won’t be restricted by region. Once the hardware is available in a region, VMs can be deployed to it as needed. Workloads on operating systems which fully support MANA will benefit from sub-second Network Interface Card (NIC) firmware upgrades, higher throughput, lower latency, increased Security and Azure Boost-enabled data path accelerations. If your workload doesn't support MANA today, you'll still be able to access Azure’s network on MANA enabled SKUs, but performance will be comparable to previous generation (non-MANA) hardware. Check out the Azure Boost Overview and the Microsoft Azure Network Adapter (MANA) overview for more detailed information and OS compatibility. To determine whether your VMs are impacted and what actions (if any) you should take, start with MANA support for existing VM SKUs. This article provides additional information about which VM Sizes are eligible to be deployed on the new MANA-enabled hardware, what actions (if any) you should take, and how to determine if the workload has been deployed on MANA-enabled hardware.20KViews10likes8Comments
Modernizing TCP Applications with Azure Application Gateway Layer 4 TCP/TLS Proxy
The Layer 4 TCP/TLS Proxy capability in Azure Application Gateway expands ingress possibilities for organizations modernizing TCP-based workloads on Azure. By supporting TCP and TLS traffic alongside existing HTTP/HTTPS capabilities, organizations can move toward more unified ingress architectures while continuing to support traditional enterprise communication patterns. Features such as TLS pass-through and Proxy Protocol v1 support also help improve flexibility for enterprise networking scenarios where preserving client connection information and supporting encrypted traffic flows are important design requirements. As cloud adoption continues to evolve, Azure-native Layer 4 ingress capabilities can help simplify networking architectures while supporting scalable and resilient application connectivity.405Views0likes0Comments
CHERIoT-Ibex: Closing the door on memory safety vulnerabilities with hardware-enforced protection
Memory safety vulnerabilities—largely arising from widely used programming languages such as C and C++—remain a leading cause of exploitable software defects across systems, from embedded devices to cloud-scale infrastructure. In simple terms, memory safety ensures that software accesses only the data it is intended to use; when this protection fails, attackers can exploit these defects to gain control of devices or disrupt critical services. Industry data shows that about 70 percent of the vulnerabilities Microsoft assigns as Common Vulnerabilities and Exposures (CVE) each year are memory safety issues, highlighting how frequently these software defects translate into real-world security risk (CISA – The Urgent Need for Memory Safety in Software Products). Hardware-enforced protections such as CHERIoT-Ibex can help eliminate these vulnerabilities at their source, reducing the likelihood that low-level software flaws can be exploited to compromise devices or disrupt workloads, supporting more trustworthy infrastructure by design. An open and certified foundation for memory-safe embedded systems CHERIoT-Ibex is the first open-source production-quality implementation of the CHERIoT instruction set architecture and among the first cores certified by the CHERI Alliance (CHERI Alliance – CHERIoT). CHERIoT is an extension of the CHERI (Capability Hardware Enhanced RISC Instructions) instruction set, with a focus on embedded and Internet of Things (IoT) applications. Ibex is an open‑source 32‑bit RISC‑V core developed by LowRISC. CHERIoT‑Ibex builds on Ibex by including CHERIoT capability extensions to provide hardware‑enforced memory safety and fine‑grained compartmentalization. It is the result of a close partnership between Microsoft Research and Azure Hardware Systems & Infrastructure, combining advanced research innovation with industry-leading silicon IP development expertise. In 2023, Microsoft open-sourced the CHERIoT Platform to bring hardware-enforced memory safety to embedded systems, including an instruction set architecture, toolchain, real-time operating system, and the RTL implementation of the CHERIoT-Ibex core. The CHERI Alliance certification recognizes its ability to provide spatial and temporal memory safety, fine-grained compartmentalization, and compatibility with the broader CHERI ecosystem. Critically, CHERIoT-Ibex achieves these security guarantees with power and area efficiency comparable to low-cost microcontrollers, demonstrating that security doesn’t have to come at a premium. Why memory safety remains a foundational security challenge Traditional embedded and microcontroller-class designs rely on software hardening and coarse-grained hardware protections that struggle to prevent attacks such as buffer overflows and use-after-free vulnerabilities, often adding complexity while still leaving gaps in protection. Consider a controller that runs privileged firmware responsible for device initialization, telemetry, and system health monitoring, while also hosting networking functionality exposed to external inputs. A memory-safe vulnerability in the networking stack could allow attackers to execute unauthorized code within the firmware environment, potentially affecting other critical services on the device. In tightly integrated systems, these failures can propagate beyond a single component, increasing overall risk. Constraining failures with hardware-enforced isolation CHERIoT-Ibex enables hardware-enforced isolation between these components, helping ensure that even if the networking stack is compromised, its ability to impact system initialization or telemetry functions remains constrained. By limiting the blast radius of software failures, CHERIoT-Ibex supports a system-level approach to security rather than relying on individual components to defend themselves in isolation. Advancing memory-safe infrastructure by design CHERIoT-Ibex’s certification by the CHERI Alliance marks an important milestone for open-source memory-safe solutions. It validates that strong security guarantees can coexist with efficiency and transparency, reflecting Microsoft’s broader silicon-to-systems strategy of embedding security into the foundational hardware infrastructure. Explore and engage with the open-source CHERIoT ecosystem by visiting the CHERIoT Platform and the CHERIoT-Ibex GitHub repository (microsoft/cheriot-ibex). The repositories enable developers and researchers to experiment with, contribute to, and build on memory-safe hardware and software foundations.614Views0likes0Comments
Deploying Azure Redis Enterprise with Geo-Replication Using Terraform
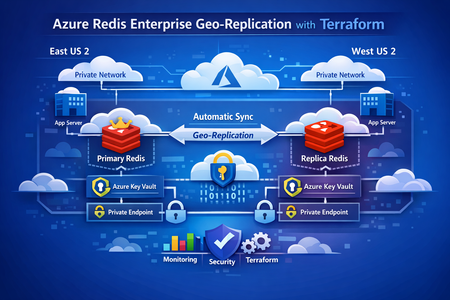
This post walks through a production‑proven pattern for running stateful services across Azure regions using Terraform. We’ll cover a primary–replica Redis architecture, regional isolation with Key Vault and networking, and a clean Terraform parameterization strategy that scales from development to production without duplication. Why Multi‑Region State Is Hard Running applications globally is easy when everything is stateless—if something fails, you redeploy. But stateful services tell a different story. Caches, message brokers, and data stores can’t be treated as disposable. They hold business‑critical data, and downtime or inconsistency quickly becomes customer‑visible. In real‑world systems, common requirements include: Low‑latency reads from multiple regions Automatic recovery when a region becomes unavailable Predictable data consistency Repeatable infrastructure from dev through production Manually configuring this per region doesn’t scale. Drift sets in. Failover is unclear. Backups get forgotten. That’s where Terraform + Azure Managed Redis geo‑replication shines. Github Link : https://github.com/vsakash5/Managed-redis.git High‑Level Architecture We use a primary–replica Redis Enterprise model: Primary Redis Single write endpoint Highly available inside its region Source of truth Replica Redis Read‑only Asynchronously synced from primary Can be promoted during disaster recovery Each region is fully isolated: Separate subnets Separate Key Vaults Private Endpoints only (no public exposure) This prevents shared failure domains and allows each region to operate independently if needed. The Terraform Design Principle Instead of maintaining separate Terraform stacks per region, the key idea is: One reusable module, one tfvars file per environment, multiple regions inside it. The module is written once. Regional differences are supplied via parameter suffixes like: _replica _secondary _tertiary This keeps logic centralized and environments consistent. Core Parameter Layers 1. Environment Identity (Shared) Terraform environment = "dev" # dev | staging | prod context_prefix = "app" Show more lines These values are reused everywhere—names, tags, and identifiers. 2. Primary Region Terraform location = "eastus2" resource_group_name = "rg-app-dev-primary" Show more lines 3. Replica Region Terraform location_replica = "uksouth" resource_group_name_replica = "rg-app-dev-replica" The symmetry is intentional. Terraform can now apply the same module twice without branching logic. Regional Isolation: Networking and Secrets Why isolation matters Geo‑replication copies data, not dependencies. If both Redis instances depend on: the same subnet the same Key Vault then a failure in one region can cascade into the other. Networking (One Subnet per Region) Benefits: Independent NSGs Independent routing Independent capacity planning Key Vault (One per Region) Why this matters: Redis credentials are not replicated Each region stores its own secrets A Key Vault outage doesn’t take both regions down Redis Configuration Primary Redis (Writes Enabled) The geo‑replication group name must match. That’s the logical binding Azure uses to link instances. Private Endpoint‑Only Access No Redis instance is exposed publicly. Each region uses: A private endpoint A workload subnet Internal DNS resolution This means: No public IPs No inbound attack surface Traffic stays on the Azure backbone Linking Primary and Replica Terraform explicitly defines the relationship: Terraform managed_redis_geo_replication_config = { primary_to_replica = { primary_redis_key = "primary" replica_keys = ["replica"] } } Terraform ensures: Primary is created first Replica is deployed second Geo‑replication is established last Environment Scaling: Dev → Staging → Prod The infrastructure pattern never changes. Only values do. Environment Group Name Dev dev-grp Staging stg-grp Prod prod-grp This is how you avoid “snowflake” environments. Disaster Recovery Strategy If the primary region fails: Applications fail over to the replica read endpoint Terraform configuration is updated to: Remove geo‑replication Promote replica config to primary Traffic is fully restored Once the original region recovers, roles can be re‑established cleanly. No click‑ops. No guesswork. Key Lessons Learned 1. Naming is Infrastructure Predictable names enable automation, discovery, and auditing. 2. Key Vault Isolation Beats Availability A shared Key Vault is a shared outage. 3. Parameterization Beats Copy‑Paste Fix once → benefit everywhere. 4. Geo‑Replication Is a Contract Matching replication group names is non‑negotiable. 5. The tfvars File Is the Source of Truth If it’s not in Terraform, it’s not real. Final Thoughts Running stateful services in multiple regions doesn’t require magic— it requires discipline: Isolate aggressively Parameterize consistently Automate everything Test failure often With this approach, adding a new region becomes configuration—not redesign. That’s how infrastructure scales.266Views1like0CommentsDemystifying On-Demand Capacity Reservations
About On-Demand Capacity Reservations Introducing the “parking garage” metaphor There are dozens of VM types available in Azure which span multiple generations of CPU across vendors and architectures. Within each Azure region are datacenters hosting pools of hardware which runs Azure services, such as virtual machines, of those types. As VMs are started and stopped by customers there is a constant ebb and flow of available capacity to run each type of VM within the region. Available capacity is driven by the rhythms of the business day, which creates variations in utilization on an hour-to-hour and even minute-to-minute basis. Longer cycles of demand such as holiday seasons, school calendars and other real-world events are also a factor. When you command an Azure Virtual Machine (VM) to start, the Azure Resource Manager (ARM) – the “engine” that manages resources in the Microsoft cloud -- needs to do a few things to make it happen. The most important of these is that it needs to identify hardware within the target region with sufficient capacity to bring the desired type and size of VM online at that moment in time. If ARM finds space for the desired VM size, the VM starts normally. However, if there is no room to start the desired VM, you will see an error similar to this one: This process of finding a place to start up an Azure VM has a lot of similarities to finding a place to park a vehicle. Parking facilities are built to handle typical demand for their location. If something is going on nearby, such as a large sporting event, which causes the need for parking to be much higher than normal then you might be out of luck when you try to find a spot because the garage is simply full. During periods of high demand in Azure this can result in VMs failing to start simply because there is nowhere to run them at that particular moment. If this happens to a VM which needed to be stopped for a configuration change or other reasons this can cause impact to your environment which you certainly want to avoid. On-Demand Capacity Reservations Azure has a resource called an On-Demand Capacity Reservation, or ODCR, which allows you to reserve a spot for a VM in the appropriate hardware within a region for a specific VM size. This is similar to “owning" a parking space: It’s a reserved place exclusively for the use of a specific VM. At a high level, the way this works is that you create an ODCR which matches the Azure region, availability zone and specific VM type, such as for a VM of type D16s_v6 in availability zone 2 of the Canada Central Azure region. Once the reservation is created, an Azure VM that matches that configuration can be associated to it so the VM now “owns” that “parking space”. This gives that VM priority over others of the same type when it needs to start because it already has a “parking space” assigned to it that can't be used by another one. More detail about VM startup Before we get further into what ODCRs are and how they work, it’s important to know a few more things about starting up a VM. Azure does not provide an explicit SLA for VM startup for virtual machines without an ODCR. The process of finding a hypervisor slot to boot up a VM is purely a “best effort” action on Azure’s part. Having quota headroom does not help with VM startup. Quota in Azure is your "credit limit" for creating VMs. Quota grants permission to create up to a certain number of cores’ worth of Virtual Machines from a particular family (like Ds_v6) but has no effect on whether you can actually start the machine once it’s created. Similarly, having a Reserved Instance purchase or a Savings Plan for a particular number of cores of a given VM family does not have any impact on the ability to start a VM either. These mechanisms are a discount mechanism only where the customer pre-pays for a certain amount of VM cores to be running 24x7 at a discounted rate. Assigning an ODCR to a virtual machine applies a formal SLA on startup for it. VMs with ODCRs get priority over ones that don’t so the likelihood of a successful startup is much higher for VMs that have one compared to those that do not, especially during times when Azure is experiencing a period of high demand for that particular VM type. The actual language of the ODCR SLA can be found in Microsoft's Service Level Agreements for Online Services document which can be downloaded from the linked site. Cost Implications of ODCRs These are the key points that you need to know about how billing works for ODCRs: The compute cost for the parking space capacity reservation for a VM is exactly the same as a running VM of the same size. There is no “double billing” for a VM to have an ODCR associated with it. Billing for the ODCR starts immediately if the quantity of reserved "parking spaces" is greater than zero. Stopping a VM that has an ODCR associated with it does not impact cost. This is because the ODCR is holding the reserved hypervisor slot even if the VM is not running. Having a Reserved Instance purchase or Savings Plan which covers the same scope as the ODCR means that the VM will be billed at the discounted rate. Are there any cases where using ODCRs results in paying more for a VM? There are two cases that I’ve identified where you pay for two ODCRs for the same VM. First, if you are using Azure Site Recovery to protect a VM in Azure by replicating it to another location, you have the option to associate the remote replica of the VM with a capacity reservation. This helps ensure that the replica will start when it’s called upon because it has a pre-allocated spot reserved for it. In this situation, if the original VM also is associated with an ODCR you are paying for both the original (running) VM and also for the reservation being held for its replica. Second, and similarly, when setting up replication for a VM that is preparing for migration into Azure via Azure Migrate, you can associate a capacity reservation with the replica for similar reasons to the above ASR example -- to ensure that the VM will start when its migrated replica is activated. If the source machine is also in Azure then you are again paying twice for the same machine. When should I use them? Capacity Reservations are an important element when designing for resiliency. They help ensure that VMs will be online when needed, even if they have to be shut down for some reason. For example, there was an incident where a customer had to shut down a VM that was serving as a firewall appliance to make an adjustment to its configuration and it failed to start up afterwards because of a capacity-related failure. This resulted in significant impact due to the loss of connectivity for systems dependent on the firewall for connectivity until they were able to bring it back online. Based on field experience and resiliency assessments, applying ODCRs to VMs that must be available 24x7 is strongly recommended. Examples of this include key functions like AD domain controllers, application servers and database servers. Also, any VM-based appliances that may be running as firewalls, load balancers or other infrastructure-support services should be considered as well. Microsoft offers assessments which review a workload for gaps that impact resiliency in many dimensions including outages in Azure. These assessments include checks for the presence of capacity reservations and will report any VM’s that do not have them as a high-risk finding. Not all VM stops in Azure are voluntary Even if you are careful to never stop a VM yourself it can sometimes happen. Not every shutdown of a VM in Azure is user-initiated. Involuntary shutdowns are rare but they can occur due to predictive hardware failures or other events which ARM will respond to by stopping the VM in order to move it out of harm's way. Creating On-Demand Capacity Reservations This section covers the components of an ODCR, the process of creating them and why creating them can fail. Components of an ODCR: An ODCR has two components to it. The first part is a Capacity Reservation Group (CRG) which is simply a "bucket" for any number of capacity reservations. To create a CRG you only need to provide its name, the region that it will be used for and which availability zones within that region it will have access to. The second -- and more important -- component is the actual Capacity Reservation which is created within a CRG. The capacity reservation requires: The name of the reservation. Including the VM size and other details in the name is useful to reduce ambiguity. An example could be “Zone1_D16s_v5” The specific VM size the reservation is for, such as “D16s_v5” The availability zone of the reservation. You can also create a regional reservation, where the VM is “zoneless”, as well. The number of parking spaces instances that the reservation holds. ODCRs can be created via the Azure portal, from the command line using PowerShell or the Azure CLI or deployed through IaC tools such as Bicep or Terraform. CRGs also can also be shared across subscriptions, which allows a CRG created and managed in one subscription to be utilized by VMs in a different subscription. When the ODCR is created, if the number of instances it contains is higher than zero then ARM will attempt to allocate the desired number of instances of the specified VM type in the target region/zone. If there is capacity available for this then the creation succeeds and you can move on to associating machines with it to give them the protection of the ODCR. If creating the ODCR is unsuccessful, the cause can be a variety of things, including: No open hypervisor slots for the desired VM in the target location – the “parking lot” was full at the moment the request was submitted. This can result from outages within Azure that reduce capacity as well as demand pressure. There is insufficient quota in the subscription to claim the necessary number of VM cores for the reservation in the region. The VM type is simply not available in the target region or AZ. Since not all Azure regions are provisioned with identical hardware this can be the cause, especially for VM types other than the popular D, E and F series machines. A restriction is applied to the subscription, zone or region that blocks creation of the reservation for some reason. What you can do if creating an ODCR fails Some things that may help if creating a capacity reservation fails and you know that quota or other restrictions are not a factor are below. Not coincidentally, these are the same recommendations that you should try when a VM fails to start because the same ARM action – finding and allocating hardware with free capacity to start the VM – is taking place. IN GENERAL, creating an ODCR outside of business hours has a higher probability of success. Demand for Azure services typically drops off at the end of the business day where the region is located. Consider using a different VM type, availability zone or a different Azure region. A script or other automation that retries at intervals until the reservation succeeds in claiming the desired number of spots can help, though it can take an unknown amount of time before this works. It may need to run for days or even weeks before it succeeds. Submitting a support ticket will create visibility to your situation from Microsoft. If the root cause is something other than capacity, support can identify that cause and provide guidance on how to resolve it. If the issue truly is a capacity squeeze, the ability of support to help get the reservation created is extremely limited because the support folks, while helpful, are not able to create capacity where none exists. In this case the support teams will usually refer you to the three options above. Protecting a VM with an ODCR Once you have the ODCR created, applying it to a VM is straightforward. To do this from the portal, open the configuration tab on the VM’s screen. Then scroll to the bottom of the panel that appears to find the “Capacity reservations” section. Select “Capacity reservation group” from the list. The list of capacity reservation groups that match the VM will appear in a drop-down menu below. Select the CRG that the VM should use and click “Apply”. If you are using an Infrastructure-as-Code approach such as Bicep or Terraform, an Azure VM is linked to a CRG by specifying the resource ID of the CRG in the appropriate property on the VM definition. Impact of associating a virtual machine with an ODCR: If the VM is not running then the change takes effect immediately. If the VM is running and has no zone assignment (a “regional” VM) then it must be stopped and restarted for the protection of the ODCR to apply. If the VM is running and has a zone assignment then the change is immediate and there is no disruption to the VM. Important note for Terraform users: There appears to be a critical behavior difference between how the AzureRM provider and the Azapi provider handle this change. If you use the AzureRM provider, Terraform will always perform an immediate stop/deallocate of the VM, apply the change and then start the VM up again. The Azapi provider works as documented above. I believe this a result of how Hashicorp coded the AzureRM provider to manage Azure resources. Where an ODCR is not the right answer ODCRs are most effective when they are used to protect VMs that need to always be running because they are providing essential services. Examples include AD domain controllers, firewall or load balancer appliances, database servers, integration servers that support workflows and the like. The primary thing to keep in mind is the cost impact of the ODCRs and whether they are necessary for the service to be functioning. Environments where machines come and go frequently, such as scale in/out setups used to minimize cost, are not ideal for ODCRs. For example, if you have a pool of app servers configured for scale-out, using ODCRs to cover the entire size of the pool means you would be paying for all machines, whether they are actually online or not. A possible approach in a scale-out environment is to determine the minimum number of VMs necessary for the service to be available -- even in a degraded state -- and use an ODCR to protect that number of instances. This way you can have confidence that at least that number of machines in the pool will always be running even if an attempt to scale out fails. Working with On-Demand Capacity Reservations (and three interesting behaviors that you should know about) This section discusses some ins and outs of working with ODCRs in your environment, especially if you need to apply them to existing machines. This is a common scenario when you are attempting to improve the resiliency of a set of VMs against impacts from maintenance, outages or other situations that may cause VMs to restart. “Associated” vs “Allocated” A capacity reservation group will always have ownership of some number of "parking spots" within a region. The number that it holds is referred to as the reservation's capacity which is expressed as a number of allocated instances. When you link a VM to a CRG, the VM becomes associated with the CRG and can take advantage of the protection that it offers from matching reservations that it contains. It is possible to associate more VMs to a CRG than it has allocated capacity for. This is called overallocation. When a CRG is overallocated, the VMs associated with it are protected on a first-come-first-served basis based on when they were started. If, for example, there are four VMs associated with a CRG but the CRG only has an allocated capacity of two, the first two associated machines which were started will receive protection but the others will not. “Interesting” On-Demand Capacity Reservation behavior #1: Here is the first of three interesting behaviors that you can use to your advantage when working with ODCRs. You can add a running VM to a capacity reservation group. As mentioned previously, if the VM is zonal then the change is immediate and nondisruptive. If the VM is regional then the VM must be stopped and restarted for the change to take effect. This is conceptually different from other Azure mechanisms used for resiliency such as Availability Sets. You can only add a VM to an availability set at the time the VM is created but you can add or remove a VM from a Capacity Reservation Group at any time whether the VM is running or not. “Interesting” On-Demand Capacity Reservation behavior #2 Interesting behavior #2 is deceptively simple. When creating a reservation, you can specify a capacity (number of allocated instances) of zero. This should always succeed because Azure needs to take no action to fulfill it -- this is just a metadata adjustment for the reservation within the CRG. This seems to not be terribly useful at first glance but keep reading. “Interesting” On-Demand Capacity Reservation behavior #3 If the number of associated VMs is higher than the allocated capacity of the reservation, you can increase the capacity of the reservation to cover the running VMs. Why does this work? Because running VMs, by definition, have a parking spot hypervisor allocation already so Azure doesn’t need to find one for it -- Azure can simply link the capacity reservation to the hypervisor slot that the running VM is using. The payoff! Or, using these three behaviors to your advantage Because ODCRs are relatively new and have not yet been adopted widely, a common finding to emerge from field resiliency assessments of running workloads is that the VMs that support the workload need to have ODCRs applied to them. In large environments there may be dozens or even hundreds of VMs that need to be protected. The process for doing this can seem daunting to a technical team that is not familiar with ODCRs. Thankfully, these three behaviors make it possible to easily protect any number of running machines with a very high probability of success -- and zero disruption if they are zonal VMs -- by proceeding in this order: Create a CRG with a reservation for the region, AZ and VM type for the machine(s) that need to be covered with a quantity of zero. (Interesting behavior #2) Associate the VMs to the capacity reservation group. At this point the CRG is overallocated so the machines are not yet protected. Remember that if the VMs are regional, a restart is required to finalize the ODCR assignment. (Interesting behavior #1) Update the reservation within the CRG to increase the number of allocated instances to match the number of running VMs. (Interesting behavior #3) When the number of instances on the reservation is equal to or higher than the number of VMs associated with it, all of the associated VMs are protected and you’re done! Final thoughts This leads to a final piece of advice about working with ODCRs, especially when you know that capacity is a challenge in the target region: As a field CSA, I recommend that you bring VMs online first, then apply a capacity reservation to them. Why? If you already have a set of running VMs that need to be protected then following what seems like the obvious process: Creating a CRG, creating reservations within it for the correct number of instances and then associating the VMs with the reservation – has a risk of failure at the step of creating the ODCR because Azure needs to find and allocate additional hypervisor slots for the reservation to own. This can be challenging when there is a lot of demand for the VM type. As the example in the previous section showed, it’s much easier to protect VMs that are already online by associating them with an existing capacity reservation, even if it doesn’t have enough instances allocated to it, and then increasing the capacity of the ODCR to cover the running machines. References: On-Demand Capacity Reservations Overview Monitor the list of restrictions on VM eligibility because it changes frequently SLA Details for On-Demand Capacity Reservations Legal fine print is in the consolidated SLA for Online Services (.docx) Some details about Overallocating capacity reservations Information on creating a Capacity Reservation Group via Bicep, Terraform or ARM template.2KViews4likes0CommentsProactive Resiliency in Azure for Specialized Workload i.e. Citrix VDI on Azure Design Framework.
In this post, I’ll share my perspective on designing cloud architectures for near-zero downtime. We’ll explore how adopting multi-region strategies and other best practices can dramatically improve reliability. The discussion will be technically and architecturally driven covering key decisions around network architecture, data replication, user experience continuity, and cost management but also touch on the business angle of why this matters. The goal is to inform and inspire you to strengthen your own systems, and guide you toward concrete actions such as engaging with Microsoft Cloud Solution Architects (CSAs), submitting workloads for resiliency reviews, and embracing multi-region design patterns. Resilience as a Shared Responsibility One fundamental truth in cloud architecture is that ensuring uptime is a shared responsibility between the cloud provider and you, the customer. Microsoft is responsible for the reliability of the cloud in other words, we build and operate Azure’s core infrastructure to be highly available. This includes the physical datacenters, network backbone, power/cooling, and built-in platform features for redundancy. We also provide a rich toolkit of resiliency features (think availability sets, Availability Zones, geo-redundant storage, service failover capabilities, backup services, etc.) that you can leverage to increase the reliability of your workloads. However, the reliability in the cloud of your specific applications and data is up to you. You control your application architecture, deployment topology, data replication, and failover strategies. If you run everything in a single region with no backups or fallbacks, even Azure’s rock-solid foundation can’t save you from an outage. On the other hand, if you architect smartly (using multiple regions, zones, and Azure resiliency features properly), you can achieve end-to-end high availability even through major platform incidents. In short: Microsoft ensures the cloud itself is resilient, but you must design resilience into your workload. It’s a true partnership one where both sides play a critical role in delivering robust, continuous services to end-users. I emphasize this because it sets the mindset: proactive resiliency is something we do with our customers. As you’ll see, Microsoft has programs and people (like CSAs) dedicated to helping you succeed in this shared model. Six Layers of Resilient Cloud Architecture for Citrix VDI workloads To systematically approach multi-region resiliency, it helps to break the problem down into layers. In my work, I arrived at a six-layer decision framework for designing resilient architectures. This was originally developed for a global Citrix DaaS deployment on Azure (hence some VDI flavor in the examples), but the principles apply broadly to cloud solutions. The layers ensure we cover everything from the ground-up network connectivity to the operational model for failover. 1. Network Fabric (the global backbone) Establish high-performance, low-latency links between regions. Preferred: Use Global VNet Peering for simplified any-to-any connectivity with minimal latency over Microsoft’s backbone (ideal for point-to-point replication traffic), rather than a more complex Azure Virtual WAN unless your topology demands it. 2. Storage Foundation (the bedrock ) In any distributed computing environment, storage is the "heaviest" component. Moving compute (VDAs) is instantaneous; moving data (profiles, user layers) is governed by bandwidth and the speed of light. The success of a multi-region DaaS deployment hinges on the performance and synchronization of the underlying storage subsystem. Use storage that can handle cross-region workload needs, especially for user data or state. In case of Citrix Daas, preferred approach is Azure NetApp Files (ANF) for consistent sub-millisecond latency and high throughput. ANF provides enterprise-grade performance (critical during “login storms” or peak I/O) and features like Cool Access tiering to optimize cost, outperforming standard Azure Files for this scenario. 3. User Profile & State (solving data gravity) Enable active-active availability of user data or application state across regions. Solution: FSLogix Cloud Cache (in a VDI context) or similar distributed caching/replication tech, which allows simultaneous read/write of profile data in multiple regions. In our case, Cloud Cache insulates the user session from WAN latency by writing to a local cache and asynchronously replicating to the secondary region, overcoming the challenge of traditional file locking. The principle extends to databases or state stores: use geo-replication or distributed databases to avoid any single-region state. 4. Access & Ingress (the intelligent front door) Ensure users/customers connect to the right region and can fail over seamlessly. Preferred: Deploy a global traffic management solution under your control e.g. customer-managed NetScaler (Citrix ADC) with Global Server Load Balancing (GSLB) to direct users to the nearest available datacenter. In our design, NetScaler’s GSLB uses DNS-based geo-routing and supports Local Host Cache for Citrix, meaning even if the cloud control plane (Citrix Cloud) is unreachable, users can still connect to their desktop apps. The general point: use Azure Front Door, Traffic Manager, or third-party equivalents to steer traffic, and avoid any solution that introduces a new single point of failure in the authentication or gateway path. 5. Master Image (ensuring global consistency) : If you rely on VM images or similar artifacts, replicate them globally. Use: Azure Compute Gallery (ACG) to manage and distribute images across regions. In our case, we maintain a single “golden” image for virtual desktops: it’s built once, then the Compute Gallery replicates it from West Europe to East US (and any other region) automatically. This ensures that when we scale out or recover in Region B, we’re launching the exact same app versions and OS as Region A. Consistency here prevents failover from causing functionality regressions. 6. Operations & Cost (smart economics at scale) Run an efficient DR strategy you want readiness without paying 2x all the time. Approach: Warm Standby with autoscaling. That means the secondary region isn’t serving full traffic during normal operations (some resources can be scaled down or even deallocated), but it can scale up rapidly when needed. For our scenario, we leverage Citrix Autoscale to keep the DR site in a minimal state only a small buffer of machines is powered on, just enough to handle a sudden failover until load-based scaling brings up the rest. This “active/passive” model (or hot-warm rather than hot-hot) strikes a balance: you pay only for what you use, yet you can meet your RTO (Recovery Time Objective) because resources spin up automatically on trigger. In cloud-native terms, you might use Azure Automation or scale sets to similar effect. The key is to avoid having an idle full duplicate environment incurring full costs 24/7, while still being prepared. Each of these layers corresponds to critical architectural choices that determine your overall resiliency. Neglect any one layer, and that’s where Murphy’s Law will strike next. For example, you might perfectly replicate your data across regions, but if you forgot about network connectivity, a regional hub outage could still cut off access. Or you have every system duplicated, but if users can’t be rerouted to the backup region in time, the benefit is lost. The six-layer framework helps make sure we cover all bases. Notably, these design best practices align very closely with Azure’s Well-Architected Framework (especially the Reliability pillar), and they’re exactly the kind of prescriptive guidance we provide through programs like the Proactive Resiliency Initiative. In fact, the PRI playbook essentially prioritizes these same steps for customers: First, harden the network foundation e.g. ensure ExpressRoute gateways are zone-redundant and circuits are “multi-homed” in at least two locations (so no single datacenter failure breaks connectivity). Next, address in-region resiliency – make sure critical workloads are distributed across Availability Zones and not vulnerable to a single zone outage. (As an aside: Microsoft’s internal data shows a huge payoff here; when we configured our top Azure services for zonal resilience, we saw a 68% reduction in platform outages that lead to support incidents!) Then, enable multi-region continuity (BCDR) – for those tier-0 and tier-1 workloads, set up cross-regional failover so even a region-wide disruption won’t take you down. Multi-region is described as the complement to (not a substitute for) zonal design: it’s about surviving the “black swan” of a region-level event, and also about supporting geo-distributed users and future growth. In other words, if you follow the six-layer approach, you’re doing exactly what our structured resiliency programs recommend.527Views1like0CommentsJoin Microsoft as we share more on Maia 200 in the Bay Area
In the next major step in our AI Infrastructure evolution, last week we introduced Maia 200, a breakthrough inference accelerator engineered to dramatically improve the economics of AI token generation. Microsoft engineering leaders will be showcasing our latest silicon innovation in San Francisco this month. Here are a few ways you can learn more and engage with this exciting technology and the team behind it: Maia 200 ISSCC Whitepaper Microsoft has submitted a technical whitepaper around Maia 200 as part of the International Solid-State Circuits Conference (ISSCC). The paper will be released on Friday, February 13 th to ISSCC attendees and be available after the conference digitally on IEEE. The paper is titled “Maia: A Reticle-Scale AI Accelerator” by Sherry Xu, Partner, Silicon Architecture at Microsoft. ISSCC Session Leadership from Azure Hardware and Systems will present a 25-minute session on Maia development titled "MAIA: A Reticle-Scale AI Accelerator" at the ISSCC conference at 2:45 PM (Session 17.4) as part of the wider ISSCC Session 17 "Highlighted Chip Releases for AI" that begins at 1:30 PM inside the Marriott Marquis in downtown San Francisco. During the session, we will highlight our design approach for Maia 200 and walk through the architecture and implementation of Microsoft’s Maia AI silicon. We’ll also share how the team engineered a reticle‑limited, ~750W AI SoC and the innovations that enabled a scalable, high‑performance accelerator. Join us at the Microsoft Silicon Social Event Microsoft will also be hosting a Silicon Social in downtown San Francisco on the evening of the 17 th . Maia 200 will be on-site marking its first public appearance outside of Microsoft labs and Azure datacenters, along with a selection of other Microsoft silicon hardware. Microsoft’s silicon engineering leadership will be attending, and we will provide food and drink during the event. All ISSCC attendees and others in the Bay Area silicon community are invited to register interest in attending by February 13 th . Due to limited capacity, confirmed attendees will receive a follow‑up email with event details, including the venue.669Views0likes0Comments