artificial intelligence
87 TopicsMicrosoft Foundry Guardrails Getting in Your Way? Here’s How to Dial Them Down
How This All Started So here’s the story. I just got back from a trip and had a pile of footage sitting on my laptop. Being the lazy (sorry, efficient) person I am, I fired up OpenCode and asked GPT-6 Astra, running on Microsoft Foundry, to cut me a travelogue. Nothing fancy: under two minutes, nice lighting, clean transitions, no cringy effects, a quick QA before showing me, and the output in its own folder. Easy, right? Nope. This is what I got instead: “Image processing blocked due to content policy violation.” Seriously? It’s holiday footage! Nothing even remotely dodgy in there. This is a classic false positive from the default guardrails, and the good news is it’s totally fixable. Let me show you how. My Setup Quick context before we dive in: I’ve got two models deployed on Microsoft Foundry, gpt-6-astra and gpt-6-sol. Both were running on Microsoft’s out-of-the-box guardrail. Step 1: Find the Guardrails Page Head over to the Microsoft Foundry portal, click Build, then hit Guardrails in the left menu. You’ll see three guardrails that Microsoft gives you by default: Microsoft.Default, Microsoft.DefaultV2 and Microsoft.MAIDefault. Microsoft.DefaultV2 is the one every new deployment gets, which is why it’s sitting on both of my models. Here’s the catch: you can’t edit or delete these Microsoft-managed defaults. So instead of tweaking them, we’re going to build our own guardrail and swap it in. Step 2: Create Your Own Guardrail Smash that "Create" button and you’ll land on the Create guardrail page. This is where all the knobs and switches live: Every control has three bits: the risk type, the intervention point (does it check what you send in, what the model spits out, or both?) and the action. The magic trick for loosening things up is flipping the action from Block to Annotate. With Annotate, Foundry still scans the content and tags it in the API response, but it stops slamming the door on your request. So What Does Each Setting Actually Do? Before you go on a switching-off spree, it’s worth knowing what each of these does and what you’re giving up when you loosen it. Here’s the quick tour: Jailbreak: This one catches prompts trying to trick the model into ignoring its rules. On Block, those prompts get rejected outright. On Annotate, they go through with a flag. Turn it off completely and you’re trusting the model’s own training to keep it in line. Network (egress rules): Controls which outbound calls a hosted agent is allowed to make. As the portal points out, it only applies to hosted agents, so for plain model deployments like mine it doesn’t change a thing. Indirect prompt injections: Watches user input and tool responses (files, docs, web pages the model reads) for sneaky instructions someone has planted. Leave it on and your agents are protected when they read outside content; switch it off and a dodgy file could quietly hijack your model. For an agentic tool like OpenCode, which reads files and runs shell commands, I’d honestly keep this one on, even if it’s just on Annotate. Spotlighting (Preview): Tags external content inside the prompt so the model can tell your real instructions apart from random untrusted data. Think of it as an extra seatbelt against indirect attacks. Content harms (Hate, Sexual, Self-harm, Violence): Each of these has a severity slider that starts at Medium blocking, meaning anything rated medium or higher gets blocked. Slide it down to Lowest blocking and only the really nasty stuff gets stopped, which kills off most false positives like mine. The asterisk means these four are mandatory: you can turn the dial down, but you can’t switch them off. Blocklists: Want to ban specific words or phrases, like profanity or your competitor’s name? This is where you do it. It’s off by default. Protected material for code and text: Checks whether the model is about to spit out known copyrighted text (song lyrics, articles and so on) or code lifted from public repos. Block stops it; Annotate lets it through with a flag. Switch it off and you’re rolling the dice on your app reproducing someone else’s copyrighted work. Step 3: Pick Your Models Hit Next and Foundry asks which agents and models you want this guardrail on. Any model you’ve already deployed in your project shows up here. For me that’s gpt-6-astra and gpt-6-sol, so I ticked both. Step 4: Name It and Pick a Streaming Mode One more Next and you’re on the Review page. Give your guardrail a name (I went with NoGuardrails, because subtlety isn’t my thing) and pick a streaming mode. You’ve got two choices: Default: Foundry buffers the response and runs it through the guardrail before each chunk goes out. Nothing reaches the user until it’s been checked. Safest option, but you’ll feel a bit of lag when streaming. Asynchronous: Content streams back the moment it’s generated, with the filters running in the background. Much snappier, but flagged content might flash up briefly before the filter catches it, so your app has to clean up after the fact. Microsoft pitches this for low-latency stuff like internal dev tools, which is exactly my use case. Give the summary a quick once-over, then click Create. Done! Did It Work? Yep! With my shiny new guardrail in place, I fired off the exact same request, this time to GPT-6 Sol. And boom: no more content policy error. The model went straight to work scanning my footage and putting the video together. Wrapping Up Look, Microsoft’s default guardrails are a solid starting point, but they can be a bit trigger-happy when you’re doing perfectly legit stuff like video editing, creative work or internal tooling. Since you can’t touch the defaults, the trick is to roll your own: flip Block to Annotate where it makes sense, drag those content harm sliders down, pick the streaming mode that fits your app, and assign it to your deployments. That’s it! One friendly word of warning though: with great power comes great responsibility. Only loosen what you actually need, keep things like indirect prompt injection detection switched on for any agent that reads files or browses the web, and think twice before doing this on anything customer-facing. And if you want to go further than the portal lets you, like switching content filters off completely, you’ll need to apply to Microsoft for approval first. Happy building!106Views0likes0CommentsResource Guide: Making Physical AI Practical for Real‑World Industrial Operations
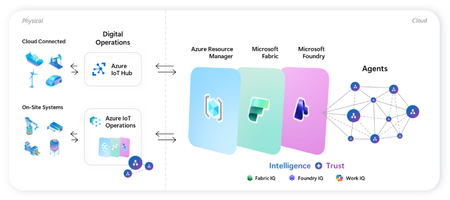
Microsoft's adaptive cloud approach brings cloud, edge, data, and AI together to help organizations turn operational technology (OT) data into intelligent action, without requiring everything to live in the cloud. At the center of this approach are key technologies that connect physical operations to cloud-scale data, analytics, and AI: Key Purpose Offering Direct-to-cloud device management + telemetry ingestion Azure IoT Hub Industrial connectivity + edge data plane Azure IoT Operations Unified analytics + real-time intelligence Microsoft Fabric On-device AI inferencing runtime Microsoft Foundry Industry recognition Microsoft named a Leader in the 2026 Gartner® Magic Quadrant™ for Global Industrial AIoT Platforms Read the announcement See it all come together Before diving into each component, watch this end-to-end demo showing how Azure IoT Operations, Azure IoT Hub, Microsoft Fabric, and Foundry Local work as one stack across the edge-to-cloud lifecycle - Making industrial AI practical for real-world operations with adaptive cloud. How these components work together Azure IoT Operations and Azure IoT Hub collect real-time data from operational assets and send semantically-ready, modeled data to Microsoft Fabric, where it's contextualized with enterprise data for downstream analytics. Microsoft Foundry extends to the edge through Foundry Local, so the same tooling used to deploy and manage AI models in the cloud applies to edge use cases. All of it integrates into Azure Resource Manager, bringing OT devices, assets, and edge AI models into the same management and security paradigm as every other Azure-managed resource. This blog walks through where to get started with each product capability: 1. Manage Cloud-Connected Devices and Telemetry with Azure IoT Hub Azure IoT Hub is a fully managed cloud service that enables secure bidirectional communication, device-to-cloud telemetry ingestion, cloud-to-device command execution, per-device authentication, remote management and more. Telemetry from IoT Hub can also be routed downstream into analytics platforms like Microsoft Fabric for visualization or AI modeling. Recommended Usage: Devices that utilize IoT Hub are distributed, stand-alone devices with fixed-functions. These devices typically do not require cloud-managed containerized workloads or cloud-managed proximal industrial protocol connectivity. Examples of appropriate device-to-cloud IoT Hub endpoint devices include water monitoring stations, vehicle telematics, distributed fluid level sensors, etc. Resources Current in-market services overview: IoT Hub: What is Azure IoT Hub? - Azure IoT Hub DPS: Overview of Azure IoT Hub Device Provisioning Service - Azure IoT Hub Device Provisioning Service ADU: Introduction to Device Update for Azure IoT Hub Building scalable solutions with Azure IoT platform: Best practices for large-scale IoT deployments - Azure IoT Hub Device Provisioning Service Scale Out an Azure IoT Hub-based Solution to Support Millions of Devices - Azure Architecture Center Azure IoT Hub scaling Try out our preview of new IoT Hub capabilities (integration with Azure Device Registry and Certificate Management) Learn more about these capabilities on our blog post: Azure IoT Hub + Azure Device Registry (Preview Refresh): Device Trust and Management at Fleet Scale… Integration with Azure Device Registry (preview): Integration with Azure Device Registry (preview) - Azure IoT Hub Microsoft-backed X.509 certificate management (preview): What is Microsoft-backed X.509 Certificate Management (Preview)? - Azure IoT Hub How to start with the preview: Deploy IoT Hub with ADR integration and certificate management (Preview) - Azure IoT Hub 2. Connect Industrial Assets with Azure IoT Operations Azure IoT Operations provides a unified data plane for the edge that runs on Azure Arc–enabled Kubernetes clusters and supports open industrial standards. It allows organizations to connect and capture equipment telemetry, normalize OT data locally, route hot-path signals to real-time analytics, securely manage layered industrial networks, and more. Edge‑processed data can then be sent upstream to Microsoft Fabric for AI‑driven analysis. Recommended Usage: Azure IoT Operations is intended to be the data plane for an adaptive cloud deployment extending the management, data, and AI capabilities of the Microsoft cloud to an on-prem device. This device binds to these cloud planes providing a platform for local data processing and intermittent connectivity. The target for these devices range from a small-gateway-style PC to a full data center. Azure IoT Operations endpoints enable cloud-managed containerized workloads and cloud-managed proximal industrial protocol connectivity. Examples of appropriate adaptive cloud and Azure IoT Operations endpoints include, on-robot computers, industrial machine controllers, retail store sensor/vision processing, and top-of-factory site infrastructure for line of business applications. Resources Azure IoT Operations Overview Azure IoT Operations Documentation Hub Releases · Azure/azure-iot-operations Quickstart: explore-iot-operations/quickstart at main · Azure-Samples/explore-iot-operations Latest release update: Open-source framework for scaling robotics from simulation to production on Azure + NVIDIA: microsoft/physical-ai-toolchain Demo video showcasing this in action: Making industrial AI practical for real-world operations with adaptive cloud How we built the demo: explore-iot-operations/quickstart at main · Azure-Samples/explore-iot-operations Edge-AI: microsoft/edge-ai: Production-ready Infrastructure as Code, applications, pluggable components, and… Latest Announcements & Blogs Making Physical AI Practical for Real-World Industrial Operations: Part 1 | Microsoft Community Hub Making Physical AI Practical for Real-World Industrial Operations: Part 2 | Microsoft Community Hub Introducing small form factor infrastructure: embed intelligence into physical systems Unlock Industrial Intelligence | Microsoft Hannover Messe 2026 From pilots to production: How Microsoft and partners are accelerating intelligent operations Partner Solutions How Mesh Systems Builds on Azure IoT Hub and Azure IoT Operations to Accelerate Industrial AI | Microsoft Community Hub Unlocking the Human Telemetry Layer for Safer Industrial Operations | Microsoft Community Hub Unlocking Smart Manufacturing: Siemens Industrial Edge Meets Azure IoT Operations Solving the Data Challenge for Manufacturers with Sight Machine & Azure IoT Operations | Microsoft Community Hub Microsoft and Rockwell Automation: Transforming Industrial AI Together | Microsoft Community Hub 3. Advanced Analytics with Microsoft Fabric Microsoft Fabric delivers a unified, end‑to‑end analytics platform that transforms streaming OT telemetry into real‑time insights and live dashboards. Fabric Operations Agents monitor industrial signals to recommend targeted actions, while Fabric IQ provides a shared semantic foundation that enables AI agents to reason over enterprise data with business context. Together, Fabric turns live industrial data into AI‑powered operational intelligence. Resources Get Started with Microsoft Fabric Learning Path Fabric Real-Time Intelligence documentation - Microsoft Fabric | Microsoft Learn Create and Configure Operations Agents - Microsoft Fabric | Microsoft Learn Fabric IQ documentation - Microsoft Fabric | Microsoft Learn 4.Run AI Models On‑Device with Foundry Local Foundry Local extends on‑device AI to Arc‑enabled Kubernetes edge clusters, providing a Microsoft‑validated inferencing layer for running AI models in industrial, disconnected or sovereign environments. Resources Foundry Local on Azure Local Documentation Participate in Foundry Local on Azure Local preview form Foundry Local on Azure Local: HELM deployment Demo Customer Stories Chevron: Chevron plans facilities of the future with Azure IoT Operations Husqvarna: Husqvarna Group Boosts Operational Efficiency with Azure Adaptive Cloud Ecopetrol: Azure IoT Operations and Azure IoT for energy help Ecopetrol optimize energy distribution while lowering operational costs P&G: Procter & Gamble cuts model deployment time up to 90% with Azure IoT Operations Toyota: Toyota Industries innovates its paint shop processes with Azure industrial AI and Azure IoT Hub1.4KViews3likes0CommentsMicrosoft Industrial AI Partner Guide: Choosing the Right Data Expertise for Every Stage
As organizations scale Industrial AI, the challenge shifts from technology selection to deciding who should lead which part of the journey -- and when. Which partners should establish secure connectivity? Who enables production grade, AI ready industrial data? When do systems integrators step in to scale globally? This Partner Guide helps customers navigate these decisions with clarity and confidence: Identify which partners align to their current digital transformation and Industrial AI scenarios leveraging Azure IoT and Azure IoT Operations Confidently combine partners over time as they evolve from connectivity to intelligence to autonomous operations This guide focuses on the Industrial AI data plane – the partners and capabilities that extract, contextualize, and operationalize industrial data so it can reliably power AI at scale. It does not attempt to catalog or prescribe end‑to‑end Industrial AI applications or cloud‑hosted AI solutions. Instead, it helps customers understand how industrial partners create the trusted, contextualized data foundation upon which AI solutions can be built. Common Customer Journey Steps 1. Modernize Connectivity & Edge Foundations The industrial transformation journey starts with securely accessing operational data without touching deterministic control loops. Customers connect automation systems to a scalable, standards-based data foundation that modernizes operations while preserving safety, uptime and control. Outcomes customers realize Standardized OT data access across plants and sites Faster onboarding of legacy and new assets Clear OT–IT boundaries that protect safety and uptime Partner strengths at this stage Industrial hardware and edge infrastructure providers Protocol translation and OT connectivity Automation and edge platforms aligned with Azure IoT Operations 2. Accelerate Insights with Industrial AI With a consistent edge-to-cloud data plane in place, customers move beyond dashboards to repeatable, production-grade Industrial AI use cases. Customers rely on expert partners to turn standardized operational data into AI‑ready signals that can be consumed by analytics and AI solutions at scale across assets, lines, and sites. Outcomes customers realize Improved Operational efficiency and performance Adaptive facilities and production quality intelligence Energy, safety, and defect detection at scale Partner strengths at this stage Industrial data services that contextualize and standardize OT signals for AI consumption Domain-specific acceleration for common Industrial AI scenarios Data pipelines integrated with Azure IoT Operations and Microsoft Fabric 3. Prepare for Autonomous Operations As organizations advance toward closed‑loop optimization, the focus shifts to safe, scalable autonomy. Customers depend on partners to align data, infrastructure, and operational interfaces, while ensuring ongoing monitoring, governance, and lifecycle management across the full operational estate. Outcomes customers realize Proven reference architectures deployed across plants AI‑ready data foundations that adapt as operations scale Coordinated interaction between OT systems, AI models, and cloud intelligence Partner strengths at this stage Industrial automation leadership and control system expertise Edge infrastructure optimized and ready for Industrial AI scale Systems integrators enabling end‑to‑end implementation and repeatability Data Intelligence Plane of Industrial AI - Partner Matrix This matrix highlights which partners have the deepest expertise in accessing, contextualizing, and operationalizing industrial data so it can reliably power AI at scale. The matrix is not a catalog of end‑to‑end Industrial AI applications; it shows how specialized partners contribute data, infrastructure, and integration capabilities on a shared Azure foundation as organizations progress from connectivity to insight to autonomous operations. How to use this matrix: Start with your scenario → identify primary partner types → layer complementary partners as you scale. Partner Type Adaptive Cloud Primary Solution Example Scenarios Geography Advantech Industrial Hardware, Industrial Connectivity LoRaWAN gateway integration + Azure IoT Operations Industrial edge platforms with built in connectivity, industrial compute, LoRaWAN, sensor networks Global Accenture GSI Industrial AI, Digital Transformation, Modernization OEE, predictive maintenance, real-time defect detection, optimize supply chains, intelligent automation and robotics, energy efficiency Global Avanade GSI Factory Agents and Analytics based on Manufacturing Data Solutions Yield / Quality optimization, OEE, Agentic Root Cause Analysis and process optimization; Unified ISA-95 Manufacturing Data estate on MS Fabric Global Belden Industrial Connectivity, Networking, Security Belden Horizon Data Operations (BHDO) + LioN-X with Azure IoT Operations OT-IT convergence, network orchestration and monitoring, ruggedized ethernet and switching, industrial WiFi, multi-vendor protocol connectivity, OT security, OPC UA Global Capgemini GSI The new AI imperative in manufacturing OEE, maintenance, defect detection, energy, robotics Global DXC GSI Intelligent Boost AI and IoT Analytics Platform 5G Industrial Connectivity, Defect detection, OEE, safety, energy monitoring Global Innominds SI Intelligent Connected Edge Platform Predictive maintenance, AI on edge, asset tracking North America, EMEA Litmus Automation Industrial Connectivity, Industrial Data Ops Litmus Edge + Azure IoT Operations Edge Data, Smart manufacturing, IIoT deployments at scale Global, North America Mesh Systems GSI & ISV Azure IoT & Azure IoT Operations implementation services and solutions (including Azure IoT Operations-aligned connector patterns) Device connectivity and management, data platforms, visualization, AI agents, and security North America, EMEA Nortal GSI Data-driven Industry Solutions IT/OT Connectivity, Unified Namespace, Digital Twins, Optimization, Edge, Industrial Data, Real‑Time Analytics & AI EMEA, North America & LATAM NVIDIA Technology Partner Accelerated AI Infrastructure; Open libraries, models, frameworks, and blueprints for AI development and deployment. Cross industry digitalization and AI development and deployment: Generative AI, Agentic AI, Physical AI, Robotics Global Oracle ISV Oracle Fusion Cloud SCM + Azure IoT Operations Real-time manufacturing Intelligence, AI powered insights, and automated production workflows Global Rockwell Automation Industrial Automation FactoryTalk Optix + Azure IoT Operations Factory modernization, visualization, edge orchestration, DataOps with connectivity context at scale, AI ops and services, physical equipment, MES Global Schneider Electric Industrial Automation Industrial Edge Physical equipment, Device modernization, energy, grid Global Siemens Industrial Automation & Software Industrial Edge + Azure IoT Operations reference architecture Industrial edge infrastructure at scale, OT/IT convergence, DataOps, Industrial AI suite, virtualized automation. Global Sight Machine ISV Integrated Industrial AI Stack Industrial AI, bottling, process optimization Global Softing Industrial Industrial Connectivity edgeConnector + Azure IoT Operations OT connectivity, multi-vendor PLC- and machine data integration, OPC UA information model deployment EMEA, Global TCS GSI Sensor to cloud intelligence Operations optimization, healthcare digital twin experiences, supply chain monitoring Global This Ecosystem Model enables Industrial AI solutions to scale through clear roles, respected boundaries and composable systems: Control systems continue to be driven by automation leaders Safety‑critical, deterministic control stays with industrial automation partners who manage real‑time operations and plant safety. Customers modernize analytics and AI while preserving uptime, reliability, and operational integrity. Data, AI, and analytics scale independently A consistent edge to cloud data plane supports cloud scale analytics and AI, accelerating insight delivery without entangling control systems or slowing operational change. This separation allows customers and software providers to build AI solutions on top of a stable, industrial‑grade data foundation without redefining control system responsibilities. Specialized partners align solutions across the estate Partners contribute focused expertise across connectivity, analytics, security, and operations, assembling solutions that reduce integration risk, shorten deployment cycles, and speed time to value across the operational estate. From vision to production Industrial AI at scale depends on turning operational data into trusted, contextualized intelligence safely, repeatably, and across the enterprise. This guide shows how industrial partners, aligned on a shared Azure foundation, create the data plane that enables AI solutions to succeed in production. When data is ready, intelligence scales. Call to action: Use this guide to identify the partners and capabilities that best align to your current Industrial AI needs and take the next step toward production‑ready outcomes on Azure.2.1KViews4likes0Comments
The Clinical Friction Ledger: Should Every Healthcare AI Tool Remove More Work Than It Creates?
The Clinical Friction Ledger: Should Every AI Feature Remove More Work Than It Creates? One question I keep coming back to is this: How can a healthcare organization determine whether an AI tool is actually reducing work? I propose a simple working framework—the Clinical Friction Ledger. On one side, record the friction removed: documentation time, unnecessary clicks, repeated data entry, handoffs, and waiting. On the other side, record the friction added: verification time, new alerts, exception handling, training, and work quietly transferred to another person or shift. An AI model can look impressive in a demonstration while making the overall care process harder. Before an AI pilot is scaled, both sides of this ledger should be examined. If the friction added outweighs the friction removed—or if the burden is simply shifted to someone else—the productivity claim is incomplete. The real measure of success is not only what the AI can do. It is whether the people closest to care experience less friction because of it. What would you put on each side of the Clinical Friction Ledger?181Views0likes0Comments
August 20 Federal Event: Accelerating Enterprise Modernization, AI & Cybersecurity
Overview Federal agencies are under increasing pressure to modernize mission systems, strengthen cybersecurity, and responsibly adopt artificial intelligence. Executive Order 14409, record federal technology investments, and Microsoft's OneGov initiative have created a unique opportunity to accelerate secure digital transformation. What Attendees Will Learn How agencies are translating AI strategy into operational outcomes. Microsoft's latest AI, cybersecurity, and modernization capabilities. How Microsoft OneGov is accelerating secure AI adoption across federal agencies. Real-world modernization strategies and success stories from CDC and USGS. Practical approaches to modernizing legacy systems while improving mission outcomes. Plus: Every attendee receives a complimentary 30-minute FY27 AI Readiness Consultation with a MERP Solutions Architect. Why Attend Join MERP Systems and Microsoft to discover the latest AI and cybersecurity innovations and hear directly from CDC and USGS as they share real-world enterprise modernization strategies and success stories. Attendees will leave with actionable insights, proven approaches, and a better understanding of how to accelerate secure AI adoption across their organizations. Event Link- https://events.teams.microsoft.com/event/b58ebc1e-e927-4e66-b73c-f25d7f43be7f@c33861f9-4a57-4bc4-bc88-d6e0c7b92c37?source=copyLinkOneEventsShareDialogTrain a simple Recommendation Engine using the new Azure AI Studio
The AI Studio Odyssey: Embark on a journey to the heart of personalization with our latest guide, “Train a Simple Recommendation Engine using the new Azure AI Studio.” Unlock the secrets of the all-new Azure AI Studio intuitive tools to craft a recommendation system that feels like magic, yet is grounded in data and user preferences. Ready to enchant your audience? Grab some popcorn and read on!6.9KViews0likes2CommentsSet Up Plaud Note Pro with Microsoft Foundry
Prerequisites Riffado, up and running: follow the setup guide in the official Riffado repository to get it going with Docker Compose. A Microsoft Foundry (formerly Azure AI Foundry) resource, with the models you want deployed; in my case, whisper for transcription and o3-mini for summaries. A Plaud device, or any audio recordings you can import into Riffado. Once Riffado is up, head to the Settings page > Providers > Add Provider, and select Custom. This is where the Azure details will go. Why "OpenAI-compatible" isn’t one thing on Microsoft Foundry Azure AI Foundry exposes two different API surfaces on the same resource, and which one serves your model depends on the model: Surface Path shape Serves OpenAI-compatible? v1 route /openai/v1/… gpt-4o-transcribe, gpt-4o-mini-transcribe, chat models, embeddings Yes: Bearer auth, model in the body, no api-version needed Classic route /openai/deployments/{name}/… Whisper (and other legacy audio) No: deployment name lives in the URL, and ?api-version= is mandatory A generic OpenAI client (Riffado's included) can only speak the first dialect. It has nowhere to put a deployment name in the path and no way to append a query parameter. That single fact drives everything below. Part 1 - Transcription Whisper and the DeploymentNotFound mystery Symptom My very first transcription attempt in Riffado failed with 404 Resource not found. Off to a flying start. Configured provider: base URL https://<resource>.services.ai.azure.com, model whisper. Dead end #1: the missing path The first bug was mine: the base URL had no path. Riffado's OpenAI client appends /audio/transcriptions to whatever you give it, so requests were hitting https://<resource>…/audio/transcriptions, a path that doesn't exist on the resource at all. Fixing the base URL to end in /openai/v1 got us to a more interesting error: POST /openai/v1/audio/transcriptions · model=whisper {"error":{"code":"DeploymentNotFound","message":"The API deployment for this resource does not exist. If you created the deployment within the last 5 minutes, please wait a moment and try again."}} Dead end #2: catalog ≠ deployment Worth checking before anything else: selecting a model in the Foundry catalog is not deploying it. GET /openai/v1/models lists everything you could deploy; only Deployments → Deploy model creates an endpoint that answers. If you get DeploymentNotFound, first confirm a deployment actually exists (the listing below requires only the API key): enumerate real deployments (classic control-plane, key auth) curl -s -H "api-key: $KEY" \ "https://<resource>.openai.azure.com/openai/deployments?api-version=2023-03-15-preview" # → {"data":[{"id":"whisper","model":"whisper","status":"succeeded",…}]} The actual cause Here is the part that nearly drove me mad: the deployment existed and was succeeded, yet the v1 route still said DeploymentNotFound. Because Whisper deployments are not served on the v1 route at all. They only answer on the classic path. Verified side by side with the same tiny WAV file: Request Result POST /openai/v1/audio/transcriptions · model=whisper · Bearer 404 DeploymentNotFound POST /openai/deployments/whisper/audio/transcriptions?api-version=2024-06-01 · Bearer 200 {"text":"you"} Same classic path, without ?api-version= 404 Resource not found Three constraints, then: Whisper needs the classic path; the classic path needs api-version; Riffado can send neither. One piece of good news hiding in the table: the classic route accepts Authorization: Bearer, not just Azure's api-key header, so the shim doesn't have to touch auth at all. The fix: a Caddy shim Drop a stock caddy:2-alpine container into the Compose network. Riffado points at it as if it were OpenAI; the shim rewrites the path, injects api-version, and proxies to Azure. The Bearer header passes through untouched. azure-shim.Caddyfile { admin off auto_https off } :80 { @transcribe path /v1/audio/transcriptions /audio/transcriptions handle @transcribe { rewrite * /openai/deployments/whisper/audio/transcriptions?api-version=2024-06-01 reverse_proxy https://<resource>.services.ai.azure.com { header_up Host <resource>.services.ai.azure.com } } handle { respond "azure-shim ok" 200 } } docker-compose.yml (added service) azure-shim: image: caddy:2-alpine restart: unless-stopped volumes: - ./azure-shim.Caddyfile:/etc/caddy/Caddyfile:ro Riffado's provider settings become: Field Value Base URL http://azure-shim/v1 Model whisper (must equal the deployment name) API key the Azure resource key (forwarded as Bearer) Verified From inside the Riffado container: POST http://azure-shim/v1/audio/transcriptions → 200 {"text":"…"}. Transcription works end-to-end in the UI. Part 2 · Summaries & titles o3-mini and the empty answer Symptom The summary button showed "An unexpected error occurred." The container logs were more honest: riffado-app logs Error generating title: TypeError: undefined is not an object (evaluating 'C.choices[0]') Riffado calls chat/completions and reads choices[0] without checking whether the response was an error. So anything the API refuses becomes "an unexpected error." What was it refusing? Cause 1: reasoning models reject the classic knobs o3-mini belongs to Azure/OpenAI's o-series reasoning models, which hard-reject parameters every classic chat client sends. Riffado sends temperature: 0.7 and max_tokens: 50 for titles (0.5 / 2000 for summaries), and o3-mini answers: POST /openai/v1/chat/completions · model=o3-mini HTTP 400 {"error":{"message":"Unsupported parameter: 'max_tokens' is not supported with this model. Use 'max_completion_tokens' instead.", …}} # and with max_tokens fixed: HTTP 400 {"error":{"message":"Unsupported parameter: 'temperature' is not supported with this model.", …}} Cause 2: reasoning tokens starve the output Stripping the bad params gets you to 200, and then comes a subtler failure, my personal favourite of this whole saga. Reasoning models spend completion tokens on internal "thinking" before emitting a single visible character. Riffado's 50-token title budget is consumed entirely by reasoning, and the reply comes back syntactically valid and empty: max_completion_tokens reasoning_effort finish_reason content 50 not set length "" (all 50 spent reasoning) 2000 not set stop "Q3 Budget Planning Strategy Meeting" 2000 low stop same, less reasoning overhead The fix: a Node shim that rewrites the request body Caddy can rewrite paths but not JSON bodies, so this shim is ~60 lines of dependency-free Node on node:20-alpine. Per request it: converts max_tokens → max_completion_tokens, strips temperature / top_p / penalties, floors the token budget at 4000, sets reasoning_effort: "low", maps /v1/* → /openai/v1/*, and forwards to the Azure resource. o3-shim.js const http = require('http'); const https = require('https'); const UPSTREAM_HOST = '<resource>.services.ai.azure.com'; // Params o-series reasoning models reject on chat/completions. const STRIP = ['temperature','top_p','presence_penalty', 'frequency_penalty','logprobs','top_logprobs']; const server = http.createServer((req, res) => { const chunks = []; req.on('data', c => chunks.push(c)); req.on('end', () => { let body = Buffer.concat(chunks); // Riffado's base_url is http://o3-shim/v1 → map to Azure's /openai/v1 let path = req.url; if (path.startsWith('/v1/')) path = '/openai' + path; const ct = (req.headers['content-type'] || '').toLowerCase(); if (ct.includes('application/json') && body.length) { try { const j = JSON.parse(body.toString('utf8')); if (j && typeof j === 'object' && !Array.isArray(j)) { if ('max_tokens' in j) { if (!('max_completion_tokens' in j)) j.max_completion_tokens = j.max_tokens; delete j.max_tokens; } // Reasoning spends tokens before any visible output; small // budgets (Riffado sends 50 for titles) return empty strings. if (Array.isArray(j.messages)) { j.max_completion_tokens = Math.max(Number(j.max_completion_tokens) || 0, 4000); if (!('reasoning_effort' in j)) j.reasoning_effort = 'low'; } for (const k of STRIP) delete j[k]; body = Buffer.from(JSON.stringify(j)); } } catch (_) { /* not JSON - forward untouched */ } } const headers = { ...req.headers, host: UPSTREAM_HOST, 'content-length': Buffer.byteLength(body) }; const up = https.request( { host: UPSTREAM_HOST, port: 443, method: req.method, path, headers }, upRes => { res.writeHead(upRes.statusCode, upRes.headers); upRes.pipe(res); } ); up.on('error', e => { res.writeHead(502, {'content-type':'application/json'}); res.end(JSON.stringify({error:{message:'o3-shim upstream error: '+e.message}})); }); up.end(body); }); }); server.listen(80, () => console.log('o3-shim listening on :80')); docker-compose.yml (added service) o3-shim: image: node:20-alpine restart: unless-stopped working_dir: /app command: ["node", "/app/o3-shim.js"] volumes: - ./o3-shim.js:/app/o3-shim.js:ro Add a second provider in Riffado (base URL http://o3-shim/v1, model o3-mini, the resource's API key) and set it as the default enhancement provider (summaries/titles), keeping the Whisper one as default for transcription. Riffado's exact title request (temperature: 0.7, max_tokens: 50) through the shim → 200, finish_reason: stop, real title text. A full meeting-transcript summary returns structured key points and action items. The final shape Reading it left to right: Riffado never talks to Azure directly. Transcription requests pass through azure-shim, a stock Caddy container that rewrites each request onto Whisper's classic deployment path and injects the mandatory api-version parameter. Summary and title requests pass through o3-shim, a tiny Node server that rewrites the request body into the shape o3-mini accepts and floors the token budget so the model's internal reasoning cannot starve the actual answer. As far as Riffado is concerned, it is simply talking to two ordinary OpenAI providers. Both shims live on the Compose network only; nothing is exposed publicly. Riffado is unmodified. Verification checklist Each layer, testable in isolation. Run these before blaming the app: smoke tests # 1. Key + resource alive? (v1 models listing, Bearer auth) curl -s -H "Authorization: Bearer $KEY" \ https://<resource>.services.ai.azure.com/openai/v1/models | head -c 200 # 2. Whisper answers on the classic path? curl -s -H "Authorization: Bearer $KEY" -F file=@test.wav \ "https://<resource>.services.ai.azure.com/openai/deployments/whisper/audio/transcriptions?api-version=2024-06-01" # 3. Shim translates correctly? (from inside the compose network) docker exec riffado-app node -e "fetch('http://azure-shim/') .then(r=>r.text()).then(console.log)" # 4. o3-mini via shim, sending the params Riffado sends? # (temperature + max_tokens:50; the shim must absorb both) If you'd rather not run shims Both shims exist because of the specific models chosen. Pick models that live natively on the v1 route and Riffado connects directly, with base URL https://<resource>.services.ai.azure.com/openai/v1 and zero extra containers: Transcription: deploy gpt-4o-mini-transcribe (or gpt-4o-transcribe) instead of Whisper. Summaries: deploy a non-reasoning chat model such as gpt-4o-mini, which happily accepts temperature and max_tokens. The shim approach earns its keep when you're standardized on specific models (Whisper's transcription quality, o3-mini's reasoning), or when you want a control point to add logging, retries, or budget caps later. For reference, this is what the finished setup looks like on Riffado's side. Each shim is registered as a plain Custom provider. Here is the whisper provider pointing at azure-shim, with Use for transcription ticked: And once both are saved, they sit side by side in the providers list, whisper tagged for transcription and o3-mini tagged for enhancement: A quick look at the Foundry portal In the Microsoft Foundry portal, head over to Models > AI Services and you will find a pleasant surprise: fifteen AI service models already deployed and ready to use, covering the Azure Speech family (including Voice Live and Speech to Text), Azure Translator, Azure Language, and Content Understanding: You can of course deploy another model for this, but the pre-deployed ones are a handy cost-saving option. Click on the Azure Speech – Voice Live radio button and you will be shown the Base URL and API Key, which you can then paste into the provider settings on Riffado's Settings page. A quick note on cost: these services are not free. They are billed pay-as-you-go based on usage. Azure Speech transcription is charged per audio hour, and Voice Live pricing is tiered by the model you choose. The free tier does include a monthly allowance, though. Check the Azure Speech pricing page before committing. And if you would rather deploy a dedicated transcription model such as whisper, Foundry gives you the flexibility to do just that. Open the model page in the catalogue, click Deploy, and go with Default settings unless you need custom quotas or guardrails: Let's test the setup On your Plaud device, just tap to start recording. The little LED bars light up to show it is listening: Or skip the device entirely and upload an audio file straight into Riffado using the Upload Audio button. Either way, the recording lands on the Recordings page; hit Transcribe and let the spinner do its thing: As you can see below, whisper, the transcription model we deployed earlier, even managed to transcribe a recording in Malay without a hitch. My 3:32 test clip came back as 186 words of clean Malay, with the language correctly detected and tagged: I have also set o3-mini as the enhancement provider, and it enhanced the transcription with a proper summary, key points, and title as well! The Meeting Notes-style summary came straight out of o3-mini through the shim, with zero manual prompting. Wrapping up What started as a TikTok-fuelled impulse buy nearly killed off by subscription pricing ended up as a fully self-hosted pipeline: Plaud for recording, Riffado as the interface, and Microsoft Foundry serving whisper and o3-mini behind two tiny shims. The total extra infrastructure came to two containers and roughly sixty lines of code, and not a single monthly subscription in sight. If you try this setup and run into a failure mode I have not covered here, do share it in the comments. Half the fun is in the debugging.402Views0likes0Comments
腾龙公司游戏网址
维《T L 9 1 9 9 8》公司开户罔纸《T L 0 6 8 . v i p 》 腾龙公司是扎根于 缅甸果敢自治区的多元化企业秉持 诚信 创新 共赢的理念, 经过多年发展业务以涵盖 房地产 基建 旅游 物流运输 以及农产品加工等多个领域, 在房地产领域公司凭借专业团队,打造出多个现代化住宅与商业化项目, 推动果敢老街城市化和公共设施建设,助力当地基础设施升级, 旅游板块投资建设高端酒店和绿发展度假村,位游客带来舒适体验, 带动区域旅游发展,物流运输上建立高效物流网络, 为企业和居民提供便捷服务 农产品加工中引入新建技术, 提升农产品附加值 增加农民收入 不仅如此 公司始终将社会责任抗在肩头。 积极投身公益事业 在教育医疗和环境保护等领域大力支持, 为果敢地区发展贡献力量,为公司将持续创新拓展业务版图, 促进区域繁荣 在新时代书写更多辉煌篇章 下期科普腾龙公司现状 带大家更多了解缅甸果敢老街376Views17likes0CommentsEmpowering the AI Generation: Microsoft's Open-Source Initiative
In a world increasingly driven by open collaboration and community-driven innovation, Microsoft has undergone a remarkable transformation. The tech giant is on a mission to provide students, startups, AI developers, and entrepreneurs with the tools and resources they need to build groundbreaking solutions. Embracing open source is at the heart of this journey.7.3KViews3likes1CommentResponsible Synthetic Data Creation for Fine-Tuning with RAFT Distillation
This blog will explore the process of crafting responsible synthetic data, evaluating it, and using it for fine-tuning models. We’ll also dive into Azure AI’s RAFT distillation recipe, a novel approach to generating synthetic datasets using Meta’s Llama 3.1 model and UC Berkeley’s Gorilla project.2.5KViews2likes0Comments