artificial intelligence
410 TopicsIntroducing Microsoft-Decision-1 in Microsoft Foundry for decision and classification workloads
Not every step in an AI application needs a large language model to generate a response. Many high-volume application steps are decisions: classify an input, select an option, assign a score, verify a condition, prioritize an item, or control a workflow. To suit these tasks, a new class of models have been developed to address these fast, structured, requests. We are excited to be adding Microsoft-Decision-1 to the Foundry Models Catalog. Our newest, decision model for applications that need to choose among predefined options rather than generate open-ended text. What are decision models? As AI applications mature, the industry is moving beyond the idea that every model interaction needs to result in generated content. Developers are increasingly building systems composed of different models, tools, and application logic, each suited to a different part of the workload. Within those systems, many of the most frequent operations are not generation problems at all. They are decisions about what should happen next. Decision models were designed for this emerging layer of the AI stack. Rather than producing an open-ended response, they evaluate a defined set of possibilities and return structured signals that an application can use to take action. That makes them particularly relevant as developers move toward more dynamic AI applications, where models need to work together and applications must continuously determine where requests should go, which actions should be taken, and when additional processing is needed. For developers, this creates an opportunity to be more intentional about where and how different models are used. Instead of relying on a general-purpose generative model for every step, developers can match the model to the task, using generative and reasoning models where their capabilities are needed and decision models for focused, repeatable choices. The result is a more modular approach to AI application design, where generation, reasoning, and decision-making become complementary building blocks for creating intelligent systems. What is Microsoft-Decision-1? Now available in public preview, Microsoft-Decision-1 is a decision model built on Qwen3.5-9B and designed for applications that need to make fast, structured choices among predefined options. It brings a purpose-built decision capability to the Foundry Models catalog, giving developers another building block for designing AI applications where different steps may benefit from different types of models. Built for predefined decisions. Microsoft-Decision-1 supports use cases such as agent controls, model routing, intent analysis, data labeling, AI judging, incident response routing, data validation, and content classification. Structured for application logic. The model produces predefined answers and confidence signals that applications can use to select the next action or route uncertain results for further review. Designed for lower-latency, lower-cost workflows. Microsoft-Decision-1 is intended for simple, repeatable, and time-sensitive decisions that do not require the generative capabilities or extended reasoning of a larger language model. You can explore these capabilities in the Foundry Playground. This example below shows Microsoft-Decision-1 checking urgency, selecting a support team, and scoring priority for a customer request. Microsoft-Decision-1 represents an area of continued model innovation at Microsoft. The team will rebase future iterations of the model on OpenAI models and Microsoft’s MAI models, bringing together advances from Microsoft’s own model portfolio with a model architecture purpose-built for decision-making. Over time, this work could create opportunities to further explore how Microsoft models can be specialized for the high-volume decisions that sit inside applications and agentic systems. For developers, Microsoft-Decision-1 expands the choices available when building applications and agents with Foundry. Rather than using the same model for every step, developers can combine generative and reasoning models with a decision model and choose the capability that best fits each part of the workflow. That model diversity is increasingly important as AI applications evolve from single-model experiences into systems that coordinate specialized models, tools, and actions. How developers are building with Microsoft-Decision-1 Enterprise applications make decisions throughout a workflow: identifying a customer’s intent, selecting a tool, routing an incident or checking whether a response meets specified criteria. For example, a support application could classify a request as a billing question, a technical issue or an account-access problem. An agent could evaluate a proposed response against a quality rubric and determine whether to accept it, revise it or request review. If the player doesn’t load, open the video in a new window: Open video These decisions can sit alongside generative and reasoning steps in the same application. A language model might draft a response, while Microsoft-Decision-1 evaluates it against defined criteria. With Microsoft-Decision-1 in the Foundry catalog, developers can explore decision workloads through the platform they use to discover and deploy models across various scenarios: Classification: Assign inputs to defined categories, such as customer intents or feedback themes. Routing: Select a model, tool, destination or workflow from a set of options. Evaluation and verification: Assess responses or inputs against specified criteria. Workflow control: Decide whether to continue, retry, stop or send a case for review. A different model for a different kind of workload For developers, decision models introduce a different way to think about optimization. An AI application may make thousands of small choices around a comparatively small number of complex generative or reasoning tasks. Running every one of those steps through the same general-purpose model can overlook an opportunity to optimize the system around the work each step actually needs to perform. That pattern is showing up across Microsoft. Xbox Research used Microsoft-Decision-1 to categorize more than 10,000 pieces of open-ended feedback into researcher-defined themes, reporting quality competitive with GPT-5 while running 80–100 times faster. Other Microsoft teams have also evaluated the model for assessing Copilot response quality and supporting adaptive replanning in Microsoft Discovery. These scenarios matter because they are not simply classification benchmarks. They are examples of decisions embedded inside larger applications. As AI architectures become more modular, developers can consider generation, reasoning, and decision-making as distinct workloads, then select models based on what each step actually requires. For benchmark methodology, measured results and additional examples, read the Command Line blog here. Putting Microsoft-Decision-1 to work For tasks with predefined outcomes, evaluate Microsoft-Decision-1 using representative inputs and the quality, latency and cost requirements of your application. Compare decision accuracy, including ambiguous cases, latency under expected traffic and cost per completed decision. Where confidence estimates inform automation or review thresholds, validate their calibration on your own data. Start with a decision in your application: The following Python example shows how to compare support-routing decisions with expected labels and measure request latency. Replace the illustrative messages and category definitions with examples from your own workload. Before running: Deploy Microsoft-Decision-1 in your Microsoft Foundry subscription and configure FOUNDRY_BASE_URL and FOUNDRY_API_KEY. Set FOUNDRY_MODEL to the model or deployment identifier specified in the quickstart. Keep credentials outside the source code. Model requests incur applicable usage charges. Integration note: Confirm the route and authentication header before running it against your deployment. #!/usr/bin/env python3 """Classify support requests with Microsoft-Decision-1.""" import json import os import urllib.error import urllib.request from collections.abc import Mapping from statistics import median from time import perf_counter from typing import Any from azure.identity import DefaultAzureCredential OPTIONS = { "billing": "Charges, invoices, refunds, or subscription payments", "technical": "Software errors, bugs, or integration failures", "account": "Sign-in, password, or account-access problems", } EXAMPLES = [ ("I was charged twice.", "billing"), ("The integration crashes during checkout.", "technical"), ("I cannot sign in after resetting my password.", "account"), ] AZURE_ENDPOINT = os.environ["AZURE_ENDPOINT"].rstrip("/") DEPLOYMENT_NAME = os.environ["DEPLOYMENT_NAME"] TIMEOUT_SECONDS = 60 TOKEN_SCOPE = "https://cognitiveservices.azure.com/.default" CREDENTIAL = DefaultAzureCredential() class DecisionAPIError(RuntimeError): """Raised when the API can't return a valid classification.""" def read_choice( payload: Any, options: Mapping[str, str], ) -> str: if not isinstance(payload, dict): raise DecisionAPIError("The API returned an invalid response.") answers = payload.get("answers") if not isinstance(answers, dict): raise DecisionAPIError("The API returned no answers object.") answer = answers.get("team") if not isinstance(answer, dict) or answer.get("type") != "choice": raise DecisionAPIError("The API returned an invalid answer.") choice = answer.get("choice") if not isinstance(choice, str) or choice not in options: raise DecisionAPIError( f"The API selected an unsupported team: {choice!r}." ) return choice def predict( text: str, options: Mapping[str, str], ) -> str: if not text.strip(): raise ValueError("text must not be empty.") if len(options) < 2: raise ValueError("options must contain at least two choices.") body = json.dumps( { "model": DEPLOYMENT_NAME, "state": text, "questions": { "team": { "type": "choice", "instructions": ( "Which team should handle this customer support " "request? Select exactly one team based on the " "primary problem." ), "criteria": dict(options), } }, } ).encode("utf-8") access_token = CREDENTIAL.get_token(TOKEN_SCOPE).token request = urllib.request.Request( f"{AZURE_ENDPOINT}/providers/microsoft/v1/systemone", data=body, headers={ "Authorization": f"Bearer {access_token}", "Content-Type": "application/json", "Accept": "application/json", }, method="POST", ) try: with urllib.request.urlopen( request, timeout=TIMEOUT_SECONDS, ) as response: response_body = response.read() except urllib.error.HTTPError as exc: raise DecisionAPIError( f"The API returned HTTP {exc.code}." ) from exc except urllib.error.URLError as exc: raise DecisionAPIError( f"Couldn't reach the API: {exc.reason}." ) from exc try: payload = json.loads(response_body) except (json.JSONDecodeError, UnicodeDecodeError) as exc: raise DecisionAPIError( "The API returned invalid JSON." ) from exc return read_choice(payload, options) def main() -> None: correct = 0 latencies_ms = [] for text, expected in EXAMPLES: start = perf_counter() predicted = predict(text, OPTIONS) elapsed_ms = (perf_counter() - start) * 1000 correct += int(predicted == expected) latencies_ms.append(elapsed_ms) print( f"Expected={expected}, predicted={predicted}, " f"latency={elapsed_ms:.1f} ms" ) accuracy = correct / len(EXAMPLES) print(f"Accuracy: {accuracy:.1%}") print( "Median request latency: " f"{median(latencies_ms):.1f} ms" ) if __name__ == "__main__": main() This small dataset illustrates the evaluation process. For meaningful results, use a larger, representative labeled dataset and inspect errors by category. The measured latency includes the client call and network time; sequential requests do not measure latency under production load. Assess cost and confidence calibration separately. Your application defines the available options and resulting actions. Use evaluation results to determine where automation is appropriate and where additional validation or human review is needed. Pricing Model Deployment Type Input Tokens (#/1M) Output tokens (#/1M) Microsoft-Decision-1 US Datazone $0.042 N/A EU Datazone $0.042 N/A Get started Explore Microsoft-Decision-1 in the Foundry catalog to make your first request. We look forward to seeing how developers use Microsoft-Decision-1 to bring structured decisions into their applications and agents through Microsoft Foundry.6KViews1like1CommentMicrosoft Foundry Guardrails Getting in Your Way? Here’s How to Dial Them Down
How This All Started So here’s the story. I just got back from a trip and had a pile of footage sitting on my laptop. Being the lazy (sorry, efficient) person I am, I fired up OpenCode and asked GPT-6 Astra, running on Microsoft Foundry, to cut me a travelogue. Nothing fancy: under two minutes, nice lighting, clean transitions, no cringy effects, a quick QA before showing me, and the output in its own folder. Easy, right? Nope. This is what I got instead: “Image processing blocked due to content policy violation.” Seriously? It’s holiday footage! Nothing even remotely dodgy in there. This is a classic false positive from the default guardrails, and the good news is it’s totally fixable. Let me show you how. My Setup Quick context before we dive in: I’ve got two models deployed on Microsoft Foundry, gpt-6-astra and gpt-6-sol. Both were running on Microsoft’s out-of-the-box guardrail. Step 1: Find the Guardrails Page Head over to the Microsoft Foundry portal, click Build, then hit Guardrails in the left menu. You’ll see three guardrails that Microsoft gives you by default: Microsoft.Default, Microsoft.DefaultV2 and Microsoft.MAIDefault. Microsoft.DefaultV2 is the one every new deployment gets, which is why it’s sitting on both of my models. Here’s the catch: you can’t edit or delete these Microsoft-managed defaults. So instead of tweaking them, we’re going to build our own guardrail and swap it in. Step 2: Create Your Own Guardrail Smash that "Create" button and you’ll land on the Create guardrail page. This is where all the knobs and switches live: Every control has three bits: the risk type, the intervention point (does it check what you send in, what the model spits out, or both?) and the action. The magic trick for loosening things up is flipping the action from Block to Annotate. With Annotate, Foundry still scans the content and tags it in the API response, but it stops slamming the door on your request. So What Does Each Setting Actually Do? Before you go on a switching-off spree, it’s worth knowing what each of these does and what you’re giving up when you loosen it. Here’s the quick tour: Jailbreak: This one catches prompts trying to trick the model into ignoring its rules. On Block, those prompts get rejected outright. On Annotate, they go through with a flag. Turn it off completely and you’re trusting the model’s own training to keep it in line. Network (egress rules): Controls which outbound calls a hosted agent is allowed to make. As the portal points out, it only applies to hosted agents, so for plain model deployments like mine it doesn’t change a thing. Indirect prompt injections: Watches user input and tool responses (files, docs, web pages the model reads) for sneaky instructions someone has planted. Leave it on and your agents are protected when they read outside content; switch it off and a dodgy file could quietly hijack your model. For an agentic tool like OpenCode, which reads files and runs shell commands, I’d honestly keep this one on, even if it’s just on Annotate. Spotlighting (Preview): Tags external content inside the prompt so the model can tell your real instructions apart from random untrusted data. Think of it as an extra seatbelt against indirect attacks. Content harms (Hate, Sexual, Self-harm, Violence): Each of these has a severity slider that starts at Medium blocking, meaning anything rated medium or higher gets blocked. Slide it down to Lowest blocking and only the really nasty stuff gets stopped, which kills off most false positives like mine. The asterisk means these four are mandatory: you can turn the dial down, but you can’t switch them off. Blocklists: Want to ban specific words or phrases, like profanity or your competitor’s name? This is where you do it. It’s off by default. Protected material for code and text: Checks whether the model is about to spit out known copyrighted text (song lyrics, articles and so on) or code lifted from public repos. Block stops it; Annotate lets it through with a flag. Switch it off and you’re rolling the dice on your app reproducing someone else’s copyrighted work. Step 3: Pick Your Models Hit Next and Foundry asks which agents and models you want this guardrail on. Any model you’ve already deployed in your project shows up here. For me that’s gpt-6-astra and gpt-6-sol, so I ticked both. Step 4: Name It and Pick a Streaming Mode One more Next and you’re on the Review page. Give your guardrail a name (I went with NoGuardrails, because subtlety isn’t my thing) and pick a streaming mode. You’ve got two choices: Default: Foundry buffers the response and runs it through the guardrail before each chunk goes out. Nothing reaches the user until it’s been checked. Safest option, but you’ll feel a bit of lag when streaming. Asynchronous: Content streams back the moment it’s generated, with the filters running in the background. Much snappier, but flagged content might flash up briefly before the filter catches it, so your app has to clean up after the fact. Microsoft pitches this for low-latency stuff like internal dev tools, which is exactly my use case. Give the summary a quick once-over, then click Create. Done! Did It Work? Yep! With my shiny new guardrail in place, I fired off the exact same request, this time to GPT-6 Sol. And boom: no more content policy error. The model went straight to work scanning my footage and putting the video together. Wrapping Up Look, Microsoft’s default guardrails are a solid starting point, but they can be a bit trigger-happy when you’re doing perfectly legit stuff like video editing, creative work or internal tooling. Since you can’t touch the defaults, the trick is to roll your own: flip Block to Annotate where it makes sense, drag those content harm sliders down, pick the streaming mode that fits your app, and assign it to your deployments. That’s it! One friendly word of warning though: with great power comes great responsibility. Only loosen what you actually need, keep things like indirect prompt injection detection switched on for any agent that reads files or browses the web, and think twice before doing this on anything customer-facing. And if you want to go further than the portal lets you, like switching content filters off completely, you’ll need to apply to Microsoft for approval first. Happy building!114Views0likes0CommentsClosing the AI Agent Governance Gap with Microsoft Foundry
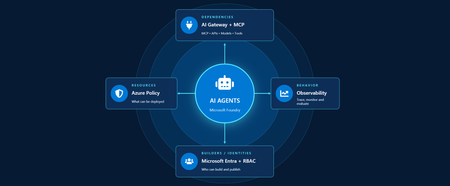
Developers are shipping agents faster than security teams can catalog them. As organizations move beyond pilots and begin operating dozens or hundreds of agents, one question keeps coming up: how do we actually get visibility into our AI agents across our environment? In this article, we'll walk through how Azure services can help establish visibility, guardrails, and cost accountability across your AI estate. Governance for AI happens across four layers: Resources – who can create new AI resources Builders – who can develop and publish agents in a certain scope Behavior – how agent outputs are evaluated, monitored, and governed Dependencies – what models, tools, APIs, and MCP servers agents can interact with Most organizations already have governance controls for identities, networking, and compliance. The challenge isn't creating new controls. It's connecting existing controls into an operating model that works for AI agents. Below we walk through each area and go a bit deeper on how to close the gap. Setting up boundaries with Azure Policy First, let's start in the Azure portal with Azure Policy. Azure Policy lets you set guardrails on what can be deployed in your environment and flags or blocks anything that doesn't comply. For AI workloads, the built-in definitions range from limiting models that people in your organization can deploy to locking down the network through enabling private endpoints. Some policies you get started with: Foundry model deployments should only use approved models: Restricts deployments to models or publishers your organization has explicitly approved Foundry model deployments should meet eligibility requirements (preview): Applies rules based on model attributes like preview vs. GA status and distribution source Azure AI Services resources should have key access disabled: Makes Microsoft Entra ID the only entry point The full list of policies related to Azure AI Services are available here: List of built-in policy definitions - Azure Policy | Microsoft Learn Why this comes first: Policy checks resources before they are created, so it proactively keeps your environment aligned with your standards. Implementing role-based access control (RBAC) Once these boundaries are in place, the next step is RBAC. Setting RBAC up early ensures that people and identities building agents have the right scope for what they actually need to do. Foundry roles only apply when you authenticate using Microsoft Entra ID. If you're using key-based authentication instead, the key grants full access with without role restrictions. API keys are convenient for quick development usage but when moving towards production, Microsoft Entra ID is the preferred method. Roles can be assigned at three scopes: the Foundry resource, a Foundry project, or an individual agent itself. Below is an example of how different personas within organization can map to a certain scope for creating and building agents with Foundry. Here's how each role in the diagram compares, from least to most privileged: Role Privilege Level What it does in Microsoft Foundry Foundry Agent Consumer Least Interact with agent endpoints in a project. This is your least-privilege role for people who only need to use agents. Foundry User Low Grants reader access to the Foundry project, the Foundry resource, and data actions for your Foundry project. Least-privilege access role for developers building and testing agents. Foundry Project Manager Medium This role lets you perform management actions on Foundry projects, build and develop with projects, and conditionally assign the Foundry User role to other user principals. Foundry Account Owner Higher Grants full access to manage Foundry projects and resources, and lets you assign the Foundry User role to other user principals. Foundry Owner Highest Grants full access to manage Foundry projects and resources to build and develop with projects. This role can also assign the Foundry User, ACR, and monitoring roles to users in the environment. Source: Role-based access control for Microsoft Foundry - Microsoft Foundry | Microsoft Learn For the agent resources themselves, assign managed identities rather than API keys since it lowers the risk of having compromised credentials. Note if you're scripting RBAC permissions: these roles were recently renamed from Azure AI User, Azure AI Owner, Azure AI Account Owner, and Azure AI Project Manager. The role IDs and permissions didn't change, so use the role definition GUID in your code to avoid issues while the rename rolls out. Observability in Microsoft Foundry Governance requires more than access control. Organizations also need evidence of how agents are being used. Observability provides the audit trail needed to investigate incidents, understand usage patterns, and track costs. The Foundry Control Plane brings these observability and governance tools together in one place, alongside services like Azure Monitor, Microsoft Entra, Microsoft Purview, and Azure Policy. In the Foundry portal, tracing is a good starting point. Once you connect an Application Insights resource to your project, Foundry turns on tracing automatically so every run, including the ones you test in the playground, is logged. After it is completed, you can search by Response ID or Trace ID to see the conversation history, token usage, run steps, tool calls, and inputs and outputs between the user and the agent. For more granular queries, you can write KQL to dive into individual agent runs or use the prebuilt Grafana dashboards in Azure Monitor. With client-side tracing, you can also export traces to observability tools you may already use, such as Datadog or Jaeger. Note: Permissions required for viewing this telemetry requires the Log Analytics Reader role on the connected Application Insights resource, and Privileged Monitoring Data Reader on top of that if the underlying Log Analytics tables are protected. Alongside all of these monitoring features, every agent comes with content safety guardrails and evaluations let you test and optimize performance before and after you publish your agents. When agents get published to Microsoft Teams and Microsoft 365 Copilot, Microsoft 365 admins can approve usage requests. These requests can be further scoped to a limited group for pilot testing/department usage or the full organization. Adding an AI gateway Observability tells you what your agents are doing, but how do you actually control them? This is where Azure API Management comes in. Once you have more than one agent, model deployment, or multiple teams consuming them, you need a single enforcement point between the agents and the resources they call. Adding Azure API Management in front of Microsoft Foundry gives you: Rate limiting and load balancing across regions and model deployments Consistent authentication and quota policies for model and tool traffic Usage tracking per team or cost center so you can accurately charge back to different departments Governed access to your custom and remote MCP servers Note: When choosing MCP servers, start with trusted, enterprise supported sources (GitHub, Microsoft, internally developed servers, etc.) that have documented security controls, enterprise authentication, clear ownership, and least-privilege permissions. Treat community MCP servers as untrusted until they have undergone a formal security review and are verified by organizations. Adding an AI gateway completes the governance picture. Azure Policy governs what can be deployed. RBAC governs who can build and manage agents. Observability provides evidence of how agents behave in production. The AI gateway extends governance into runtime, controlling how agents interact with models, tools, and external systems. Combined, these layers help organizations move beyond simply building agents to operating them responsibly at scale. Extend governance across the wider estate A few directions to take this further: MCP registry in Azure API Center – As MCP usage grows, you can create an approved inventory of MCP servers and APIs that can be used across an organization. Microsoft Agent 365 – Microsoft's enterprise control plane for AI agents. It gives every agent its own Microsoft Entra Agent ID and published Foundry agents sync to its registry automatically. This gives your IT team one place to run access reviews, lifecycle policies, and owner attestation across every agent in the tenant, including shadow agents discovered outside Foundry. Copilot Studio – when you add an MCP tool, you can point it at the API Management URL instead of the direct remote endpoint to gain additional observability through the gateway. GitHub Copilot – you can apply the same AI gateway-fronted MCP registry, applied to the developer side. Microsoft Purview – data classification, DLP, audit, and AI interaction governance across the wider estate. Where to go next Looking for a quick start? Turn on the three Azure Policy definitions above in audit mode against a non-production subscription and see what gets flagged that is out of compliance. Ready to design the end-to-end pattern? Take a look at this Cloud Adoption Framework guidance on AI governance and governing Azure platform services for AI. Want to go deeper on agent observability? Start with these articles around Application Insights integrations with Foundry: Use Insights in Microsoft Foundry and Monitor AI Agents with Application Insights Governing AI agents doesn't require starting from scratch. The identity, policy, monitoring, and cost controls you already use for the rest of your Azure estate can extend to AI workloads. Start with one layer, connect the next, and build a governance foundation that grows with your AI adoption.584Views3likes0CommentsResource Guide: Making Physical AI Practical for Real‑World Industrial Operations
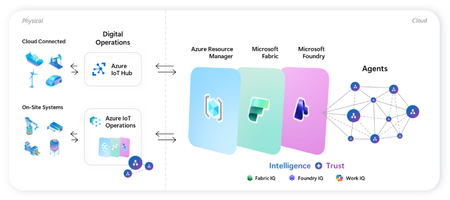
Microsoft's adaptive cloud approach brings cloud, edge, data, and AI together to help organizations turn operational technology (OT) data into intelligent action, without requiring everything to live in the cloud. At the center of this approach are key technologies that connect physical operations to cloud-scale data, analytics, and AI: Key Purpose Offering Direct-to-cloud device management + telemetry ingestion Azure IoT Hub Industrial connectivity + edge data plane Azure IoT Operations Unified analytics + real-time intelligence Microsoft Fabric On-device AI inferencing runtime Microsoft Foundry Industry recognition Microsoft named a Leader in the 2026 Gartner® Magic Quadrant™ for Global Industrial AIoT Platforms Read the announcement See it all come together Before diving into each component, watch this end-to-end demo showing how Azure IoT Operations, Azure IoT Hub, Microsoft Fabric, and Foundry Local work as one stack across the edge-to-cloud lifecycle - Making industrial AI practical for real-world operations with adaptive cloud. How these components work together Azure IoT Operations and Azure IoT Hub collect real-time data from operational assets and send semantically-ready, modeled data to Microsoft Fabric, where it's contextualized with enterprise data for downstream analytics. Microsoft Foundry extends to the edge through Foundry Local, so the same tooling used to deploy and manage AI models in the cloud applies to edge use cases. All of it integrates into Azure Resource Manager, bringing OT devices, assets, and edge AI models into the same management and security paradigm as every other Azure-managed resource. This blog walks through where to get started with each product capability: 1. Manage Cloud-Connected Devices and Telemetry with Azure IoT Hub Azure IoT Hub is a fully managed cloud service that enables secure bidirectional communication, device-to-cloud telemetry ingestion, cloud-to-device command execution, per-device authentication, remote management and more. Telemetry from IoT Hub can also be routed downstream into analytics platforms like Microsoft Fabric for visualization or AI modeling. Recommended Usage: Devices that utilize IoT Hub are distributed, stand-alone devices with fixed-functions. These devices typically do not require cloud-managed containerized workloads or cloud-managed proximal industrial protocol connectivity. Examples of appropriate device-to-cloud IoT Hub endpoint devices include water monitoring stations, vehicle telematics, distributed fluid level sensors, etc. Resources Current in-market services overview: IoT Hub: What is Azure IoT Hub? - Azure IoT Hub DPS: Overview of Azure IoT Hub Device Provisioning Service - Azure IoT Hub Device Provisioning Service ADU: Introduction to Device Update for Azure IoT Hub Building scalable solutions with Azure IoT platform: Best practices for large-scale IoT deployments - Azure IoT Hub Device Provisioning Service Scale Out an Azure IoT Hub-based Solution to Support Millions of Devices - Azure Architecture Center Azure IoT Hub scaling Try out our preview of new IoT Hub capabilities (integration with Azure Device Registry and Certificate Management) Learn more about these capabilities on our blog post: Azure IoT Hub + Azure Device Registry (Preview Refresh): Device Trust and Management at Fleet Scale… Integration with Azure Device Registry (preview): Integration with Azure Device Registry (preview) - Azure IoT Hub Microsoft-backed X.509 certificate management (preview): What is Microsoft-backed X.509 Certificate Management (Preview)? - Azure IoT Hub How to start with the preview: Deploy IoT Hub with ADR integration and certificate management (Preview) - Azure IoT Hub 2. Connect Industrial Assets with Azure IoT Operations Azure IoT Operations provides a unified data plane for the edge that runs on Azure Arc–enabled Kubernetes clusters and supports open industrial standards. It allows organizations to connect and capture equipment telemetry, normalize OT data locally, route hot-path signals to real-time analytics, securely manage layered industrial networks, and more. Edge‑processed data can then be sent upstream to Microsoft Fabric for AI‑driven analysis. Recommended Usage: Azure IoT Operations is intended to be the data plane for an adaptive cloud deployment extending the management, data, and AI capabilities of the Microsoft cloud to an on-prem device. This device binds to these cloud planes providing a platform for local data processing and intermittent connectivity. The target for these devices range from a small-gateway-style PC to a full data center. Azure IoT Operations endpoints enable cloud-managed containerized workloads and cloud-managed proximal industrial protocol connectivity. Examples of appropriate adaptive cloud and Azure IoT Operations endpoints include, on-robot computers, industrial machine controllers, retail store sensor/vision processing, and top-of-factory site infrastructure for line of business applications. Resources Azure IoT Operations Overview Azure IoT Operations Documentation Hub Releases · Azure/azure-iot-operations Quickstart: explore-iot-operations/quickstart at main · Azure-Samples/explore-iot-operations Latest release update: Open-source framework for scaling robotics from simulation to production on Azure + NVIDIA: microsoft/physical-ai-toolchain Demo video showcasing this in action: Making industrial AI practical for real-world operations with adaptive cloud How we built the demo: explore-iot-operations/quickstart at main · Azure-Samples/explore-iot-operations Edge-AI: microsoft/edge-ai: Production-ready Infrastructure as Code, applications, pluggable components, and… Latest Announcements & Blogs Making Physical AI Practical for Real-World Industrial Operations: Part 1 | Microsoft Community Hub Making Physical AI Practical for Real-World Industrial Operations: Part 2 | Microsoft Community Hub Introducing small form factor infrastructure: embed intelligence into physical systems Unlock Industrial Intelligence | Microsoft Hannover Messe 2026 From pilots to production: How Microsoft and partners are accelerating intelligent operations Partner Solutions How Mesh Systems Builds on Azure IoT Hub and Azure IoT Operations to Accelerate Industrial AI | Microsoft Community Hub Unlocking the Human Telemetry Layer for Safer Industrial Operations | Microsoft Community Hub Unlocking Smart Manufacturing: Siemens Industrial Edge Meets Azure IoT Operations Solving the Data Challenge for Manufacturers with Sight Machine & Azure IoT Operations | Microsoft Community Hub Microsoft and Rockwell Automation: Transforming Industrial AI Together | Microsoft Community Hub 3. Advanced Analytics with Microsoft Fabric Microsoft Fabric delivers a unified, end‑to‑end analytics platform that transforms streaming OT telemetry into real‑time insights and live dashboards. Fabric Operations Agents monitor industrial signals to recommend targeted actions, while Fabric IQ provides a shared semantic foundation that enables AI agents to reason over enterprise data with business context. Together, Fabric turns live industrial data into AI‑powered operational intelligence. Resources Get Started with Microsoft Fabric Learning Path Fabric Real-Time Intelligence documentation - Microsoft Fabric | Microsoft Learn Create and Configure Operations Agents - Microsoft Fabric | Microsoft Learn Fabric IQ documentation - Microsoft Fabric | Microsoft Learn 4.Run AI Models On‑Device with Foundry Local Foundry Local extends on‑device AI to Arc‑enabled Kubernetes edge clusters, providing a Microsoft‑validated inferencing layer for running AI models in industrial, disconnected or sovereign environments. Resources Foundry Local on Azure Local Documentation Participate in Foundry Local on Azure Local preview form Foundry Local on Azure Local: HELM deployment Demo Customer Stories Chevron: Chevron plans facilities of the future with Azure IoT Operations Husqvarna: Husqvarna Group Boosts Operational Efficiency with Azure Adaptive Cloud Ecopetrol: Azure IoT Operations and Azure IoT for energy help Ecopetrol optimize energy distribution while lowering operational costs P&G: Procter & Gamble cuts model deployment time up to 90% with Azure IoT Operations Toyota: Toyota Industries innovates its paint shop processes with Azure industrial AI and Azure IoT Hub1.4KViews3likes0Comments
Your Agents Need More Than a Place to Run
In architecture reviews with enterprise teams moving their first agentic applications toward production, I often hear the same plan: the team has containerized their agent and intends to run it on the managed Kubernetes cluster the organization already trusts. The reasoning is sensible, since the platform team knows the tooling and security has approved the network model, and for the first use case or two it is often the right call. Having watched this unfold in my years leading AgenticAI customer engineers and forward deployed engineers, and now helping customers reach production on Azure, I want to describe what happens next, before leaders commit rather than after. One thing to note is Azure supports multiple ways to build and operate agents. Foundry Agent Service provides an integrated managed runtime around your agent code. Azure Kubernetes Service supports teams that need Kubernetes-level control or want to extend an established platform, while Azure Container Apps provides managed container hosting. These services can work together. The decision is which capabilities and responsibilities best fit the workload. Where the cluster is the right answer A stateless retrieval application, a document extraction pipeline, or a classification job is a web service that happens to call a model, and a container platform runs web services well. A large retail customer of mine ran an invoice extraction agent on containers for over a year with almost no issues, and I never suggested they move it. The cluster remains the right home for several other situations as well. LLM invocations embedded inside existing microservices, event driven, or batch pipelines fit container platforms naturally. Genuine constraints such as air-gapped or sovereign environment, regions where a managed service is not yet offered are a good reason to run your own stack, and strong engineering team that already operates at that level can be a real asset. Even when the agents themselves move to a managed runtime, the tool servers, business APIs, and data services those agents call, often stay on your cluster, so they are complementary far more often than they are competitors. The problem is that these early wins can make agents seem like just another workload. Where the wheels come off The first failure is the state. A research agent that plans, searches, and synthesizes for ninety minutes is a long-running stateful process, while a Kubernetes pod is a disposable container the scheduler may restart at any time. A financial services team I worked with lost costly research run to a routine node upgrade, and responded as capable engineers do by building checkpointing, a durable store, and a resume mechanism. It worked, but they now owned a piece of infrastructure they had to keep correct as their agent's framework changed beneath it. A managed agent runtime absorbs this. Hosted agents in Foundry Agent Service, as one example, give every session a VM-isolated sandbox with a persistent file system, a durable state store that survives crashes and restarts and can hold checkpoints for frameworks such as LangGraph or Microsoft Agent Framework, and a resilient execution mode that recovers long-running work after a process interruption. The second is the human-in-the-loop. A commercial insurance customer’s claims agent needed sign-off from an adjuster and sometimes a second reviewer, with days between steps. Stopping an agent cleanly at the moment it needs a decision, holding its full session for four days without paying to keep it running, and resuming it correctly when the approval arrives is not something a container orchestrator gives out the box. The team built agent session suspend and resume, a queue, a durable state store, notifications, and an approval interface, and ended up with a small workflow engine nobody had planned to own. In hosted agents, an idle session is deprovisioned with its state persisted and restored onto fresh compute when the same session ID returns, so an agent waiting on an approval cost nothing while it waits, and sessions are retained for up to thirty days of inactivity. The approval experience remains yours to design, which is where your engineers' time should go. The third is multi-turn conversation, which quietly pushes teams into building their own context management system. The first version appends each turn to history, and within few turns the history outgrows the context window while cost and latency climb. So, the team adds truncation, then summarization, then retrieval of earlier turns, then per-user and per-tenant scoping, then expiry and deletion rules for privacy. An industrial customer's safety compliance assistant, with conversations stretching across days, followed exactly this path and ended up with a bespoke thread store and summarization pipeline nobody had budgeted for. Its first serious incident came when a summary silently dropped a compliance-relevant instruction. With the Responses protocol in hosted agents in Foundry, conversation history is a durable, platform-managed record keyed by a conversation ID and reachable from any channel, so the thread store is no longer yours to build, although deciding what to summarize or retrieve remains a design choice for your agent. The fourth is identity. On a cluster, the path of least resistance is a shared service account, and in one review a security architect asked which actions had been taken on behalf of which user, only to learn that the logs could not say. Hosted agents create a dedicated Microsoft Entra agent identity for each agent at deploy time, use on-behalf-of flows to act with the user's delegated permissions in interactive scenarios and the agent's own identity in autonomous ones, and keep the agent identifiable for audit in both cases. The fifth is per-user session isolation, which is the difference between an agent that serves many people and an agent that mixes them up. Agents read files, run code, and hold working data, and on a shared pod the default is that many users share a process, a file system, and often a cache. Giving every user session its own sandboxed environment and storage, so that one person's documents and intermediate results can never surface in another's, means engineering hard isolation boundaries and proving them to your security team. Hosted agents make a VM-isolated sandbox per session the default, and their durable state store can partition items per end user, so one store is safe to share across the users of a multitenant agent. And lastly, Evaluation and optimization are where the gap widens. The largest difference between teams that scale and those that stall is evaluation. Because agents are probabilistic and multi-step, staging tests often miss failures such as a wrong tool choice or a policy violation deep in a task. One customer’s agent passed every offline check but degraded unnoticed for weeks after a model update because evaluation stopped at release. Mature teams continuously evaluate production traces, combine automated judges with sampled human review, and red-team regularly.Once quality is measurable, teams can deliberately balance prompts, models, tools, latency, and cost. One team cut per-task cost by routing simple steps to smaller models after evaluation confirmed quality held. Self-built stacks require teams to assemble and maintain tracing, datasets, judges, and release gates. Hosted agents instead combines default OpenTelemetry traces with continuous evaluation, adversarial testing, and datasets generated from agent instructions. Staged closed-loop optimization uses those traces to improve instructions, tool descriptions, and model selection without extra plumbing. The real cost is the velocity gap Leaders usually expect me to quantify the initial build, and that is the smaller number. A team of four building the first agent often becomes ten or twelve within a year, and a growing share of them are maintaining a runtime for agents rather than building agents that serve the business. The enterprise has quietly created an internal agent infrastructure company in a field where the patterns for memory, tools, evaluation, and safety are rewritten every few months, while hyperscalers put hundreds of engineers on exactly this problem and ship at a cadence no single platform group can match. Foundry Agent Service, for instance, bundle content safety guardrails into the runtime and route outbound traffic through a customer virtual network, capabilities that platform teams otherwise assemble one integration at a time. This plumbing does not differentiate your organization, so the question is whether your scarcest engineers should spend years on it or on the workflows, data, and judgment only your company has. This is also why the technology companies held up as examples are a poor template. Many built their own runtimes because managed options did not yet exist and had large platform organizations to carry the load. Even they tend to invest in a custom runtime for the first handful of use cases and then migrate as managed services mature, because the maintenance burden compounds while the strategic value of owning the plumbing does not. What I would do as the leader I am not arguing against Kubernetes or for moving everything tomorrow. Comparable managed runtimes exist across the hyperscalers, and I use hosted agents as the running example only because it is the one I know best from the inside. Managed agent services are still maturing, some workloads have real data residency or customization needs, and abstraction always constrains something. What I am arguing for is a deliberate choice for each use case, guided by three questions: whether the agent must outlive a single request by running long, waiting on humans, or remembering across sessions whether it must act with its own identity, auditable delegation, and policy enforcement whether your team would be building anything a managed service already provides, and who will still maintain it in two years. Key takeaways Match the runtime to the workload. Containers on your existing cluster suit stateless, short-lived agents, while long-running, human-in-the-loop, and memory-dependent agents need capabilities your platform team was never hired to build. Count the hidden team. The real cost of self-hosting is the growing group of engineers maintaining state, identity, memory, guardrails, and tracing instead of solving business problems. Make evaluation continuous and connected to production traces. Pre-release testing alone will miss the drift and trajectory failures that hurt you, and optimization of quality, cost, and latency depends on that evaluation data. Follow the pattern of the leaders, not their early architecture. Companies that built custom runtimes did so before managed options matured, and most of them move toward managed services as those options improve. A practical place to begin is your roadmap for the next twelve months. Sort each use case into stateless and short-lived or long-running and human-dependent, and for every agent in the second group put a price on the engineers who would maintain the runtime rather than the business logic. I would like to hear how you have drawn this line, and where a managed service was not yet ready for something you needed.738Views2likes0CommentsIntroducing GPT-6.1 Sol in Microsoft Foundry: Advanced intelligence, optimized for production agents
Today, OpenAI's GPT-6.1 Sol is generally available in Microsoft Foundry. GPT-6.1 Sol is an upgrade to GPT-6 Sol, delivering substantial improvements in agentic coding, computer use, and professional work, with performance approaching GPT-6 Astra across these evaluations. It offers a new balance of capability and cost for important work at higher frequency, making it more affordable for developers to build and run very capable agents at scale. Just one week after GPT-6 Sol and Luna joined our generally available lineup, this release continues the momentum of the GPT-6 series in Foundry: models that produce less noise and are more capable of completing full tasks with agents. GPT-6.1 Sol carries that progress forward for teams whose production workloads run all day, every day. What's new in GPT-6.1 Sol GPT-6.1 Sol advances the three capabilities that matter most for production agents: Agentic coding. GPT-6.1 Sol plans, edits, tests, and iterates across a codebase with improved performance on complex tasks and extended workflows involving multiple tool calls. More capable computer use. Improved reliability navigating real interfaces help agents operate the workflows that span multiple application steps, with permissions and human oversight suited to the task. Deeper Professional work. Stronger performance on the analysis, drafting, and multi-step knowledge tasks that make up daily enterprise work, with improvements in factual accuracy those workflows demand. GPT-6.1 Sol accepts text and image inputs and produces text, with a total context window of up to 1M tokens. This provides room to bring large codebases and document sets, within the model’s context limits. Flexible reasoning lets teams tailor the model’s depth of analysis to the needs of each task. This can help teams use tokens more efficiently by reserving deeper reasoning for the work that needs it. As in last Tuesday's announcement, the starting point is quality alongside cost per task, not model capability in isolation. Use that lens to evaluate GPT-6.1 Sol against the needs of your own production workloads. Where to put GPT-6.1 Sol to work Because these gains compound in agentic loops, valuable use cases include agent workloads that run frequently: Software engineering agents that triage issues, implement changes across a repository, respond to code review, and keep CI green, with costs that support running them on every pull request, not just the hard ones. Computer-use agents that complete back-office processes end to end: updating records across line-of-business systems, reconciling data between applications, and handling workflows in browsers. Professional work agents for research synthesis, contract and document review, financial analysis, and report generation, where work recurs weekly or daily and rewards consistent quality per task. High-frequency customer and employee workflows, where GPT-6.1 Sol's capability-cost balance lets teams upgrade the intelligence behind every interaction without upgrading the budget. The right intelligence behind every agent The right model for a job should be determined through evaluations. GPT-6.1 Sol joins GPT-6 Astra, GPT-6 Sol, and GPT-6 Luna in the Foundry model catalog: start with GPT-6 Astra for the most demanding reasoning, use GPT-6.1 Sol as the new default for production agents and complex workflows, and scale high-volume data and preparatory tasks with Luna. As with the rest of the GPT-6 series, look beyond price per token to cost per task, alongside quality and reliability. Foundry brings evaluation, tracing, and monitoring together so teams can make that call with evidence, then switch models without re-platforming. Deploy it your way With GPT-6.1 Sol in Microsoft Foundry, teams can choose how they scale and where processing takes place. Standard deployment offers flexible capacity billed by usage across Global regions and US, EU, and APAC Data Zones. Provisioned Throughput is available at launch through Global and US Data Zone deployments, providing reserved capacity for critical production workloads. Additional regions and deployment options will follow soon. That is the Foundry advantage: the flexibility to balance capacity, performance, and data residency requirements within one enterprise platform. Teams can match each workload to a supported combination of serving option and processing location, rather than apply the same deployment approach to every application. GPT-6.1 Sol Pricing* Model Deployment Context Length Pricing (USD $/million tokens) Input Cached Input Cached Writes Output GPT-6.1 Sol Global Standard Short context $2.00 $0.10 $2.50 $10.00 Long context $4.00 $0.20 $5.00 $15.00 Data Zone Standard (US) Short context $2.20 $0.11 $2.75 $11.00 Long context $4.40 $0.22 $5.50 $16.50 Data Zone Standard (EU) Short context $2.40 $0.12 $3.00 $12.00 Long context $4.80 $0.24 $6.00 $18.00 Data Zone Standard (APAC) Short context $2.40 $0.12 $3.00 $12.00 Long context $4.80 $0.24 $6.00 $18.00 *Prices shown are for Standard deployments. Provisioned Throughput pricing varies by deployment type. For each offer, the US Data Zone is priced at a 10% premium to Global, and the EU and APAC Data Zones are priced at a 20% premium to Global. For current rates and terms, see the Azure OpenAI pricing page., see the Azure OpenAI pricing page. Build safer agents on Foundry GPT-6.1 Sol runs with the same layered protections as the GPT-6 series in Foundry: alignment training in the model, content filters and guardrails on prompts and outputs, prompt injection mitigations on tool calls and responses, and enterprise identity and access controls governing what agents can reach. Microsoft Purview applies data policies and human checkpoints at every phase. Start building Your next agent needs more than a powerful model. Foundry pairs GPT-6.1 Sol with the deployment flexibility, observability, and enterprise controls to take it from first workload to production at scale. Explore GPT-6.1 Sol in the Microsoft Foundry model catalog and evaluate where it fits in your next agent.5.5KViews1like0Comments
From Prompt to Production: Building Azure Architecture Diagrams with AI
Author: Arturo Quiroga, Senior Partner Solutions Architect — Microsoft Cloud architects spend significant time translating ideas into architecture diagrams. They toggle between Visio, draw.io, pricing calculators, and documentation. According to the 2024 Stack Overflow Developer Survey, 61% of developers spend more than 30 minutes a day searching for answers or solutions, time lost to context-switching rather than design. What if you could describe your architecture in plain English and get a diagram, cost estimate, and deployment guide in minutes? The Challenge: Fragmented Architecture Workflows Designing Azure architectures today typically involves multiple disconnected steps: Sketch the architecture in a diagramming tool Look up official Azure icons and drag them into place Research pricing across regions using the Azure Pricing Calculator Validate the design against the Well-Architected Framework (WAF) Write deployment documentation and Infrastructure as Code templates Compare alternative designs manually Each step lives in a different tool, and keeping them in sync as designs evolve is costly. The Azure Architecture Diagram Builder brings these workflows together in a single browser-based experience. How It Works Describe your architecture in natural language, for example "A HIPAA-compliant healthcare platform with FHIR APIs, event-driven processing, and multi-region disaster recovery", and the AI generates a diagram with grouped services, data flow connections, and logical organization. Figure 1. Enter a natural-language prompt describing your architecture. Curated example prompts help you get started, and you can optionally upload an existing diagram for the AI to analyze. The tool uses Azure OpenAI to power generation across multiple models, enabling you to choose the model that best fits your scenario — from fast iterations to deeper reasoning. Key Features AI-Powered Architecture Generation Describe what you need in plain English, and the AI creates an architecture diagram with: 714 official Azure service icons across 29 categories Smart grouping: services are logically organized (Frontend, Backend, Data, Security) Data flow connections: labeled edges showing how data moves through the system 13 curated example prompts: from simple web apps to complex enterprise scenarios like Zero Trust networks, Industrial IoT with 5,000+ sensors, and global multiplayer gaming backends Figure 2. A generated industrial IoT architecture. Top: the clean diagram view as initially produced. Bottom: the same diagram with per-service monthly cost overlays toggled on, plus a running subscription total in the toolbar. Architecture Image Import Already have an architecture on a whiteboard or in a screenshot? Upload the image and let the AI analyze it, mapping services to official Azure icons and recreating the architecture as an editable, interactive diagram. Figure 3. Upload a photo of a whiteboard sketch (top-right reference panel) and the AI recreates it as an editable diagram with official Azure service icons and labeled data flow connections. ARM Template Import Import existing ARM templates to visualize your current infrastructure. The AI parses resource definitions and dependencies, groups related resources into logical layers, and produces a meaningful diagram of what you actually have deployed — a fast way to document an inherited environment or sanity-check a template before deployment. Figure 4. ARM template import in action. Top: the parser status banner while resources and dependencies are being analyzed. Bottom: the resulting diagram, with resources auto-grouped into logical layers (Web Tier, Data Layer, Container Platform, Observability & Logging) and a Generated from: ARM Template badge linking the diagram back to its source file. Well-Architected Framework Validation Validate your architecture against all five WAF pillars — Security, Reliability, Performance Efficiency, Cost Optimization, and Operational Excellence. The validator provides: An overall WAF score with pillar-level breakdowns Specific findings with severity levels Actionable recommendations you can select and apply Select the recommendations you agree with, and the AI regenerates an improved architecture incorporating those changes. Figure 5. WAF validation results showing the overall score, per-pillar breakdowns, and individual findings with severity badges. Tick the recommendations you want and the AI rebuilds the diagram with those changes applied. Multi-Model Comparison Run the same architecture prompt through multiple AI models side-by-side and compare: Architecture Comparison: service counts, connection counts, groups, token usage, and latency Validation Comparison: WAF scores across models, severity breakdowns, and finding counts Apply Winner: pick the best result and apply it to the canvas with one click Present Critique: a talking avatar narrates the AI-generated ranking with live closed captions Figure 6. Multi-model comparison. Top: select the models and reasoning effort, then enter the prompt. Bottom: side-by-side results across all selected models with service counts, latency, token usage, and Fastest / Cheapest / Most Thorough badges. Multi-Region Cost Estimation Get cost estimates from the Azure Retail Prices API across 8 Azure regions: East US 2, Australia East, Canada Central, Brazil South, Mexico Central, West Europe, Sweden Central, and Southeast Asia. Features include: Color-coded cost legend (green / yellow / red thresholds) SKU and tier information for each service Export options: CSV, JSON, plain-text summary, and an analysis report with top cost drivers, Reserved Instance flags, and a ranked multi-region comparison table Figure 7. The cost legend overlay shows per-service pricing with color-coded thresholds. The region selector in the toolbar lets you re-price the entire architecture in any of eight Azure regions. Deployment Guide Generation with Bicep Generate step-by-step deployment documentation including: Prerequisites and Azure resource requirements Step-by-step deployment instructions Bicep templates for each service (Infrastructure as Code) Post-deployment verification steps Security configuration recommendations Figure 8. Each generated Deployment Guide opens with the architecture name, an estimated deployment time, and a prerequisites checklist covering subscription roles, CLI versions, Microsoft Entra ID permissions, and region requirements, followed by numbered, copy-ready deployment steps. Figure 9. The Infrastructure as Code section produces a main.bicep orchestrator plus a per-service module (Log Analytics, Key Vault, Cosmos DB, SQL Database, Event Hubs, Azure Functions, and more). The Download All Templates button packages everything into a ready-to-deploy folder. Workflow Animation & Avatar Presenter Visualize how data flows through your architecture with step-by-step animations that highlight services on the canvas as each step plays. When the Azure Speech Service is configured, a photorealistic talking avatar can narrate the workflow or present model comparison results, with live word-by-word closed captions in a draggable, resizable panel. Figure 10. A workflow step is highlighted on the canvas as the Avatar Presenter narrates that step. Live word-by-word closed captions appear in a draggable, resizable panel, useful for accessibility and stakeholder demos. Export Options Figure 11. A single-slide PowerPoint export, available in dark or light theme, ready to drop straight into a stakeholder deck. Format Use Case PNG Documentation, presentations SVG Scalable vector graphics PPTX Single PowerPoint slide (dark or light theme) Draw.io Edit in diagrams.net JSON Backup, version control CSV / ZIP Cost analysis with multi-region comparison Highlights The Azure Architecture Diagram Builder unifies the architecture design lifecycle in a single tool: End-to-end workflow: from natural-language description to deployable Bicep templates without tool switching Official Azure icons: 714 icons across 29 categories, mapped directly from the Azure service catalog Live pricing: queries the Azure Retail Prices API at design time rather than relying on static estimates WAF-integrated validation: architectural best practices built into the design loop rather than applied after the fact Multi-model flexibility: choose the AI model that best suits each task, with fast models for iteration and reasoning models for complex designs Open source: the source code is available for customization and contribution One-Command Deploy with Azure Developer CLI The fastest way to get your own instance running is with azd : # Install azd (once) brew tap azure/azd && brew install azd # macOS winget install microsoft.azd # Windows # Clone, configure, and deploy git clone https://github.com/Arturo-Quiroga-MSFT/azure-architecture-diagram-builder cd azure-architecture-diagram-builder azd auth login azd env set AZURE_OPENAI_ENDPOINT "https://your-resource.openai.azure.com/" azd env set AZURE_OPENAI_API_KEY "your-key" azd up # Provisions infrastructure + builds + deploys (~8 min) azd up provisions the following via Bicep: Resource Purpose Azure Container Registry Stores the Docker image Azure Container Apps Runs the app (nginx + token server) Log Analytics + Application Insights Monitoring and telemetry Azure Speech (S0) Avatar Presenter (optional, keyless auth via managed identity) Try It Today The Azure Architecture Diagram Builder is available now: Live demo: https://aka.ms/diagram-builder Source code: GitHub repository Documentation: See the Getting Started Guide for detailed setup instructions We welcome feedback and contributions. Use the GitHub Issues page to report bugs, suggest features, or share your experience. Tags: artificial intelligence · application · apps & devops · well architected · infrastructure5.8KViews3likes4CommentsFrom Features to Flow: How Real-World Adoption Reshaped the Azure Architecture Diagram Builder
In May, I introduced the open-source Azure Architecture Diagram Builder as a way to move from a natural-language prompt to an Azure architecture diagram, cost estimate, Well-Architected assessment, and deployment guidance. In July, I shared how the project had become agent-ready through Model Context Protocol (MCP). Those posts described what the tool could do. The more interesting story came next: what happened when people actually used it. As adoption grew, the central product question changed. It was no longer simply, Can AI generate an Azure architecture? It became: How do we help an architect choose how to begin, improve a result without losing their work, validate it responsibly, and turn it into something another person can use? That question reshaped the Azure Architecture Diagram Builder from a collection of capabilities into a guided workflow: Create → Refine → Validate & Improve → Share or Build This post explains what we learned, what changed in the product, and why the hardest part of AI-assisted architecture is not the first diagram. It is everything that comes after it. TL;DR. Growing adoption created a feedback loop. Aggregate usage showed that people moved beyond generation into validation, recommendations, exports, and deployment guidance. Privacy-safe feedback revealed recurring problems with diagram integrity, preservation of human edits, cost credibility, export quality, and validation continuity. Those signals led to a four-stage architecture journey that keeps human judgment and professional review at the center. The same lesson now shapes agent access and the next product boundary: distinguish logical proposals from evidence-backed physical architecture. Adoption created a product feedback loop As of August 5, 2026, the first two Azure Architecture Blog articles had accumulated approximately 12,100 combined views. A refreshed view of deduplicated application telemetry through August 13 recorded: Activity Aggregate count Architecture generation and refinement events 5,023 Well-Architected validations 960 Recommendations applied 175 Diagram exports 2,020 Deployment guides generated 212 As of August 13, the public repository had reached 45 stars and 14 forks. In GitHub’s current rolling 14-day window, the repository recorded 277 unique visitors and 67 unique cloners. These numbers measure different things and should not be added together. Article views are not unique readers. Application activity uses anonymous telemetry identifiers, not verified people. GitHub traffic is a rolling aggregate window. The signals are useful because of the pattern they reveal, not because they can be combined into one headline user count. Activity also accelerated during the period following the second article. Compared with the May 19–July 9 baseline, daily activity from July 10 through August 13 was approximately 7.0 times higher for architecture generation and refinement, 5.6 times higher for Well-Architected validation, and 5.9 times higher for recommendation application. The timing coincided with publication; it does not prove that the article alone caused the growth. The important product lesson was simpler: people were not stopping after the first diagram. They were testing alternatives, validating designs, applying recommendations, exporting artifacts, and asking how to move toward implementation. Generation was the entry point, not the complete job. The first guided-journey signals reinforce the need for more than one starting path. Through August 13, the new journey instrumentation recorded 880 interactions from 174 anonymous identifiers across 241 sessions. At first start, structured brief/image generation and Guided Chat were selected at almost the same frequency (158 and 156 events), while template and live-Azure import added another 68 selections. These are interaction counts, not unique people or conversion rates, and the window is still too early to claim that the journey improves completion. They are enough to show that architecture work does not begin in one uniform way. In-product Start Here panel showing the four-stage Azure Architecture Diagram Builder journey: Create, Refine, Validate and Improve, and Share or Build. Figure 1. The in-product Start Here panel explains one complete architecture loop. The stages are recommendations, not gates, and direct access to every tool remains available. Stage 1: Create — make the starting choice explicit As capabilities accumulated, the first screen became harder to interpret. Architecture Chat and structured generation were both useful, but they competed for attention. Importing an existing architecture was available, yet easy to miss. The new starting experience makes three paths explicit: Starting path Best suited for Guided Chat Exploring requirements conversationally and refining them over multiple turns Generate Diagram Providing a structured brief or image and producing a first architecture quickly Import Existing Opening an existing architecture or infrastructure artifact for analysis and editing This is not a marketing landing page placed in front of the tool. It is a small decision point inside the authoring experience. Once a path is selected, the user lands on the real canvas. The distinction matters because different architecture tasks begin with different levels of certainty. Sometimes the architect knows the target services. Sometimes the problem needs discovery. Sometimes the architecture already exists and the work is to understand or improve it. The product should acknowledge those differences instead of pretending every design starts with a perfect prompt. Start chooser presenting Guided Chat, Generate Diagram, and Import Existing as three equal entry paths. Figure 2. Three starting paths reflect three different architecture situations: discovery, structured generation, and analysis of an existing design. Stage 2: Refine — preserve human work One of the clearest feedback themes was not about adding another AI capability. It was about preventing AI from casually undoing human effort. An architect might spend time arranging a one-page diagram for a review, resizing groups, moving labels, or emphasizing a specific boundary. A subsequent AI refinement could improve the service selection while disrupting that carefully prepared layout. The design principle that emerged was straightforward: AI acceleration should preserve deliberate human work by default. Refinement now retains existing node positions, group geometry, sizes, and viewport context whenever possible. The model can change the architecture without treating every turn as permission to redraw the entire document. The same principle applies beyond geometry: Preserve the prior validation result when recommendations change the architecture. Preserve the active light or dark theme in exported artifacts. Preserve the distinction between the authoring canvas and the presentation deliverable. Preserve user-configured pricing assumptions rather than replacing them with one fixed estimate. This is a broader lesson for AI-assisted tools. A generated result is not the only source of value. The edits, judgments, and communication choices a person adds afterward are part of the artifact too. Before-and-after AADB canvases showing an AI refinement that adds Azure Front Door and WAF while retaining the positions of eight existing services and the anchors of four existing groups. Figure 3. In this controlled synthetic refinement, all eight existing service positions and four group anchors remained unchanged. The containing Application group expanded to accommodate the new edge tier, so preservation does not imply that every group dimension stays fixed. Quality is structural, not only visual A diagram can look polished while still being architecturally confusing. Early feedback exposed cases where a generated service appeared disconnected because a model referenced a display name instead of the service identifier used by the canvas. The correction was not another prompt instruction alone. The application now resolves connection endpoints across identifiers, normalized service names, and service-type aliases. It repairs valid edges, drops invalid or self-referential edges, detects remaining orphan nodes, and records aggregate integrity signals. That creates a more useful definition of diagram quality: Are the services connected as intended? Were any generated edges repaired or dropped? Are there orphaned nodes? Did refinement preserve the existing layout? Did an architecture change receive a fresh validation? Visual polish still matters, especially when an artifact leaves the editor. But structural integrity gives the product something deterministic to test and monitor. Stage 3: Validate & Improve — treat validation as a lifecycle The Azure Well-Architected Framework is most useful when validation becomes iterative rather than ceremonial. The Diagram Builder can assess a proposed design across the five Well-Architected pillars, surface findings, and apply selected recommendations. But that workflow exposed an important state-management problem: when the architecture changed, the prior validation result disappeared along with the obvious route back to revalidation. The updated experience keeps the previous report, marks it Revalidate Needed, and makes clear that the score describes an earlier state of the architecture. A new validation replaces it only after the updated design has been assessed. This distinction prevents a stale score from looking current. It also clarifies what an architecture-level assessment can and cannot prove. A diagram may show that a WAF, cache, backup service, or secondary region exists. It usually cannot prove that purge protection, diagnostic routing, encryption settings, role assignments, health probes, or failover policies are configured correctly. That is why validation findings need to distinguish between: Pattern-level gaps — missing or misplaced architectural components Configuration-level gaps — required settings that must be verified in Infrastructure as Code or the deployed environment Generated scores and recommendations help architects review a design; they do not replace an Azure Well-Architected Review, security review, deployment validation, or professional judgment. Validation result retained after architecture recommendations are applied, with a Revalidate Needed status and action. Figure 4. Architecture changes make a previous validation historical, not useless. The result remains available while the interface clearly asks for a fresh validation. Stage 4: Share or Build — design for the artifact’s destination The editing canvas and the final deliverable serve different purposes. Canvas dots, handles, navigation controls, and selection states help during authoring. They can make an exported diagram feel unfinished. The Diagram Builder now separates those concerns with Plain, Dots, and Grid export backgrounds while preserving the active light or dark theme. The same AADB architecture shown first on the editing canvas with the export menu open and then as the resulting Plain PNG without authoring controls. Figure 5. Authoring and delivery are different contexts. The upper view shows the editable canvas and its real export controls; the lower view is the Plain PNG produced from that same canvas, without editing chrome. Cost language is deliberately qualified. Azure services often combine fixed, usage-based, and configuration-dependent charges. A baseline that includes six numerically priced services but excludes 20 usage-based items is not the total cost of the architecture. The output identifies those exclusions rather than treating missing values as zero. The final stage also includes deployment guides and Infrastructure as Code. Here, honesty about artifact coverage is essential. A generated Bicep file may be a useful starter while still omitting private endpoints, diagnostic settings, failover configuration, or service-specific resources. The artifact should state what it implements, what remains conceptual, and whether Azure Resource Manager validation passed. AI-generated diagrams, costs, validation results, deployment guides, and Infrastructure as Code should all be reviewed and validated before production use. The same journey now extends to agents The MCP server introduced in the previous article makes the Diagram Builder available to agent experiences such as Microsoft Scout. The four-stage journey provides a useful way to think about agent orchestration too: Import or create one canonical architecture. Refine it without silently changing the intended topology. Validate it, apply supported improvements, and revalidate. Render or generate artifacts with explicit coverage and limitations. The current MCP surface exposes 12 tools, three resources, and three reusable prompts. It can normalize an existing architecture, validate and harden it deterministically, estimate regional costs from a dated pricing snapshot, render presentation/technical/cost views, and generate Bicep, Terraform, and deployment guidance. The calling agent still owns orchestration and reasoning; the MCP server is intended to remain a deterministic architecture capability, not a second hidden agent. The native MCP renderer can project one canonical architecture into three communication profiles: Presentation emphasizes the primary request path, reduces supporting labels, and removes pricing. Technical preserves complete connection detail for engineering inspection. Cost retains the focused composition while adding service-level pricing assumptions, a fixed-priced baseline, and explicit exclusions. These are MCP-generated SVG views, not Blueprint diagrams or screenshots of the editable web canvas. The services, connections, and groups remain the same; only the information treatment changes. The AADB MCP renderer projecting the same canonical architecture into presentation, technical, and cost SVG profiles. Figure 6. Native AADB MCP output from one 8-service, 9-connection, 4-group architecture. Presentation prioritizes the story, Technical exposes connection detail, and Cost foregrounds pricing assumptions and exclusions. Recent work on the MCP renderer added purpose-built presentation, technical, and cost profiles. More importantly, testing agent-generated artifacts reinforced an accountability principle: a polished diagram and a compiled Bicep file do not prove deployability. An agent workflow should report whether topology changed, whether validation improved, which services are represented only conceptually, and whether the generated IaC passed Azure preflight. That is more useful than an unsupported claim that a design is production-ready. Trust also includes the tool boundary itself. The hosted MCP endpoints now require a bearer token for real session operations; missing or incorrect credentials are rejected. A shared token is appropriate for the current controlled integration, but it is not the end state for enterprise multi-user access. Entra ID/OAuth, per-client authorization, rotation, and revocation remain future hardening work. Microsoft Scout response after an authenticated Azure Architecture Diagram Builder MCP workflow, showing the tools used, initial and final validation scores, cost scope, Bicep classification, rendered architecture, artifact links, coverage gaps, and no-deployment warning. Figure 7. The guided lifecycle extends beyond the web application. In this synthetic Scout run with GPT-5.6 Sol, the agent used authenticated AADB MCP tools to validate, harden, cost, render, and generate starter artifacts while explicitly reporting coverage gaps and that nothing was deployed. Learning from adoption without identifying people Product learning does not require reconstructing individual identities. The findings behind this article use aggregate, deduplicated application telemetry, public article counters, public repository totals, and paraphrased feedback themes. They do not correlate Application Insights identifiers, feedback records, GitHub accounts, or email addresses. Written feedback remains submittable without contact information. When someone explicitly opts into follow-up, the email address is stored with the feedback record in Cosmos DB and is not sent to normal product telemetry. The current 180-day expiry field is a retention marker; automated deletion must be implemented and verified before describing that retention period as enforced. Those boundaries matter for both product design and public writing: Aggregate activity rather than profiling individuals. Paraphrase themes rather than publishing comments without permission. Keep optional contact consent separate from telemetry. Avoid presenting anonymous identifiers as confirmed people. Avoid claiming that publication timing proves acquisition causality. This is not a claim of legal compliance. It is a product discipline: collect less, preserve user agency, and make only the claims the evidence supports. What changed The guided journey is the visible result, but the deeper change is how the project now evaluates progress. Earlier question Better question Did the model generate a diagram? Did it generate a connected and understandable architecture? Did the user click Validate? Was the current architecture validated, and was it revalidated after changes? Did export start? Did a professional artifact finish generating successfully? Does the IaC compile? What does it actually implement, and does Azure preflight pass? How many features exist? Can an architect understand the next useful step? The model portfolio continued to evolve as well. The production selector now contains 15 configured entries, including MAI-Thinking-1 (Public Preview). But the more consequential changes in this article are deliberately model-independent: preserve human work, keep state and provenance explicit, qualify generated artifacts, and authenticate the tools agents can call. The goal is not to remove flexibility. Architects can still open any tool directly, rearrange the canvas, reject recommendations, change pricing assumptions, or export at any point. The goal is to make the workflow coherent without pretending architecture itself is linear. The next boundary: logical versus physical architecture Recent feedback points to a harder problem than adding another model or export format. Architects working with private Azure AI landing zones need to distinguish shared platform resources from project-owned resources, preserve VNet and subnet boundaries, and reason about CIDRs, NSGs, route tables, private endpoints, DNS, and managed identities. The current Topology mode can show services and relationships, but it should not imply exact physical fidelity when those facts are absent. A useful logical diagram answers what exists and how it interacts. A physical or low-level design must answer where it is deployed, how it is isolated, and which values came from evidence. That is the next technical direction I am exploring: an evidence-aware Physical Architecture view backed by deterministic reconstruction from Terraform plan/state, ARM, or a live Azure inventory. Exact fields would be labeled as observed or resolved; AI suggestions would remain explicitly proposed; unsupported or missing inputs would be reported instead of silently invented. This capability is not shipped today, and it will require its own schema, validation rules, layout, security review, and evaluation set. That distinction matters. The lesson from adoption is not to put every architecture concern into one crowded canvas. It is to make each artifact’s purpose and evidence boundary clear. Try it, challenge it, help shape what comes next The Azure Architecture Diagram Builder remains open source, and the live experience is available today: Live app: https://aka.ms/diagram-builder Source code: github.com/Arturo-Quiroga-MSFT/azure-architecture-diagram-builder Getting started: Documentation and deployment guidance The next phase is to measure whether the guided journey helps people complete the full loop, especially recommendation-to-revalidation and artifact-generation success. In parallel, I am beginning the narrower physical-architecture investigation described above. Both efforts will use aggregate signals, reviewed fixtures, and sufficiently large cohorts rather than individual journey reconstruction. Try the workflow with a real architecture problem. Tell me where the handoffs are unclear, where the diagram loses intent, or where an artifact claims more than it implements. Those are the gaps worth fixing next. Measurement note: Article views are rounded public counters observed August 5, 2026. Application figures use deduplicated retained telemetry through August 13 and anonymous identifiers. GitHub totals and rolling 14-day traffic were observed August 13. The comparison windows are May 19–July 9 and July 10–August 13. These signals have different populations and must not be added together. Timing comparisons show concurrent activity, not causal attribution.1.1KViews1like2CommentsMicrosoft Industrial AI Partner Guide: Choosing the Right Data Expertise for Every Stage
As organizations scale Industrial AI, the challenge shifts from technology selection to deciding who should lead which part of the journey -- and when. Which partners should establish secure connectivity? Who enables production grade, AI ready industrial data? When do systems integrators step in to scale globally? This Partner Guide helps customers navigate these decisions with clarity and confidence: Identify which partners align to their current digital transformation and Industrial AI scenarios leveraging Azure IoT and Azure IoT Operations Confidently combine partners over time as they evolve from connectivity to intelligence to autonomous operations This guide focuses on the Industrial AI data plane – the partners and capabilities that extract, contextualize, and operationalize industrial data so it can reliably power AI at scale. It does not attempt to catalog or prescribe end‑to‑end Industrial AI applications or cloud‑hosted AI solutions. Instead, it helps customers understand how industrial partners create the trusted, contextualized data foundation upon which AI solutions can be built. Common Customer Journey Steps 1. Modernize Connectivity & Edge Foundations The industrial transformation journey starts with securely accessing operational data without touching deterministic control loops. Customers connect automation systems to a scalable, standards-based data foundation that modernizes operations while preserving safety, uptime and control. Outcomes customers realize Standardized OT data access across plants and sites Faster onboarding of legacy and new assets Clear OT–IT boundaries that protect safety and uptime Partner strengths at this stage Industrial hardware and edge infrastructure providers Protocol translation and OT connectivity Automation and edge platforms aligned with Azure IoT Operations 2. Accelerate Insights with Industrial AI With a consistent edge-to-cloud data plane in place, customers move beyond dashboards to repeatable, production-grade Industrial AI use cases. Customers rely on expert partners to turn standardized operational data into AI‑ready signals that can be consumed by analytics and AI solutions at scale across assets, lines, and sites. Outcomes customers realize Improved Operational efficiency and performance Adaptive facilities and production quality intelligence Energy, safety, and defect detection at scale Partner strengths at this stage Industrial data services that contextualize and standardize OT signals for AI consumption Domain-specific acceleration for common Industrial AI scenarios Data pipelines integrated with Azure IoT Operations and Microsoft Fabric 3. Prepare for Autonomous Operations As organizations advance toward closed‑loop optimization, the focus shifts to safe, scalable autonomy. Customers depend on partners to align data, infrastructure, and operational interfaces, while ensuring ongoing monitoring, governance, and lifecycle management across the full operational estate. Outcomes customers realize Proven reference architectures deployed across plants AI‑ready data foundations that adapt as operations scale Coordinated interaction between OT systems, AI models, and cloud intelligence Partner strengths at this stage Industrial automation leadership and control system expertise Edge infrastructure optimized and ready for Industrial AI scale Systems integrators enabling end‑to‑end implementation and repeatability Data Intelligence Plane of Industrial AI - Partner Matrix This matrix highlights which partners have the deepest expertise in accessing, contextualizing, and operationalizing industrial data so it can reliably power AI at scale. The matrix is not a catalog of end‑to‑end Industrial AI applications; it shows how specialized partners contribute data, infrastructure, and integration capabilities on a shared Azure foundation as organizations progress from connectivity to insight to autonomous operations. How to use this matrix: Start with your scenario → identify primary partner types → layer complementary partners as you scale. Partner Type Adaptive Cloud Primary Solution Example Scenarios Geography Advantech Industrial Hardware, Industrial Connectivity LoRaWAN gateway integration + Azure IoT Operations Industrial edge platforms with built in connectivity, industrial compute, LoRaWAN, sensor networks Global Accenture GSI Industrial AI, Digital Transformation, Modernization OEE, predictive maintenance, real-time defect detection, optimize supply chains, intelligent automation and robotics, energy efficiency Global Avanade GSI Factory Agents and Analytics based on Manufacturing Data Solutions Yield / Quality optimization, OEE, Agentic Root Cause Analysis and process optimization; Unified ISA-95 Manufacturing Data estate on MS Fabric Global Belden Industrial Connectivity, Networking, Security Belden Horizon Data Operations (BHDO) + LioN-X with Azure IoT Operations OT-IT convergence, network orchestration and monitoring, ruggedized ethernet and switching, industrial WiFi, multi-vendor protocol connectivity, OT security, OPC UA Global Capgemini GSI The new AI imperative in manufacturing OEE, maintenance, defect detection, energy, robotics Global DXC GSI Intelligent Boost AI and IoT Analytics Platform 5G Industrial Connectivity, Defect detection, OEE, safety, energy monitoring Global Innominds SI Intelligent Connected Edge Platform Predictive maintenance, AI on edge, asset tracking North America, EMEA Litmus Automation Industrial Connectivity, Industrial Data Ops Litmus Edge + Azure IoT Operations Edge Data, Smart manufacturing, IIoT deployments at scale Global, North America Mesh Systems GSI & ISV Azure IoT & Azure IoT Operations implementation services and solutions (including Azure IoT Operations-aligned connector patterns) Device connectivity and management, data platforms, visualization, AI agents, and security North America, EMEA Nortal GSI Data-driven Industry Solutions IT/OT Connectivity, Unified Namespace, Digital Twins, Optimization, Edge, Industrial Data, Real‑Time Analytics & AI EMEA, North America & LATAM NVIDIA Technology Partner Accelerated AI Infrastructure; Open libraries, models, frameworks, and blueprints for AI development and deployment. Cross industry digitalization and AI development and deployment: Generative AI, Agentic AI, Physical AI, Robotics Global Oracle ISV Oracle Fusion Cloud SCM + Azure IoT Operations Real-time manufacturing Intelligence, AI powered insights, and automated production workflows Global Rockwell Automation Industrial Automation FactoryTalk Optix + Azure IoT Operations Factory modernization, visualization, edge orchestration, DataOps with connectivity context at scale, AI ops and services, physical equipment, MES Global Schneider Electric Industrial Automation Industrial Edge Physical equipment, Device modernization, energy, grid Global Siemens Industrial Automation & Software Industrial Edge + Azure IoT Operations reference architecture Industrial edge infrastructure at scale, OT/IT convergence, DataOps, Industrial AI suite, virtualized automation. Global Sight Machine ISV Integrated Industrial AI Stack Industrial AI, bottling, process optimization Global Softing Industrial Industrial Connectivity edgeConnector + Azure IoT Operations OT connectivity, multi-vendor PLC- and machine data integration, OPC UA information model deployment EMEA, Global TCS GSI Sensor to cloud intelligence Operations optimization, healthcare digital twin experiences, supply chain monitoring Global This Ecosystem Model enables Industrial AI solutions to scale through clear roles, respected boundaries and composable systems: Control systems continue to be driven by automation leaders Safety‑critical, deterministic control stays with industrial automation partners who manage real‑time operations and plant safety. Customers modernize analytics and AI while preserving uptime, reliability, and operational integrity. Data, AI, and analytics scale independently A consistent edge to cloud data plane supports cloud scale analytics and AI, accelerating insight delivery without entangling control systems or slowing operational change. This separation allows customers and software providers to build AI solutions on top of a stable, industrial‑grade data foundation without redefining control system responsibilities. Specialized partners align solutions across the estate Partners contribute focused expertise across connectivity, analytics, security, and operations, assembling solutions that reduce integration risk, shorten deployment cycles, and speed time to value across the operational estate. From vision to production Industrial AI at scale depends on turning operational data into trusted, contextualized intelligence safely, repeatably, and across the enterprise. This guide shows how industrial partners, aligned on a shared Azure foundation, create the data plane that enables AI solutions to succeed in production. When data is ready, intelligence scales. Call to action: Use this guide to identify the partners and capabilities that best align to your current Industrial AI needs and take the next step toward production‑ready outcomes on Azure.2.1KViews4likes0Comments