analytics
858 TopicsCan Fabric Copilot Run on a Separate Capacity?
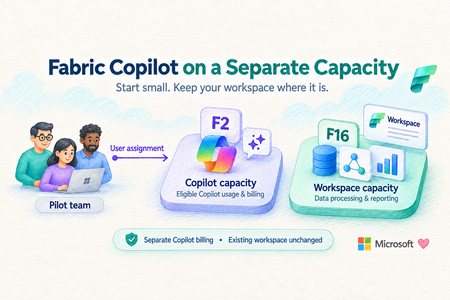
Microsoft Cloud Architects: Yassine El Ouardi and Rafia Aqil Customer question: Can we bill our team’s Fabric Copilot usage to a separate capacity while keeping data processing and reporting on our existing capacity? Answer: Yes. An organization can designate a Fabric capacity for Copilot usage and assign specific users or groups to it. Eligible Copilot usage from those users is then billed to the designated capacity rather than the capacity hosting their content. The workspace can remain on its existing capacity for its underlying workloads. The minimum Fabric SKU for a designated Copilot capacity is F2. That makes F2 a starting point for a small team, not a guarantee that it will be large enough for every usage pattern. Monitor consumption as adoption grows and scale the capacity if needed. LAB: In this lab, I created an F2 capacity for Copilot and kept the Adventure Works workspace on a separate F16 capacity. The setup illustrates the key architectural choice: assign users to the Copilot capacity, rather than moving their workspace to it. F2 capacity created: The Azure overview shows the new, active F2 Fabric capacity intended for the Copilot test. Both capacities visible: The admin portal lists the existing F16 capacity alongside the new F2 capacity. Copilot assignment setting under the capacity: The F2 capacity settings show where an administrator can designate the capacity for Copilot and select users or groups. Original workspace stays on F16: Workspace settings show that the Adventure Works workspace remains assigned to the F16 capacity. Semantic model opened: The Adventure Works model provides a practical workload for testing Copilot’s modeling assistance. Question submitted: The test asks Copilot to help fix the data model; the screenshot captures it processing the request. Recommendations returned: Copilot proposes specific model changes and says it has not applied them without confirmation. Capacity health checked: Fabric Capacity Metrics displays both capacities for comparison; this view shows 8 successful operations completed successfully for the Copilot Capacity. Takeaway: A separate Copilot capacity gives a small team a way to consolidate Copilot billing without relocating its workspace. Start with F2 where the feature’s requirements are met, then size from observed usage.103Views0likes0Comments
A streaming pipeline can be healthy even when the data isn't complete yet.
One thing worth separating in streaming systems is processing time from event time. A message can arrive late because of a disconnected device, a network delay or an upstream system that buffers events. If downstream aggregations assume every event arrives in chronological order, the resulting windows can be misleading. In event-stream processing, event-time windows and watermarks help define how long the system waits for late events before considering a window sufficiently complete. The exact behaviour depends on the processing engine and its configuration. A few questions come up when designing these pipelines: How late can events realistically arrive? What should happen to events that arrive after the allowed lateness? Does the business require corrected historical aggregates? How do you monitor event-time lag separately from processing latency? There is not one watermark setting that fits every workload. A short delay may reduce reporting latency but increase the number of late events that need separate handling. How do you choose the lateness threshold for Azure streaming workloads, especially when the business expects both low latency and accurate historical results?126Views0likes1CommentSimplify private connectivity for Azure Databricks Serverless with Private Network Gateway
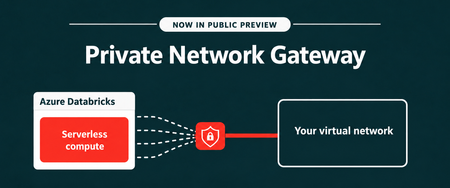
Recently, we announced the public preview of Private Network Gateway (PNG) for Azure Databricks - a simpler way to connect Azure Databricks serverless workloads to resources accessible from your Azure Virtual Network. With a single managed connection into your network, PNG helps reduce connectivity complexity while letting you control which resources serverless workloads can access. In this post, we explain what PNG means for private connectivity and how to get started. PNG brings the serverless experience together with the Azure networking environment and controls organizations already use, helping make serverless practical for a broader set of enterprise workloads. One connection to your network Azure Databricks serverless compute runs in an Azure Databricks managed network. This removes infrastructure management overhead, but private resources still need an explicit network path from serverless compute. Today, connecting serverless compute to resources you manage such as databases, Kafka clusters, and internal APIs could require separate private endpoints, load balancers, and proxy VMs for individual resources. That complexity grows as workloads need to reach more services across virtual networks, peered networks, and on-premises environments. Private Network Gateway introduces a simpler model: one gateway to your network instead of separately creating connectivity infrastructure for each resource. With Private Network Gateway on Azure Databricks, you can: Simplify private data ingestion. Use Lakeflow Connect on serverless compute to ingest from supported databases across your virtual network and connected on-premises environments. Connect AI agents to private services. An agent built on Azure Databricks can call a private MCP server you host. Use private package repositories. Install Python libraries from a private PyPI, Artifactory, or Nexus repository inside your network. Route egress through your existing firewall. Send traffic through your firewall or content inspection service so egress can be filtered and logged using your own tools. Use your own source IP. SaaS applications such as Salesforce can see a source IP belonging to your organization. Getting started is straightforward Private Network Gateway is designed to simplify the setup needed to bring serverless compute into your network. You delegate one subnet in your Azure Virtual Network to Azure Databricks. Private Network Gateway then establishes a managed, encrypted gateway from serverless compute into that subnet. The gateway is configured within a Network Connectivity Configuration (NCC), the account-level object used for Azure Databricks serverless networking. You can attach the NCC to your workspaces, and supported serverless workloads can then reach the private destinations you allow. And because the gateway is managed for you, there are no gateway VMs for you to deploy, patch, or scale in your network. Keep control of your Azure network Simplifying connectivity doesn’t mean giving up control of your network boundary. Private Network Gateway provides a dedicated path into your network rather than a shared appliance carrying other customers’ traffic. The gateway applies workspace-level access controls before traffic leaves, and isolation is enforced through encapsulation and network security rules. Once traffic reaches your subnet, your existing Azure networking controls continue to determine what serverless workloads can reach. This includes your route tables, network security groups, DNS resolvers, and security appliances. You also control how much traffic travels through the gateway: Specific destinations: Send only the fully qualified domain names you specify through Private Network Gateway. Other traffic retains its normal path. All traffic: Route outbound traffic through your network, except traffic matching a more specific Private Link or service-endpoint path. This can be used when you want broader egress inspection through your firewall or want traffic to leave through your own IP addresses. Private Network Gateway is also additive to your existing connectivity architecture. It sits alongside the private connectivity and egress controls you already use and can be enabled or removed without changing the existing setup. Bringing serverless to more of your Azure Databricks workloads Azure Databricks combines Databricks capabilities with native integration across the Azure ecosystem. Private Network Gateway extends that Azure Databricks experience to private networking for serverless workloads. Instead of building connectivity infrastructure for every resource, you can establish one managed gateway from serverless compute to your network and keep using your existing Azure network controls to decide where traffic goes. The result is a simpler approach to connecting serverless workloads to private enterprise resources while keeping the network boundary in your control. Get started today Private network gateway - Azure Databricks | Microsoft Learn Introducing Private Network Gateway | Databricks Blog597Views1like0Comments
Optimize selective analytics reads in Azure Data Lake Storage with ABFS Vectored Read
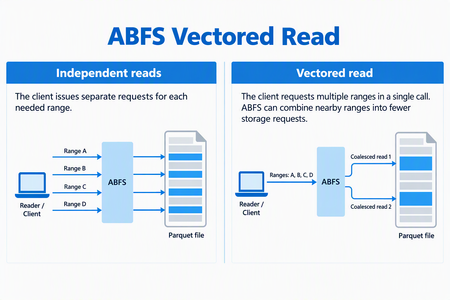
ABFS Vectored Read helps compatible analytics engines reduce request overhead when reading selected portions of columnar files in Azure Data Lake Storage. By coordinating multiple noncontiguous byte ranges through the Azure Blob File System (ABFS) driver, it can combine nearby ranges into fewer storage requests and execute those requests asynchronously. For data engineers working with selective Parquet queries, this brings the storage read pattern closer to what the query needs: a coordinated set of ranges rather than a collection of independent small reads. When the Parquet reader supports vectored I/O and the runtime includes a compatible ABFS client, Spark workloads that use higher-level APIs can enable this capability through configuration - without rewriting queries, changing application logic, or migrating data. Why selective reads need coordinated I/O Consider a query that selects a few columns from a Parquet dataset and filters out most row groups. The reader can skip much of the data the query doesn't need, but the data it needs may be spread across different parts of the file. Reading each range independently can create many small storage requests. Each request carries network and processing overhead, so selecting less data doesn't necessarily remove the cost of coordinating those reads. Vectored Read lets a compatible reader provide the ranges together, giving the client an opportunity to plan the I/O as a group. How ABFS Vectored Read works A compatible reader submits the file ranges it needs together. ABFS validates and sorts the ranges, combines nearby ranges when appropriate, and divides the resulting work to fit its read buffers. It then queues the storage requests asynchronously and returns the requested bytes to the corresponding range buffers. Illustrative request pattern, not a benchmark. Actual grouping depends on range layout and client configuration; coalesced storage requests can include bytes between the requested ranges. This is a client-side optimization. It does not change the file format or rewrite your stored data. The engine still receives the data for the ranges it requested. What this means for your workloads For compatible selective-read workloads, Vectored Read offers: Less request overhead: Combining nearby ranges can reduce separate storage requests and network round trips. Coordinated I/O: Asynchronous reads allow the client to work on multiple requested ranges without treating every range as an isolated operation. Configuration-based adoption: Compatible Spark workloads using the Hadoop Parquet and ABFS path can use the feature without rewriting their queries. The best starting point is a workload that reads selected portions of Parquet files through abfs:// or abfss://. Full sequential scans may see less benefit, and engines that bypass the Hadoop/ABFS path do not use this capability. Support depends on the Hadoop, hadoop-azure, and parquet-hadoop libraries included in the runtime, not only on the Spark version. See Availability and resources for the minimum versions and verification guidance. The benefit depends on the number, size, and spacing of requested ranges, the coalescing configuration, storage and network latency, concurrency and caching. Combining ranges can reduce requests and round trips, but it can also read additional bytes between noncontiguous requested ranges. Compare query duration, storage transactions, bytes read, and resource utilization against a controlled baseline using representative data and concurrency. Get started First, verify that your runtime contains Apache Hadoop 3.3.5 or later, including the hadoop-azure module, and parquet-hadoop 1.12.3 or later. The presence of an ABFS URI alone does not establish that the optimized implementation is installed. For Spark, enable the Parquet setting before the application starts, using the spark.hadoop. prefix: spark-submit \ --conf spark.hadoop.parquet.hadoop.vectored.io.enabled=true \ <other-options> \ <application> Replace the command placeholders with your normal submission options and application. Set the property explicitly rather than relying on a default, which can vary by packaged Parquet version. For managed services, use the service's supported cluster or session configuration mechanism. Availability and resources Azure Databricks does not currently support ABFS Vectored Read because its runtime ships an ABFS version that does not include this capability. In addition, Photon does not use the ABFS driver for data access, even when a workload uses an abfs:// or abfss:// URI. Therefore, the presence of an ABFS URI alone does not indicate that Vectored Read is available. For other packaged or managed runtimes, verify that the environment includes Apache Hadoop 3.3.5 or later with the hadoop-azure module, and parquet-hadoop 1.12.3 or later. Start with one representative selective-read workload and compare it with your baseline. For background, see the ABFS driver overview.367Views2likes0Comments
Databricks connect with Azure SQL Database
While following a Data Engineering hands-on tutorial on a YouTube channel, I ran into a JDBC connection failure in a Medallion architecture (Bronze to Silver pipeline). Interestingly, my initial connection configuration code runs successfully, but the actual read operation using spark.read.jdbc throws an error. Both connections use the same personal account login. Error: [FAILED_JDBC.CONNECTION] Failed JDBC jdbc:sqlserver:*********(redacted) on the operation: SQLSTATE: HV000 Why is spark.read.jdbc throwing a [FAILED_JDBC.CONNECTION] error with SQLSTATE: HV000 when the basic connection details are correct and working elsewhere? Any help to resolve this is greatly appreciated.149Views0likes1CommentMigrating Azure Cosmos DB Across Regions
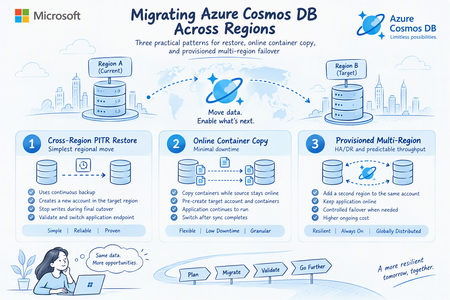
What this article delivers? A decision-oriented, implementation-ready walkthrough based on a hands-on Azure Cosmos DB for NoSQL lab. It corrects the online copy sequence, includes the required Azure CLI snippets, and separates migration duration from application cutover downtime. Regional migration in Azure Cosmos DB is not a single operation. The correct pattern depends on whether the priority is the simplest supported move, the smallest application outage, or a durable multi-region architecture. The Three Migration Patterns at a Glance Pattern Best fit App impact Destination Primary caution 1. Cross-Region PITR restore Simplest regional move Stop writes during final cutover New account created by restore Target-region capacity and restore-point readiness 2. Online copy Minimal downtime Source stays online until cutover Pre-created account and empty target containers Preview prerequisites, RBAC, RU limits, one job per container 3. Provisioned multi-region HA/DR and predictable throughput Online while adding region; controlled failover Same account, second region Higher ongoing cost; conversion back to serverless is not a standard self-service path Before you migrate: establish the decision inputs A reliable migration plan starts by separating total data-movement time from business downtime. Online copy can run for hours or days without requiring the application to stop. Restore may complete quickly, but the application still needs a controlled write freeze, validation, endpoint change, and restart. Define both measures explicitly. Capacity is a migration dependency: A restore that creates a new account still requires the target region to accept the deployment. Validate region availability early, keep an escalation path ready, and avoid treating a successful small-environment test as a capacity guarantee for production. Current Environment Setup Cosmos DB Environment with Capacity Mode= Serverless: Current CosmoDB Topology: Data Count in current database pre-migration: Approach 1: Cross-region point-in-time restore This is the preferred first option when the customer can accept a short write outage and is comfortable moving to a new Cosmos DB account. The restore operation creates the target account; you do not pre-create the destination account as you do for online container copy. Conceptual Plan: Execution flow Confirm the source account uses continuous backup and that the required restore point is available. Validate target-region readiness and prepare the target account name, resource group, networking, identity, and application configuration plan. Schedule the cutover and stop application writes. Start the restore into the target region. Azure creates the new account. Validate account state, databases, containers, policies, item counts, networking, private endpoints, and data-plane RBAC. Update the application endpoint and credentials or managed-identity assignments. Start the application and validate reads and writes. Keep the source account unchanged for an agreed rollback window, then retire it after sign-off. Pre-checks and validation snippets RG="CosmoDB_Demo" SRC_ACCOUNT="demotestingenvironment" az cosmosdb show \ --resource-group "$RG" \ --name "$SRC_ACCOUNT" \ --query "{Account:name,BackupPolicy:backupPolicy.type,Locations:locations[].locationName,State:provisioningState}" \ -o json Review BackupPolicy Type: Note Follow Restore an Account That Uses Continuous Backup Mode - Azure Cosmos DB | Microsoft Learn to update to restore option In the Azure Portal: Cosmos DB → testingenvironmentfordemo → Backup & Restore. Periodic → Continuous Referesh the page and fill in Restore requirements. Cross region restore incurs additional charges on top of the normal point-in-time restores, the price depends on the regions that you are restore from and to. Learn more New Account is created, with data: Testing and Validation Check if the deployment is successful: Count of data across both databases are the same: Approach 2: Online container copy with minimal downtime Online container copy is a container-by-container migration. The application continues reading and writing to the source during the initial copy and incremental synchronization. At cutover, the team stops source writes, waits for the job to catch up, calls the completion operation, validates the target, and then switches the application. The Azure CLI command group and the feature are preview capabilities, so production adoption should include preview acceptance, current limitation review, and a tested fallback. Reference topology used in the lab Component Source Destination Account demotestingenvironment demotestingenvironmentrestore Database demotestingDB demotestingDB Container demotestingDBID demotestingDBID-copy Partition key /category /category Mode Serverless Serverless in the lab Step 1: Define reusable variables RG="CosmoDB_Demo" SRC_ACCOUNT="demotestingenvironment" DEST_ACCOUNT="demotestingenvironmentrestore" SRC_DB="demotestingDB" SRC_CONTAINER="demotestingDBID" DEST_DB="demotestingDB" DEST_CONTAINER="demotestingDBID-copy" JOB="online-copy-hls-final-04" Install the copy extension az extension add --name cosmosdb-preview --upgrade Step 2: Verify source az cosmosdb show -g "$RG" -n "$SRC_ACCOUNT" --query "{Backup:backupPolicy.type,Capabilities:capabilities[].name,State:provisioningState}" -o json Confirm that Backup is Continuous. Confirm that the source has All Versions and Deletes change feed enabled, and review compatibility limitations before applying the capability to an existing production account. Step 3: Create the empty destination container az cosmosdb sql container create -g "$RG" -a "$DEST_ACCOUNT" -d "$DEST_DB" -n "$DEST_CONTAINER" -p "/category" Configure source identity and destination access az cosmosdb identity assign -g "$RG" -n "$SRC_ACCOUNT" SRC_PRINCIPAL=$(az cosmosdb show -g "$RG" -n "$SRC_ACCOUNT" --query "identity.principalId" -o tsv) az cosmosdb update -g "$RG" -n "$SRC_ACCOUNT" --default-identity "SystemAssignedIdentity" az cosmosdb sql role assignment create -g "$RG" -a "$DEST_ACCOUNT" --role-definition-id "00000000-0000-0000-0000-000000000002" --principal-id "$SRC_PRINCIPAL" --scope "/" Step 4: Start Online Copy az cosmosdb copy create --resource-group "$RG" --job-name "$JOB" --src-account "$SRC_ACCOUNT" --dest-account "$DEST_ACCOUNT" --src-nosql database="$SRC_DB" container="$SRC_CONTAINER" --dest-nosql database="$DEST_DB" container="$DEST_CONTAINER" --mode Online Monitor az cosmosdb copy show -g "$RG" -a "$DEST_ACCOUNT" -n "$JOB" --query "{Status:status,Processed:processedCount,Total:totalCount,Error:error}" -o table Query the destination container SELECT * FROM c WHERE c.id = "HLS-ONLINE-COPY-001" Also review via CLI The record appearing in the destination proves both the initial copy and the incremental-change path. Also compare source and target counts, but do not rely on count equality alone; validate representative documents, partition-key values, updates, deletes, TTL behavior, and application queries. Note: Perform the production cutover correctly Stop all writes to the source container. Wait for the online job to catch up and confirm Error is null. Run the complete operation to finalize the online copy job. Validate target counts, representative records, updates/deletes, indexing behavior, networking, identity, and application connectivity. Switch the application endpoint to the destination account and container. Run read/write smoke tests and monitor 429s, 403s, latency, and error rates. Keep the source unchanged for the approved rollback window, then retire it. Approach 3: Convert to provisioned throughput and use multi-region replication This pattern changes the question from “How do I copy data into a second account?” to “How do I extend the existing account into a second region and fail over?” It is appropriate when the workload needs predictable throughput, stronger regional resiliency, or serverless limits make copy-based approaches impractical. Convert the existing serverless account to provisioned throughput. Review and right-size the initial manual throughput assigned to each container or database. Add the target region as an additional region on the same account. Wait for replication and validate application connectivity. Change failover priority or initiate the approved failover method so the target region becomes the write region. Decide whether to retain the original region for HA/DR or remove it after validation. Convert: Azure Portal → Cosmos DB → demotestingenvironment → Overview → Change capacity mode to provisioned throughput and confirm. Refresh and the capacity mode should change. Under Settings, select Replicate data globally, Select West US 2 as the existing region and under Additional regions, select North Central US. Change the write region: Validate current write region Decision framework Decision question Restore Online copy Provisioned multi-region Can the app stop writes briefly? Best fit Not required during bulk copy Not required while adding region Must the target be an existing account? No; restore creates a new account Yes; pre-create target account/container Same account Need to remain serverless? Supported if target deployment is accepted Possible, but throughput can slow copy No; account becomes provisioned Need built-in regional HA after migration? Single target account unless redesigned Single target account unless redesigned Best fit Main production risk Target capacity and cutover validation Preview prerequisites, RBAC, 429s, copy duration Cost, throughput sizing, irreversible architecture choice References Container Copy Jobs - Azure Cosmos DB Azure CLI: az cosmosdb copy Restore an Azure Cosmos DB account using continuous backup Migrate an account to continuous backup mode Configure data-plane role-based access control Change from serverless to provisioned throughput Compare provisioned throughput and serverless Azure Cosmos DB pricing281Views1like0Comments
URGENT: Microsoft Edge incorrectly flags paytracc.com as typosquatting after multiple reports
Microsoft Edge Website Typo Protection incorrectly flags https://paytracc.com as a possible misspelling of paytrace.com. Paytracc.com is the legitimate official domain of PayTracc, an independent financial technology product. “PayTracc” is the intentional registered brand spelling and is not impersonating or affiliated with PayTrace. The warning has continued despite repeated reports through the “Report that this site URL is not a misspelling” option. Technical verification: • https://paytracc.com returns HTTP 200 OK. • http://paytracc.com returns HTTP 301 and redirects to HTTPS. • A valid TLS certificate and HSTS are enabled. • Chrome and other browsers do not display this warning. • The issue is reproducible only in Microsoft Edge Website Typo Protection. This false positive is discouraging customers from accessing the website. Anyways to resolve this please? Affected domain: https://paytracc.com Incorrect suggested domain: paytrace.com165Views0likes1CommentMeasuring Microsoft 365 Copilot adoption beyond license activation
In adoption programs, I think the interesting measurement starts after users have access. At DataToBiz, we have been looking at the difference between someone trying Copilot once and actually incorporating it into a recurring workflow. For example, repeat usage around a specific task tells a very different story from initial activation. How are teams measuring that second stage of adoption without relying only on license or usage counts?226Views0likes1CommentOptimizing Oracle-to-Power BI Performance and the Path to Modern Analytics
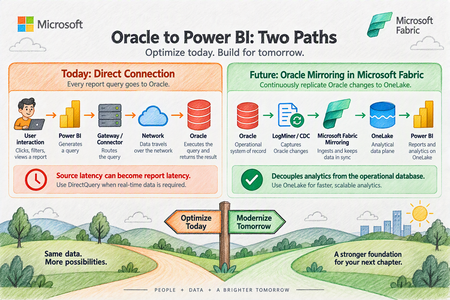
Organizations frequently rely on Oracle databases for large-scale operational workloads while using Microsoft Power BI as their enterprise analytics and visualization platform. Although connecting Power BI directly to Oracle is fully supported, performance can become challenging as datasets grow into the millions of rows. A recent enterprise scenario involving millions of Oracle records illustrates an important principle: Oracle-to-Power BI performance should not be attributed to a single component without first isolating the entire retrieval path. This article provides a practical framework for optimizing that architecture today, while also examining how Microsoft Fabric Mirroring can provide a different data-access pattern for future analytics workloads. The Performance Challenge Consider an Oracle environment containing approximately 15 million records. Testing showed substantially different behavior depending on the client used to retrieve the same Oracle data: A direct Oracle query executed through TOAD returned millions of rows in about eight minutes. Tableau connected to the same Oracle table from the same laptop and refreshed millions of rows in 20 to 30 minutes. Power BI Desktop, however, continued processing for multiple hours before the operation was terminated by network or database controls. Importantly, the Power BI query did not contain additional Power Query transformations. The customer was directly executing SQL and loading the resulting data. This is an extremely useful diagnostic comparison because it demonstrates that Oracle is capable of returning the underlying dataset considerably faster than the Power BI test. It does not, however, prove that the Power BI Oracle connector itself is the single root cause. Performance Is a Pipeline, Not a Single Component Oracle-to-Power BI performance involves several layers: A bottleneck at any one of these layers can affect overall refresh or query performance. Therefore, the first architectural principle is: Measure every layer before attempting to tune the entire solution. A troubleshooting exercise should evaluate: Oracle server-side execution time SQL execution plan Oracle provider/client behavior FetchSize behavior Network transfer Power Query evaluation Query folding Power BI model processing Report design Gateway behavior when the Power BI Service is introduced This approach avoids prematurely concluding that Oracle, Power BI, the gateway, or the connector is inherently responsible for the slowdown. Start With the Oracle Provider Power BI currently provides two important approaches for Oracle connectivity. Built-in Oracle provider Modern versions of Power BI Desktop include Microsoft's bundled Oracle Managed ODP.NET provider. This reduces the dependency on separately installing Oracle client software. For environments using the built-in provider, testing should be performed with a current Power BI Desktop release because provider behavior and defaults can change between releases. Oracle Client for Microsoft Tools Oracle Client for Microsoft Tools, or OCMT, remains another supported option. OCMT configures Oracle Data Provider for .NET and can therefore be tested independently from the built-in provider. This gives architects a useful isolation mechanism: Test A: Built-in Oracle provider vs. Test B: OCMT provider. Use the same: workstation SQL statement Oracle database table credentials network path expected row count Changing several variables simultaneously makes the results considerably harder to interpret. Understand FetchSize One of the most important areas identified during troubleshooting is FetchSize. FetchSize controls how much data the Oracle provider retrieves during each fetch operation. For large datasets, a small FetchSize can require many retrieval operations, increasing overhead. Increasing FetchSize allows the provider to retrieve more data at a time and may improve throughput. However, FetchSize tuning should be tested independently from the choice of Oracle provider. Switching to OCMT, for example, does not by itself demonstrate whether FetchSize tuning improves performance. Benchmark the same SQL and dataset using consistent test conditions and compare elapsed time and throughput. FetchSize controls how much Oracle data the provider pulls back in each retrieval batch. Think of FetchSize like the size of a delivery truck. Imagine Power BI needs to retrieve a very large dataset from Oracle. Small FetchSize: Oracle → 📦 → Power BI Oracle → 📦 → Power BI Oracle → 📦 → Power BI Oracle → 📦 → Power BI ...many retrieval operations Larger FetchSize: Oracle → 📦📦📦📦📦 → Power BI Oracle → 📦📦📦📦📦 → Power BI ...fewer retrieval operations The idea is simple: FetchSize determines how much data the Oracle provider fetches at a time. Examine Oracle Data Types FetchSize is not the only provider consideration. Schema matters. A troubleshooting package should include the table DDL rather than only a list of column names. Pay particular attention to large-object types such as: BLOB CLOB Large-object columns may materially change retrieval behavior and can make simply increasing FetchSize insufficient. Therefore capture: complete table DDL column names Oracle data types row width presence of BLOB/CLOB columns expected total result size Do not optimize FetchSize without understanding the shape of the data being transferred. Filter Rows and Columns as Early as Possible Probably the most universally applicable Power Query optimization is also one of the simplest: Do not retrieve data you do not need. Instead of retrieving every row and column and filtering afterward, reduce the dataset at Oracle whenever possible. Good Oracle SQL should therefore: select only required columns apply restrictive predicates at the source aggregate at Oracle where appropriate avoid unnecessary data transfer This matters substantially when Power BI and Oracle are separated by a network boundary. Preserve Query Folding Power Query query folding allows Power BI transformations to be translated back into SQL executed by the relational source. For relational sources such as Oracle, maintaining folding can substantially reduce the amount of work performed by the Power Query mashup engine. The preferred pattern is: Where practical: filter early remove unnecessary columns early avoid transformations that unexpectedly break folding inspect where folding stops push relational operations back into Oracle For DirectQuery, folding is particularly important because the source remains part of the interactive report-query path. Be Careful With Native SQL and Incremental Refresh Native SQL can be extremely valuable for troubleshooting. Running the same targeted SELECT statement through Power BI that is executed directly against Oracle creates a useful A/B test. It helps isolate questions such as: Is Oracle itself taking a long time? Is Power BI generating a different query? Is additional processing happening after Oracle returns the data? Is the retrieval/provider layer adding significant latency? However, architecture matters. Power BI guidance warns that later Power Query steps cannot necessarily fold after a native SQL query, and native SQL has important implications for incremental refresh. Therefore, native SQL is useful both as an optimization technique in some architectures and as a diagnostic isolation technique, but it should not automatically be substituted for a well-folded Power Query design. Prefer Import for Traditional Oracle BI Workloads If the business does not require near-real-time data, Import should generally be evaluated before DirectQuery for large Oracle analytical workloads. With Import: The latency of Oracle, networking, and the provider is mostly experienced during refresh rather than repeatedly during user interaction. This usually provides a more predictable interactive experience. DirectQuery produces a different dependency chain: As a result, source latency can become report latency. Use DirectQuery when its architectural benefits are required, rather than simply because the source database supports it. Make Incremental Refresh Truly Incremental Import does not necessarily mean repeatedly loading the entire Oracle dataset. For large fact tables, incremental refresh should be evaluated so that only required partitions are refreshed. However, there is an important condition: RangeStart and RangeEnd filtering needs to be pushed back to Oracle. If partition filters do not fold, Power BI can end up retrieving considerably more source data than expected before applying the filtering. Therefore incremental refresh testing should verify that the Oracle query generated by Power BI contains the expected predicates. Treat the Gateway as Its Own Performance Layer Once the workload moves into the Power BI Service, however, the on-premises data gateway becomes another measurable component. For production deployments examine: gateway version Oracle provider/client version CPU memory network proximity to Oracle refresh concurrency DirectQuery concurrency competing workloads Where necessary, large refresh workloads and latency-sensitive DirectQuery workloads can be isolated onto different gateway resources. Do not diagnose gateway performance from a Power BI Desktop test where the gateway is not involved. Optimize DirectQuery If It Cannot Be Avoided Sometimes Import is not viable because users require data with very low latency. If Oracle must remain behind DirectQuery, reduce unnecessary work at every level. At Oracle index frequently filtered columns appropriately review execution plans select only necessary columns reduce returned rows avoid unnecessarily expensive calculations In Power Query maintain query folding push filtering to Oracle minimize transformations requiring local evaluation In the semantic model use efficient dimensional modeling avoid unnecessary high-cardinality columns consider aggregation strategies where appropriate In reports limit visual density use selective filters avoid generating unnecessary simultaneous source queries test with realistic user concurrency DirectQuery performance needs to be assessed as an end-to-end architecture, rather than as an individual SQL benchmark. Collect Diagnostics Before Declaring a Root Cause For difficult Oracle performance cases, establish a repeatable diagnostic package. Capture: Oracle database version execution plan SQL execution duration table DDL data types row count approximate returned data size Provider built-in provider versus OCMT provider/client version FetchSize configuration Power BI Power BI Desktop version generated SQL Query Diagnostics Mashup traces Applied Steps or M code total execution time Network Oracle-to-client path throughput latency connection interruptions or timeouts Comparison clients If Tableau or another Oracle client appears dramatically faster, reproduce the same SQL, same columns, same records, same database and preferably the same machine. Only then does the comparison become a useful engineering benchmark. Future Architecture: Oracle Mirroring in Microsoft Fabric Optimizing the direct Oracle connection solves one class of problem. Microsoft Fabric Mirroring provides a different architecture altogether. Instead of repeatedly placing Oracle in the analytical query path, Fabric can continuously replicate Oracle changes into OneLake. Conceptually: Fabric Mirroring uses Oracle LogMiner to capture changes and maintain an analytical copy in OneLake. This separates many downstream analytical reads from the operational Oracle database. The key architectural advantage isn't simply "a faster connector." The advantage is decoupling analytics from the operational database. Recommended Architecture Decision Tree Requirement: traditional BI with scheduled freshness Use: Oracle → Import → Power BI semantic model. Then optimize: FetchSize provider query folding source-side filtering incremental refresh Requirement: operational or near-real-time reporting where Oracle must remain the source Evaluate: Oracle → DirectQuery → Power BI. But aggressively optimize: Oracle SQL execution plans query folding visual density provider configuration concurrency gateway architecture Requirement: enterprise analytics with frequent Oracle changes and growing BI/AI requirements Evaluate: Oracle → Fabric Mirroring → OneLake → Fabric / Power BI. This reduces repeated analytical pressure against the operational Oracle environment and creates a reusable analytical data foundation for additional workloads. A Practical Troubleshooting Sequence A useful Oracle-to-Power BI performance investigation can be organized into five phases. Phase 1: Establish the Oracle baseline Execute exactly the same query directly against Oracle. Record: SQL → rows → bytes → execution time Phase 2: Isolate the provider Run the same dataset through: Built-in Oracle provider and OCMT. Record the results independently. Phase 3: Test FetchSize Test controlled FetchSize values while holding every other variable constant. Measure throughput rather than relying on subjective impressions. Phase 4: Optimize Power Query Validate: query folding source filtering column projection transformations incremental refresh behavior Phase 5: Decide whether the architecture itself should change If extremely large Oracle datasets must continually feed analytical workloads, consider whether repeatedly querying Oracle remains the appropriate long-term design. At that point, Fabric Mirroring becomes an architectural discussion rather than simply another troubleshooting step. Final Takeaway Oracle-to-Power BI performance problems should not immediately be categorized as an Oracle problem, a Power BI problem, or a gateway problem. They are usually best investigated as a data retrieval pipeline. For existing Power BI architectures, the strongest optimization sequence is: Efficient Oracle SQL For the longer term, Microsoft Fabric Mirroring changes the architecture: Oracle becomes the operational system of record while OneLake becomes the analytical data plane. That separation can be particularly valuable as organizations expand from traditional Power BI reporting into broader Fabric analytics, data engineering and AI workloads.293Views1like0CommentsIntroducing the Microsoft Sentinel ASIM EmailEvent schema
Email remains one of the most common entry points for security threats. Yet email products often describe the same activity with different table names, fields, and values. This makes it harder to build detections and investigations that work consistently across data sources. The Microsoft Sentinel Advanced Security Information Model, or ASIM, EmailEvent schema is now available. It provides a common structure for email delivery and inspection events, helping customers and partners create security content that works across supported email data sources. A consistent view of email security activity EmailEvent standardizes the information analysts need to understand what happened to an email and why. It covers: Email delivery and inspection events Sender, source, and recipient information Message subject, size, direction, and delivery location URLs and file attachments SPF, DKIM, and DMARC authentication results Delivery actions such as delivered, blocked, quarantined, or deleted Threat, risk, confidence, tactic, technique, and remediation details Instead of learning a different data model for every product, analysts can query the normalized EmailEvent fields. Parser developers map each source's native data to the same schema. How it works Consider an email that contains a suspicious attachment. The email security product records the sender, recipients, attachment, authentication results, inspection verdict, and final action. A connector collects that event. A parser or Data Collection Rule maps the source fields to EmailEvent. Microsoft Sentinel can then query the normalized record using the same field names used for other supported email sources. This common structure separates security content from the details of a specific product. When another source adds an EmailEvent parser, existing source-independent queries and detections can work with that source without being rewritten around its native field names. Why it matters Simpler analytics: Write queries against one consistent set of email fields. Broader coverage: Apply source-independent security content across normalized email sources. Faster investigations: Compare delivery, authentication, attachment, URL, and threat details without translating different data models. Easier integration: Give connector and parser developers a defined contract for bringing new email telemetry into ASIM. EmailEvent does not replace the rich native data produced by email security products. It provides a consistent security layer that makes that data easier to use together. Build on EmailEvent The EmailEvent release includes the schema definition, source-independent parser framework, filtering parser, deployment templates, and validation support in the Azure-Sentinel repository. The schema version is 1.0.0. Customers can use normalized EmailEvent data to develop hunting queries, analytics rules, workbooks, and investigation experiences. Partners and community contributors can create source-specific parsers that map their email data to the schema. Get started Normalization Email Schema MS Learn Learn about normalization and ASIM Explore the EmailEvent implementation in Azure-Sentinel Deploy ASIM parsers Thank you to the ASIM engineering and partner teams who contributed to the schema, deployment path, validation, and release.815Views1like0Comments