analytics
857 Topics
Databricks connect with Azure SQL Database
While following a Data Engineering hands-on tutorial on a YouTube channel, I ran into a JDBC connection failure in a Medallion architecture (Bronze to Silver pipeline). Interestingly, my initial connection configuration code runs successfully, but the actual read operation using spark.read.jdbc throws an error. Both connections use the same personal account login. Error: [FAILED_JDBC.CONNECTION] Failed JDBC jdbc:sqlserver:*********(redacted) on the operation: SQLSTATE: HV000 Why is spark.read.jdbc throwing a [FAILED_JDBC.CONNECTION] error with SQLSTATE: HV000 when the basic connection details are correct and working elsewhere? Any help to resolve this is greatly appreciated.123Views0likes1Comment
A streaming pipeline can be healthy even when the data isn't complete yet.
One thing worth separating in streaming systems is processing time from event time. A message can arrive late because of a disconnected device, a network delay or an upstream system that buffers events. If downstream aggregations assume every event arrives in chronological order, the resulting windows can be misleading. In event-stream processing, event-time windows and watermarks help define how long the system waits for late events before considering a window sufficiently complete. The exact behaviour depends on the processing engine and its configuration. A few questions come up when designing these pipelines: How late can events realistically arrive? What should happen to events that arrive after the allowed lateness? Does the business require corrected historical aggregates? How do you monitor event-time lag separately from processing latency? There is not one watermark setting that fits every workload. A short delay may reduce reporting latency but increase the number of late events that need separate handling. How do you choose the lateness threshold for Azure streaming workloads, especially when the business expects both low latency and accurate historical results?117Views0likes1Comment
Legacy SSRS reports after upgrading Azure DevOps Server 2020 to 2022 or 25H2
We are currently planning an upgrade from Azure DevOps Server 2020 to Azure DevOps Server 2022 or 25H2, and one of our biggest concerns is reporting. We understand that Microsoft’s recommended direction is to move to Power BI based on Analytics / OData. However, for on-prem environments with a large number of existing SSRS reports, rebuilding everything from scratch would require significant time and effort. Since Warehouse and Analysis Services are no longer available in newer versions, we would like to understand how other on-prem teams are handling legacy SSRS reporting during and after the upgrade. Have you rebuilt your reports in Power BI, moved to another reporting approach, or found a practical way to keep existing SSRS reports available during the transition? Any real-world experience, lessons learned, or recommended approaches would be greatly appreciated.511Views0likes4CommentsSimplify private connectivity for Azure Databricks Serverless with Private Network Gateway
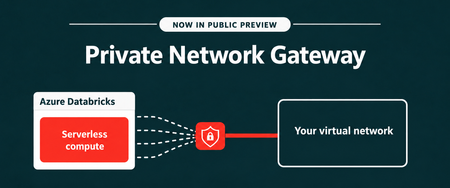
Recently, we announced the public preview of Private Network Gateway (PNG) for Azure Databricks - a simpler way to connect Azure Databricks serverless workloads to resources accessible from your Azure Virtual Network. With a single managed connection into your network, PNG helps reduce connectivity complexity while letting you control which resources serverless workloads can access. In this post, we explain what PNG means for private connectivity and how to get started. PNG brings the serverless experience together with the Azure networking environment and controls organizations already use, helping make serverless practical for a broader set of enterprise workloads. One connection to your network Azure Databricks serverless compute runs in an Azure Databricks managed network. This removes infrastructure management overhead, but private resources still need an explicit network path from serverless compute. Today, connecting serverless compute to resources you manage such as databases, Kafka clusters, and internal APIs could require separate private endpoints, load balancers, and proxy VMs for individual resources. That complexity grows as workloads need to reach more services across virtual networks, peered networks, and on-premises environments. Private Network Gateway introduces a simpler model: one gateway to your network instead of separately creating connectivity infrastructure for each resource. With Private Network Gateway on Azure Databricks, you can: Simplify private data ingestion. Use Lakeflow Connect on serverless compute to ingest from supported databases across your virtual network and connected on-premises environments. Connect AI agents to private services. An agent built on Azure Databricks can call a private MCP server you host. Use private package repositories. Install Python libraries from a private PyPI, Artifactory, or Nexus repository inside your network. Route egress through your existing firewall. Send traffic through your firewall or content inspection service so egress can be filtered and logged using your own tools. Use your own source IP. SaaS applications such as Salesforce can see a source IP belonging to your organization. Getting started is straightforward Private Network Gateway is designed to simplify the setup needed to bring serverless compute into your network. You delegate one subnet in your Azure Virtual Network to Azure Databricks. Private Network Gateway then establishes a managed, encrypted gateway from serverless compute into that subnet. The gateway is configured within a Network Connectivity Configuration (NCC), the account-level object used for Azure Databricks serverless networking. You can attach the NCC to your workspaces, and supported serverless workloads can then reach the private destinations you allow. And because the gateway is managed for you, there are no gateway VMs for you to deploy, patch, or scale in your network. Keep control of your Azure network Simplifying connectivity doesn’t mean giving up control of your network boundary. Private Network Gateway provides a dedicated path into your network rather than a shared appliance carrying other customers’ traffic. The gateway applies workspace-level access controls before traffic leaves, and isolation is enforced through encapsulation and network security rules. Once traffic reaches your subnet, your existing Azure networking controls continue to determine what serverless workloads can reach. This includes your route tables, network security groups, DNS resolvers, and security appliances. You also control how much traffic travels through the gateway: Specific destinations: Send only the fully qualified domain names you specify through Private Network Gateway. Other traffic retains its normal path. All traffic: Route outbound traffic through your network, except traffic matching a more specific Private Link or service-endpoint path. This can be used when you want broader egress inspection through your firewall or want traffic to leave through your own IP addresses. Private Network Gateway is also additive to your existing connectivity architecture. It sits alongside the private connectivity and egress controls you already use and can be enabled or removed without changing the existing setup. Bringing serverless to more of your Azure Databricks workloads Azure Databricks combines Databricks capabilities with native integration across the Azure ecosystem. Private Network Gateway extends that Azure Databricks experience to private networking for serverless workloads. Instead of building connectivity infrastructure for every resource, you can establish one managed gateway from serverless compute to your network and keep using your existing Azure network controls to decide where traffic goes. The result is a simpler approach to connecting serverless workloads to private enterprise resources while keeping the network boundary in your control. Get started today Private network gateway - Azure Databricks | Microsoft Learn Introducing Private Network Gateway | Databricks Blog554Views1like0Comments
Optimize selective analytics reads in Azure Data Lake Storage with ABFS Vectored Read
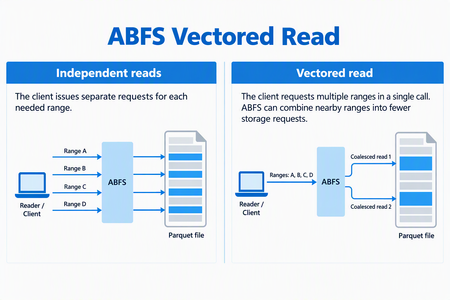
ABFS Vectored Read helps compatible analytics engines reduce request overhead when reading selected portions of columnar files in Azure Data Lake Storage. By coordinating multiple noncontiguous byte ranges through the Azure Blob File System (ABFS) driver, it can combine nearby ranges into fewer storage requests and execute those requests asynchronously. For data engineers working with selective Parquet queries, this brings the storage read pattern closer to what the query needs: a coordinated set of ranges rather than a collection of independent small reads. When the Parquet reader supports vectored I/O and the runtime includes a compatible ABFS client, Spark workloads that use higher-level APIs can enable this capability through configuration - without rewriting queries, changing application logic, or migrating data. Why selective reads need coordinated I/O Consider a query that selects a few columns from a Parquet dataset and filters out most row groups. The reader can skip much of the data the query doesn't need, but the data it needs may be spread across different parts of the file. Reading each range independently can create many small storage requests. Each request carries network and processing overhead, so selecting less data doesn't necessarily remove the cost of coordinating those reads. Vectored Read lets a compatible reader provide the ranges together, giving the client an opportunity to plan the I/O as a group. How ABFS Vectored Read works A compatible reader submits the file ranges it needs together. ABFS validates and sorts the ranges, combines nearby ranges when appropriate, and divides the resulting work to fit its read buffers. It then queues the storage requests asynchronously and returns the requested bytes to the corresponding range buffers. Illustrative request pattern, not a benchmark. Actual grouping depends on range layout and client configuration; coalesced storage requests can include bytes between the requested ranges. This is a client-side optimization. It does not change the file format or rewrite your stored data. The engine still receives the data for the ranges it requested. What this means for your workloads For compatible selective-read workloads, Vectored Read offers: Less request overhead: Combining nearby ranges can reduce separate storage requests and network round trips. Coordinated I/O: Asynchronous reads allow the client to work on multiple requested ranges without treating every range as an isolated operation. Configuration-based adoption: Compatible Spark workloads using the Hadoop Parquet and ABFS path can use the feature without rewriting their queries. The best starting point is a workload that reads selected portions of Parquet files through abfs:// or abfss://. Full sequential scans may see less benefit, and engines that bypass the Hadoop/ABFS path do not use this capability. Support depends on the Hadoop, hadoop-azure, and parquet-hadoop libraries included in the runtime, not only on the Spark version. See Availability and resources for the minimum versions and verification guidance. The benefit depends on the number, size, and spacing of requested ranges, the coalescing configuration, storage and network latency, concurrency and caching. Combining ranges can reduce requests and round trips, but it can also read additional bytes between noncontiguous requested ranges. Compare query duration, storage transactions, bytes read, and resource utilization against a controlled baseline using representative data and concurrency. Get started First, verify that your runtime contains Apache Hadoop 3.3.5 or later, including the hadoop-azure module, and parquet-hadoop 1.12.3 or later. The presence of an ABFS URI alone does not establish that the optimized implementation is installed. For Spark, enable the Parquet setting before the application starts, using the spark.hadoop. prefix: spark-submit \ --conf spark.hadoop.parquet.hadoop.vectored.io.enabled=true \ <other-options> \ <application> Replace the command placeholders with your normal submission options and application. Set the property explicitly rather than relying on a default, which can vary by packaged Parquet version. For managed services, use the service's supported cluster or session configuration mechanism. Availability and resources Azure Databricks does not currently support ABFS Vectored Read because its runtime ships an ABFS version that does not include this capability. In addition, Photon does not use the ABFS driver for data access, even when a workload uses an abfs:// or abfss:// URI. Therefore, the presence of an ABFS URI alone does not indicate that Vectored Read is available. For other packaged or managed runtimes, verify that the environment includes Apache Hadoop 3.3.5 or later with the hadoop-azure module, and parquet-hadoop 1.12.3 or later. Start with one representative selective-read workload and compare it with your baseline. For background, see the ABFS driver overview.326Views2likes0CommentsTableau to Power BI Migration: Semantic Layer-First Approach for Cloud Architects
Author's: Mahjabin Ahmed, Yassine El Ouardi, Lavanya Sreedhar LavanyaSreedhar, Peter Lo PeterLo, Aryan Anmol aryananmol, Shreya Harvu shreyaharvu and Rafia Aqil Rafia_Aqil In this guide, we provide practical guidance for migrating from Tableau to Power BI, with a focus on technical best practices and architecture. Unifying business intelligence on the Microsoft Fabric platform, enterprises gain closer integration with Microsoft 365 (Teams, Copilot, Excel). For cloud solution architects and BI developers, a successful migration is not just about rebuilding dashboards in a new tool. It requires thoughtful architectural planning and a shift to a more model-centric approach to BI. Why Semantic Layer-First Architecture Matters The Traditional Migration Challenge Most Tableau to Power BI migrations follow a dashboard-centric approach: teams attempt to replicate existing Tableau workbooks, calculated fields, and LOD (Level of Detail) expressions directly into Power BI reports. While this may seem efficient initially, it creates significant downstream challenges: Duplicated logic: Each report embeds its own calculations and business rules, leading to conflicting KPIs across the organization Maintenance overhead: Changes to business logic require updating dozens or hundreds of individual reports Governance gaps: Without centralized definitions, semantic drift occurs—different teams calculate "Revenue" or "Active Customer" differently Scalability issues: As data volumes grow, report-level transformations become performance bottlenecks The Semantic Layer-First Alternative Microsoft's recommended approach centers on semantic models (formerly called datasets)—centralized, governed data models that separate business logic from visualization. In this architecture: The payoff is substantial: when data evolves or business rules change, you update the semantic model once, and all dependent reports automatically reflect the changes—no manual redesign required. Understanding Migration Complexity: Simple to Very Complex Dashboards Not all Tableau dashboards are created equal. The migration strategy should align with dashboard complexity, and the semantic layer approach becomes increasingly valuable as complexity grows. Follow a Step-by-Step Migration Strategy Migrating from Tableau to Power BI is not a one-click effort – it requires a mix of automated and manual refactoring, plus a sound change management plan. Below are key strategies and best practices for a successful migration: Audit your Tableau estate: Start by taking inventory of all existing Tableau workbooks, data sources, and dashboards. Determine what needs to be migrated (focus on high-value, widely used reports first) and identify any redundant or obsolete content that can be retired rather than converted. Conduct a proof-of-concept (PoC): Before migrating everything, pick a representative complex dashboard (or a subset of your data) and perform a pilot migration. This will help you validate that Power BI can connect to your data (e.g. setting up the Power BI gateways for on-premises sources), test performance (Import vs DirectQuery modes), and experiment with replicating key visuals or calculations. Use the PoC to uncover any surprises early – for example, test that any Level of Detail expressions or table calculations in Tableau can be re-created in DAX. The lessons learned here should inform your overall project plan. Use a phased migration approach: Plan to run Tableau and Power BI in parallel for some period, rather than switching everything at once. Migrate in waves – for example, by business unit or subject area – and incorporate user feedback as you go. This phased approach reduces risk and allows your team to improve the process with each iteration. It also gives end users time to adjust gradually. Migrate high-impact dashboards first: Prioritize the migration of key reports and dashboards that are critical to the business or have the most usage. Delivering these early wins will not only surface any technical challenges to solve but will also help demonstrate the value of Power BI’s capabilities to stakeholders. Early success builds buy-in and momentum for the rest of the migration. Reimagine (don’t just replicate) the experience: It’s rarely possible – or desirable – to exactly re-create every Tableau visualization pixel-for-pixel in Power BI. Embrace the opportunity to focus on business questions and improve user experience with Power BI’s features. For example, rather than replicating a complex Tableau workaround, you might implement a cleaner solution in Power BI using native features (like bookmarks, drilldowns, or simpler navigation between pages). Engage business users and subject matter experts during this redesign to ensure the new reports meet their needs. Enable dataset reusability: One major benefit of the Power BI approach is the ability to create shared datasets and dataflows. As you migrate, look for opportunities to create central semantic models (datasets) that can serve multiple reports. For instance, if several Tableau workbooks are all using similar data about sales, you can create one central Sales dataset in Power BI. Report creators across the organization can then build different Power BI reports on that single dataset without duplicating data or logic. This reduces maintenance and promotes a “build once, reuse often” strategy. Provide training and support: Expect a learning curve for teams moving to Power BI – especially those who are very fluent in Tableau. Plan for user upskilling and training programs. Establish a support community or office hours where new users can ask questions and get help. If possible, identify Power BI champions or recruit a Power BI Center of Excellence (COE) team who can guide others. During the transition, ensure there are subject matter experts (SMEs) available to address questions and validate that the new reports are correct. Manage change and expectations: It’s important to communicate why the organization is moving to Power BI (e.g. benefits like deeper integration, lower TCO, better governance) to get buy-in from end users. Some users may be resistant to change, especially if they’ve invested a lot of time in mastering Tableau. Prepare to handle varying responses – emphasize the personal benefits (like improved performance, new capabilities, or career growth with popular skills) to encourage adoption. Also, involve influential business users early and gather their feedback, so they feel ownership in the new solution. Establish governance from Day 1: Don’t wait until after migration to think about governance. Use this chance to set up Power BI governance aligned to best practices. Decide on important aspects such as workspace naming conventions, who can create or publish content, how you’ll monitor usage and costs, and how to manage data access and security (for example, designing a strategy for RLS/OLS/CLS, and deciding when to use per-user datasets vs. organizational semantic models). Good governance will ensure your shiny new Power BI environment doesn’t sprawl into chaos over time. Allow time for adjustment and iteration: Finally, be patient and iterative. Depending on the scale of your organization and the number of Tableau assets, a full migration can take months or even a year or more. Plan realistic transition periods where both systems might coexist. Continuously refine your approach with each wave of migration. Power BI’s frequent update cadence (monthly releases) means new features may emerge even during your project – stay updated, as new capabilities could simplify your migration (for example, the introduction of field parameters or Copilot might let you modernize certain Tableau features more easily). Reimagine (don’t just replicate) the experience (Step 5): Phase 1: Assessment and Planning 1. Audit Your Tableau Estate Inventory all workbooks, data sources, and calculated fields Identify high-traffic dashboards (prioritize for early migration) Categorize by complexity (Simple/Medium/Complex/Very Complex) 2. Design Your Semantic Architecture Map Tableau data sources to Power BI data sources (DirectQuery, Import, or Direct Lake) Plan star schema for fact/dimension tables Identify shared calculations that should live in semantic models vs. report-specific logic 3. Choose Storage Modes Source Type Recommended Mode Rationale Databricks Delta Lake Direct Lake Real-time analytics, no refresh lag Azure SQL Database DirectQuery or Import Based on data volume and refresh SLAs On-Premises SQL Server Import (via Gateway) Network latency considerations Excel/CSV files Import Small reference data Phase 2: Build the Semantic Layer 1. Create Star Schema Data Models Tableau often relies on flat, denormalized datasets. Power BI performs best with star schemas: Fact tables: Transactional data (sales, orders, events) with foreign keys to dimensions Dimension tables: Descriptive attributes (customers, products, dates) with primary keys Relationships: One-to-many from dimension to fact, leveraging bidirectional filtering sparingly 2. Migrate Calculations to DAX Measures Convert Tableau calculated fields to DAX measures in the semantic model: --Example of DAX: -- Define as measure: Total Revenue = SUMX( 'Sales', 'Sales'[Quantity] * 'Sales'[Unit Price] ) 2.1 Use Copilot to Accelerate DAX Development Leverage Copilot in Power BI Desktop to generate and validate DAX: Describe the calculation in natural language Copilot suggests DAX syntax Review, test, and refine 2.2 Document your Semantic Model Invest in creating an AI-ready foundation for your semantic model. AI systems need to understand unique business contexts in order to prioritize correct information to provide consistent and reliable responses to your end users. Name Tables and Columns Clearly: Avoid ambiguity in your semantic model. Use human-readable, business-friendly names. Avoid abbreviations, acronyms, or technical terms. This improves Copilot’s ability to interpret user intent. Create Meaningful Measures: Define reusable DAX measures for key business metrics (e.g., Revenue, Profit Margin). AI features rely on these to generate insights and summaries. Document Semantic Model objects: Add descriptions and synonyms to your Tables, Columns and measures. This enhances natural language querying and improves Copilot’s contextual understanding. Build an AI Data Schema: prepare your semantic model for AI by utilizing tooling features such as Prep data for AI. Phase 3: Understanding Migration Complexity: Simple to Very Complex Dashboards Not all Tableau dashboards are created equal. The migration strategy should align with dashboard complexity, and the semantic layer approach becomes increasingly valuable as complexity grows. 1. Dashboard Conversion Best Practices Think in "pages" not "sheets": Power BI reports combine multiple visuals per page; group related visuals logically Use slicers for interactivity: Replace Tableau filters with Power BI slicers and filter pane Leverage bookmarks for navigation: Create dynamic report experiences with show/hide containers Simple Complexity Level Category Tableau Feature Power BI Equivalent Microsoft Fabric Enhancements Best Practice Notes Data Model Single custom SQL Power Query for data shaping and ETL. OneLake Shortcuts for unified data access. Use star schema for optimized performance; push logic into the semantic layer rather than visuals. Calculations Basic IF/ELSE, SUM Data Analysis Expressions (DAX) for measures and calculated columns. Copilot for Power BI to assist with DAX creation. Fabric IQ for natural language queries. Centralize calculations in semantic models for consistency and governance. Medium Complexity Level Category Tableau Feature Power BI Equivalent Fabric Enhancements Best Practice Notes Data Model Multiple custom SQL (up to 3) Connect live to databases (Azure Databricks): DirectQuery in Power BI Connect with cloud data sources: Power BI data sources OneLake Shortcuts for unified access without databricks compute cost. Semantic Models can combine multiple sources. Optimize with star schema; Prefer OneLake Shortcuts for performance; avoid heavy transformations in visuals. Calculations Nested IFs, CASE Data Analysis Expressions (DAX) for measures and calculated columns. Copilot for Power BI to assist with DAX creation. Fabric Data Agent for conversational BI. Fabric IQ for natural language queries: Fabric IQ Centralize logic in semantic models; use Copilot for automation and validation; keep calculations reusable. Reporting Tooltip format in Bar and Map visuals Select All/Clear option for Single Select dropdown Standard tooltips offer help tooltips, text, and background formatting. Dynamic tooltip will be able to create the Tooltip page and reuse it in multiple visuals The customization is so much better than the OOB tooltips Create report tooltip pages in Power BI - Power BI | Microsoft Learn Use Clear All Slicers Button. Disable Single Select, Add Clear All Slicers button, Customize the Button and Use the Button Complex Complexity Level Category Tableau Feature Power BI Equivalent Fabric Enhancements Best Practice Notes Data Model Multiple sources Create relationship using more than one column Composite Models in Power BI (DirectQuery + Import) for combining multiple sources, also connect to various cloud services. Dataflows for pre-processing. Power BI allows a relationship between 2 tables based on only one active column. OneLake Shortcuts for unified access without Azure Databricks compute cost; Microsoft Fabric Dataflows Gen2 offers multiple ways to ingest, transform, and load data efficiently. Consolidate sources into semantic models; use Direct Lake for performance; Plan and design data model to comply with star schema supported by Power BI Relationship DAX USERELATIONSHIP DAX for activating relationships in Power BI for a specific calculation Calculations LOD, window functions Data Analysis Expressions (DAX) for measures and calculated columns. Copilot to assist with complex DAX. Fabric IQ Ontology for semantic alignment. Change how visuals interact in a Power BI report. Centralize calculations in semantic layer; use variables in DAX for readability and performance. Fabric Data Agent for a conversational BI. Very Complex Complexity Level Category Tableau Feature Power BI Equivalent Fabric Enhancements Best Practice Notes Data Model Multi-source, Excel, SQL Composite Models in Power BI (DirectQuery + Import) for combining multiple sources, also connect to various cloud services. Dataflows for pre-processing. OneLake Shortcuts for unified access; Connector overview build-in support. Mirroring for real-time sync. Combine multiple sources into well-structured semantic models for consistency and optimized performance. Calculations Predictive logic Data Analysis Expressions (DAX) for measures and calculated columns. Fabric AutoML, ML models, AI Insights, Python/R, Notebook‑based ML (Spark/Scikit‑Learn), Fabric AI Functions, Fabric IQ Ontology Fabric Data Agent for a conversational BI. Centralize logic in semantic models; leverage Copilot for automation and parameter-driven workflows. Prepare for Copilot. 2. Tableau Feature Equivalents Tableau Feature Power BI Equivalent Microsoft Learn Link Calculated Fields DAX Measures DAX Documentation Parameters Field Parameters / Bookmarks Use report readers to change visuals Actions Drillthrough / Bookmarks Drillthrough Tableau Prep Power Query / Dataflows Differences between Dataflow Gen1 and Dataflow Gen2 Tableau Server Power BI Service What is Power BI? Overview of Components and Benefits Phase 4: Governance and Deployment Workspace Planning (Dev / Test / Prod Separation) A proper workspace strategy is essential for governed deployments in Fabric and Power BI. Fabric supports separate Development, Test, and Production stages using Deployment Pipelines, enabling controlled promotions of semantic models, reports, dataflows, notebooks, lakehouses, and other items. You can assign each workspace to a pipeline stage (Dev → Test → Prod) to ensure safe lifecycle management. Sensitivity Labeling (Microsoft Purview Information Protection) Sensitivity labels allow governed classification and protection of data across Fabric items. Sensitivity labels can be applied directly to Fabric items (semantic models, reports, dataflows, etc.) through the item's header flyout or the item settings. Labels from Microsoft Purview Information Protection enforce data access rules and help organizations meet compliance requirements. Endorsement & Certification (Promoted, Certified, Master Data) Endorsement improves discoverability and trust in shared organizational content. Promoted: Item creators mark content as recommended for broader use. Certified: Administrators or authorized reviewers validate content meets organizational quality standards. Master Data: Indicates authoritative single‑source‑of‑truth items such as semantic models or lakehouses. All Fabric items except dashboards can be promoted or certified; data‑containing items can be designated as Master Data. Monitoring & Capacity Planning Determine the appropriate size for fabric capacity when migrating from Tableau to PowerBI. The Fabric SKU Estimator can generate a SKU recommendation (estimate) for your capacity requirements. Ensuring performance and cost efficiency requires ongoing monitoring of your Fabric capacity. Microsoft recommends evaluating workloads using Fabric Capacity Metrics and planning SKU sizes based on real usage. Fabric uses bursting and smoothing to handle spikes while enforcing capacity limits. Monitoring helps identify high compute usage, background refreshes, and interactive workloads to optimize performance. Fabric Data Source Connections (OneLake+ Manage Connections) Microsoft Fabric is designed as an end‑to‑end analytics platform that integrates data from many different source systems into a unified environment powered by OneLake, Data Factory, Real‑Time Analytics, Dataflows , Lakehouses, Warehouses, and Mirrored Databases. The Strategic Advantage: Semantic Layer + Fabric IQ The semantic layer-first approach sets the foundation for the next evolution in enterprise analytics. Fabric IQ (announced at Ignite 2025) is Microsoft's semantic intelligence platform that auto-elevates semantic models into ontologies—structured knowledge graphs that power AI agents, Copilot experiences, and cross-domain data reasoning. What this means for your migration: Semantic models you build today become the foundation for AI-driven analytics tomorrow Data Agents can reason across multiple semantic models, answering questions that span domains Business users transition from "report consumers" to "data explorers" via natural language interfaces Conclusion: Build for the Future, Not Just for Today Migrating from Tableau to Power BI is more than a technology swap—it's an opportunity to re-architect your analytics strategy for the cloud-native, AI-powered era. The semantic layer-first approach requires upfront investment in data modeling, DAX expertise, and Fabric platform adoption. But the payoff is transformative: Consistency: Single source of truth for all business metrics Scalability: Semantic models that serve hundreds of reports and thousands of users Agility: Changes to business logic propagate instantly across the enterprise Future-readiness: Foundation for Fabric IQ, Data Agents, and AI-driven insights Start your migration with the end in mind: not just convert dashboards, but a modern, governed, AI-ready analytics platform that scales with your business. Addressing Key Migration Concerns (1) Why a semantic‑layered model approach is better than recreating Tableau dashboards A semantic‑layered modeling approach is the optimal strategy for migration and is significantly more effective than attempting to recreate Tableau dashboards exactly as they exist. By contrast, Power BI and Fabric encourage a semantic model–first architecture, where all business rules, relationships, calculations, and transformations are centralized in a governed model that serves many dashboards. The approach not only provides consistency and reuse across the enterprise but also ensures that report authors build on a single certified version of the truth. (2) How semantic-layered model approach reduces the constant redesign caused by changing data needs. A semantic‑layered modeling approach directly addresses concern about constant changes and frequent redesigns of dashboards when data evolves. With a semantic layer, changes are absorbed in the model layer—so the logic is updated once and flows automatically into all dependent reports. Combined with Fabric features like OneLake shortcuts, Direct Lake mode, and centralized governance, the semantic layer drastically reduces breakage, minimizes rework, and ensures scalability as data continues to grow and shift. Additional Resources Direct Lake in Microsoft Fabric Create Fabric Data Agents OneLake Shortcuts Write DAX queries with Copilot - DAX Prepare Your Data for AI - Power BI | Microsoft Learn5.2KViews4likes3CommentsMeasuring Microsoft 365 Copilot adoption beyond license activation
In adoption programs, I think the interesting measurement starts after users have access. At DataToBiz, we have been looking at the difference between someone trying Copilot once and actually incorporating it into a recurring workflow. For example, repeat usage around a specific task tells a very different story from initial activation. How are teams measuring that second stage of adoption without relying only on license or usage counts?205Views0likes1Comment